Cache uaparse fully; drop the bot field and is_bot
This commit is contained in:

@@ -23,14 +23,12 @@ r.pretty # "Chrome/152 Windows"
|
||||
r.engine # "Chromium"
|
||||
r.os # "Windows"
|
||||
r.kind # "browser"
|
||||
r.bot # ""
|
||||
r.url # ""
|
||||
|
||||
r = uaparse("Mozilla/5.0 (Linux; Android 13; Pixel 7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.6885.65 Mobile Safari/537.36; compatible; facebookexternalhit/1.1; +http://www.facebook.com/externalhit_uatext.php")
|
||||
|
||||
r.pretty # "Facebook"
|
||||
r.pretty # "Facebook (social)"
|
||||
r.kind # "social"
|
||||
r.bot # "Facebook"
|
||||
r.provider # "Meta"
|
||||
r.url # "http://www.facebook.com/externalhit_uatext.php"
|
||||
```
|
||||
@@ -44,7 +42,6 @@ r.url # "http://www.facebook.com/externalhit_uatext.php"
|
||||
| pretty | Compact display string (below); empty for empty/missing UAs, the raw UA when unrecognized |
|
||||
| engine | Chromium, Gecko, Safari, ArkWeb (HarmonyOS), or empty |
|
||||
| os | Windows, macOS, Linux, iOS, Android, HarmonyOS, or empty |
|
||||
| bot | Crawler/unfurler display name, or empty |
|
||||
| kind | browser, ai, search, social, analytics, spider, or empty (scripts/HTTP libraries) |
|
||||
| url | The crawler's info URL (the +https://… pointer), or empty; not part of pretty — link it in the UI |
|
||||
| provider | The bot's provider for known crawler families (Meta, Google, OpenAI, ...), or empty |
|
||||
@@ -108,7 +105,17 @@ The table below compares representative results. uarite shows `r.pretty`; the ua
|
||||
|
||||
Measured on modern browser UAs, **uarite resolves family, version and OS at 100%**. ua-parser and user-agents land at 80%, while user-agent-parser does slightly better at 92%.
|
||||
|
||||
Crawler detection was also tested against real-world crawler UAs from [monperrus/crawler-user-agents](https://github.com/monperrus/crawler-user-agents). Here user-agent-parser got only 32% right and worse, crashed on 5 UAs. A slight difference was found with the other contenders, user-agents coming at 60% and ua-parser at 64% correct. Our module **uarite scores 95%**, and could detect _which_ crawler it is for 80% (bot field set).
|
||||
Crawler detection was also tested against real-world crawler UAs from [monperrus/crawler-user-agents](https://github.com/monperrus/crawler-user-agents). Here user-agent-parser got only 32% right and worse, crashed on 5 UAs. A slight difference was found with the other contenders, user-agents coming at 60% and ua-parser at 64% correct. Our module **uarite scores 97%**, and could detect _which_ crawler it is for 80% (named in pretty).
|
||||
|
||||
## Performance
|
||||
|
||||
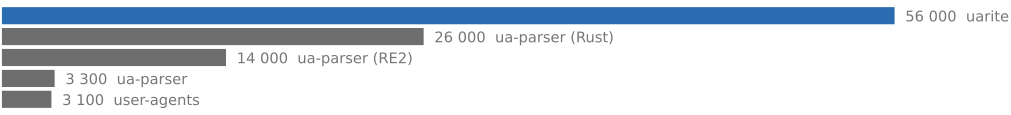
All compared parsers cache repeated User-Agents, making cache hits effectively free. The useful difference is therefore the first parse of a new string.
|
||||
|
||||
|
||||
|
||||
*User-Agents parsed per second, first parse of previously unseen strings (cache cold), equal share of browser and crawler UAs. One-off setup costs excluded — ua-parser's very first parse alone takes ~59 ms loading its regex database.*
|
||||
|
||||
In our benchmarks, cold parses of previously unseen UAs (half browsers, half crawlers) take roughly **16 µs** with uarite. user-agent-parser is faster at **8 µs**, while the pure-Python ua-parser/user-agents path takes roughly **320 µs**, which can be a considerable slowdown; ua-parser's native backends help but still trail at ~77 µs (RE2) and ~47 µs (Rust).
|
||||
|
||||
## Design
|
||||
|
||||
|
||||
Reference in New Issue
Block a user