Cache uaparse fully; drop the bot field and is_bot
This commit is contained in:

@@ -23,14 +23,12 @@ r.pretty # "Chrome/152 Windows"
|
||||
r.engine # "Chromium"
|
||||
r.os # "Windows"
|
||||
r.kind # "browser"
|
||||
r.bot # ""
|
||||
r.url # ""
|
||||
|
||||
r = uaparse("Mozilla/5.0 (Linux; Android 13; Pixel 7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.6885.65 Mobile Safari/537.36; compatible; facebookexternalhit/1.1; +http://www.facebook.com/externalhit_uatext.php")
|
||||
|
||||
r.pretty # "Facebook"
|
||||
r.pretty # "Facebook (social)"
|
||||
r.kind # "social"
|
||||
r.bot # "Facebook"
|
||||
r.provider # "Meta"
|
||||
r.url # "http://www.facebook.com/externalhit_uatext.php"
|
||||
```
|
||||
@@ -44,7 +42,6 @@ r.url # "http://www.facebook.com/externalhit_uatext.php"
|
||||
| pretty | Compact display string (below); empty for empty/missing UAs, the raw UA when unrecognized |
|
||||
| engine | Chromium, Gecko, Safari, ArkWeb (HarmonyOS), or empty |
|
||||
| os | Windows, macOS, Linux, iOS, Android, HarmonyOS, or empty |
|
||||
| bot | Crawler/unfurler display name, or empty |
|
||||
| kind | browser, ai, search, social, analytics, spider, or empty (scripts/HTTP libraries) |
|
||||
| url | The crawler's info URL (the +https://… pointer), or empty; not part of pretty — link it in the UI |
|
||||
| provider | The bot's provider for known crawler families (Meta, Google, OpenAI, ...), or empty |
|
||||
@@ -108,7 +105,17 @@ The table below compares representative results. uarite shows `r.pretty`; the ua
|
||||
|
||||
Measured on modern browser UAs, **uarite resolves family, version and OS at 100%**. ua-parser and user-agents land at 80%, while user-agent-parser does slightly better at 92%.
|
||||
|
||||
Crawler detection was also tested against real-world crawler UAs from [monperrus/crawler-user-agents](https://github.com/monperrus/crawler-user-agents). Here user-agent-parser got only 32% right and worse, crashed on 5 UAs. A slight difference was found with the other contenders, user-agents coming at 60% and ua-parser at 64% correct. Our module **uarite scores 95%**, and could detect _which_ crawler it is for 80% (bot field set).
|
||||
Crawler detection was also tested against real-world crawler UAs from [monperrus/crawler-user-agents](https://github.com/monperrus/crawler-user-agents). Here user-agent-parser got only 32% right and worse, crashed on 5 UAs. A slight difference was found with the other contenders, user-agents coming at 60% and ua-parser at 64% correct. Our module **uarite scores 97%**, and could detect _which_ crawler it is for 80% (named in pretty).
|
||||
|
||||
## Performance
|
||||
|
||||
All compared parsers cache repeated User-Agents, making cache hits effectively free. The useful difference is therefore the first parse of a new string.
|
||||
|
||||
|
||||
|
||||
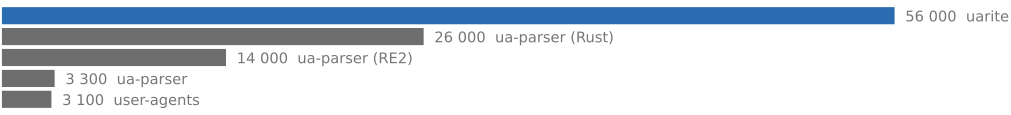
*User-Agents parsed per second, first parse of previously unseen strings (cache cold), equal share of browser and crawler UAs. One-off setup costs excluded — ua-parser's very first parse alone takes ~59 ms loading its regex database.*
|
||||
|
||||
In our benchmarks, cold parses of previously unseen UAs (half browsers, half crawlers) take roughly **16 µs** with uarite. user-agent-parser is faster at **8 µs**, while the pure-Python ua-parser/user-agents path takes roughly **320 µs**, which can be a considerable slowdown; ua-parser's native backends help but still trail at ~77 µs (RE2) and ~47 µs (Rust).
|
||||
|
||||
## Design
|
||||
|
||||
|
||||
+93
-29
@@ -1,14 +1,25 @@
|
||||
# /// script
|
||||
# requires-python = ">=3.14"
|
||||
# dependencies = [
|
||||
# "ua-parser[re2,regex]>=1.0.2",
|
||||
# "uarite",
|
||||
# "user-agent-parser>=0.2.1",
|
||||
# "user-agents>=2.2.0",
|
||||
# ]
|
||||
#
|
||||
# [tool.uv.sources]
|
||||
# uarite = { path = "..", editable = true }
|
||||
# ///
|
||||
"""Benchmark uarite vs ua-parser vs user-agents vs user-agent-parser.
|
||||
|
||||
Reproduces the README's numbers: browser accuracy on 100 modern UAs,
|
||||
crawler detection on 2163 real-world crawler UAs, and timing (unique UAs,
|
||||
a realistic repeat/unique mix, a pure bot storm) with cache introspection.
|
||||
|
||||
Data lives in scripts/data (see download_data.py). Requires uarite
|
||||
(installed) plus the benchmark-only reference parsers:
|
||||
Data lives in scripts/data (see download_data.py). All dependencies,
|
||||
including uarite itself (editable), are declared inline:
|
||||
|
||||
uv run --with ua-parser --with user-agents --with user-agent-parser \
|
||||
python scripts/bench.py
|
||||
uv run scripts/bench.py
|
||||
"""
|
||||
|
||||
import json
|
||||
@@ -17,17 +28,55 @@ import re
|
||||
import timeit
|
||||
from pathlib import Path
|
||||
|
||||
import ua_parser
|
||||
from ua_parser import parse as ua_parse
|
||||
from user_agent_parser import parse as uap_parse
|
||||
from user_agents import parse as uas_parse
|
||||
|
||||
from uarite import uaparse
|
||||
from uarite.core import _parse_client
|
||||
|
||||
ALL_DOMAINS = (
|
||||
ua_parser.Domain.USER_AGENT | ua_parser.Domain.OS | ua_parser.Domain.DEVICE
|
||||
)
|
||||
|
||||
|
||||
_VARIANTS = {}
|
||||
|
||||
|
||||
def ua_variant(name):
|
||||
"""ua-parser with a specific resolver backend (pure/re2/rust), lazily
|
||||
built so its one-time database load lands in the untimed warm-up call.
|
||||
The default parse() picks whichever native backend is installed, so
|
||||
backends must be forced explicitly to benchmark them separately."""
|
||||
if name not in _VARIANTS:
|
||||
ctor = {
|
||||
"pure": ua_parser.BasicResolver,
|
||||
"re2": ua_parser.Re2Resolver,
|
||||
"rust": ua_parser.RegexResolver,
|
||||
}[name]
|
||||
parser = ua_parser.Parser(
|
||||
ua_parser.CachingResolver(
|
||||
ctor(ua_parser.load_builtins()), ua_parser.Cache(2000)
|
||||
)
|
||||
)
|
||||
_VARIANTS[name] = lambda ua: parser(ua, ALL_DOMAINS)
|
||||
return _VARIANTS[name]
|
||||
|
||||
|
||||
def uap_pure(ua):
|
||||
return ua_variant("pure")(ua)
|
||||
|
||||
|
||||
def uap_re2(ua):
|
||||
return ua_variant("re2")(ua)
|
||||
|
||||
|
||||
def uap_rust(ua):
|
||||
return ua_variant("rust")(ua)
|
||||
|
||||
DATA = Path(__file__).parent / "data"
|
||||
BROWSERS = json.loads((DATA / "top-user-agents.json").read_text())
|
||||
CRAWLERS = json.loads((DATA / "crawler-user-agents.json").read_text())
|
||||
OWN = (DATA / "ua.txt").read_text().splitlines()
|
||||
CRAWLER_UAS = [ua for c in CRAWLERS for ua in (c.get("instances") or [c["pattern"]])]
|
||||
|
||||
|
||||
@@ -149,7 +198,9 @@ def score_crawlers():
|
||||
elif name == "user-agent-parser":
|
||||
bot = uap_parse(ua)[4] == "Bot"
|
||||
else:
|
||||
bot = bool(uaparse(ua).bot)
|
||||
# Anything not recognized as a real browser is automated:
|
||||
# known bots, generic spiders, clients, spoofed claims.
|
||||
bot = uaparse(ua).kind != "browser"
|
||||
except Exception:
|
||||
crashes += name == "user-agent-parser"
|
||||
continue
|
||||
@@ -193,7 +244,9 @@ def bench_realistic():
|
||||
f" with 2000 mostly-unique bots)"
|
||||
)
|
||||
for name, fn in (
|
||||
("ua-parser", ua_parse),
|
||||
("ua-parser (pure)", uap_pure),
|
||||
("ua-parser (re2)", uap_re2),
|
||||
("ua-parser (rust)", uap_rust),
|
||||
("user-agents", uas_parse),
|
||||
("user-agent-parser", uap_parse),
|
||||
("uarite", uaparse),
|
||||
@@ -204,7 +257,9 @@ def bench_realistic():
|
||||
print(f"{name:20} {t / len(mix) * 1e6:7.1f} µs/UA cache: {info}")
|
||||
print(f"\n## pure bot storm ({len(storm)} unique UAs, zero cache value)")
|
||||
for name, fn in (
|
||||
("ua-parser", ua_parse),
|
||||
("ua-parser (pure)", uap_pure),
|
||||
("ua-parser (re2)", uap_re2),
|
||||
("ua-parser (rust)", uap_rust),
|
||||
("user-agents", uas_parse),
|
||||
("user-agent-parser", uap_parse),
|
||||
("uarite", uaparse),
|
||||
@@ -228,8 +283,8 @@ def safe(fn):
|
||||
|
||||
def cache_info(name):
|
||||
if name == "uarite":
|
||||
i = _parse_client.cache_info()
|
||||
return f"{i.hits} hits / {i.misses} misses (cap 1024, browsers only)"
|
||||
i = uaparse.cache_info()
|
||||
return f"{i.hits} hits / {i.misses} misses (cap 1024)"
|
||||
if name == "user-agent-parser":
|
||||
from user_agent_parser.parser import _cached_parse_user_agent
|
||||
|
||||
@@ -239,33 +294,48 @@ def cache_info(name):
|
||||
from ua_parser.user_agent_parser import _PARSE_CACHE
|
||||
|
||||
return f"{len(_PARSE_CACHE)} entries (cap 200, CLEARS when full)"
|
||||
if name == "ua-parser":
|
||||
if name.startswith("ua-parser"):
|
||||
return "cap 2000 S3-FIFO (scan-resistant)"
|
||||
return ""
|
||||
|
||||
|
||||
def bench():
|
||||
alluas = BROWSERS + CRAWLER_UAS + OWN
|
||||
n = 3
|
||||
"""Cold-cache speed: a single pass over previously unseen UAs, with
|
||||
equal shares of realistic browser and crawler strings since they take
|
||||
different parse paths. Runs before the accuracy passes, which would
|
||||
otherwise warm every parser's cache with these very strings.
|
||||
|
||||
Each parser first parses one dummy UA (untimed) so that lazy regex
|
||||
compilation and database loading do not land on the first real item —
|
||||
ua-parser's first parse alone costs ~59 ms loading its database. The
|
||||
cache gains nothing from it since all timed UAs are unique."""
|
||||
rng = random.Random(7)
|
||||
work = BROWSERS + rng.sample(CRAWLER_UAS, len(BROWSERS))
|
||||
rng.shuffle(work)
|
||||
res = {}
|
||||
for name, fn in (
|
||||
("ua-parser", ua_parse),
|
||||
("ua-parser (pure)", uap_pure),
|
||||
("ua-parser (re2)", uap_re2),
|
||||
("ua-parser (rust)", uap_rust),
|
||||
("user-agents", uas_parse),
|
||||
("user-agent-parser", uap_parse),
|
||||
("uarite", uaparse),
|
||||
):
|
||||
fn = safe(fn)
|
||||
t = timeit.timeit(lambda: [fn(u) for u in alluas], number=n)
|
||||
res[name] = t / n / len(alluas) * 1e6
|
||||
# warm cache: repeat a small realistic working set many times
|
||||
working = (BROWSERS + OWN[:50]) * 10
|
||||
t = timeit.timeit(lambda: [uaparse(u) for u in working], number=n)
|
||||
res["uarite (warm cache)"] = t / n / len(working) * 1e6
|
||||
return res
|
||||
fn("Warmup/1.0 (+https://example.com/warmup)")
|
||||
uaparse.cache_clear()
|
||||
t = timeit.timeit(lambda: [fn(u) for u in work], number=1)
|
||||
res[name] = t / len(work) * 1e6
|
||||
return res, len(work)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
print(f"## browser accuracy (n={len(BROWSERS)}): family / version / OS correct")
|
||||
res, nwork = bench()
|
||||
print(f"## speed (µs per cold parse, {nwork} unique UAs,"
|
||||
" half browsers / half crawlers)")
|
||||
for k, v in res.items():
|
||||
print(f"{k:20} {v:8.1f}")
|
||||
print(f"\n## browser accuracy (n={len(BROWSERS)}): family / version / OS correct")
|
||||
for k, (f, v, o) in score_browsers().items():
|
||||
print(f"{k:14} {f:3}/100 {v:3}/100 {o:3}/100")
|
||||
det, url_have, url_got, crashes = score_crawlers()
|
||||
@@ -274,10 +344,4 @@ if __name__ == "__main__":
|
||||
print(f"{k:18} {v:5} ({v / len(CRAWLER_UAS):.1%})")
|
||||
print(f"user-agent-parser crashed on {crashes} UAs")
|
||||
print(f"\nuarite URL extraction: {url_got}/{url_have} of instances carrying a URL")
|
||||
print(
|
||||
"\n## speed (µs per parse, mixed set of %d UAs)"
|
||||
% (len(BROWSERS) + len(CRAWLER_UAS) + len(OWN))
|
||||
)
|
||||
for k, v in bench().items():
|
||||
print(f"{k:20} {v:8.1f}")
|
||||
bench_realistic()
|
||||
|
||||
@@ -0,0 +1,67 @@
|
||||
# /// script
|
||||
# requires-python = ">=3.14"
|
||||
# dependencies = ["matplotlib"]
|
||||
# ///
|
||||
"""Bar chart of cold-parse throughput for the README's Performance section.
|
||||
|
||||
Numbers are pasted from `uv run scripts/bench.py` (the cold 50/50
|
||||
browser/crawler mix, µs per parse) and shown as parses per second.
|
||||
Transparent SVG, text baked to paths, neutral grays: renders the same
|
||||
on light and dark themes. All labels sit on the bars themselves.
|
||||
Very wide aspect ratio: forges render images at full content width,
|
||||
so height alone controls how tall it appears.
|
||||
|
||||
uv run scripts/speedplot.py
|
||||
"""
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import matplotlib
|
||||
|
||||
matplotlib.use("Agg")
|
||||
matplotlib.rcParams["svg.fonttype"] = "path" # text as paths: renders anywhere
|
||||
import matplotlib.pyplot as plt # noqa: E402
|
||||
|
||||
# µs per cold parse, from scripts/bench.py.
|
||||
US = {
|
||||
"user-agent-parser": 8.2,
|
||||
"uarite": 17.7,
|
||||
"ua-parser (Rust)": 46.6,
|
||||
"ua-parser (RE2)": 77.1,
|
||||
"ua-parser (pure)": 321.5,
|
||||
"user-agents": 334.4,
|
||||
}
|
||||
|
||||
#: Readable on both white and dark backgrounds.
|
||||
OUTSIDE = "#767676"
|
||||
|
||||
data = sorted(((n, 1e6 / us) for n, us in US.items()), key=lambda t: -t[1])
|
||||
names = [n for n, _ in data][::-1]
|
||||
values = [v for _, v in data][::-1]
|
||||
colors = ["#6e6e6e"] * len(data)
|
||||
colors[names.index("uarite")] = "#2b6cb0"
|
||||
|
||||
fig, ax = plt.subplots(figsize=(12, 1.7), dpi=100)
|
||||
bars = ax.barh(names, values, color=colors, height=0.62)
|
||||
ax.set_xlim(0, max(values))
|
||||
ax.axis("off")
|
||||
|
||||
for bar, name, v in zip(bars, names, values):
|
||||
# Round to three significant digits: 121951 -> "122 000".
|
||||
rounded = round(v, 2 - int(f"{v:.0e}".split("e")[1]))
|
||||
label = f"{name} {rounded:,.0f}".replace(",", " ")
|
||||
y = bar.get_y() + bar.get_height() / 2
|
||||
if bar.get_width() > max(values) * 0.28:
|
||||
# Long bar: white text inside, right-aligned at the bar end.
|
||||
ax.text(bar.get_width() - max(values) * 0.012, y, label,
|
||||
va="center", ha="right", color="white", fontsize=11)
|
||||
else:
|
||||
# Short bar: theme-neutral gray text just past the bar end.
|
||||
ax.text(bar.get_width() + max(values) * 0.012, y, label,
|
||||
va="center", color=OUTSIDE, fontsize=11)
|
||||
|
||||
fig.tight_layout(pad=0.2)
|
||||
out = Path("docs/bench-speed.svg")
|
||||
out.parent.mkdir(exist_ok=True)
|
||||
fig.savefig(out, transparent=True)
|
||||
print("wrote", out)
|
||||
+5
-12
@@ -13,7 +13,6 @@ class UA:
|
||||
pretty: str = ""
|
||||
engine: str = ""
|
||||
os: str = ""
|
||||
bot: str = ""
|
||||
kind: str = ""
|
||||
url: str = ""
|
||||
provider: str = ""
|
||||
@@ -154,15 +153,15 @@ def model_name(model: str) -> str:
|
||||
return model
|
||||
|
||||
|
||||
@lru_cache(maxsize=1024)
|
||||
def uaparse(ua: str) -> UA:
|
||||
"""Parse a User-Agent string into a compact ``UA`` record.
|
||||
|
||||
``pretty`` is "" for empty/missing UAs and the original string when
|
||||
nothing is recognized.
|
||||
|
||||
Only the browser path is cached: real visitors repeat (cache hits),
|
||||
while crawlers and scripts are mostly one-hit wonders whose entries
|
||||
would just flush the cache.
|
||||
Everything is cached: a dict lookup on the full UA string is far
|
||||
cheaper than re-parsing, and the frozen ``UA`` is shared safely.
|
||||
"""
|
||||
if not ua or not ua.strip() or ua in ("-", "null"):
|
||||
return UA()
|
||||
@@ -173,15 +172,14 @@ def uaparse(ua: str) -> UA:
|
||||
label = KIND_LABEL.get(kind, "") if name in LABELED else ""
|
||||
pretty = f"{name} ({label})" if label else name
|
||||
return UA(
|
||||
pretty=pretty, bot=name, kind=kind, url=url(ua),
|
||||
pretty=pretty, kind=kind, url=url(ua),
|
||||
provider=PROVIDER_OF.get(name, ""),
|
||||
)
|
||||
return _parse_client(ua)
|
||||
|
||||
|
||||
@lru_cache(maxsize=1024)
|
||||
def _parse_client(ua: str) -> UA:
|
||||
"""Browser/client parsing behind the cache; ``uaparse`` filters bots out."""
|
||||
"""Browser/client parsing; ``uaparse`` filters bots out."""
|
||||
r = _client(ua)
|
||||
# Frozen ancient browser strings are scanners/scripts, not users: show
|
||||
# the claimed browser, but mark it and drop the fake engine/os/kind.
|
||||
@@ -244,8 +242,3 @@ def _client(ua: str) -> UA:
|
||||
os_name = os(ua)
|
||||
pretty = f"{b} {os_name}".strip()
|
||||
return UA(pretty=pretty or ua, engine=engine(b), os=os_name, kind="browser")
|
||||
|
||||
|
||||
def is_bot(ua: str) -> bool:
|
||||
"""True when the UA claims a crawler or link-unfurling identity."""
|
||||
return bool(uaparse(ua).bot)
|
||||
|
||||
Reference in New Issue
Block a user