README, and support script cleanup.
This commit is contained in:

@@ -1,17 +1,17 @@
|
||||
# User-Agent parsed Right
|
||||
# User-Agent Parsing Done Right
|
||||
|
||||
User-Agent parsing in Python has a long lineage. ua-parser is the official Python implementation of the ua-parser project, built around uap-core: the regex database extracted from BrowserScope's original parser and shared by implementations in many languages. user-agents wraps ua-parser with higher-level device and capability detection but its last release was in 2020. user-agent-parser is a separate implementation first released in 2022 and substantially updated in 2026, taking its own approach rather than building on uap-core. None of the three has further dependencies, but the regex databases weigh something: ua-parser and user-agents each install about half a megabyte, user-agent-parser at 166 kB. We are merely 29 kB and yet perform better especially with the new crawlers of the AI boom.
|
||||
There are plenty of UA parsers for Python: ua-parser is the official Python port of the large upstream project, while user-agents builds on top of it with higher-level device detection. Among newer implementations, user-agent-parser is the most promising and is included here for comparison.
|
||||
|
||||
This module is another take on the same problem: a small, dependency-free, compact pure-Python parser. It returns structured classifications, but also the thing most applications eventually need: **a short human-readable pretty description**.
|
||||
This module takes a smaller, faster, modern approach. It's a dependency-free pure-Python parser weighing only 25 kB, with strong handling of current browsers and crawlers. Despite its light weight, uarite identifies both browsers and crawlers more accurately than any competing implementation tested here.
|
||||
|
||||
Add to your project:
|
||||
It returns structured classification, but also the thing most applications eventually need: **a short pretty description**.
|
||||
|
||||
Add it to your project:
|
||||
|
||||
```sh
|
||||
uv add uarite
|
||||
```
|
||||
|
||||
We correctly detect disguised crawlers, distinguish traffic of AI learning, search engines and social media share previews. We handle HarmonyOS and bots without calling them Android, resolving common device model codes, and fall back to reasonable output even when all else fails.
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
@@ -27,7 +27,7 @@ r.url # ""
|
||||
|
||||
r = uaparse("Mozilla/5.0 (Linux; Android 13; Pixel 7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.6885.65 Mobile Safari/537.36; compatible; facebookexternalhit/1.1; +http://www.facebook.com/externalhit_uatext.php")
|
||||
|
||||
r.pretty # "Facebook (social)"
|
||||
r.pretty # "Facebook"
|
||||
r.kind # "social"
|
||||
r.provider # "Meta"
|
||||
r.url # "http://www.facebook.com/externalhit_uatext.php"
|
||||
@@ -35,48 +35,26 @@ r.url # "http://www.facebook.com/externalhit_uatext.php"
|
||||
|
||||
## Output
|
||||
|
||||
`uaparse(ua)` returns a frozen `UA` dataclass:
|
||||
`uaparse(ua)` returns a `UA` dataclass with string fields. Any field may be empty when the information is unavailable.
|
||||
|
||||
| Field | Content |
|
||||
| -------- | ------------------------------------------------------------------------------------------------- |
|
||||
| pretty | Compact display string (below); empty for empty/missing UAs, the raw UA when unrecognized |
|
||||
| engine | Chromium, Gecko, Safari, ArkWeb (HarmonyOS), or empty |
|
||||
| os | Windows, macOS, Linux, iOS, Android, HarmonyOS, or empty |
|
||||
| kind | browser, ai, search, social, analytics, spider, or empty (scripts/HTTP libraries) |
|
||||
| url | The crawler's info URL (the +https://… pointer), or empty; not part of pretty — link it in the UI |
|
||||
| provider | The bot's provider for known crawler families (Meta, Google, OpenAI, ...), or empty |
|
||||
| Field | Content |
|
||||
| -------- | ------------------------------------------------ |
|
||||
| pretty | Compact display string; raw UA when unrecognized |
|
||||
| engine | Chromium, Gecko, Safari, ArkWeb |
|
||||
| os | Windows, macOS, Linux, iOS, Android, HarmonyOS |
|
||||
| kind | browser, ai, search, social, analytics, spider |
|
||||
| url | Crawler information URL |
|
||||
| provider | Provider of a known crawler family |
|
||||
|
||||
`os` is the major OS only, no version — meant for things like offering OS-specific downloads. `engine` is derived from the browser identity: every recognized browser is Chromium except Firefox/LibreWolf (Gecko) and Safari and all of iOS (Safari's engine is all Apple allows there); HarmonyOS browsers run ArkWeb. Both are left empty for crawlers: the browser and OS in a disguised crawler UA are part of the disguise.
|
||||
The pretty field is intended for UIs and logs. The url can be attached to it as a link when available.
|
||||
|
||||
`kind` is `"browser"` for Mozilla-format UAs with no bot token, `"ai"` for training-data and AI-assistant fetchers (GPTBot, ClaudeBot, Google-Extended, ...), `"search"` for search-engine indexing (Googlebot, Bingbot, ...), `"preview"` for social link-preview fetchers (Facebook, WhatsApp, Slack, ...), `"spider"` for generic or unknown crawlers, and `""` for scripts and HTTP libraries.
|
||||
The engine and os fields are intentionally broad. The kind field distinguishes browsers from AI collectors, search engines, social previews, monitoring tools, generic spiders, and ordinary HTTP clients. Any non-browser kind represents automated traffic.
|
||||
|
||||
The kind field describes our detection of visitor type: browser for actual browsers, ai for AI training collectors, agents and user-initiated fetches (GPTBot, ClaudeBot, ChatGPT-User, Google-Extended, ...), search for search-engine indexing (Googlebot, Bingbot, ...), social for link-sharing unfurlers (Facebook, WhatsApp, Slack, ...), analytics for monitoring and site-analytics crawlers (UptimeRobot, AdsBot-Google, MJ12bot), spider for generic or unknown crawlers, and empty for scripts and HTTP libraries. Any value other than browser means the visitor is automated.
|
||||
|
||||
`pretty` is intended to be shown directly:
|
||||
|
||||
- Desktop: `Chrome/152 Windows`, `Safari/18 macOS`
|
||||
- iPhone/iPad: `iPhone iOS 17` — the device and iOS version, not Safari (the only browser iOS has)
|
||||
- Android: `Chrome/118 Pixel 6`, or `Chrome/152 Android` when the device is unknown
|
||||
- Crawlers: `GPTBot (AI)`, `Googlebot (search)`, `Facebook` — the kind suffix appears only where a provider runs crawlers of more than one kind; single-kind providers stay plain
|
||||
- Scripts: `python-requests/2.32.5`, `pip/24.3.1 Linux`
|
||||
|
||||
Chrome's reduced Android UA reports the frozen values `Android 10; K`; neither is real device information, so uarite deliberately reports simply `Android`. HarmonyOS compatibility strings are similarly recognized before their misleading Android tokens.
|
||||
|
||||
## Performance
|
||||
|
||||
All compared parsers cache repeated User-Agents, making cache hits effectively free. The useful difference is therefore the first parse of a new string.
|
||||
|
||||
In our benchmarks, uncached uarite parses take roughly **3–7 µs**. user-agent-parser is in the same general range at **~7 µs**, while the pure-Python ua-parser/user-agents path takes roughly **130–250 µs**.
|
||||
|
||||
The cache strategies differ in ways that matter under adversarial traffic. uarite caches only browser/client results (1024-entry LRU): crawlers tend to be unique and would otherwise evict the repeating UAs where caching is useful. user-agent-parser's 512-entry LRU lets a bot storm evict browsers, and user-agents' 200-entry dict clears entirely when full.
|
||||
Detection is necessarily limited by what the User-Agent reveals. Crawlers can masquerade as ordinary browsers or other crawlers, so sites that need stronger identification should use additional methods rather than relying on UA detection alone.
|
||||
|
||||
## Accuracy
|
||||
|
||||
The main difference is not how many fields can be returned, but what the parser believes the User-Agent actually says.
|
||||
|
||||
For example, reduced Chrome does not really tell us that the device is named `K` or that it runs Android 10; an Android compatibility token does not make HarmonyOS Android; and a Facebook or Google crawler containing a plausible Chrome UA is still a crawler, not a Chrome visitor.
|
||||
|
||||
The table below compares representative results. uarite shows `r.pretty`; the ua-parser display strings are assembled from its structured output for comparison. user-agents is omitted: it shares the ua-parser backend and returns virtually identical data in a slightly different structure.
|
||||
The table below compares representative User-Agent formats with ua-parser. user-agents produces nearly identical results and is left out.
|
||||
|
||||
| Case | uarite¹ | ua-parser² |
|
||||
| ---------------------------- | ------------------------- | --------------------------------------------- |
|
||||
@@ -91,7 +69,7 @@ The table below compares representative results. uarite shows `r.pretty`; the ua
|
||||
| Huawei HarmonyOS phone | HuaweiBrowser/6 HarmonyOS | Huawei Browser/6 Android❌ Huawei Browser |
|
||||
| GPTBot | GPTBot (AI) | GPTBot/1 Spider |
|
||||
| Googlebot (disguised) | Googlebot (search) | Googlebot/2 Android❌ Spider |
|
||||
| Facebook preview (disguised) | Facebook (social) | FacebookBot/1 Android Pixel 7 ❌ |
|
||||
| Facebook preview (disguised) | Facebook | FacebookBot/1 Android Pixel 7 ❌ |
|
||||
| Meta crawler (disguised) | Meta-ExternalAgent (AI) | Chrome/145 Windows ❌ |
|
||||
| WhatsApp preview | WhatsApp | WhatsApp/10 Spider |
|
||||
| Bytespider | Bytespider | Bytespider/ Android❌ Generic Smartphone |
|
||||
@@ -99,28 +77,31 @@ The table below compares representative results. uarite shows `r.pretty`; the ua
|
||||
| AhrefsBot | AhrefsBot | AhrefsBot/7 Spider |
|
||||
| python-requests | python-requests/2.32.5 | Python Requests/2 |
|
||||
|
||||
❌ marks an incorrect browser, OS, or device interpretation.
|
||||
¹ `r.pretty` shown as is
|
||||
² `{user_agent.family}/{user_agent.major} {os.family} {device.family}`
|
||||
- ❌ marks an incorrect data such as OS from disquise or Android 10; K (compat) on modern devices
|
||||
- ¹ `r.pretty` shown as is
|
||||
- ² `{r.user_agent.family}/{r.user_agent.major} {r.os.family} {r.device.family}`
|
||||
|
||||
Measured on modern browser UAs, **uarite resolves family, version and OS at 100%**. ua-parser and user-agents land at 80%, while user-agent-parser does slightly better at 92%.
|
||||
On our modern-browser test set, **uarite resolves family, version, and OS at 100%**. ua-parser and user-agents score 80%, while user-agent-parser reaches 92%.
|
||||
|
||||
Crawler detection was also tested against real-world crawler UAs from [monperrus/crawler-user-agents](https://github.com/monperrus/crawler-user-agents). Here user-agent-parser got only 32% right and worse, crashed on 5 UAs. A slight difference was found with the other contenders, user-agents coming at 60% and ua-parser at 64% correct. Our module **uarite scores 97%**, and could detect _which_ crawler it is for 80% (named in pretty).
|
||||
Crawler detection was tested against real-world UAs from [monperrus/crawler-user-agents](https://github.com/monperrus/crawler-user-agents). user-agent-parser scored 32%, user-agents 60%, and ua-parser 64%. **uarite scores 97%**, identifying the specific crawler by name in 80% of cases.
|
||||
|
||||
The benchmark and test scripts are available in the repository's scripts folder.
|
||||
|
||||
## Performance
|
||||
|
||||
Startup cost matters for single-item processing, such as a script run per request: from import to the first parsed User-Agent, uarite takes about **10 ms**, while ua-parser takes **50–90 ms** depending on the backend.
|
||||
Import and first parse takes about **10 ms** for uarite, compared with 50–90 ms for ua-parser depending on backend.
|
||||
|
||||
|
||||

|
||||
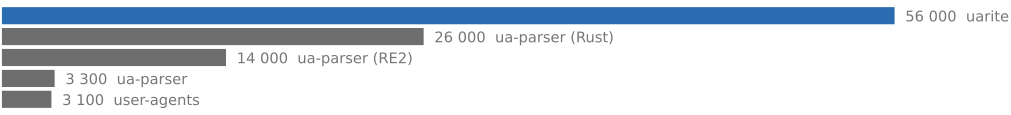
_User-Agents parsed per second per CPU core, first parse of unseen strings, with equal shares of browser and crawler UAs. One-off setup costs excluded._
|
||||
|
||||
_User-Agents parsed per second, first parse of previously unseen strings, equal share of browser and crawler UAs. One-off setup costs excluded._
|
||||
All parsers cache results. With cache hits, **uarite reaches about 36 million lookups per second**, compared with about 5 million for ua-parser and 600 000 for user-agents.
|
||||
|
||||
All parsers here cache repeated User-Agents, bringing the cost of a repeated string down to nearly zero. The differences only show on the first parse of a new string — exactly the case shown above.
|
||||
## Why yet another UA parser
|
||||
|
||||
## Design
|
||||
Rather than relying on a large historical regex database, the parser focuses on modern UA formats and parses them directly, choosing the most specific interpretation available. This keeps the implementation small while handling today's browsers and crawler traffic well.
|
||||
|
||||
Rather than a large regex database trying to match given fields, we actually parse the modern forms of UA strings, and take the most specific interpretation of them to avoid the mess of compatibility tags they usually contain. This is built against modern traffic, including AI crawlers that make a large part of today's traffic, and for modern browser. Purposefully ignoring the decades of history other UA parser frameworks have.
|
||||
Until now, I had been using those other modules and building my own pretty-UA formatting on top of them, fixing by post processing issues the upstream didn't care of.
|
||||
|
||||
The most important feature, absent from others, is the built in formatting of pretty UA strings suitable for user interfaces and logging. Hopefully you will find use for that. And in case something could be better, please report an issue.
|
||||
Eventually it became easier to start over with a parser designed around modern traffic. The result is uarite.
|
||||
|
||||
Until now I had been using those other modules, building my own pretty UA formatting of top of them. Where the modules had misdetections, I have tried reporting bugs but the upstream didn't have any interest on fixing their database. Therefore, I found it easier to write my own completely from a modern starting point, and uarite is that thing, done right, as I think. Hopefully this helps you too.
|
||||
Hopefully it helps you too.
|
||||
|
||||
+3
-4
@@ -34,7 +34,6 @@ from user_agent_parser import parse as uap_parse
|
||||
from user_agents import parse as uas_parse
|
||||
|
||||
from uarite import uaparse
|
||||
from uarite.core import _parse_client
|
||||
|
||||
ALL_DOMAINS = (
|
||||
ua_parser.Domain.USER_AGENT | ua_parser.Domain.OS | ua_parser.Domain.DEVICE
|
||||
@@ -284,8 +283,8 @@ def safe(fn):
|
||||
|
||||
def cache_info(name):
|
||||
if name == "uarite":
|
||||
i = _parse_client.cache_info()
|
||||
return f"{i.hits} hits / {i.misses} misses (cap 1024, browsers only)"
|
||||
i = uaparse.cache_info()
|
||||
return f"{i.hits} hits / {i.misses} misses (cap 1024)"
|
||||
if name == "user-agent-parser":
|
||||
from user_agent_parser.parser import _cached_parse_user_agent
|
||||
|
||||
@@ -324,7 +323,7 @@ def bench():
|
||||
):
|
||||
fn = safe(fn)
|
||||
fn("Warmup/1.0 (+https://example.com/warmup)")
|
||||
_parse_client.cache_clear()
|
||||
uaparse.cache_clear()
|
||||
t = timeit.timeit(lambda: [fn(u) for u in work], number=1)
|
||||
res[name] = t / len(work) * 1e6
|
||||
return res, len(work)
|
||||
|
||||
@@ -20,7 +20,7 @@ import matplotlib
|
||||
|
||||
matplotlib.use("Agg")
|
||||
matplotlib.rcParams["svg.fonttype"] = "path" # text as paths: renders anywhere
|
||||
import matplotlib.pyplot as plt
|
||||
import matplotlib.pyplot as plt # noqa: E402
|
||||
|
||||
# µs per cold parse, from scripts/bench.py.
|
||||
US = {
|
||||
|
||||
Reference in New Issue
Block a user