
User-Agent Parsing Done Right
There are plenty of UA parsers for Python: ua-parser is the official Python port of the large upstream project, while user-agents builds on top of it with higher-level device detection. Among newer implementations, user-agent-parser is the most promising and is included here for comparison.
This module takes a smaller, faster, modern approach. It's a dependency-free pure-Python parser weighing only 25 kB, with strong handling of current browsers and crawlers. Despite its light weight, uarite identifies both browsers and crawlers more accurately than any competing implementation tested here.
It returns structured classification, but also the thing most applications eventually need: a short pretty description.
Add it to your project:
uv add uarite
Usage
from uarite import uaparse

r = uaparse("Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/152.0.0.0 Safari/537.36")

r.pretty    # "Chrome/152 Windows"
r.engine    # "Chromium"
r.os        # "Windows"
r.kind      # "browser"
r.url       # ""

r = uaparse("Mozilla/5.0 (Linux; Android 13; Pixel 7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.6885.65 Mobile Safari/537.36; compatible; facebookexternalhit/1.1; +http://www.facebook.com/externalhit_uatext.php")

r.pretty    # "Facebook"
r.kind      # "social"
r.provider  # "Meta"
r.url       # "http://www.facebook.com/externalhit_uatext.php"
Output
uaparse(ua) returns a UA dataclass with string fields. Any field may be empty when the information is unavailable.
| Field | Content |
|---|---|
| pretty | Compact display string; raw UA when unrecognized |
| engine | Chromium, Gecko, Safari, ArkWeb |
| os | Windows, macOS, Linux, iOS, Android, HarmonyOS |
| kind | browser, ai, search, social, analytics, spider |
| url | Crawler information URL |
| provider | Provider of a known crawler family |
The pretty field is intended for UIs and logs. The url can be attached to it as a link when available.
The engine and os fields are intentionally broad. The kind field distinguishes browsers from AI collectors, search engines, social previews, monitoring tools, generic spiders, and ordinary HTTP clients. Any non-browser kind represents automated traffic.
Detection is necessarily limited by what the User-Agent reveals. Crawlers can masquerade as ordinary browsers or other crawlers, so sites that need stronger identification should use additional methods rather than relying on UA detection alone.
Accuracy
The table below compares representative User-Agent formats with ua-parser. user-agents produces nearly identical results and is left out.
| Case | uarite¹ | ua-parser² |
|---|---|---|
| Chrome, Windows | Chrome/152 Windows | Chrome/152 Windows |
| Safari, macOS | Safari/18 macOS | Safari/18 Mac OS X Mac |
| Opera, Linux | Opera/106 Linux | Opera/106 Linux |
| Chrome, Android (no model) | Chrome/152 Android | Chrome Mobile/152 Android K❌ |
| Chrome, Android (Pixel) | Chrome/118 Pixel 6 | Chrome Mobile/118 Android Pixel 6 |
| Edge, Android (model code) | Edge/110 Galaxy S7 | Edge Mobile/110 Android Samsung SM-G930P |
| Firefox, Android | Firefox/154 Android 15 | Firefox Mobile/154 Android Generic Smartphone |
| Safari, iPhone | iPhone iOS 17 | Mobile Safari/17 iOS iPhone |
| Huawei HarmonyOS phone | HuaweiBrowser/6 HarmonyOS | Huawei Browser/6 Android❌ Huawei Browser |
| GPTBot | GPTBot (AI) | GPTBot/1 Spider |
| Googlebot (disguised) | Googlebot (search) | Googlebot/2 Android❌ Spider |
| Facebook preview (disguised) | FacebookBot/1 Android Pixel 7 ❌ | |
| Meta crawler (disguised) | Meta-ExternalAgent (AI) | Chrome/145 Windows ❌ |
| WhatsApp preview | WhatsApp/10 Spider | |
| Bytespider | Bytespider | Bytespider/ Android❌ Generic Smartphone |
| BingPreview | BingPreview | BingPreview/1 Windows❌ Spider |
| AhrefsBot | AhrefsBot | AhrefsBot/7 Spider |
| python-requests | python-requests/2.32.5 | Python Requests/2 |
- ❌ marks an incorrect data such as OS from disquise or Android 10; K (compat) on modern devices
- ¹
r.prettyshown as is - ²
{r.user_agent.family}/{r.user_agent.major} {r.os.family} {r.device.family}
On our modern-browser test set, uarite resolves family, version, and OS at 100%. ua-parser and user-agents score 80%, while user-agent-parser reaches 92%.
Crawler detection was tested against real-world UAs from monperrus/crawler-user-agents. user-agent-parser scored 32%, user-agents 60%, and ua-parser 64%. uarite scores 97%, identifying the specific crawler by name in 80% of cases.
The benchmark and test scripts are available in the repository's scripts folder.
Performance
Import and first parse takes about 10 ms for uarite, compared with 50–90 ms for ua-parser depending on backend.
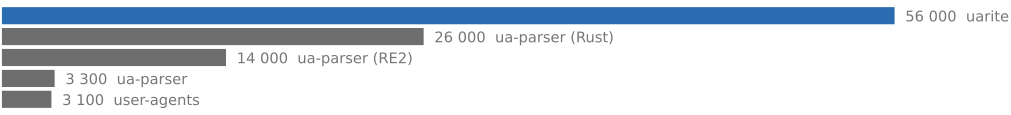 User-Agents parsed per second per CPU core, first parse of unseen strings, with equal shares of browser and crawler UAs. One-off setup costs excluded.
All parsers cache results. With cache hits, uarite reaches about 36 million lookups per second, compared with about 5 million for ua-parser and 600 000 for user-agents.
Why yet another UA parser
Rather than relying on a large historical regex database, the parser focuses on modern UA formats and parses them directly, choosing the most specific interpretation available. This keeps the implementation small while handling today's browsers and crawler traffic well.
Until now, I had been using those other modules and building my own pretty-UA formatting on top of them, fixing by post processing issues the upstream didn't care of.
Eventually it became easier to start over with a parser designed around modern traffic. The result is uarite.
Hopefully it helps you too.