Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 LeoVasanko |
38a10725e0 | ||
|
LeoVasanko
|
8b0c7a7af1 | ||
|
LeoVasanko
|
d01bf1d88f | ||
|
LeoVasanko
|
9b12e53039 | ||
|
LeoVasanko
|
7e2fcc05f6 | ||
|
LeoVasanko
|
ecd5d3bc9e | ||
|
LeoVasanko
|
82d5eb28fb | ||
|
LeoVasanko
|
1149e7cdfd | ||
|
LeoVasanko
|
38f3ccebd3 | ||
|
LeoVasanko
|
c41504e70c | ||
|
LeoVasanko
|
bb70279e61 | ||
|
LeoVasanko
|
931f00f647 | ||
|
LeoVasanko
|
9041061e86 | ||
|
LeoVasanko
|
5fc20c5578 | ||
|
LeoVasanko
|
550131d43b | ||
|
LeoVasanko
|
f2fc6f657f | ||
|
LeoVasanko
|
1477c240a1 | ||
|
LeoVasanko
|
c891bc84a8 | ||
|
LeoVasanko
|
c11cbd4250 | ||
|
LeoVasanko
|
9779857dcd | ||
|
LeoVasanko
|
9ec4f877eb | ||
|
LeoVasanko
|
6a6a012efe | ||
|
LeoVasanko
|
2c28ab1f25 | ||
|
LeoVasanko
|
e6eadb2ecd | ||
|
LeoVasanko
|
ff6b195973 | ||
|
LeoVasanko
|
36e2fdd5ff | ||
|
LeoVasanko
|
8f462b9e1d | ||
|
LeoVasanko
|
838db5b55c | ||
|
LeoVasanko
|
e5300eaac0 | ||
|
LeoVasanko
|
d1f1b9ecb8 | ||
|
LeoVasanko
|
26af7c633b | ||
|
LeoVasanko
|
c072f15cb5 | ||
|
LeoVasanko
|
23030cd1c4 | ||
|
LeoVasanko
|
2a39e1f0ea | ||
|
LeoVasanko
|
d3addadf14 | ||
|
LeoVasanko
|
0a4d54c1b7 | ||
|
LeoVasanko
|
c2776d2e2d | ||
|
LeoVasanko
|
e5bc736ffa | ||
|
LeoVasanko
|
258fc79753 | ||
|
LeoVasanko
|
7a60ef5384 | ||
|
LeoVasanko
|
22454f2d29 | ||
|
LeoVasanko
|
589c789d4d | ||
|
LeoVasanko
|
5f2454d8e8 | ||
|
LeoVasanko
|
2fa15132fb | ||
|
LeoVasanko
|
76cd0224de | ||
|
LeoVasanko
|
b0d13a67a0 | ||
|
LeoVasanko
|
568605b09a |
@@ -0,0 +1,3 @@
|
||||
# Mass lint/format commits that add noise to git blame.
|
||||
# Enable locally with: git config blame.ignoreRevsFile .git-blame-ignore-revs
|
||||
38f3cce # Apply linters and formatters
|
||||
@@ -0,0 +1,77 @@
|
||||
name: release
|
||||
|
||||
on:
|
||||
push:
|
||||
tags:
|
||||
- "v*"
|
||||
|
||||
# Runner host prerequisites: git, uv, node/npm, .NET SDK.
|
||||
jobs:
|
||||
gui-build:
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- os: macos
|
||||
shell: bash
|
||||
- os: windows
|
||||
shell: cmd
|
||||
- os: linux
|
||||
shell: bash
|
||||
runs-on: ${{ matrix.os }}
|
||||
steps:
|
||||
# Plain git clone: full history so setuptools_scm sees tags, and both
|
||||
# shells work. Windows uses cmd: bash resolves to WSL (refuses SYSTEM
|
||||
# accounts) and powershell hits the script execution policy under SYSTEM.
|
||||
- name: Checkout
|
||||
shell: ${{ matrix.shell }}
|
||||
run: |
|
||||
git clone "${{ gitea.server_url }}/${{ gitea.repository }}.git" .
|
||||
git checkout -f "${{ gitea.sha }}"
|
||||
|
||||
# guibuild.py carries its own inline (PEP 723) deps — mediahive[gui]
|
||||
# from the local checkout — so no project sync or --extra is needed.
|
||||
- name: Build GUI app and dist packages
|
||||
shell: ${{ matrix.shell }}
|
||||
run: uv run scripts/guibuild.py
|
||||
|
||||
# Every platform converges on the one release for the tag; release.py
|
||||
# reuses an existing release and skips already-uploaded assets.
|
||||
# Only the linux job publishes the wheel/sdist (identical across platforms).
|
||||
- name: Create Gitea release and upload assets
|
||||
if: matrix.os == 'linux'
|
||||
shell: ${{ matrix.shell }}
|
||||
env:
|
||||
GITEA_TOKEN: ${{ secrets.GITEA_TOKEN }}
|
||||
run: uv run scripts/release.py
|
||||
|
||||
- name: Attach platform artifact to the Gitea release
|
||||
if: matrix.os != 'linux'
|
||||
shell: ${{ matrix.shell }}
|
||||
env:
|
||||
GITEA_TOKEN: ${{ secrets.GITEA_TOKEN }}
|
||||
run: uv run scripts/release.py --no-dist
|
||||
|
||||
# Publish the Python package to PyPI only once every platform's GUI build
|
||||
# has succeeded. Jobs don't share a workspace, so the platform-independent
|
||||
# wheel/sdist are rebuilt here (same tag version) instead of being passed
|
||||
# around as artifacts.
|
||||
publish-pypi:
|
||||
needs: gui-build
|
||||
runs-on: linux
|
||||
steps:
|
||||
- name: Checkout
|
||||
shell: bash
|
||||
run: |
|
||||
git clone "${{ gitea.server_url }}/${{ gitea.repository }}.git" .
|
||||
git checkout -f "${{ gitea.sha }}"
|
||||
|
||||
- name: Build wheel and sdist
|
||||
shell: bash
|
||||
run: uv build
|
||||
|
||||
- name: Publish to PyPI
|
||||
shell: bash
|
||||
env:
|
||||
UV_PUBLISH_TOKEN: ${{ secrets.PYPI_TOKEN }}
|
||||
run: uv publish
|
||||
@@ -19,3 +19,6 @@ package-lock.json
|
||||
# Dotfiles
|
||||
.*
|
||||
!.gitignore
|
||||
!.gitea/
|
||||
!.git-blame-ignore-revs
|
||||
!.pre-commit-config.yaml
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
# MediaHive agent notes
|
||||
|
||||
## Python 3.14 syntax: unparenthesized `except` is valid
|
||||
|
||||
This project targets Python **>= 3.14** (see `requires-python` in
|
||||
`pyproject.toml`). Per [PEP 758](https://peps.python.org/pep-0758/) (Final,
|
||||
Python 3.14), multiple exception types may be caught **without parentheses**:
|
||||
|
||||
```python
|
||||
except OSError, ValueError: # valid Python 3.14+, equivalent to except (OSError, ValueError):
|
||||
```
|
||||
|
||||
Parentheses are still required when an `as` clause is used:
|
||||
`except (OSError, ValueError) as e:`.
|
||||
|
||||
Do not "fix" these into tuple form, and do not flag them as Python 2 remnant
|
||||
syntax errors — that rule is obsolete training data. Any syntax validation,
|
||||
compilation check, or linting of this codebase must run under Python 3.14+
|
||||
(e.g. `python -m py_compile` with a 3.14 interpreter); older interpreters
|
||||
will report false SyntaxErrors on this and other 3.14-only constructs.
|
||||
@@ -1,20 +1,30 @@
|
||||

|
||||
|
||||
|
||||
# MediaHive
|
||||
|
||||
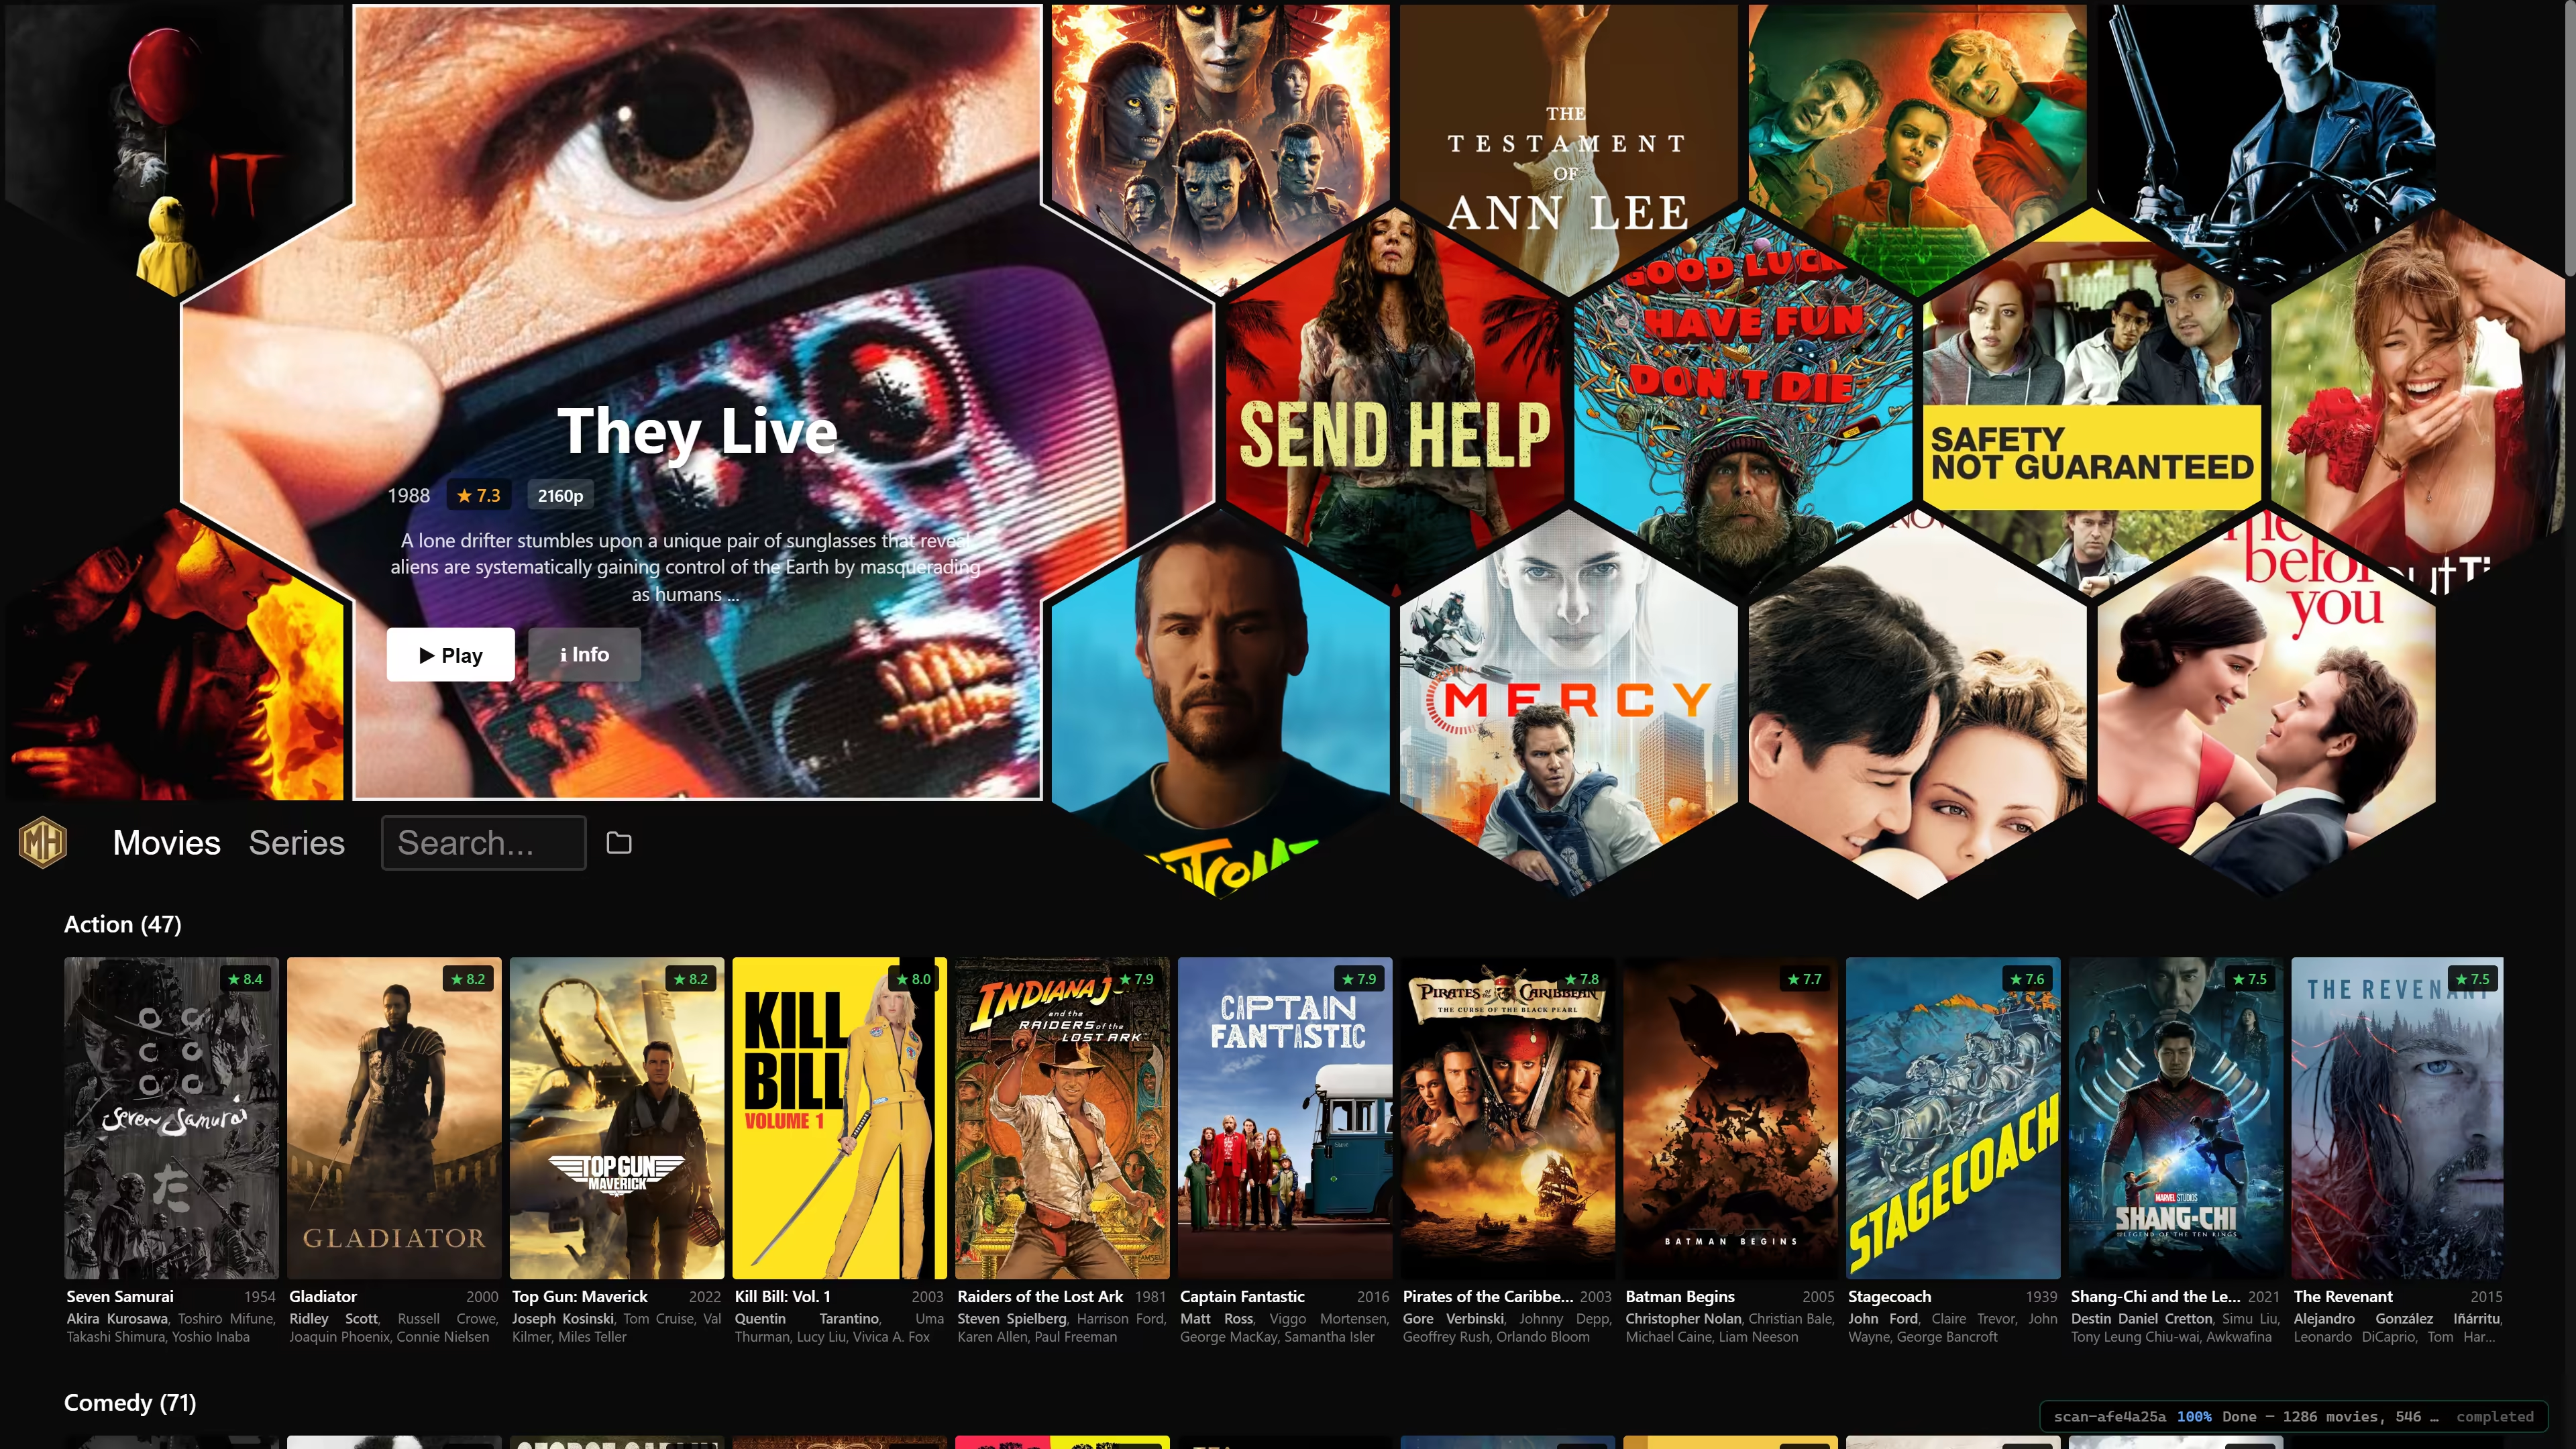
Netflix style browsing of your local media archive. Supports keyboard, mouse and gamepad navigation. Uses your favorite movie player.
|
||||
|
||||
**[Windows and Mac portable ZIP downloads](https://git.zi.fi/LeoVasanko/mediahive/releases)**
|
||||
## Downloads
|
||||
|
||||
- **Windows**: [Installer](https://git.zi.fi/LeoVasanko/mediahive/releases/download/latest/MediaHive-win64-setup.exe) · [Portable ZIP](https://git.zi.fi/LeoVasanko/mediahive/releases/download/latest/MediaHive-win64-portable.zip)
|
||||
- **macOS**: [Installer](https://git.zi.fi/LeoVasanko/mediahive/releases/download/latest/MediaHive-macos.pkg)
|
||||
- **Linux**: [AppImage](https://git.zi.fi/LeoVasanko/mediahive/releases/download/latest/MediaHive-linux.AppImage)
|
||||
|
||||
You may also run or install with [UV](https://docs.astral.sh/uv/getting-started/installation/):
|
||||
|
||||
```
|
||||
uvx --from mediahive[gui] mediahive
|
||||
```
|
||||
|
||||
## What It Does
|
||||
|
||||
- Scans your chosen media folder for all movies and series that can be found
|
||||
- Produces preview video clips and downloads metadata
|
||||
- Search on cast and character names, not just titles
|
||||
- Search on names and other metadata, not just titles
|
||||
- Remembers per-episode playback positions and offers series continue points
|
||||
- Hand off playback to your preferred system player
|
||||
- Implement gamepad controls for MPC-BE on Windows (where needed)
|
||||
|
||||
Extract the ZIP in some place and run MediaHive.exe to start the app. Currently we have no installer, but you can pin to start/taskbar for easier access. On the first startup the app asks for your media folder, that can later be changed by clicking in-app folder icon.
|
||||
On first startup, the app asks for your media folder, which you can later change using the in-app folder icon.
|
||||
|
||||
Note that `.mediahive` folder is created in your media folder to hold all the metadata and preview clips, avoiding the lengthy processing that you will see on initial startup.
|
||||
|
||||
@@ -25,7 +35,7 @@ MediaHive is designed to work with a mouse, keyboard, or gamepad.
|
||||
| Input | Controls |
|
||||
| --- | --- |
|
||||
| Mouse | Click posters, rows, search, play, and folder actions directly. |
|
||||
| Keyboard | Arrow keys move focus, `Enter` activates the focused item, `Escape` goes back, and `/` jumps to search. |
|
||||
| Keyboard | Arrow keys move focus, `Enter` activates the focused item, `Escape` goes back, and `/` or `Ctrl`/`Cmd`+`F` jumps to search. |
|
||||
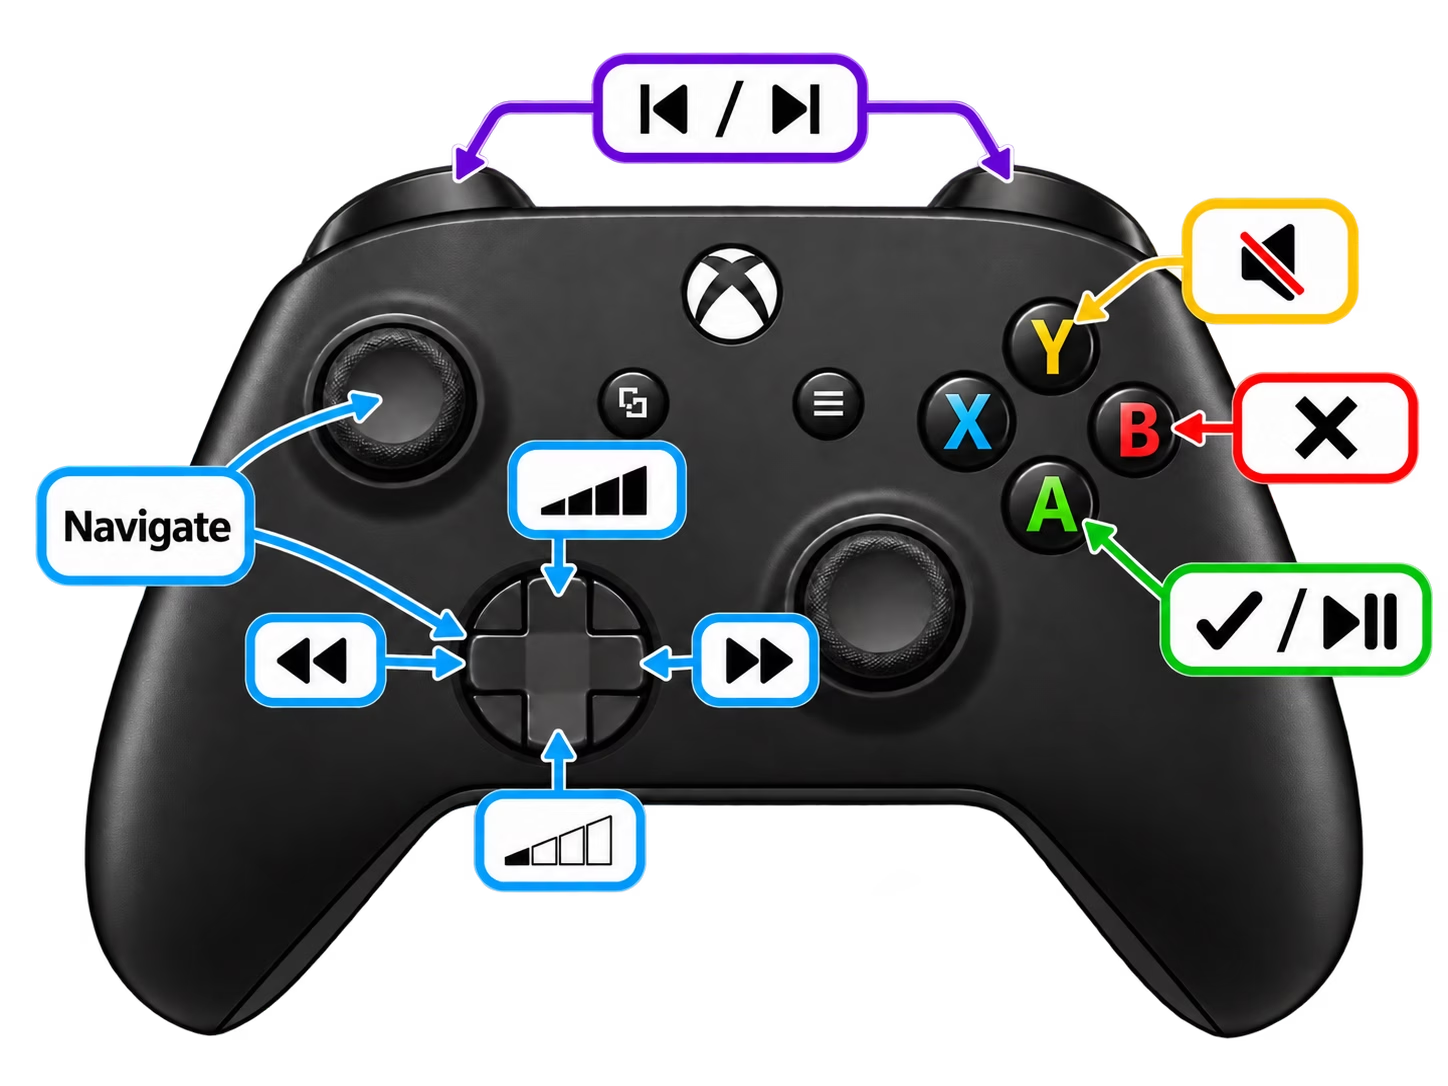
| Gamepad | D-pad or left stick moves focus, `A` selects or plays, and `B` goes back. `RB`/`LB` browses adjacent items, and the Search bar has an OSD keyboard. Player controls during playback. |
|
||||
|
||||
## Recommended Players
|
||||
@@ -36,12 +46,13 @@ MediaHive is designed to work with a mouse, keyboard, or gamepad.
|
||||
|
||||
MediaHive opens files with the OS default player, but one specific player may be configured via settings. You are of course free to use any player instead.
|
||||
|
||||
- `A` toggles play and pause.
|
||||
- `B` closes the player.
|
||||
- `Y` toggles mute.
|
||||
- D-pad up and down change volume.
|
||||
- D-pad left and right seek during playback, or step frames while paused.
|
||||
|
||||
**Gamepad controls are currently available only on MPC-BE, with its WebUI enabled.**
|
||||
|
||||
## Background
|
||||
|
||||
This project started as a personal project that I have used for browsing my warez for some time now. It is still in early development, but I have just now made it public for a wider audience.
|
||||
This project started as a personal project that I have used for browsing my warez for some time now. After it grew in number of users, I've put serious development effort into it to provide a truly polished view, while responding to user needs.
|
||||
|
||||
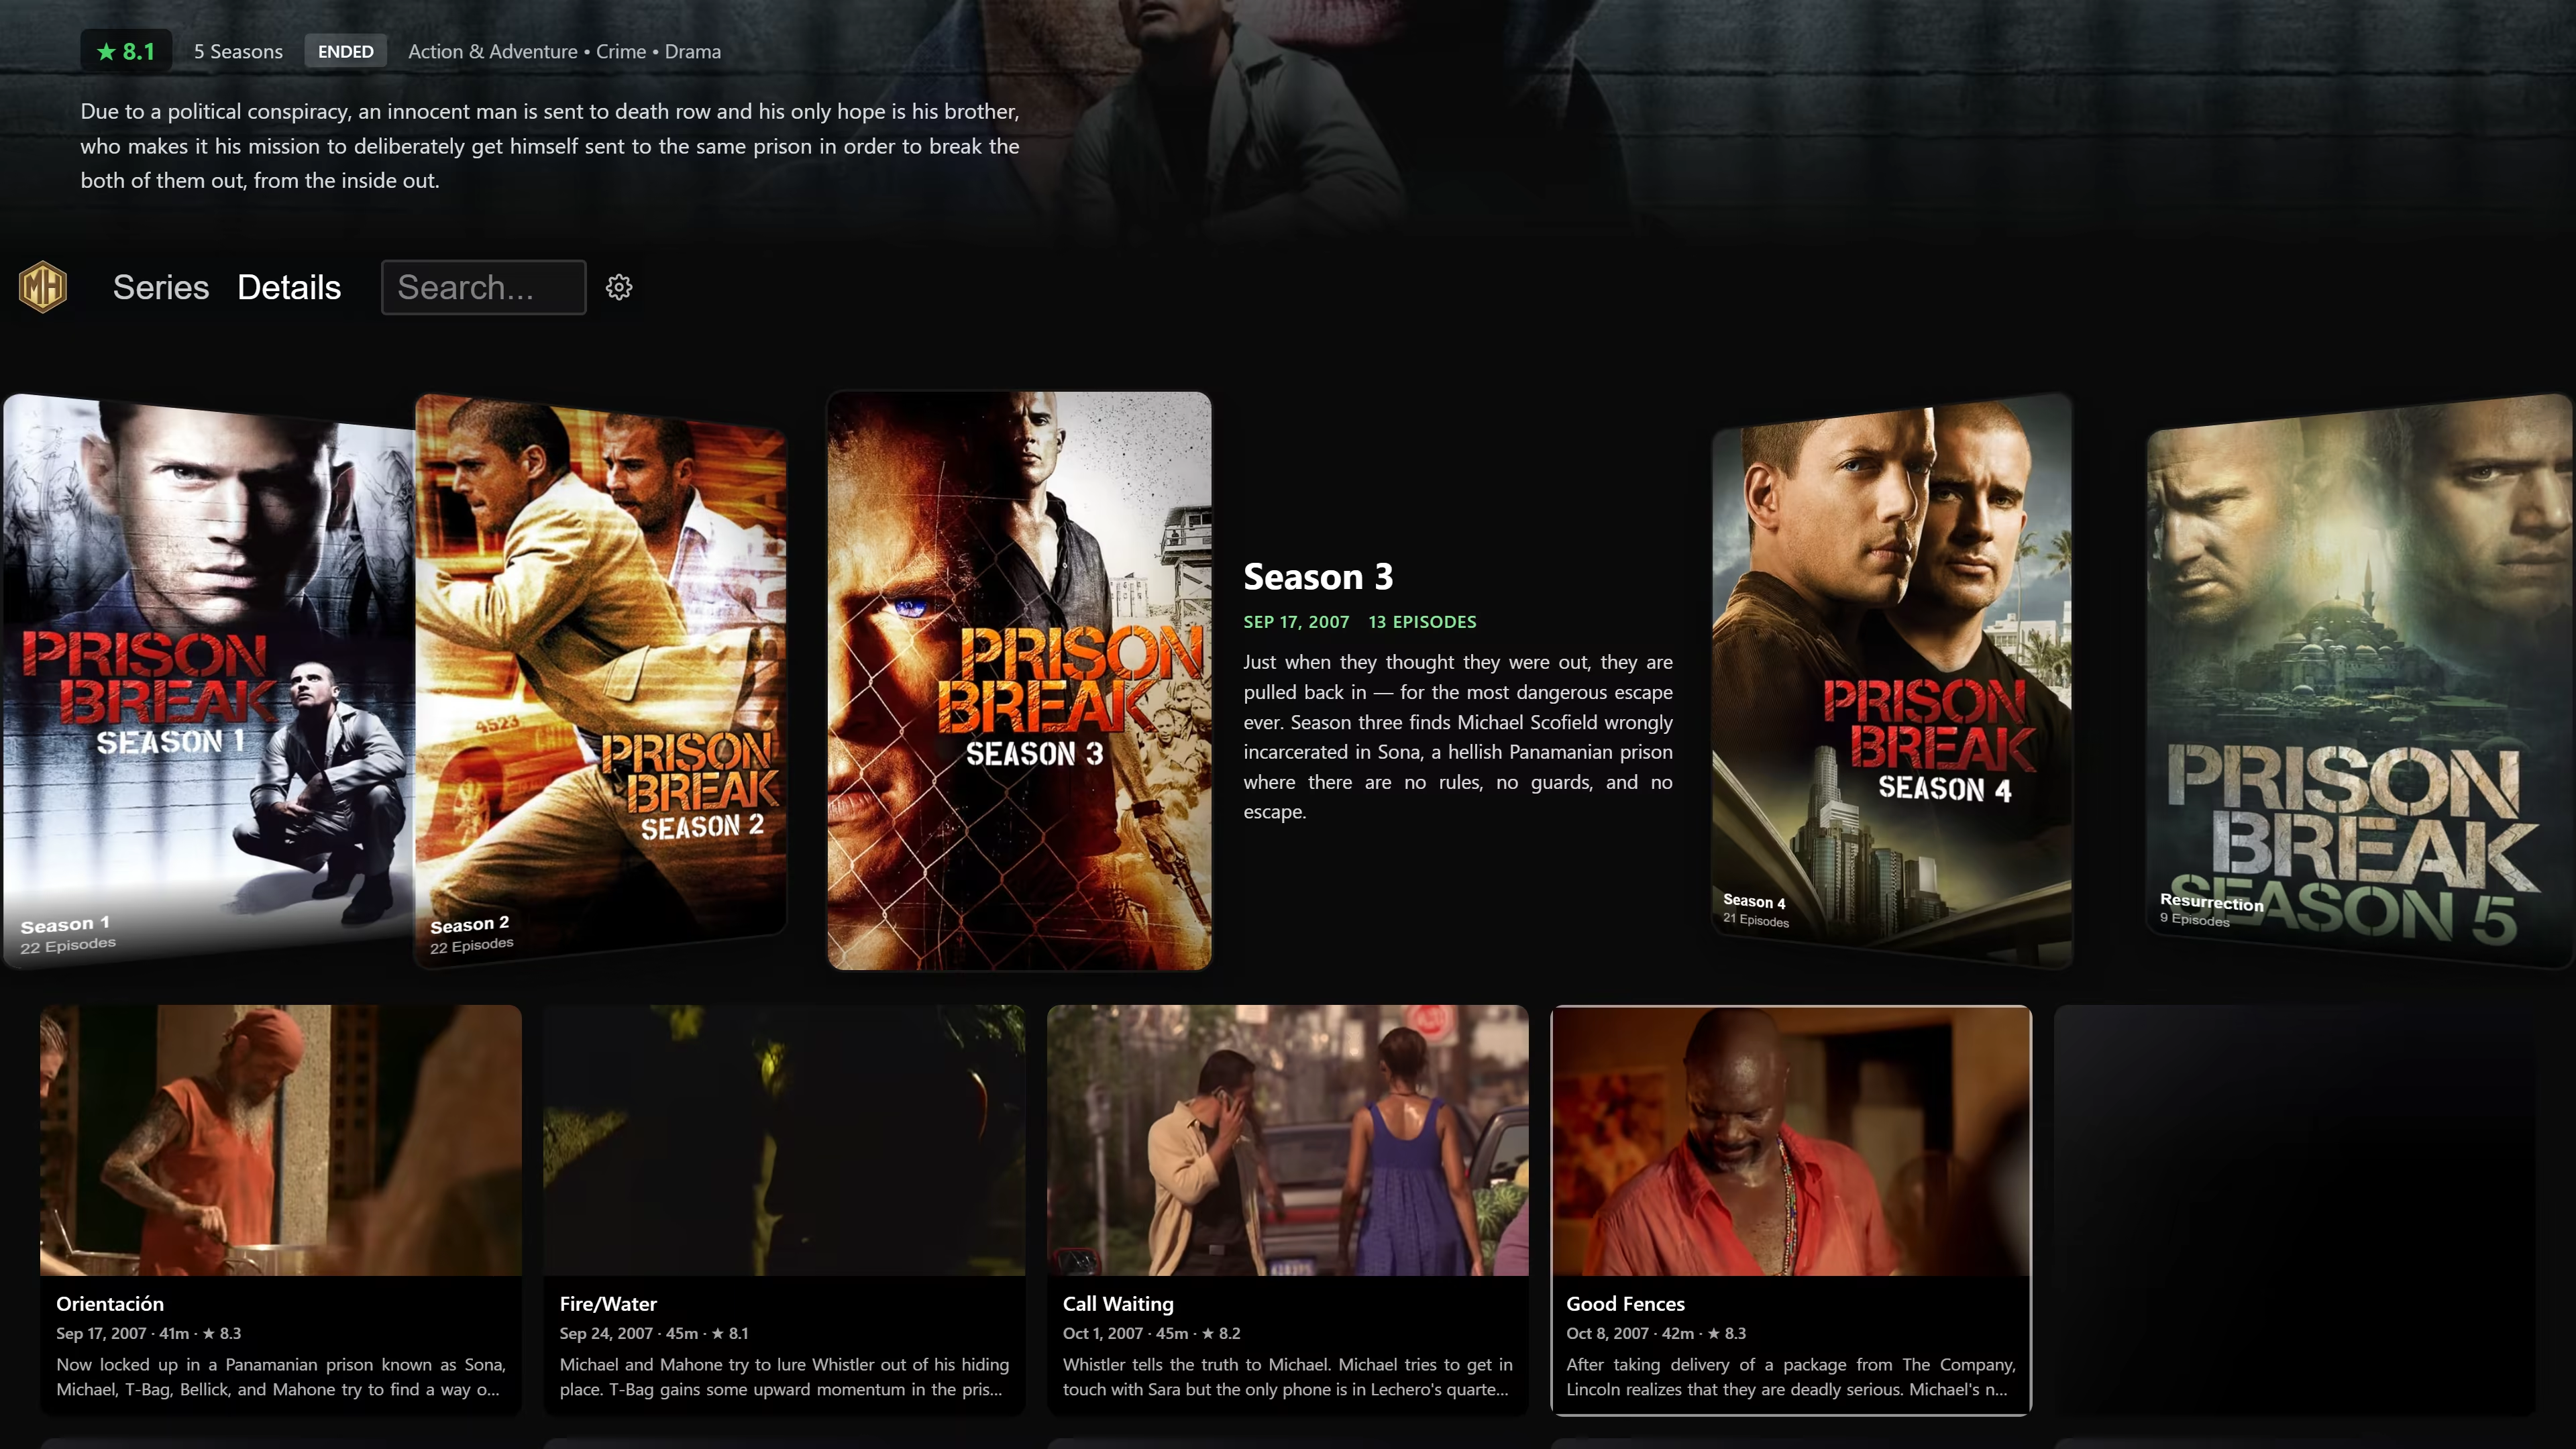
Little details include flags for audio and subtitle languages (also srt) and a series view with per episode video previews while avoiding spoilers of the episodes you haven't gotten to yet:
|
||||
|
||||
|
||||
|
||||
+30
-11
@@ -10,23 +10,42 @@ All media paths are scoped to a **root**, identified by a friendly `root_id`
|
||||
| --- | --- | --- |
|
||||
| `GET` | `/api/health` | Lightweight health check. |
|
||||
| `GET` | `/api/config` | Returns the current root configuration. |
|
||||
| `PUT` | `/api/config/roots` | Atomically replace the full root set. |
|
||||
| `POST` | `/api/play/{root_id}` | Opens a media file with the system player. |
|
||||
| `POST` | `/api/open-folder/{root_id}` | Opens a folder in the system file explorer. |
|
||||
| `GET` | `/api/meta/{root_id}/{meta_key}` | Returns allowed metadata from `<root>/.mediahive`. |
|
||||
| `GET` | `/api/meta/playback-state` | Returns merged resume positions across all roots. |
|
||||
| `GET` | `/api/player/status` | Returns whether remote player control is currently available. |
|
||||
| `GET` | `/api/mpcbe/status` | Reports whether MPC-BE's local web interface is reachable. |
|
||||
| `PUT` | `/api/config/roots` | Atomically replace the full root set. Returns `{ "status": "ok", "accepted": [{path, root_id}], "failed": [...] }`. |
|
||||
| `GET` | `/api/update` | Returns `{ "version", "auto_update", "pending_version" }` — installed version, auto-update preference, and any downloaded update staged for the next launch (Velopack GUI builds only; `null` elsewhere). |
|
||||
| `PUT` | `/api/config/auto-update` | Enable/disable automatic update downloads. Body `{ "enabled": bool }`, persisted in config. |
|
||||
| `POST` | `/api/update/restart` | Applies the staged update and restarts into it. `404` when no update is pending. |
|
||||
| `POST` | `/api/play/{root_id}` | Opens a media file with a media player. Also starts an assumed-playback session (see notes). |
|
||||
| `GET` | `/api/players` | Lists detected media players. Returns `{ "players": [{id, name, family, path}] }`, including synthetic `default` and `custom` entries. |
|
||||
| `POST` | `/api/activity` | Reports user input activity; finalizes any assumed-playback session. Returns `{ "status": "ok", "finalized": bool }`. |
|
||||
| `POST` | `/api/open-folder/{root_id}` | Opens a folder in the system file explorer; given a file path, selects the file instead. |
|
||||
| `GET` | `/api/meta/{root_id}/{meta_key}` | Returns allowed metadata from `<root>/.mediahive`, as `{ "key": meta_key, "data": ... }`. |
|
||||
| `GET` | `/api/meta/playback-state` | Returns merged resume positions across all roots, as `{ "key": "playback-state", "data": ... }`. Series entries carry one continue point per series (`season`/`episode` = last watched) plus a per-episode watch map (`episodes`: `"S<season>E<episode>"` → `{pos, ts, done}`); completing an episode marks it done and advances the point to the next episode. |
|
||||
| `POST` | `/api/meta/playback-state` | Updates one resume entry (`root_id`, `file_path`, `pos`; null `pos` clears a movie or advances a series' continue point). Returns `{ "status": "ok", "slug", "pos" }` plus `season`/`episode` when the continue point advances. |
|
||||
| `GET` | `/api/player/status` | Returns whether remote player control is currently available. Accepts an optional `?port=` override (default 13579). |
|
||||
| `GET` | `/api/mpcbe/status` | Reports whether MPC-BE's local web interface is reachable, as `{ "reachable": true|false }`. Accepts an optional `?port=` override; always `false` on non-Windows. |
|
||||
| `GET` | `/api/media/{root_id}/{file_path:path}` | Serves files from the specified root. |
|
||||
| `GET` | `/api/assets/{root_id}/{asset_type}/{asset_path:path}` | Serves typed assets from `<root>/.mediahive`. |
|
||||
| `WS` | `/api/ws` | Streams roots, index updates, and task progress for all roots. |
|
||||
| `WS` | `/api/ws` | Streams roots, index updates, and task progress for all roots (see WebSocket notes). |
|
||||
|
||||
## Notes
|
||||
|
||||
- `PUT /api/config/roots` accepts `{ "roots": { "name": "/absolute/path", ... } }`, validates paths, and atomically swaps the active set.
|
||||
- `POST /api/play/{root_id}` and `POST /api/open-folder/{root_id}` expect JSON request bodies with `file_path` / `folder_path` relative to the root.
|
||||
- `GET /api/media/{root_id}/{file_path:path}` is constrained to the specified root; path traversal outside the root is rejected.
|
||||
- `POST /api/play/{root_id}` and `POST /api/open-folder/{root_id}` expect JSON request bodies with `file_path` / `folder_path` relative to the root. The play body additionally accepts `player_id` (a value from `GET /api/players`; unknown ids yield 400) and `player_custom_cmd` (command template used when `player_id` is `custom`).
|
||||
- `GET /api/media/{root_id}/{file_path:path}` is constrained to the specified root; path traversal outside the root is rejected. Single-range requests are supported (`206` with `Content-Range`, `416` on invalid ranges), responses carry a weak `ETag` (`If-None-Match` yields `304`) and `Cache-Control: public, max-age=604800, immutable`.
|
||||
- `GET /api/assets/{root_id}/{asset_type}/{asset_path:path}` is constrained to `<root>/.mediahive/{asset_type}` where `asset_type` is one of `movies`, `series`, `people`.
|
||||
- `GET /api/meta/{root_id}/{meta_key}` supports metadata keys currently limited to `playback-state` and `scanignore`.
|
||||
- `GET /api/player/status` returns `{ "remote": true|false }`.
|
||||
- `GET /api/mpcbe/status` returns `false` on non-Windows platforms.
|
||||
- Roots may also be provided at startup via CLI arguments (`mediahive /path/to/media ...`), which are passed to the server through fastapi-vue's env config (`mediahive.config.config`) and override the persisted configuration.
|
||||
- Assumed playback: after `POST /api/play/{root_id}` the launched item is assumed to be playing while the frontend reports no input activity. On the next `POST /api/activity` the guessed position (`resume base + elapsed`, capped at the TMDb runtime) is written once; watches under 5 minutes are discarded (a peek is not progress). A resume entry written by another tracker (e.g. the GUI's MPC-BE tracker) during the session overrides the guess. The MPC-BE tracker likewise ignores sessions shorter than 5 minutes.
|
||||
|
||||
## WebSocket
|
||||
|
||||
`GET /api/ws` sends tagged msgspec JSON messages as binary frames (message shapes are defined in `mediahive/models/protocol.py`):
|
||||
|
||||
- `roots` — full root list and per-root status: `{roots: [{root_id, path, status, error, snapshot_loaded, movies, series}]}`.
|
||||
- `init` — full index payload `{roots: {root_id: {movies, series, people}}}`, re-sent when the root set changes or a snapshot finishes loading.
|
||||
- `upsert` — single item inserted or updated: `{root_id, kind ("movie"|"series"), id, item, people?}`.
|
||||
- `remove` — single item removed: `{root_id, kind, id}`.
|
||||
- `task` — background task progress: `{root_id, data}`.
|
||||
|
||||
Clients must send (any) text frame to keep the receive loop alive.
|
||||
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 121 KiB |
+8
-6
@@ -1,6 +1,6 @@
|
||||
# Development
|
||||
|
||||
This document covers the developer-facing ways to run MediaHive locally. The main [README.md](../README.md) is aimed at Windows end users.
|
||||
This document covers the developer-facing ways to run MediaHive locally. The main [README.md](../README.md) covers end-user startup across platforms (installer/AppImage downloads, `uvx --from mediahive[gui] mediahive` on Linux/other).
|
||||
|
||||
## Requirements
|
||||
|
||||
@@ -40,13 +40,14 @@ uv run --extra gui python -m mediahive.winmain /path/to/media/folder
|
||||
|
||||
This launches the same pywebview-based desktop flow used by the Windows build.
|
||||
|
||||
## Migrate Existing Index Snapshots
|
||||
## Building And Releasing
|
||||
|
||||
```bash
|
||||
uv run python scripts/indexmigr.py /path/to/media/root --write
|
||||
```
|
||||
The helper scripts are directly executable via their `uv run` shebang (on Windows, run them with `uv run scripts/<name>.py`):
|
||||
|
||||
This applies versioned snapshot migrations to `.mediahive/index.json` outside the main application. Use it before starting a newer build against an older index.
|
||||
- `./scripts/guibuild.py` builds the PyInstaller desktop app and packages it with Velopack under `build/`: per-user `Setup.exe` (Windows), `.pkg` installer (macOS), `.AppImage` (Linux), plus the update feed in `build/velopack/`. On Windows it also creates a `-win64-portable.zip` (no auto-updates). Requires node/npm and the .NET SDK (>= 10 runtime) installed on the build host; `vpk` and ffmpeg are downloaded once into a persistent user cache (`~/.cache/mediahive-build`, `%LOCALAPPDATA%\mediahive-build` on Windows).
|
||||
- `./scripts/release.py` publishes a release to the Gitea releases page, uploading the platform artifacts and the Velopack update feed files — installed apps auto-update from the latest release.
|
||||
|
||||
Python packaging builds the frontend automatically through the hatch build hook `scripts/fastapi-vue/buildhook.py` (see `pyproject.toml`), so wheels and sdists always ship a fresh `mediahive/frontend-build`.
|
||||
|
||||
## Notes
|
||||
|
||||
@@ -54,3 +55,4 @@ This applies versioned snapshot migrations to `.mediahive/index.json` outside th
|
||||
- The desktop app remembers the chosen folder between launches.
|
||||
- HTTP and WebSocket endpoints are documented in [API.md](API.md).
|
||||
- MPC-BE integration details (Windows only) live in [mpc-be.md](mpc-be.md).
|
||||
- Scanner/indexer design notes and the v0.5.0 rescan fixes are reviewed in [scanning-review.md](scanning-review.md).
|
||||
|
||||
+3
-1
@@ -611,7 +611,9 @@ Current native command usage is centered on:
|
||||
|
||||
- `889` for play/pause
|
||||
- `816` for exit
|
||||
- `-1&position=HH:MM:SS` for exact 4-second seeking
|
||||
- `-1&position=HH:MM:SS` to seek to the stored resume position when playback starts
|
||||
|
||||
The GUI also polls `/variables.html` for the live position and duration and posts resume positions back to the MediaHive backend (`/api/meta/playback-state`), which is how per-episode resume positions and series continue points are tracked. Sessions shorter than 5 minutes are ignored.
|
||||
|
||||
## Guidance
|
||||
|
||||
|
||||
@@ -0,0 +1,352 @@
|
||||
# Scanner review — findings, fixes, and measured results
|
||||
|
||||
Date: 2026-09-03 (review); fixes implemented same day.
|
||||
Scope: `mediahive/hivescan/*`, `mediahive/index_store.py`, `mediahive/root_registry.py`,
|
||||
`mediahive/models/events.py`
|
||||
Method: code review plus instrumented runs of the real `RootScanner` (monkeypatched
|
||||
timers around every ffmpeg invocation, HTTP request, and filesystem primitive).
|
||||
|
||||
Structure of this document:
|
||||
|
||||
- **Section 1** records the findings as measured against the *pre-fix* code
|
||||
(line references are from that revision).
|
||||
- **Section 2** describes the fixes that were implemented for each finding.
|
||||
- **Section 3** gives before/after measurements.
|
||||
- **Appendix A** (blob storage options) is kept for reference only; it was
|
||||
explicitly decided **not** to change the on-disk storage format for now.
|
||||
|
||||
Test environment (details omitted intentionally): the media library lives on a
|
||||
network-mounted filesystem (SMB/CIFS). Two roots were measured:
|
||||
|
||||
- **Subset root**: 163 torrents (121 movies, 40 series entries), stale/empty index.
|
||||
- **Full library root**: existing index with 1127 movies, 159 series,
|
||||
1608 episodes, ~2983 video files, ~35k people records.
|
||||
|
||||
Environment characteristic that dominates several measurements:
|
||||
`stat`/`scandir`/`exists` on the network mount are ~0.1 ms (attribute caching
|
||||
works), but **every small file write costs ~0.2 s** (synchronous write-through).
|
||||
The scanner writes thousands of small files into `.mediahive/` on that mount.
|
||||
|
||||
---
|
||||
|
||||
## 1. Findings (pre-fix)
|
||||
|
||||
### F1 — Partial rescan replaces whole entries (the "disappearing seasons" bug)
|
||||
|
||||
**This is a correctness bug, not a performance issue.**
|
||||
|
||||
Chain of events:
|
||||
|
||||
1. Discovery mtime-gates per torrent directory/file. Touching one season
|
||||
directory of a series yields a `downloads` list containing *only that
|
||||
season*.
|
||||
2. `_process_series` rebuilds the `Series` object from only the items it was
|
||||
given.
|
||||
3. `IndexStore.upsert_series` **replaced the entire entry** and broadcast the
|
||||
partial series to all connected clients.
|
||||
|
||||
Measured end-to-end on a 5-season series (5 separate season torrents,
|
||||
110 episodes):
|
||||
|
||||
```
|
||||
full scan -> index entry seasons [1,2,3,4,5] (110 episodes)
|
||||
touch season 4 -> rescan 0.2 s, emits ONE upsert: seasons [4] (22 episodes)
|
||||
-> index entry is now seasons [4] — seasons 1-3,5 gone
|
||||
```
|
||||
|
||||
The missing seasons returned only when a scan happened to include all seasons
|
||||
again — in practice the next **process restart**, because the seen-mtimes map
|
||||
(F2) was memory-only and forced a full rediscovery at startup.
|
||||
|
||||
Same bug class, other variants:
|
||||
|
||||
- **Movies**: a touched version directory dropped the other versions of the
|
||||
same movie from the listing.
|
||||
- **TMDb dedupe collapse**: when a partial entry arrived under a *different*
|
||||
item id for an already-known TMDb id, the old **complete** entry was
|
||||
explicitly deleted.
|
||||
- **Deletions were never detected**: discovery only ever added to
|
||||
`_seen_mtimes`; nothing emitted removals. A torrent deleted from disk stayed
|
||||
in the index forever.
|
||||
|
||||
### F2 — No persistent scan state: every restart was a full reprocess
|
||||
|
||||
All scanner state was process memory: `_seen_mtimes`, the ffmpeg probe cache,
|
||||
and the episode/playable-file/bluray-probe caches.
|
||||
|
||||
Consequences measured:
|
||||
|
||||
- **Steady-state rescan within one process: 0.2 s** (subset root, nothing
|
||||
changed) — mtime gating worked fine while the process lived.
|
||||
- **Warm-restart scan (fresh process caches, all disk caches warm): 56.5 s**
|
||||
for the same 163 items, of which **52.9 s (94 %) was re-running ffmpeg probes
|
||||
on all 469 video files** (21 s `ffmpeg -i` + 32 s `showinfo` passes on HDR
|
||||
files). TMDb was 100 % disk-cache hits and cost 0.8 s total.
|
||||
- Scaled to the full library: every application restart re-probed **~2983
|
||||
files ≈ 6–8 minutes** of sequential ffmpeg, during which the whole index was
|
||||
re-derived and re-upserted item by item (see F4).
|
||||
|
||||
### F3 — Preview (showreel) generation: restart storms and infinite retries
|
||||
|
||||
- **Every scan that included an item enqueued all of its reel tasks**, whether
|
||||
or not the reels existed. Existence was only checked later by the serial
|
||||
worker. A full scan of the subset root enqueued **467** tasks; the full
|
||||
library would enqueue ~2700.
|
||||
- **Nothing was persisted about the queue.** A restart before the queue drained
|
||||
started everything over.
|
||||
- **Failures were never recorded.** In the drain test, 3 of 18 movies failed
|
||||
deterministically (DoVi profile 7 titles require `libplacebo` tonemapping,
|
||||
which fails on GPU-less machines; one file has a matroska demux error). The
|
||||
same files were retried on every subsequent drain — ~1.5 s of probing plus
|
||||
crop detection plus an error task broadcast to every client, **forever**.
|
||||
- The reel-existence check required **all five** reels; short videos
|
||||
legitimately produce fewer, so they were treated as "missing" and re-queued
|
||||
on every scan, generating nothing new each time.
|
||||
- Measured generation pace with software AV1 encoding: ~16–28 s per movie
|
||||
(5 clips), ~4–5 s per episode clip.
|
||||
- The reel worker rebroadcast **whole items** built from stale scan data,
|
||||
clobbering newer store state.
|
||||
|
||||
### F4 — Degraded operation while a full scan is in progress
|
||||
|
||||
- Items were re-upserted one by one as processed; combined with F1, any
|
||||
partial rescan interleaved with normal use made listings lose data until the
|
||||
next restart.
|
||||
- The showreel worker broadcast an **error task for every permanent failure on
|
||||
every scan** (F3), producing user-visible noise.
|
||||
- The index snapshot was rewritten every 5 s while dirty; with 1286+ items
|
||||
that is a ~7.5 MB serialize + write per flush, continuously, for the
|
||||
duration of a scan.
|
||||
- `upsert_*` rebuilt the TMDb-id lookup maps on **every** upsert — O(n²) per
|
||||
scan. Measured negligible; fixed anyway as part of the merge work.
|
||||
|
||||
### F5 — Cold-scan cost was serialized small-file I/O, not TMDb
|
||||
|
||||
Cold scan of the subset root: **975 s for 163 items**.
|
||||
|
||||
| Time | Share | Where |
|
||||
|---|---|---|
|
||||
| 763 s | 78 % | `download_cast_profile`: 3494 cast images, strictly serialized; ≈0.22 s each ≈ 0.19 s network-mount write + 0.03 s HTTP |
|
||||
| ~100 s | 10 % | ffmpeg probes (469 files, incl. 83 HDR `showinfo` passes) |
|
||||
| 73 s | 7 % | TMDb API layer: 217 uncached requests (27 s HTTP) **plus ~41 s writing per-request cache JSON files** to the network mount |
|
||||
| ~75 s | 8 % | covers / backdrops / season posters (same small-write cost) |
|
||||
| 0.3 s | — | filesystem discovery walk |
|
||||
|
||||
Notes:
|
||||
|
||||
- The TMDb disk cache itself is fine: once warm it serves 282 requests in
|
||||
0.8 s. Cache *reads* need no optimization.
|
||||
- The full cast of every title was downloaded sequentially, one tiny file per
|
||||
person (the full library has ~35k people records). Re-runs are cheap
|
||||
(exists-check), so this was a cold-scan-only cost — but it made the first
|
||||
scan of a new root take ~8× longer than everything else combined.
|
||||
|
||||
### F6 — Measured as noise (not worth effort)
|
||||
|
||||
- The 30-second rescan loop's tree walk: 3.5–6 s per pass over the full
|
||||
library (~1900 directories). Continuous but light.
|
||||
- `get_directory_size` per torrent: 0.1 s total in the scan.
|
||||
- TMDb disk-cache reads: sub-second per scan.
|
||||
- `trigger_scan` was dead code — nothing called it.
|
||||
- `_seen_mtimes` was updated *before* processing; a cancelled/failed scan
|
||||
permanently lost that update until the next restart.
|
||||
- The in-process probe cache was keyed by path only; a replaced file kept
|
||||
stale probe data until restart.
|
||||
|
||||
---
|
||||
|
||||
## 2. Implemented fixes
|
||||
|
||||
All proposals P1–P5 from the review were implemented, keeping the existing
|
||||
on-disk format unchanged (no blob storage — see Appendix A).
|
||||
|
||||
### F1 → merge-semantics upserts + deletion sync
|
||||
|
||||
- The `Upsert` event now carries `scanned: list[str]` — the media-root-relative
|
||||
torrent paths whose content was (re)scanned to build the item
|
||||
(`mediahive/models/events.py`; `_process_movies`/`_process_series` yield it).
|
||||
- `IndexStore.upsert_movie/upsert_series` (`mediahive/index_store.py`) merge a
|
||||
partial rebuild into the existing entry instead of replacing it:
|
||||
file entries belonging to scanned torrents are replaced, everything else is
|
||||
preserved, episodes/seasons emptied by the merge are dropped, same-episode
|
||||
multi-release files are unioned, and non-None scalar fields from the fresh
|
||||
scan win. The store broadcasts only when the merged result actually changed.
|
||||
- The TMDb dedupe collapse now folds duplicates through the same merge (the
|
||||
complete entry's scalars win), so a partial candidate can no longer delete a
|
||||
complete entry; the reverse TMDb-id map is fixed up incrementally instead of
|
||||
rebuilding both maps per upsert (also F4/P5).
|
||||
- **Deletion sync**: discovery collects the full set of candidate torrent
|
||||
paths; after a fully completed scan the scanner emits a new `Sync` event and
|
||||
`IndexStore.sync_torrent_paths` drops file entries whose torrent path is
|
||||
gone, cascading to empty episodes/seasons/items with proper removals.
|
||||
|
||||
### F2 → persisted scan state and probe cache
|
||||
|
||||
Three small JSON files under `.mediahive/` per root, loaded at scanner start
|
||||
and written atomically (tmp + rename) **only when changed**:
|
||||
|
||||
- `scan-state.json`: relpath → mtime. A restart over an unchanged library now
|
||||
discovers "0 new items" and finishes in walk time. Mtimes are committed
|
||||
**after** the scan completes successfully (fixes the pre-commit nit from F6):
|
||||
a cancelled/failed scan retries its items.
|
||||
- `probe-cache.json`: path → {mtime, size, probe fields} for every probed
|
||||
file, **failures included**. Keying by mtime+size makes it self-invalidating
|
||||
when a file is replaced (also fixes the stale-probe nit from F6). Non-plain
|
||||
paths (bluray:/concat: URIs) fail `stat` and stay memory-cached only.
|
||||
- `reel-state.json`: see F3 below.
|
||||
|
||||
### F3 → reel-state persistence, backoff, and queue gating
|
||||
|
||||
- `reel-state.json` records, per media folder (movies) or per episode
|
||||
(`folder#SxxEyy`), the video's mtime+size, status (`done`/`failed`),
|
||||
attempt count, and last-attempt timestamp.
|
||||
- `_reel_needed` gates both scan-time queueing and the worker:
|
||||
`done` entries are skipped; `failed` entries back off exponentially
|
||||
(6 h → 12 h → … capped at 1 week); entries with no record fall back to a
|
||||
cheap on-disk existence check, and existing reels are silently recorded as
|
||||
`done` so future scans take the cheap path. This ends both the infinite
|
||||
retries of unreadable files and the re-queueing of short videos.
|
||||
- The worker no longer rebroadcasts whole (stale) items: it sends narrow
|
||||
`MovieShowreel` / `EpisodeReel` events, and the store updates only the reel
|
||||
fields of the current entry (`set_movie_showreel` / `set_episode_reel`).
|
||||
- Reel state is persisted at scan finalize, on scanner `stop()`, and as soon
|
||||
as the reel queue drains (a crash between scans no longer loses records).
|
||||
|
||||
### F5 → bounded parallelism for downloads and TMDb fetches
|
||||
|
||||
- Cast-profile downloads: `asyncio.gather` with a semaphore of 8.
|
||||
- TMDb title lookups (movies and series) are prefetched in parallel
|
||||
(semaphore of 4) before the grouping loops, which then read the per-call
|
||||
caches.
|
||||
- Season-detail fetches are prefetched in parallel (semaphore of 4) before the
|
||||
season loop.
|
||||
- Per-item cover/backdrop/poster logic is unchanged (exists-check-fast when
|
||||
warm).
|
||||
|
||||
### Housekeeping (P5)
|
||||
|
||||
- Dead `trigger_scan` removed (`is_scanning` kept).
|
||||
- TMDb-id index bookkeeping is incremental (see F1 above).
|
||||
- `_rebuild_tmdb_indexes` remains only for snapshot load and dedupe.
|
||||
|
||||
---
|
||||
|
||||
## 3. Measured results
|
||||
|
||||
Subset root (163 items, 121 movies / 40 series entries, 469 video files),
|
||||
same network mount:
|
||||
|
||||
| Scenario | Before | After |
|
||||
|---|---|---|
|
||||
| Touch one season of a 5-season series | other 4 seasons vanish until next full scan | 0.3 s rescan, one partial upsert (`scanned=[S04]`), store keeps all 5 seasons |
|
||||
| Steady rescan, nothing changed (same process) | 0.2 s | 0.2 s, 0 upserts, no writes |
|
||||
| Warm restart, unchanged library (fresh process) | 56.5 s (94 % ffmpeg re-probes) + 467 reel tasks queued | **0.2 s, 0 upserts, reel queue 0** |
|
||||
| First scan with warm TMDb cache but no probe cache | 56.5 s | 51.6 s once — writes `probe-cache.json` (469 records, 207 KB); subsequent runs skip all probing |
|
||||
| Permanently unreadable files (3 DoVi/libplacebo movies) | retried on every scan and every startup, error broadcast each time | recorded as failed once, skipped within backoff |
|
||||
| Cold scan, nothing cached | 975 s | not re-measured end-to-end; the dominant terms are now 8-way parallel (cast images: 3494 downloads measured at 3.7 s when warm) |
|
||||
| Deleted torrent | stayed in index forever | removed on the next completed scan via `Sync` |
|
||||
|
||||
Unit-level checks (synthetic `IndexStore` + scanner state, no filesystem
|
||||
library involved): partial upsert preserves untouched seasons and replaces
|
||||
rescanned torrent files; multi-release episode union; sync removal cascades;
|
||||
single-episode reel updates; probe-cache save/load roundtrip; reel backoff
|
||||
math; reel-state persistence roundtrip across scanner instances.
|
||||
|
||||
---
|
||||
|
||||
## Appendix A — Blob storage options: scan-time vs runtime concerns
|
||||
|
||||
**Status: reference only — not implemented.** The current on-disk format
|
||||
(one file per artifact) was deliberately kept. This appendix stays as
|
||||
documentation of the options if write amplification or file counts ever
|
||||
become an operational issue.
|
||||
|
||||
The two concerns have opposite constraints, so they should be decided
|
||||
separately:
|
||||
|
||||
- **Scan-time data** is written and read only by the scanner. Nothing in the
|
||||
server serves it. Storage format is therefore a pure implementation detail
|
||||
and can be changed freely.
|
||||
- **Runtime data** is delivered to the frontend as plain files via
|
||||
`/api/assets/{root}/{movies|series|people}/{path}` (covers, posters,
|
||||
backdrops, person photos) and `/api/media/{root}/{path}` (media files), with
|
||||
etag/range streaming. Anything that replaces files here must keep an HTTP
|
||||
serving story working.
|
||||
|
||||
### A.1 Artifact inventory (measured)
|
||||
|
||||
| Artifact | Class | Avg size | Count (full library) | Total | Written |
|
||||
|---|---|---|---|---|---|
|
||||
| TMDb response cache JSON | scan-time | 25 KB (median 9 KB) | ~8,500 | ~215 MB | on every uncached API request |
|
||||
| Probe results / scan state / reel state | scan-time | ~0.5 KB/record | ~3,000 records | ~1.5 MB | per processed file |
|
||||
| Person photos | runtime | 11.4 KB | ~22,500 | ~262 MB | once per person |
|
||||
| `cover.jpg` / season posters | runtime | ~77 KB | ~2,100 | ~164 MB | once per title/season |
|
||||
| `backdrop.jpg` | runtime | ~147 KB | ~1,460 | ~220 MB | once per title |
|
||||
| Reel clips (WebM/AV1) | runtime | ~450 KB | ~8,700 | ~4.0 GB | once per title/episode |
|
||||
| `index.json` snapshot | both | 7.5 MB | 1 | 7.5 MB | debounced, only when dirty |
|
||||
|
||||
Reference point for the write-amplification math: on the network mount one
|
||||
small-file write costs ~0.2 s, while a single 7.5 MB sequential write costs
|
||||
the same ~0.2 s (~40 MB/s). So ~31,000 tiny files ≈ 1.7 hours of serialized
|
||||
write time, versus ~6 s for the same bytes as one bulk dump.
|
||||
|
||||
### A.2 Scan-time blob store (TMDb cache, probe cache, scan state)
|
||||
|
||||
Nothing here is served, so the only requirement is fast lookup + cheap
|
||||
persistence. Two workable shapes:
|
||||
|
||||
- **RAM map + debounced atomic dump.** Plain dicts keyed by request hash /
|
||||
file path, dumped as one binary file (length-prefixed msgspec or JSON blob,
|
||||
optionally zstd-compressed) with tmp-write + rename, on the same
|
||||
dirty-flag + debounce discipline `index.json` already uses. Effects: the
|
||||
~8,500 individual cache writes collapse into a handful of bulk flushes;
|
||||
warm lookups become dict hits with zero filesystem calls. TMDb JSON
|
||||
compresses ~10× (215 MB → ~20–25 MB), so a full dump is a sub-second write.
|
||||
Caveat: holding all responses parsed in RAM costs ~200 MB for the full
|
||||
library; storing raw response *bytes* and parsing lazily, or capping to
|
||||
entries referenced by known index items, keeps this modest.
|
||||
- **SQLite (stdlib, WAL mode).** One database file, incremental commits, crash
|
||||
safety without full dumps, and kernel page cache instead of explicit RAM
|
||||
management. Better fit if the cache is allowed to grow unbounded, at the
|
||||
price of slightly more code.
|
||||
|
||||
Either way, keep the existing cache *semantics* unchanged: cache HTTP-level
|
||||
failures, never cache network errors. With persisted scan state in place the
|
||||
TMDb cache becomes write-rarely (new items only), which further lowers the
|
||||
value of elaborate engineering here — the simple dump is likely enough.
|
||||
|
||||
### A.3 Runtime-served artifacts
|
||||
|
||||
- **Reels, covers, backdrops, season posters: keep as files.** They are few
|
||||
per title, tens-to-hundreds of KB, written exactly once, and benefit from
|
||||
the existing etag/range file serving. No write-amplification problem.
|
||||
- **Person photos** (~22.5k files × 11.4 KB) are the one runtime class where
|
||||
tiny files hurt at scan time. Three options, in increasing invasiveness:
|
||||
1. **Keep files, fix only the scan-time behavior** — bounded-parallel
|
||||
downloads, optionally capped to top-N billed cast. Zero changes to
|
||||
serving; the cold-scan cost drops ~8× but the file count stays.
|
||||
*(This is the option currently implemented.)*
|
||||
2. **Blob db + serve from the db.** Person photos move into the same store
|
||||
as above; the assets handler gains one branch for the `people` asset
|
||||
type that streams bytes from the db instead of the filesystem.
|
||||
Eliminates all 22.5k tiny files. If full RAM residency (262 MB) is
|
||||
undesirable, use SQLite and let the page cache handle it.
|
||||
3. **Hybrid lazy materialization.** The db is authoritative at scan time
|
||||
(no tiny writes during scans); the assets handler writes the photo to the
|
||||
conventional path on first request and serves it as a file thereafter.
|
||||
Serving logic and URLs stay unchanged; disk usage appears only for
|
||||
people actually viewed.
|
||||
|
||||
Note that `index.json` itself is already the right shape: one atomic 7.5 MB
|
||||
file, rewritten only when dirty. The goal for everything else is simply to
|
||||
reach the same shape per concern.
|
||||
|
||||
### A.4 Recommendation (if revisited)
|
||||
|
||||
| Concern | Recommended treatment |
|
||||
|---|---|
|
||||
| TMDb response cache | RAM map + debounced single-file dump (SQLite if growth matters) |
|
||||
| Probe cache, seen-mtimes, reel-failure records | same dump mechanism, separate small files *(currently: three small JSON files, written only when dirty)* |
|
||||
| Person photos | option 1 now (parallel + lazy fetching); option 2 or 3 if file count becomes an operational issue |
|
||||
| Covers, posters, backdrops, reels | unchanged — plain files |
|
||||
| `index.json` | unchanged |
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 303 KiB |
+130
-171
@@ -11,12 +11,19 @@
|
||||
<span>Library activity</span>
|
||||
<span v-if="!wsConnected" class="activity-connection">Reconnecting...</span>
|
||||
</div>
|
||||
<div v-for="root in progressRoots" :key="root.rootId" class="activity-root" :class="root.toneClass">
|
||||
<div
|
||||
v-for="root in progressRoots"
|
||||
:key="root.rootId"
|
||||
class="activity-root"
|
||||
:class="root.toneClass"
|
||||
>
|
||||
<div class="activity-root-title">{{ root.rootLabel }}</div>
|
||||
<div v-if="root.scanTarget" class="activity-root-target">{{ root.scanTarget }}</div>
|
||||
<div class="activity-phase-row">
|
||||
<span class="activity-phase">{{ root.phaseLabel }}</span>
|
||||
<span v-if="root.progressLabel" class="activity-progress-label">{{ root.progressLabel }}</span>
|
||||
<span v-if="root.progressLabel" class="activity-progress-label">{{
|
||||
root.progressLabel
|
||||
}}</span>
|
||||
</div>
|
||||
<div class="activity-bar" :class="{ 'activity-bar-indeterminate': !root.isDeterminate }">
|
||||
<div
|
||||
@@ -38,6 +45,9 @@
|
||||
:current-view="headerCurrentView"
|
||||
:search-query="searchQuery"
|
||||
:roots="headerRoots"
|
||||
:scan-tasks="tasks"
|
||||
:scan-connected="wsConnected"
|
||||
:initial-scan-mode="isInitialScanMode"
|
||||
:mpc-be-connected="mpcBeConnected"
|
||||
:nav-row="1"
|
||||
:position="headerPosition"
|
||||
@@ -177,6 +187,8 @@
|
||||
:all-movies="mediaIndex?.movies ?? []"
|
||||
:focus-episode="focusEpisode"
|
||||
:has-resume-position="hasResumePosition"
|
||||
:get-resume-point="getResumePoint"
|
||||
:get-resume-episodes="getResumeEpisodes"
|
||||
:get-root-name="getRootName"
|
||||
@close="closeDetail"
|
||||
@play="handlePlay"
|
||||
@@ -200,7 +212,7 @@ import type {
|
||||
SeriesUi,
|
||||
MediaItem,
|
||||
EpisodeWithSeries,
|
||||
TaskInfo,
|
||||
SeriesResumePoint,
|
||||
} from "./types"
|
||||
import {
|
||||
playMedia,
|
||||
@@ -208,10 +220,18 @@ import {
|
||||
isMpcBeReachable,
|
||||
fetchResumePositions,
|
||||
getPlayerStatus,
|
||||
type ResumePositionEntry,
|
||||
type EpisodeWatchEntry,
|
||||
} from "./api"
|
||||
import { useSettings } from "./composables/useSettings"
|
||||
import { useKeyboardNavigation, setActiveNavigationScope } from "./composables/useKeyboardNavigation"
|
||||
import {
|
||||
useKeyboardNavigation,
|
||||
setActiveNavigationScope,
|
||||
} from "./composables/useKeyboardNavigation"
|
||||
import type { SyncedRowScrollSnapshot } from "./composables/useKeyboardNavigation"
|
||||
import { useMediaWebSocket } from "./composables/useMediaWebSocket"
|
||||
import { computeProgressRoots, type RootTaskInfo } from "./composables/useScanProgress"
|
||||
import { useSettingsOpen } from "./composables/useSettingsOpen"
|
||||
import Header from "./components/Header.vue"
|
||||
import CollageHero from "./components/CollageHero.vue"
|
||||
import MediaRow from "./components/MediaRow.vue"
|
||||
@@ -219,7 +239,13 @@ import MediaDetail from "./components/MediaDetail.vue"
|
||||
import type { SearchResultItem, SearchResponseMessage } from "./search-worker"
|
||||
|
||||
// Initialize keyboard navigation
|
||||
const { getFocusState, restoreFocusState, focusElement } = useKeyboardNavigation()
|
||||
const {
|
||||
getFocusState,
|
||||
restoreFocusState,
|
||||
focusElement,
|
||||
snapshotSyncedRowScroll,
|
||||
restoreSyncedRowScroll,
|
||||
} = useKeyboardNavigation()
|
||||
|
||||
const router = useRouter()
|
||||
const route = useRoute()
|
||||
@@ -270,20 +296,6 @@ const {
|
||||
roots: rootStatuses,
|
||||
} = useMediaWebSocket()
|
||||
|
||||
type RootTaskInfo = TaskInfo & { root_id: string }
|
||||
|
||||
interface ProgressRootState {
|
||||
rootId: string
|
||||
rootLabel: string
|
||||
scanTarget: string | null
|
||||
phaseLabel: string
|
||||
phaseDetail: string | null
|
||||
progressPercent: number
|
||||
progressLabel: string | null
|
||||
isDeterminate: boolean
|
||||
toneClass: string
|
||||
}
|
||||
|
||||
const activeTasks = computed<RootTaskInfo[]>(() => Array.from(tasks.value.values()))
|
||||
|
||||
function getRootName(rootId: string | null | undefined): string | null {
|
||||
@@ -291,131 +303,15 @@ function getRootName(rootId: string | null | undefined): string | null {
|
||||
return rootStatuses.value.get(rootId)?.root_id || null
|
||||
}
|
||||
|
||||
function normalizePosixPath(value: string): string {
|
||||
return value.replace(/\\/g, "/")
|
||||
}
|
||||
const progressRoots = computed(() =>
|
||||
computeProgressRoots(
|
||||
activeTasks.value,
|
||||
(rootId) => rootStatuses.value.get(rootId)?.path || null,
|
||||
isInitialScanMode.value,
|
||||
),
|
||||
)
|
||||
|
||||
function extractScanPath(detail: string): string | null {
|
||||
if (!detail.startsWith("Scanning:")) return null
|
||||
let value = detail.replace(/^Scanning:\s*/i, "").trim()
|
||||
value = value.replace(/\s*\(\d+\s+found\)\s*$/i, "").trim()
|
||||
return value || null
|
||||
}
|
||||
|
||||
function buildScanTarget(rootId: string, rootPath: string | null, detail: string): string | null {
|
||||
const rawPath = extractScanPath(detail)
|
||||
if (!rawPath) return null
|
||||
|
||||
const posixRaw = normalizePosixPath(rawPath)
|
||||
const posixRoot = rootPath ? normalizePosixPath(rootPath) : null
|
||||
|
||||
let relative = posixRaw
|
||||
if (posixRoot) {
|
||||
const lowRaw = posixRaw.toLowerCase()
|
||||
const lowRoot = posixRoot.toLowerCase()
|
||||
if (lowRaw === lowRoot) {
|
||||
relative = ""
|
||||
} else if (lowRaw.startsWith(`${lowRoot}/`)) {
|
||||
relative = posixRaw.slice(posixRoot.length).replace(/^\/+/, "")
|
||||
}
|
||||
}
|
||||
|
||||
if (!relative) return rootId
|
||||
if (relative.toLowerCase().startsWith(`${rootId.toLowerCase()}/`)) return relative
|
||||
return `${rootId}/${relative}`
|
||||
}
|
||||
|
||||
function describeRootProgress(
|
||||
rootId: string,
|
||||
rootPath: string | null,
|
||||
tasksForRoot: RootTaskInfo[],
|
||||
isInitialScanMode: boolean,
|
||||
): ProgressRootState | null {
|
||||
const running = tasksForRoot.filter((task) => task.status === "running")
|
||||
const latestError = [...tasksForRoot].reverse().find((task) => task.status === "error") || null
|
||||
|
||||
if (running.length === 0 && !latestError) return null
|
||||
|
||||
const scanTask = running.find((task) => task.id.startsWith("scan-")) || null
|
||||
const showreelCount = running.filter((task) => task.id.startsWith("showreel-")).length
|
||||
const otherRunningCount = running.length - (scanTask ? 1 : 0) - showreelCount
|
||||
|
||||
let phaseLabel = "Processing media"
|
||||
let phaseDetail: string | null = null
|
||||
let scanTarget: string | null = null
|
||||
let isDeterminate = false
|
||||
let progressPercent = 0
|
||||
let progressLabel: string | null = null
|
||||
let toneClass = ""
|
||||
|
||||
if (scanTask) {
|
||||
const detail = (scanTask.detail || "").trim()
|
||||
scanTarget = buildScanTarget(rootId, rootPath, detail)
|
||||
if (detail.startsWith("Scanning:")) {
|
||||
phaseLabel = isInitialScanMode ? "Scanning folders" : "Checking for updates"
|
||||
phaseDetail = isInitialScanMode ? "Looking for new files" : "Running background scan"
|
||||
} else if (/^Processing\s+\d+\s+(items|movies|series)/i.test(detail)) {
|
||||
phaseLabel = "Preparing titles"
|
||||
phaseDetail = "Matching files and grouping releases"
|
||||
} else {
|
||||
phaseLabel = "Fetching metadata"
|
||||
phaseDetail = detail ? `Current title: ${detail}` : "Updating titles and artwork"
|
||||
}
|
||||
if (scanTask.progress > 0 && scanTask.progress <= 1) {
|
||||
isDeterminate = true
|
||||
progressPercent = Math.max(1, Math.round(scanTask.progress * 100))
|
||||
progressLabel = `${progressPercent}%`
|
||||
}
|
||||
} else if (showreelCount > 0) {
|
||||
phaseLabel = "Generating previews"
|
||||
phaseDetail = showreelCount === 1 ? "Building 1 preview reel" : `Building ${showreelCount} preview reels`
|
||||
} else if (otherRunningCount > 0) {
|
||||
phaseLabel = "Finalizing updates"
|
||||
phaseDetail = "Applying library changes"
|
||||
} else if (latestError) {
|
||||
phaseLabel = "Needs attention"
|
||||
phaseDetail = latestError.detail || "A background task failed"
|
||||
toneClass = "activity-root-error"
|
||||
}
|
||||
|
||||
if (showreelCount > 0 && scanTask) {
|
||||
phaseDetail = phaseDetail
|
||||
? `${phaseDetail}. Preview generation is running in parallel.`
|
||||
: "Preview generation is running in parallel"
|
||||
}
|
||||
|
||||
return {
|
||||
rootId,
|
||||
rootLabel: rootId,
|
||||
scanTarget,
|
||||
phaseLabel,
|
||||
phaseDetail,
|
||||
progressPercent,
|
||||
progressLabel,
|
||||
isDeterminate,
|
||||
toneClass,
|
||||
}
|
||||
}
|
||||
|
||||
const progressRoots = computed<ProgressRootState[]>(() => {
|
||||
const byRoot = new Map<string, RootTaskInfo[]>()
|
||||
for (const task of activeTasks.value) {
|
||||
const list = byRoot.get(task.root_id) || []
|
||||
list.push(task)
|
||||
byRoot.set(task.root_id, list)
|
||||
}
|
||||
|
||||
const rows: ProgressRootState[] = []
|
||||
const initial = isInitialScanMode.value
|
||||
for (const [rootId, rootTasks] of byRoot) {
|
||||
const rootPath = rootStatuses.value.get(rootId)?.path || null
|
||||
const row = describeRootProgress(rootId, rootPath, rootTasks, initial)
|
||||
if (row) rows.push(row)
|
||||
}
|
||||
return rows.sort((a, b) => a.rootLabel.localeCompare(b.rootLabel))
|
||||
})
|
||||
|
||||
const isSettingsView = computed(() => route.path === "/settings")
|
||||
const isSettingsView = useSettingsOpen()
|
||||
const hasLibraryItems = computed(() => {
|
||||
if (!mediaIndex.value) return false
|
||||
return mediaIndex.value.movies.length > 0 || mediaIndex.value.series.length > 0
|
||||
@@ -430,10 +326,8 @@ const headerRoots = computed(() =>
|
||||
)
|
||||
|
||||
const showProgressPanel = computed(() => {
|
||||
if (isInitialScanMode.value) {
|
||||
return !wsConnected.value || progressRoots.value.length > 0
|
||||
}
|
||||
if (!isSettingsView.value) return false
|
||||
if (isSettingsView.value) return false
|
||||
if (!isInitialScanMode.value) return false
|
||||
return !wsConnected.value || progressRoots.value.length > 0
|
||||
})
|
||||
|
||||
@@ -460,7 +354,11 @@ watch(
|
||||
const key = `${task.root_id}:${task.id}`
|
||||
nextSeen.set(key, task.status)
|
||||
const previousStatus = seenTaskStates.get(key)
|
||||
if (task.id.startsWith("scan-") && task.status === "completed" && previousStatus !== "completed") {
|
||||
if (
|
||||
task.id.startsWith("scan-") &&
|
||||
task.status === "completed" &&
|
||||
previousStatus !== "completed"
|
||||
) {
|
||||
const detail = (task.detail || "").trim()
|
||||
const doneMatch = detail.match(/^Done\s+[\u2014-]\s+(\d+)\s+movies,\s+(\d+)\s+series$/i)
|
||||
if (doneMatch) {
|
||||
@@ -468,7 +366,9 @@ watch(
|
||||
const series = Number(doneMatch[2] || "0")
|
||||
if (movies > 0 || series > 0) {
|
||||
const rootName = getRootName(task.root_id) || task.root_id
|
||||
showLibraryUpdateToast(`Library updated in ${rootName}: ${movies} movies, ${series} series`)
|
||||
showLibraryUpdateToast(
|
||||
`Library updated in ${rootName}: ${movies} movies, ${series} series`,
|
||||
)
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -490,7 +390,7 @@ const settings = useSettings()
|
||||
const searchResults = ref<MediaItem[]>([])
|
||||
const isSearching = ref(false)
|
||||
const mpcBeConnected = ref(false)
|
||||
const resumePositions = ref<Record<string, number>>({})
|
||||
const resumePositions = ref<Record<string, ResumePositionEntry>>({})
|
||||
const searchQuery = ref(getRouteSearchQuery())
|
||||
const searchReturnPath = ref<string | null>(null)
|
||||
const browsePanelRef = ref<HTMLElement | null>(null)
|
||||
@@ -533,6 +433,10 @@ async function refreshResumePositions() {
|
||||
resumePositions.value = await fetchResumePositions()
|
||||
}
|
||||
|
||||
function refreshResumePositionsAsEvent() {
|
||||
void refreshResumePositions()
|
||||
}
|
||||
|
||||
async function refreshPlayerStatus() {
|
||||
if (!isMpcFamilySelected()) {
|
||||
mpcBeConnected.value = false
|
||||
@@ -548,7 +452,23 @@ async function refreshPlayerStatus() {
|
||||
|
||||
function hasResumePosition(mediaId: string | null) {
|
||||
if (!mediaId) return false
|
||||
return Number(resumePositions.value[mediaId] || 0) > 0
|
||||
return (resumePositions.value[mediaId]?.pos || 0) > 0
|
||||
}
|
||||
|
||||
function getResumePoint(mediaId: string | null): SeriesResumePoint | null {
|
||||
if (!mediaId) return null
|
||||
const entry = resumePositions.value[mediaId]
|
||||
if (!entry || entry.season === null || entry.episode === null) return null
|
||||
return {
|
||||
seasonNumber: entry.season,
|
||||
episodeNumber: entry.episode,
|
||||
positionSeconds: entry.pos,
|
||||
}
|
||||
}
|
||||
|
||||
function getResumeEpisodes(mediaId: string | null): Record<string, EpisodeWatchEntry> | null {
|
||||
if (!mediaId) return null
|
||||
return resumePositions.value[mediaId]?.episodes ?? null
|
||||
}
|
||||
|
||||
function startMpcBePolling() {
|
||||
@@ -641,7 +561,9 @@ function showAdjacentDetail(offset: -1 | 1): boolean {
|
||||
const sequence = getDetailAdjacentSequence(current)
|
||||
if (sequence.length < 2) return false
|
||||
|
||||
const currentIndex = sequence.findIndex((item) => item.id === current.id && item.type === current.type)
|
||||
const currentIndex = sequence.findIndex(
|
||||
(item) => item.id === current.id && item.type === current.type,
|
||||
)
|
||||
if (currentIndex < 0) return false
|
||||
|
||||
const nextIndex = currentIndex + offset
|
||||
@@ -674,6 +596,23 @@ const searchCategories = ref<{ name: string; items: MediaItem[] }[]>([])
|
||||
const focusStateMap = new Map<string, { row: number; col: number }>()
|
||||
// Track the last viewed item ID to restore focus to the right card
|
||||
const lastViewedItemId = ref<string | null>(null)
|
||||
let browseScrollSnapshot: { panelTop: number; rows: SyncedRowScrollSnapshot } | null = null
|
||||
|
||||
function captureBrowseScrollSnapshot() {
|
||||
browseScrollSnapshot = {
|
||||
panelTop: browsePanelRef.value?.scrollTop ?? 0,
|
||||
rows: snapshotSyncedRowScroll(),
|
||||
}
|
||||
}
|
||||
|
||||
function restoreBrowseScrollSnapshot() {
|
||||
if (!browseScrollSnapshot) return
|
||||
if (browsePanelRef.value) {
|
||||
browsePanelRef.value.scrollTop = browseScrollSnapshot.panelTop
|
||||
}
|
||||
restoreSyncedRowScroll(browseScrollSnapshot.rows)
|
||||
browseScrollSnapshot = null
|
||||
}
|
||||
|
||||
// Save current focus state for a page
|
||||
function saveFocusForPage(page: string) {
|
||||
@@ -693,22 +632,24 @@ function restoreFocusForPage(page: string) {
|
||||
if (lastViewedItemId.value) {
|
||||
// Use nextTick + timeout to ensure DOM is updated after navigation
|
||||
setTimeout(() => {
|
||||
restoreBrowseScrollSnapshot()
|
||||
const itemId = lastViewedItemId.value
|
||||
// Find the element with matching item id
|
||||
const element = document.querySelector(`[data-item-id="${itemId}"]`) as HTMLElement | null
|
||||
if (element) {
|
||||
focusElement(element)
|
||||
focusElement(element, { preserveScroll: true })
|
||||
lastViewedItemId.value = null
|
||||
return
|
||||
}
|
||||
// Fallback to saved focus state
|
||||
const state = focusStateMap.get(page)
|
||||
restoreFocusState(state || null)
|
||||
restoreFocusState(state || null, { preserveScroll: true })
|
||||
lastViewedItemId.value = null
|
||||
}, 100)
|
||||
} else {
|
||||
restoreBrowseScrollSnapshot()
|
||||
const state = focusStateMap.get(page)
|
||||
restoreFocusState(state || null)
|
||||
restoreFocusState(state || null, { preserveScroll: true })
|
||||
}
|
||||
}
|
||||
|
||||
@@ -718,7 +659,10 @@ function restoreBrowseFocus(path: string) {
|
||||
}, 100)
|
||||
}
|
||||
|
||||
function getSearchExitTargetFromFocusedCard(): { path: "/movies" | "/series"; itemId: string } | null {
|
||||
function getSearchExitTargetFromFocusedCard(): {
|
||||
path: "/movies" | "/series"
|
||||
itemId: string
|
||||
} | null {
|
||||
const active = document.activeElement as HTMLElement | null
|
||||
const focusedCard = active?.closest("[data-item-id]") as HTMLElement | null
|
||||
if (!focusedCard) return null
|
||||
@@ -779,9 +723,7 @@ function clearSearch(options: { preferBack?: boolean; targetPath?: string } = {}
|
||||
? normalizeHistoryPath(window.history.state.back)
|
||||
: ""
|
||||
const canRestoreWithBack =
|
||||
options.preferBack !== false &&
|
||||
searchReturnPath.value === targetPath &&
|
||||
backPath === targetPath
|
||||
options.preferBack !== false && searchReturnPath.value === targetPath && backPath === targetPath
|
||||
|
||||
searchReturnPath.value = null
|
||||
|
||||
@@ -910,6 +852,7 @@ onMounted(() => {
|
||||
document.addEventListener("keydown", handleDetailAdjacentKey)
|
||||
window.addEventListener("mediahive:gamepad-action", onGamepadAction as EventListener)
|
||||
window.addEventListener("mediahive:gamepad-button", onRawGamepadButton as EventListener)
|
||||
window.addEventListener("mediahive:resume-updated", refreshResumePositionsAsEvent)
|
||||
})
|
||||
|
||||
onUnmounted(() => {
|
||||
@@ -917,6 +860,7 @@ onUnmounted(() => {
|
||||
document.removeEventListener("keydown", handleDetailAdjacentKey)
|
||||
window.removeEventListener("mediahive:gamepad-action", onGamepadAction as EventListener)
|
||||
window.removeEventListener("mediahive:gamepad-button", onRawGamepadButton as EventListener)
|
||||
window.removeEventListener("mediahive:resume-updated", refreshResumePositionsAsEvent)
|
||||
stopMpcBePolling()
|
||||
})
|
||||
|
||||
@@ -1002,7 +946,7 @@ const activePanelScrollTop = computed(() => {
|
||||
})
|
||||
|
||||
const headerStyle = computed(() => {
|
||||
if (route.path === "/settings") {
|
||||
if (isSettingsView.value) {
|
||||
return {}
|
||||
}
|
||||
return {
|
||||
@@ -1025,6 +969,12 @@ function showDetail(item: MediaItem) {
|
||||
const currentPage = route.path === "/series" ? "series" : "movies"
|
||||
saveFocusForPage(currentPage)
|
||||
|
||||
// Capture the exact browse scroll positions to restore on return,
|
||||
// but only when leaving the browse page (not for detail-to-detail hops)
|
||||
if (!isDetailOpen.value) {
|
||||
captureBrowseScrollSnapshot()
|
||||
}
|
||||
|
||||
// Check if there are matched episodes to focus on
|
||||
if (item.type === "series" && item.searchMatchInfo?.matchedEpisodes?.length) {
|
||||
const firstMatch = item.searchMatchInfo.matchedEpisodes[0]
|
||||
@@ -1044,14 +994,18 @@ function showDetail(item: MediaItem) {
|
||||
handlePlay(playableFile)
|
||||
} else {
|
||||
const searchPath = searchQuery.value ? getSearchPath(searchQuery.value) : null
|
||||
router.push({ path: `/series/${epData.series.id}`, state: searchPath ? { searchPath } : undefined })
|
||||
router.push({
|
||||
path: `/series/${epData.series.id}`,
|
||||
state: searchPath ? { searchPath } : undefined,
|
||||
})
|
||||
}
|
||||
} else {
|
||||
const detailSearchPath = getDetailSearchPath()
|
||||
const searchPath = searchQuery.value
|
||||
? getSearchPath(searchQuery.value)
|
||||
: detailSearchPath
|
||||
router.push({ path: `/${item.type}/${item.id}`, state: searchPath ? { searchPath } : undefined })
|
||||
const searchPath = searchQuery.value ? getSearchPath(searchQuery.value) : detailSearchPath
|
||||
router.push({
|
||||
path: `/${item.type}/${item.id}`,
|
||||
state: searchPath ? { searchPath } : undefined,
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1072,9 +1026,7 @@ function handleActorSearch(actorName: string) {
|
||||
|
||||
function handleSelectMovieFromDetail(movieId: string) {
|
||||
const detailSearchPath = getDetailSearchPath()
|
||||
const searchPath = searchQuery.value
|
||||
? getSearchPath(searchQuery.value)
|
||||
: detailSearchPath
|
||||
const searchPath = searchQuery.value ? getSearchPath(searchQuery.value) : detailSearchPath
|
||||
router.push({ path: `/movies/${movieId}`, state: searchPath ? { searchPath } : undefined })
|
||||
}
|
||||
|
||||
@@ -1090,10 +1042,15 @@ function focusDetailEntryTarget(item: MediaItem): boolean {
|
||||
'[data-nav-release-item="true"][data-nav-row="2"][data-nav-col="0"][data-nav-focusable="true"]',
|
||||
) as HTMLElement | null
|
||||
} else if (item.type === "series") {
|
||||
// Initial episode tile (first season, first episode) maps to row 2 / col 0.
|
||||
// Row 2 is the season selector strip; land on the selected season poster.
|
||||
target = detailPanel.querySelector(
|
||||
'.episode-tile[data-nav-row="2"][data-nav-col="0"][data-nav-focusable="true"]',
|
||||
'.season-poster-card.season-poster-card--selected[data-nav-focusable="true"]',
|
||||
) as HTMLElement | null
|
||||
if (!target) {
|
||||
target = detailPanel.querySelector(
|
||||
'.episode-tile[data-nav-focusable="true"]',
|
||||
) as HTMLElement | null
|
||||
}
|
||||
}
|
||||
|
||||
if (target) {
|
||||
@@ -1108,7 +1065,9 @@ function focusDetailEntryTarget(item: MediaItem): boolean {
|
||||
return true
|
||||
}
|
||||
|
||||
const firstFocusable = detailPanel.querySelector('[data-nav-focusable="true"]') as HTMLElement | null
|
||||
const firstFocusable = detailPanel.querySelector(
|
||||
'[data-nav-focusable="true"]',
|
||||
) as HTMLElement | null
|
||||
if (firstFocusable) {
|
||||
focusElement(firstFocusable)
|
||||
return true
|
||||
|
||||
+93
-8
@@ -148,10 +148,25 @@ function splitAssetTypePath(assetPath: string): { assetType: string; relativePat
|
||||
return { assetType: assetType.toLowerCase(), relativePath: rest.join("/") }
|
||||
}
|
||||
|
||||
/** Watch progress for one episode of a series. */
|
||||
export interface EpisodeWatchEntry {
|
||||
pos: number
|
||||
done: boolean
|
||||
}
|
||||
|
||||
/** One stored continue point. season/episode are set for series, null for movies. */
|
||||
export interface ResumePositionEntry {
|
||||
pos: number
|
||||
season: number | null
|
||||
episode: number | null
|
||||
/** Per-episode watch progress for series, keyed "S<season>E<episode>". */
|
||||
episodes?: Record<string, EpisodeWatchEntry>
|
||||
}
|
||||
|
||||
/**
|
||||
* Fetch merged resume positions from all roots.
|
||||
*/
|
||||
export async function fetchResumePositions(): Promise<Record<string, number>> {
|
||||
export async function fetchResumePositions(): Promise<Record<string, ResumePositionEntry>> {
|
||||
try {
|
||||
const response = await fetch("/api/meta/playback-state")
|
||||
if (!response.ok) return {}
|
||||
@@ -160,12 +175,30 @@ export async function fetchResumePositions(): Promise<Record<string, number>> {
|
||||
if (!positions || typeof positions !== "object") {
|
||||
return {}
|
||||
}
|
||||
const normalized: Record<string, number> = {}
|
||||
const normalized: Record<string, ResumePositionEntry> = {}
|
||||
for (const [slug, value] of Object.entries(positions as Record<string, unknown>)) {
|
||||
if (!value || typeof value !== "object") continue
|
||||
const pos = (value as { pos?: unknown }).pos
|
||||
if (typeof pos === "number" && Number.isFinite(pos) && pos > 0) {
|
||||
normalized[slug] = pos
|
||||
const entry = value as { pos?: unknown; season?: unknown; episode?: unknown }
|
||||
if (typeof entry.pos !== "number" || !Number.isFinite(entry.pos) || entry.pos < 0) {
|
||||
continue
|
||||
}
|
||||
normalized[slug] = {
|
||||
pos: entry.pos,
|
||||
season: typeof entry.season === "number" ? entry.season : null,
|
||||
episode: typeof entry.episode === "number" ? entry.episode : null,
|
||||
}
|
||||
const rawEpisodes = (entry as { episodes?: unknown }).episodes
|
||||
if (rawEpisodes && typeof rawEpisodes === "object") {
|
||||
const watches: Record<string, EpisodeWatchEntry> = {}
|
||||
for (const [key, watch] of Object.entries(rawEpisodes as Record<string, unknown>)) {
|
||||
if (!watch || typeof watch !== "object") continue
|
||||
const w = watch as { pos?: unknown; done?: unknown }
|
||||
if (typeof w.pos !== "number" || !Number.isFinite(w.pos)) continue
|
||||
watches[key] = { pos: w.pos, done: w.done === true }
|
||||
}
|
||||
if (Object.keys(watches).length > 0) {
|
||||
normalized[slug].episodes = watches
|
||||
}
|
||||
}
|
||||
}
|
||||
return normalized
|
||||
@@ -174,6 +207,29 @@ export async function fetchResumePositions(): Promise<Record<string, number>> {
|
||||
}
|
||||
}
|
||||
|
||||
/**
|
||||
* Report that the user is actively interacting with the UI.
|
||||
*
|
||||
* Ends any server-side assumed-playback session (launched item is assumed
|
||||
* watched while the UI sees no input). Throttled; fire-and-forget.
|
||||
*/
|
||||
let lastActivityReportAt = 0
|
||||
export function reportUserActivity(): void {
|
||||
const now = Date.now()
|
||||
if (now - lastActivityReportAt < 5000) return
|
||||
lastActivityReportAt = now
|
||||
void fetch("/api/activity", { method: "POST" })
|
||||
.then(async (response) => {
|
||||
if (!response.ok) return
|
||||
const data = await response.json().catch(() => null)
|
||||
if (data?.finalized) {
|
||||
// An assumed-playback position was just written; let views refetch.
|
||||
window.dispatchEvent(new Event("mediahive:resume-updated"))
|
||||
}
|
||||
})
|
||||
.catch(() => {})
|
||||
}
|
||||
|
||||
/**
|
||||
* Replace the full root set atomically
|
||||
*/
|
||||
@@ -370,13 +426,42 @@ export function getCoverUrl(coverPath: string | null, rootId?: string | null): s
|
||||
}
|
||||
|
||||
/**
|
||||
* Invoke the native OS folder picker via pywebview, then add the selected
|
||||
* folder to the server's root list. Only works inside the packaged desktop app.
|
||||
* Invoke the native OS folder picker via pywebview.
|
||||
* Only works inside the packaged desktop app; returns null elsewhere.
|
||||
*/
|
||||
export async function pickFolderAndAddRoot(): Promise<string | null> {
|
||||
export async function pickFolder(): Promise<string | null> {
|
||||
// eslint-disable-next-line @typescript-eslint/no-explicit-any
|
||||
const api = (window as any).pywebview?.api
|
||||
if (!api) return null
|
||||
const folder: string | null = await api.pick_folder()
|
||||
return folder
|
||||
}
|
||||
|
||||
export interface UpdateStatus {
|
||||
version: string
|
||||
auto_update: boolean
|
||||
pending_version: string | null
|
||||
}
|
||||
|
||||
/** Fetch version, auto-update preference, and any downloaded pending update. */
|
||||
export async function fetchUpdateStatus(): Promise<UpdateStatus> {
|
||||
const response = await fetch("/api/update")
|
||||
if (!response.ok) throw new Error(`Failed to fetch update status: ${response.status}`)
|
||||
return response.json()
|
||||
}
|
||||
|
||||
/** Enable or disable automatic update downloads (persisted server-side). */
|
||||
export async function setAutoUpdate(enabled: boolean): Promise<void> {
|
||||
const response = await fetch("/api/config/auto-update", {
|
||||
method: "PUT",
|
||||
headers: { "Content-Type": "application/json" },
|
||||
body: JSON.stringify({ enabled }),
|
||||
})
|
||||
if (!response.ok) throw new Error(`Failed to save auto-update setting: ${response.status}`)
|
||||
}
|
||||
|
||||
/** Apply a downloaded update and restart the app into it. */
|
||||
export async function restartForUpdate(): Promise<void> {
|
||||
const response = await fetch("/api/update/restart", { method: "POST" })
|
||||
if (!response.ok) throw new Error(`Failed to restart for update: ${response.status}`)
|
||||
}
|
||||
|
||||
@@ -594,13 +594,7 @@ function activateItem(item: MediaItem) {
|
||||
|
||||
function handleItemClick(event: MouseEvent, item: MediaItem) {
|
||||
// Let modified clicks navigate natively
|
||||
if (
|
||||
event.button !== 0 ||
|
||||
event.ctrlKey ||
|
||||
event.metaKey ||
|
||||
event.shiftKey ||
|
||||
event.altKey
|
||||
) {
|
||||
if (event.button !== 0 || event.ctrlKey || event.metaKey || event.shiftKey || event.altKey) {
|
||||
return
|
||||
}
|
||||
event.preventDefault()
|
||||
|
||||
@@ -0,0 +1,192 @@
|
||||
<template>
|
||||
<div
|
||||
v-if="visible"
|
||||
ref="menuRef"
|
||||
class="episode-release-menu"
|
||||
:style="menuStyle"
|
||||
tabindex="-1"
|
||||
@keydown="handleKeydown"
|
||||
>
|
||||
<div class="episode-release-header">{{ episodeName }}</div>
|
||||
<div v-if="releases.length > 0" class="episode-release-list">
|
||||
<ReleaseVersionCard
|
||||
v-for="(release, index) in releases"
|
||||
:key="index"
|
||||
:torrent="release"
|
||||
:best="index === 0"
|
||||
:selectable="!!release.playable_file"
|
||||
:disabled="!release.playable_file"
|
||||
compact-flags
|
||||
variant="menu"
|
||||
inert-card
|
||||
show-actions
|
||||
:play-label="getPlayLabel(release.playable_file)"
|
||||
@play="emit('play', release.playable_file || '')"
|
||||
@open-folder="emit('openFolder', release.playable_file || '')"
|
||||
/>
|
||||
</div>
|
||||
<div v-else class="episode-release-empty">No versions available</div>
|
||||
</div>
|
||||
</template>
|
||||
|
||||
<script setup lang="ts">
|
||||
import { computed, nextTick, onBeforeUnmount, ref, watch } from "vue"
|
||||
import type { Torrent } from "../types"
|
||||
import ReleaseVersionCard from "./ReleaseVersionCard.vue"
|
||||
|
||||
const props = defineProps<{
|
||||
visible: boolean
|
||||
x: number
|
||||
y: number
|
||||
episodeName: string
|
||||
releases: Torrent[]
|
||||
hasResumePosition: (filePath: string | null) => boolean
|
||||
}>()
|
||||
|
||||
const emit = defineEmits<{
|
||||
play: [string]
|
||||
openFolder: [string]
|
||||
close: []
|
||||
}>()
|
||||
|
||||
const menuRef = ref<HTMLElement | null>(null)
|
||||
const menuLeft = ref(0)
|
||||
const menuTop = ref(0)
|
||||
const VIEWPORT_MARGIN = 12
|
||||
|
||||
const menuStyle = computed(() => ({
|
||||
left: `${menuLeft.value}px`,
|
||||
top: `${menuTop.value}px`,
|
||||
}))
|
||||
|
||||
function getPlayLabel(filePath: string | null | undefined): string {
|
||||
return props.hasResumePosition(filePath || null) ? "Continue" : "Play"
|
||||
}
|
||||
|
||||
function getFocusableElements(): HTMLElement[] {
|
||||
if (!menuRef.value) return []
|
||||
return Array.from(menuRef.value.querySelectorAll<HTMLElement>(".ctx-btn:not(:disabled)"))
|
||||
}
|
||||
|
||||
function focusNext(delta: number) {
|
||||
const elements = getFocusableElements()
|
||||
if (elements.length === 0) return
|
||||
const currentIndex = elements.findIndex((el) => el === document.activeElement)
|
||||
const nextIndex =
|
||||
currentIndex < 0 ? 0 : (currentIndex + delta + elements.length) % elements.length
|
||||
elements[nextIndex].focus()
|
||||
}
|
||||
|
||||
function handleKeydown(event: KeyboardEvent) {
|
||||
if (event.key === "Tab") {
|
||||
event.preventDefault()
|
||||
focusNext(event.shiftKey ? -1 : 1)
|
||||
return
|
||||
}
|
||||
if (event.key === "ArrowDown" || event.key === "ArrowRight") {
|
||||
event.preventDefault()
|
||||
focusNext(1)
|
||||
return
|
||||
}
|
||||
if (event.key === "ArrowUp" || event.key === "ArrowLeft") {
|
||||
event.preventDefault()
|
||||
focusNext(-1)
|
||||
return
|
||||
}
|
||||
if (event.key === "Escape") {
|
||||
event.preventDefault()
|
||||
emit("close")
|
||||
return
|
||||
}
|
||||
}
|
||||
|
||||
function clampToViewport() {
|
||||
const menu = menuRef.value
|
||||
if (!menu) return
|
||||
|
||||
const width = menu.offsetWidth
|
||||
const height = menu.offsetHeight
|
||||
|
||||
const maxLeft = Math.max(VIEWPORT_MARGIN, window.innerWidth - width - VIEWPORT_MARGIN)
|
||||
const maxTop = Math.max(VIEWPORT_MARGIN, window.innerHeight - height - VIEWPORT_MARGIN)
|
||||
|
||||
menuLeft.value = Math.min(Math.max(props.x, VIEWPORT_MARGIN), maxLeft)
|
||||
menuTop.value = Math.min(Math.max(props.y, VIEWPORT_MARGIN), maxTop)
|
||||
}
|
||||
|
||||
function handleViewportChange() {
|
||||
if (!props.visible) return
|
||||
clampToViewport()
|
||||
}
|
||||
|
||||
watch(
|
||||
() => [props.visible, props.x, props.y, props.episodeName, props.releases.length],
|
||||
async ([visible]) => {
|
||||
if (!visible) return
|
||||
await nextTick()
|
||||
clampToViewport()
|
||||
// Focus first action button for keyboard navigation
|
||||
const firstBtn = menuRef.value?.querySelector(".ctx-btn:not(:disabled)") as HTMLElement | null
|
||||
firstBtn?.focus()
|
||||
},
|
||||
{ immediate: true },
|
||||
)
|
||||
|
||||
watch(
|
||||
() => props.visible,
|
||||
(visible) => {
|
||||
if (visible) {
|
||||
window.addEventListener("resize", handleViewportChange)
|
||||
return
|
||||
}
|
||||
window.removeEventListener("resize", handleViewportChange)
|
||||
},
|
||||
{ immediate: true },
|
||||
)
|
||||
|
||||
onBeforeUnmount(() => {
|
||||
window.removeEventListener("resize", handleViewportChange)
|
||||
})
|
||||
</script>
|
||||
|
||||
<style scoped>
|
||||
.episode-release-menu {
|
||||
position: fixed;
|
||||
z-index: 1000;
|
||||
background: rgba(20, 20, 30, 0.98);
|
||||
border: 1px solid rgba(255, 255, 255, 0.15);
|
||||
border-radius: 8px;
|
||||
min-width: 420px;
|
||||
max-width: min(820px, calc(100vw - 24px));
|
||||
max-height: calc(100vh - 24px);
|
||||
overflow-y: auto;
|
||||
box-shadow: 0 8px 32px rgba(0, 0, 0, 0.6);
|
||||
padding: 8px;
|
||||
}
|
||||
|
||||
.episode-release-header {
|
||||
padding: 10px 12px;
|
||||
font-weight: 600;
|
||||
font-size: 0.9rem;
|
||||
background: rgba(255, 255, 255, 0.05);
|
||||
border-bottom: 1px solid rgba(255, 255, 255, 0.1);
|
||||
border-radius: 6px;
|
||||
margin-bottom: 8px;
|
||||
white-space: nowrap;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
}
|
||||
|
||||
.episode-release-list {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: 8px;
|
||||
}
|
||||
|
||||
.episode-release-empty {
|
||||
padding: 16px;
|
||||
text-align: center;
|
||||
color: rgba(255, 255, 255, 0.5);
|
||||
font-size: 0.85rem;
|
||||
}
|
||||
</style>
|
||||
+735
-234
File diff suppressed because it is too large
Load Diff
@@ -1,7 +1,13 @@
|
||||
<template>
|
||||
<Teleport to="body">
|
||||
<Transition name="hex-keyboard-fade">
|
||||
<div v-if="visible" ref="keyboardRef" class="hex-keyboard" @click.stop @keydown="handleKeyDown">
|
||||
<div
|
||||
v-if="visible"
|
||||
ref="keyboardRef"
|
||||
class="hex-keyboard"
|
||||
@click.stop
|
||||
@keydown="handleKeyDown"
|
||||
>
|
||||
<div ref="gridRef" class="hex-keyboard-grid">
|
||||
<div
|
||||
v-for="(row, rowIndex) in rows"
|
||||
@@ -26,7 +32,9 @@
|
||||
tabindex="-1"
|
||||
@click="handleKeyClick(key)"
|
||||
>
|
||||
<span class="hex-key-label" :class="{ 'hex-key-label-large': key.id === 'sp' }">{{ key.label }}</span>
|
||||
<span class="hex-key-label" :class="{ 'hex-key-label-large': key.id === 'sp' }">{{
|
||||
key.label
|
||||
}}</span>
|
||||
</button>
|
||||
</div>
|
||||
<!-- Green focus outline rendered separately on top -->
|
||||
@@ -174,11 +182,16 @@ function getCoord(index: number): { row: number; col: number } {
|
||||
|
||||
function getRowRange(row: number): { start: number; count: number } {
|
||||
switch (row) {
|
||||
case 0: return { start: ROW_0_START, count: ROW_0_COUNT }
|
||||
case 1: return { start: ROW_1_START, count: ROW_1_COUNT }
|
||||
case 2: return { start: ROW_2_START, count: ROW_2_COUNT }
|
||||
case 3: return { start: ROW_3_START, count: ROW_3_COUNT }
|
||||
default: return { start: 0, count: 0 }
|
||||
case 0:
|
||||
return { start: ROW_0_START, count: ROW_0_COUNT }
|
||||
case 1:
|
||||
return { start: ROW_1_START, count: ROW_1_COUNT }
|
||||
case 2:
|
||||
return { start: ROW_2_START, count: ROW_2_COUNT }
|
||||
case 3:
|
||||
return { start: ROW_3_START, count: ROW_3_COUNT }
|
||||
default:
|
||||
return { start: 0, count: 0 }
|
||||
}
|
||||
}
|
||||
|
||||
@@ -247,10 +260,7 @@ function close() {
|
||||
emit("close")
|
||||
}
|
||||
|
||||
function findNext(
|
||||
currentIdx: number,
|
||||
direction: "up" | "down" | "left" | "right",
|
||||
): number | null {
|
||||
function findNext(currentIdx: number, direction: "up" | "down" | "left" | "right"): number | null {
|
||||
const current = getCoord(currentIdx)
|
||||
|
||||
if (direction === "left") {
|
||||
@@ -510,10 +520,18 @@ onUnmounted(() => {
|
||||
}
|
||||
|
||||
/* Row horizontal offsets for honeycomb staggering */
|
||||
.hex-keyboard-row-0 { margin-left: 0; }
|
||||
.hex-keyboard-row-1 { margin-left: calc(var(--key-w) * 0.5); }
|
||||
.hex-keyboard-row-2 { margin-left: calc(var(--key-w) * 1.0); }
|
||||
.hex-keyboard-row-3 { margin-left: calc(var(--key-w) * 1.5); }
|
||||
.hex-keyboard-row-0 {
|
||||
margin-left: 0;
|
||||
}
|
||||
.hex-keyboard-row-1 {
|
||||
margin-left: calc(var(--key-w) * 0.5);
|
||||
}
|
||||
.hex-keyboard-row-2 {
|
||||
margin-left: calc(var(--key-w) * 1);
|
||||
}
|
||||
.hex-keyboard-row-3 {
|
||||
margin-left: calc(var(--key-w) * 1.5);
|
||||
}
|
||||
|
||||
.hex-key {
|
||||
position: relative;
|
||||
@@ -529,7 +547,9 @@ onUnmounted(() => {
|
||||
align-items: center;
|
||||
justify-content: center;
|
||||
clip-path: polygon(50% 0%, 100% 25%, 100% 75%, 50% 100%, 0% 75%, 0% 25%);
|
||||
transition: transform 0.15s ease, color 0.3s ease;
|
||||
transition:
|
||||
transform 0.15s ease,
|
||||
color 0.3s ease;
|
||||
outline: none;
|
||||
transform: scale(0.97);
|
||||
}
|
||||
@@ -538,7 +558,8 @@ onUnmounted(() => {
|
||||
.hex-key-row-0 {
|
||||
background: linear-gradient(180deg, #626b7bd0 0%, #3a3f4ad0 100%);
|
||||
}
|
||||
.hex-key-row-1, .hex-key-row-3 {
|
||||
.hex-key-row-1,
|
||||
.hex-key-row-3 {
|
||||
background: linear-gradient(180deg, #2a3343d0 0%, #2c3242d0 100%);
|
||||
}
|
||||
.hex-key-row-2 {
|
||||
@@ -553,8 +574,12 @@ onUnmounted(() => {
|
||||
}
|
||||
|
||||
@keyframes hex-label-fade {
|
||||
0% { color: #22c55e; }
|
||||
100% { color: #ffffff; }
|
||||
0% {
|
||||
color: #22c55e;
|
||||
}
|
||||
100% {
|
||||
color: #ffffff;
|
||||
}
|
||||
}
|
||||
|
||||
/* Special key backgrounds override row gradients */
|
||||
@@ -600,8 +625,13 @@ onUnmounted(() => {
|
||||
}
|
||||
|
||||
@keyframes hex-outline-blink {
|
||||
0%, 100% { opacity: 1; }
|
||||
50% { opacity: 0.4; }
|
||||
0%,
|
||||
100% {
|
||||
opacity: 1;
|
||||
}
|
||||
50% {
|
||||
opacity: 0.4;
|
||||
}
|
||||
}
|
||||
|
||||
/* Transition */
|
||||
|
||||
@@ -6,7 +6,7 @@
|
||||
v-for="entry in flagEntries"
|
||||
:key="entry.countryCode"
|
||||
class="language-flag"
|
||||
:title="`${entry.countryCode}: ${entry.sourceCodes.join(', ')}`"
|
||||
:title="formatLanguageFlagTitle(entry, externalCodes)"
|
||||
v-html="entry.svg"
|
||||
></span>
|
||||
<span
|
||||
@@ -22,11 +22,12 @@
|
||||
|
||||
<script setup lang="ts">
|
||||
import { computed } from "vue"
|
||||
import { buildLanguageFlags } from "../utils/languageFlags"
|
||||
import { buildLanguageFlags, formatLanguageFlagTitle } from "../utils/languageFlags"
|
||||
|
||||
const props = defineProps<{
|
||||
label?: string
|
||||
codes: string[] | null | undefined
|
||||
externalCodes?: string[] | null
|
||||
compact?: boolean
|
||||
}>()
|
||||
|
||||
|
||||
@@ -18,6 +18,7 @@
|
||||
:src="posterImageUrl"
|
||||
:alt="item.title || 'Unknown'"
|
||||
loading="lazy"
|
||||
decoding="async"
|
||||
@error="imageError = true"
|
||||
/>
|
||||
<div v-else class="media-card-placeholder">
|
||||
@@ -79,7 +80,9 @@
|
||||
</div>
|
||||
<div v-else-if="subtitle" class="media-card-detail">{{ subtitle }}</div>
|
||||
<div v-if="directorAndCast" class="media-card-detail person-list">
|
||||
<span v-if="director" class="director-name person-token">{{ formatPersonLabel(director) }}</span>
|
||||
<span v-if="director" class="director-name person-token">{{
|
||||
formatPersonLabel(director)
|
||||
}}</span>
|
||||
<span
|
||||
v-for="(castName, castIndex) in formattedCastNames"
|
||||
:key="`${castName}-${castIndex}`"
|
||||
@@ -111,13 +114,7 @@ const emit = defineEmits<{
|
||||
|
||||
function handleClick(event: MouseEvent) {
|
||||
// Let modified clicks (middle-click, ctrl+click, etc.) navigate natively
|
||||
if (
|
||||
event.button !== 0 ||
|
||||
event.ctrlKey ||
|
||||
event.metaKey ||
|
||||
event.shiftKey ||
|
||||
event.altKey
|
||||
) {
|
||||
if (event.button !== 0 || event.ctrlKey || event.metaKey || event.shiftKey || event.altKey) {
|
||||
return
|
||||
}
|
||||
// Prevent default navigation for plain left-clicks and synthetic clicks
|
||||
|
||||
@@ -2,10 +2,12 @@
|
||||
<!-- Full screen view for series -->
|
||||
<SeriesFullView
|
||||
v-if="item.type === 'series'"
|
||||
:key="item.id"
|
||||
:series="item.data as Series"
|
||||
:all-movies="allMovies"
|
||||
:focus-episode="focusEpisode"
|
||||
:has-resume-position="hasResumePosition"
|
||||
:resume-point="getResumePoint(item.id)"
|
||||
:resume-episodes="getResumeEpisodes(item.id)"
|
||||
:get-root-name="getRootName"
|
||||
@close="$emit('close')"
|
||||
@play="handlePlay"
|
||||
@@ -17,7 +19,7 @@
|
||||
<div v-else class="movie-page">
|
||||
<div class="movie-page-content">
|
||||
<!-- Diagonal collage header -->
|
||||
<div class="collage-header">
|
||||
<div ref="collageHeaderRef" class="collage-header">
|
||||
<!-- Background collage of showreel videos -->
|
||||
<div class="collage-grid">
|
||||
<div
|
||||
@@ -184,7 +186,11 @@
|
||||
v-if="item.type === 'movies' && collectionMovies.length > 1"
|
||||
class="similar-movies-section"
|
||||
>
|
||||
<div class="similar-movies-grid" data-sync-scroll-row="true" data-sync-scroll-group="similar">
|
||||
<div
|
||||
class="similar-movies-grid"
|
||||
data-sync-scroll-row="true"
|
||||
data-sync-scroll-group="similar"
|
||||
>
|
||||
<a
|
||||
v-for="(movie, collectionIndex) in collectionMovies"
|
||||
:key="movie.localId"
|
||||
@@ -233,7 +239,16 @@
|
||||
|
||||
<script setup lang="ts">
|
||||
import { computed, ref, watch, onMounted, onUnmounted, nextTick } from "vue"
|
||||
import type { CastMember, MediaItem, Movie, MovieUi, Series, Torrent } from "../types"
|
||||
import type {
|
||||
CastMember,
|
||||
MediaItem,
|
||||
Movie,
|
||||
MovieUi,
|
||||
Series,
|
||||
SeriesResumePoint,
|
||||
Torrent,
|
||||
} from "../types"
|
||||
import type { EpisodeWatchEntry } from "../api"
|
||||
import {
|
||||
getCoverUrl,
|
||||
getVideoPreviewUrl,
|
||||
@@ -253,12 +268,15 @@ import {
|
||||
FOCUSABLE_ATTR,
|
||||
setModalOpen,
|
||||
} from "../composables/useKeyboardNavigation"
|
||||
import { useIdlePreviewPlayback } from "../composables/useIdlePreviewPlayback"
|
||||
|
||||
const props = defineProps<{
|
||||
item: MediaItem
|
||||
allMovies: MovieUi[]
|
||||
focusEpisode?: { seasonNumber: number; episodeNumber: number } | null
|
||||
hasResumePosition: (mediaId: string | null) => boolean
|
||||
getResumePoint: (mediaId: string | null) => SeriesResumePoint | null
|
||||
getResumeEpisodes: (mediaId: string | null) => Record<string, EpisodeWatchEntry> | null
|
||||
getRootName: (rootId: string | null | undefined) => string | null
|
||||
}>()
|
||||
const emit = defineEmits<{
|
||||
@@ -278,6 +296,22 @@ const safariAutoplay = isSafariBrowser()
|
||||
const COLLAGE_START_OFFSETS_SECONDS = [0, 8, 6, 4, 2]
|
||||
const DESKTOP_NAV_SHORTCUT_MIN_WIDTH = 900
|
||||
|
||||
const collageHeaderRef = ref<HTMLElement | null>(null)
|
||||
let collageHeaderVisible = true
|
||||
let collageHeaderObserver: IntersectionObserver | null = null
|
||||
const staggerTimers = new Set<ReturnType<typeof setTimeout>>()
|
||||
const COLLAGE_STOP_STEP_MS = 500
|
||||
let staggerToken = 0
|
||||
|
||||
const { stopped: previewPlaybackStopped } = useIdlePreviewPlayback({
|
||||
onStop: stopPreviews,
|
||||
onRestart: () => startStaggeredPlayback(),
|
||||
})
|
||||
|
||||
function previewsSuppressed(): boolean {
|
||||
return previewPlaybackStopped.value || !collageHeaderVisible || document.hidden
|
||||
}
|
||||
|
||||
let disposeOutOfBoundsHandler: (() => void) | null = null
|
||||
let lastReleaseShortcutRow: number | null = null
|
||||
|
||||
@@ -294,7 +328,9 @@ function getReleaseAtRow(row: number): HTMLElement | null {
|
||||
}
|
||||
|
||||
function getLastReleaseRowBefore(castRow: number): number | null {
|
||||
const releases = Array.from(document.querySelectorAll<HTMLElement>('[data-nav-release-item="true"]'))
|
||||
const releases = Array.from(
|
||||
document.querySelectorAll<HTMLElement>('[data-nav-release-item="true"]'),
|
||||
)
|
||||
let best: number | null = null
|
||||
for (const release of releases) {
|
||||
const row = parseInt(release.getAttribute("data-nav-row") || "", 10)
|
||||
@@ -321,11 +357,7 @@ function registerMovieOutOfBoundsShortcut() {
|
||||
return null
|
||||
}
|
||||
|
||||
if (
|
||||
direction === "left" &&
|
||||
current.hasAttribute("data-nav-cast-item") &&
|
||||
currentCol === 0
|
||||
) {
|
||||
if (direction === "left" && current.hasAttribute("data-nav-cast-item") && currentCol === 0) {
|
||||
const targetRow = lastReleaseShortcutRow ?? getLastReleaseRowBefore(currentRow)
|
||||
if (targetRow === null) return null
|
||||
return getReleaseAtRow(targetRow)
|
||||
@@ -362,15 +394,35 @@ function isVideoReady(index: number): boolean {
|
||||
return videoStates.value[index] === "ready"
|
||||
}
|
||||
|
||||
function cancelStaggeredPlayback() {
|
||||
staggerToken += 1
|
||||
for (const timer of staggerTimers) {
|
||||
clearTimeout(timer)
|
||||
}
|
||||
staggerTimers.clear()
|
||||
}
|
||||
|
||||
function scheduleStaggeredStart(token: number, start: () => void, delayMs: number) {
|
||||
const timer = setTimeout(() => {
|
||||
staggerTimers.delete(timer)
|
||||
if (token !== staggerToken || previewsSuppressed()) return
|
||||
start()
|
||||
}, delayMs)
|
||||
staggerTimers.add(timer)
|
||||
}
|
||||
|
||||
// Start staggered video playback
|
||||
function startStaggeredPlayback() {
|
||||
cancelStaggeredPlayback()
|
||||
const token = staggerToken
|
||||
const videos = videoRefs.value.filter((v) => v !== null) as HTMLVideoElement[]
|
||||
if (videos.length === 0) return
|
||||
if (videos.length === 0 || previewsSuppressed()) return
|
||||
|
||||
if (safariAutoplay) {
|
||||
videos.forEach((video, index) => {
|
||||
const offset = COLLAGE_START_OFFSETS_SECONDS[index] ?? 0
|
||||
const startVideo = () => {
|
||||
if (token !== staggerToken || previewsSuppressed()) return
|
||||
video.currentTime = offset
|
||||
video.play().catch(() => {})
|
||||
}
|
||||
@@ -390,11 +442,46 @@ function startStaggeredPlayback() {
|
||||
|
||||
// Set up staggered start for remaining videos
|
||||
for (let i = 1; i < videos.length; i++) {
|
||||
setTimeout(() => {
|
||||
const video = videos[i]
|
||||
if (!video) return
|
||||
video.play().catch(() => {})
|
||||
}, i * 2000)
|
||||
scheduleStaggeredStart(
|
||||
token,
|
||||
() => {
|
||||
const video = videos[i]
|
||||
if (!video) return
|
||||
video.play().catch(() => {})
|
||||
},
|
||||
i * 2000,
|
||||
)
|
||||
}
|
||||
}
|
||||
|
||||
function scheduleStaggeredStop(token: number, stop: () => void, delayMs: number) {
|
||||
const timer = setTimeout(() => {
|
||||
staggerTimers.delete(timer)
|
||||
if (token !== staggerToken) return
|
||||
stop()
|
||||
}, delayMs)
|
||||
staggerTimers.add(timer)
|
||||
}
|
||||
|
||||
// Stop all collage previews with a stagger, and cancel pending staggered starts
|
||||
function stopPreviews() {
|
||||
cancelStaggeredPlayback()
|
||||
const token = staggerToken
|
||||
clearHoverAudioIdleTimer()
|
||||
hoveredVideoIndex = null
|
||||
for (const interval of volumeFadeIntervals.values()) {
|
||||
clearInterval(interval)
|
||||
}
|
||||
volumeFadeIntervals.clear()
|
||||
|
||||
let stopIndex = 0
|
||||
for (const video of videoRefs.value) {
|
||||
if (video && !video.paused && !video.ended) {
|
||||
scheduleStaggeredStop(token, () => video.pause(), stopIndex * COLLAGE_STOP_STEP_MS)
|
||||
stopIndex += 1
|
||||
} else {
|
||||
video?.pause()
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -497,6 +584,19 @@ onMounted(() => {
|
||||
startStaggeredPlayback()
|
||||
}, 100)
|
||||
|
||||
// Pause the collage videos while the header is scrolled out of view
|
||||
if (collageHeaderRef.value) {
|
||||
collageHeaderObserver = new IntersectionObserver((entries) => {
|
||||
collageHeaderVisible = entries[0]?.isIntersecting ?? true
|
||||
if (collageHeaderVisible) {
|
||||
startStaggeredPlayback()
|
||||
} else {
|
||||
stopPreviews()
|
||||
}
|
||||
})
|
||||
collageHeaderObserver.observe(collageHeaderRef.value)
|
||||
}
|
||||
|
||||
registerMovieOutOfBoundsShortcut()
|
||||
})
|
||||
|
||||
@@ -666,23 +766,8 @@ const castNavRow = computed(() => {
|
||||
return hasDesktopSimilarShortcut ? 4 + movieVersions.value.length : 2 + movieVersions.value.length
|
||||
})
|
||||
|
||||
const collectionMovies = computed((): Array<{
|
||||
title: string
|
||||
localId: string
|
||||
coverPath: string | null
|
||||
rootId: string | null
|
||||
year: string | null
|
||||
hyphenLang: string | null
|
||||
isCurrent: boolean
|
||||
}> => {
|
||||
if (props.item.type !== "movies") return []
|
||||
|
||||
const movie = props.item.data as Movie
|
||||
const collectionName = movie.info?.collection?.trim()
|
||||
if (!collectionName) return []
|
||||
const normalizedCollectionName = collectionName.toLowerCase()
|
||||
|
||||
const matches: Array<{
|
||||
const collectionMovies = computed(
|
||||
(): Array<{
|
||||
title: string
|
||||
localId: string
|
||||
coverPath: string | null
|
||||
@@ -690,60 +775,77 @@ const collectionMovies = computed((): Array<{
|
||||
year: string | null
|
||||
hyphenLang: string | null
|
||||
isCurrent: boolean
|
||||
}> = []
|
||||
}> => {
|
||||
if (props.item.type !== "movies") return []
|
||||
|
||||
let hasCurrentInMatches = false
|
||||
const movie = props.item.data as Movie
|
||||
const collectionName = movie.info?.collection?.trim()
|
||||
if (!collectionName) return []
|
||||
const normalizedCollectionName = collectionName.toLowerCase()
|
||||
|
||||
for (const libraryMovie of props.allMovies || []) {
|
||||
const otherCollectionName = libraryMovie.info?.collection?.trim().toLowerCase()
|
||||
if (otherCollectionName !== normalizedCollectionName) continue
|
||||
const matches: Array<{
|
||||
title: string
|
||||
localId: string
|
||||
coverPath: string | null
|
||||
rootId: string | null
|
||||
year: string | null
|
||||
hyphenLang: string | null
|
||||
isCurrent: boolean
|
||||
}> = []
|
||||
|
||||
const title = libraryMovie.title || libraryMovie.info?.title
|
||||
if (!title) continue
|
||||
let hasCurrentInMatches = false
|
||||
|
||||
const isCurrent = libraryMovie.id === props.item.id
|
||||
if (isCurrent) hasCurrentInMatches = true
|
||||
for (const libraryMovie of props.allMovies || []) {
|
||||
const otherCollectionName = libraryMovie.info?.collection?.trim().toLowerCase()
|
||||
if (otherCollectionName !== normalizedCollectionName) continue
|
||||
|
||||
matches.push({
|
||||
title,
|
||||
localId: libraryMovie.id,
|
||||
coverPath: libraryMovie.cover_path || null,
|
||||
rootId: libraryMovie.root_id || null,
|
||||
year: libraryMovie.year
|
||||
? String(libraryMovie.year)
|
||||
: libraryMovie.info?.release_date?.slice(0, 4) || null,
|
||||
hyphenLang: normalizeHyphenationLang(libraryMovie.info?.original_language),
|
||||
isCurrent,
|
||||
})
|
||||
}
|
||||
const title = libraryMovie.title || libraryMovie.info?.title
|
||||
if (!title) continue
|
||||
|
||||
if (!hasCurrentInMatches) {
|
||||
matches.push({
|
||||
title: props.item.title || (props.item.data as Movie).info?.title || "Current movie",
|
||||
localId: props.item.id,
|
||||
coverPath: props.item.cover_path || null,
|
||||
rootId: props.item.root_id || null,
|
||||
year: props.item.year
|
||||
? String(props.item.year)
|
||||
: (props.item.data as Movie).info?.release_date?.slice(0, 4) || null,
|
||||
hyphenLang: normalizeHyphenationLang((props.item.data as Movie).info?.original_language),
|
||||
isCurrent: true,
|
||||
})
|
||||
}
|
||||
const isCurrent = libraryMovie.id === props.item.id
|
||||
if (isCurrent) hasCurrentInMatches = true
|
||||
|
||||
return matches
|
||||
.sort((a, b) => {
|
||||
const yearA = parseInt(a.year || "", 10)
|
||||
const yearB = parseInt(b.year || "", 10)
|
||||
const hasYearA = Number.isFinite(yearA)
|
||||
const hasYearB = Number.isFinite(yearB)
|
||||
matches.push({
|
||||
title,
|
||||
localId: libraryMovie.id,
|
||||
coverPath: libraryMovie.cover_path || null,
|
||||
rootId: libraryMovie.root_id || null,
|
||||
year: libraryMovie.year
|
||||
? String(libraryMovie.year)
|
||||
: libraryMovie.info?.release_date?.slice(0, 4) || null,
|
||||
hyphenLang: normalizeHyphenationLang(libraryMovie.info?.original_language),
|
||||
isCurrent,
|
||||
})
|
||||
}
|
||||
|
||||
if (hasYearA && hasYearB && yearA !== yearB) return yearA - yearB
|
||||
if (hasYearA !== hasYearB) return hasYearA ? -1 : 1
|
||||
return a.title.localeCompare(b.title)
|
||||
})
|
||||
.slice(0, 24)
|
||||
})
|
||||
if (!hasCurrentInMatches) {
|
||||
matches.push({
|
||||
title: props.item.title || (props.item.data as Movie).info?.title || "Current movie",
|
||||
localId: props.item.id,
|
||||
coverPath: props.item.cover_path || null,
|
||||
rootId: props.item.root_id || null,
|
||||
year: props.item.year
|
||||
? String(props.item.year)
|
||||
: (props.item.data as Movie).info?.release_date?.slice(0, 4) || null,
|
||||
hyphenLang: normalizeHyphenationLang((props.item.data as Movie).info?.original_language),
|
||||
isCurrent: true,
|
||||
})
|
||||
}
|
||||
|
||||
return matches
|
||||
.sort((a, b) => {
|
||||
const yearA = parseInt(a.year || "", 10)
|
||||
const yearB = parseInt(b.year || "", 10)
|
||||
const hasYearA = Number.isFinite(yearA)
|
||||
const hasYearB = Number.isFinite(yearB)
|
||||
|
||||
if (hasYearA && hasYearB && yearA !== yearB) return yearA - yearB
|
||||
if (hasYearA !== hasYearB) return hasYearA ? -1 : 1
|
||||
return a.title.localeCompare(b.title)
|
||||
})
|
||||
.slice(0, 24)
|
||||
},
|
||||
)
|
||||
|
||||
function normalizeHyphenationLang(language: string | null | undefined): string | null {
|
||||
if (!language) return null
|
||||
@@ -798,14 +900,6 @@ const ratingClass = computed(() => {
|
||||
return "rating-low"
|
||||
})
|
||||
|
||||
const seasons = computed(() => {
|
||||
if (props.item.type !== "series") return []
|
||||
const series = props.item.data as Series
|
||||
return series.seasons || []
|
||||
})
|
||||
|
||||
const selectedSeasonIndex = ref<number>(0)
|
||||
|
||||
const versionActionMenu = ref<{
|
||||
visible: boolean
|
||||
x: number
|
||||
@@ -892,17 +986,6 @@ function handleMovieMenuKeydown(event: KeyboardEvent) {
|
||||
}
|
||||
}
|
||||
|
||||
// Select first season by default
|
||||
watch(
|
||||
seasons,
|
||||
(s) => {
|
||||
if (s.length > 0 && selectedSeasonIndex.value >= s.length) {
|
||||
selectedSeasonIndex.value = 0
|
||||
}
|
||||
},
|
||||
{ immediate: true },
|
||||
)
|
||||
|
||||
function handlePlay(filePath: string | null) {
|
||||
if (filePath) {
|
||||
emit("play", filePath)
|
||||
@@ -990,6 +1073,9 @@ onUnmounted(() => {
|
||||
window.removeEventListener("mousemove", handleHoverAudioMouseMove)
|
||||
window.removeEventListener("mediahive:gamepad-action", handleGamepadAction as EventListener)
|
||||
clearHoverAudioIdleTimer()
|
||||
cancelStaggeredPlayback()
|
||||
collageHeaderObserver?.disconnect()
|
||||
collageHeaderObserver = null
|
||||
disposeOutOfBoundsHandler?.()
|
||||
disposeOutOfBoundsHandler = null
|
||||
lastReleaseShortcutRow = null
|
||||
|
||||
@@ -84,7 +84,7 @@ const disabled = computed(() => !props.filePath)
|
||||
function getFocusableElements(): HTMLElement[] {
|
||||
if (!menuRef.value) return []
|
||||
return Array.from(
|
||||
menuRef.value.querySelectorAll<HTMLElement>(".version-action-item:not(:disabled)")
|
||||
menuRef.value.querySelectorAll<HTMLElement>(".version-action-item:not(:disabled)"),
|
||||
)
|
||||
}
|
||||
|
||||
|
||||
@@ -44,6 +44,7 @@
|
||||
<LanguageFlags
|
||||
class="language-flags-subs"
|
||||
:codes="torrent.subtitle_languages"
|
||||
:external-codes="torrent.external_subtitle_languages"
|
||||
:compact="compactFlags"
|
||||
/>
|
||||
</div>
|
||||
@@ -335,7 +336,12 @@ const hdr10PlusPattern = /hdr10\+|hdr10plus/i
|
||||
|
||||
const hasHdr10Plus = computed(() => {
|
||||
if (props.torrent.hdr10plus) return true
|
||||
const text = [props.torrent.title, props.torrent.quality, props.torrent.codec, props.torrent.audio]
|
||||
const text = [
|
||||
props.torrent.title,
|
||||
props.torrent.quality,
|
||||
props.torrent.codec,
|
||||
props.torrent.audio,
|
||||
]
|
||||
.filter(Boolean)
|
||||
.join(" ")
|
||||
return hdr10PlusPattern.test(text)
|
||||
|
||||
File diff suppressed because it is too large
Load Diff
@@ -110,7 +110,9 @@ function getDigitalRepeatIntervalMs(holdMs: number): number {
|
||||
|
||||
function getAnalogRepeatIntervalMs(intensity: number): number {
|
||||
const normalized = Math.min(Math.max(intensity, 0), 1)
|
||||
return Math.round(ANALOG_REPEAT_MAX_MS - (ANALOG_REPEAT_MAX_MS - ANALOG_REPEAT_MIN_MS) * normalized)
|
||||
return Math.round(
|
||||
ANALOG_REPEAT_MAX_MS - (ANALOG_REPEAT_MAX_MS - ANALOG_REPEAT_MIN_MS) * normalized,
|
||||
)
|
||||
}
|
||||
|
||||
function normalizeAxisIntensity(rawValue: number): number {
|
||||
|
||||
@@ -0,0 +1,74 @@
|
||||
import { onUnmounted, ref, type Ref } from "vue"
|
||||
|
||||
export const PREVIEW_IDLE_MS = 30_000
|
||||
|
||||
const ACTIVITY_EVENTS = ["mousemove", "mousedown", "wheel", "keydown", "touchstart"] as const
|
||||
const GAMEPAD_ACTIVITY_EVENT = "mediahive:gamepad-action"
|
||||
|
||||
interface IdlePreviewPlaybackOptions {
|
||||
idleMs?: number
|
||||
onStop: () => void
|
||||
onRestart: () => void
|
||||
}
|
||||
|
||||
// Stops preview videos after a period without user input and restarts them
|
||||
// (via the component's staggered startup) when activity resumes. Also stops
|
||||
// previews while the tab is hidden. Activity listeners run in the capture
|
||||
// phase so the stopped flag clears before hover/focus handlers react.
|
||||
export function useIdlePreviewPlayback(options: IdlePreviewPlaybackOptions): {
|
||||
stopped: Ref<boolean>
|
||||
} {
|
||||
const idleMs = options.idleMs ?? PREVIEW_IDLE_MS
|
||||
const stopped = ref(false)
|
||||
let idleTimer: ReturnType<typeof setTimeout> | null = null
|
||||
|
||||
function clearIdleTimer() {
|
||||
if (idleTimer !== null) {
|
||||
clearTimeout(idleTimer)
|
||||
idleTimer = null
|
||||
}
|
||||
}
|
||||
|
||||
function stop() {
|
||||
clearIdleTimer()
|
||||
if (stopped.value) return
|
||||
stopped.value = true
|
||||
options.onStop()
|
||||
}
|
||||
|
||||
function handleActivity() {
|
||||
if (document.hidden) return
|
||||
if (stopped.value) {
|
||||
stopped.value = false
|
||||
options.onRestart()
|
||||
}
|
||||
clearIdleTimer()
|
||||
idleTimer = setTimeout(stop, idleMs)
|
||||
}
|
||||
|
||||
function handleVisibilityChange() {
|
||||
if (document.hidden) {
|
||||
stop()
|
||||
} else {
|
||||
handleActivity()
|
||||
}
|
||||
}
|
||||
|
||||
for (const eventName of ACTIVITY_EVENTS) {
|
||||
window.addEventListener(eventName, handleActivity, { passive: true, capture: true })
|
||||
}
|
||||
window.addEventListener(GAMEPAD_ACTIVITY_EVENT, handleActivity, { passive: true, capture: true })
|
||||
document.addEventListener("visibilitychange", handleVisibilityChange)
|
||||
idleTimer = setTimeout(stop, idleMs)
|
||||
|
||||
onUnmounted(() => {
|
||||
for (const eventName of ACTIVITY_EVENTS) {
|
||||
window.removeEventListener(eventName, handleActivity, { capture: true })
|
||||
}
|
||||
window.removeEventListener(GAMEPAD_ACTIVITY_EVENT, handleActivity, { capture: true })
|
||||
document.removeEventListener("visibilitychange", handleVisibilityChange)
|
||||
clearIdleTimer()
|
||||
})
|
||||
|
||||
return { stopped }
|
||||
}
|
||||
@@ -1,8 +1,11 @@
|
||||
import { reportUserActivity } from "../api"
|
||||
|
||||
type InputModality = "mouse" | "keyboard" | "gamepad"
|
||||
|
||||
const MOUSE_IDLE_MS = 1400
|
||||
const MOUSE_INTENT_DISTANCE_PX = 28
|
||||
const MOUSE_INTENT_WINDOW_MS = 700
|
||||
const MOUSE_OVER_INTENT_RECENCY_MS = 500
|
||||
const MOUSE_INTENT_SELECTOR = [
|
||||
"[data-nav-focusable]",
|
||||
"button",
|
||||
@@ -25,6 +28,7 @@ let mouseIdleTimer: number | null = null
|
||||
let pointerVisible = false
|
||||
let mouseTravelPx = 0
|
||||
let lastMouseMoveAt = 0
|
||||
let lastAnyMouseMoveAt = 0
|
||||
|
||||
function clearMouseIdleTimer() {
|
||||
if (mouseIdleTimer !== null) {
|
||||
@@ -90,7 +94,9 @@ function registerMouseIntentTravel(event: MouseEvent): boolean {
|
||||
}
|
||||
|
||||
function handleMouseMove(event: MouseEvent) {
|
||||
reportUserActivity()
|
||||
showPointerFromMotion()
|
||||
lastAnyMouseMoveAt = performance.now()
|
||||
|
||||
if (modality === "mouse") {
|
||||
applyInputState(true)
|
||||
@@ -107,11 +113,19 @@ function handleMouseOver(event: MouseEvent) {
|
||||
if (modality === "mouse") return
|
||||
if (!isMouseIntentTarget(event.target)) return
|
||||
|
||||
// Browsers fire mouseover/mouseenter when scrolling or re-rendering moves
|
||||
// content under a stationary cursor (e.g. sideways season browsing while
|
||||
// the pointer happens to rest over the episode grid). Without recent real
|
||||
// pointer motion this is not mouse intent — activating mouse input here
|
||||
// would let hover handlers steal keyboard/gamepad focus.
|
||||
if (performance.now() - lastAnyMouseMoveAt > MOUSE_OVER_INTENT_RECENCY_MS) return
|
||||
|
||||
// Entering an interactive target indicates likely mouse intent.
|
||||
activateMouseInput()
|
||||
}
|
||||
|
||||
function handleMouseIntentAction(event: MouseEvent | WheelEvent) {
|
||||
reportUserActivity()
|
||||
pointerVisible = true
|
||||
if (isMouseIntentTarget(event.target)) {
|
||||
activateMouseInput()
|
||||
@@ -124,6 +138,7 @@ function handleMouseIntentAction(event: MouseEvent | WheelEvent) {
|
||||
|
||||
function handleKeyboardActivity(event: KeyboardEvent) {
|
||||
if (event.metaKey || event.ctrlKey || event.altKey) return
|
||||
reportUserActivity()
|
||||
activateNonMouseInput("keyboard")
|
||||
}
|
||||
|
||||
|
||||
@@ -36,6 +36,10 @@ const FOCUSABLE_ATTR = "data-nav-focusable"
|
||||
const ROW_ATTR = "data-nav-row"
|
||||
const COL_ATTR = "data-nav-col"
|
||||
const ENTRY_COL_ATTR = "data-nav-entry-col"
|
||||
// Like ENTRY_COL_ATTR, but only applies when entering the row from above
|
||||
// (ArrowDown). Lets a row declare a fixed landing column for downward entry
|
||||
// without hijacking upward or horizontal moves.
|
||||
const ENTRY_COL_FROM_ABOVE_ATTR = "data-nav-entry-col-from-above"
|
||||
const SYNC_SCROLL_ROW_ATTR = "data-sync-scroll-row"
|
||||
const SYNC_SCROLL_GROUP_ATTR = "data-sync-scroll-group"
|
||||
const DEFAULT_SYNC_SCROLL_GROUP = "browse"
|
||||
@@ -99,7 +103,10 @@ function measureGlobalMetrics(group: string): boolean {
|
||||
const rowStyle = window.getComputedStyle(row)
|
||||
const paddingLeft = parseFloat(rowStyle.paddingLeft || "0")
|
||||
const viewportWidth = row.clientWidth
|
||||
const deadzoneInset = Math.max(paddingLeft, (viewportWidth - cardWidth) * SYNC_SCROLL_DEADZONE_RATIO)
|
||||
const deadzoneInset = Math.max(
|
||||
paddingLeft,
|
||||
(viewportWidth - cardWidth) * SYNC_SCROLL_DEADZONE_RATIO,
|
||||
)
|
||||
const leftDeadzoneRaw = rowStyle.getPropertyValue(SYNC_SCROLL_LEFT_DEADZONE_VAR).trim()
|
||||
const leftDeadzone = Number.isFinite(parseFloat(leftDeadzoneRaw))
|
||||
? Math.max(0, parseFloat(leftDeadzoneRaw))
|
||||
@@ -171,10 +178,7 @@ function getRowMaxScroll(row: HTMLElement): number {
|
||||
if (n === 0) return 0
|
||||
const lastCol = n - 1
|
||||
const lastItemLeft = m.paddingLeft + lastCol * m.stride
|
||||
const maxVisibleLeft = Math.max(
|
||||
m.paddingLeft,
|
||||
m.viewportWidth - m.cardWidth - m.rightDeadzone,
|
||||
)
|
||||
const maxVisibleLeft = Math.max(m.paddingLeft, m.viewportWidth - m.cardWidth - m.rightDeadzone)
|
||||
return Math.max(0, lastItemLeft - maxVisibleLeft)
|
||||
}
|
||||
|
||||
@@ -276,14 +280,8 @@ function updateSyncedRowTarget(anchorCol: number, anchorRow: HTMLElement | null
|
||||
if (!m) return
|
||||
|
||||
const itemLeft = m.paddingLeft + anchorCol * m.stride
|
||||
const leftVisibleLimit = Math.max(
|
||||
m.paddingLeft,
|
||||
m.leftDeadzone,
|
||||
)
|
||||
const rightVisibleLimit = Math.max(
|
||||
m.paddingLeft,
|
||||
m.viewportWidth - m.cardWidth - m.rightDeadzone,
|
||||
)
|
||||
const leftVisibleLimit = Math.max(m.paddingLeft, m.leftDeadzone)
|
||||
const rightVisibleLimit = Math.max(m.paddingLeft, m.viewportWidth - m.cardWidth - m.rightDeadzone)
|
||||
|
||||
// Keep focus inside the deadzone: no scroll while the focused item remains
|
||||
// between left and right limits.
|
||||
@@ -350,7 +348,9 @@ function getLocalSyncedRowCol(
|
||||
element: HTMLElement,
|
||||
requestedCol: number,
|
||||
): number {
|
||||
const cards = Array.from(anchorRow.querySelectorAll<HTMLElement>(`.media-card[${FOCUSABLE_ATTR}]`))
|
||||
const cards = Array.from(
|
||||
anchorRow.querySelectorAll<HTMLElement>(`.media-card[${FOCUSABLE_ATTR}]`),
|
||||
)
|
||||
if (cards.length === 0) return Math.max(0, requestedCol)
|
||||
|
||||
const cardCols = cards
|
||||
@@ -462,9 +462,7 @@ function ensureElementVisibleVertically(element: HTMLElement) {
|
||||
// Element finding / navigation (unchanged logic, uses getMetrics() now)
|
||||
// ---------------------------------------------------------------------------
|
||||
|
||||
function resolveOutOfBoundsNavigation(
|
||||
context: OutOfBoundsNavigationContext,
|
||||
): HTMLElement | null {
|
||||
function resolveOutOfBoundsNavigation(context: OutOfBoundsNavigationContext): HTMLElement | null {
|
||||
const handlers = Array.from(outOfBoundsHandlers)
|
||||
for (let i = handlers.length - 1; i >= 0; i--) {
|
||||
const result = handlers[i]?.(context)
|
||||
@@ -619,10 +617,7 @@ function findElementClosestToLogicalViewportX(
|
||||
return nearest
|
||||
}
|
||||
|
||||
function findNextElement(
|
||||
current: HTMLElement,
|
||||
direction: NavDirection,
|
||||
): HTMLElement | null {
|
||||
function findNextElement(current: HTMLElement, direction: NavDirection): HTMLElement | null {
|
||||
const currentRow = parseInt(current.getAttribute(ROW_ATTR) || "0", 10)
|
||||
const currentCol = parseInt(current.getAttribute(COL_ATTR) || "0", 10)
|
||||
const byRow = getElementsByRow()
|
||||
@@ -672,8 +667,21 @@ function findNextElement(
|
||||
desiredCol.value = currentCol
|
||||
}
|
||||
|
||||
const entryTarget = findElementAt(targetRow, targetCol, true)
|
||||
const targetRowElements = byRow.get(targetRow) ?? []
|
||||
|
||||
if (direction === "down") {
|
||||
for (const el of targetRowElements) {
|
||||
const fromAboveCol = el.element.getAttribute(ENTRY_COL_FROM_ABOVE_ATTR)
|
||||
if (fromAboveCol === null) continue
|
||||
const fromAboveTarget = targetRowElements.find((e) => e.col === parseInt(fromAboveCol, 10))
|
||||
if (fromAboveTarget) {
|
||||
desiredCol.value = fromAboveTarget.col
|
||||
return fromAboveTarget.element
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
const entryTarget = findElementAt(targetRow, targetCol, true)
|
||||
const hasEntryOverride = targetRowElements.some((el) => el.element.hasAttribute(ENTRY_COL_ATTR))
|
||||
if (hasEntryOverride) {
|
||||
return entryTarget?.element || null
|
||||
@@ -702,7 +710,7 @@ function findNextElement(
|
||||
}
|
||||
}
|
||||
|
||||
function focusElement(element: HTMLElement | null) {
|
||||
function focusElement(element: HTMLElement | null, options?: { preserveScroll?: boolean }) {
|
||||
if (!element) return
|
||||
if (!isElementInActiveScope(element)) return
|
||||
|
||||
@@ -714,8 +722,10 @@ function focusElement(element: HTMLElement | null) {
|
||||
element.classList.add("nav-focused")
|
||||
element.focus({ preventScroll: true })
|
||||
|
||||
ensureElementVisibleVertically(element)
|
||||
syncRowsToElement(element)
|
||||
if (!options?.preserveScroll) {
|
||||
ensureElementVisibleVertically(element)
|
||||
syncRowsToElement(element)
|
||||
}
|
||||
|
||||
focusedElement.value = element
|
||||
}
|
||||
@@ -727,13 +737,16 @@ function getFocusState(): { row: number; col: number } | null {
|
||||
return { row, col }
|
||||
}
|
||||
|
||||
function restoreFocusState(state: { row: number; col: number } | null) {
|
||||
function restoreFocusState(
|
||||
state: { row: number; col: number } | null,
|
||||
options?: { preserveScroll?: boolean },
|
||||
) {
|
||||
if (!state) return
|
||||
|
||||
const target = findElementAt(state.row, state.col)
|
||||
if (target) {
|
||||
setTimeout(() => {
|
||||
focusElement(target.element)
|
||||
focusElement(target.element, options)
|
||||
}, 50)
|
||||
}
|
||||
}
|
||||
@@ -893,6 +906,32 @@ export function installKeyboardNavigation() {
|
||||
})
|
||||
}
|
||||
|
||||
export interface SyncedRowScrollSnapshot {
|
||||
rows: [HTMLElement, number][]
|
||||
offset: number
|
||||
targetOffset: number
|
||||
}
|
||||
|
||||
function snapshotSyncedRowScroll(): SyncedRowScrollSnapshot {
|
||||
return {
|
||||
rows: getSyncedRows().map((row) => [row, row.scrollLeft]),
|
||||
offset: syncedRowsCurrentOffset,
|
||||
targetOffset: syncedRowsTargetOffset,
|
||||
}
|
||||
}
|
||||
|
||||
function restoreSyncedRowScroll(snapshot: SyncedRowScrollSnapshot) {
|
||||
stopSyncedRowAnimation()
|
||||
for (const [row, scrollLeft] of snapshot.rows) {
|
||||
if (row.isConnected) {
|
||||
row.scrollLeft = scrollLeft
|
||||
}
|
||||
}
|
||||
syncedRowsCurrentOffset = snapshot.offset
|
||||
syncedRowsTargetOffset = snapshot.targetOffset
|
||||
lastSyncedRowsAnimationAt = null
|
||||
}
|
||||
|
||||
export function useKeyboardNavigation() {
|
||||
return {
|
||||
focusedElement,
|
||||
@@ -901,6 +940,8 @@ export function useKeyboardNavigation() {
|
||||
focusAt,
|
||||
getFocusState,
|
||||
restoreFocusState,
|
||||
snapshotSyncedRowScroll,
|
||||
restoreSyncedRowScroll,
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
@@ -159,10 +159,7 @@ export function useMediaWebSocket() {
|
||||
return { ...normalizeSeries(series, rootId, people), id, root_id: rootId }
|
||||
}
|
||||
|
||||
function normalizeCastMember(
|
||||
member: unknown,
|
||||
people: Map<number, Person>,
|
||||
): CastMember {
|
||||
function normalizeCastMember(member: unknown, people: Map<number, Person>): CastMember {
|
||||
if (!Array.isArray(member)) {
|
||||
return {
|
||||
name: "",
|
||||
@@ -346,7 +343,10 @@ export function useMediaWebSocket() {
|
||||
}
|
||||
}
|
||||
|
||||
function mergeItemsByHash<T extends MovieUi | SeriesUi>(items: T[], mergeFn: (a: T, b: T) => T): T[] {
|
||||
function mergeItemsByHash<T extends MovieUi | SeriesUi>(
|
||||
items: T[],
|
||||
mergeFn: (a: T, b: T) => T,
|
||||
): T[] {
|
||||
const map = new Map<string, T[]>()
|
||||
for (const item of items) {
|
||||
const hash = getContentHash(item.id)
|
||||
@@ -436,7 +436,14 @@ export function useMediaWebSocket() {
|
||||
connected.value = wsRef.value?.readyState === WebSocket.OPEN
|
||||
}
|
||||
|
||||
function applyRootInit(rootId: string, rootData: { movies: Record<string, Movie>; series: Record<string, Series>; people?: Record<string, unknown> }) {
|
||||
function applyRootInit(
|
||||
rootId: string,
|
||||
rootData: {
|
||||
movies: Record<string, Movie>
|
||||
series: Record<string, Series>
|
||||
people?: Record<string, unknown>
|
||||
},
|
||||
) {
|
||||
const state = ensureRootState(rootId)
|
||||
|
||||
state.peopleMap.clear()
|
||||
@@ -502,7 +509,10 @@ export function useMediaWebSocket() {
|
||||
const parsed = Number(id)
|
||||
const normalized = normalizePerson(person)
|
||||
if (Number.isFinite(parsed)) {
|
||||
state.peopleMap.set(parsed, normalized || { name: "", profile_path: null, gender: null })
|
||||
state.peopleMap.set(
|
||||
parsed,
|
||||
normalized || { name: "", profile_path: null, gender: null },
|
||||
)
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -0,0 +1,128 @@
|
||||
import type { TaskInfo } from "../types"
|
||||
|
||||
export type RootTaskInfo = TaskInfo & { root_id: string }
|
||||
|
||||
export interface ProgressRootState {
|
||||
rootId: string
|
||||
rootLabel: string
|
||||
scanTarget: string | null
|
||||
phaseLabel: string
|
||||
phaseDetail: string | null
|
||||
progressPercent: number
|
||||
progressLabel: string | null
|
||||
isDeterminate: boolean
|
||||
toneClass: string
|
||||
}
|
||||
|
||||
function normalizePosixPath(value: string): string {
|
||||
return value.replace(/\\/g, "/")
|
||||
}
|
||||
|
||||
function extractScanPath(detail: string): string | null {
|
||||
if (!detail.startsWith("Scanning:")) return null
|
||||
let value = detail.replace(/^Scanning:\s*/i, "").trim()
|
||||
value = value.replace(/\s*\(\d+\s+found\)\s*$/i, "").trim()
|
||||
return value || null
|
||||
}
|
||||
|
||||
function buildScanTarget(rootPath: string | null, detail: string): string | null {
|
||||
const rawPath = extractScanPath(detail)
|
||||
if (!rawPath) return null
|
||||
|
||||
const posixRaw = normalizePosixPath(rawPath)
|
||||
const posixRoot = rootPath ? normalizePosixPath(rootPath) : null
|
||||
|
||||
if (posixRoot) {
|
||||
const lowRaw = posixRaw.toLowerCase()
|
||||
const lowRoot = posixRoot.toLowerCase()
|
||||
if (lowRaw === lowRoot) return posixRoot
|
||||
if (lowRaw.startsWith(`${lowRoot}/`)) {
|
||||
return posixRaw.slice(posixRoot.length).replace(/^\/+/, "")
|
||||
}
|
||||
}
|
||||
return posixRaw
|
||||
}
|
||||
|
||||
function describeRootProgress(
|
||||
rootId: string,
|
||||
rootPath: string | null,
|
||||
tasksForRoot: RootTaskInfo[],
|
||||
isInitialScanMode: boolean,
|
||||
): ProgressRootState | null {
|
||||
const running = tasksForRoot.filter((task) => task.status === "running")
|
||||
const latestError = [...tasksForRoot].reverse().find((task) => task.status === "error") || null
|
||||
|
||||
if (running.length === 0 && !latestError) return null
|
||||
|
||||
const scanTask = running.find((task) => task.id.startsWith("scan-")) || null
|
||||
const showreelCount = running.filter((task) => task.id.startsWith("showreel-")).length
|
||||
const otherRunningCount = running.length - (scanTask ? 1 : 0) - showreelCount
|
||||
|
||||
let phaseLabel = "Processing media"
|
||||
let phaseDetail: string | null = null
|
||||
let scanTarget: string | null = null
|
||||
let isDeterminate = false
|
||||
let progressPercent = 0
|
||||
let progressLabel: string | null = null
|
||||
let toneClass = ""
|
||||
|
||||
if (scanTask) {
|
||||
const detail = (scanTask.detail || "").trim()
|
||||
scanTarget = buildScanTarget(rootPath, detail)
|
||||
if (detail.startsWith("Scanning:")) {
|
||||
phaseLabel = isInitialScanMode ? "Scanning folders" : "Checking for updates"
|
||||
} else if (/^Processing\s+\d+\s+(items|movies|series)/i.test(detail)) {
|
||||
phaseLabel = "Preparing titles"
|
||||
} else if (/^(Starting scan|No new items|Done|Scan cancelled)/i.test(detail)) {
|
||||
phaseLabel = isInitialScanMode ? "Scanning folders" : "Checking for updates"
|
||||
} else {
|
||||
phaseLabel = "Fetching metadata"
|
||||
phaseDetail = detail || null
|
||||
}
|
||||
if (scanTask.progress > 0 && scanTask.progress <= 1) {
|
||||
isDeterminate = true
|
||||
progressPercent = Math.max(1, Math.round(scanTask.progress * 100))
|
||||
progressLabel = `${progressPercent}%`
|
||||
}
|
||||
} else if (showreelCount > 0) {
|
||||
phaseLabel = "Generating previews"
|
||||
} else if (otherRunningCount > 0) {
|
||||
phaseLabel = "Finalizing updates"
|
||||
} else if (latestError) {
|
||||
phaseLabel = "Needs attention"
|
||||
phaseDetail = latestError.detail || "A background task failed"
|
||||
toneClass = "activity-root-error"
|
||||
}
|
||||
|
||||
return {
|
||||
rootId,
|
||||
rootLabel: rootId,
|
||||
scanTarget,
|
||||
phaseLabel,
|
||||
phaseDetail,
|
||||
progressPercent,
|
||||
progressLabel,
|
||||
isDeterminate,
|
||||
toneClass,
|
||||
}
|
||||
}
|
||||
|
||||
export function computeProgressRoots(
|
||||
tasks: Iterable<RootTaskInfo>,
|
||||
getRootPath: (rootId: string) => string | null,
|
||||
isInitialScanMode: boolean,
|
||||
): ProgressRootState[] {
|
||||
const byRoot = new Map<string, RootTaskInfo[]>()
|
||||
for (const task of tasks) {
|
||||
const list = byRoot.get(task.root_id) || []
|
||||
list.push(task)
|
||||
byRoot.set(task.root_id, list)
|
||||
}
|
||||
|
||||
const rows: ProgressRootState[] = []
|
||||
for (const [rootId, rootTasks] of byRoot) {
|
||||
const row = describeRootProgress(rootId, getRootPath(rootId), rootTasks, isInitialScanMode)
|
||||
if (row) rows.push(row)
|
||||
}
|
||||
return rows.sort((a, b) => a.rootLabel.localeCompare(b.rootLabel))
|
||||
}
|
||||
@@ -17,9 +17,9 @@ const STORAGE_KEY = "MediaHive"
|
||||
const RESOLUTION_PRIORITY: Record<string, number> = {
|
||||
"8K": 5,
|
||||
"4K": 4,
|
||||
"FHD": 3,
|
||||
"HD": 2,
|
||||
"SD": 1,
|
||||
FHD: 3,
|
||||
HD: 2,
|
||||
SD: 1,
|
||||
}
|
||||
|
||||
// Max resolution priority allowed for each preference level
|
||||
@@ -59,7 +59,13 @@ function loadSettings(): MediaHiveSettings {
|
||||
} catch {
|
||||
// ignore parse errors
|
||||
}
|
||||
return { preferredResolution: "rmax", preferredHdr: "none", playerId: "default", playerCustomCmd: null, playerMpcPort: null }
|
||||
return {
|
||||
preferredResolution: "rmax",
|
||||
preferredHdr: "none",
|
||||
playerId: "default",
|
||||
playerCustomCmd: null,
|
||||
playerMpcPort: null,
|
||||
}
|
||||
}
|
||||
|
||||
const settings = reactive<MediaHiveSettings>(loadSettings())
|
||||
|
||||
@@ -0,0 +1,9 @@
|
||||
import { ref } from "vue"
|
||||
|
||||
// Settings is an overlay, not a route: opening it must not change the URL or
|
||||
// the view behind it, so the open state is plain shared local state.
|
||||
const settingsOpen = ref(false)
|
||||
|
||||
export function useSettingsOpen() {
|
||||
return settingsOpen
|
||||
}
|
||||
@@ -6,10 +6,60 @@ import { installKeyboardNavigation } from "./composables/useKeyboardNavigation"
|
||||
import { installGamepadNavigation } from "./composables/useGamepadNavigation"
|
||||
import { installInputModalityTracking } from "./composables/useInputModality"
|
||||
|
||||
function postClientError(payload: {
|
||||
message: string
|
||||
stack: string | null
|
||||
source: string | null
|
||||
}) {
|
||||
fetch("/api/client-log", {
|
||||
method: "POST",
|
||||
headers: { "Content-Type": "application/json" },
|
||||
body: JSON.stringify(payload),
|
||||
}).catch(() => {})
|
||||
}
|
||||
|
||||
function installErrorCapture() {
|
||||
window.addEventListener("error", (event) => {
|
||||
const source =
|
||||
event.filename != null ? `${event.filename}:${event.lineno ?? 0}:${event.colno ?? 0}` : null
|
||||
postClientError({
|
||||
message: event.message || String(event.error ?? "Unknown error"),
|
||||
stack: event.error?.stack ?? null,
|
||||
source,
|
||||
})
|
||||
})
|
||||
window.addEventListener("unhandledrejection", (event) => {
|
||||
const reason = event.reason
|
||||
postClientError({
|
||||
message: reason instanceof Error ? reason.message : `Unhandled rejection: ${String(reason)}`,
|
||||
stack: reason instanceof Error ? (reason.stack ?? null) : null,
|
||||
source: "unhandledrejection",
|
||||
})
|
||||
})
|
||||
}
|
||||
|
||||
function installReloadShortcut() {
|
||||
document.addEventListener(
|
||||
"keydown",
|
||||
(event) => {
|
||||
if (
|
||||
event.key === "F5" ||
|
||||
((event.ctrlKey || event.metaKey) && event.key.toLowerCase() === "r")
|
||||
) {
|
||||
event.preventDefault()
|
||||
window.location.reload()
|
||||
}
|
||||
},
|
||||
{ capture: true },
|
||||
)
|
||||
}
|
||||
|
||||
// Install global keyboard navigation handlers immediately
|
||||
installInputModalityTracking()
|
||||
installKeyboardNavigation()
|
||||
installGamepadNavigation()
|
||||
installReloadShortcut()
|
||||
installErrorCapture()
|
||||
|
||||
// Unregister any legacy service workers — MediaHive no longer uses a PWA/SW.
|
||||
if ("serviceWorker" in navigator) {
|
||||
|
||||
@@ -37,9 +37,9 @@ const router = createRouter({
|
||||
component: EmptyRouteComponent,
|
||||
},
|
||||
{
|
||||
// Settings is now an overlay with no URL of its own; keep old links working.
|
||||
path: "/settings",
|
||||
name: "settings",
|
||||
component: EmptyRouteComponent,
|
||||
redirect: "/movies",
|
||||
},
|
||||
{
|
||||
path: "/series",
|
||||
|
||||
@@ -1,13 +1,7 @@
|
||||
// Search Web Worker - runs search off the main thread
|
||||
// This file is loaded as a Web Worker, not imported as a module.
|
||||
|
||||
import type {
|
||||
MovieUi,
|
||||
SeriesUi,
|
||||
MatchedPerson,
|
||||
MatchedEpisode,
|
||||
SearchMatchInfo,
|
||||
} from "./types"
|
||||
import type { MovieUi, SeriesUi, MatchedPerson, MatchedEpisode, SearchMatchInfo } from "./types"
|
||||
|
||||
// ---------------------------------------------------------------------------
|
||||
// Message types
|
||||
@@ -65,7 +59,7 @@ let series: SeriesUi[] = []
|
||||
function normalizeSearchText(value: string): string {
|
||||
return value
|
||||
.toLowerCase()
|
||||
.replace(/[^a-z0-9\-]+/g, " ")
|
||||
.replace(/[^a-z0-9-]+/g, " ")
|
||||
.trim()
|
||||
.replace(/\s+/g, " ")
|
||||
}
|
||||
@@ -277,7 +271,9 @@ function getMatchedWordIndexes(queryWords: string[], value: string): number[] {
|
||||
}
|
||||
|
||||
function mergePersonMatch(target: PersonMatch[], candidate: PersonCandidate): void {
|
||||
const existing = target.find((person) => person.name.toLowerCase() === candidate.name.toLowerCase())
|
||||
const existing = target.find(
|
||||
(person) => person.name.toLowerCase() === candidate.name.toLowerCase(),
|
||||
)
|
||||
if (existing) {
|
||||
if (!existing.roles.includes(candidate.role)) existing.roles.push(candidate.role)
|
||||
if (candidate.highlightRoles) existing.highlightRoles = true
|
||||
@@ -292,9 +288,7 @@ function mergePersonMatch(target: PersonMatch[], candidate: PersonCandidate): vo
|
||||
}
|
||||
|
||||
function getBestContiguousWordRun(indexes: number[], availableIndexes: Set<number>): number[] {
|
||||
const sorted = indexes
|
||||
.filter((index) => availableIndexes.has(index))
|
||||
.sort((a, b) => a - b)
|
||||
const sorted = indexes.filter((index) => availableIndexes.has(index)).sort((a, b) => a - b)
|
||||
|
||||
if (sorted.length === 0) return []
|
||||
|
||||
|
||||
@@ -106,6 +106,11 @@ html.mouse-active ::-webkit-scrollbar-thumb:hover {
|
||||
transition: top 0.6s cubic-bezier(0.4, 0, 0.2, 1);
|
||||
}
|
||||
|
||||
/* Leave room for the fixed app-exit button in desktop (pywebview) mode. */
|
||||
.header--gui {
|
||||
padding-right: 3.5rem;
|
||||
}
|
||||
|
||||
.header::before {
|
||||
content: "";
|
||||
position: absolute;
|
||||
@@ -420,6 +425,10 @@ html:not(.mouse-active) .btn-secondary.nav-focused {
|
||||
outline: none;
|
||||
text-decoration: none;
|
||||
color: inherit;
|
||||
/* Skip rendering work for cards scrolled out of view (long rows). Width is
|
||||
fixed; the intrinsic height is only a pre-first-render estimate. */
|
||||
content-visibility: auto;
|
||||
contain-intrinsic-height: auto 330px;
|
||||
}
|
||||
|
||||
html.mouse-active .media-card:hover,
|
||||
|
||||
@@ -53,6 +53,7 @@ export interface Torrent {
|
||||
audio: string | null
|
||||
audio_languages: string[] | null
|
||||
subtitle_languages: string[] | null
|
||||
external_subtitle_languages?: string[] | null
|
||||
hdr?: boolean
|
||||
dovi?: boolean
|
||||
atmos?: boolean
|
||||
@@ -109,6 +110,13 @@ export interface Series {
|
||||
seasons: Season[]
|
||||
}
|
||||
|
||||
/** A series' single continue point (last watched position). */
|
||||
export interface SeriesResumePoint {
|
||||
seasonNumber: number
|
||||
episodeNumber: number
|
||||
positionSeconds: number
|
||||
}
|
||||
|
||||
export interface MovieUi extends Movie {
|
||||
id: string
|
||||
root_id: string | null
|
||||
|
||||
@@ -16,17 +16,18 @@ const LANGUAGE_TO_COUNTRY: Record<string, string> = {
|
||||
// Spanish (including LATAM variants collapsed to Spain flag)
|
||||
es: "ES",
|
||||
spa: "ES",
|
||||
esp: "ES",
|
||||
esl: "ES",
|
||||
spl: "ES",
|
||||
"es-es": "ES",
|
||||
"es-419": "ES",
|
||||
"spa-la": "ES",
|
||||
|
||||
// Portuguese
|
||||
// Portuguese (Brazilian variant collapses to Portugal flag)
|
||||
pt: "PT",
|
||||
por: "PT",
|
||||
"pt-pt": "PT",
|
||||
"pt-br": "BR",
|
||||
"pt-br": "PT",
|
||||
|
||||
// Major European languages
|
||||
fr: "FR",
|
||||
@@ -49,7 +50,7 @@ const LANGUAGE_TO_COUNTRY: Record<string, string> = {
|
||||
fi: "FI",
|
||||
fin: "FI",
|
||||
pl: "PL",
|
||||
पोल: "PL",
|
||||
pol: "PL",
|
||||
cs: "CZ",
|
||||
ces: "CZ",
|
||||
cze: "CZ",
|
||||
@@ -121,6 +122,113 @@ const LANGUAGE_TO_COUNTRY: Record<string, string> = {
|
||||
eu: "ES",
|
||||
baq: "ES",
|
||||
eus: "ES",
|
||||
gl: "ES",
|
||||
glg: "ES",
|
||||
|
||||
// Additional ISO 639-2 codes (bibliographic + terminology)
|
||||
mk: "MK",
|
||||
mkd: "MK",
|
||||
mac: "MK",
|
||||
et: "EE",
|
||||
est: "EE",
|
||||
lv: "LV",
|
||||
lav: "LV",
|
||||
lt: "LT",
|
||||
lit: "LT",
|
||||
is: "IS",
|
||||
isl: "IS",
|
||||
ice: "IS",
|
||||
ga: "IE",
|
||||
gle: "IE",
|
||||
cy: "GB",
|
||||
cym: "GB",
|
||||
wel: "GB",
|
||||
gd: "GB",
|
||||
gla: "GB",
|
||||
mt: "MT",
|
||||
mlt: "MT",
|
||||
sq: "AL",
|
||||
sqi: "AL",
|
||||
alb: "AL",
|
||||
be: "BY",
|
||||
bel: "BY",
|
||||
bs: "BA",
|
||||
bos: "BA",
|
||||
scc: "RS",
|
||||
scr: "HR",
|
||||
nb: "NO",
|
||||
nob: "NO",
|
||||
nn: "NO",
|
||||
nno: "NO",
|
||||
kk: "KZ",
|
||||
kaz: "KZ",
|
||||
az: "AZ",
|
||||
aze: "AZ",
|
||||
hy: "AM",
|
||||
hye: "AM",
|
||||
arm: "AM",
|
||||
ka: "GE",
|
||||
kat: "GE",
|
||||
geo: "GE",
|
||||
uz: "UZ",
|
||||
uzb: "UZ",
|
||||
tk: "TM",
|
||||
tuk: "TM",
|
||||
tg: "TJ",
|
||||
tgk: "TJ",
|
||||
ky: "KG",
|
||||
kir: "KG",
|
||||
mn: "MN",
|
||||
mon: "MN",
|
||||
bo: "CN",
|
||||
bod: "CN",
|
||||
tib: "CN",
|
||||
my: "MM",
|
||||
mya: "MM",
|
||||
bur: "MM",
|
||||
km: "KH",
|
||||
khm: "KH",
|
||||
lo: "LA",
|
||||
lao: "LA",
|
||||
si: "LK",
|
||||
sin: "LK",
|
||||
ne: "NP",
|
||||
nep: "NP",
|
||||
bn: "BD",
|
||||
ben: "BD",
|
||||
ta: "IN",
|
||||
tam: "IN",
|
||||
te: "IN",
|
||||
tel: "IN",
|
||||
kn: "IN",
|
||||
kan: "IN",
|
||||
ml: "IN",
|
||||
mal: "IN",
|
||||
mr: "IN",
|
||||
mar: "IN",
|
||||
gu: "IN",
|
||||
guj: "IN",
|
||||
pa: "IN",
|
||||
pan: "IN",
|
||||
tl: "PH",
|
||||
tgl: "PH",
|
||||
fil: "PH",
|
||||
af: "ZA",
|
||||
afr: "ZA",
|
||||
am: "ET",
|
||||
amh: "ET",
|
||||
so: "SO",
|
||||
som: "SO",
|
||||
ha: "NG",
|
||||
hau: "NG",
|
||||
yo: "NG",
|
||||
yor: "NG",
|
||||
ig: "NG",
|
||||
ibo: "NG",
|
||||
ku: "TR",
|
||||
kur: "TR",
|
||||
ps: "AF",
|
||||
pus: "AF",
|
||||
}
|
||||
|
||||
function normalizeLanguageCode(code: string): string {
|
||||
@@ -265,9 +373,13 @@ export function mapLanguageToCountry(code: string): string | null {
|
||||
const direct = LANGUAGE_TO_COUNTRY[normalized]
|
||||
if (direct) return direct
|
||||
|
||||
// region-tag style code like en-us / pt-br / es-mx
|
||||
// region-tag style code like en-us / pt-br / es-mx: variants collapse to
|
||||
// the base language's host-country flag; only fall back to the region
|
||||
// itself when the base language is unmapped.
|
||||
const hyphenParts = normalized.split("-")
|
||||
if (hyphenParts.length >= 2) {
|
||||
const base = LANGUAGE_TO_COUNTRY[hyphenParts[0]]
|
||||
if (base) return base
|
||||
const region = hyphenParts[hyphenParts.length - 1]
|
||||
if (/^[a-z]{2}$/i.test(region)) {
|
||||
return region.toUpperCase()
|
||||
@@ -341,10 +453,15 @@ export function buildLanguageFlags(codes: string[] | null | undefined): {
|
||||
const LANGUAGE_NAME_OVERRIDES: Record<string, string> = {
|
||||
eng: "English",
|
||||
spa: "Spanish",
|
||||
esp: "Spanish",
|
||||
"spa-la": "Spanish",
|
||||
"es-419": "Spanish",
|
||||
esl: "Spanish",
|
||||
spl: "Spanish",
|
||||
por: "Portuguese",
|
||||
"pt-br": "Portuguese",
|
||||
nob: "Norwegian",
|
||||
nno: "Norwegian",
|
||||
fre: "French",
|
||||
fra: "French",
|
||||
ger: "German",
|
||||
@@ -431,6 +548,52 @@ function summarizeLanguageCodes(codes: string[] | null | undefined): string {
|
||||
return names.join(", ")
|
||||
}
|
||||
|
||||
const REGION_NAME_OVERRIDES: Record<string, string> = {
|
||||
GB: "UK",
|
||||
US: "US",
|
||||
}
|
||||
|
||||
function toRegionName(countryCode: string): string {
|
||||
const override = REGION_NAME_OVERRIDES[countryCode]
|
||||
if (override) return override
|
||||
const display = new Intl.DisplayNames(["en"], { type: "region" })
|
||||
return display.of(countryCode) ?? countryCode
|
||||
}
|
||||
|
||||
export function formatLanguageFlagTitle(
|
||||
entry: LanguageFlagEntry,
|
||||
externalCodes?: string[] | null,
|
||||
): string {
|
||||
const names: string[] = []
|
||||
const variants: string[] = []
|
||||
const external = new Set((externalCodes ?? []).map((c) => resolveLanguageIdentifier(c)))
|
||||
let hasExternal = false
|
||||
for (const code of entry.sourceCodes) {
|
||||
const normalized = resolveLanguageIdentifier(code)
|
||||
const base = normalized.split("-", 1)[0]
|
||||
const name = toLanguageName(base)
|
||||
if (!names.includes(name)) names.push(name)
|
||||
// Explicit region tags (en-us, es-419) become parenthesized variants;
|
||||
// plain codes contribute their host country.
|
||||
const suffix = normalized.split("-").pop() ?? ""
|
||||
const region =
|
||||
/^[a-z]{2}$|^\d{3}$/i.test(suffix) && normalized.includes("-")
|
||||
? suffix.toUpperCase()
|
||||
: mapLanguageToCountry(code)
|
||||
const regionName = region ? toRegionName(region) : null
|
||||
const variant = external.has(normalized)
|
||||
? regionName
|
||||
? `${regionName} srt`
|
||||
: "srt"
|
||||
: regionName
|
||||
if (variant && !variants.includes(variant)) variants.push(variant)
|
||||
if (external.has(normalized)) hasExternal = true
|
||||
}
|
||||
const title = names.join(" / ")
|
||||
if (variants.length > 1 || hasExternal) return `${title} (${variants.join(", ")})`
|
||||
return title
|
||||
}
|
||||
|
||||
export function formatAudioSubtitleSummary(
|
||||
audioCodes: string[] | null | undefined,
|
||||
subtitleCodes: string[] | null | undefined,
|
||||
|
||||
@@ -5,13 +5,14 @@
|
||||
* Configures Vite for FastAPI backend integration:
|
||||
* - Proxies /api/* requests to the FastAPI backend
|
||||
* - Builds to the Python module's frontend-build directory
|
||||
* - Disables Vite's screen clearing on startup
|
||||
*
|
||||
* Options:
|
||||
* paths - Array of paths to proxy (default: ["/api"])
|
||||
* paths - Array of paths to proxy (default: ['/api'])
|
||||
*/
|
||||
|
||||
export default function fastapiVue({ paths = ["/api"] } = {}) {
|
||||
const backendUrl = process.env.MEDIAHIVE_BACKEND_URL || "http://localhost:8420"
|
||||
export default function fastapiVue({ paths = ['/api'] } = {}) {
|
||||
const backendUrl = process.env.MEDIAHIVE_BACKEND_URL || 'http://localhost:8421'
|
||||
|
||||
// Build proxy configuration for each path
|
||||
const proxy = {}
|
||||
@@ -24,11 +25,12 @@ export default function fastapiVue({ paths = ["/api"] } = {}) {
|
||||
}
|
||||
|
||||
return {
|
||||
name: "vite-plugin-fastapi-mediahive",
|
||||
name: 'vite-plugin-fastapi-mediahive',
|
||||
config: () => ({
|
||||
clearScreen: false,
|
||||
server: { proxy },
|
||||
build: {
|
||||
outDir: "../mediahive/frontend-build",
|
||||
outDir: '../mediahive/frontend-build',
|
||||
emptyOutDir: true,
|
||||
},
|
||||
}),
|
||||
|
||||
@@ -0,0 +1,19 @@
|
||||
pre-commit:
|
||||
parallel: true
|
||||
commands:
|
||||
ruff-check:
|
||||
glob: "*.py"
|
||||
run: .venv/bin/ruff check --fix {staged_files}
|
||||
stage_fixed: true
|
||||
ruff-format:
|
||||
glob: "*.py"
|
||||
run: .venv/bin/ruff format {staged_files}
|
||||
stage_fixed: true
|
||||
oxlint:
|
||||
glob: "frontend/src/**"
|
||||
run: npm --prefix frontend run lint
|
||||
stage_fixed: true
|
||||
oxfmt:
|
||||
glob: "frontend/src/**"
|
||||
run: npm --prefix frontend run format
|
||||
stage_fixed: true
|
||||
+94
-7
@@ -1,16 +1,20 @@
|
||||
"""MediaHive CLI entrypoint."""
|
||||
|
||||
import os
|
||||
|
||||
# Must be set before fastapi_vue env bindings are created (mediahive.config).
|
||||
os.environ["FASTAPI_VUE"] = "MEDIAHIVE"
|
||||
|
||||
import argparse
|
||||
import asyncio
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from fastapi_vue import server
|
||||
from fastapi_vue import env, server
|
||||
|
||||
from mediahive.config import config
|
||||
|
||||
DEFAULT_PORT = 8420
|
||||
DEVMODE = os.getenv("MEDIAHIVE_DEV") == "1"
|
||||
|
||||
|
||||
def _configure_windows_event_loop_policy() -> None:
|
||||
@@ -33,6 +37,54 @@ def _derive_name(path: str) -> str:
|
||||
return p.name or p.anchor.strip("/\\").lower() or "media"
|
||||
|
||||
|
||||
def _dev_reload_supervisor() -> None:
|
||||
"""Windows dev-mode reloader: restart the server process on changes.
|
||||
|
||||
uvicorn's own reload cannot work here: it restarts the child with
|
||||
CTRL_C_EVENT, which is never delivered to a plain spawn child (no own
|
||||
console process group), so the reloader blocks in join() after the
|
||||
first reload and the old server — scanner included — keeps running.
|
||||
And even when the child does restart, uvicorn passes it sockets bound
|
||||
by the parent; ProactorEventLoop cannot register inherited sockets
|
||||
with IOCP (WinError 87 on accept), while the selector loop would lose
|
||||
asyncio subprocess support (ffmpeg/ffprobe showreel generation).
|
||||
|
||||
So: watch the package directory ourselves and respawn a fresh child
|
||||
process that binds its own sockets. The child runs with
|
||||
MEDIAHIVE_DEV_CHILD=1 and reload disabled. Scanner state is persisted
|
||||
after every scan, so a non-graceful child exit on reload loses nothing.
|
||||
"""
|
||||
import subprocess
|
||||
|
||||
import watchfiles
|
||||
|
||||
watch_dir = Path(__file__).parent
|
||||
argv = [sys.executable, "-m", "mediahive", *sys.argv[1:]]
|
||||
child_env = dict(os.environ, MEDIAHIVE_DEV_CHILD="1")
|
||||
|
||||
print(f"Dev reloader: watching {watch_dir}", file=sys.stderr)
|
||||
proc = subprocess.Popen(argv, env=child_env)
|
||||
try:
|
||||
for changes in watchfiles.watch(watch_dir):
|
||||
changed = sorted({str(Path(p).name) for _, p in changes})
|
||||
print(
|
||||
f"Dev reloader: change in {', '.join(changed[:5])} — restarting",
|
||||
file=sys.stderr,
|
||||
)
|
||||
proc.terminate()
|
||||
proc.wait()
|
||||
proc = subprocess.Popen(argv, env=child_env)
|
||||
except KeyboardInterrupt:
|
||||
pass
|
||||
finally:
|
||||
proc.terminate()
|
||||
try:
|
||||
proc.wait(timeout=5)
|
||||
except subprocess.TimeoutExpired:
|
||||
proc.kill()
|
||||
proc.wait()
|
||||
|
||||
|
||||
def main() -> None:
|
||||
_configure_windows_event_loop_policy()
|
||||
|
||||
@@ -54,9 +106,30 @@ def main() -> None:
|
||||
action="append",
|
||||
help=(f"Endpoint (default: localhost:{DEFAULT_PORT})."),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--gui",
|
||||
action="store_true",
|
||||
help="Run with GUI (fails if GUI dependencies are not installed)",
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
# --listen implies server-only mode; use --gui to force GUI even with --listen.
|
||||
use_gui = args.gui or not args.listen
|
||||
|
||||
if use_gui:
|
||||
try:
|
||||
from mediahive.winmain import gui_main
|
||||
except ImportError as exc:
|
||||
if args.gui:
|
||||
raise RuntimeError(
|
||||
"GUI dependencies are not installed. "
|
||||
"Install with: uv pip install mediahive[gui]"
|
||||
) from exc
|
||||
else:
|
||||
gui_main()
|
||||
return
|
||||
|
||||
if args.media_folders:
|
||||
roots: dict[str, str] = {}
|
||||
for path in args.media_folders:
|
||||
@@ -71,15 +144,29 @@ def main() -> None:
|
||||
name = f"{base_name}{suffix}"
|
||||
suffix += 1
|
||||
roots[name] = p.as_posix()
|
||||
os.environ["MEDIAHIVE_ROOTS"] = json.dumps(roots)
|
||||
# Teleported to the server process by fastapi-vue's server.run().
|
||||
config.roots = roots
|
||||
|
||||
if (
|
||||
env.dev
|
||||
and sys.platform == "win32"
|
||||
and os.environ.get("MEDIAHIVE_DEV_CHILD") != "1"
|
||||
):
|
||||
_dev_reload_supervisor()
|
||||
return
|
||||
|
||||
dev = {"reload": True, "reload_dirs": ["mediahive"]}
|
||||
server.run(
|
||||
"mediahive.server:app",
|
||||
listen=args.listen,
|
||||
default_port=DEFAULT_PORT,
|
||||
server_header=False,
|
||||
loop="none" if sys.platform == "win32" else "auto",
|
||||
**(dev if DEVMODE and sys.platform != "win32" else {}),
|
||||
reload=Path(__file__).parent if env.dev and sys.platform != "win32" else False,
|
||||
# fastapi-vue routes the root logger at INFO in dev / WARNING in prod;
|
||||
# keep our own loggers visible in production too.
|
||||
log_config={
|
||||
"loggers": {"mediahive": {"level": "DEBUG" if env.dev else "INFO"}}
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -1,253 +0,0 @@
|
||||
"""Custom access logging middleware for FastAPI/Uvicorn."""
|
||||
|
||||
import logging
|
||||
import sys
|
||||
import time
|
||||
from ipaddress import IPv6Address
|
||||
|
||||
from starlette.middleware.base import BaseHTTPMiddleware
|
||||
from starlette.requests import Request
|
||||
from starlette.responses import Response
|
||||
|
||||
logger = logging.getLogger("mediahive.access")
|
||||
|
||||
_RESET = "\033[0m"
|
||||
_STATUS_INFO = "\033[32m" # 1xx (green)
|
||||
_STATUS_OK = "\033[1;92m" # 2xx (bright green)
|
||||
_STATUS_REDIRECT = "\033[32m" # 3xx (green)
|
||||
_STATUS_CLIENT_ERR = "\033[0;31m" # 4xx (red)
|
||||
_STATUS_SERVER_ERR = "\033[1;91m" # 5xx (bold bright red)
|
||||
_METHOD_READ = "\033[0;34m" # GET, HEAD, OPTIONS (blue)
|
||||
_METHOD_WRITE = "\033[1;94m" # POST, PUT, DELETE, PATCH (bold bright blue)
|
||||
_HOST = "\033[38;5;242m" # hostname (dark grey)
|
||||
_PATH = "\033[38;5;250m" # path (white)
|
||||
_TIMING = "\033[38;5;242m" # timing/devmode (dark grey)
|
||||
_WS_OPEN = "\033[38;5;226m" # WebSocket connect (brightest yellow from 6x6x6 cube)
|
||||
_WS_CLOSE = "\033[38;5;142m" # WebSocket disconnect (significantly dimmer yellow)
|
||||
_WS_STATUS = "\033[38;5;242m" # WebSocket close status (dark grey)
|
||||
|
||||
|
||||
def format_ipv6_network(ip: str) -> str:
|
||||
"""Format IPv6 address to show only network part (first 64 bits).
|
||||
|
||||
Special addresses are returned as-is for clarity:
|
||||
- ::1 (loopback)
|
||||
- :: (unspecified)
|
||||
- ::ffff:x.x.x.x (IPv4-mapped, returns just the IPv4 part)
|
||||
- fe80:: (link-local, returned as-is since interface-specific)
|
||||
"""
|
||||
try:
|
||||
# Strip brackets that some proxies add around IPv6
|
||||
ip = ip.strip("[]")
|
||||
# Strip zone ID (e.g., fe80::1%eth0)
|
||||
if "%" in ip:
|
||||
ip = ip.split("%")[0]
|
||||
addr = IPv6Address(ip)
|
||||
|
||||
# Special cases - return as-is or with minimal processing
|
||||
if addr.is_loopback: # ::1
|
||||
return "::1"
|
||||
if addr.is_unspecified: # ::
|
||||
return "::"
|
||||
if addr.ipv4_mapped: # ::ffff:x.x.x.x
|
||||
return str(addr.ipv4_mapped)
|
||||
if addr.is_link_local: # fe80::/10 - interface-specific, keep full
|
||||
return str(addr)
|
||||
|
||||
# Regular addresses: truncate to /64 network prefix
|
||||
network_int = int(addr) >> 64
|
||||
# Format as IPv6 with trailing ::
|
||||
# Split into 4 groups of 16 bits
|
||||
groups = []
|
||||
for _ in range(4):
|
||||
groups.insert(0, format(network_int & 0xFFFF, "x"))
|
||||
network_int >>= 16
|
||||
# Compress consecutive zero groups
|
||||
result = ":".join(groups) + "::"
|
||||
# Simplify leading zeros in groups and compress, then strip trailing ::
|
||||
return str(IPv6Address(result + "0")).removesuffix("::")
|
||||
except Exception:
|
||||
return ip
|
||||
|
||||
|
||||
def format_client_ip(ip: str) -> str:
|
||||
"""Format client IP, compressing IPv6 to network part only."""
|
||||
if not ip or ip == "-":
|
||||
return "-"
|
||||
# Strip brackets for detection (some proxies add them)
|
||||
stripped = ip.strip("[]")
|
||||
if ":" in stripped:
|
||||
return format_ipv6_network(ip)
|
||||
return ip
|
||||
|
||||
|
||||
def status_color(status: int) -> str:
|
||||
"""Return color code based on HTTP status."""
|
||||
if status < 200:
|
||||
return _STATUS_INFO
|
||||
if status < 300:
|
||||
return _STATUS_OK
|
||||
if status < 400:
|
||||
return _STATUS_REDIRECT
|
||||
if status < 500:
|
||||
return _STATUS_CLIENT_ERR
|
||||
return _STATUS_SERVER_ERR
|
||||
|
||||
|
||||
def method_color(method: str) -> str:
|
||||
"""Return color code based on HTTP method."""
|
||||
if method in ("GET", "HEAD", "OPTIONS"):
|
||||
return _METHOD_READ
|
||||
return _METHOD_WRITE
|
||||
|
||||
|
||||
def format_access_log(
|
||||
client: str,
|
||||
status: int,
|
||||
method: str,
|
||||
host: str,
|
||||
path: str,
|
||||
duration_ms: float,
|
||||
extra: str = "",
|
||||
) -> str:
|
||||
"""Format access log line with colors and aligned fields."""
|
||||
# Format components with fixed widths for alignment
|
||||
ip = format_client_ip(client).ljust(19) # IPv6 network max 19 chars
|
||||
timing = f"{duration_ms:.0f}ms"
|
||||
method_padded = method.ljust(7) # Longest method is OPTIONS (7)
|
||||
|
||||
status_str = f"{status_color(status)}{status}{_RESET}"
|
||||
timing_str = f"{_TIMING}{timing}{_RESET}"
|
||||
method_str = f"{method_color(method)}{method_padded}{_RESET}"
|
||||
host_str = f"{_HOST}{host}{_RESET}"
|
||||
path_str = f"{_PATH}{path}{_RESET}"
|
||||
|
||||
# Format: "IP STATUS METHOD host path [extra] TIMING"
|
||||
extra_str = f" {_TIMING}{extra}{_RESET}" if extra else ""
|
||||
return (
|
||||
f"{ip} {status_str} {method_str} {host_str}{path_str}{extra_str} {timing_str}"
|
||||
)
|
||||
|
||||
|
||||
# WebSocket connection counter (mod 100)
|
||||
_ws_counter = 0
|
||||
|
||||
|
||||
def _next_ws_id() -> int:
|
||||
"""Get next WebSocket connection ID (0-99)."""
|
||||
global _ws_counter
|
||||
ws_id = _ws_counter
|
||||
_ws_counter = (_ws_counter + 1) % 100
|
||||
return ws_id
|
||||
|
||||
|
||||
def log_ws_open(ws) -> int:
|
||||
"""Log WebSocket connection open. Returns connection ID for use in close."""
|
||||
ws_id = _next_ws_id()
|
||||
|
||||
client = ws.client.host if ws.client else "-"
|
||||
host = ws.headers.get("host", "-")
|
||||
path = ws.url.path
|
||||
origin = ws.headers.get("origin")
|
||||
|
||||
ip = format_client_ip(client).ljust(19)
|
||||
# ID right-aligned like status codes (3 chars), emoji formatted like method
|
||||
id_str = f"{_WS_OPEN}{str(ws_id).rjust(3)}{_RESET}"
|
||||
# Emoji (2 display width) + 6 spaces = 8 display chars, but within color for alignment
|
||||
emoji_str = f"{_METHOD_READ}🔌 {_RESET}"
|
||||
|
||||
# Determine if origin should be shown (omit when same as host)
|
||||
# Origin header includes scheme (e.g., "https://example.com"), compare host part
|
||||
origin_host = origin.split("://", 1)[-1] if origin else None
|
||||
show_origin = origin_host and origin_host != host
|
||||
|
||||
host_str = f"{_HOST}{host}{_RESET}"
|
||||
path_str = f"{_PATH}{path}{_RESET}"
|
||||
origin_str = f" {_RESET}from {_HOST}{origin_host}{_RESET}" if show_origin else ""
|
||||
|
||||
logger.info(f"{ip} {id_str} {emoji_str}{host_str}{path_str}{origin_str}")
|
||||
return ws_id
|
||||
|
||||
|
||||
# WebSocket close codes to human-readable status
|
||||
WS_CLOSE_CODES = {
|
||||
1000: "ok",
|
||||
1001: "going away",
|
||||
1002: "protocol error",
|
||||
1003: "unsupported",
|
||||
1005: "no status",
|
||||
1006: "abnormal",
|
||||
1007: "invalid data",
|
||||
1008: "policy violation",
|
||||
1009: "too large",
|
||||
1010: "extension required",
|
||||
1011: "server error",
|
||||
1012: "restarting",
|
||||
1013: "try again",
|
||||
1014: "bad gateway",
|
||||
1015: "tls error",
|
||||
}
|
||||
|
||||
|
||||
def log_ws_close(ws_id: int, close_code: int | None, duration: float) -> None:
|
||||
"""Log WebSocket connection close with duration and status."""
|
||||
# ID right-aligned like status codes (3 chars), "closed" formatted like method
|
||||
id_str = f"{_WS_CLOSE}{str(ws_id).rjust(3)}{_RESET}"
|
||||
# Pad within the dim color to keep full width in color (8 display chars)
|
||||
closed_str = f"{_TIMING}closed {_RESET}"
|
||||
timing = f"{duration * 1000:.0f}ms"
|
||||
|
||||
# Convert close code to status text
|
||||
if close_code is None:
|
||||
code = "----"
|
||||
status = "unknown"
|
||||
else:
|
||||
code = str(close_code)
|
||||
status = WS_CLOSE_CODES.get(close_code, f"code {close_code}")
|
||||
|
||||
# Status code and text in normal color, not dim
|
||||
status_str = f"{code} {status}"
|
||||
timing_str = f"{_TIMING}{timing}{_RESET}"
|
||||
|
||||
logger.info(f"{' ' * 19} {id_str} {closed_str}{status_str} {timing_str}")
|
||||
|
||||
|
||||
class AccessLogMiddleware(BaseHTTPMiddleware):
|
||||
"""Middleware that logs HTTP requests with custom format."""
|
||||
|
||||
async def dispatch(self, request: Request, call_next) -> Response:
|
||||
start = time.perf_counter()
|
||||
response = await call_next(request)
|
||||
duration_ms = (time.perf_counter() - start) * 1000
|
||||
|
||||
client = request.client.host if request.client else "-"
|
||||
host = request.headers.get("host", "-")
|
||||
method = request.method
|
||||
path = request.url.path
|
||||
if request.url.query:
|
||||
path = f"{path}?{request.url.query}"
|
||||
status = response.status_code
|
||||
|
||||
extra = getattr(request.state, "log_extra", "")
|
||||
|
||||
line = format_access_log(
|
||||
client, status, method, host, path, duration_ms, extra=extra
|
||||
)
|
||||
logger.info(line)
|
||||
|
||||
return response
|
||||
|
||||
|
||||
def configure_access_logging():
|
||||
"""Configure the access logger to output to stderr."""
|
||||
handler = logging.StreamHandler(sys.stderr)
|
||||
handler.setFormatter(logging.Formatter("%(message)s"))
|
||||
logger.addHandler(handler)
|
||||
logger.setLevel(logging.INFO)
|
||||
logger.propagate = False
|
||||
# Suppress uvicorn access logs to avoid duplicate request lines.
|
||||
logging.getLogger("uvicorn.access").setLevel(logging.WARNING)
|
||||
# Suppress uvicorn websocket "connection open/closed" messages.
|
||||
logging.getLogger("uvicorn.error").setLevel(logging.WARNING)
|
||||
# Suppress watchfiles "X changes detected" INFO messages (keep WARNING for reload notification)
|
||||
logging.getLogger("watchfiles.main").setLevel(logging.WARNING)
|
||||
@@ -0,0 +1,7 @@
|
||||
Welcome to the MediaHive installer.
|
||||
|
||||
During installation and on first launch, macOS may ask you to allow
|
||||
permissions (for example, access to your media folders or the local
|
||||
network). Please allow these so MediaHive can find and play your media.
|
||||
|
||||
Click Continue to begin.
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 197 KiB |
+27
-30
@@ -1,57 +1,54 @@
|
||||
r"""Platform-appropriate config persistence for MediaHive.
|
||||
|
||||
Config file location:
|
||||
Windows: %APPDATA%\mediahive\config.toml
|
||||
macOS: ~/Library/Application Support/mediahive/config.toml
|
||||
Linux: $XDG_CONFIG_HOME/mediahive/config.toml (~/.config/mediahive/config.toml)
|
||||
Locations (via platformdirs):
|
||||
Config — Windows: %LOCALAPPDATA%\mediahive\config.toml
|
||||
macOS: ~/Library/Application Support/mediahive/config.toml
|
||||
Linux: $XDG_CONFIG_HOME/mediahive/config.toml
|
||||
Logs — Windows: %LOCALAPPDATA%\mediahive\mediahive.log
|
||||
macOS: ~/Library/Logs/mediahive/mediahive.log
|
||||
Linux: $XDG_STATE_HOME/mediahive/mediahive.log
|
||||
"""
|
||||
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
import msgspec
|
||||
import msgspec.toml
|
||||
from fastapi_vue import env
|
||||
from platformdirs import user_config_path, user_log_path
|
||||
|
||||
|
||||
class Config(msgspec.Struct):
|
||||
media_folder: str | None = None
|
||||
class Config(msgspec.Struct, omit_defaults=True):
|
||||
roots: dict[str, str] | None = None
|
||||
auto_update: bool = True
|
||||
|
||||
|
||||
# Runtime config shared between the CLI entrypoint and the server process via
|
||||
# fastapi-vue's env teleport (MEDIAHIVE_CONFIG). Values set here take
|
||||
# precedence over the persisted config file.
|
||||
config = env(Config)
|
||||
|
||||
|
||||
def config_dir() -> Path:
|
||||
if sys.platform == "win32":
|
||||
base = Path(os.environ.get("APPDATA") or Path.home())
|
||||
elif sys.platform == "darwin":
|
||||
base = Path.home() / "Library" / "Application Support"
|
||||
else:
|
||||
base = Path(os.environ.get("XDG_CONFIG_HOME") or (Path.home() / ".config"))
|
||||
return base / "mediahive"
|
||||
# appauthor=False: avoid the doubled %LOCALAPPDATA%\mediahive\mediahive.
|
||||
# roaming=False: config is machine-specific state, not something to sync
|
||||
# across a domain profile.
|
||||
return user_config_path("mediahive", appauthor=False, roaming=False)
|
||||
|
||||
|
||||
def log_dir() -> Path:
|
||||
# opinion=False: no extra Logs/ subdir; mediahive.log sits beside config.
|
||||
return user_log_path("mediahive", appauthor=False, opinion=False)
|
||||
|
||||
|
||||
def config_path() -> Path:
|
||||
return config_dir() / "config.toml"
|
||||
|
||||
|
||||
def _migrate_legacy_media_folder(cfg: Config) -> Config:
|
||||
"""If roots is empty but media_folder exists, seed roots with it."""
|
||||
if cfg.roots:
|
||||
return cfg
|
||||
if not cfg.media_folder:
|
||||
return cfg
|
||||
path = Path(cfg.media_folder)
|
||||
name = path.name or path.anchor.strip("/\\").lower() or "media"
|
||||
# Resolve collisions simply by using the basename; if user had weird layout
|
||||
# they can rename via the UI later.
|
||||
return msgspec.structs.replace(cfg, roots={name: cfg.media_folder})
|
||||
|
||||
|
||||
def load_config() -> Config:
|
||||
path = config_path()
|
||||
if path.exists():
|
||||
try:
|
||||
cfg = msgspec.toml.decode(path.read_bytes(), type=Config)
|
||||
return _migrate_legacy_media_folder(cfg)
|
||||
return msgspec.toml.decode(path.read_bytes(), type=Config)
|
||||
except OSError, msgspec.DecodeError, msgspec.ValidationError:
|
||||
return Config()
|
||||
return Config()
|
||||
|
||||
@@ -1,13 +1,18 @@
|
||||
"""Hivescan CLI entrypoint."""
|
||||
|
||||
import os
|
||||
|
||||
# Must be set before fastapi_vue env bindings are created (mediahive.config).
|
||||
os.environ.setdefault("FASTAPI_VUE", "MEDIAHIVE")
|
||||
|
||||
import argparse
|
||||
import asyncio
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from mediahive.config import config
|
||||
|
||||
|
||||
def _configure_windows_event_loop_policy() -> None:
|
||||
"""Ensure Windows uses Proactor loop so asyncio subprocess APIs are available."""
|
||||
@@ -55,11 +60,9 @@ The server exposes a unified endpoint:
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
# Defer filesystem validation to the server; pass raw path via env.
|
||||
# Defer filesystem validation to the server; pass raw path via env config.
|
||||
media_root = Path(args.media_folder).expanduser()
|
||||
os.environ["MEDIAHIVE_ROOTS"] = json.dumps({
|
||||
media_root.name or "media": media_root.as_posix()
|
||||
})
|
||||
config.roots = {media_root.name or "media": media_root.as_posix()}
|
||||
|
||||
logging.basicConfig(
|
||||
level=logging.INFO,
|
||||
|
||||
+135
-20
@@ -16,6 +16,7 @@ from mediahive.hivescan.models import ContentType, ParsedContent
|
||||
from mediahive.hivescan.scanning import (
|
||||
find_cover_image,
|
||||
find_episode_files,
|
||||
find_external_subtitle_languages,
|
||||
find_metadata_probe_file,
|
||||
find_playable_file,
|
||||
)
|
||||
@@ -61,6 +62,18 @@ def _infer_hdr10plus(*values: str | None) -> bool:
|
||||
return bool(_HDR10PLUS_RE.search(text))
|
||||
|
||||
|
||||
def _merge_subtitle_languages(
|
||||
probed: list[str] | None,
|
||||
external: list[str],
|
||||
) -> list[str] | None:
|
||||
"""Union embedded subtitle languages with sidecar-subtitle languages."""
|
||||
merged = list(probed or [])
|
||||
for lang in external:
|
||||
if lang not in merged:
|
||||
merged.append(lang)
|
||||
return merged or None
|
||||
|
||||
|
||||
def _compact_playable_file(file_key: str, playable_file: str | None) -> str | None:
|
||||
"""Store playable paths compactly relative to the file key when possible."""
|
||||
if not playable_file:
|
||||
@@ -99,6 +112,7 @@ async def _build_torrent_info(
|
||||
probe_target = await find_metadata_probe_file(playable_file)
|
||||
if probe_target:
|
||||
probe_info = await probe_media_info(str(probe_target))
|
||||
external_subs = await find_external_subtitle_languages(playable_file)
|
||||
|
||||
if item.content_hash and item.content_hash.size == 0:
|
||||
item.content_hash.size = await asyncio.to_thread(
|
||||
@@ -125,7 +139,11 @@ async def _build_torrent_info(
|
||||
codec=item.codec,
|
||||
audio=item.audio,
|
||||
audio_languages=probe_info.audio_languages if probe_info else None,
|
||||
subtitle_languages=probe_info.subtitle_languages if probe_info else None,
|
||||
subtitle_languages=_merge_subtitle_languages(
|
||||
probe_info.subtitle_languages if probe_info else None,
|
||||
external_subs,
|
||||
),
|
||||
external_subtitle_languages=external_subs or None,
|
||||
hdr=probe_info.hdr if probe_info else False,
|
||||
dovi=probe_info.dovi if probe_info else False,
|
||||
atmos=probe_info.atmos if probe_info else False,
|
||||
@@ -148,20 +166,30 @@ async def _cache_people_profiles(
|
||||
if not info or not info.cast:
|
||||
return info, people
|
||||
|
||||
semaphore = asyncio.Semaphore(8)
|
||||
|
||||
async def fetch_profile(cast_credit, person):
|
||||
async with semaphore:
|
||||
return cast_credit.id, await download_cast_profile(
|
||||
person.profile_path,
|
||||
media_folder,
|
||||
person.name,
|
||||
cast_credit.id,
|
||||
)
|
||||
|
||||
tasks = []
|
||||
for cast_credit in info.cast:
|
||||
if cast_credit.id is None:
|
||||
continue
|
||||
person = people.get(cast_credit.id)
|
||||
if person is None or not person.profile_path:
|
||||
continue
|
||||
downloaded_path = await download_cast_profile(
|
||||
person.profile_path,
|
||||
media_folder,
|
||||
person.name,
|
||||
cast_credit.id,
|
||||
)
|
||||
tasks.append(fetch_profile(cast_credit, person))
|
||||
|
||||
for cast_id, downloaded_path in await asyncio.gather(*tasks):
|
||||
if downloaded_path:
|
||||
people[cast_credit.id] = Person(
|
||||
person = people[cast_id]
|
||||
people[cast_id] = Person(
|
||||
name=person.name,
|
||||
profile_path=Path(downloaded_path).name,
|
||||
gender=person.gender,
|
||||
@@ -197,12 +225,16 @@ async def _collect_episode_files(
|
||||
all_episode_files[key] = []
|
||||
for file_path, file_size in files:
|
||||
probe = await get_probe(file_path)
|
||||
external_subs = await find_external_subtitle_languages(file_path)
|
||||
all_episode_files[key].append({
|
||||
"path": file_path,
|
||||
"size": file_size,
|
||||
"probed_resolution": probe.resolution,
|
||||
"audio_languages": probe.audio_languages,
|
||||
"subtitle_languages": probe.subtitle_languages,
|
||||
"subtitle_languages": _merge_subtitle_languages(
|
||||
probe.subtitle_languages, external_subs
|
||||
),
|
||||
"external_subtitle_languages": external_subs or None,
|
||||
"hdr": probe.hdr,
|
||||
"dovi": probe.dovi,
|
||||
"atmos": probe.atmos,
|
||||
@@ -245,12 +277,18 @@ async def _collect_episode_files(
|
||||
item.content_hash.path,
|
||||
)
|
||||
size = item.content_hash.size if item.content_hash else 0
|
||||
external_subs = await find_external_subtitle_languages(
|
||||
playable
|
||||
)
|
||||
all_episode_files[key].append({
|
||||
"path": playable,
|
||||
"size": size,
|
||||
"probed_resolution": probe.resolution,
|
||||
"audio_languages": probe.audio_languages,
|
||||
"subtitle_languages": probe.subtitle_languages,
|
||||
"subtitle_languages": _merge_subtitle_languages(
|
||||
probe.subtitle_languages, external_subs
|
||||
),
|
||||
"external_subtitle_languages": external_subs or None,
|
||||
"hdr": probe.hdr,
|
||||
"dovi": probe.dovi,
|
||||
"atmos": probe.atmos,
|
||||
@@ -333,6 +371,7 @@ def _build_episodes_data(
|
||||
audio=f.get("audio"),
|
||||
audio_languages=f.get("audio_languages"),
|
||||
subtitle_languages=f.get("subtitle_languages"),
|
||||
external_subtitle_languages=f.get("external_subtitle_languages"),
|
||||
hdr=bool(f.get("hdr")),
|
||||
dovi=bool(f.get("dovi")),
|
||||
atmos=bool(f.get("atmos")),
|
||||
@@ -378,6 +417,25 @@ async def _build_seasons_data(
|
||||
seasons_map[season_num] = {}
|
||||
seasons_map[season_num][episode_num] = files
|
||||
|
||||
# Prefetch all missing season details in parallel; the loop below then
|
||||
# reads them straight from season_cache.
|
||||
if tmdb_id:
|
||||
missing = [
|
||||
season_num
|
||||
for season_num in seasons_map
|
||||
if (tmdb_id, season_num) not in season_cache
|
||||
]
|
||||
if missing:
|
||||
semaphore = asyncio.Semaphore(4)
|
||||
|
||||
async def prefetch(num: int) -> None:
|
||||
async with semaphore:
|
||||
season_cache[tmdb_id, num] = await fetch_season_details(
|
||||
tmdb_id, num
|
||||
)
|
||||
|
||||
await asyncio.gather(*(prefetch(num) for num in missing))
|
||||
|
||||
seasons_data = []
|
||||
for season_num in sorted(seasons_map.keys()):
|
||||
episodes_in_season = seasons_map[season_num]
|
||||
@@ -442,11 +500,15 @@ async def _process_movies(
|
||||
generate_showreels: bool,
|
||||
media_root: str | None = None,
|
||||
root_id: str | None = None,
|
||||
) -> AsyncIterator[tuple[str, Movie, tuple[str, Path, str] | None, dict[int, Person]]]:
|
||||
) -> AsyncIterator[
|
||||
tuple[str, Movie, tuple[str, Path, str] | None, dict[int, Person], list[str]]
|
||||
]:
|
||||
"""Async generator that processes all movies.
|
||||
|
||||
Yields:
|
||||
Tuples of ``(Movie, showreel_task_or_None)`` as each movie is processed.
|
||||
Tuples of ``(movie_id, Movie, showreel_task_or_None, people, scanned)``
|
||||
as each movie is processed. ``scanned`` lists the media-root-relative
|
||||
torrent paths whose content was (re)scanned to build the movie.
|
||||
|
||||
"""
|
||||
_ = root_id
|
||||
@@ -499,6 +561,21 @@ async def _process_movies(
|
||||
len(categories[ContentType.MOVIE]),
|
||||
) if movie_groups else None
|
||||
|
||||
# Prefetch TMDb lookups for all unique titles in parallel; the grouping
|
||||
# loop below then reads them straight from movie_tmdb_cache.
|
||||
if movie_groups:
|
||||
semaphore = asyncio.Semaphore(4)
|
||||
first_by_key = {
|
||||
f"{items[0].title.lower()}:{items[0].year}": items[0]
|
||||
for items in movie_groups.values()
|
||||
}
|
||||
|
||||
async def prefetch(item: ParsedContent) -> None:
|
||||
async with semaphore:
|
||||
await get_movie_tmdb(item.title, item.year)
|
||||
|
||||
await asyncio.gather(*(prefetch(item) for item in first_by_key.values()))
|
||||
|
||||
for idx, (_movie_key, items) in enumerate(movie_groups.items(), 1):
|
||||
first_item = items[0]
|
||||
logger.debug(
|
||||
@@ -640,7 +717,10 @@ async def _process_movies(
|
||||
showreel_source_sets=showreel_source_sets or None,
|
||||
files=files,
|
||||
)
|
||||
yield item_id, movie, showreel_task, people
|
||||
scanned = [
|
||||
make_relative_path(item.path.as_posix(), media_root) for item in items
|
||||
]
|
||||
yield item_id, movie, showreel_task, people, scanned
|
||||
|
||||
# Process movies without TMDb info
|
||||
for group_data in no_tmdb_movie_groups.values():
|
||||
@@ -712,7 +792,10 @@ async def _process_movies(
|
||||
showreel_source_sets=showreel_source_sets or None,
|
||||
files=files,
|
||||
)
|
||||
yield item_id, movie, showreel_task, {}
|
||||
scanned = [
|
||||
make_relative_path(item.path.as_posix(), media_root) for item in items
|
||||
]
|
||||
yield item_id, movie, showreel_task, {}, scanned
|
||||
|
||||
|
||||
async def _process_series(
|
||||
@@ -723,12 +806,16 @@ async def _process_series(
|
||||
media_root: str | None = None,
|
||||
root_id: str | None = None,
|
||||
) -> AsyncIterator[
|
||||
tuple[str, Series, list[tuple[str, Path, int, int, str]], dict[int, Person]]
|
||||
tuple[
|
||||
str, Series, list[tuple[str, Path, int, int, str]], dict[int, Person], list[str]
|
||||
]
|
||||
]:
|
||||
"""Async generator that processes all series.
|
||||
|
||||
Yields:
|
||||
Tuples of ``(Series, episode_reel_tasks)`` as each series is processed.
|
||||
Tuples of ``(series_id, Series, episode_reel_tasks, people, scanned)``
|
||||
as each series is processed. ``scanned`` lists the media-root-relative
|
||||
torrent paths whose content was (re)scanned to build the series.
|
||||
|
||||
"""
|
||||
_ = root_id
|
||||
@@ -783,6 +870,20 @@ async def _process_series(
|
||||
len(categories[ContentType.SERIES]),
|
||||
)
|
||||
|
||||
# Prefetch TMDb lookups for all unique titles in parallel; the grouping
|
||||
# loop below then reads them straight from series_tmdb_cache.
|
||||
if series_groups:
|
||||
semaphore = asyncio.Semaphore(4)
|
||||
first_by_key = {
|
||||
items[0].title.lower(): items[0] for items in series_groups.values()
|
||||
}
|
||||
|
||||
async def prefetch(item: ParsedContent) -> None:
|
||||
async with semaphore:
|
||||
await get_series_tmdb(item.title)
|
||||
|
||||
await asyncio.gather(*(prefetch(item) for item in first_by_key.values()))
|
||||
|
||||
for idx, (_series_key, items) in enumerate(series_groups.items(), 1):
|
||||
first_item = items[0]
|
||||
logger.debug(" [%d/%d] %s", idx, len(series_groups), first_item.title)
|
||||
@@ -879,7 +980,11 @@ async def _process_series(
|
||||
)
|
||||
|
||||
if not seasons_data:
|
||||
logger.info(" Skipping %s - no episodes found", display_title)
|
||||
logger.info(
|
||||
" Skipping %s - no episodes in the %d scanned torrent(s)",
|
||||
display_title,
|
||||
len(items),
|
||||
)
|
||||
continue
|
||||
|
||||
different_titles = sorted(
|
||||
@@ -898,7 +1003,10 @@ async def _process_series(
|
||||
backdrop_path=make_relative_path(backdrop_path, media_root),
|
||||
seasons=seasons_data,
|
||||
)
|
||||
yield series_id, series, ep_reel_tasks, people
|
||||
scanned = [
|
||||
make_relative_path(item.path.as_posix(), media_root) for item in items
|
||||
]
|
||||
yield series_id, series, ep_reel_tasks, people, scanned
|
||||
|
||||
# Process series without TMDb info
|
||||
for group_data in no_tmdb_groups.values():
|
||||
@@ -928,7 +1036,11 @@ async def _process_series(
|
||||
)
|
||||
|
||||
if not seasons_data:
|
||||
logger.info(" Skipping %s - no episodes found", title)
|
||||
logger.info(
|
||||
" Skipping %s - no episodes in the %d scanned torrent(s)",
|
||||
title,
|
||||
len(items),
|
||||
)
|
||||
continue
|
||||
|
||||
item_timestamps = [await get_added_timestamp(item.path) for item in items]
|
||||
@@ -941,4 +1053,7 @@ async def _process_series(
|
||||
cover_path=make_relative_path(cover_path, media_root),
|
||||
seasons=seasons_data,
|
||||
)
|
||||
yield series_id, series, ep_reel_tasks, {}
|
||||
scanned = [
|
||||
make_relative_path(item.path.as_posix(), media_root) for item in items
|
||||
]
|
||||
yield series_id, series, ep_reel_tasks, {}, scanned
|
||||
|
||||
+831
-229
File diff suppressed because it is too large
Load Diff
@@ -28,12 +28,61 @@ VIDEO_EXTENSIONS = {
|
||||
".m2ts",
|
||||
}
|
||||
|
||||
# Caches for expensive operations
|
||||
# External subtitle file extensions
|
||||
SUBTITLE_EXTENSIONS = {".srt", ".ass", ".ssa", ".vtt", ".sub"}
|
||||
|
||||
# Non-language tokens that may follow the language in a sidecar filename
|
||||
_SUBTITLE_FLAG_TOKENS = {"forced", "sdh", "cc", "hi", "dhi", "commentary", "signs"}
|
||||
|
||||
# ISO 639-1 -> ISO 639-2/B for common sidecar language tags, so they merge
|
||||
# with the codes ffmpeg reports for embedded tracks.
|
||||
_ISO_639_1_TO_639_2 = {
|
||||
"ar": "ara",
|
||||
"cs": "ces",
|
||||
"da": "dan",
|
||||
"de": "deu",
|
||||
"el": "ell",
|
||||
"en": "eng",
|
||||
"es": "esp",
|
||||
"fi": "fin",
|
||||
"fr": "fra",
|
||||
"he": "heb",
|
||||
"hi": "hin",
|
||||
"hu": "hun",
|
||||
"id": "ind",
|
||||
"it": "ita",
|
||||
"ja": "jpn",
|
||||
"ko": "kor",
|
||||
"nl": "nld",
|
||||
"no": "nor",
|
||||
"pl": "pol",
|
||||
"pt": "por",
|
||||
"ru": "rus",
|
||||
"sv": "swe",
|
||||
"th": "tha",
|
||||
"tr": "tur",
|
||||
"uk": "ukr",
|
||||
"vi": "vie",
|
||||
"zh": "zho",
|
||||
}
|
||||
|
||||
# Caches for expensive operations. These are per-scan only: the scanner
|
||||
# clears them at the start of every scan. Caching across scans is wrong —
|
||||
# an empty result recorded before a download finished (or during a transient
|
||||
# network-mount error) would stick for the process lifetime and report
|
||||
# "no episodes found" for series that do have episodes.
|
||||
_episode_files_cache: dict[str, dict[tuple[int, int], list[tuple[str, int]]]] = {}
|
||||
_playable_file_cache: dict[str, str | None] = {}
|
||||
_bluray_probe_file_cache: dict[str, str | None] = {}
|
||||
|
||||
|
||||
def clear_scan_caches() -> None:
|
||||
"""Drop all per-scan filesystem caches; called at the start of each scan."""
|
||||
_episode_files_cache.clear()
|
||||
_playable_file_cache.clear()
|
||||
_bluray_probe_file_cache.clear()
|
||||
|
||||
|
||||
def _scandir_split(
|
||||
directory: Path,
|
||||
stop_event: threading.Event,
|
||||
@@ -311,6 +360,56 @@ async def find_playable_file(path: Path) -> str | None:
|
||||
return result
|
||||
|
||||
|
||||
def _sidecar_subtitle_language(video_stem: str, filename: str) -> str | None:
|
||||
"""Language tag from a sidecar subtitle name like `<stem>.esp.srt`, if any."""
|
||||
if not filename.startswith(video_stem + "."):
|
||||
return None
|
||||
suffix = Path(filename).suffix.lower()
|
||||
if suffix not in SUBTITLE_EXTENSIONS:
|
||||
return None
|
||||
middle = filename[len(video_stem) + 1 : -len(suffix)]
|
||||
tokens = [t for t in middle.split(".") if t]
|
||||
while tokens and tokens[-1].lower() in _SUBTITLE_FLAG_TOKENS:
|
||||
tokens.pop()
|
||||
if not tokens:
|
||||
return None
|
||||
code = tokens[-1].lower()
|
||||
if not code.isalpha() or not 2 <= len(code) <= 3:
|
||||
return None
|
||||
code = _ISO_639_1_TO_639_2.get(code, code)
|
||||
return None if code == "und" else code
|
||||
|
||||
|
||||
def _scan_external_subtitle_languages(video_path: Path) -> list[str]:
|
||||
languages: list[str] = []
|
||||
with os.scandir(video_path.parent) as entries:
|
||||
for entry in entries:
|
||||
if not entry.is_file(follow_symlinks=False):
|
||||
continue
|
||||
lang = _sidecar_subtitle_language(video_path.stem, entry.name)
|
||||
if lang and lang not in languages:
|
||||
languages.append(lang)
|
||||
return languages
|
||||
|
||||
|
||||
async def find_external_subtitle_languages(video_path: str | None) -> list[str]:
|
||||
"""Languages of external subtitle files sitting next to a video file.
|
||||
|
||||
Matches sidecars named `<stem>.<lang>.<ext>` (e.g. `Movie.esp.srt` ->
|
||||
``esp``), optionally with flags like ``forced``/``sdh`` after the language.
|
||||
Bare `<stem>.<ext>` files carry no language tag and are ignored.
|
||||
"""
|
||||
if not video_path or "://" in video_path or video_path.startswith("concat:"):
|
||||
return []
|
||||
path = Path(video_path)
|
||||
if path.suffix.lower() not in VIDEO_EXTENSIONS:
|
||||
return []
|
||||
try:
|
||||
return await asyncio.to_thread(_scan_external_subtitle_languages, path)
|
||||
except OSError, PermissionError:
|
||||
return []
|
||||
|
||||
|
||||
async def find_metadata_probe_file(playable_path: str | None) -> str | None:
|
||||
"""Resolve a path suitable for ffmpeg stream metadata probing.
|
||||
|
||||
|
||||
@@ -7,13 +7,14 @@ and HDR passthrough.
|
||||
|
||||
import asyncio
|
||||
import contextlib
|
||||
import json
|
||||
import logging
|
||||
import re
|
||||
import shlex
|
||||
import subprocess
|
||||
import sys
|
||||
from collections import Counter
|
||||
from dataclasses import dataclass
|
||||
from dataclasses import asdict, dataclass
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
@@ -425,6 +426,85 @@ class MediaProbeInfo:
|
||||
|
||||
|
||||
_media_probe_cache: dict[str, MediaProbeInfo] = {}
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Persistent probe records
|
||||
#
|
||||
# Probe results are keyed by (path, mtime, size) and persisted to
|
||||
# ``probe-cache.json`` under the root's .mediahive folder so that process
|
||||
# restarts do not re-run ffmpeg on unchanged files. The in-RAM structures
|
||||
# are process-global (keyed by absolute path, so sharing across roots is
|
||||
# safe); each root loads/saves its own file, merging into the same dict.
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
_probe_records: dict[str, dict] = {}
|
||||
_probe_records_path: Path | None = None
|
||||
_probe_records_dirty = False
|
||||
|
||||
|
||||
def load_probe_records(path: Path) -> None:
|
||||
"""Load persisted probe records from ``path`` (missing file is fine)."""
|
||||
global _probe_records_path
|
||||
_probe_records_path = path
|
||||
try:
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
except FileNotFoundError:
|
||||
return
|
||||
except OSError, ValueError:
|
||||
logger.exception("Failed to load probe cache from %s", path)
|
||||
return
|
||||
records = data.get("records")
|
||||
if isinstance(records, dict):
|
||||
_probe_records.update(records)
|
||||
logger.info("Loaded probe cache: %d records from %s", len(records), path)
|
||||
|
||||
|
||||
def probe_records_dirty() -> bool:
|
||||
return _probe_records_dirty
|
||||
|
||||
|
||||
def save_probe_records() -> None:
|
||||
"""Persist probe records if any were added since the last save."""
|
||||
global _probe_records_dirty
|
||||
if not _probe_records_dirty or _probe_records_path is None:
|
||||
return
|
||||
_probe_records_dirty = False
|
||||
try:
|
||||
payload = json.dumps({"version": 1, "records": _probe_records})
|
||||
tmp = _probe_records_path.with_suffix(".tmp")
|
||||
tmp.parent.mkdir(parents=True, exist_ok=True)
|
||||
tmp.write_text(payload, encoding="utf-8")
|
||||
tmp.replace(_probe_records_path)
|
||||
except OSError, TypeError, ValueError:
|
||||
logger.exception("Failed to save probe cache to %s", _probe_records_path)
|
||||
|
||||
|
||||
def _record_probe(video_path: str, stat_info, info: MediaProbeInfo) -> None:
|
||||
global _probe_records_dirty
|
||||
if stat_info is None:
|
||||
return # Non-plain paths (bluray:/concat: URIs) are not persisted
|
||||
_probe_records[video_path] = {
|
||||
"mtime": int(stat_info.st_mtime),
|
||||
"size": stat_info.st_size,
|
||||
"info": asdict(info),
|
||||
}
|
||||
_probe_records_dirty = True
|
||||
|
||||
|
||||
def _lookup_probe_record(video_path: str, stat_info) -> MediaProbeInfo | None:
|
||||
rec = _probe_records.get(video_path)
|
||||
if rec is None or stat_info is None:
|
||||
return None
|
||||
if rec.get("mtime") != int(stat_info.st_mtime):
|
||||
return None
|
||||
if rec.get("size") != stat_info.st_size:
|
||||
return None
|
||||
try:
|
||||
return MediaProbeInfo(**rec["info"])
|
||||
except TypeError, KeyError:
|
||||
return None
|
||||
|
||||
|
||||
_duration_re = re.compile(r"Duration:\s*(\d+):(\d+):(\d+(?:\.\d+)?)")
|
||||
_dimension_re = re.compile(r"(\d{2,5})x(\d{2,5})")
|
||||
_dovi_profile_re = re.compile(
|
||||
@@ -449,11 +529,23 @@ async def probe_media_info(video_path: str) -> MediaProbeInfo:
|
||||
if cached is not None:
|
||||
return cached
|
||||
|
||||
# Stat once: used both to validate persisted records and to key new ones.
|
||||
# Non-plain paths (bluray:/concat: URIs) fail stat and stay memory-cached.
|
||||
stat_info = None
|
||||
with contextlib.suppress(OSError, ValueError):
|
||||
stat_info = await AsyncPath(video_path).stat()
|
||||
|
||||
recorded = _lookup_probe_record(video_path, stat_info)
|
||||
if recorded is not None:
|
||||
_media_probe_cache[video_path] = recorded
|
||||
return recorded
|
||||
|
||||
info = MediaProbeInfo()
|
||||
cmd = ["ffmpeg", "-hide_banner", "-i", video_path]
|
||||
ffmpeg_result = await _run_ffmpeg(cmd, timeout_seconds=30, allow_nonzero_exit=True)
|
||||
if ffmpeg_result is None:
|
||||
_media_probe_cache[video_path] = info
|
||||
_record_probe(video_path, stat_info, info)
|
||||
return info
|
||||
|
||||
stdout, stderr = ffmpeg_result
|
||||
@@ -552,6 +644,7 @@ async def probe_media_info(video_path: str) -> MediaProbeInfo:
|
||||
info.subtitle_languages = subtitle_languages or None
|
||||
|
||||
_media_probe_cache[video_path] = info
|
||||
_record_probe(video_path, stat_info, info)
|
||||
return info
|
||||
|
||||
|
||||
|
||||
@@ -2,7 +2,6 @@
|
||||
|
||||
import os
|
||||
import re
|
||||
import time
|
||||
import unicodedata
|
||||
from pathlib import Path
|
||||
|
||||
@@ -11,9 +10,6 @@ from aiopathlib import AsyncPath
|
||||
# Default output folder name (created at common root of scanned paths)
|
||||
DEFAULT_OUTPUT_FOLDER = ".mediahive"
|
||||
|
||||
# Threshold for considering atime "too close" to current time (1 hour)
|
||||
_ATIME_FRESHNESS_THRESHOLD = 3600
|
||||
|
||||
# Resolution priority for quality sorting (higher = better)
|
||||
RESOLUTION_PRIORITY = {
|
||||
"8K": 5,
|
||||
@@ -108,10 +104,9 @@ def normalize_resolution_label(value: str | None) -> str | None:
|
||||
async def get_added_timestamp(path: Path) -> int | None:
|
||||
"""Get the timestamp when a torrent was added to the collection.
|
||||
|
||||
Heuristic:
|
||||
- For directories: use ctime (most accurate for torrent folder creation)
|
||||
- For files: use atime unless it's too close to current time (suggesting
|
||||
the filesystem updates atime on reads), otherwise use max(mtime, ctime)
|
||||
Best-effort rule:
|
||||
- On Windows: use ctime (creation-time semantics)
|
||||
- On other OSes: use mtime (ctime is metadata-change time on Unix)
|
||||
|
||||
Returns:
|
||||
Unix timestamp as int, or None if path doesn't exist
|
||||
@@ -122,17 +117,9 @@ async def get_added_timestamp(path: Path) -> int | None:
|
||||
stat_info = await ap.stat()
|
||||
except OSError, PermissionError:
|
||||
return None
|
||||
|
||||
if await ap.is_dir():
|
||||
if os.name == "nt":
|
||||
return int(stat_info.st_ctime)
|
||||
|
||||
now = time.time()
|
||||
atime = stat_info.st_atime
|
||||
|
||||
if now - atime < _ATIME_FRESHNESS_THRESHOLD:
|
||||
return int(max(stat_info.st_mtime, stat_info.st_ctime))
|
||||
|
||||
return int(atime)
|
||||
return int(stat_info.st_mtime)
|
||||
|
||||
|
||||
def get_directory_size(path: Path) -> int:
|
||||
|
||||
+291
-18
@@ -18,10 +18,13 @@ from aiopathlib import AsyncPath
|
||||
from fastapi import WebSocket
|
||||
|
||||
from mediahive.models.data import (
|
||||
Episode,
|
||||
IndexSnapshot,
|
||||
Movie,
|
||||
Season,
|
||||
Series,
|
||||
TaskInfo,
|
||||
Torrent,
|
||||
)
|
||||
from mediahive.models.events import Remove, Task, Upsert
|
||||
from mediahive.models.tmdb import Person
|
||||
@@ -147,6 +150,120 @@ class IndexStore:
|
||||
return None
|
||||
return item.info.tmdb_id
|
||||
|
||||
def torrent_paths(self) -> set[str]:
|
||||
"""All media-root-relative torrent paths currently in the index.
|
||||
|
||||
The scanner uses this to reprocess items that are missing from the
|
||||
index even though their mtime is unchanged (e.g. after the snapshot
|
||||
was wiped or an upsert never landed).
|
||||
"""
|
||||
paths: set[str] = set()
|
||||
for movie in self.movies.values():
|
||||
paths.update(movie.files)
|
||||
for show in self.series.values():
|
||||
for season in show.seasons:
|
||||
for episode in season.episodes:
|
||||
paths.update(episode.files)
|
||||
return paths
|
||||
|
||||
@staticmethod
|
||||
def _newest_from_files(files: dict[str, Torrent]) -> int | None:
|
||||
timestamps = [t.added_at for t in files.values() if t.added_at]
|
||||
return max(timestamps) if timestamps else None
|
||||
|
||||
# ------------------------------------------------------------------
|
||||
# Merge helpers (partial rescan support)
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
def _merge_movie(self, existing: Movie, new: Movie, scanned: set[str]) -> Movie:
|
||||
"""Merge a partially rebuilt movie into the existing entry.
|
||||
|
||||
File entries belonging to torrents in ``scanned`` are replaced by the
|
||||
new data; everything else is preserved.
|
||||
"""
|
||||
files = {k: v for k, v in existing.files.items() if k not in scanned}
|
||||
files.update(new.files)
|
||||
return Movie(
|
||||
title=new.title or existing.title,
|
||||
info=new.info or existing.info,
|
||||
year=new.year if new.year is not None else existing.year,
|
||||
newest=(
|
||||
self._newest_from_files(files)
|
||||
or max(filter(None, [existing.newest, new.newest]), default=None)
|
||||
),
|
||||
cover_path=new.cover_path or existing.cover_path,
|
||||
backdrop_path=new.backdrop_path or existing.backdrop_path,
|
||||
showreel_images=new.showreel_images or existing.showreel_images,
|
||||
showreel_source_sets=new.showreel_source_sets
|
||||
or existing.showreel_source_sets,
|
||||
files=files,
|
||||
)
|
||||
|
||||
def _merge_series(self, existing: Series, new: Series, scanned: set[str]) -> Series:
|
||||
"""Merge a partially rebuilt series into the existing entry.
|
||||
|
||||
File entries belonging to torrents in ``scanned`` are replaced by the
|
||||
new data; seasons/episodes/files from torrents that were not rescanned
|
||||
are preserved. Episodes and seasons left without files are dropped.
|
||||
"""
|
||||
seasons: dict[int, Season] = {}
|
||||
for season in existing.seasons:
|
||||
episodes: dict[int, Episode] = {}
|
||||
for ep in season.episodes:
|
||||
files = {k: v for k, v in ep.files.items() if k not in scanned}
|
||||
if files:
|
||||
episodes[ep.episode_number] = msgspec.structs.replace(
|
||||
ep, files=files
|
||||
)
|
||||
if episodes:
|
||||
seasons[season.season_number] = msgspec.structs.replace(
|
||||
season,
|
||||
episodes=list(episodes.values()),
|
||||
episode_count=len(episodes),
|
||||
)
|
||||
|
||||
for season in new.seasons:
|
||||
current = seasons.get(season.season_number)
|
||||
if current is None:
|
||||
seasons[season.season_number] = season
|
||||
continue
|
||||
episodes = {ep.episode_number: ep for ep in current.episodes}
|
||||
for ep in season.episodes:
|
||||
old = episodes.get(ep.episode_number)
|
||||
if old is None:
|
||||
episodes[ep.episode_number] = ep
|
||||
continue
|
||||
# Same episode from an unscanned torrent too: union the files,
|
||||
# prefer fresh metadata/reel info from the new scan.
|
||||
files = dict(old.files)
|
||||
files.update(ep.files)
|
||||
episodes[ep.episode_number] = msgspec.structs.replace(
|
||||
ep,
|
||||
files=files,
|
||||
reel_image=ep.reel_image or old.reel_image,
|
||||
reel_sources=ep.reel_sources or old.reel_sources,
|
||||
)
|
||||
ordered = [episodes[k] for k in sorted(episodes)]
|
||||
seasons[season.season_number] = msgspec.structs.replace(
|
||||
season,
|
||||
episodes=ordered,
|
||||
episode_count=len(ordered),
|
||||
poster_path=season.poster_path or current.poster_path,
|
||||
)
|
||||
|
||||
alt_titles = sorted(
|
||||
set(existing.alternative_titles or []) | set(new.alternative_titles or [])
|
||||
)
|
||||
return Series(
|
||||
title=new.title or existing.title,
|
||||
info=new.info or existing.info,
|
||||
alternative_titles=alt_titles or None,
|
||||
newest=max(filter(None, [existing.newest, new.newest]), default=None),
|
||||
cover_path=new.cover_path or existing.cover_path,
|
||||
backdrop_path=new.backdrop_path or existing.backdrop_path,
|
||||
seasons=[seasons[k] for k in sorted(seasons)],
|
||||
)
|
||||
|
||||
def _rebuild_tmdb_indexes(self) -> None:
|
||||
"""Rebuild TMDb id lookup maps from the current in-memory items."""
|
||||
self._movie_tmdb_ids.clear()
|
||||
@@ -189,22 +306,34 @@ class IndexStore:
|
||||
self._rebuild_tmdb_indexes()
|
||||
|
||||
def _collapse_movie_tmdb_duplicates(self, tmdb_id: int, keep_id: str) -> None:
|
||||
"""Remove other movie entries that share a TMDb id."""
|
||||
"""Fold other entries that share a TMDb id into the kept one."""
|
||||
for item_id, movie in list(self.movies.items()):
|
||||
if item_id == keep_id:
|
||||
continue
|
||||
if self._get_tmdb_id(movie) == tmdb_id:
|
||||
self.movies.pop(item_id, None)
|
||||
self._rebuild_tmdb_indexes()
|
||||
if self._get_tmdb_id(movie) != tmdb_id:
|
||||
continue
|
||||
kept = self.movies.get(keep_id)
|
||||
if kept is not None:
|
||||
# Preserve any file versions the duplicate alone carried.
|
||||
self.movies[keep_id] = self._merge_movie(movie, kept, set())
|
||||
self.movies.pop(item_id, None)
|
||||
if self._movie_tmdb_ids.get(tmdb_id) == item_id:
|
||||
self._movie_tmdb_ids[tmdb_id] = keep_id
|
||||
|
||||
def _collapse_series_tmdb_duplicates(self, tmdb_id: int, keep_id: str) -> None:
|
||||
"""Remove other series entries that share a TMDb id."""
|
||||
"""Fold other entries that share a TMDb id into the kept one."""
|
||||
for item_id, series in list(self.series.items()):
|
||||
if item_id == keep_id:
|
||||
continue
|
||||
if self._get_tmdb_id(series) == tmdb_id:
|
||||
self.series.pop(item_id, None)
|
||||
self._rebuild_tmdb_indexes()
|
||||
if self._get_tmdb_id(series) != tmdb_id:
|
||||
continue
|
||||
kept = self.series.get(keep_id)
|
||||
if kept is not None:
|
||||
# Preserve any seasons/episodes the duplicate alone carried.
|
||||
self.series[keep_id] = self._merge_series(series, kept, set())
|
||||
self.series.pop(item_id, None)
|
||||
if self._series_tmdb_ids.get(tmdb_id) == item_id:
|
||||
self._series_tmdb_ids[tmdb_id] = keep_id
|
||||
|
||||
async def _write_snapshot(self) -> None:
|
||||
"""Write current index to disk (called from debounce task)."""
|
||||
@@ -300,8 +429,14 @@ class IndexStore:
|
||||
item_id: str,
|
||||
item: Movie,
|
||||
people: dict[int, Person] | None = None,
|
||||
scanned: list[str] | None = None,
|
||||
) -> bool:
|
||||
"""Insert or update a movie. Returns True if it was a real change."""
|
||||
"""Insert or update a movie. Returns True if it was a real change.
|
||||
|
||||
When ``scanned`` is given, the item is a partial rebuild covering only
|
||||
those torrent paths; it is merged into the existing entry instead of
|
||||
replacing it.
|
||||
"""
|
||||
tmdb_id = self._get_tmdb_id(item)
|
||||
existing_id = self._movie_tmdb_ids.get(tmdb_id) if tmdb_id is not None else None
|
||||
if existing_id is not None and existing_id != item_id:
|
||||
@@ -311,6 +446,10 @@ class IndexStore:
|
||||
if tmdb_id is not None:
|
||||
self._movie_tmdb_ids[tmdb_id] = item_id
|
||||
self._collapse_movie_tmdb_duplicates(tmdb_id, item_id)
|
||||
existing = self.movies.get(item_id)
|
||||
|
||||
if existing is not None and scanned is not None:
|
||||
item = self._merge_movie(existing, item, set(scanned))
|
||||
|
||||
if existing is not None:
|
||||
if msgspec.json.encode(existing) == msgspec.json.encode(item):
|
||||
@@ -334,8 +473,14 @@ class IndexStore:
|
||||
item_id: str,
|
||||
item: Series,
|
||||
people: dict[int, Person] | None = None,
|
||||
scanned: list[str] | None = None,
|
||||
) -> bool:
|
||||
"""Insert or update a series. Returns True if it was a real change."""
|
||||
"""Insert or update a series. Returns True if it was a real change.
|
||||
|
||||
When ``scanned`` is given, the item is a partial rebuild covering only
|
||||
those torrent paths; it is merged into the existing entry instead of
|
||||
replacing it.
|
||||
"""
|
||||
tmdb_id = self._get_tmdb_id(item)
|
||||
existing_id = (
|
||||
self._series_tmdb_ids.get(tmdb_id) if tmdb_id is not None else None
|
||||
@@ -347,6 +492,10 @@ class IndexStore:
|
||||
if tmdb_id is not None:
|
||||
self._series_tmdb_ids[tmdb_id] = item_id
|
||||
self._collapse_series_tmdb_duplicates(tmdb_id, item_id)
|
||||
existing = self.series.get(item_id)
|
||||
|
||||
if existing is not None and scanned is not None:
|
||||
item = self._merge_series(existing, item, set(scanned))
|
||||
|
||||
if existing is not None:
|
||||
if msgspec.json.encode(existing) == msgspec.json.encode(item):
|
||||
@@ -367,22 +516,146 @@ class IndexStore:
|
||||
|
||||
def remove_movie(self, item_id: str) -> None:
|
||||
"""Remove a movie from the index and broadcast."""
|
||||
self.movies.pop(item_id, None)
|
||||
for tmdb_id, mapped_id in list(self._movie_tmdb_ids.items()):
|
||||
if mapped_id == item_id:
|
||||
self._movie_tmdb_ids.pop(tmdb_id, None)
|
||||
movie = self.movies.pop(item_id, None)
|
||||
if movie is None:
|
||||
return
|
||||
tmdb_id = self._get_tmdb_id(movie)
|
||||
if tmdb_id is not None and self._movie_tmdb_ids.get(tmdb_id) == item_id:
|
||||
self._movie_tmdb_ids.pop(tmdb_id, None)
|
||||
self._schedule_snapshot()
|
||||
self._broadcast(Remove(kind="movie", id=item_id))
|
||||
|
||||
def remove_series(self, item_id: str) -> None:
|
||||
"""Remove a series from the index and broadcast."""
|
||||
self.series.pop(item_id, None)
|
||||
for tmdb_id, mapped_id in list(self._series_tmdb_ids.items()):
|
||||
if mapped_id == item_id:
|
||||
self._series_tmdb_ids.pop(tmdb_id, None)
|
||||
series = self.series.pop(item_id, None)
|
||||
if series is None:
|
||||
return
|
||||
tmdb_id = self._get_tmdb_id(series)
|
||||
if tmdb_id is not None and self._series_tmdb_ids.get(tmdb_id) == item_id:
|
||||
self._series_tmdb_ids.pop(tmdb_id, None)
|
||||
self._schedule_snapshot()
|
||||
self._broadcast(Remove(kind="series", id=item_id))
|
||||
|
||||
# ------------------------------------------------------------------
|
||||
# Scanner-driven maintenance
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
def sync_torrent_paths(self, paths: set[str]) -> None:
|
||||
"""Drop file entries whose torrent path no longer exists on disk.
|
||||
|
||||
``paths`` is the complete set of media-root-relative torrent paths the
|
||||
scanner found during a fully completed discovery pass. Episodes and
|
||||
seasons left without files are dropped; items left without any files
|
||||
are removed entirely.
|
||||
"""
|
||||
for item_id, movie in list(self.movies.items()):
|
||||
kept = {k: v for k, v in movie.files.items() if k in paths}
|
||||
if len(kept) == len(movie.files):
|
||||
continue
|
||||
if not kept:
|
||||
self.remove_movie(item_id)
|
||||
continue
|
||||
updated = msgspec.structs.replace(
|
||||
movie, files=kept, newest=self._newest_from_files(kept)
|
||||
)
|
||||
self.movies[item_id] = updated
|
||||
self._schedule_snapshot()
|
||||
self._broadcast(Upsert(kind="movie", id=item_id, item=updated))
|
||||
|
||||
for item_id, series in list(self.series.items()):
|
||||
removed_any = False
|
||||
new_seasons: list[Season] = []
|
||||
for season in series.seasons:
|
||||
new_episodes: list[Episode] = []
|
||||
for ep in season.episodes:
|
||||
files = {k: v for k, v in ep.files.items() if k in paths}
|
||||
if len(files) < len(ep.files):
|
||||
removed_any = True
|
||||
if files:
|
||||
new_episodes.append(msgspec.structs.replace(ep, files=files))
|
||||
else:
|
||||
removed_any = True
|
||||
if not new_episodes:
|
||||
removed_any = True
|
||||
continue
|
||||
if len(new_episodes) < len(season.episodes):
|
||||
season = msgspec.structs.replace(
|
||||
season,
|
||||
episodes=new_episodes,
|
||||
episode_count=len(new_episodes),
|
||||
)
|
||||
new_seasons.append(season)
|
||||
if not removed_any:
|
||||
continue
|
||||
if not new_seasons:
|
||||
self.remove_series(item_id)
|
||||
continue
|
||||
updated_series = msgspec.structs.replace(series, seasons=new_seasons)
|
||||
self.series[item_id] = updated_series
|
||||
self._schedule_snapshot()
|
||||
self._broadcast(Upsert(kind="series", id=item_id, item=updated_series))
|
||||
|
||||
def set_movie_showreel(
|
||||
self,
|
||||
item_id: str,
|
||||
showreel_images: list[str] | None,
|
||||
showreel_source_sets: list[list[str]] | None,
|
||||
) -> None:
|
||||
"""Update only the showreel fields of a movie (reel worker callback)."""
|
||||
movie = self.movies.get(item_id)
|
||||
if movie is None:
|
||||
return
|
||||
updated = msgspec.structs.replace(
|
||||
movie,
|
||||
showreel_images=showreel_images,
|
||||
showreel_source_sets=showreel_source_sets,
|
||||
)
|
||||
if msgspec.json.encode(updated) == msgspec.json.encode(movie):
|
||||
return
|
||||
self.movies[item_id] = updated
|
||||
self._schedule_snapshot()
|
||||
self._broadcast(Upsert(kind="movie", id=item_id, item=updated))
|
||||
|
||||
def set_episode_reel(
|
||||
self,
|
||||
item_id: str,
|
||||
season_num: int,
|
||||
episode_num: int,
|
||||
reel_image: str | None,
|
||||
reel_sources: list[str] | None,
|
||||
) -> None:
|
||||
"""Update only the reel fields of one episode (reel worker callback)."""
|
||||
series = self.series.get(item_id)
|
||||
if series is None:
|
||||
return
|
||||
for season in series.seasons:
|
||||
if season.season_number != season_num:
|
||||
continue
|
||||
for ep in season.episodes:
|
||||
if ep.episode_number != episode_num:
|
||||
continue
|
||||
if ep.reel_image == reel_image and ep.reel_sources == reel_sources:
|
||||
return
|
||||
new_episodes = [
|
||||
msgspec.structs.replace(
|
||||
e, reel_image=reel_image, reel_sources=reel_sources
|
||||
)
|
||||
if e is ep
|
||||
else e
|
||||
for e in season.episodes
|
||||
]
|
||||
new_seasons = [
|
||||
msgspec.structs.replace(s, episodes=new_episodes)
|
||||
if s is season
|
||||
else s
|
||||
for s in series.seasons
|
||||
]
|
||||
updated = msgspec.structs.replace(series, seasons=new_seasons)
|
||||
self.series[item_id] = updated
|
||||
self._schedule_snapshot()
|
||||
self._broadcast(Upsert(kind="series", id=item_id, item=updated))
|
||||
return
|
||||
|
||||
# ------------------------------------------------------------------
|
||||
# WebSocket management
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
@@ -26,6 +26,7 @@ class Torrent(msgspec.Struct, omit_defaults=True):
|
||||
audio: str | None = None
|
||||
audio_languages: list[str] | None = None
|
||||
subtitle_languages: list[str] | None = None
|
||||
external_subtitle_languages: list[str] | None = None
|
||||
hdr: bool = False
|
||||
dovi: bool = False
|
||||
atmos: bool = False
|
||||
|
||||
@@ -14,12 +14,20 @@ from .tmdb import Person
|
||||
|
||||
|
||||
class Upsert(msgspec.Struct, tag="upsert"):
|
||||
"""Single item inserted or updated."""
|
||||
"""Single item inserted or updated.
|
||||
|
||||
``scanned`` lists the media-root-relative torrent paths whose content was
|
||||
(re)scanned to build this item. When present, the store merges the item
|
||||
into the existing entry instead of replacing it wholesale: only data
|
||||
belonging to the scanned torrents is replaced. ``None`` means full
|
||||
replacement (legacy behaviour).
|
||||
"""
|
||||
|
||||
kind: str # "movie" or "series"
|
||||
id: str
|
||||
item: Movie | Series
|
||||
people: dict[int, Person] | None = None
|
||||
scanned: list[str] | None = None
|
||||
|
||||
|
||||
class Remove(msgspec.Struct, tag="remove"):
|
||||
@@ -29,6 +37,35 @@ class Remove(msgspec.Struct, tag="remove"):
|
||||
id: str
|
||||
|
||||
|
||||
class Sync(msgspec.Struct, tag="sync"):
|
||||
"""Full set of media-root-relative torrent paths currently on disk.
|
||||
|
||||
Sent by the scanner after a successfully completed discovery pass so the
|
||||
store can drop entries whose files no longer exist. Internal only —
|
||||
never forwarded to WebSocket clients.
|
||||
"""
|
||||
|
||||
paths: list[str]
|
||||
|
||||
|
||||
class MovieShowreel(msgspec.Struct, tag="movie-showreel"):
|
||||
"""Reel worker result for a movie (internal, scanner → store)."""
|
||||
|
||||
id: str
|
||||
showreel_images: list[str] | None = None
|
||||
showreel_source_sets: list[list[str]] | None = None
|
||||
|
||||
|
||||
class EpisodeReel(msgspec.Struct, tag="episode-reel"):
|
||||
"""Reel worker result for one episode (internal, scanner → store)."""
|
||||
|
||||
id: str
|
||||
season: int
|
||||
episode: int
|
||||
reel_image: str | None = None
|
||||
reel_sources: list[str] | None = None
|
||||
|
||||
|
||||
class Task(msgspec.Struct, tag="task"):
|
||||
"""Task progress broadcast."""
|
||||
|
||||
@@ -36,4 +73,4 @@ class Task(msgspec.Struct, tag="task"):
|
||||
|
||||
|
||||
# Union of scan events (scanner → server) and WS broadcast messages
|
||||
ScanEvent = Upsert | Task
|
||||
ScanEvent = Upsert | Sync | MovieShowreel | EpisodeReel | Task
|
||||
|
||||
@@ -11,7 +11,14 @@ import msgspec
|
||||
|
||||
from mediahive.config import load_config, save_config
|
||||
from mediahive.index_store import IndexStore
|
||||
from mediahive.models.events import ScanEvent, Task, Upsert
|
||||
from mediahive.models.events import (
|
||||
EpisodeReel,
|
||||
MovieShowreel,
|
||||
ScanEvent,
|
||||
Sync,
|
||||
Task,
|
||||
Upsert,
|
||||
)
|
||||
|
||||
logger = logging.getLogger("mediahive.root_registry")
|
||||
|
||||
@@ -158,9 +165,27 @@ class RootContext:
|
||||
event = await self._events.get()
|
||||
if isinstance(event, Upsert):
|
||||
if event.kind == "movie":
|
||||
self.store.upsert_movie(event.id, event.item, event.people)
|
||||
self.store.upsert_movie(
|
||||
event.id, event.item, event.people, event.scanned
|
||||
)
|
||||
else:
|
||||
self.store.upsert_series(event.id, event.item, event.people)
|
||||
self.store.upsert_series(
|
||||
event.id, event.item, event.people, event.scanned
|
||||
)
|
||||
elif isinstance(event, Sync):
|
||||
self.store.sync_torrent_paths(set(event.paths))
|
||||
elif isinstance(event, MovieShowreel):
|
||||
self.store.set_movie_showreel(
|
||||
event.id, event.showreel_images, event.showreel_source_sets
|
||||
)
|
||||
elif isinstance(event, EpisodeReel):
|
||||
self.store.set_episode_reel(
|
||||
event.id,
|
||||
event.season,
|
||||
event.episode,
|
||||
event.reel_image,
|
||||
event.reel_sources,
|
||||
)
|
||||
elif isinstance(event, Task):
|
||||
self.store.broadcast_task(event.data)
|
||||
except asyncio.CancelledError:
|
||||
@@ -328,6 +353,10 @@ class Supervisor:
|
||||
|
||||
async def shutdown(self) -> None:
|
||||
async with self._lock:
|
||||
for ctx in list(self._contexts.values()):
|
||||
await ctx.stop()
|
||||
# Stop roots concurrently — each may wait on task cancellation and
|
||||
# network-mount snapshot flushes, and those delays must not add up.
|
||||
await asyncio.gather(
|
||||
*(ctx.stop() for ctx in list(self._contexts.values())),
|
||||
return_exceptions=True,
|
||||
)
|
||||
self._contexts.clear()
|
||||
|
||||
+583
-101
@@ -9,6 +9,7 @@ from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import ctypes
|
||||
import importlib.metadata
|
||||
import json
|
||||
import logging
|
||||
import mimetypes
|
||||
@@ -28,19 +29,19 @@ from pathlib import Path
|
||||
|
||||
import aiofiles
|
||||
import msgspec
|
||||
import msgspec.structs
|
||||
from fastapi import FastAPI, HTTPException, Request, WebSocket, WebSocketDisconnect
|
||||
from fastapi.middleware.cors import CORSMiddleware
|
||||
from fastapi.responses import FileResponse, Response, StreamingResponse
|
||||
from fastapi_vue import Frontend
|
||||
|
||||
from mediahive.__main__ import DEVMODE
|
||||
from mediahive.access_logging import (
|
||||
AccessLogMiddleware,
|
||||
configure_access_logging,
|
||||
log_ws_close,
|
||||
log_ws_open,
|
||||
from fastapi.responses import (
|
||||
FileResponse,
|
||||
PlainTextResponse,
|
||||
Response,
|
||||
StreamingResponse,
|
||||
)
|
||||
from mediahive.config import load_config
|
||||
from fastapi_vue import Frontend, env
|
||||
|
||||
from mediahive import updater
|
||||
from mediahive.config import config, load_config, log_dir, save_config
|
||||
from mediahive.hivescan.images import close_image_client
|
||||
from mediahive.hivescan.scanner import RootScanner
|
||||
from mediahive.hivescan.tmdb_client import close_http_client
|
||||
@@ -63,8 +64,6 @@ from mediahive.root_registry import Supervisor
|
||||
|
||||
logger = logging.getLogger("mediahive.server")
|
||||
|
||||
configure_access_logging()
|
||||
|
||||
MPC_BE_DEFAULT_PORT = 13579
|
||||
|
||||
# Suppress console windows when spawning subprocesses on Windows
|
||||
@@ -89,16 +88,62 @@ if sys.platform == "win32":
|
||||
|
||||
|
||||
@dataclass
|
||||
class _PlaybackEntry:
|
||||
"""Single resume position entry with timestamp."""
|
||||
class _EpisodeWatch:
|
||||
"""Per-episode watch progress within a series entry."""
|
||||
|
||||
pos: int
|
||||
ts: datetime
|
||||
done: bool = False
|
||||
|
||||
def to_dict(self) -> dict:
|
||||
return {"pos": self.pos, "ts": self.ts, "done": self.done}
|
||||
|
||||
@staticmethod
|
||||
def from_dict(data: dict) -> _EpisodeWatch | None:
|
||||
if not isinstance(data, dict):
|
||||
return None
|
||||
pos = data.get("pos")
|
||||
ts = data.get("ts")
|
||||
if not isinstance(pos, int) or pos < 0:
|
||||
return None
|
||||
if isinstance(ts, str):
|
||||
try:
|
||||
ts = datetime.fromisoformat(ts)
|
||||
except ValueError, TypeError:
|
||||
return None
|
||||
elif not isinstance(ts, datetime):
|
||||
return None
|
||||
return _EpisodeWatch(pos=pos, ts=ts, done=bool(data.get("done")))
|
||||
|
||||
|
||||
def _episode_watch_key(season: int, episode: int) -> str:
|
||||
return f"S{season}E{episode}"
|
||||
|
||||
|
||||
@dataclass
|
||||
class _PlaybackEntry:
|
||||
"""Resume entry for one media slug.
|
||||
|
||||
season/episode form the series' single continue point (last watched
|
||||
episode), None for movies. episodes holds per-episode watch progress
|
||||
for series, keyed "S<season>E<episode>".
|
||||
"""
|
||||
|
||||
pos: int
|
||||
ts: datetime
|
||||
season: int | None = None
|
||||
episode: int | None = None
|
||||
episodes: dict[str, _EpisodeWatch] = field(default_factory=dict)
|
||||
|
||||
def to_dict(self) -> dict:
|
||||
return {
|
||||
"pos": self.pos,
|
||||
"ts": self.ts,
|
||||
"season": self.season,
|
||||
"episode": self.episode,
|
||||
"episodes": {
|
||||
key: watch.to_dict() for key, watch in sorted(self.episodes.items())
|
||||
},
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
@@ -118,7 +163,22 @@ class _PlaybackEntry:
|
||||
pass
|
||||
else:
|
||||
return None
|
||||
return _PlaybackEntry(pos=pos, ts=ts)
|
||||
season = data.get("season")
|
||||
episode = data.get("episode")
|
||||
episodes: dict[str, _EpisodeWatch] = {}
|
||||
raw_episodes = data.get("episodes")
|
||||
if isinstance(raw_episodes, dict):
|
||||
for key, watch_data in raw_episodes.items():
|
||||
watch = _EpisodeWatch.from_dict(watch_data)
|
||||
if watch is not None:
|
||||
episodes[str(key)] = watch
|
||||
return _PlaybackEntry(
|
||||
pos=pos,
|
||||
ts=ts,
|
||||
season=season if isinstance(season, int) else None,
|
||||
episode=episode if isinstance(episode, int) else None,
|
||||
episodes=episodes,
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -131,7 +191,8 @@ class _PlaybackRootSnapshot:
|
||||
class PlaybackStateCache:
|
||||
"""Background cache for merged playback-state across all active roots.
|
||||
|
||||
Stores resume positions by movie slug with timestamps. When merging
|
||||
Stores resume positions by media slug (movie id, or series id with a
|
||||
season/episode continue point) with timestamps. When merging
|
||||
across roots, picks the most recent entry for each slug.
|
||||
"""
|
||||
|
||||
@@ -164,7 +225,7 @@ class PlaybackStateCache:
|
||||
"""Return merged resume entries keyed by slug (most recent wins)."""
|
||||
with self._lock:
|
||||
return {
|
||||
slug: _PlaybackEntry(e.pos, e.ts)
|
||||
slug: _PlaybackEntry(e.pos, e.ts, e.season, e.episode, dict(e.episodes))
|
||||
for slug, e in self._merged_entries.items()
|
||||
}
|
||||
|
||||
@@ -174,15 +235,50 @@ class PlaybackStateCache:
|
||||
root_path: Path,
|
||||
slug: str,
|
||||
pos: int | None,
|
||||
season: int | None = None,
|
||||
episode: int | None = None,
|
||||
*,
|
||||
done_episode: tuple[int, int] | None = None,
|
||||
) -> None:
|
||||
"""Read-modify-write one root file and refresh the in-memory cache immediately."""
|
||||
"""Read-modify-write one root file and refresh the in-memory cache immediately.
|
||||
|
||||
For series entries, updates both the series continue point (last
|
||||
watched episode) and the per-episode watch map. done_episode marks a
|
||||
completed episode as fully watched without touching the continue
|
||||
point position semantics (used together with advancing the point).
|
||||
"""
|
||||
file_path = root_path / ".mediahive" / "playback-state.json"
|
||||
entries = self._read_resume_entries(file_path)
|
||||
|
||||
if pos is None:
|
||||
if pos is None and done_episode is None:
|
||||
entries.pop(slug, None)
|
||||
else:
|
||||
entries[slug] = _PlaybackEntry(pos=pos, ts=datetime.now())
|
||||
now = datetime.now()
|
||||
entry = entries.get(slug)
|
||||
if entry is None:
|
||||
entry = _PlaybackEntry(pos=pos or 0, ts=now)
|
||||
entries[slug] = entry
|
||||
if pos is not None:
|
||||
entry.pos = pos
|
||||
entry.ts = now
|
||||
entry.season = season
|
||||
entry.episode = episode
|
||||
if season is not None and episode is not None and pos > 0:
|
||||
entry.episodes[_episode_watch_key(season, episode)] = _EpisodeWatch(
|
||||
pos=pos, ts=now
|
||||
)
|
||||
elif done_episode is not None:
|
||||
# Final episode completed: no continue point remains, but the
|
||||
# per-episode watch history is kept for indicators.
|
||||
entry.pos = 0
|
||||
entry.ts = now
|
||||
entry.season = None
|
||||
entry.episode = None
|
||||
if done_episode is not None:
|
||||
done_season, done_ep = done_episode
|
||||
entry.episodes[_episode_watch_key(done_season, done_ep)] = (
|
||||
_EpisodeWatch(pos=0, ts=now, done=True)
|
||||
)
|
||||
|
||||
self._write_resume_entries(file_path, entries)
|
||||
|
||||
@@ -211,7 +307,6 @@ class PlaybackStateCache:
|
||||
previous = self._roots
|
||||
|
||||
next_roots: dict[str, _PlaybackRootSnapshot] = {}
|
||||
merged: dict[str, _PlaybackEntry] = {}
|
||||
|
||||
for root_id, ctx in contexts.items():
|
||||
file_path = ctx.root_path / ".mediahive" / "playback-state.json"
|
||||
@@ -226,15 +321,9 @@ class PlaybackStateCache:
|
||||
|
||||
next_roots[root_id] = snapshot
|
||||
|
||||
# Merge: for each slug, keep the entry with the most recent timestamp
|
||||
for slug, entry in snapshot.entries.items():
|
||||
existing = merged.get(slug)
|
||||
if existing is None or entry.ts > existing.ts:
|
||||
merged[slug] = entry
|
||||
|
||||
with self._lock:
|
||||
self._roots = next_roots
|
||||
self._merged_entries = merged
|
||||
self._merged_entries = self._build_merged_entries(next_roots)
|
||||
|
||||
@staticmethod
|
||||
def _signature(path: Path) -> tuple[bool, int, int]:
|
||||
@@ -288,12 +377,33 @@ class PlaybackStateCache:
|
||||
def _build_merged_entries(
|
||||
roots: dict[str, _PlaybackRootSnapshot],
|
||||
) -> dict[str, _PlaybackEntry]:
|
||||
"""Merge resume entries across roots.
|
||||
|
||||
Newest continue point per slug, and newest watch state per episode
|
||||
key within each slug.
|
||||
"""
|
||||
merged: dict[str, _PlaybackEntry] = {}
|
||||
for snapshot in roots.values():
|
||||
for slug, entry in snapshot.entries.items():
|
||||
existing = merged.get(slug)
|
||||
if existing is None or entry.ts > existing.ts:
|
||||
merged[slug] = entry
|
||||
if existing is None:
|
||||
merged[slug] = _PlaybackEntry(
|
||||
entry.pos,
|
||||
entry.ts,
|
||||
entry.season,
|
||||
entry.episode,
|
||||
dict(entry.episodes),
|
||||
)
|
||||
continue
|
||||
if entry.ts > existing.ts:
|
||||
existing.pos = entry.pos
|
||||
existing.ts = entry.ts
|
||||
existing.season = entry.season
|
||||
existing.episode = entry.episode
|
||||
for key, watch in entry.episodes.items():
|
||||
current = existing.episodes.get(key)
|
||||
if current is None or watch.ts > current.ts:
|
||||
existing.episodes[key] = watch
|
||||
return merged
|
||||
|
||||
|
||||
@@ -378,21 +488,195 @@ def _expand_torrent_playable_path(file_key: str, playable_file: str | None) -> s
|
||||
return f"{file_key}/{playable_file}"
|
||||
|
||||
|
||||
def _resolve_movie_slug_for_file_path(ctx, file_path: str) -> str | None:
|
||||
def _resolve_media_ref_for_file_path(
|
||||
ctx, file_path: str
|
||||
) -> tuple[str, int | None, int | None] | None:
|
||||
"""Resolve a playable file path to (slug, season_number, episode_number).
|
||||
|
||||
Movies return (movie_id, None, None); series episode files return
|
||||
(series_id, season_number, episode_number).
|
||||
"""
|
||||
target = _normalize_media_path_value(file_path)
|
||||
for movie_id, movie in ctx.store.movies.items():
|
||||
for file_key, torrent in movie.files.items():
|
||||
normalized_key = _normalize_media_path_value(file_key)
|
||||
if normalized_key == target:
|
||||
return movie_id
|
||||
return movie_id, None, None
|
||||
playable_path = _expand_torrent_playable_path(
|
||||
file_key, torrent.playable_file
|
||||
)
|
||||
if _normalize_media_path_value(playable_path) == target:
|
||||
return movie_id
|
||||
return movie_id, None, None
|
||||
for series_id, show in ctx.store.series.items():
|
||||
for season in show.seasons:
|
||||
for episode in season.episodes:
|
||||
for file_key, torrent in episode.files.items():
|
||||
normalized_key = _normalize_media_path_value(file_key)
|
||||
if normalized_key == target:
|
||||
return series_id, season.season_number, episode.episode_number
|
||||
playable_path = _expand_torrent_playable_path(
|
||||
file_key, torrent.playable_file
|
||||
)
|
||||
if _normalize_media_path_value(playable_path) == target:
|
||||
return series_id, season.season_number, episode.episode_number
|
||||
return None
|
||||
|
||||
|
||||
def _next_episode_ref(
|
||||
show, season_number: int, episode_number: int
|
||||
) -> tuple[int, int] | None:
|
||||
"""Return the (season_number, episode_number) following the given episode."""
|
||||
for season_index, season in enumerate(show.seasons):
|
||||
if season.season_number != season_number:
|
||||
continue
|
||||
for episode_index, episode in enumerate(season.episodes):
|
||||
if episode.episode_number != episode_number:
|
||||
continue
|
||||
if episode_index + 1 < len(season.episodes):
|
||||
return season.season_number, season.episodes[
|
||||
episode_index + 1
|
||||
].episode_number
|
||||
if season_index + 1 < len(show.seasons):
|
||||
next_season = show.seasons[season_index + 1]
|
||||
if next_season.episodes:
|
||||
return next_season.season_number, next_season.episodes[
|
||||
0
|
||||
].episode_number
|
||||
return None
|
||||
return None
|
||||
|
||||
|
||||
# --- Assumed playback tracking (player-agnostic fallback) ---
|
||||
#
|
||||
# Launching an external player returns immediately and no player API is
|
||||
# guaranteed, so for arbitrary players we cannot observe real progress.
|
||||
# Instead: when the user launches an item and the frontend then sees no
|
||||
# input activity, the item is assumed to be playing. The resume position is
|
||||
# written once, when frontend activity resumes (i.e. the user came back).
|
||||
# The MPC-BE tracker in the GUI overrides this: if a newer entry for the
|
||||
# slug was written while the session ran, the guess is discarded.
|
||||
|
||||
ASSUMED_PLAYBACK_MIN_WATCH_S = 300
|
||||
|
||||
|
||||
@dataclass
|
||||
class _AssumedPlaybackSession:
|
||||
root_id: str
|
||||
slug: str
|
||||
season: int | None
|
||||
episode: int | None
|
||||
base_pos_s: int
|
||||
started_mono: float
|
||||
started_wall: datetime
|
||||
duration_s: int | None
|
||||
|
||||
|
||||
_assumed_playback: _AssumedPlaybackSession | None = None
|
||||
|
||||
|
||||
def _media_duration_seconds(
|
||||
ctx, slug: str, season_number: int | None, episode_number: int | None
|
||||
) -> int | None:
|
||||
"""Best-known runtime in seconds (TMDb, minutes) for a media ref."""
|
||||
minutes: int | None = None
|
||||
if season_number is None:
|
||||
movie = ctx.store.movies.get(slug)
|
||||
if movie is not None and movie.info is not None:
|
||||
minutes = movie.info.runtime
|
||||
else:
|
||||
show = ctx.store.series.get(slug)
|
||||
if show is not None:
|
||||
for season in show.seasons:
|
||||
if season.season_number != season_number:
|
||||
continue
|
||||
for episode in season.episodes:
|
||||
if episode.episode_number == episode_number:
|
||||
minutes = episode.runtime
|
||||
break
|
||||
break
|
||||
return minutes * 60 if minutes else None
|
||||
|
||||
|
||||
def _start_assumed_playback(ctx, root_id: str, file_path: str) -> None:
|
||||
"""Begin a guessed-watch session for a freshly launched file."""
|
||||
global _assumed_playback
|
||||
# Time between two launches counts as watching the previous item.
|
||||
_finalize_assumed_playback()
|
||||
|
||||
ref = _resolve_media_ref_for_file_path(ctx, file_path)
|
||||
if ref is None:
|
||||
return
|
||||
slug, season_number, episode_number = ref
|
||||
|
||||
entry = playback_state_cache.get_merged_entries().get(slug)
|
||||
base_pos_s = 0
|
||||
if entry is not None:
|
||||
if season_number is None or (entry.season, entry.episode) == (
|
||||
season_number,
|
||||
episode_number,
|
||||
):
|
||||
base_pos_s = entry.pos
|
||||
|
||||
_assumed_playback = _AssumedPlaybackSession(
|
||||
root_id=root_id,
|
||||
slug=slug,
|
||||
season=season_number,
|
||||
episode=episode_number,
|
||||
base_pos_s=base_pos_s,
|
||||
started_mono=time.monotonic(),
|
||||
started_wall=datetime.now(),
|
||||
duration_s=_media_duration_seconds(ctx, slug, season_number, episode_number),
|
||||
)
|
||||
|
||||
|
||||
def _finalize_assumed_playback() -> bool:
|
||||
"""Close the guessed-watch session, writing the assumed position.
|
||||
|
||||
Returns True when a resume position was actually written.
|
||||
"""
|
||||
global _assumed_playback
|
||||
session = _assumed_playback
|
||||
_assumed_playback = None
|
||||
if session is None:
|
||||
return False
|
||||
|
||||
elapsed_s = int(time.monotonic() - session.started_mono)
|
||||
if elapsed_s < ASSUMED_PLAYBACK_MIN_WATCH_S:
|
||||
return False
|
||||
pos_s = session.base_pos_s + elapsed_s
|
||||
if session.duration_s:
|
||||
pos_s = min(pos_s, session.duration_s)
|
||||
if pos_s <= 0:
|
||||
return False
|
||||
|
||||
# A newer entry written while this session ran (e.g. the GUI's real
|
||||
# MPC-BE tracker finalizing on player close) overrides the guess.
|
||||
current = playback_state_cache.get_merged_entries().get(session.slug)
|
||||
if current is not None and current.ts > session.started_wall:
|
||||
return False
|
||||
|
||||
ctx = supervisor.get(session.root_id)
|
||||
if ctx is None:
|
||||
return False
|
||||
playback_state_cache.update_resume_position(
|
||||
session.root_id,
|
||||
ctx.root_path,
|
||||
session.slug,
|
||||
pos_s,
|
||||
session.season,
|
||||
session.episode,
|
||||
)
|
||||
logger.info(
|
||||
"Assumed playback: %s S%sE%s +%ds -> pos %ds",
|
||||
session.slug,
|
||||
session.season,
|
||||
session.episode,
|
||||
elapsed_s,
|
||||
pos_s,
|
||||
)
|
||||
return True
|
||||
|
||||
|
||||
def _load_root_metadata(root_path: Path, meta_key: str):
|
||||
"""Load allowed per-root metadata values from .mediahive."""
|
||||
key = meta_key.strip().lower().strip("/")
|
||||
@@ -660,7 +944,12 @@ async def _attach_scanners() -> None:
|
||||
for ctx in supervisor.all_contexts().values():
|
||||
if ctx.scanner is None and ctx.status == "ready":
|
||||
try:
|
||||
scanner = RootScanner(ctx.root_id, ctx.root_path, ctx.send_event)
|
||||
scanner = RootScanner(
|
||||
ctx.root_id,
|
||||
ctx.root_path,
|
||||
ctx.send_event,
|
||||
ctx.store.torrent_paths,
|
||||
)
|
||||
await scanner.start()
|
||||
ctx.scanner = scanner
|
||||
except Exception:
|
||||
@@ -686,23 +975,14 @@ async def _activate_all_roots() -> None:
|
||||
"""
|
||||
desired: dict[str, str] = {}
|
||||
|
||||
# 1. CLI roots via MEDIAHIVE_ROOTS (JSON dict)
|
||||
env_roots_raw = os.environ.get("MEDIAHIVE_ROOTS")
|
||||
env_roots: dict[str, str] | None = None
|
||||
if env_roots_raw:
|
||||
try:
|
||||
parsed = json.loads(env_roots_raw)
|
||||
if isinstance(parsed, dict):
|
||||
env_roots = parsed
|
||||
except Exception:
|
||||
logger.exception("Failed to parse MEDIAHIVE_ROOTS")
|
||||
|
||||
# 1. CLI roots (teleported via fastapi-vue's env config) take precedence
|
||||
# 2. Persisted config roots (used only when CLI roots are not provided)
|
||||
cfg = load_config()
|
||||
if env_roots is not None:
|
||||
desired.update(env_roots)
|
||||
elif cfg.roots:
|
||||
desired.update(cfg.roots)
|
||||
if config.roots:
|
||||
desired.update(config.roots)
|
||||
else:
|
||||
cfg = load_config()
|
||||
if cfg.roots:
|
||||
desired.update(cfg.roots)
|
||||
|
||||
if not desired:
|
||||
logger.info("No roots configured; waiting for PUT /api/config/roots")
|
||||
@@ -748,6 +1028,7 @@ async def lifespan(_app: FastAPI):
|
||||
try:
|
||||
yield
|
||||
finally:
|
||||
_finalize_assumed_playback()
|
||||
playback_state_cache.stop()
|
||||
await event_loop_lag_monitor.stop()
|
||||
|
||||
@@ -767,10 +1048,7 @@ async def lifespan(_app: FastAPI):
|
||||
await close_image_client()
|
||||
|
||||
|
||||
app = FastAPI(title="MediaHive Server", lifespan=lifespan, debug=DEVMODE)
|
||||
|
||||
# Custom access logging (uvicorn access logs are suppressed in access_logging)
|
||||
app.add_middleware(AccessLogMiddleware)
|
||||
app = FastAPI(title="MediaHive Server", lifespan=lifespan, debug=env.dev)
|
||||
|
||||
# Allow CORS for development
|
||||
app.add_middleware(
|
||||
@@ -793,6 +1071,114 @@ async def health_check():
|
||||
return {"status": "ok"}
|
||||
|
||||
|
||||
@app.get("/api/version")
|
||||
async def get_version():
|
||||
"""Return the installed MediaHive package version."""
|
||||
try:
|
||||
version = importlib.metadata.version("mediahive")
|
||||
except importlib.metadata.PackageNotFoundError:
|
||||
version = "dev"
|
||||
return {"version": version}
|
||||
|
||||
|
||||
# --- Auto-update (Velopack, GUI builds only) ---
|
||||
|
||||
|
||||
@app.get("/api/update")
|
||||
async def get_update_status():
|
||||
"""Version, auto-update preference, and any staged (downloaded) update."""
|
||||
version = (await get_version())["version"]
|
||||
cfg = load_config()
|
||||
pending = await asyncio.to_thread(updater.pending_update)
|
||||
return {
|
||||
"version": version,
|
||||
"auto_update": cfg.auto_update,
|
||||
"pending_version": pending,
|
||||
}
|
||||
|
||||
|
||||
@app.put("/api/config/auto-update")
|
||||
async def put_auto_update(request: Request):
|
||||
"""Enable/disable automatic update downloads (persisted in config)."""
|
||||
body = msgspec.json.decode(await request.body())
|
||||
enabled = bool(body.get("enabled", True))
|
||||
cfg = load_config()
|
||||
save_config(msgspec.structs.replace(cfg, auto_update=enabled))
|
||||
with suppress(AttributeError, TypeError):
|
||||
config.auto_update = enabled
|
||||
if enabled:
|
||||
# Catch up on anything missed while updates were disabled.
|
||||
asyncio.create_task(asyncio.to_thread(updater.check_and_download))
|
||||
return {"auto_update": enabled}
|
||||
|
||||
|
||||
@app.post("/api/update/restart")
|
||||
async def restart_for_update():
|
||||
"""Apply the staged update and restart into it (never returns on success)."""
|
||||
applied = await asyncio.to_thread(updater.apply_pending_and_restart)
|
||||
if not applied:
|
||||
raise HTTPException(status_code=404, detail="No downloaded update to apply")
|
||||
return {"status": "restarting"}
|
||||
|
||||
|
||||
def _read_log() -> str:
|
||||
"""Return the full application log file."""
|
||||
path = log_dir() / "mediahive.log"
|
||||
if not path.exists():
|
||||
return ""
|
||||
try:
|
||||
return path.read_text(encoding="utf-8", errors="replace")
|
||||
except OSError:
|
||||
return ""
|
||||
|
||||
|
||||
@app.get("/api/log")
|
||||
async def get_log():
|
||||
"""Return the full application log file."""
|
||||
return PlainTextResponse(_read_log())
|
||||
|
||||
|
||||
@app.websocket("/api/log/ws")
|
||||
async def ws_log(ws: WebSocket) -> None:
|
||||
"""Stream the application log: full log on connect and on every change."""
|
||||
await ws.accept()
|
||||
last_sent: str | None = None
|
||||
try:
|
||||
while True:
|
||||
current = _read_log()
|
||||
if current != last_sent:
|
||||
last_sent = current
|
||||
await ws.send_text(current)
|
||||
await asyncio.sleep(1.0)
|
||||
except WebSocketDisconnect, OSError, RuntimeError:
|
||||
pass
|
||||
|
||||
|
||||
@app.post("/api/client-log", status_code=204)
|
||||
async def post_client_log(request: Request):
|
||||
"""Append a client-side (webview) error report to client-errors.log."""
|
||||
try:
|
||||
payload = msgspec.json.decode(await request.body())
|
||||
except msgspec.DecodeError:
|
||||
payload = {}
|
||||
message = str(payload.get("message") or "")
|
||||
stack = payload.get("stack")
|
||||
source = payload.get("source")
|
||||
try:
|
||||
dirpath = log_dir()
|
||||
dirpath.mkdir(parents=True, exist_ok=True)
|
||||
with (dirpath / "client-errors.log").open("a", encoding="utf-8") as f:
|
||||
timestamp = datetime.now().isoformat(timespec="seconds")
|
||||
f.write(f"[{timestamp}] {message}\n")
|
||||
if source:
|
||||
f.write(f" source: {source}\n")
|
||||
if stack:
|
||||
f.write(f" stack: {stack}\n")
|
||||
except OSError:
|
||||
pass
|
||||
return Response(status_code=204)
|
||||
|
||||
|
||||
@app.get("/api/config")
|
||||
async def get_config():
|
||||
"""Return current server configuration."""
|
||||
@@ -829,9 +1215,6 @@ async def ws_endpoint(ws: WebSocket) -> None:
|
||||
attached_contexts = supervisor.all_contexts()
|
||||
outbound: asyncio.Queue[bytes] = asyncio.Queue()
|
||||
|
||||
start = time.perf_counter()
|
||||
ws_id = log_ws_open(ws)
|
||||
close_code: int | None = None
|
||||
prev_root_ids: set[str] = set()
|
||||
prev_meta: dict[str, tuple[str, str, str | None, bool]] = {}
|
||||
|
||||
@@ -918,9 +1301,7 @@ async def ws_endpoint(ws: WebSocket) -> None:
|
||||
try:
|
||||
while True:
|
||||
await ws.receive_text()
|
||||
except WebSocketDisconnect as exc:
|
||||
close_code = exc.code
|
||||
except OSError, RuntimeError:
|
||||
except WebSocketDisconnect, OSError, RuntimeError:
|
||||
pass
|
||||
finally:
|
||||
sender_task.cancel()
|
||||
@@ -935,8 +1316,6 @@ async def ws_endpoint(ws: WebSocket) -> None:
|
||||
if ctx is not None:
|
||||
ctx.store.remove_listener(listener)
|
||||
|
||||
log_ws_close(ws_id, close_code, time.perf_counter() - start)
|
||||
|
||||
|
||||
# --- Media actions ---
|
||||
|
||||
@@ -999,6 +1378,10 @@ async def play_media(root_id: str, request: Request, response: Response):
|
||||
|
||||
launch_ms = (time.perf_counter() - launch_t0) * 1000.0
|
||||
total_ms = (time.perf_counter() - req_start) * 1000.0
|
||||
|
||||
# Player-agnostic fallback: assume the launched item is being watched
|
||||
# until frontend activity resumes (real MPC-BE tracking overrides).
|
||||
_start_assumed_playback(ctx, root_id, req.file_path)
|
||||
loop_lag_ms, loop_lag_max_ms = event_loop_lag_monitor.snapshot()
|
||||
|
||||
if trace_id:
|
||||
@@ -1110,6 +1493,16 @@ async def root_metadata(root_id: str, meta_key: str):
|
||||
return {"key": meta_key, "data": _load_root_metadata(ctx.root_path, meta_key)}
|
||||
|
||||
|
||||
@app.post("/api/activity")
|
||||
async def report_activity():
|
||||
"""Report user input activity in the frontend.
|
||||
|
||||
Ends any assumed-playback session: activity means the user is back at
|
||||
the UI, so the launched item's guessed watch time is written out.
|
||||
"""
|
||||
return {"status": "ok", "finalized": _finalize_assumed_playback()}
|
||||
|
||||
|
||||
@app.get("/api/meta/playback-state")
|
||||
async def merged_playback_state():
|
||||
"""Return merged playback-state resume positions from in-memory cache.
|
||||
@@ -1124,18 +1517,66 @@ async def merged_playback_state():
|
||||
|
||||
@app.post("/api/meta/playback-state")
|
||||
async def write_playback_state(request: Request):
|
||||
"""Update one playback-state entry via backend-managed read-modify-write."""
|
||||
"""Update one playback-state entry via backend-managed read-modify-write.
|
||||
|
||||
A series episode played to completion (pos null) is marked fully watched
|
||||
in the per-episode watch map and advances the series' single continue
|
||||
point to the next episode (pos 0); finishing the final episode clears
|
||||
the continue point but keeps the watch history.
|
||||
"""
|
||||
req = msgspec.json.decode(await request.body(), type=PlaybackStateUpdateRequest)
|
||||
ctx = _get_context(req.root_id)
|
||||
slug = _resolve_movie_slug_for_file_path(ctx, req.file_path)
|
||||
if slug is None:
|
||||
ref = _resolve_media_ref_for_file_path(ctx, req.file_path)
|
||||
if ref is None:
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail=f"Movie not found for file path: {req.file_path}",
|
||||
detail=f"Media not found for file path: {req.file_path}",
|
||||
)
|
||||
|
||||
pos = None if req.pos is None or req.pos <= 0 else int(req.pos)
|
||||
playback_state_cache.update_resume_position(req.root_id, ctx.root_path, slug, pos)
|
||||
slug, season_number, episode_number = ref
|
||||
|
||||
if req.pos is None or req.pos <= 0:
|
||||
if season_number is None:
|
||||
playback_state_cache.update_resume_position(
|
||||
req.root_id, ctx.root_path, slug, None
|
||||
)
|
||||
return {"status": "ok", "slug": slug, "pos": None}
|
||||
|
||||
show = ctx.store.series.get(slug)
|
||||
next_ref = (
|
||||
_next_episode_ref(show, season_number, episode_number)
|
||||
if show is not None
|
||||
else None
|
||||
)
|
||||
done = (season_number, episode_number)
|
||||
if next_ref is None:
|
||||
playback_state_cache.update_resume_position(
|
||||
req.root_id, ctx.root_path, slug, None, done_episode=done
|
||||
)
|
||||
return {"status": "ok", "slug": slug, "pos": None}
|
||||
|
||||
next_season, next_episode = next_ref
|
||||
playback_state_cache.update_resume_position(
|
||||
req.root_id,
|
||||
ctx.root_path,
|
||||
slug,
|
||||
0,
|
||||
next_season,
|
||||
next_episode,
|
||||
done_episode=done,
|
||||
)
|
||||
return {
|
||||
"status": "ok",
|
||||
"slug": slug,
|
||||
"pos": 0,
|
||||
"season": next_season,
|
||||
"episode": next_episode,
|
||||
}
|
||||
|
||||
pos = int(req.pos)
|
||||
playback_state_cache.update_resume_position(
|
||||
req.root_id, ctx.root_path, slug, pos, season_number, episode_number
|
||||
)
|
||||
return {"status": "ok", "slug": slug, "pos": pos}
|
||||
|
||||
|
||||
@@ -1186,6 +1627,74 @@ def _resolve_root_scoped_path(base: Path, raw_path: str) -> Path:
|
||||
return candidate
|
||||
|
||||
|
||||
class StreamingFileResponse(StreamingResponse):
|
||||
"""Stream a file from disk with optional single-range support.
|
||||
|
||||
Unlike plain ``StreamingResponse`` with a generator, the file handle is
|
||||
held in ``stream_response`` scope across the send loop (the same pattern
|
||||
as Starlette's ``FileResponse``), so it is always closed promptly and in
|
||||
flow — including on client disconnect, where a generator's cleanup would
|
||||
be deferred to GC and its exceptions lost.
|
||||
"""
|
||||
|
||||
chunk_size = 64 * 1024
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
path: Path,
|
||||
*,
|
||||
file_size: int,
|
||||
etag: str,
|
||||
cache_control: str,
|
||||
media_type: str,
|
||||
range_header: str | None = None,
|
||||
) -> None:
|
||||
if range_header:
|
||||
self._start, self._end = _parse_range_header(range_header, file_size)
|
||||
status_code = 206
|
||||
else:
|
||||
self._start, self._end = 0, file_size - 1
|
||||
status_code = 200
|
||||
|
||||
headers = {
|
||||
"Cache-Control": cache_control,
|
||||
"ETag": etag,
|
||||
"Accept-Ranges": "bytes",
|
||||
"Content-Length": str(self._end - self._start + 1),
|
||||
}
|
||||
if status_code == 206:
|
||||
headers["Content-Range"] = f"bytes {self._start}-{self._end}/{file_size}"
|
||||
|
||||
super().__init__( # body_iterator is unused; stream_response is overridden
|
||||
content=(),
|
||||
status_code=status_code,
|
||||
headers=headers,
|
||||
media_type=media_type,
|
||||
)
|
||||
self.path = path
|
||||
|
||||
async def stream_response(self, send) -> None:
|
||||
await send({
|
||||
"type": "http.response.start",
|
||||
"status": self.status_code,
|
||||
"headers": self.raw_headers,
|
||||
})
|
||||
async with aiofiles.open(self.path, "rb") as f:
|
||||
await f.seek(self._start)
|
||||
remaining = self._end - self._start + 1
|
||||
while remaining > 0:
|
||||
chunk = await f.read(min(self.chunk_size, remaining))
|
||||
if not chunk:
|
||||
break
|
||||
remaining -= len(chunk)
|
||||
await send({
|
||||
"type": "http.response.body",
|
||||
"body": chunk,
|
||||
"more_body": True,
|
||||
})
|
||||
await send({"type": "http.response.body", "body": b"", "more_body": False})
|
||||
|
||||
|
||||
def _serve_file_response(full_path: Path, file_path: str, request: Request):
|
||||
"""Serve a file with range + cache support."""
|
||||
if not full_path.exists():
|
||||
@@ -1219,40 +1728,13 @@ def _serve_file_response(full_path: Path, file_path: str, request: Request):
|
||||
headers={"Cache-Control": cache_control, "ETag": etag},
|
||||
)
|
||||
|
||||
async def stream_file(start: int, end: int):
|
||||
async with aiofiles.open(full_path, "rb") as f:
|
||||
await f.seek(start)
|
||||
remaining = end - start + 1
|
||||
while remaining > 0:
|
||||
chunk = await f.read(min(64 * 1024, remaining))
|
||||
if not chunk:
|
||||
break
|
||||
remaining -= len(chunk)
|
||||
yield chunk
|
||||
|
||||
headers = {
|
||||
"Cache-Control": cache_control,
|
||||
"ETag": etag,
|
||||
"Accept-Ranges": "bytes",
|
||||
}
|
||||
|
||||
if range_header:
|
||||
start, end = _parse_range_header(range_header, file_size)
|
||||
headers["Content-Range"] = f"bytes {start}-{end}/{file_size}"
|
||||
headers["Content-Length"] = str(end - start + 1)
|
||||
return StreamingResponse(
|
||||
stream_file(start, end),
|
||||
status_code=206,
|
||||
media_type=content_type,
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
headers["Content-Length"] = str(file_size)
|
||||
|
||||
return StreamingResponse(
|
||||
stream_file(0, file_size - 1),
|
||||
return StreamingFileResponse(
|
||||
full_path,
|
||||
file_size=file_size,
|
||||
etag=etag,
|
||||
cache_control=cache_control,
|
||||
media_type=content_type,
|
||||
headers=headers,
|
||||
range_header=range_header,
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,82 @@
|
||||
"""Optional Velopack auto-update integration (GUI builds only).
|
||||
|
||||
In development and portable-ZIP runs Velopack is either not installed or the
|
||||
app is not a Velopack installation; every helper degrades to a no-op then, so
|
||||
callers never need to special-case those environments.
|
||||
"""
|
||||
|
||||
import logging
|
||||
|
||||
from mediahive.config import load_config
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
VELOPACK_REPO_URL = "https://git.zi.fi/LeoVasanko/mediahive"
|
||||
|
||||
|
||||
def _manager():
|
||||
"""Return a Velopack UpdateManager, or None when updates are unavailable."""
|
||||
try:
|
||||
import velopack
|
||||
except ImportError:
|
||||
return None
|
||||
try:
|
||||
return velopack.UpdateManager(velopack.GiteaSource(VELOPACK_REPO_URL))
|
||||
except RuntimeError, OSError:
|
||||
# Not a Velopack installation (dev / portable run).
|
||||
return None
|
||||
|
||||
|
||||
def pending_update() -> str | None:
|
||||
"""Version of a downloaded update staged for the next launch, if any."""
|
||||
mgr = _manager()
|
||||
if mgr is None:
|
||||
return None
|
||||
try:
|
||||
asset = mgr.get_update_pending_restart()
|
||||
except RuntimeError, OSError:
|
||||
return None
|
||||
return str(asset.Version) if asset is not None else None
|
||||
|
||||
|
||||
def apply_pending_and_restart() -> bool:
|
||||
"""Apply the staged update and restart into it. False when nothing pending."""
|
||||
mgr = _manager()
|
||||
if mgr is None:
|
||||
return False
|
||||
try:
|
||||
asset = mgr.get_update_pending_restart()
|
||||
if asset is None:
|
||||
return False
|
||||
logger.info("Velopack: applying staged update %s and restarting", asset.Version)
|
||||
mgr.apply_updates_and_restart(asset)
|
||||
except (RuntimeError, OSError) as exc:
|
||||
logger.warning("Velopack: failed to apply staged update: %s", exc)
|
||||
return False
|
||||
return True
|
||||
|
||||
|
||||
def check_and_download() -> None:
|
||||
"""Download available updates in the background, unless disabled in config.
|
||||
|
||||
Downloaded updates are applied automatically by Velopack on the next app
|
||||
start, so the running session is never interrupted. Network failures and
|
||||
non-Velopack runs are expected and skipped quietly.
|
||||
"""
|
||||
if not load_config().auto_update:
|
||||
logger.info("Velopack: automatic updates disabled, skipping check")
|
||||
return
|
||||
mgr = _manager()
|
||||
if mgr is None:
|
||||
return
|
||||
try:
|
||||
info = mgr.check_for_updates()
|
||||
if info is None:
|
||||
logger.info("Velopack: no update available")
|
||||
return
|
||||
version = info.TargetFullRelease.Version
|
||||
logger.info("Velopack: downloading update %s", version)
|
||||
mgr.download_updates(info)
|
||||
logger.info("Velopack: update %s staged, applies on next launch", version)
|
||||
except (RuntimeError, OSError) as exc:
|
||||
logger.info("Velopack update check skipped: %s", exc)
|
||||
+382
-68
@@ -9,6 +9,7 @@ import asyncio
|
||||
import contextlib
|
||||
import ctypes
|
||||
import html
|
||||
import importlib.metadata
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
@@ -23,11 +24,21 @@ import urllib.request
|
||||
from concurrent.futures import Future, ThreadPoolExecutor
|
||||
from pathlib import Path
|
||||
|
||||
# Must be set before fastapi_vue env bindings are created (mediahive.config);
|
||||
# this module is the PyInstaller entry point and may run without __main__.
|
||||
os.environ.setdefault("FASTAPI_VUE", "MEDIAHIVE")
|
||||
|
||||
import msgspec.structs
|
||||
import uvicorn
|
||||
import velopack
|
||||
import webview
|
||||
from fastapi_vue import env
|
||||
from fastapi_vue.logging import patch_log_config
|
||||
from fastapi_vue.startupbox import print_box
|
||||
from tracerite.html import html_traceback
|
||||
|
||||
from mediahive.config import load_config, save_config
|
||||
from mediahive import updater
|
||||
from mediahive.config import config, load_config, log_dir, save_config
|
||||
from mediahive.volume_control import get_volume, set_volume, volume_max
|
||||
|
||||
logger = logging.getLogger("mediahive.winmain")
|
||||
@@ -53,6 +64,9 @@ MPC_BE_STATE_RUNNING = 2
|
||||
MPC_BE_SEEK_BEGIN_COMMAND = 1085
|
||||
MPC_BE_RESUME_APPLY_THRESHOLD_MS = 15000
|
||||
MPC_BE_RESUME_CLEAR_MARGIN_MS = 15000
|
||||
# Watching (or presumably watching) less than this leaves no position data:
|
||||
# brief peeks and seeks back to re-view a scene are not true progress.
|
||||
MPC_BE_RESUME_MIN_WATCH_MS = 5 * 60 * 1000
|
||||
MPC_BE_PLAYBACK_STATE_FLUSH_SECONDS = 1.0
|
||||
VOLUME_MIN = 0.0
|
||||
VOLUME_MAX = 1.5
|
||||
@@ -139,7 +153,20 @@ def _expand_playable_file(file_key: str, playable_file: str | None) -> str:
|
||||
return f"{file_key}/{playable_file}"
|
||||
|
||||
|
||||
def _fetch_resume_positions(backend_url: str) -> dict[str, int]:
|
||||
def _fetch_resume_positions(
|
||||
backend_url: str,
|
||||
) -> tuple[
|
||||
dict[str, tuple[int, int | None, int | None]],
|
||||
dict[tuple[str, int, int], int],
|
||||
]:
|
||||
"""Fetch resume state from the backend.
|
||||
|
||||
Returns (continue_points, episode_positions): continue_points map a slug
|
||||
to (pos_ms, season_number, episode_number) — season/episode set for the
|
||||
series' single continue point, None for movies. episode_positions map
|
||||
(slug, season, episode) to pos_ms for partially watched episodes;
|
||||
fully watched episodes are absent.
|
||||
"""
|
||||
req = urllib.request.Request(
|
||||
url=f"{backend_url}/api/meta/playback-state",
|
||||
method="GET",
|
||||
@@ -148,21 +175,45 @@ def _fetch_resume_positions(backend_url: str) -> dict[str, int]:
|
||||
with urllib.request.urlopen(req, timeout=2) as resp:
|
||||
raw = json.loads(resp.read().decode("utf-8"))
|
||||
except OSError, TimeoutError, urllib.error.URLError, json.JSONDecodeError:
|
||||
return {}
|
||||
return {}, {}
|
||||
|
||||
data = raw.get("data") if isinstance(raw, dict) else None
|
||||
positions = data.get("resume_positions") if isinstance(data, dict) else None
|
||||
if not isinstance(positions, dict):
|
||||
return {}
|
||||
return {}, {}
|
||||
|
||||
cleaned: dict[str, int] = {}
|
||||
cleaned: dict[str, tuple[int, int | None, int | None]] = {}
|
||||
episode_positions: dict[tuple[str, int, int], int] = {}
|
||||
for slug, value in positions.items():
|
||||
if not isinstance(slug, str) or not isinstance(value, dict):
|
||||
continue
|
||||
pos = value.get("pos")
|
||||
season = value.get("season")
|
||||
episode = value.get("episode")
|
||||
if isinstance(pos, int) and pos > 0:
|
||||
cleaned[slug] = pos * 1000
|
||||
return cleaned
|
||||
cleaned[slug] = (
|
||||
pos * 1000,
|
||||
season if isinstance(season, int) else None,
|
||||
episode if isinstance(episode, int) else None,
|
||||
)
|
||||
elif pos == 0 and isinstance(season, int) and isinstance(episode, int):
|
||||
# Series episode boundary marker (previous episode completed).
|
||||
cleaned[slug] = (0, season, episode)
|
||||
|
||||
episodes = value.get("episodes")
|
||||
if not isinstance(episodes, dict):
|
||||
continue
|
||||
for key, watch in episodes.items():
|
||||
match = re.fullmatch(r"S(\d+)E(\d+)", str(key))
|
||||
if not match or not isinstance(watch, dict):
|
||||
continue
|
||||
ep_pos = watch.get("pos")
|
||||
if watch.get("done") or not isinstance(ep_pos, int) or ep_pos <= 0:
|
||||
continue
|
||||
episode_positions[slug, int(match.group(1)), int(match.group(2))] = (
|
||||
ep_pos * 1000
|
||||
)
|
||||
return cleaned, episode_positions
|
||||
|
||||
|
||||
def _post_resume_position(
|
||||
@@ -190,51 +241,105 @@ def _post_resume_position(
|
||||
return False
|
||||
|
||||
|
||||
def _load_movie_slug_map(index_path: Path) -> dict[str, str]:
|
||||
def _media_file_key(
|
||||
mapping: dict[str, str], file_key: str, torrent: object, media_key: str
|
||||
) -> None:
|
||||
"""Map both the raw file key and its expanded playable path to a media key."""
|
||||
mapping[_normalize_media_path(file_key)] = media_key
|
||||
playable_file = torrent.get("playable_file") if isinstance(torrent, dict) else None
|
||||
expanded = _expand_playable_file(
|
||||
file_key, playable_file if isinstance(playable_file, str) else None
|
||||
)
|
||||
mapping[_normalize_media_path(expanded)] = media_key
|
||||
|
||||
|
||||
def _split_media_key(media_key: str) -> tuple[str, int | None, int | None]:
|
||||
"""Split a media key into (slug, season_number, episode_number)."""
|
||||
slug, separator, ep_ref = media_key.partition("#")
|
||||
if not separator:
|
||||
return slug, None, None
|
||||
match = re.fullmatch(r"S(\d+)E(\d+)", ep_ref)
|
||||
if not match:
|
||||
return slug, None, None
|
||||
return slug, int(match.group(1)), int(match.group(2))
|
||||
|
||||
|
||||
def _load_media_key_map(index_path: Path) -> dict[str, str]:
|
||||
"""Map normalized playable file paths to media keys.
|
||||
|
||||
Movies map to their movie id; series episodes map to
|
||||
"<series_id>#S<season>E<episode>" so episode switches are detected while
|
||||
the backend keeps a single continue point per series.
|
||||
"""
|
||||
try:
|
||||
raw = json.loads(index_path.read_text(encoding="utf-8"))
|
||||
except OSError, TypeError, json.JSONDecodeError:
|
||||
return {}
|
||||
|
||||
movies = raw.get("movies") if isinstance(raw, dict) else None
|
||||
if not isinstance(movies, dict):
|
||||
if not isinstance(raw, dict):
|
||||
return {}
|
||||
|
||||
mapping: dict[str, str] = {}
|
||||
for movie_id, movie in movies.items():
|
||||
if not isinstance(movie_id, str) or not isinstance(movie, dict):
|
||||
continue
|
||||
files = movie.get("files")
|
||||
if not isinstance(files, dict):
|
||||
continue
|
||||
for file_key, torrent in files.items():
|
||||
if not isinstance(file_key, str):
|
||||
|
||||
movies = raw.get("movies")
|
||||
if isinstance(movies, dict):
|
||||
for movie_id, movie in movies.items():
|
||||
if not isinstance(movie_id, str) or not isinstance(movie, dict):
|
||||
continue
|
||||
normalized_key = _normalize_media_path(file_key)
|
||||
mapping[normalized_key] = movie_id
|
||||
playable_file = (
|
||||
torrent.get("playable_file") if isinstance(torrent, dict) else None
|
||||
)
|
||||
expanded = _expand_playable_file(
|
||||
file_key, playable_file if isinstance(playable_file, str) else None
|
||||
)
|
||||
mapping[_normalize_media_path(expanded)] = movie_id
|
||||
files = movie.get("files")
|
||||
if not isinstance(files, dict):
|
||||
continue
|
||||
for file_key, torrent in files.items():
|
||||
if not isinstance(file_key, str):
|
||||
continue
|
||||
_media_file_key(mapping, file_key, torrent, movie_id)
|
||||
|
||||
series = raw.get("series")
|
||||
if isinstance(series, dict):
|
||||
for series_id, show in series.items():
|
||||
if not isinstance(series_id, str) or not isinstance(show, dict):
|
||||
continue
|
||||
seasons = show.get("seasons")
|
||||
if not isinstance(seasons, list):
|
||||
continue
|
||||
for season in seasons:
|
||||
if not isinstance(season, dict):
|
||||
continue
|
||||
season_number = season.get("season_number")
|
||||
episodes = season.get("episodes")
|
||||
if not isinstance(season_number, int) or not isinstance(episodes, list):
|
||||
continue
|
||||
for episode in episodes:
|
||||
if not isinstance(episode, dict):
|
||||
continue
|
||||
episode_number = episode.get("episode_number")
|
||||
files = episode.get("files")
|
||||
if not isinstance(episode_number, int) or not isinstance(
|
||||
files, dict
|
||||
):
|
||||
continue
|
||||
media_key = f"{series_id}#S{season_number}E{episode_number}"
|
||||
for file_key, torrent in files.items():
|
||||
if not isinstance(file_key, str):
|
||||
continue
|
||||
_media_file_key(mapping, file_key, torrent, media_key)
|
||||
|
||||
return mapping
|
||||
|
||||
|
||||
def _media_key_for_filepath(
|
||||
filepath: str, roots: dict[str, Path]
|
||||
) -> tuple[str | None, str, str] | None:
|
||||
"""Resolve a filepath to a (movie_slug, root_id, relative_key) tuple."""
|
||||
"""Resolve a filepath to a (media_key, root_id, relative_key) tuple."""
|
||||
for root_id, root in roots.items():
|
||||
try:
|
||||
relative = Path(filepath).resolve().relative_to(root.resolve())
|
||||
relative_key = relative.as_posix()
|
||||
index_path = root / ".mediahive" / "index.json"
|
||||
movie_slug = _load_movie_slug_map(index_path).get(
|
||||
media_key = _load_media_key_map(index_path).get(
|
||||
_normalize_media_path(relative_key)
|
||||
)
|
||||
return movie_slug, root_id, relative_key
|
||||
return media_key, root_id, relative_key
|
||||
except OSError, RuntimeError, ValueError:
|
||||
continue
|
||||
return None
|
||||
@@ -347,7 +452,7 @@ def _start_gamepad_remote(
|
||||
status_miss_count = 0
|
||||
|
||||
playback_state = _default_playback_state()
|
||||
resume_positions = _fetch_resume_positions(backend_url)
|
||||
resume_positions, episode_positions = _fetch_resume_positions(backend_url)
|
||||
tracked_media_key: str | None = None
|
||||
tracked_root_id: str | None = None
|
||||
tracked_relative_path = ""
|
||||
@@ -399,18 +504,34 @@ def _start_gamepad_remote(
|
||||
|
||||
position_ms = player_position_ms or 0
|
||||
duration_ms = player_duration_ms or 0
|
||||
tracked_slug, tracked_season, tracked_episode = _split_media_key(
|
||||
tracked_media_key
|
||||
)
|
||||
if _should_clear_resume(position_ms, duration_ms):
|
||||
resume_positions.pop(tracked_media_key, None)
|
||||
resume_positions.pop(tracked_slug, None)
|
||||
if tracked_season is not None and tracked_episode is not None:
|
||||
episode_positions.pop(
|
||||
(tracked_slug, tracked_season, tracked_episode), None
|
||||
)
|
||||
if tracked_root_id and tracked_relative_path:
|
||||
_post_resume_position(
|
||||
backend_url, tracked_root_id, tracked_relative_path, None
|
||||
)
|
||||
elif position_ms <= MPC_BE_RESUME_CLEAR_MARGIN_MS:
|
||||
# Ignore brief starts; keep the previous saved resume position.
|
||||
elif position_ms < MPC_BE_RESUME_MIN_WATCH_MS:
|
||||
# Peeks and brief seeks are not true progress; keep the previous
|
||||
# saved resume position.
|
||||
pass
|
||||
else:
|
||||
position_seconds = max(0, position_ms // 1000)
|
||||
resume_positions[tracked_media_key] = position_ms
|
||||
resume_positions[tracked_slug] = (
|
||||
position_ms,
|
||||
tracked_season,
|
||||
tracked_episode,
|
||||
)
|
||||
if tracked_season is not None and tracked_episode is not None:
|
||||
episode_positions[tracked_slug, tracked_season, tracked_episode] = (
|
||||
position_ms
|
||||
)
|
||||
if tracked_root_id and tracked_relative_path:
|
||||
_post_resume_position(
|
||||
backend_url,
|
||||
@@ -453,8 +574,36 @@ def _start_gamepad_remote(
|
||||
if resume_applied_for_key == tracked_media_key:
|
||||
return
|
||||
|
||||
saved_position = resume_positions.get(tracked_media_key)
|
||||
if not isinstance(saved_position, int):
|
||||
tracked_slug, tracked_season, tracked_episode = _split_media_key(
|
||||
tracked_media_key
|
||||
)
|
||||
if tracked_season is not None and tracked_episode is not None:
|
||||
# Series: the episode's own saved position wins; fall back to the
|
||||
# series continue point when it points at this very episode.
|
||||
saved_position = episode_positions.get((
|
||||
tracked_slug,
|
||||
tracked_season,
|
||||
tracked_episode,
|
||||
))
|
||||
if saved_position is None:
|
||||
saved = resume_positions.get(tracked_slug)
|
||||
if saved is None or (saved[1], saved[2]) != (
|
||||
tracked_season,
|
||||
tracked_episode,
|
||||
):
|
||||
# The series continue point belongs to a different episode.
|
||||
resume_applied_for_key = tracked_media_key
|
||||
return
|
||||
saved_position = saved[0]
|
||||
else:
|
||||
saved = resume_positions.get(tracked_slug)
|
||||
if saved is None:
|
||||
resume_applied_for_key = tracked_media_key
|
||||
return
|
||||
saved_position = saved[0]
|
||||
|
||||
if saved_position <= 0:
|
||||
# Episode boundary marker (previous episode completed): start at 0.
|
||||
resume_applied_for_key = tracked_media_key
|
||||
return
|
||||
if player_position_ms is None or player_duration_ms is None:
|
||||
@@ -463,7 +612,11 @@ def _start_gamepad_remote(
|
||||
resume_applied_for_key = tracked_media_key
|
||||
return
|
||||
if _should_clear_resume(saved_position, player_duration_ms):
|
||||
resume_positions.pop(tracked_media_key, None)
|
||||
resume_positions.pop(tracked_slug, None)
|
||||
if tracked_season is not None and tracked_episode is not None:
|
||||
episode_positions.pop(
|
||||
(tracked_slug, tracked_season, tracked_episode), None
|
||||
)
|
||||
resume_applied_for_key = tracked_media_key
|
||||
return
|
||||
if len(pending_requests) >= MPC_BE_MAX_INFLIGHT_REQUESTS:
|
||||
@@ -687,33 +840,82 @@ def _start_gamepad_remote(
|
||||
return thread
|
||||
|
||||
|
||||
def _rotate_and_open_log(log_path: Path):
|
||||
"""Rotate mediahive.log to .log.1 and open a fresh log file.
|
||||
|
||||
Raises OSError when a previous MediaHive instance still holds the file
|
||||
open (Windows forbids renaming a file that is open without delete
|
||||
sharing) — callers treat that as "previous instance not dead yet".
|
||||
"""
|
||||
prev = log_path.with_suffix(".log.1")
|
||||
if log_path.exists():
|
||||
if prev.exists():
|
||||
prev.unlink()
|
||||
log_path.rename(prev)
|
||||
fd = os.open(log_path, os.O_WRONLY | os.O_CREAT | os.O_TRUNC)
|
||||
return os.fdopen(fd, "w", encoding="utf-8", buffering=1) # line-buffered
|
||||
|
||||
|
||||
def _wait_for_previous_instance(log_path: Path, timeout: float = 15.0):
|
||||
"""Show a waiting notice while a previous MediaHive instance exits.
|
||||
|
||||
Returns an open log file handle, or None on timeout.
|
||||
"""
|
||||
result: list = []
|
||||
window = webview.create_window(
|
||||
"MediaHive", html=_WAIT_HTML, width=520, height=280, resizable=False
|
||||
)
|
||||
|
||||
def poll() -> None:
|
||||
deadline = time.monotonic() + timeout
|
||||
while time.monotonic() < deadline:
|
||||
try:
|
||||
result.append(_rotate_and_open_log(log_path))
|
||||
break
|
||||
except OSError:
|
||||
time.sleep(0.5)
|
||||
window.destroy()
|
||||
|
||||
webview.start(func=poll, icon=_icon_path(), **_webview_start_kwargs())
|
||||
return result[0] if result else None
|
||||
|
||||
|
||||
def _setup_logging() -> Path:
|
||||
"""Redirect stdout/stderr and configure logging to a file in %APPDATA%/mediahive/.
|
||||
"""Redirect stdout/stderr and configure logging to a file in the platform log dir.
|
||||
|
||||
In a PyInstaller --windowed build there is no console, so any print() or
|
||||
unhandled exception traceback would be lost. This ensures everything ends
|
||||
up in a persistent log file the user can send for bug reports.
|
||||
Returns the path to the log file.
|
||||
"""
|
||||
from mediahive.config import config_dir
|
||||
log_directory = log_dir()
|
||||
log_directory.mkdir(parents=True, exist_ok=True)
|
||||
log_path = log_directory / "mediahive.log"
|
||||
|
||||
log_dir = config_dir()
|
||||
log_dir.mkdir(parents=True, exist_ok=True)
|
||||
log_path = log_dir / "mediahive.log"
|
||||
try:
|
||||
log_file = _rotate_and_open_log(log_path)
|
||||
except OSError:
|
||||
# A previous instance still holds the log file. It is usually on its
|
||||
# way out — give it a couple of seconds silently first.
|
||||
log_file = None
|
||||
deadline = time.monotonic() + 2.0
|
||||
while log_file is None and time.monotonic() < deadline:
|
||||
time.sleep(0.25)
|
||||
with contextlib.suppress(OSError):
|
||||
log_file = _rotate_and_open_log(log_path)
|
||||
if log_file is None:
|
||||
log_file = _wait_for_previous_instance(log_path)
|
||||
if log_file is None:
|
||||
# Never fail startup over logging: fall back to a per-process file.
|
||||
log_path = log_directory / f"mediahive-{os.getpid()}.log"
|
||||
with contextlib.suppress(OSError):
|
||||
fd = os.open(log_path, os.O_WRONLY | os.O_CREAT | os.O_TRUNC)
|
||||
log_file = os.fdopen(fd, "w", encoding="utf-8", buffering=1)
|
||||
|
||||
# Rotate: keep previous run as .log.1
|
||||
prev = log_path.with_suffix(".log.1")
|
||||
if log_path.exists():
|
||||
if prev.exists():
|
||||
prev.unlink()
|
||||
log_path.rename(prev)
|
||||
|
||||
fd = os.open(log_path, os.O_WRONLY | os.O_CREAT | os.O_TRUNC)
|
||||
log_file = os.fdopen(fd, "w", encoding="utf-8", buffering=1) # line-buffered
|
||||
|
||||
# Redirect raw stdout/stderr so print() and tracebacks go to the file
|
||||
sys.stdout = log_file
|
||||
sys.stderr = log_file
|
||||
if log_file is not None:
|
||||
# Redirect raw stdout/stderr so print() and tracebacks go to the file
|
||||
sys.stdout = log_file
|
||||
sys.stderr = log_file
|
||||
|
||||
# force=True removes handlers added by uvicorn/fastapi during import so that
|
||||
# basicConfig actually takes effect (without it, it's a silent no-op)
|
||||
@@ -742,6 +944,70 @@ _SETUP_HTML = """<!DOCTYPE html>
|
||||
<div><h1>MediaHive</h1><p>Choose a folder that contains your media…</p></div>
|
||||
</body></html>"""
|
||||
|
||||
# Shown when a previous instance is still shutting down.
|
||||
_WAIT_HTML = """<!DOCTYPE html>
|
||||
<html><head><meta charset="utf-8"><style>
|
||||
* { box-sizing: border-box; margin: 0; padding: 0; }
|
||||
body { background: #141414; color: #fff;
|
||||
font-family: 'Segoe UI', system-ui, sans-serif;
|
||||
display: flex; align-items: center; justify-content: center;
|
||||
height: 100vh; text-align: center; }
|
||||
h1 { font-size: 2rem; color: #e50914; margin-bottom: .5rem; }
|
||||
p { color: #aaa; }
|
||||
</style></head><body>
|
||||
<div><h1>MediaHive</h1>
|
||||
<p>Waiting for the previous MediaHive instance to finish exiting…</p></div>
|
||||
</body></html>"""
|
||||
|
||||
|
||||
def _show_fatal_error(exc: BaseException) -> None:
|
||||
"""Show an unhandled exception as a TraceRite HTML page in a webview.
|
||||
|
||||
Frozen --windowed builds otherwise surface crashes only as PyInstaller's
|
||||
plain-text error dialog (or nothing at all).
|
||||
"""
|
||||
fragment = str(html_traceback(exc))
|
||||
page = (
|
||||
"<!DOCTYPE html><html><head><meta charset='utf-8'>"
|
||||
"<title>MediaHive — Error</title></head>"
|
||||
f"<body style='margin:1.5rem'>{fragment}</body></html>"
|
||||
)
|
||||
webview.create_window("MediaHive — Error", html=page, width=1100, height=750)
|
||||
webview.start(icon=_icon_path(), **_webview_start_kwargs())
|
||||
|
||||
|
||||
def _velopack_startup() -> None:
|
||||
"""Handle Velopack install/update/uninstall hooks and pending updates.
|
||||
|
||||
Must be the first thing at startup: when Velopack launches the app with
|
||||
--veloapp-* hook arguments (during install/update/uninstall), run()
|
||||
executes the hook and exits the process, so the GUI never starts.
|
||||
Applies downloaded-but-pending updates. No-op in development and
|
||||
portable-ZIP runs.
|
||||
"""
|
||||
velopack.App().run()
|
||||
|
||||
|
||||
def _check_for_updates() -> None:
|
||||
"""Download available updates in the background (unless disabled in config).
|
||||
|
||||
Downloaded updates are applied automatically by Velopack on the next app
|
||||
start (via _velopack_startup), so the running session is never
|
||||
interrupted. Not a Velopack install (dev/portable) and network failures
|
||||
are expected and skipped quietly.
|
||||
"""
|
||||
updater.check_and_download()
|
||||
|
||||
|
||||
def gui_main() -> None:
|
||||
"""Run the GUI, rendering fatal exceptions as a TraceRite HTML window."""
|
||||
_velopack_startup()
|
||||
try:
|
||||
winmain()
|
||||
except Exception as exc:
|
||||
logger.exception("Fatal error")
|
||||
_show_fatal_error(exc)
|
||||
|
||||
|
||||
class JsApi:
|
||||
"""Python methods exposed to the frontend via window.pywebview.api."""
|
||||
@@ -756,6 +1022,16 @@ class JsApi:
|
||||
result = self._window.create_file_dialog(webview.FOLDER_DIALOG)
|
||||
return result[0] if result else None
|
||||
|
||||
def exit_app(self) -> None:
|
||||
"""Close the window, shutting the app down (like the OS close button)."""
|
||||
if self._window:
|
||||
self._window.destroy()
|
||||
|
||||
def toggle_fullscreen(self) -> None:
|
||||
"""Switch between fullscreen and windowed mode in place."""
|
||||
if self._window:
|
||||
self._window.toggle_fullscreen()
|
||||
|
||||
def set_volume(self, x: float) -> None:
|
||||
"""Set system master volume from slider position ``x`` (0.0 .. 1.5)."""
|
||||
# Clamp to the platform's maximum so the slider never exceeds what
|
||||
@@ -884,8 +1160,26 @@ def _configure_windows_event_loop_policy() -> None:
|
||||
asyncio.set_event_loop_policy(policy_cls())
|
||||
|
||||
|
||||
def _strip_mark_of_the_web() -> None:
|
||||
"""Remove Zone.Identifier streams from bundled DLLs (frozen Windows only).
|
||||
|
||||
Files extracted from a downloaded ZIP carry the Mark-of-the-Web, and the
|
||||
.NET Framework CLR refuses to load such assemblies — pythonnet then fails
|
||||
with "Failed to resolve Python.Runtime.Loader.Initialize from
|
||||
.../Python.Runtime.dll". Strip the mark from the bundled DLLs before
|
||||
pywebview loads the CLR.
|
||||
"""
|
||||
if not getattr(sys, "frozen", False) or sys.platform != "win32":
|
||||
return
|
||||
meipass = Path(sys._MEIPASS) # type: ignore[attr-defined]
|
||||
for dll in meipass.rglob("*.dll"):
|
||||
with contextlib.suppress(OSError):
|
||||
Path(f"{dll}:Zone.Identifier").unlink()
|
||||
|
||||
|
||||
def winmain() -> None:
|
||||
_configure_windows_event_loop_policy()
|
||||
_strip_mark_of_the_web()
|
||||
|
||||
parser = argparse.ArgumentParser(description="MediaHive")
|
||||
parser.add_argument(
|
||||
@@ -893,7 +1187,7 @@ def winmain() -> None:
|
||||
nargs="?",
|
||||
help="Path to the media folder (default: saved config or initial setup dialog)",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
args, _unknown = parser.parse_known_args()
|
||||
|
||||
_prepend_meipass_to_path()
|
||||
|
||||
@@ -912,10 +1206,6 @@ def winmain() -> None:
|
||||
initial_roots[name] = p.as_posix()
|
||||
elif cfg.roots:
|
||||
initial_roots = cfg.roots
|
||||
elif cfg.media_folder:
|
||||
p = _normalize_media_root_input(cfg.media_folder)
|
||||
name = p.name or "media"
|
||||
initial_roots[name] = p.as_posix()
|
||||
|
||||
if not initial_roots:
|
||||
folder = _run_initial_setup()
|
||||
@@ -929,23 +1219,43 @@ def winmain() -> None:
|
||||
if cfg.roots != initial_roots:
|
||||
save_config(msgspec.structs.replace(cfg, roots=initial_roots))
|
||||
|
||||
# Pass roots to the server via env (validation deferred to server startup)
|
||||
os.environ["MEDIAHIVE_ROOTS"] = json.dumps(initial_roots)
|
||||
# Pass roots to the in-process server via the shared env config
|
||||
# (validation deferred to server startup)
|
||||
config.roots = initial_roots
|
||||
|
||||
backend_port = _reserve_backend_port()
|
||||
backend_url = f"http://{BACKEND_HOST}:{backend_port}"
|
||||
os.environ["MEDIAHIVE_BACKEND_URL"] = backend_url
|
||||
|
||||
# Run the FastAPI backend on a background thread
|
||||
config = uvicorn.Config(
|
||||
# Startup banner, same as fastapi-vue's server.run() prints in CLI mode.
|
||||
# Goes to stderr, which frozen builds redirect to the log file.
|
||||
try:
|
||||
version = importlib.metadata.version("mediahive")
|
||||
except importlib.metadata.PackageNotFoundError:
|
||||
version = "dev"
|
||||
print_box(f"MediaHive {version}\n{backend_url}")
|
||||
|
||||
# Run the FastAPI backend on a background thread. fastapi-vue's patched
|
||||
# log config wires up its access-log middleware, emoji level prefixes and
|
||||
# tracerite tracebacks (colors are auto-disabled when stderr is not a tty,
|
||||
# e.g. redirected to the log file in frozen builds).
|
||||
log_config = patch_log_config(uvicorn.config.LOGGING_CONFIG)
|
||||
# fastapi-vue routes the root logger at INFO in dev / WARNING in prod;
|
||||
# keep our own loggers visible in production too.
|
||||
log_config.setdefault("loggers", {})["mediahive"] = {
|
||||
"level": "DEBUG" if env.dev else "INFO"
|
||||
}
|
||||
uvicorn_config = uvicorn.Config(
|
||||
"mediahive.server:app",
|
||||
host=BACKEND_HOST,
|
||||
port=backend_port,
|
||||
loop="asyncio",
|
||||
log_level="warning",
|
||||
server_header=False,
|
||||
timeout_graceful_shutdown=0,
|
||||
access_log=False, # fastapi-vue's middleware replaces uvicorn's
|
||||
log_config=log_config,
|
||||
)
|
||||
server = uvicorn.Server(config)
|
||||
server = uvicorn.Server(uvicorn_config)
|
||||
backend_thread = threading.Thread(
|
||||
target=server.run, daemon=True, name="mediahive-backend"
|
||||
)
|
||||
@@ -969,6 +1279,10 @@ def winmain() -> None:
|
||||
server.should_exit = True
|
||||
raise RuntimeError(f"Backend did not become ready within {HEALTH_TIMEOUT}s")
|
||||
|
||||
threading.Thread(
|
||||
target=_check_for_updates, daemon=True, name="mediahive-update-check"
|
||||
).start()
|
||||
|
||||
api = JsApi()
|
||||
logger.info("Configured pywebview backend: %s", _selected_webview_backend())
|
||||
window = webview.create_window(
|
||||
@@ -1038,4 +1352,4 @@ def winmain() -> None:
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
winmain()
|
||||
gui_main()
|
||||
|
||||
+53
-47
@@ -8,11 +8,12 @@ dependencies = [
|
||||
"aiofiles>=25.1.0",
|
||||
"aiopathlib>=0.6.0",
|
||||
"bencodepy>=0.9.5",
|
||||
"fastapi-vue>=0.5.2",
|
||||
"fastapi-vue~=1.7.2",
|
||||
"fastapi[standard]>=0.128.0",
|
||||
"httpx[http2]>=0.28.1",
|
||||
"msgspec>=0.19",
|
||||
"parse-torrent-title>=2.8.1",
|
||||
"platformdirs>=4.0",
|
||||
"tomli-w>=1.2.0",
|
||||
"uvicorn[standard]>=0.40.0",
|
||||
]
|
||||
@@ -36,7 +37,11 @@ artifacts = ["mediahive/frontend-build"]
|
||||
only-packages = true
|
||||
|
||||
[tool.hatch.build.targets.sdist.hooks.custom]
|
||||
path = "scripts/fastapi-vue/build-frontend.py"
|
||||
path = "scripts/fastapi-vue/buildhook.py"
|
||||
|
||||
[tool.hatch.build.targets.sdist.force-include]
|
||||
"scripts/fastapi-vue/buildhook.py" = "scripts/fastapi-vue/buildhook.py"
|
||||
"scripts/fastapi-vue/buildutil.py" = "scripts/fastapi-vue/buildutil.py"
|
||||
|
||||
[tool.uv]
|
||||
package = true
|
||||
@@ -46,17 +51,21 @@ parse-torrent-title = { git = "https://github.com/platelminto/parse-torrent-titl
|
||||
|
||||
[project.optional-dependencies]
|
||||
gui = [
|
||||
"pywebview>=6.2.1; platform_system != 'Darwin'",
|
||||
"pywebview[qt5]>=6.2.1; platform_system == 'Darwin'",
|
||||
"qtpy>=2.4.1; platform_system == 'Darwin'",
|
||||
"PyQt5>=5.15.11; platform_system == 'Darwin'",
|
||||
# pywebview's qt extra is Qt6-only (QtPy + PyQt6 + PyQt6-WebEngine);
|
||||
# Qt5 would come from its separate qt5 extra, which we do not use.
|
||||
"pywebview[qt]>=6.2.1; platform_system != 'Windows'",
|
||||
"pywebview>=6.2.1; platform_system == 'Windows'",
|
||||
"velopack>=1.2",
|
||||
"pythonnet>=3.1.0rc0; platform_system == 'Windows' and python_version >= '3.14'",
|
||||
"pyinstaller>=6.0",
|
||||
# scripts/guibuild.py reads the version with it (same logic as hatch-vcs).
|
||||
"setuptools_scm>=8",
|
||||
]
|
||||
|
||||
[dependency-groups]
|
||||
dev = [
|
||||
"httpx>=0.28.1",
|
||||
"lefthook>=2.1.14",
|
||||
"ruff>=0.15.14",
|
||||
"setuptools-scm>=8",
|
||||
]
|
||||
@@ -67,55 +76,52 @@ preview = true
|
||||
[tool.ruff.lint]
|
||||
select = ["ALL"]
|
||||
ignore = [
|
||||
"D203",
|
||||
"D213",
|
||||
"DOC201",
|
||||
"COM812",
|
||||
"T201",
|
||||
"incorrect-blank-line-before-class",
|
||||
"multi-line-summary-second-line",
|
||||
"docstring-missing-returns",
|
||||
"missing-trailing-comma",
|
||||
"print",
|
||||
"EM",
|
||||
"TC",
|
||||
"TRY003",
|
||||
"raise-vanilla-args",
|
||||
"S",
|
||||
"CPY001",
|
||||
"missing-copyright-notice",
|
||||
"PLR",
|
||||
"PLW",
|
||||
# TEMP suppressions - revisit and remove after focused cleanup passes.
|
||||
"C901",
|
||||
"DOC501",
|
||||
"ANN201",
|
||||
"D103",
|
||||
"FBT001",
|
||||
"ANN001",
|
||||
"D102",
|
||||
"TRY300",
|
||||
"D107",
|
||||
"ANN202",
|
||||
"B904",
|
||||
"ASYNC220",
|
||||
"E501",
|
||||
"INP001",
|
||||
"FBT002",
|
||||
"PLC0415",
|
||||
"D101",
|
||||
"RUF006",
|
||||
"SLF001",
|
||||
"ASYNC240",
|
||||
"N801",
|
||||
"SIM102",
|
||||
"DTZ005",
|
||||
"RUF034",
|
||||
"D415",
|
||||
"D400",
|
||||
"ANN401",
|
||||
"complex-structure",
|
||||
"docstring-missing-exception",
|
||||
"missing-return-type-undocumented-public-function",
|
||||
"undocumented-public-function",
|
||||
"boolean-type-hint-positional-argument",
|
||||
"missing-type-function-argument",
|
||||
"undocumented-public-method",
|
||||
"try-consider-else",
|
||||
"undocumented-public-init",
|
||||
"missing-return-type-private-function",
|
||||
"raise-without-from-inside-except",
|
||||
"create-subprocess-in-async-function",
|
||||
"line-too-long",
|
||||
"implicit-namespace-package",
|
||||
"boolean-default-value-positional-argument",
|
||||
"import-outside-top-level",
|
||||
"undocumented-public-class",
|
||||
"asyncio-dangling-task",
|
||||
"private-member-access",
|
||||
"blocking-path-method-in-async-function",
|
||||
"invalid-class-name",
|
||||
"collapsible-if",
|
||||
"call-datetime-now-without-tzinfo",
|
||||
"useless-if-else",
|
||||
"missing-terminal-punctuation",
|
||||
"missing-trailing-period",
|
||||
"any-type",
|
||||
# Allow en-dash in docstrings (used for list formatting)
|
||||
"RUF002",
|
||||
"ambiguous-unicode-character-docstring",
|
||||
# Allow ctypes COM variable names (CLSID_*, IID_*, etc.)
|
||||
"N806",
|
||||
"non-lowercase-variable-in-function",
|
||||
# Allow inline comments that describe output formats
|
||||
"ERA001",
|
||||
"commented-out-code",
|
||||
# Allow unused local variables in ctypes COM boilerplate
|
||||
"F841",
|
||||
"unused-variable",
|
||||
]
|
||||
|
||||
[tool.ruff.lint.per-file-ignores]
|
||||
"mediahive/access_logging.py" = ["BLE001", "G004"]
|
||||
|
||||
@@ -1,162 +0,0 @@
|
||||
#!/usr/bin/env python3
|
||||
"""RTorrent Client - Communicate with rtorrent via XMLRPC over SCGI socket."""
|
||||
|
||||
import socket
|
||||
import xmlrpc.client
|
||||
from pathlib import Path
|
||||
|
||||
|
||||
class SCGITransport(xmlrpc.client.Transport):
|
||||
"""SCGI transport for communicating with rtorrent via Unix socket."""
|
||||
|
||||
def __init__(self, socket_path: str) -> None:
|
||||
super().__init__()
|
||||
self.socket_path = socket_path
|
||||
|
||||
def single_request(self, _host, _handler, request_body, _verbose=False):
|
||||
# Create SCGI request
|
||||
headers = f"CONTENT_LENGTH\x00{len(request_body)}\x00SCGI\x001\x00"
|
||||
request = f"{len(headers)}:{headers},{request_body.decode('utf-8')}"
|
||||
|
||||
# Connect to socket
|
||||
sock = socket.socket(socket.AF_UNIX, socket.SOCK_STREAM)
|
||||
sock.connect(self.socket_path)
|
||||
sock.send(request.encode("utf-8"))
|
||||
|
||||
# Read response
|
||||
response = b""
|
||||
while True:
|
||||
data = sock.recv(4096)
|
||||
if not data:
|
||||
break
|
||||
response += data
|
||||
sock.close()
|
||||
|
||||
# Parse response - skip HTTP headers
|
||||
if b"\r\n\r\n" in response:
|
||||
response = response.split(b"\r\n\r\n", 1)[1]
|
||||
|
||||
return self.parse_response(response)
|
||||
|
||||
def parse_response(self, response_body):
|
||||
p, u = xmlrpc.client.getparser()
|
||||
p.feed(response_body)
|
||||
p.close()
|
||||
return u.close()
|
||||
|
||||
|
||||
class RTorrentClient:
|
||||
"""Client for communicating with rtorrent via XMLRPC over SCGI socket."""
|
||||
|
||||
def __init__(
|
||||
self, socket_path: str = "/home/user/rtorrent/.session/rpc.socket"
|
||||
) -> None:
|
||||
self.socket_path = socket_path
|
||||
transport = SCGITransport(socket_path)
|
||||
self.proxy = xmlrpc.client.ServerProxy(
|
||||
"http://localhost/RPC2", transport=transport
|
||||
)
|
||||
|
||||
def get_loaded_hashes(self) -> set[str]:
|
||||
"""Get set of info hashes for all currently loaded torrents."""
|
||||
try:
|
||||
downloads = self.proxy.download_list("")
|
||||
return {h.upper() for h in downloads}
|
||||
except (OSError, xmlrpc.client.Error) as e:
|
||||
print(f"Error getting loaded torrents: {e}")
|
||||
return set()
|
||||
|
||||
def load_torrent(self, torrent_path: Path, download_dir: Path) -> bool:
|
||||
"""Load a torrent file and set its download directory.
|
||||
|
||||
Uses load.start_verbose to load and immediately start/hash-check.
|
||||
|
||||
Args:
|
||||
torrent_path: Path to the .torrent file
|
||||
download_dir: Directory where the data already exists
|
||||
|
||||
Returns:
|
||||
True if successful, False otherwise
|
||||
|
||||
"""
|
||||
try:
|
||||
# load.start_verbose with d.directory.set to specify download location
|
||||
# This will hash-check existing files instead of re-downloading
|
||||
self.proxy.load.start_verbose(
|
||||
"", str(torrent_path), f'd.directory.set="{download_dir}"'
|
||||
)
|
||||
return True
|
||||
except (OSError, xmlrpc.client.Error) as e:
|
||||
print(f"Error loading torrent {torrent_path}: {e}")
|
||||
return False
|
||||
|
||||
def get_torrent_info(self, info_hash: str) -> dict | None:
|
||||
"""Get info about a loaded torrent."""
|
||||
try:
|
||||
name = self.proxy.d.name(info_hash)
|
||||
message = self.proxy.d.message(info_hash)
|
||||
tied_file = self.proxy.d.tied_to_file(info_hash)
|
||||
directory = self.proxy.d.directory(info_hash)
|
||||
base_path = self.proxy.d.base_path(info_hash) # Actual data path
|
||||
is_multi_file = self.proxy.d.is_multi_file(info_hash)
|
||||
return {
|
||||
"hash": info_hash,
|
||||
"name": name,
|
||||
"message": message,
|
||||
"tied_file": tied_file,
|
||||
"directory": directory,
|
||||
"base_path": base_path, # Full path to data (file or folder)
|
||||
"is_multi_file": is_multi_file,
|
||||
}
|
||||
except (OSError, xmlrpc.client.Error) as e:
|
||||
print(f"Error getting torrent info for {info_hash}: {e}")
|
||||
return None
|
||||
|
||||
def get_unregistered_torrents(self) -> list[dict]:
|
||||
"""Find all torrents with 'unregistered' or 'not registered' tracker errors.
|
||||
|
||||
Returns:
|
||||
List of torrent info dicts for torrents with registration errors
|
||||
|
||||
"""
|
||||
unregistered = []
|
||||
try:
|
||||
hashes = self.proxy.download_list("")
|
||||
for info_hash in hashes:
|
||||
try:
|
||||
message = self.proxy.d.message(info_hash)
|
||||
if message and (
|
||||
"unregistered" in message.lower()
|
||||
or "not registered" in message.lower()
|
||||
):
|
||||
info = self.get_torrent_info(info_hash)
|
||||
if info:
|
||||
unregistered.append(info)
|
||||
except OSError, xmlrpc.client.Error:
|
||||
continue
|
||||
except (OSError, xmlrpc.client.Error) as e:
|
||||
print(f"Error scanning for unregistered torrents: {e}")
|
||||
return unregistered
|
||||
|
||||
def remove_torrent(self, info_hash: str, delete_files: bool = False) -> bool:
|
||||
"""Remove a torrent from rtorrent.
|
||||
|
||||
Args:
|
||||
info_hash: The info hash of the torrent to remove
|
||||
delete_files: If True, also delete downloaded files (default: False)
|
||||
|
||||
Returns:
|
||||
True if successful, False otherwise
|
||||
|
||||
"""
|
||||
try:
|
||||
if delete_files:
|
||||
# This would delete the data - NOT what we want
|
||||
self.proxy.d.erase(info_hash)
|
||||
else:
|
||||
# Just remove from rtorrent, keep files
|
||||
self.proxy.d.erase(info_hash)
|
||||
return True
|
||||
except (OSError, xmlrpc.client.Error) as e:
|
||||
print(f"Error removing torrent {info_hash}: {e}")
|
||||
return False
|
||||
+26
-8
@@ -5,12 +5,13 @@
|
||||
# pyinstaller --noconfirm --clean scripts/MediaHive.spec
|
||||
#
|
||||
# Or use the build script (recommended—handles versioning and packaging):
|
||||
# uv run scripts/winbuild.py
|
||||
# uv run scripts/guibuild.py
|
||||
|
||||
import sys
|
||||
import mediahive.winmain
|
||||
import mediahive.server
|
||||
from pathlib import Path
|
||||
from PyInstaller.utils.hooks import collect_data_files
|
||||
|
||||
block_cipher = None
|
||||
|
||||
@@ -19,7 +20,15 @@ _frontend_build = _pkg / "frontend-build"
|
||||
_logo_webp = _pkg / "assets" / "mediahive.webp"
|
||||
_icon_win = _pkg / "assets" / "mediahive.ico"
|
||||
_icon_mac = _pkg / "assets" / "mediahive.icns"
|
||||
_tools_dir = Path(SPECPATH).parent / "build" / "ffmpeg"
|
||||
# ffmpeg staging lives in the persistent build cache (same logic as
|
||||
# scripts/guibuild.py); fall back to the legacy build/ffmpeg location.
|
||||
from platformdirs import user_cache_path
|
||||
|
||||
_tools_dir = (
|
||||
user_cache_path("mediahive-build", appauthor=False, opinion=False) / "ffmpeg"
|
||||
)
|
||||
if not _tools_dir.exists():
|
||||
_tools_dir = Path(SPECPATH).parent / "build" / "ffmpeg"
|
||||
_tool_names = ["ffmpeg.exe"] if sys.platform == "win32" else ["ffmpeg"]
|
||||
|
||||
_binaries = []
|
||||
@@ -32,6 +41,9 @@ _datas = [
|
||||
# Bundled Vue frontend served by the FastAPI backend
|
||||
(str(_frontend_build), "mediahive/frontend-build"),
|
||||
]
|
||||
# tracerite (indirect dep) loads style.css / script.js at runtime; PyInstaller
|
||||
# has no hook for it, so collect its package data explicitly
|
||||
_datas += collect_data_files("tracerite")
|
||||
if _icon_win.exists():
|
||||
_datas.append((str(_icon_win), "mediahive/assets"))
|
||||
if _icon_mac.exists():
|
||||
@@ -76,11 +88,12 @@ if sys.platform == "darwin":
|
||||
# pywebview Qt backend selected dynamically via webview.start(gui="qt")
|
||||
"webview.platforms.qt",
|
||||
"qtpy",
|
||||
"PyQt5",
|
||||
"PyQt5.QtCore",
|
||||
"PyQt5.QtGui",
|
||||
"PyQt5.QtWidgets",
|
||||
"PyQt5.QtWebEngineWidgets",
|
||||
"PyQt6",
|
||||
"PyQt6.QtCore",
|
||||
"PyQt6.QtGui",
|
||||
"PyQt6.QtWidgets",
|
||||
"PyQt6.QtWebEngineCore",
|
||||
"PyQt6.QtWebEngineWidgets",
|
||||
]
|
||||
)
|
||||
|
||||
@@ -119,6 +132,11 @@ exe = EXE(
|
||||
windowed=True,
|
||||
)
|
||||
|
||||
# UPX breaks .NET assemblies: packing Python.Runtime.dll strips/corrupts its
|
||||
# CLR metadata and pythonnet then fails with "Failed to resolve
|
||||
# Python.Runtime.Loader.Initialize from .../Python.Runtime.dll".
|
||||
_upx_exclude = ["Python.Runtime.dll"] if sys.platform == "win32" else []
|
||||
|
||||
coll = COLLECT(
|
||||
exe,
|
||||
a.binaries,
|
||||
@@ -126,7 +144,7 @@ coll = COLLECT(
|
||||
a.datas,
|
||||
strip=False,
|
||||
upx=True,
|
||||
upx_exclude=[],
|
||||
upx_exclude=_upx_exclude,
|
||||
name="MediaHive",
|
||||
)
|
||||
|
||||
|
||||
Regular → Executable
+24
-12
@@ -5,13 +5,15 @@
|
||||
import argparse
|
||||
import asyncio
|
||||
import os
|
||||
import subprocess
|
||||
import sys
|
||||
from contextlib import suppress
|
||||
from pathlib import Path
|
||||
|
||||
import tracerite
|
||||
|
||||
# Import util.py from scripts/fastapi-vue (not a package, so we adjust sys.path)
|
||||
sys.path.insert(0, str(Path(__file__).with_name("fastapi-vue")))
|
||||
from devutil import ( # type: ignore[import-not-found]
|
||||
from devutil import (
|
||||
ProcessGroup,
|
||||
check_ports_free,
|
||||
logger,
|
||||
@@ -22,11 +24,15 @@ from devutil import ( # type: ignore[import-not-found]
|
||||
|
||||
DEFAULT_VITE_PORT = 8420
|
||||
DEFAULT_DEV_PORT = 8421
|
||||
HEALTH = "/api/health?from=devserver.py"
|
||||
|
||||
|
||||
async def run_devserver(
|
||||
listen: str, backend: str, extra_args: list[str] | None = None
|
||||
listen: str,
|
||||
backend: str,
|
||||
extra_args: list[str] | None = None,
|
||||
) -> None:
|
||||
"""Start Vite and FastAPI dev servers with hot reload."""
|
||||
reporoot = Path(__file__).parent.parent
|
||||
front = reporoot / "frontend"
|
||||
if not (front / "package.json").exists():
|
||||
@@ -36,20 +42,22 @@ async def run_devserver(
|
||||
viteurl, npm_install, vite = setup_vite(listen, DEFAULT_VITE_PORT)
|
||||
backurl, mediahive = setup_cli("mediahive", backend, DEFAULT_DEV_PORT)
|
||||
|
||||
# Tell the everyone by environment (vite proxy and backend devmode use these)
|
||||
# Tell everyone via environment (vite proxy and backend devmode use these)
|
||||
os.environ["MEDIAHIVE_VITE_URL"] = viteurl
|
||||
os.environ["MEDIAHIVE_BACKEND_URL"] = backurl
|
||||
os.environ["MEDIAHIVE_DEV"] = "1"
|
||||
|
||||
async with ProcessGroup() as pg:
|
||||
pg.create_task(check_ports_free(viteurl, backurl))
|
||||
npm_i = await pg.spawn(*npm_install, cwd=front)
|
||||
await check_ports_free(viteurl, backurl)
|
||||
await pg.spawn(*mediahive, *(extra_args or []))
|
||||
await pg.wait(npm_i, ready(backurl, path="/api/health?from=devserver.py"))
|
||||
await pg.spawn(*vite, cwd=front)
|
||||
await pg.spawn(*mediahive, *(extra_args or []), vital=True)
|
||||
await pg.wait(npm_i, ready(backurl, path=HEALTH))
|
||||
await pg.spawn(*vite, cwd=front, vital=True)
|
||||
|
||||
|
||||
def main() -> None:
|
||||
"""Parse CLI arguments and run the devserver."""
|
||||
tracerite.load()
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Run Vite and FastAPI development servers",
|
||||
formatter_class=argparse.RawDescriptionHelpFormatter,
|
||||
@@ -58,21 +66,25 @@ def main() -> None:
|
||||
parser.add_argument(
|
||||
"-l",
|
||||
"--listen",
|
||||
metavar="host:port",
|
||||
metavar="addr",
|
||||
help=f"Vite (default: localhost:{DEFAULT_VITE_PORT})",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--backend",
|
||||
metavar="host:port",
|
||||
metavar="addr",
|
||||
help=f"FastAPI (default: localhost:{DEFAULT_DEV_PORT})",
|
||||
)
|
||||
args, extra_args = parser.parse_known_args()
|
||||
with suppress(KeyboardInterrupt):
|
||||
try:
|
||||
asyncio.run(run_devserver(args.listen, args.backend, extra_args))
|
||||
except* KeyboardInterrupt:
|
||||
pass # user stopped the devserver: normal exit
|
||||
except* subprocess.SubprocessError, RuntimeError:
|
||||
raise SystemExit(1) from None # logged in devutil already; exit 1
|
||||
|
||||
|
||||
HELP_EPILOG = """
|
||||
scripts/devserver.py [args to mediahive]
|
||||
Other options are forwarded to mediahive [args]
|
||||
|
||||
JS_RUNTIME environment variable can be used to select the JS runtime:
|
||||
npm, deno, bun, or full path to the runtime executable (node maps to npm).
|
||||
|
||||
@@ -1,17 +0,0 @@
|
||||
"""Hatch build hook for building Vue frontend during package build."""
|
||||
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from hatchling.builders.hooks.plugin.interface import ( # type: ignore[import-not-found]
|
||||
BuildHookInterface,
|
||||
)
|
||||
|
||||
sys.path.insert(0, str(Path(__file__).parent))
|
||||
from buildutil import build
|
||||
|
||||
|
||||
class CustomBuildHook(BuildHookInterface):
|
||||
def initialize(self, version, build_data) -> None:
|
||||
super().initialize(version, build_data)
|
||||
build("frontend")
|
||||
@@ -0,0 +1,18 @@
|
||||
"""Hatch build hook for building Vue frontend during package build."""
|
||||
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
from hatchling.builders.hooks.plugin.interface import BuildHookInterface
|
||||
|
||||
sys.path.insert(0, str(Path(__file__).parent))
|
||||
from buildutil import build
|
||||
|
||||
|
||||
class CustomBuildHook(BuildHookInterface): # type: ignore[misc]
|
||||
"""Hatch build hook that builds Vue frontend during package build."""
|
||||
|
||||
def initialize(self, version: str, build_data: dict) -> None: # type: ignore[override]
|
||||
"""Build frontend before package is built."""
|
||||
super().initialize(version, build_data)
|
||||
build("frontend")
|
||||
@@ -7,21 +7,30 @@ import shutil
|
||||
import subprocess
|
||||
from pathlib import Path
|
||||
|
||||
MIN_NODE_VERSION = 20
|
||||
|
||||
class _PrefixFormatter(logging.Formatter):
|
||||
"""Formatter that adds prefix based on log level."""
|
||||
|
||||
class _Formatter(logging.Formatter):
|
||||
"""Prefix formatter, intentionally different from fastapi_vue.logging.
|
||||
|
||||
INFO and below pass through unprefixed so messages can use their own
|
||||
markings (>>>, ###); WARNING and above get an emoji prefix.
|
||||
"""
|
||||
|
||||
def format(self, record: logging.LogRecord) -> str:
|
||||
if record.levelno >= logging.ERROR:
|
||||
return f"🛑 {record.getMessage()}"
|
||||
if record.levelno >= logging.WARNING:
|
||||
return f"⚠️ {record.getMessage()}"
|
||||
return f"💣 {record.getMessage()}"
|
||||
return record.getMessage()
|
||||
|
||||
|
||||
_handler = logging.StreamHandler()
|
||||
_handler.setFormatter(_PrefixFormatter())
|
||||
_handler.setFormatter(_Formatter())
|
||||
logger = logging.getLogger("fastapi-vue")
|
||||
logger.addHandler(_handler)
|
||||
logger.setLevel(logging.INFO)
|
||||
logger.propagate = False # own handler; do not double-print via a configured root
|
||||
|
||||
|
||||
def _check_node_version(node_path: str) -> None:
|
||||
@@ -31,81 +40,118 @@ def _check_node_version(node_path: str) -> None:
|
||||
"""
|
||||
try:
|
||||
result = subprocess.run(
|
||||
[node_path, "--version"], capture_output=True, text=True, check=True
|
||||
[node_path, "--version"],
|
||||
capture_output=True,
|
||||
text=True,
|
||||
check=True,
|
||||
)
|
||||
version_str = result.stdout.strip()
|
||||
# Parse version like "v20.10.0" or "v18.17.1"
|
||||
match = re.match(r"v(\d+)", version_str)
|
||||
if match:
|
||||
major_version = int(match.group(1))
|
||||
if major_version >= 20:
|
||||
if major_version >= MIN_NODE_VERSION:
|
||||
return
|
||||
raise RuntimeError(
|
||||
f"Node.js {version_str} found, but v20+ required (install with nvm)"
|
||||
)
|
||||
msg = f"Node.js {version_str} found, but v{MIN_NODE_VERSION}+ required"
|
||||
raise RuntimeError(msg)
|
||||
except subprocess.CalledProcessError, FileNotFoundError, ValueError:
|
||||
pass
|
||||
raise RuntimeError("Could not determine Node.js version")
|
||||
msg = "Could not determine Node.js version"
|
||||
raise RuntimeError(msg)
|
||||
|
||||
|
||||
def _validate_npm_runtime(tool: str) -> bool:
|
||||
"""Validate npm runtime by checking Node.js version. Returns True if valid."""
|
||||
node_path = shutil.which("node", path=str(Path(tool).parent))
|
||||
if node_path is None:
|
||||
return False
|
||||
try:
|
||||
_check_node_version(node_path)
|
||||
except RuntimeError:
|
||||
return False
|
||||
return True
|
||||
|
||||
|
||||
def _find_runtime_from_env(options: list[str]) -> tuple[str, str] | None:
|
||||
"""Find runtime specified by JS_RUNTIME environment variable."""
|
||||
js_runtime_env = os.environ.get("JS_RUNTIME")
|
||||
if not js_runtime_env:
|
||||
return None
|
||||
|
||||
js_runtime = js_runtime_env
|
||||
js_path = Path(js_runtime)
|
||||
runtime_name = js_path.name
|
||||
|
||||
# Map node to npm
|
||||
if runtime_name == "node":
|
||||
runtime_name = "npm"
|
||||
js_runtime = str(js_path.parent / "npm") if js_path.parent.name else "npm"
|
||||
|
||||
for option in options:
|
||||
if option != runtime_name and not runtime_name.startswith(option):
|
||||
continue
|
||||
|
||||
tool = shutil.which(js_runtime)
|
||||
if tool is None:
|
||||
msg = f"JS_RUNTIME={js_runtime_env}: {option} not found"
|
||||
raise RuntimeError(msg)
|
||||
|
||||
if option == "npm":
|
||||
node_path = shutil.which("node", path=str(Path(tool).parent))
|
||||
if node_path is None:
|
||||
msg = f"JS_RUNTIME={js_runtime_env}: node not found"
|
||||
raise RuntimeError(msg)
|
||||
_check_node_version(node_path)
|
||||
|
||||
return tool, option
|
||||
|
||||
msg = f"JS_RUNTIME={js_runtime_env} not recognized"
|
||||
raise RuntimeError(msg)
|
||||
|
||||
|
||||
def _auto_detect_runtime(options: list[str]) -> tuple[str, str]:
|
||||
"""Auto-detect JavaScript runtime from available options."""
|
||||
node_version_error: RuntimeError | None = None
|
||||
|
||||
for option in options:
|
||||
tool = shutil.which(option)
|
||||
if not tool:
|
||||
continue
|
||||
|
||||
if option == "npm" and not _validate_npm_runtime(tool):
|
||||
try:
|
||||
node_path = shutil.which("node", path=str(Path(tool).parent))
|
||||
if node_path:
|
||||
_check_node_version(node_path)
|
||||
except RuntimeError as e:
|
||||
node_version_error = e
|
||||
continue
|
||||
|
||||
return tool, option
|
||||
|
||||
if node_version_error:
|
||||
raise node_version_error
|
||||
msg = "Node.js (v20+), Deno or Bun is required but none was found"
|
||||
raise RuntimeError(msg)
|
||||
|
||||
|
||||
def find_js_runtime() -> tuple[str, str]:
|
||||
"""Find a JavaScript runtime from JS_RUNTIME env or auto-detect.
|
||||
|
||||
Returns (tool_path, tool_name) where tool_name is "deno", "npm", or "bun".
|
||||
Raises JSRuntimeError if no suitable runtime is found.
|
||||
Raises RuntimeError if no suitable runtime is found.
|
||||
"""
|
||||
options = ["npm", "deno", "bun"]
|
||||
node_version_error: RuntimeError | None = None
|
||||
|
||||
# Check for JS_RUNTIME environment variable
|
||||
if js_runtime_env := os.environ.get("JS_RUNTIME"):
|
||||
js_runtime = js_runtime_env
|
||||
js_path = Path(js_runtime)
|
||||
runtime_name = js_path.name
|
||||
# Map node to npm
|
||||
if runtime_name == "node":
|
||||
runtime_name = "npm"
|
||||
js_runtime = str(js_path.parent / "npm") if js_path.parent.name else "npm"
|
||||
for option in options:
|
||||
if option == runtime_name or runtime_name.startswith(option):
|
||||
tool = shutil.which(js_runtime)
|
||||
if tool is None:
|
||||
raise RuntimeError(
|
||||
f"JS_RUNTIME={js_runtime_env}: {option} not found"
|
||||
)
|
||||
# Check Node.js version if using npm
|
||||
if option == "npm":
|
||||
node_path = shutil.which("node", path=str(Path(tool).parent))
|
||||
if node_path is None:
|
||||
raise RuntimeError(
|
||||
f"JS_RUNTIME={js_runtime_env}: node not found"
|
||||
)
|
||||
_check_node_version(node_path) # Raises on failure
|
||||
return tool, option
|
||||
raise RuntimeError(f"JS_RUNTIME={js_runtime_env} not recognized")
|
||||
if result := _find_runtime_from_env(options):
|
||||
return result
|
||||
|
||||
# Auto-detect
|
||||
for option in options:
|
||||
if tool := shutil.which(option):
|
||||
# Check Node.js version if using npm
|
||||
if option == "npm":
|
||||
node_path = shutil.which("node", path=str(Path(tool).parent))
|
||||
if node_path is None:
|
||||
continue
|
||||
try:
|
||||
_check_node_version(node_path)
|
||||
except RuntimeError as e:
|
||||
node_version_error = e
|
||||
continue # Try next runtime
|
||||
return tool, option
|
||||
|
||||
# No runtime found - provide helpful error
|
||||
if node_version_error:
|
||||
raise node_version_error
|
||||
raise RuntimeError("Node.js (v20+), Deno or Bun is required but none was found")
|
||||
return _auto_detect_runtime(options)
|
||||
|
||||
|
||||
def find_build_tool():
|
||||
def find_build_tool() -> tuple[list[str], list[str]]:
|
||||
"""Find JavaScript runtime and construct install/build commands.
|
||||
|
||||
Returns (install_cmd, build_cmd) tuples of command lists.
|
||||
@@ -143,9 +189,7 @@ def find_dev_tool() -> list[str]:
|
||||
|
||||
if name == "bun":
|
||||
logger.warning(
|
||||
"Bun has a bug in WS proxying "
|
||||
"(https://github.com/oven-sh/bun/issues/9882). "
|
||||
"Consider using npm instead."
|
||||
"Bun has a WS proxy bug (github.com/oven-sh/bun/issues/9882). Consider npm.",
|
||||
)
|
||||
|
||||
return [tool, *dev_args[name]]
|
||||
@@ -178,9 +222,9 @@ def build(folder: str = "frontend") -> None:
|
||||
install_cmd, build_cmd = find_build_tool()
|
||||
except RuntimeError as e:
|
||||
logger.warning(e)
|
||||
raise SystemExit(1)
|
||||
raise SystemExit(1) from None
|
||||
|
||||
def run(cmd) -> None:
|
||||
def run(cmd: list[str]) -> None:
|
||||
display_cmd = [Path(cmd[0]).stem, *cmd[1:]]
|
||||
logger.info("### %s", " ".join(display_cmd))
|
||||
subprocess.run(cmd, check=True, cwd=folder)
|
||||
@@ -190,4 +234,4 @@ def build(folder: str = "frontend") -> None:
|
||||
logger.info("")
|
||||
run(build_cmd)
|
||||
except subprocess.CalledProcessError:
|
||||
raise SystemExit(1)
|
||||
raise SystemExit(1) from None
|
||||
|
||||
+125
-118
@@ -1,153 +1,154 @@
|
||||
"""Utilities for the devserver script in the source repository.
|
||||
"""Utilities meant for devserver script, used only in source repository with dev deps."""
|
||||
|
||||
Used only with development dependencies.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import subprocess
|
||||
import sys
|
||||
from collections.abc import Coroutine
|
||||
from asyncio.subprocess import Process
|
||||
from contextlib import suppress
|
||||
from pathlib import Path
|
||||
from typing import Any, Self
|
||||
from subprocess import CalledProcessError
|
||||
from typing import TYPE_CHECKING, Any
|
||||
from urllib.parse import urlsplit
|
||||
|
||||
import httpx
|
||||
from buildutil import find_dev_tool, find_install_tool, logger
|
||||
from fastapi_vue.hostutil import parse_endpoint
|
||||
|
||||
if TYPE_CHECKING:
|
||||
from collections.abc import Awaitable
|
||||
|
||||
class ProcessGroup:
|
||||
"""Manage async subprocesses with automatic cleanup.
|
||||
|
||||
Acts like TaskGroup for processes.
|
||||
"""
|
||||
class ProcessGroup(asyncio.TaskGroup):
|
||||
"""TaskGroup with structured ownership of async subprocesses."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._procs: list[asyncio.subprocess.Process] = []
|
||||
self._cmds: dict[int, str] = {} # pid -> command name
|
||||
def __init__(self, *, terminate_timeout: float = 10) -> None:
|
||||
"""Set the grace period before terminate() escalates to kill()."""
|
||||
super().__init__()
|
||||
self._terminate_timeout = terminate_timeout
|
||||
self._cmds: dict[Process, tuple[str, ...]] = {}
|
||||
|
||||
async def spawn(
|
||||
self, *cmd: str, cwd: str | None = None
|
||||
) -> asyncio.subprocess.Process:
|
||||
"""Spawn a subprocess and track it."""
|
||||
cmd_name = Path(cmd[0]).stem
|
||||
logger.info(">>> %s", " ".join([cmd_name, *cmd[1:]]))
|
||||
proc = await asyncio.create_subprocess_exec(*cmd, cwd=cwd)
|
||||
self._procs.append(proc)
|
||||
self._cmds[proc.pid] = cmd_name
|
||||
return proc
|
||||
self, *cmd: str, cwd: str | None = None, vital: bool = False
|
||||
) -> Process:
|
||||
"""Spawn and own a subprocess. If a vital process exits, the group cancels."""
|
||||
|
||||
async def wait(
|
||||
self, *waitables: asyncio.subprocess.Process | Coroutine[Any, Any, Any]
|
||||
) -> None:
|
||||
"""Wait for processes/coroutines to complete, raise SystemExit on failure."""
|
||||
async def run() -> None:
|
||||
name = Path(cmd[0]).stem
|
||||
logger.info(">>> %s", " ".join([name, *cmd[1:]]))
|
||||
try:
|
||||
proc = await asyncio.create_subprocess_exec(*cmd, cwd=cwd)
|
||||
self._cmds[proc] = cmd
|
||||
started.set_result(proc)
|
||||
except Exception as e: # ruff: ignore[blind-except]
|
||||
started.set_exception(e)
|
||||
return
|
||||
|
||||
async def wait_proc(proc: asyncio.subprocess.Process) -> None:
|
||||
returncode = await proc.wait()
|
||||
if returncode != 0:
|
||||
cmd_name = self._cmds.get(proc.pid, "unknown")
|
||||
raise subprocess.CalledProcessError(returncode, cmd_name)
|
||||
|
||||
tasks = [
|
||||
wait_proc(w) if isinstance(w, asyncio.subprocess.Process) else w
|
||||
for w in waitables
|
||||
]
|
||||
try:
|
||||
await asyncio.gather(*tasks)
|
||||
except subprocess.CalledProcessError as e:
|
||||
logger.warning("%s failed with exit status %d", e.cmd, e.returncode)
|
||||
raise SystemExit(1) from None
|
||||
|
||||
async def __aenter__(self) -> Self:
|
||||
"""Return this process group context manager."""
|
||||
return self
|
||||
|
||||
async def __aexit__(
|
||||
self,
|
||||
exc_type: type[BaseException] | None,
|
||||
*_: object,
|
||||
) -> None:
|
||||
"""Wait for one process to exit, terminate others, then wait for all."""
|
||||
await self._cleanup(immediate=exc_type is not None)
|
||||
|
||||
async def _cleanup(self, immediate: bool = False) -> None:
|
||||
running = [p for p in self._procs if p.returncode is None]
|
||||
if not running:
|
||||
return
|
||||
|
||||
if not immediate:
|
||||
# Wait for any one process to exit
|
||||
with suppress(asyncio.CancelledError):
|
||||
await asyncio.wait(
|
||||
[asyncio.create_task(p.wait()) for p in running],
|
||||
return_when=asyncio.FIRST_COMPLETED,
|
||||
)
|
||||
|
||||
# Terminate remaining processes
|
||||
for p in self._procs:
|
||||
if p.returncode is None:
|
||||
try:
|
||||
returncode = await proc.wait()
|
||||
finally:
|
||||
with suppress(ProcessLookupError):
|
||||
p.terminate()
|
||||
|
||||
# Wait for all to finish (with overall timeout), shielded from cancellation
|
||||
still_running = [p for p in self._procs if p.returncode is None]
|
||||
if still_running:
|
||||
with suppress(asyncio.CancelledError):
|
||||
proc.terminate()
|
||||
try:
|
||||
await asyncio.shield(
|
||||
asyncio.wait_for(
|
||||
asyncio.gather(*[p.wait() for p in still_running]),
|
||||
timeout=10,
|
||||
)
|
||||
)
|
||||
await asyncio.wait_for(proc.wait(), self._terminate_timeout)
|
||||
except TimeoutError:
|
||||
for p in self._procs:
|
||||
if p.returncode is None:
|
||||
with suppress(ProcessLookupError):
|
||||
p.kill()
|
||||
await p.wait()
|
||||
with suppress(ProcessLookupError):
|
||||
proc.kill()
|
||||
await proc.wait()
|
||||
|
||||
if vital:
|
||||
logger.warning("Vital process %s exited", name)
|
||||
raise CalledProcessError(returncode, cmd)
|
||||
|
||||
started = asyncio.get_running_loop().create_future()
|
||||
self.create_task(run())
|
||||
return await asyncio.shield(started)
|
||||
|
||||
async def wait(self, *waitables: Process | Awaitable) -> tuple[Any, ...]:
|
||||
"""Wait concurrently and return results in argument order."""
|
||||
|
||||
async def task(w: Process | Awaitable) -> Any:
|
||||
if not isinstance(w, Process):
|
||||
return await w
|
||||
if retcode := await w.wait():
|
||||
cmd = self._cmds[w]
|
||||
logger.warning(
|
||||
"Process %s exited with status %d", Path(cmd[0]).stem, retcode
|
||||
)
|
||||
raise CalledProcessError(retcode, cmd)
|
||||
return retcode
|
||||
|
||||
async with asyncio.TaskGroup() as group:
|
||||
tasks = [group.create_task(task(w)) for w in waitables]
|
||||
|
||||
return tuple(task.result() for task in tasks)
|
||||
|
||||
|
||||
async def http_get_server(url: str, timeout: float) -> str | None: # ruff: ignore[async-function-with-timeout]
|
||||
"""GET url with plain asyncio streams, return the response Server header.
|
||||
|
||||
Returns an empty string when the server responds without a Server header,
|
||||
and None when the server is unreachable or doesn't answer in time.
|
||||
"""
|
||||
parts = urlsplit(url)
|
||||
host = parts.hostname or "localhost"
|
||||
port = parts.port or (443 if parts.scheme == "https" else 80)
|
||||
path = parts.path or "/"
|
||||
if parts.query:
|
||||
path += f"?{parts.query}"
|
||||
try:
|
||||
async with asyncio.timeout(timeout):
|
||||
reader, writer = await asyncio.open_connection(host, port)
|
||||
try:
|
||||
writer.write(f"GET {path} HTTP/1.0\r\nHost: {host}\r\n\r\n".encode())
|
||||
await writer.drain()
|
||||
data = await reader.readuntil(b"\r\n\r\n")
|
||||
finally:
|
||||
writer.close()
|
||||
except OSError, EOFError, ValueError, TimeoutError:
|
||||
return None
|
||||
for line in data.decode(errors="replace").split("\r\n"):
|
||||
if line.lower().startswith("server:"):
|
||||
return line[7:].strip()
|
||||
return ""
|
||||
|
||||
|
||||
async def check_ports_free(*urls: str) -> None:
|
||||
"""Verify URLs are not responding (ports are free).
|
||||
|
||||
Raise SystemExit if any endpoint responds.
|
||||
Meant to run as a task inside a TaskGroup. Logs the conflict and raises
|
||||
RuntimeError (handled like a failed process) if any URL responds.
|
||||
"""
|
||||
|
||||
async def check(client: httpx.AsyncClient, url: str) -> None:
|
||||
with suppress(httpx.RequestError):
|
||||
res = await client.get(url, timeout=0.1)
|
||||
server = res.headers.get("server", "server")
|
||||
logger.warning("Conflicting %s already running at %s", server, url)
|
||||
raise SystemExit(1)
|
||||
|
||||
async with httpx.AsyncClient() as client:
|
||||
await asyncio.gather(*[check(client, url) for url in urls])
|
||||
servers = await asyncio.gather(*(http_get_server(url, timeout=0.1) for url in urls))
|
||||
for url, server in zip(urls, servers, strict=True):
|
||||
if server is not None:
|
||||
logger.error(
|
||||
"Conflicting %s already running at %s", server or "server", url
|
||||
)
|
||||
raise RuntimeError(url)
|
||||
|
||||
|
||||
async def ready(url: str, path: str = "") -> None:
|
||||
async def ready(url: str, path: str = "", max_attempts: int = 50) -> None:
|
||||
"""Wait for the server to be ready by polling an endpoint.
|
||||
|
||||
Raises SystemExit(1) if server doesn't start in time.
|
||||
Use empty path to disable the check and make this return immediately.
|
||||
Logs, then raises RuntimeError if the server doesn't start in time.
|
||||
"""
|
||||
max_attempts = 50
|
||||
full_url = f"{url}{path}"
|
||||
if not path:
|
||||
return
|
||||
|
||||
async with httpx.AsyncClient() as client:
|
||||
for attempt in range(max_attempts):
|
||||
try:
|
||||
await client.get(full_url, timeout=1.0)
|
||||
logger.info("✓ Backend ready!")
|
||||
return
|
||||
except httpx.RequestError:
|
||||
if attempt == max_attempts - 1:
|
||||
logger.warning("Backend didn't start in time")
|
||||
raise SystemExit(1)
|
||||
await asyncio.sleep(0.1)
|
||||
for attempt in range(max_attempts):
|
||||
if await http_get_server(f"{url}{path}", timeout=1.0) is not None:
|
||||
logger.info("🟢 Backend ready!")
|
||||
return
|
||||
if attempt == max_attempts - 1:
|
||||
logger.error("Backend at %s didn't start in time", url)
|
||||
raise RuntimeError(url)
|
||||
await asyncio.sleep(0.1)
|
||||
|
||||
|
||||
def setup_vite(
|
||||
endpoint: str, default_port: int = 5173
|
||||
endpoint: str,
|
||||
default_port: int = 5173,
|
||||
) -> tuple[str, list[str], list[str]]:
|
||||
"""Parse frontend endpoint and build commands.
|
||||
|
||||
@@ -173,7 +174,9 @@ def setup_vite(
|
||||
|
||||
|
||||
def setup_fastapi(
|
||||
endpoint: str, module: str, default_port: int = 8000
|
||||
endpoint: str,
|
||||
module: str,
|
||||
default_port: int = 8000,
|
||||
) -> tuple[str, list[str]]:
|
||||
"""Parse backend endpoint and build uvicorn command.
|
||||
|
||||
@@ -205,7 +208,9 @@ def setup_fastapi(
|
||||
|
||||
|
||||
def setup_cli(
|
||||
cli: str, endpoint: str, default_port: int = 8000
|
||||
cli: str,
|
||||
endpoint: str,
|
||||
default_port: int = 8000,
|
||||
) -> tuple[str, list[str]]:
|
||||
"""Parse backend endpoint and build CLI command.
|
||||
|
||||
@@ -221,5 +226,7 @@ def setup_cli(
|
||||
host = endpoints[0]["host"]
|
||||
port = endpoints[0]["port"]
|
||||
|
||||
cmd = [cli, f"--listen={host}:{port}"]
|
||||
# Run the package as a module with the current interpreter, instead of
|
||||
# relying on a PATH-installed CLI entry point.
|
||||
cmd = [sys.executable, "-m", cli, f"--listen={host}:{port}"]
|
||||
return f"http://{host}:{port}", cmd
|
||||
|
||||
Regular → Executable
+374
-32
@@ -1,22 +1,36 @@
|
||||
"""Build the desktop GUI application and package it as a version-numbered ZIP.
|
||||
#!/usr/bin/env -S uv run
|
||||
# /// script
|
||||
# requires-python = ">=3.14"
|
||||
# dependencies = [
|
||||
# "mediahive[gui]",
|
||||
# ]
|
||||
#
|
||||
# [tool.uv.sources]
|
||||
# mediahive = { path = "../" }
|
||||
# ///
|
||||
"""Build the desktop GUI application and package it with Velopack.
|
||||
|
||||
Usage:
|
||||
uv run scripts/winbuild.py
|
||||
uv run scripts/guibuild.py
|
||||
|
||||
This runs in the project environment where dependencies
|
||||
are available via pyproject.toml.
|
||||
Self-contained: inline script dependencies above make uv resolve the
|
||||
package (with the gui extra) plus this script's own direct imports.
|
||||
|
||||
This script:
|
||||
1. Reads the version from pyproject.toml
|
||||
2. Runs `uv build` to produce the wheel/sdist
|
||||
3. On Windows, downloads the latest ffmpeg.exe for bundling
|
||||
4. On macOS arm64, downloads a prebuilt ffmpeg binary for bundling
|
||||
3. On Windows/macOS, downloads the ffmpeg binary for bundling
|
||||
4. Builds MediaHive using PyInstaller
|
||||
5. Creates a ZIP file with the version number
|
||||
5. Packages with Velopack: Setup.exe (Windows), .pkg (macOS),
|
||||
.AppImage (Linux), plus the update feed in build/velopack/
|
||||
that release.py uploads for in-app auto-updates
|
||||
6. On Windows, also creates a portable ZIP (no auto-updates)
|
||||
"""
|
||||
|
||||
import io
|
||||
import os
|
||||
import platform
|
||||
import re
|
||||
import shutil
|
||||
import stat
|
||||
import subprocess
|
||||
@@ -24,8 +38,10 @@ import sys
|
||||
import urllib.request
|
||||
import zipfile
|
||||
from pathlib import Path
|
||||
from typing import NamedTuple
|
||||
|
||||
import setuptools_scm
|
||||
from platformdirs import user_cache_path
|
||||
|
||||
# BtbN automated builds always publish a 'latest' tag with this asset.
|
||||
_FFMPEG_URL = (
|
||||
@@ -35,29 +51,86 @@ _FFMPEG_URL = (
|
||||
_MACOS_ARM64_TOOL_URLS = {
|
||||
"ffmpeg": "https://www.osxexperts.net/ffmpeg81arm.zip",
|
||||
}
|
||||
_FFMPEG_STAGING = Path(__file__).parent.parent / "build" / "ffmpeg"
|
||||
_REPO_ROOT = Path(__file__).parent.parent
|
||||
_ASSETS_DIR = _REPO_ROOT / "mediahive" / "assets"
|
||||
|
||||
|
||||
def _platform_zip_suffix() -> str:
|
||||
machine = platform.machine().lower()
|
||||
arch = {
|
||||
"x86_64": "x64",
|
||||
"amd64": "x64",
|
||||
"arm64": "arm64",
|
||||
"aarch64": "arm64",
|
||||
}.get(machine, machine or "unknown")
|
||||
def _build_cache_dir() -> Path:
|
||||
"""Return the persistent cross-build cache dir for downloaded tools (CI wipes build/)."""
|
||||
return user_cache_path("mediahive-build", appauthor=False, opinion=False)
|
||||
|
||||
|
||||
_FFMPEG_STAGING = _build_cache_dir() / "ffmpeg"
|
||||
|
||||
# Velopack CLI (dotnet tool package). Runs on the machine's .NET runtime; the
|
||||
# produced Setup.exe/Update.exe are native and need no runtime on end-user
|
||||
# machines. Pin a version whose tools target an installed .NET major.
|
||||
_VPK_VERSION = "1.2.158"
|
||||
_VPK_URL = (
|
||||
f"https://api.nuget.org/v3-flatcontainer/vpk/{_VPK_VERSION}"
|
||||
f"/vpk.{_VPK_VERSION}.nupkg"
|
||||
)
|
||||
_VPK_STAGING = _build_cache_dir() / f"vpk-{_VPK_VERSION}"
|
||||
|
||||
|
||||
class _Platform(NamedTuple):
|
||||
"""Per-platform naming/packaging constants.
|
||||
|
||||
tag is the release artifact suffix. Only Windows keeps an arch marker
|
||||
(win64); macOS builds are arm64-only and we ship one Linux flavor.
|
||||
"""
|
||||
|
||||
tag: str # win64 / macos / linux
|
||||
channel: str # Velopack update channel: win / osx / linux
|
||||
rid: str # Velopack runtime id
|
||||
dist_dir: str # PyInstaller output dir under build/
|
||||
icon: str # file in mediahive/assets
|
||||
main_exe: str
|
||||
setup_ext: str
|
||||
|
||||
|
||||
def _platform() -> _Platform:
|
||||
if sys.platform == "win32":
|
||||
return "win64"
|
||||
return _Platform(
|
||||
"win64",
|
||||
"win",
|
||||
"win-x64",
|
||||
"MediaHive",
|
||||
"mediahive.ico",
|
||||
"MediaHive.exe",
|
||||
".exe",
|
||||
)
|
||||
if sys.platform == "darwin":
|
||||
return f"macos-{arch}"
|
||||
return f"linux-{arch}"
|
||||
return _Platform(
|
||||
"macos",
|
||||
"osx",
|
||||
"osx-arm64",
|
||||
"MediaHive.app",
|
||||
"mediahive.icns",
|
||||
"MediaHive",
|
||||
".pkg",
|
||||
)
|
||||
return _Platform(
|
||||
"linux",
|
||||
"linux",
|
||||
"linux-x64",
|
||||
"MediaHive",
|
||||
"mediahive.png",
|
||||
"MediaHive",
|
||||
".AppImage",
|
||||
)
|
||||
|
||||
|
||||
def setup_artifact_name() -> str:
|
||||
"""Versionless name so releases/download/latest/<name> links stay valid."""
|
||||
p = _platform()
|
||||
# Windows keeps the -setup suffix: a bare .exe isn't self-explanatory.
|
||||
suffix = "-setup" if sys.platform == "win32" else ""
|
||||
return f"MediaHive-{p.tag}{suffix}{p.setup_ext}"
|
||||
|
||||
|
||||
def fetch_ffmpeg() -> Path:
|
||||
"""Download latest ffmpeg.exe from BtbN builds into build/ffmpeg/."""
|
||||
"""Download latest ffmpeg.exe from BtbN builds into the persistent build cache."""
|
||||
dest = _FFMPEG_STAGING / "ffmpeg.exe"
|
||||
if dest.exists():
|
||||
print(f"ffmpeg already staged at {dest}, skipping download.")
|
||||
@@ -82,7 +155,7 @@ def fetch_ffmpeg() -> Path:
|
||||
|
||||
|
||||
def fetch_macos_arm64_binaries() -> dict[str, Path]:
|
||||
"""Download prebuilt macOS arm64 ffmpeg binary into build/ffmpeg/."""
|
||||
"""Download prebuilt macOS arm64 ffmpeg binary into the persistent build cache."""
|
||||
if sys.platform != "darwin" or platform.machine().lower() not in {
|
||||
"arm64",
|
||||
"aarch64",
|
||||
@@ -179,6 +252,268 @@ def ensure_macos_icon() -> Path:
|
||||
return icon_icns
|
||||
|
||||
|
||||
_VPK_TFM = "net10.0"
|
||||
_VPK_REQUIRED_DOTNET_MAJOR = int(re.fullmatch(r"net(\d+)\.0", _VPK_TFM).group(1))
|
||||
|
||||
|
||||
def fetch_vpk() -> Path:
|
||||
"""Download the Velopack CLI package into the persistent build cache.
|
||||
|
||||
Returns the path to vpk.dll, runnable with `dotnet vpk.dll ...`.
|
||||
"""
|
||||
vpk_dll = _VPK_STAGING / "tools" / _VPK_TFM / "any" / "vpk.dll"
|
||||
if vpk_dll.exists():
|
||||
print(f"vpk already staged at {_VPK_STAGING}, skipping download.")
|
||||
return vpk_dll
|
||||
|
||||
_VPK_STAGING.mkdir(parents=True, exist_ok=True)
|
||||
print(f"Downloading vpk from {_VPK_URL} ...")
|
||||
with urllib.request.urlopen(_VPK_URL) as resp:
|
||||
data = resp.read()
|
||||
|
||||
with zipfile.ZipFile(io.BytesIO(data)) as zf:
|
||||
zf.extractall(_VPK_STAGING)
|
||||
|
||||
if not vpk_dll.exists():
|
||||
raise RuntimeError(f"vpk.dll not found in package at {vpk_dll}")
|
||||
print(f"vpk staged at {_VPK_STAGING}")
|
||||
return vpk_dll
|
||||
|
||||
|
||||
def _dotnet_runtime_major(exe: Path) -> int | None:
|
||||
"""Return the highest installed Microsoft.NETCore.App major version, or None."""
|
||||
try:
|
||||
result = subprocess.run(
|
||||
[str(exe), "--list-runtimes"], capture_output=True, text=True, timeout=30
|
||||
)
|
||||
except OSError, subprocess.TimeoutExpired:
|
||||
return None
|
||||
if result.returncode != 0:
|
||||
return None
|
||||
majors = []
|
||||
for line in result.stdout.splitlines():
|
||||
parts = line.split()
|
||||
if len(parts) >= 2 and parts[0] == "Microsoft.NETCore.App":
|
||||
try:
|
||||
majors.append(int(parts[1].split(".")[0]))
|
||||
except ValueError:
|
||||
continue
|
||||
return max(majors, default=None)
|
||||
|
||||
|
||||
def fetch_dotnet() -> str:
|
||||
"""Resolve a system dotnet host able to run vpk (needs .NET >= 10).
|
||||
|
||||
The .NET SDK is a build prerequisite installed on the build machine —
|
||||
downloading a runtime per build is slow and flaky. Several dotnet
|
||||
installations may coexist (PATH may resolve to a runtime-only .NET 8
|
||||
while scoop holds the SDK 10), so probe known locations and pick the
|
||||
newest runtime rather than the first that runs.
|
||||
"""
|
||||
exe_name = "dotnet.exe" if sys.platform == "win32" else "dotnet"
|
||||
candidates: list[Path] = []
|
||||
root = os.environ.get("DOTNET_ROOT")
|
||||
if root:
|
||||
candidates.append(Path(root) / exe_name)
|
||||
which = shutil.which("dotnet")
|
||||
if which:
|
||||
candidates.append(Path(which))
|
||||
if sys.platform == "win32":
|
||||
candidates += [
|
||||
Path(r"C:\ProgramData\scoop\apps\dotnet-sdk\current") / exe_name,
|
||||
Path(r"C:\Program Files\dotnet") / exe_name,
|
||||
]
|
||||
elif sys.platform == "darwin":
|
||||
candidates += [
|
||||
Path("/opt/homebrew/bin") / exe_name,
|
||||
Path("/usr/local/share/dotnet") / exe_name,
|
||||
]
|
||||
else:
|
||||
candidates += [
|
||||
Path("/usr/share/dotnet") / exe_name,
|
||||
Path("/usr/lib/dotnet") / exe_name,
|
||||
Path.home() / ".dotnet" / exe_name,
|
||||
]
|
||||
|
||||
best: tuple[int, Path] | None = None
|
||||
for exe in candidates:
|
||||
if not exe.exists():
|
||||
continue
|
||||
major = _dotnet_runtime_major(exe)
|
||||
if major is not None and (best is None or major > best[0]):
|
||||
best = (major, exe)
|
||||
|
||||
if best is not None and best[0] >= _VPK_REQUIRED_DOTNET_MAJOR:
|
||||
print(f"Using dotnet at {best[1]} (.NET {best[0]})")
|
||||
return str(best[1])
|
||||
|
||||
found = f"newest found is .NET {best[0]} at {best[1]}" if best else "none found"
|
||||
raise RuntimeError(
|
||||
f"vpk requires Microsoft.NETCore.App >= {_VPK_REQUIRED_DOTNET_MAJOR} ({found}). "
|
||||
"Install the current .NET SDK on this build machine "
|
||||
"(Windows: `scoop install dotnet-sdk`; macOS: `brew install dotnet-sdk`; "
|
||||
"Linux: distro `dotnet-sdk` package or the dotnet-install script)."
|
||||
)
|
||||
|
||||
|
||||
def build_velopack(version: str) -> Path:
|
||||
"""Build the Velopack installer/bundle for this platform.
|
||||
|
||||
Windows: per-user Setup.exe. macOS: .pkg installer. Linux: .AppImage.
|
||||
Also produces the update feed (releases.<channel>.json, *.nupkg) in
|
||||
build/velopack/ for release.py to upload — in-app auto-updates read it
|
||||
from the Gitea release. Velopack installs carry no Mark-of-the-Web, so
|
||||
the .NET CLR loads pythonnet/pywebview assemblies that it refuses from
|
||||
a downloaded ZIP.
|
||||
"""
|
||||
plat = _platform()
|
||||
dist_folder = _REPO_ROOT / "build" / plat.dist_dir
|
||||
if not dist_folder.exists():
|
||||
raise FileNotFoundError(f"Distribution folder not found: {dist_folder}")
|
||||
|
||||
vpk_dll = fetch_vpk()
|
||||
releases_dir = _REPO_ROOT / "build" / "velopack"
|
||||
|
||||
cmd = [
|
||||
fetch_dotnet(),
|
||||
str(vpk_dll),
|
||||
"pack",
|
||||
"--packId",
|
||||
"MediaHive",
|
||||
"--packVersion",
|
||||
version,
|
||||
"--packDir",
|
||||
str(dist_folder),
|
||||
"--mainExe",
|
||||
plat.main_exe,
|
||||
"--packAuthors",
|
||||
"MediaHive",
|
||||
"--packTitle",
|
||||
"MediaHive",
|
||||
"--icon",
|
||||
str(_ASSETS_DIR / plat.icon),
|
||||
"--runtime",
|
||||
plat.rid,
|
||||
"--outputDir",
|
||||
str(releases_dir),
|
||||
]
|
||||
if sys.platform == "darwin":
|
||||
cmd += ["--instWelcome", str(_ASSETS_DIR / "macos-installer-welcome.txt")]
|
||||
print(f"Running: {' '.join(cmd)}")
|
||||
try:
|
||||
result = subprocess.run(cmd, cwd=_REPO_ROOT, capture_output=True, text=True)
|
||||
except OSError as exc:
|
||||
raise RuntimeError(f"vpk failed to start: {exc}") from exc
|
||||
if result.returncode != 0:
|
||||
raise RuntimeError(
|
||||
f"vpk pack failed with exit code {result.returncode}\n"
|
||||
f"stdout:\n{result.stdout}\nstderr:\n{result.stderr}"
|
||||
)
|
||||
|
||||
setup = next(iter(sorted(releases_dir.glob(f"*Setup*{plat.setup_ext}"))), None)
|
||||
if setup is None:
|
||||
setup = next(iter(sorted(releases_dir.glob(f"*{plat.setup_ext}"))), None)
|
||||
if setup is None:
|
||||
raise RuntimeError(f"vpk produced no *{plat.setup_ext} in {releases_dir}")
|
||||
if sys.platform == "darwin":
|
||||
force_macos_user_install(setup)
|
||||
artifact = _REPO_ROOT / "build" / setup_artifact_name()
|
||||
artifact.unlink(missing_ok=True)
|
||||
setup.rename(artifact)
|
||||
rename_feed_package(releases_dir, version, plat.channel)
|
||||
return artifact
|
||||
|
||||
|
||||
def rename_feed_package(releases_dir: Path, version: str, channel: str) -> None:
|
||||
"""Rename this platform's update-feed nupkg in place.
|
||||
|
||||
vpk hardcodes MediaHive-{ver}[-{channel}]-full.nupkg (Windows, the legacy
|
||||
default channel, gets no marker). Rename all to the uniform
|
||||
mediahive-{ver}-{channel}-full.nupkg: lowercase groups them with the
|
||||
wheel/sdist below the capitalized user downloads on the release page,
|
||||
and every platform carries its channel. releases.<channel>.json
|
||||
references the filename, so patch it too.
|
||||
"""
|
||||
old_name = f"MediaHive-{version}-full.nupkg"
|
||||
if not (releases_dir / old_name).exists():
|
||||
old_name = f"MediaHive-{version}-{channel}-full.nupkg"
|
||||
nupkg = releases_dir / old_name
|
||||
if not nupkg.exists():
|
||||
raise RuntimeError(f"vpk produced no {old_name} in {releases_dir}")
|
||||
|
||||
new_name = f"mediahive-{version}-{channel}-full.nupkg"
|
||||
manifest = releases_dir / f"releases.{channel}.json"
|
||||
text = manifest.read_text()
|
||||
if old_name not in text:
|
||||
raise RuntimeError(f"{manifest.name} does not reference {old_name}")
|
||||
manifest.write_text(text.replace(old_name, new_name))
|
||||
nupkg.rename(nupkg.with_name(new_name))
|
||||
|
||||
|
||||
def force_macos_user_install(pkg: Path) -> None:
|
||||
"""Restrict the Velopack-generated pkg to per-user installs (~/Applications).
|
||||
|
||||
Velopack hardcodes two install domains (currentUserHome + localSystem) in
|
||||
the distribution XML. System installs land in /Applications, which the
|
||||
user may not own — Velopack's UpdateMac then cannot replace the .app on
|
||||
auto-update. With a single domain, macOS Installer skips the Destination
|
||||
Select page and installs to ~/Applications without admin rights.
|
||||
|
||||
Also drops the `sudo -u "$USER"` prefix from Velopack's postinstall
|
||||
script: under a per-user install the script already runs as the
|
||||
installing user, and sudo would fail for lack of a tty.
|
||||
|
||||
NB: only ever use `pkgutil --expand` (which keeps component Payloads
|
||||
archived) — `--expand-full` flattens payloads to loose files that
|
||||
`--flatten` cannot repack, producing a pkg that "installs" nothing.
|
||||
"""
|
||||
expanded = pkg.with_name(pkg.stem + "-expanded")
|
||||
shutil.rmtree(expanded, ignore_errors=True)
|
||||
subprocess.run(["pkgutil", "--expand", str(pkg), str(expanded)], check=True)
|
||||
|
||||
dist_xml = expanded / "Distribution"
|
||||
xml = dist_xml.read_text()
|
||||
new_xml, count = re.subn(
|
||||
r"<domains [^>]*/>",
|
||||
'<domains enable_anywhere="false" enable_currentUserHome="true" enable_localSystem="false" />',
|
||||
xml,
|
||||
)
|
||||
if count != 1:
|
||||
raise RuntimeError("Unexpected distribution.xml: <domains> not found")
|
||||
dist_xml.write_text(new_xml)
|
||||
|
||||
# Edit postinstall inside the component pkg. Depending on the macOS
|
||||
# version, --expand leaves the component as an archived file (needs a
|
||||
# nested expand/flatten round) or as an already-expanded directory.
|
||||
components = list(expanded.glob("*.pkg"))
|
||||
if len(components) != 1:
|
||||
contents = sorted(p.name for p in expanded.iterdir())
|
||||
raise RuntimeError(
|
||||
f"Unexpected pkg layout: components={components} in {contents}"
|
||||
)
|
||||
component = components[0]
|
||||
if component.is_dir():
|
||||
comp_dir = component
|
||||
else:
|
||||
comp_dir = expanded / (component.stem + "-component")
|
||||
subprocess.run(
|
||||
["pkgutil", "--expand", str(component), str(comp_dir)], check=True
|
||||
)
|
||||
postinstall = comp_dir / "Scripts" / "postinstall"
|
||||
script = postinstall.read_text()
|
||||
if 'sudo -u "$USER" ' not in script:
|
||||
raise RuntimeError("Unexpected postinstall script: sudo prefix not found")
|
||||
postinstall.write_text(script.replace('sudo -u "$USER" ', ""))
|
||||
if comp_dir is not component:
|
||||
subprocess.run(
|
||||
["pkgutil", "--flatten", str(comp_dir), str(component)], check=True
|
||||
)
|
||||
shutil.rmtree(comp_dir)
|
||||
|
||||
subprocess.run(["pkgutil", "--flatten", str(expanded), str(pkg)], check=True)
|
||||
shutil.rmtree(expanded)
|
||||
|
||||
|
||||
def read_version() -> str:
|
||||
"""Read version via setuptools_scm (same logic as hatch-vcs)."""
|
||||
return setuptools_scm.get_version(root=str(_REPO_ROOT))
|
||||
@@ -216,18 +551,18 @@ def build_executable() -> None:
|
||||
raise RuntimeError(f"PyInstaller failed with exit code {result.returncode}")
|
||||
|
||||
|
||||
def create_zip(version: str) -> Path:
|
||||
"""Create a version-numbered ZIP file of the build/MediaHive folder."""
|
||||
repo_root = _REPO_ROOT
|
||||
dist_folder = repo_root / "build" / "MediaHive"
|
||||
def create_portable_zip() -> Path:
|
||||
"""Create the Windows portable ZIP of the build/MediaHive folder.
|
||||
|
||||
Velopack-less plain-folder distribution for users who cannot or do not
|
||||
want to run Setup.exe. No auto-updates; the app strips Mark-of-the-Web
|
||||
from bundled DLLs at first run instead.
|
||||
"""
|
||||
dist_folder = _REPO_ROOT / "build" / "MediaHive"
|
||||
if not dist_folder.exists():
|
||||
raise FileNotFoundError(f"Distribution folder not found: {dist_folder}")
|
||||
|
||||
zip_name = f"MediaHive-{version}-{_platform_zip_suffix()}.zip"
|
||||
zip_path = repo_root / "build" / zip_name
|
||||
zip_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
zip_path = _REPO_ROOT / "build" / "MediaHive-win64-portable.zip"
|
||||
print(f"Creating {zip_path}...")
|
||||
shutil.make_archive(
|
||||
str(zip_path.with_suffix("")), # removes .zip so make_archive can add it
|
||||
@@ -238,6 +573,9 @@ def create_zip(version: str) -> Path:
|
||||
|
||||
|
||||
def main() -> None:
|
||||
# Windows consoles default to cp1252, which can't encode ✓/✗
|
||||
sys.stdout.reconfigure(errors="replace")
|
||||
sys.stderr.reconfigure(errors="replace")
|
||||
try:
|
||||
version = read_version()
|
||||
print(f"MediaHive version: {version}")
|
||||
@@ -254,10 +592,14 @@ def main() -> None:
|
||||
)
|
||||
build_wheel()
|
||||
build_executable()
|
||||
zip_path = create_zip(version)
|
||||
|
||||
print(f"✓ Built successfully: {zip_path}")
|
||||
print(f" Size: {zip_path.stat().st_size / (1024 * 1024):.1f} MB")
|
||||
artifacts = [build_velopack(version)]
|
||||
if sys.platform == "win32":
|
||||
artifacts.append(create_portable_zip())
|
||||
|
||||
for artifact_path in artifacts:
|
||||
print(f"✓ Built successfully: {artifact_path}")
|
||||
print(f" Size: {artifact_path.stat().st_size / (1024 * 1024):.1f} MB")
|
||||
except (FileNotFoundError, OSError, RuntimeError, ValueError) as e:
|
||||
print(f"✗ Build failed: {e}", file=sys.stderr)
|
||||
sys.exit(1)
|
||||
|
||||
Regular → Executable
+117
-40
@@ -1,3 +1,4 @@
|
||||
#!/usr/bin/env -S uv run
|
||||
"""Publish a MediaHive release to Gitea.
|
||||
|
||||
Usage:
|
||||
@@ -8,10 +9,15 @@ Reads from [project.urls] Repository in pyproject.toml.
|
||||
Token: GITEA_TOKEN environment variable
|
||||
|
||||
Steps:
|
||||
1. Find clean-versioned ZIPs in build/ and matching dist/ wheels/sdists
|
||||
2. Abort if any dist files are missing for a found ZIP version
|
||||
3. Create a Gitea release for each version and upload all assets
|
||||
1. Read the clean tag version via setuptools_scm, find platform artifacts
|
||||
in build/ and matching dist/ wheels/sdists
|
||||
2. Abort if any dist files are missing
|
||||
3. Create a Gitea release for each version (or reuse the existing one
|
||||
for the tag, skipping already-uploaded assets) and upload all assets
|
||||
4. Remind the user to run: uv publish
|
||||
|
||||
Parallel CI platform builds converge on one release per tag; pass --no-dist
|
||||
on all but one platform so only it uploads the wheel/sdist.
|
||||
"""
|
||||
|
||||
import argparse
|
||||
@@ -23,6 +29,7 @@ from pathlib import Path
|
||||
from urllib.parse import urlparse
|
||||
|
||||
import httpx
|
||||
import setuptools_scm
|
||||
|
||||
REPO_ROOT = Path(__file__).parent.parent
|
||||
|
||||
@@ -62,20 +69,31 @@ def load_token() -> str:
|
||||
# ZIP + dist helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
# Matches MediaHive-1.2.3-win64.zip, MediaHive-1.2.3-macos-arm64.zip, etc.
|
||||
# Rejects dev/dirty versions like MediaHive-1.2.3.dev0+gabcd-win64.zip
|
||||
_CLEAN_ZIP_RE = re.compile(r"^MediaHive-(\d+(?:\.\d+)*)-([A-Za-z0-9._-]+)\.zip$")
|
||||
# Installer artifacts are versionless (MediaHive-win64-setup.exe,
|
||||
# MediaHive-macos-setup.pkg, MediaHive-linux-setup.AppImage,
|
||||
# MediaHive-win64-portable.zip) so /releases/download/latest/<name> links
|
||||
# stay valid. The version comes from setuptools_scm instead.
|
||||
_ARTIFACT_RE = re.compile(
|
||||
r"^MediaHive-(?!\d)[A-Za-z0-9._-]+\.(?:zip|dmg|exe|pkg|AppImage)$"
|
||||
)
|
||||
|
||||
|
||||
def find_releasable_zips() -> list[tuple[Path, str, str]]:
|
||||
"""Return (path, version, platform_tag) for clean-versioned ZIPs in build/."""
|
||||
def read_version() -> str:
|
||||
"""Read version via setuptools_scm, refusing dev/dirty versions."""
|
||||
version = setuptools_scm.get_version(root=str(REPO_ROOT))
|
||||
if not re.fullmatch(r"\d+(?:\.\d+)*", version):
|
||||
raise RuntimeError(
|
||||
f"Refusing to release non-clean version {version!r}. Tag a release first."
|
||||
)
|
||||
return version
|
||||
|
||||
|
||||
def find_releasable_artifacts() -> list[Path]:
|
||||
"""Return platform artifact paths in build/."""
|
||||
build_dir = REPO_ROOT / "build"
|
||||
results = []
|
||||
for p in sorted(build_dir.glob("MediaHive-*.zip")):
|
||||
m = _CLEAN_ZIP_RE.match(p.name)
|
||||
if m:
|
||||
results.append((p, m.group(1), m.group(2)))
|
||||
return results
|
||||
return [
|
||||
p for p in sorted(build_dir.glob("MediaHive-*")) if _ARTIFACT_RE.match(p.name)
|
||||
]
|
||||
|
||||
|
||||
def find_dist_files(version: str) -> list[Path]:
|
||||
@@ -107,6 +125,23 @@ def find_dist_files(version: str) -> list[Path]:
|
||||
return [wheel, sdist]
|
||||
|
||||
|
||||
def find_velopack_feed_files() -> list[Path]:
|
||||
"""Velopack update feed files produced by vpk pack in build/velopack/.
|
||||
|
||||
Only what the in-app updater (GiteaSource) reads from the latest
|
||||
release: this channel's releases.<channel>.json index and the nupkg
|
||||
payload it points to. The legacy RELEASES and assets.*.json manifests
|
||||
(Squirrel compat / setup bootstrap) are not uploaded.
|
||||
"""
|
||||
releases_dir = REPO_ROOT / "build" / "velopack"
|
||||
if not releases_dir.exists():
|
||||
return []
|
||||
files: list[Path] = []
|
||||
for pattern in ("releases.*.json", "*.nupkg"):
|
||||
files.extend(sorted(releases_dir.glob(pattern)))
|
||||
return files
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Gitea API helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
@@ -116,6 +151,18 @@ def gitea_headers(token: str) -> dict:
|
||||
return {"Authorization": f"token {token}", "Accept": "application/json"}
|
||||
|
||||
|
||||
def get_release_by_tag(
|
||||
client: httpx.Client, base_url: str, repo: str, tag: str
|
||||
) -> dict | None:
|
||||
"""Return the existing release for a tag, or None."""
|
||||
url = f"{base_url}/api/v1/repos/{repo}/releases/tags/{tag}"
|
||||
resp = client.get(url)
|
||||
if resp.status_code == 404:
|
||||
return None
|
||||
resp.raise_for_status()
|
||||
return resp.json()
|
||||
|
||||
|
||||
def create_release(
|
||||
client: httpx.Client,
|
||||
base_url: str,
|
||||
@@ -124,8 +171,12 @@ def create_release(
|
||||
version: str,
|
||||
notes: str,
|
||||
draft: bool,
|
||||
) -> int:
|
||||
"""Create a Gitea release and return its id."""
|
||||
) -> tuple[int, set[str]]:
|
||||
"""Create a Gitea release, or reuse the existing one for the tag.
|
||||
|
||||
Returns (release_id, names of assets already attached), so parallel
|
||||
platform builds can converge on one release without conflicts.
|
||||
"""
|
||||
url = f"{base_url}/api/v1/repos/{repo}/releases"
|
||||
payload = {
|
||||
"tag_name": tag,
|
||||
@@ -136,11 +187,17 @@ def create_release(
|
||||
}
|
||||
resp = client.post(url, json=payload)
|
||||
if resp.status_code == 409:
|
||||
raise RuntimeError(f"A release for tag '{tag}' already exists on Gitea.")
|
||||
existing = get_release_by_tag(client, base_url, repo, tag)
|
||||
if existing is None:
|
||||
raise RuntimeError(f"Release for tag '{tag}' conflicts but cannot be read.")
|
||||
release_id = existing["id"]
|
||||
assets = {a["name"] for a in existing.get("assets", [])}
|
||||
print(f"Release for tag '{tag}' already exists (id={release_id}), reusing it.")
|
||||
return release_id, assets
|
||||
resp.raise_for_status()
|
||||
release_id = resp.json()["id"]
|
||||
print(f"Created release id={release_id} (draft={draft})")
|
||||
return release_id
|
||||
return release_id, set()
|
||||
|
||||
|
||||
def upload_asset(
|
||||
@@ -153,7 +210,10 @@ def upload_asset(
|
||||
"""Upload a file to the release and return the download URL."""
|
||||
url = f"{base_url}/api/v1/repos/{repo}/releases/{release_id}/assets"
|
||||
size_mb = path.stat().st_size / (1024 * 1024)
|
||||
mime = "application/zip" if path.suffix == ".zip" else "application/octet-stream"
|
||||
mime = {
|
||||
".zip": "application/zip",
|
||||
".dmg": "application/x-apple-diskimage",
|
||||
}.get(path.suffix, "application/octet-stream")
|
||||
print(f"Uploading {path.name} ({size_mb:.1f} MB) ...")
|
||||
with Path(path).open("rb") as fh:
|
||||
resp = client.post(
|
||||
@@ -173,6 +233,10 @@ def upload_asset(
|
||||
|
||||
|
||||
def main() -> None:
|
||||
# Windows consoles default to cp1252, which can't encode ✓/✗
|
||||
sys.stdout.reconfigure(errors="replace")
|
||||
sys.stderr.reconfigure(errors="replace")
|
||||
|
||||
parser = argparse.ArgumentParser(description="Publish a MediaHive release to Gitea")
|
||||
parser.add_argument(
|
||||
"--draft", action="store_true", help="Create as a draft release"
|
||||
@@ -180,46 +244,59 @@ def main() -> None:
|
||||
parser.add_argument(
|
||||
"--notes", default="", metavar="TEXT", help="Release notes body"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--no-dist",
|
||||
action="store_true",
|
||||
help="Skip wheel/sdist upload (for parallel platform builds; one job uploads them)",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
try:
|
||||
cfg = load_gitea_config()
|
||||
token = load_token()
|
||||
version = read_version()
|
||||
|
||||
zips = find_releasable_zips()
|
||||
if not zips:
|
||||
artifacts = find_releasable_artifacts()
|
||||
if not artifacts:
|
||||
print(
|
||||
"No clean-versioned ZIPs found in build/.\n"
|
||||
"No platform artifacts found in build/.\n"
|
||||
"Run scripts/guibuild.py first.",
|
||||
file=sys.stderr,
|
||||
)
|
||||
sys.exit(1)
|
||||
|
||||
# Validate all dist files exist before touching Gitea
|
||||
dist_files: dict[str, list[Path]] = {}
|
||||
for _, version, _platform_tag in zips:
|
||||
dist_files[version] = find_dist_files(version)
|
||||
dist_files: list[Path] = [] if args.no_dist else find_dist_files(version)
|
||||
|
||||
base_url = cfg["url"].rstrip("/")
|
||||
repo = cfg["repo"]
|
||||
|
||||
with httpx.Client(headers=gitea_headers(token)) as client:
|
||||
release_ids_by_version: dict[str, int] = {}
|
||||
for zip_path, version, platform_tag in zips:
|
||||
print(f"\nReleasing {version} ...")
|
||||
tag = f"v{version}"
|
||||
release_id = release_ids_by_version.get(version)
|
||||
if release_id is None:
|
||||
release_id = create_release(
|
||||
client, base_url, repo, tag, version, args.notes, args.draft
|
||||
)
|
||||
release_ids_by_version[version] = release_id
|
||||
for path in dist_files[version]:
|
||||
upload_asset(client, base_url, repo, release_id, path)
|
||||
print(f"\nReleasing {version} ...")
|
||||
tag = f"v{version}"
|
||||
release_id, uploaded = create_release(
|
||||
client, base_url, repo, tag, version, args.notes, args.draft
|
||||
)
|
||||
for path in dist_files:
|
||||
if path.name in uploaded:
|
||||
print(f"Skipping {path.name}, already on the release.")
|
||||
continue
|
||||
upload_asset(client, base_url, repo, release_id, path)
|
||||
|
||||
print(f"Uploading platform artifact: {platform_tag}")
|
||||
upload_asset(client, base_url, repo, release_id, zip_path)
|
||||
print(f" ✓ {tag} published")
|
||||
for artifact_path in artifacts:
|
||||
if artifact_path.name in uploaded:
|
||||
print(f"Skipping {artifact_path.name}, already on the release.")
|
||||
continue
|
||||
print(f"Uploading platform artifact: {artifact_path.name}")
|
||||
upload_asset(client, base_url, repo, release_id, artifact_path)
|
||||
uploaded.add(artifact_path.name)
|
||||
for feed_file in find_velopack_feed_files():
|
||||
if feed_file.name in uploaded:
|
||||
print(f"Skipping {feed_file.name}, already on the release.")
|
||||
continue
|
||||
upload_asset(client, base_url, repo, release_id, feed_file)
|
||||
uploaded.add(feed_file.name)
|
||||
print(f" ✓ {tag} published")
|
||||
|
||||
print("\nDone. To publish to PyPI, run:")
|
||||
print(" uv publish")
|
||||
|
||||
@@ -1,467 +0,0 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Torrent Scanner - Scans for .torrent files and analyzes their trackers."""
|
||||
|
||||
import argparse
|
||||
import hashlib
|
||||
import shutil
|
||||
from collections.abc import Iterator
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
|
||||
import bencodepy
|
||||
|
||||
from rtorrent_client import RTorrentClient
|
||||
|
||||
|
||||
def _expand_path_pattern(pattern: str) -> list[Path]:
|
||||
"""Expand a user-provided path or glob pattern with pathlib."""
|
||||
expanded = Path(pattern).expanduser()
|
||||
pattern_text = str(expanded)
|
||||
has_glob = any(ch in pattern_text for ch in "*?[")
|
||||
|
||||
if not has_glob:
|
||||
return [expanded] if expanded.exists() else []
|
||||
|
||||
normalized = pattern_text.replace("\\", "/")
|
||||
if expanded.is_absolute():
|
||||
root = Path(expanded.anchor)
|
||||
remainder = normalized[len(expanded.anchor) :].lstrip("/")
|
||||
return list(root.glob(remainder)) if remainder else []
|
||||
return list(Path().glob(normalized))
|
||||
|
||||
|
||||
@dataclass
|
||||
class TorrentInfo:
|
||||
"""Information extracted from a torrent file."""
|
||||
|
||||
path: Path
|
||||
name: str
|
||||
trackers: list[str]
|
||||
size: int | None = None
|
||||
files: list[str] | None = None
|
||||
info_hash: str | None = None
|
||||
is_multi_file: bool = False
|
||||
|
||||
def has_tracker(self, domain: str) -> bool:
|
||||
"""Check if any tracker URL contains the given domain."""
|
||||
return any(domain.lower() in tracker.lower() for tracker in self.trackers)
|
||||
|
||||
def get_download_directory(self) -> Path:
|
||||
"""Get the download directory (parent of .torrents folder).
|
||||
|
||||
Assumes .torrent files are in <download_dir>/.torrents/
|
||||
so the actual downloads are one level up.
|
||||
"""
|
||||
return self.path.parent.parent
|
||||
|
||||
def get_expected_data_path(self) -> Path:
|
||||
"""Get the expected path where downloaded data should exist.
|
||||
|
||||
For multi-file torrents: download_dir/torrent_name/ (directory)
|
||||
For single-file torrents: download_dir/torrent_name (file)
|
||||
"""
|
||||
return self.get_download_directory() / self.name
|
||||
|
||||
def verify_download_exists(self) -> tuple[bool, str]:
|
||||
"""Verify that the downloaded data exists on disk.
|
||||
|
||||
Returns:
|
||||
Tuple of (exists: bool, message: str)
|
||||
|
||||
"""
|
||||
expected_path = self.get_expected_data_path()
|
||||
|
||||
if self.is_multi_file:
|
||||
# Multi-file torrent: expect a directory
|
||||
if not expected_path.exists():
|
||||
return False, f"Directory not found: {expected_path}"
|
||||
if not expected_path.is_dir():
|
||||
return False, f"Expected directory but found file: {expected_path}"
|
||||
# Optionally check if at least some files exist
|
||||
existing_files = list(expected_path.rglob("*"))
|
||||
file_count = sum(1 for f in existing_files if f.is_file())
|
||||
if file_count == 0:
|
||||
return False, f"Directory exists but is empty: {expected_path}"
|
||||
return True, f"Directory exists with {file_count} files"
|
||||
# Single-file torrent: expect a file
|
||||
if not expected_path.exists():
|
||||
return False, f"File not found: {expected_path}"
|
||||
if expected_path.is_dir():
|
||||
return False, f"Expected file but found directory: {expected_path}"
|
||||
return True, f"File exists: {expected_path}"
|
||||
|
||||
|
||||
def parse_torrent(filepath: Path) -> TorrentInfo | None:
|
||||
"""Parse a .torrent file and extract relevant information.
|
||||
|
||||
Args:
|
||||
filepath: Path to the .torrent file
|
||||
|
||||
Returns:
|
||||
TorrentInfo object or None if parsing fails
|
||||
|
||||
"""
|
||||
try:
|
||||
data = bencodepy.decode(Path(filepath).read_bytes())
|
||||
except (OSError, ValueError, TypeError) as e:
|
||||
print(f"Error parsing {filepath}: {e}")
|
||||
return None
|
||||
|
||||
# Extract trackers
|
||||
trackers = []
|
||||
|
||||
# Main announce URL
|
||||
if b"announce" in data:
|
||||
announce = data[b"announce"]
|
||||
if isinstance(announce, bytes):
|
||||
trackers.append(announce.decode("utf-8", errors="replace"))
|
||||
|
||||
# Announce list (multiple trackers)
|
||||
if b"announce-list" in data:
|
||||
for tier in data[b"announce-list"]:
|
||||
for tracker in tier:
|
||||
if isinstance(tracker, bytes):
|
||||
url = tracker.decode("utf-8", errors="replace")
|
||||
if url not in trackers:
|
||||
trackers.append(url)
|
||||
|
||||
# Extract name
|
||||
info = data.get(b"info", {})
|
||||
name = info.get(b"name", b"Unknown").decode("utf-8", errors="replace")
|
||||
|
||||
# Calculate info hash
|
||||
info_hash = hashlib.sha1(bencodepy.encode(info)).hexdigest().upper()
|
||||
|
||||
# Extract size and files
|
||||
size = None
|
||||
files = None
|
||||
is_multi_file = False
|
||||
|
||||
if b"length" in info:
|
||||
# Single file torrent
|
||||
size = info[b"length"]
|
||||
files = [name]
|
||||
is_multi_file = False
|
||||
elif b"files" in info:
|
||||
# Multi-file torrent
|
||||
files = []
|
||||
size = 0
|
||||
is_multi_file = True
|
||||
for file_info in info[b"files"]:
|
||||
file_path = "/".join(
|
||||
p.decode("utf-8", errors="replace") for p in file_info.get(b"path", [])
|
||||
)
|
||||
files.append(file_path)
|
||||
size += file_info.get(b"length", 0)
|
||||
|
||||
return TorrentInfo(
|
||||
path=filepath,
|
||||
name=name,
|
||||
trackers=trackers,
|
||||
size=size,
|
||||
files=files,
|
||||
info_hash=info_hash,
|
||||
is_multi_file=is_multi_file,
|
||||
)
|
||||
|
||||
|
||||
def scan_torrent_directories(paths: list[str]) -> Iterator[Path]:
|
||||
"""Scan directories for .torrent files.
|
||||
|
||||
Args:
|
||||
paths: List of directory paths or glob patterns to scan
|
||||
|
||||
Yields:
|
||||
Path objects for each .torrent file found
|
||||
|
||||
"""
|
||||
for pattern in paths:
|
||||
for torrent_dir in _expand_path_pattern(pattern):
|
||||
if torrent_dir.is_dir():
|
||||
yield from torrent_dir.glob("*.torrent")
|
||||
|
||||
|
||||
def find_torrents_with_tracker(
|
||||
tracker_domain: str, paths: list[str]
|
||||
) -> list[TorrentInfo]:
|
||||
"""Find all torrents that have a specific tracker domain.
|
||||
|
||||
Args:
|
||||
tracker_domain: Domain to search for in tracker URLs (e.g., "hdbits.org")
|
||||
paths: List of directory paths or glob patterns to scan
|
||||
|
||||
Returns:
|
||||
List of TorrentInfo objects for matching torrents
|
||||
|
||||
"""
|
||||
matching_torrents = []
|
||||
|
||||
for torrent_path in scan_torrent_directories(paths):
|
||||
info = parse_torrent(torrent_path)
|
||||
if info and info.has_tracker(tracker_domain):
|
||||
matching_torrents.append(info)
|
||||
|
||||
return matching_torrents
|
||||
|
||||
|
||||
def format_size(size_bytes: int | None) -> str:
|
||||
"""Format bytes as human-readable size."""
|
||||
if size_bytes is None:
|
||||
return "Unknown"
|
||||
|
||||
for unit in ["B", "KB", "MB", "GB", "TB"]:
|
||||
if size_bytes < 1024:
|
||||
return f"{size_bytes:.2f} {unit}"
|
||||
size_bytes /= 1024
|
||||
return f"{size_bytes:.2f} PB"
|
||||
|
||||
|
||||
def main() -> None:
|
||||
"""Run the torrent scanner command-line workflow."""
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Scan and manage torrent files",
|
||||
formatter_class=argparse.RawDescriptionHelpFormatter,
|
||||
epilog="""
|
||||
Examples:
|
||||
%(prog)s /path/to/torrents*/.torrents/
|
||||
%(prog)s /mnt/disk1/torrents/.torrents/ /mnt/disk2/torrents/.torrents/
|
||||
%(prog)s /torrents*/.torrents/ --tracker hdbits.org
|
||||
%(prog)s /torrents*/.torrents/ --dry
|
||||
""",
|
||||
)
|
||||
parser.add_argument(
|
||||
"paths",
|
||||
nargs="+",
|
||||
help="Directories or glob patterns containing .torrent files",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--dry",
|
||||
action="store_true",
|
||||
help="Dry run - show what would be done without making changes",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--tracker",
|
||||
default="hdbits.org",
|
||||
help="Tracker domain to filter by (default: hdbits.org)",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
dry_run = args.dry
|
||||
tracker_domain = args.tracker
|
||||
|
||||
# Expand glob patterns
|
||||
expanded_paths = []
|
||||
for pattern in args.paths:
|
||||
matches = [str(path) for path in _expand_path_pattern(pattern)]
|
||||
if matches:
|
||||
expanded_paths.extend(matches)
|
||||
else:
|
||||
expanded_paths.append(pattern)
|
||||
|
||||
if dry_run:
|
||||
print("=" * 60)
|
||||
print("DRY RUN MODE - No changes will be made")
|
||||
print("=" * 60)
|
||||
|
||||
print("Scanning for torrents...")
|
||||
print(f"Search paths: {expanded_paths}")
|
||||
print("-" * 60)
|
||||
|
||||
# Parse all torrents
|
||||
all_torrents: list[TorrentInfo] = []
|
||||
for torrent_path in scan_torrent_directories(expanded_paths):
|
||||
info = parse_torrent(torrent_path)
|
||||
if info:
|
||||
all_torrents.append(info)
|
||||
|
||||
# Separate by tracker
|
||||
with_hdbits = [t for t in all_torrents if t.has_tracker(tracker_domain)]
|
||||
without_hdbits = [t for t in all_torrents if not t.has_tracker(tracker_domain)]
|
||||
|
||||
# Print stats
|
||||
print(f"\n{'=' * 60}")
|
||||
print("SUMMARY")
|
||||
print(f"{'=' * 60}")
|
||||
print(f"Total torrents scanned: {len(all_torrents)}")
|
||||
print(f"With {tracker_domain}: {len(with_hdbits)}")
|
||||
print(f"Without {tracker_domain}: {len(without_hdbits)}")
|
||||
|
||||
# Add hdbits torrents to rtorrent
|
||||
if with_hdbits:
|
||||
print(f"\n{'=' * 60}")
|
||||
print("VERIFYING DOWNLOADS & ADDING TO RTORRENT")
|
||||
print(f"{'=' * 60}")
|
||||
|
||||
# First, verify which torrents have their data
|
||||
verified = []
|
||||
missing_data = []
|
||||
|
||||
for torrent in with_hdbits:
|
||||
exists, message = torrent.verify_download_exists()
|
||||
if exists:
|
||||
verified.append(torrent)
|
||||
else:
|
||||
missing_data.append((torrent, message))
|
||||
|
||||
print("\nVerification results:")
|
||||
print(f" Downloads found: {len(verified)}")
|
||||
print(f" Downloads missing: {len(missing_data)}")
|
||||
|
||||
# Report missing downloads
|
||||
if missing_data:
|
||||
print(f"\n{'=' * 60}")
|
||||
print("TORRENTS WITH MISSING DATA (will not add)")
|
||||
print(f"{'=' * 60}")
|
||||
for torrent, message in missing_data:
|
||||
print(f"\n Name: {torrent.name}")
|
||||
print(f" Torrent: {torrent.path}")
|
||||
print(f" Reason: {message}")
|
||||
|
||||
# Now add verified torrents to rtorrent
|
||||
if verified:
|
||||
print(f"\n{'=' * 60}")
|
||||
print(f"ADDING {len(verified)} VERIFIED TORRENTS TO RTORRENT")
|
||||
print(f"{'=' * 60}")
|
||||
|
||||
client = RTorrentClient()
|
||||
loaded_hashes = client.get_loaded_hashes()
|
||||
print(f"Currently loaded in rtorrent: {len(loaded_hashes)} torrents")
|
||||
|
||||
added = 0
|
||||
skipped = 0
|
||||
failed = 0
|
||||
|
||||
for torrent in verified:
|
||||
if torrent.info_hash and torrent.info_hash in loaded_hashes:
|
||||
print(f"Skipping (already loaded): {torrent.name}")
|
||||
skipped += 1
|
||||
else:
|
||||
download_dir = torrent.get_download_directory()
|
||||
if dry_run:
|
||||
print(f"Would add: {torrent.name}")
|
||||
print(f" Download dir: {download_dir}")
|
||||
added += 1
|
||||
else:
|
||||
print(f"Adding: {torrent.name}")
|
||||
print(f" Download dir: {download_dir}")
|
||||
if client.load_torrent(torrent.path, download_dir):
|
||||
added += 1
|
||||
else:
|
||||
failed += 1
|
||||
|
||||
if dry_run:
|
||||
print(f"\nDry run: {added} would be added, {skipped} already loaded")
|
||||
else:
|
||||
print(
|
||||
f"\nRtorrent results: {added} added, "
|
||||
f"{skipped} skipped, {failed} failed"
|
||||
)
|
||||
|
||||
# Clean up unregistered torrents from rtorrent
|
||||
print(f"\n{'=' * 60}")
|
||||
print("CHECKING FOR UNREGISTERED TORRENTS")
|
||||
print(f"{'=' * 60}")
|
||||
|
||||
client = RTorrentClient()
|
||||
unregistered = client.get_unregistered_torrents()
|
||||
|
||||
if unregistered:
|
||||
print(f"Found {len(unregistered)} unregistered torrent(s):\n")
|
||||
|
||||
removed_from_rtorrent = 0
|
||||
removed_torrent_files = 0
|
||||
removed_downloads = 0
|
||||
|
||||
for torrent_info in unregistered:
|
||||
# Determine the download path (base_path is the actual file/folder)
|
||||
download_path = (
|
||||
Path(torrent_info["base_path"]) if torrent_info["base_path"] else None
|
||||
)
|
||||
|
||||
if dry_run:
|
||||
status = "[DRY]"
|
||||
if download_path:
|
||||
print(f" {status} {download_path}")
|
||||
else:
|
||||
print(f" {status} {torrent_info['name']} (no data path)")
|
||||
# Remove from rtorrent (keeps downloaded files)
|
||||
elif client.remove_torrent(torrent_info["hash"]):
|
||||
removed_from_rtorrent += 1
|
||||
|
||||
# Delete the .torrent file if it exists
|
||||
tied_file = torrent_info["tied_file"]
|
||||
if tied_file:
|
||||
torrent_file = Path(tied_file)
|
||||
if torrent_file.exists():
|
||||
try:
|
||||
torrent_file.unlink()
|
||||
removed_torrent_files += 1
|
||||
except OSError:
|
||||
pass
|
||||
|
||||
# Delete the downloaded files
|
||||
if download_path and download_path.exists():
|
||||
try:
|
||||
if download_path.is_dir():
|
||||
shutil.rmtree(download_path)
|
||||
else:
|
||||
download_path.unlink()
|
||||
removed_downloads += 1
|
||||
print(f" [DEL] {download_path}")
|
||||
except OSError as e:
|
||||
print(f" [ERR] {download_path}: {e}")
|
||||
else:
|
||||
print(f" [DEL] {torrent_info['name']} (no data)")
|
||||
else:
|
||||
print(f" [ERR] {torrent_info['name']}: failed to remove from rtorrent")
|
||||
|
||||
print()
|
||||
if dry_run:
|
||||
print(
|
||||
f"Dry run: {len(unregistered)} would be removed "
|
||||
"(rtorrent + .torrent + downloads)"
|
||||
)
|
||||
else:
|
||||
print(
|
||||
f"Cleanup: {removed_from_rtorrent} from rtorrent, "
|
||||
f"{removed_torrent_files} .torrents, {removed_downloads} downloads"
|
||||
)
|
||||
else:
|
||||
print("No unregistered torrents found.")
|
||||
|
||||
# List torrents without hdbits.org
|
||||
if without_hdbits:
|
||||
print(f"\n{'=' * 60}")
|
||||
print(f"TORRENTS WITHOUT {tracker_domain.upper()}")
|
||||
print(f"{'=' * 60}")
|
||||
for torrent in without_hdbits:
|
||||
print(f"\nName: {torrent.name}")
|
||||
print(f"Path: {torrent.path}")
|
||||
print(f"Size: {format_size(torrent.size)}")
|
||||
if torrent.trackers:
|
||||
print("Trackers:")
|
||||
for tracker in torrent.trackers:
|
||||
print(f" - {tracker}")
|
||||
else:
|
||||
print("Trackers: (none)")
|
||||
|
||||
# Remove the non-hdbits torrent files
|
||||
print(f"\n{'=' * 60}")
|
||||
if dry_run:
|
||||
print(f"WOULD REMOVE {len(without_hdbits)} TORRENT FILE(S)")
|
||||
print(f"{'=' * 60}")
|
||||
for torrent in without_hdbits:
|
||||
print(f"Would remove: {torrent.path}")
|
||||
else:
|
||||
print(f"REMOVING {len(without_hdbits)} TORRENT FILE(S)")
|
||||
print(f"{'=' * 60}")
|
||||
for torrent in without_hdbits:
|
||||
try:
|
||||
torrent.path.unlink()
|
||||
print(f"Removed: {torrent.path}")
|
||||
except OSError as e:
|
||||
print(f"Failed to remove {torrent.path}: {e}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
Reference in New Issue
Block a user