Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 LeoVasanko |
0ff5c6b526 | ||
|
LeoVasanko
|
2aed176c9e | ||
|
LeoVasanko
|
9ff22016d1 | ||
|
LeoVasanko
|
97bde49296 | ||
|
LeoVasanko
|
4f97a6592c | ||
|
LeoVasanko
|
7e86efeb9f | ||
|
LeoVasanko
|
580ebac06c | ||
|
LeoVasanko
|
4d6735f609 | ||
|
LeoVasanko
|
6c0de19ae8 | ||
|
LeoVasanko
|
91a16f56c5 | ||
|
LeoVasanko
|
cc2cc23b3b | ||
|
LeoVasanko
|
d0ce619db7 | ||
|
LeoVasanko
|
1f5e52505f | ||
|
LeoVasanko
|
e8e56ce2ea | ||
|
LeoVasanko
|
aae8d58c9f | ||
|
LeoVasanko
|
c337651020 | ||
|
LeoVasanko
|
b248241af0 | ||
|
LeoVasanko
|
4bccf6855e | ||
|
LeoVasanko
|
e0c1b37c0b | ||
|
LeoVasanko
|
b004fcd644 | ||
|
LeoVasanko
|
0c7fe15635 | ||
|
LeoVasanko
|
2be3b32586 | ||
|
LeoVasanko
|
867132f26b | ||
|
LeoVasanko
|
4522b8fa40 | ||
|
LeoVasanko
|
2d221f6204 | ||
|
LeoVasanko
|
626dc1df8f | ||
|
LeoVasanko
|
02396f4482 | ||
|
LeoVasanko
|
7724290921 | ||
|
LeoVasanko
|
3b1804b093 | ||
|
LeoVasanko
|
4cd8dbfc73 | ||
|
LeoVasanko
|
dc4bdf6efc | ||
|
LeoVasanko
|
a458bded09 | ||
|
LeoVasanko
|
3a4745389e | ||
|
LeoVasanko
|
4eea3ae3af | ||
|
LeoVasanko
|
69583fb9fe | ||
|
LeoVasanko
|
b57b7060ec | ||
|
LeoVasanko
|
3f27a0a292 | ||
|
LeoVasanko
|
b30d909a23 | ||
|
LeoVasanko
|
13fecd2118 | ||
|
LeoVasanko
|
11a138e19f | ||
|
LeoVasanko
|
ebd5911a38 | ||
|
LeoVasanko
|
db57125953 | ||
|
LeoVasanko
|
986e28c220 | ||
|
LeoVasanko
|
33a4a76364 | ||
|
LeoVasanko
|
9fb4b5a681 | ||
|
LeoVasanko
|
0c1349b037 | ||
|
LeoVasanko
|
54f8c8e09b | ||
|
LeoVasanko
|
78f4ddb2f0 | ||
|
LeoVasanko
|
e6a0c57446 | ||
|
LeoVasanko
|
d6d07db2c5 | ||
|
LeoVasanko
|
38af57218a | ||
|
LeoVasanko
|
eb2e8f8273 | ||
|
LeoVasanko
|
792b9e7aa9 | ||
|
LeoVasanko
|
4c6ab3dde6 | ||
|
LeoVasanko
|
9d70f17587 | ||
|
LeoVasanko
|
029bfe105e | ||
|
LeoVasanko
|
62031fd5dd | ||
|
LeoVasanko
|
13cf716bb1 | ||
|
LeoVasanko
|
cbd50cfece | ||
|
LeoVasanko
|
85ef968cd6 | ||
|
LeoVasanko
|
7631c9f0a3 | ||
|
LeoVasanko
|
d7d03754d1 | ||
|
LeoVasanko
|
65fec6c519 | ||
|
LeoVasanko
|
dc55445ae0 | ||
|
LeoVasanko
|
b133ad6dd6 | ||
|
LeoVasanko
|
4413c7efdf | ||
|
LeoVasanko
|
2f533eaf09 | ||
|
LeoVasanko
|
1d46843c76 | ||
|
LeoVasanko
|
d3e2196c83 | ||
|
LeoVasanko
|
b6e6e46cfb | ||
|
LeoVasanko
|
7a4544731d | ||
|
LeoVasanko
|
fd1987c9b3 | ||
|
LeoVasanko
|
85a306296f | ||
|
LeoVasanko
|
2b9c7635d3 | ||
|
LeoVasanko
|
7e8e0a2ea7 | ||
|
LeoVasanko
|
8fc5dd7b9b | ||
|
LeoVasanko
|
fbebddeaa9 | ||
|
LeoVasanko
|
31895065f8 | ||
|
LeoVasanko
|
447a565b05 | ||
|
LeoVasanko
|
399aa95d44 | ||
|
LeoVasanko
|
f793d21c5e | ||
|
LeoVasanko
|
fb3e6d1a04 | ||
|
LeoVasanko
|
fd75a260b5 | ||
|
LeoVasanko
|
6058853341 | ||
|
LeoVasanko
|
9adc48479f | ||
|
LeoVasanko
|
864492b897 | ||
|
LeoVasanko
|
515c6e1435 | ||
|
LeoVasanko
|
daa1670653 | ||
|
LeoVasanko
|
e3fbce8ece | ||
|
LeoVasanko
|
775dc3f65a | ||
|
LeoVasanko
|
d21c3edbfc | ||
|
LeoVasanko
|
794e1ba26e | ||
|
LeoVasanko
|
b8d2b9f32c | ||
|
LeoVasanko
|
ad03216e93 | ||
|
LeoVasanko
|
1d64d1e653 | ||
|
LeoVasanko
|
72e722c094 | ||
|
LeoVasanko
|
22c4f0e752 | ||
|
LeoVasanko
|
5101a5c5bf | ||
|
LeoVasanko
|
c801fdc929 | ||
|
LeoVasanko
|
8df6594432 | ||
|
LeoVasanko
|
7743639812 | ||
|
LeoVasanko
|
f659f5f6be | ||
|
LeoVasanko
|
f962d70e3b | ||
|
LeoVasanko
|
6910ccad73 | ||
|
LeoVasanko
|
2060dc815c | ||
|
LeoVasanko
|
ffa7200a6e | ||
|
LeoVasanko
|
bdac75e70a | ||
|
LeoVasanko
|
a116d78951 | ||
|
LeoVasanko
|
825379ca2a | ||
|
LeoVasanko
|
ddf323bf41 | ||
|
LeoVasanko
|
f708e1dbca | ||
|
LeoVasanko
|
1d0bc3f59d | ||
|
LeoVasanko
|
60d5155fd2 | ||
|
LeoVasanko
|
3518ac9ac7 | ||
|
LeoVasanko
|
5c2433b766 | ||
|
LeoVasanko
|
2959f971bc | ||
|
LeoVasanko
|
8ee22de060 | ||
|
LeoVasanko
|
9be1491f0e | ||
|
LeoVasanko
|
29c1dc64ed | ||
|
LeoVasanko
|
a27958117f | ||
|
LeoVasanko
|
56fd5f854d | ||
|
LeoVasanko
|
932aee4404 | ||
|
LeoVasanko
|
ca1c0d5a6f | ||
|
LeoVasanko
|
9cbc4ab59d | ||
|
LeoVasanko
|
7aa2abbf8f | ||
|
LeoVasanko
|
eddb3f22f3 | ||
|
LeoVasanko
|
1702281dbf | ||
|
LeoVasanko
|
38b894a789 | ||
|
LeoVasanko
|
06409cdaac | ||
|
LeoVasanko
|
7ba6094360 | ||
|
LeoVasanko
|
c59ab2f058 | ||
|
LeoVasanko
|
078e80591b | ||
|
LeoVasanko
|
6563eebdba | ||
|
LeoVasanko
|
cac74ebb6b | ||
|
LeoVasanko
|
8b1bb6f994 | ||
|
LeoVasanko
|
3173a113b6 | ||
|
LeoVasanko
|
a21f919601 | ||
|
LeoVasanko
|
158b5f1961 | ||
|
LeoVasanko
|
f9ce0a4f3b | ||
|
LeoVasanko
|
2d595f8c15 | ||
|
LeoVasanko
|
b1fc8e24d7 | ||
|
LeoVasanko
|
c5cf799f68 | ||
|
LeoVasanko
|
a5edc7b3b6 | ||
|
LeoVasanko
|
09ebc63690 | ||
|
LeoVasanko
|
2868843028 | ||
|
LeoVasanko
|
6fcebaea3f | ||
|
LeoVasanko
|
4a48d08a19 | ||
|
LeoVasanko
|
e3e29251ca | ||
|
LeoVasanko
|
8affc41289 | ||
|
LeoVasanko
|
2de4717230 | ||
|
LeoVasanko
|
563e8fcaf2 | ||
|
LeoVasanko
|
921a5484a2 | ||
|
LeoVasanko
|
0e2e52fa45 | ||
|
LeoVasanko
|
075848f782 | ||
|
LeoVasanko
|
7b8899af92 | ||
|
LeoVasanko
|
6d2ae104d7 | ||
|
LeoVasanko
|
b7fc543a83 | ||
|
LeoVasanko
|
b868033ddc | ||
|
LeoVasanko
|
8aad64cced | ||
|
LeoVasanko
|
319163ee7e | ||
|
LeoVasanko
|
87b16b7144 | ||
|
LeoVasanko
|
20ae6501f2 | ||
|
LeoVasanko
|
a16fe88114 | ||
|
LeoVasanko
|
c77598adc7 | ||
|
LeoVasanko
|
29f8fac013 | ||
|
LeoVasanko
|
6199e5a69e | ||
|
LeoVasanko
|
375b4b6bdb | ||
|
LeoVasanko
|
fdb3e42d6f | ||
|
LeoVasanko
|
51a6a16221 | ||
|
LeoVasanko
|
0798e24d24 | ||
|
LeoVasanko
|
3be2d08ac9 | ||
|
LeoVasanko
|
b7d5b23ae6 | ||
|
LeoVasanko
|
6eaa1c1a8b | ||
|
LeoVasanko
|
f341d22aa0 | ||
|
LeoVasanko
|
1a479ceb24 | ||
|
LeoVasanko
|
ff553d018a | ||
|
LeoVasanko
|
c807d48a13 | ||
|
LeoVasanko
|
9c383c1c8b | ||
|
LeoVasanko
|
462e995adc | ||
|
LeoVasanko
|
ea069b98da | ||
|
LeoVasanko
|
deb5419c47 | ||
|
LeoVasanko
|
242b62784c | ||
|
LeoVasanko
|
f78229bd30 | ||
|
LeoVasanko
|
7f4bc8efa4 | ||
|
LeoVasanko
|
3100010335 | ||
|
LeoVasanko
|
7556bb7f4f | ||
|
LeoVasanko
|
1a1a21712e | ||
|
LeoVasanko
|
f0e6162f02 | ||
|
LeoVasanko
|
b4e8fad090 | ||
|
LeoVasanko
|
11f8de2df5 | ||
|
LeoVasanko
|
81f08e7760 | ||
|
LeoVasanko
|
1d65a57fdf | ||
|
LeoVasanko
|
e175b39f35 | ||
|
LeoVasanko
|
178d22c05c | ||
|
LeoVasanko
|
dfd3ef1dad | ||
|
LeoVasanko
|
512ed91b31 | ||
|
LeoVasanko
|
3b074c02ed | ||
|
LeoVasanko
|
58e5d3ef2b | ||
|
LeoVasanko
|
5769747a95 |
@@ -1,7 +1,8 @@
|
||||
.*
|
||||
!.gitignore
|
||||
*.lock
|
||||
*.kantadb
|
||||
/localhost
|
||||
dbip-*.mmdb*
|
||||
/pagerite/frontend-build
|
||||
package-lock.json
|
||||
|
||||
|
||||
@@ -5,288 +5,56 @@
|
||||
|
||||
Please instead ask the user to see from dev tools what you need, e.g. to look up something in DOM or log. Use console.log for debugging where needed (and otherwise for permanently kept useful messages in the app).
|
||||
|
||||
## What this is
|
||||
|
||||
Pagerite: a single-user CMS/blog. FastAPI serves HTML rendered in Python
|
||||
with html5tagger; content is persisted in a kanta database and rendered on
|
||||
the fly per request. Vue is used only for interactive bits (editing tools),
|
||||
not for the public pages. See `docs/design-principles.md` for the design.
|
||||
|
||||
## Layout
|
||||
|
||||
- `pagerite/` — the Python backend package (hatchling build target).
|
||||
- Server run by CLI entry point `uv run pagerite` (no auto reloads, build needed)
|
||||
- Dev mode `scripts/devserver.py` (which the user mostly uses for auto reloads, no build needed)
|
||||
- Avoid running the server yourself, ask the user to test
|
||||
- `app.py` — the FastAPI app. FastAPI's built-in API docs are disabled
|
||||
(`docs_url`/`redoc_url`/`openapi_url=None`) because `/docs` belongs to
|
||||
our content. Our own routes (content pages, `/_api/...`, `/_f/...`) are
|
||||
registered BEFORE `frontend.route(app, "/")` is called: fastapi-vue
|
||||
inserts its file routes at the position where
|
||||
`route()` was called (during `load()` in the lifespan), so anything
|
||||
defined earlier wins. The one exception is the content catch-all
|
||||
`/{path:path}`, registered AFTER `frontend.route()` so that built
|
||||
frontend assets still take priority over content slugs. The `Frontend`
|
||||
is constructed with `spa=False` explicitly: it only serves the built
|
||||
files without a catch-all. The build mirrors the URL space — hashed
|
||||
immutable assets under `/_assets/`, `favicon.ico` at the site root —
|
||||
and an `index.html` in the build would become a `/` route, so leave it
|
||||
out of the build to keep `/` ours.
|
||||
- `data.py` — msgspec Structs for the kanta database. The site structure
|
||||
is a tree: `Data.menu` maps top-level slugs to `Node`s, each with
|
||||
`children` keyed by slug — the URL path is the slug chain. The front
|
||||
page is whichever top-level node has slug "" (parallel to the other
|
||||
main level pages, not their parent); it cannot have children, and
|
||||
renaming its slug away leaves no front page ("/" redirects to the
|
||||
first nav item). `Node.content` is
|
||||
the Markdown page, or None for a pure category label whose URL renders
|
||||
a placeholder page (while nav links to it point at its first child);
|
||||
every label's title and slug are editable. Siblings order by the fractional `Node.order` key: a moved
|
||||
item gets a fresh key relative to its new siblings, all others keep
|
||||
theirs. `resolve`/`find_slot` walk the tree by path; moves are slot
|
||||
detach/attach carrying the whole subtree. Legacy flat `Data.pages`
|
||||
(pre-tree databases) migrates into `menu` on startup. The app owns
|
||||
the `Data` object; reads are plain attribute access, writes in
|
||||
`kanta.transaction(...)`.
|
||||
`Data.files` is a content-addressed store (blake3[:12] + extension)
|
||||
mapping file names to bytes, served at `/_f/{name}` with immutable
|
||||
caching; pages reference files by absolute `/_f/` URLs so hierarchy
|
||||
moves never break them. `Node.banner` is a raw trusted HTML snippet
|
||||
for the header banner (img, styled div, canvas+script...); empty
|
||||
inherits from the node's ancestors (front page last). It is rendered
|
||||
AFTER the banner design's artwork, so author code (e.g. a `<style>`
|
||||
override) always wins over the design's own styles.
|
||||
`Node.banner_design` picks a banner design: a theme folder name whose
|
||||
`banner.css` styles it and whose `banner.html` (arbitrary markup:
|
||||
canvas + style + script) or `banner.svg` supplies the inline artwork
|
||||
(wrapped in `div[data-design]`); "" = explicitly no design, None =
|
||||
inherit (nearest ancestor, front page last, then the active theme's
|
||||
own design if it ships banner.css/banner.svg/banner.html). The design's banner.css
|
||||
is linked in `<head>` (id `pagerite-banner`) between the theme and the
|
||||
custom CSS.
|
||||
`Data.version` is bumped on every write
|
||||
and embedded in page ETags so nav-affecting changes invalidate caches.
|
||||
`Data.brand` is the site name (header link + `<title>` suffix), editable
|
||||
in the site editor via `/_api/settings`; empty = no header link and
|
||||
no `<title>` suffix. `Data.brand_html` is raw trusted HTML replacing the
|
||||
brand link entirely (rendered in a `#brand` div on top of the banner,
|
||||
next to the nav) — site-wide, not per-page like banners; edited in the
|
||||
site editor with image/video upload into `Data.files`. `Data.theme` is
|
||||
the active theme name (empty =
|
||||
none/base only); themes are folders in `pagerite/themes/{name}`
|
||||
containing `theme.css` and/or `banner.css` (+ `banner.svg` artwork and
|
||||
any extra assets the CSS references, like summer's `grass.svg`),
|
||||
served by the backend at `/_themes/{name}/...` — read from disk per
|
||||
request (etag by mtime), never built, so on-disk edits show on the
|
||||
next page load even in prod. The theme selector and banner-design
|
||||
selector enumerate these folders via `GET /_api/settings`.
|
||||
`Data.custom_css` is raw trusted CSS injected inline in every page
|
||||
`<head>` (id `pagerite-user`) and swapped during fetch-navigation;
|
||||
editable in the site editor. Font picks (heading/body/brand) in the
|
||||
site editor are stored as plain `:root` rows in `custom_css`
|
||||
(`--font-body: var(--font-source-sans);` format — parsed out and
|
||||
rewritten on change, the `:root` block added/removed as needed),
|
||||
referencing the per-family variables (`--font-source-sans` etc.) from
|
||||
pagerite.css;
|
||||
the base stylesheet's `--font-brand` defaults to `var(--font-heading)`.
|
||||
`Data.favicon` names a file in the content-addressed `files` store,
|
||||
uploaded/cleared in the site editor via `PUT`/`DELETE
|
||||
/_api/settings/favicon`; when set it is linked as `<link rel="icon">`
|
||||
on every page, otherwise browsers fall back to the build's
|
||||
`/favicon.ico` by convention.
|
||||
- `markdown.py` — markdown-it-py renderer (html passthrough + attrs,
|
||||
footnote, deflist, tasklists, admon, gfm_autolink, sub/superscript
|
||||
plugins; typographer + breaks on). Custom
|
||||
image rule: relative srcs resolve against the page path; an image
|
||||
standing alone in its paragraph becomes a figure (captioned when
|
||||
titled), while inline-with-text images and raw <img> HTML stay plain.
|
||||
A `{dates}` line expands to the article's
|
||||
published/updated dateline (`p.dateline`, from `Node.created`/
|
||||
`modified`; left literal in previews of unsaved pages).
|
||||
- `views.py` — the shared page layout as an html5tagger `Template` with
|
||||
placeholders (`Title`, `Brand`, `Banner`, `Nav`, `Sidebar`, `Main`), nav
|
||||
rendering straight from the `Data.menu` tree (siblings sorted by
|
||||
`Node.order`; nav links to content-less labels point at their first
|
||||
child via `first_leaf`, the first published descendant with content),
|
||||
and page/404 rendering. If the markdown contains its own h1, the page title
|
||||
is NOT rendered as an additional h1 (it still supplies <title> and nav
|
||||
labels). The navbar holds
|
||||
top-level items only; the current section's subitems go to a left
|
||||
`#sidebar` as a nested list (the section's direct children plain,
|
||||
deeper levels indented with article-list-style markers), which is
|
||||
rendered when the section offers at least two
|
||||
published items, or exactly one while viewing anything other than that
|
||||
only page — the section index, a 404, a grandchild (so those pages can
|
||||
reach the child), and also on that only page itself when it has
|
||||
published children of its own; no aside element at all on the front
|
||||
page, leaf
|
||||
pages and the sole childless page of a one-page section. Also,
|
||||
category labels are nodes without content — None *or* empty markdown —
|
||||
and their nav links point at their first child page. Dynamic regions have stable ids
|
||||
(`#page-banner`, `#nav`, `#sidebar`, `#main`) for fetch-navigation swaps
|
||||
(`#sidebar` may be absent on either side of a swap).
|
||||
- `seed.py` — demo content written on startup for paths missing from the
|
||||
database (never overwrites existing pages).
|
||||
- `frontend/src/` — the Vue editor and public-page entries.
|
||||
- `main.js` — Vue editor app entry, mounts the tabbed EditorShell.
|
||||
- `pagerite.js` — public page entry; runs fetch-navigation, scroll-reveal,
|
||||
OverlayScrollbars on `document.body` (floating, auto-hiding scrollbars
|
||||
that never reserve layout space or shift the page when appearing;
|
||||
native scroll APIs like `window.scrollTo` keep working; themed via the
|
||||
`--os-*` variables in pagerite.css),
|
||||
brand shrink-to-fit (the themed size is the maximum; JS reduces the
|
||||
font-size so a long brand or narrow viewport still fits one line),
|
||||
code copy buttons, and the auth check. It first probes `GET /auth/api/settings`
|
||||
to detect whether Paskia SSO is available, then `GET /_api/settings` to
|
||||
learn the current session's admin status. The same reverse proxy that
|
||||
gates `/_api` returns 401 for anonymous users, 403 for users without
|
||||
the admin permission, and 200 for admins. When Paskia is detected, a
|
||||
🔑 login button (anonymous) or 🔐 profile button (logged in) is shown in
|
||||
the banner corner; both open Paskia's iframe dialog via `showAuthIframe`
|
||||
instead of navigating away. Admins also get the 🖊️ page/banner edit pens
|
||||
and a ⚙️ site-settings pen (asset URLs from the
|
||||
`pagerite:editor-src`/`-css` meta tags). If no Paskia SSO is
|
||||
detected (dev/no proxy), editing is left open. Pages themselves render
|
||||
identically for everyone; the real gate is the auth proxy in front of
|
||||
all of `/_api`. The backend links the stylesheets in a fixed order —
|
||||
base (Vite build), theme, banner design, custom CSS last — each with
|
||||
a stable id so the site editor can swap them in place.
|
||||
- `assets/` — shared styles and data files built by Vite and served hashed
|
||||
under `/_assets/`: `pagerite.css` (base layout + conservative
|
||||
variables), `pygments.css`,
|
||||
and `fonts/` (self-hosted Source
|
||||
Sans 3/Source Serif 4/Fraunces/Literata/Cormorant/Playfair
|
||||
Display/Inter/Montserrat/Fira Code/Cause/Exo 2/New Rocker
|
||||
variable woff2). The `::view-transition*` block at the end of `pagerite.css` (from
|
||||
termotohtori.fi) is fragile — do not tweak. Themes are NOT built:
|
||||
`pagerite/themes/{name}/theme.css` (theme overrides and font picks:
|
||||
`purple` = dark dusk palette with Fraunces/Literata and a tilted
|
||||
oversized gradient brand; `corporate` = light-first with automatic
|
||||
`prefers-color-scheme` dark mode, Montserrat/Inter and a huge solid
|
||||
brand; `nitro` = racing/HUD style following `prefers-color-scheme`
|
||||
(warm light-grey page, deep violet in dark), Montserrat/Literata,
|
||||
black as an accent only, a straight orange blade under the banner, and
|
||||
an orange racing-tab nav clipped with a bezier `shape()`; `summer` =
|
||||
light playful meadow, one palette sampled from its illustrated
|
||||
`banner.svg` (sky/grass/sun/flower pink), Fraunces/Literata, a tilted
|
||||
gradient brand, flower bullets, and a layered-parallax banner (sun
|
||||
rises, clouds drift, nearer hills move less) with idle animations
|
||||
(swaying flowers, floating clouds, breathing sun glow) wrapped in
|
||||
`prefers-reduced-motion: no-preference`) and the
|
||||
companion `banner.css` banner designs are served by the backend.
|
||||
- Vite builds ES-module `.js` outputs; the backend renders `<script
|
||||
type="module">` for them (module scripts defer by default).
|
||||
- The database file is `pagerite.kantadb` in the cwd (`PAGERITE_DB`
|
||||
overrides); gitignored. Do not delete it without asking.
|
||||
- `scripts/fastapi-vue/` — helper scripts from the fastapi-vue template
|
||||
(build hook etc.), do not edit.
|
||||
- `frontend/` — the Vue editor as a single tabbed `EditorShell.vue` mounted
|
||||
in a host div created inside the static document. The shell hosts four
|
||||
kept-alive tabs (ordered site-wide first — site, structure — then, after a
|
||||
visual break, the per-page tabs — article, banner): `PageEditor.vue`
|
||||
(CodeMirror + server-rendered preview over WebSocket `/_api/ws/editor`,
|
||||
previewing into the visible article; editor scroll drives the article
|
||||
scroll — while any editor is open the window scroll is locked
|
||||
(`body.editing`), the panel exactly fills the available window height, and
|
||||
only `#main` scrolls; a format bar offers Markdown helpers — bold/italic/code/link/
|
||||
table/image upload, with Ctrl/Cmd-B/I/S bindings — for the
|
||||
hard-to-remember syntax) — edits content and
|
||||
title only, never the path — `BannerEditor.vue`
|
||||
(per-page banner HTML + banner design selector, previewed into
|
||||
`#page-banner`), `SiteEditor.vue` (site brand + optional custom brand
|
||||
HTML with image/video upload + theme selector + font picker + favicon
|
||||
upload — clicking the preview tile picks a new one — +
|
||||
site-wide custom CSS, CSS injected into
|
||||
`<head id="pagerite-user">`), and `StructureEditor.vue` (the
|
||||
vue-draggable structure tree with
|
||||
always-editable title/slug inputs per row). Media uploads everywhere use
|
||||
🖼️ icon buttons (pasting into the editor works too). The article, banner and
|
||||
site-settings pens are shorthands that open the shell on the matching tab;
|
||||
once open, clicking a pen switches tabs (and retargets the editors to the
|
||||
current page) instead of closing/remounting. The ✕ in the tab bar closes
|
||||
the shell (Escape too); tabs have no close buttons of their own. Closing
|
||||
only HIDES the shell — the Vue app stays mounted, so page-editor state
|
||||
(unsaved text included) survives until a real page reload; saving there is
|
||||
explicit (💾/Ctrl+S) and refreshes the page regions in place. Admin panels
|
||||
never reload the page. In-place
|
||||
page re-rendering shared by the banner/site/structure tabs lives in
|
||||
`swapdoc.js` (`runScripts`/`loadPlain`: fetch a page, swap the dynamic
|
||||
regions, replaceState). Placeholder texts are reserved for showing the
|
||||
actual default in effect when a field is left empty (e.g. the pending
|
||||
row's slug derived from its title); labels and help are real elements or
|
||||
tooltips, never placeholders.
|
||||
Everything saves immediately as you edit (brand/title/CSS debounced,
|
||||
slug on commit since it renames the path), theme change swaps the
|
||||
stylesheet in place, tree rows navigate in place without transitions when
|
||||
focused, and the front page is a root-only row whose empty slug is
|
||||
editable like any other. Every
|
||||
non-empty list (and the root) ends with a non-draggable ➕ footer row
|
||||
(vuedraggable `#footer` slot): clicking it starts a new pending page at
|
||||
that level (its slug placeholder shows the slug derived live from the
|
||||
title being typed), and while dragging it is the list's "end of list" drop
|
||||
target. Committing a pending page PUTs it with empty markdown (creates
|
||||
an empty page that renders with its title — saving never deletes;
|
||||
deletion is the page editor's explicit choice: saving trimmed-empty
|
||||
text issues a REST DELETE), then switches to the page editor tab for
|
||||
the actual writing. Dropping ON the lower part of a row moves the page
|
||||
under that row (the child list's container invisibly overlaps its own
|
||||
row's bottom via negative margin — Sortable inserts it as the first child
|
||||
natively), while a row's exposed top edge inserts a sibling before it. Row
|
||||
indentation is structural (each nested list margin-indents itself), so a
|
||||
dragged row previews its whole subtree at the target list's depth. The
|
||||
shell is dynamic-imported onto the content page by pagerite.js when an edit
|
||||
pen is clicked (the pens are injected by pagerite.js after the session
|
||||
validates; they carry `data-editor-src`/`data-editor-css`/`data-editor-mode`).
|
||||
In dev, modules load from the Vite dev server (`PAGERITE_VITE_URL`),
|
||||
in prod from the hashed build assets resolved via
|
||||
`frontend-build/.vite/manifest.json`. `vite.config.js` sets
|
||||
`appType: 'mpa'` (no SPA fallback) and builds with `manifest: true`,
|
||||
`assetsDir: '_/assets'` (so the build mirrors the URL space;
|
||||
`frontend/public/favicon.ico` lands at the build root and is served at
|
||||
`/favicon.ico`). JS inputs are `src/main.js` and `src/pagerite.js`, plus
|
||||
`src/assets/pagerite.css` as a separate stylesheet entry; theme and
|
||||
banner-design CSS are NOT built — they live in `pagerite/themes/{name}/`
|
||||
and are served by the backend. There
|
||||
is no `index.html` source (it would shadow `/` and turn missing dev paths
|
||||
into an empty Vue shell). All outputs are ES modules. The build sets
|
||||
`preserveEntrySignatures: 'exports-only'` because main.js is consumed
|
||||
via dynamic `import()` for its `openEditor`/`closeEditor` exports — Vite
|
||||
app builds otherwise strip unused entry exports, leaving dead edit pens.
|
||||
In dev the backend links theme/banner-design stylesheets like in prod
|
||||
(`/_themes/...`); only the base CSS is Vite-injected from JS, and
|
||||
pagerite.js then re-appends the `#pagerite-theme`/`#pagerite-banner`/
|
||||
`#pagerite-user` elements to restore the canonical order (base < theme <
|
||||
design < custom CSS). Theme switches in the site editor simply swap the
|
||||
`#pagerite-theme` link href, identically in dev and prod.
|
||||
vite-plugin-fastapi.js has an
|
||||
auto-upgrade marker — edit `vite.config.js`, not the plugin.
|
||||
- `docs/` — design documentation.
|
||||
Pagerite is a CMS. See `docs` for the full design and implementation details. Key files for code changes:
|
||||
|
||||
- `pagerite/` — Python backend package (hatchling build target).
|
||||
- `app.py` — thin FastAPI assembly: lifespan, `FastAPI(...)`, router includes (route ordering: api/tracking/files routers, then `frontend.route(app, "/")`, then the pages catch-all last).
|
||||
- `state.py` — shared core, no routes: env-derived site constants, `data`/`kanta`, `analytics_store`, the fastapi-vue `frontend`, the render cache (`_html_response`, `_invalidate_pages`), the translator `dispatcher`, slug helpers, `@kanta.bootstrap` hooks.
|
||||
- `files.py` — `FileStore` (content-addressed, RAM-cached), image derivative helpers (`store_image`), file routes (`/_api/files`, `/_f/`, `/_themes/`, `/_fonts/`, favicon settings).
|
||||
- `api.py` — editor REST + WS: `/_api/pages`, `/_api/structure`, `/_api/settings`, `/_api/toggle-task`, `/_api/translations`, `/_api/ws/editor`, `/_translate/{key}`.
|
||||
- `tracking.py` — visit analytics: GeoIP, client enrichment, favicon fetch, `/_ws`, `/_api/ws/analytics`, the `/_a` page (docs/analytics.md).
|
||||
- `pages.py` — public content pages: `/`, `/sitemap.xml`, `/robots.txt`, the `/{path:path}` catch-all.
|
||||
- `feeds.py` — machine-readable exports: `/llms.txt`, `/feed.json` (JSON Feed 1.1), `/feed.xml` (RSS 2.0 + atom:link); all published articles, full content, linked from every page `<head>` and the sitemap, recorded in analytics.
|
||||
- `data.py` — msgspec Structs for the kanta database.
|
||||
- `chunks.py` — block-level Markdown chunking and content-hash keys for the chunk stores (docs/migrate.md).
|
||||
- `i18n.py` — language selection, translation assembly (chunks + overrides) and translated-edit recording (per-chunk user overrides in `Data.overrides`, per-language title overrides, refresh).
|
||||
- `translate.py` — translator service protocol (msgspec structs), the connected-client `Dispatcher` (job pipeline, result validation) and pending/store core for the `/_translate/{key}` WebSocket (docs/localization.md); api.py only registers the route.
|
||||
- `segments.py` — the translation round trip: fragments split into pure-prose wire segments (via markdown.make_md's verbatim parser; link- and formatting-carrying blocks stay whole, link/formatted texts inline, Markdown stripped) and translations spliced back by source offset, link/formatting markdown re-inserted at weight-mapped positions (docs/localization.md).
|
||||
- `migrations.py` — kanta migrations (`migrate_vN`); ALL schema/storage upgrades live here (raw state dict before struct decoding), never in the app lifespan: v1 moves legacy in-db file blobs to the on-disk store and rebuilds the legacy flat `pages` as the menu tree, v2 rewrites `/_f/{hash}.ext` image links to the extension-less form, backfills AVIF/WebP/JPEG derivatives on disk and drops the obsolete `version` field.
|
||||
- `markdown.py` — markdown-it-py renderer.
|
||||
- `views.py` — shared page layout and rendering; theme/user-font resolution across `THEME_DIRS` / `FONT_DIRS` (cwd, site, platform data roots, then built-in `pagerite/themes/`, see `docs/themes-and-assets.md`).
|
||||
- `seed.py` — demo content, written only on first database creation.
|
||||
- `analytics.py` — visit analytics collection (see `docs/analytics.md`). UA formatting/bot detection comes from the **uarite** package.
|
||||
- `frontend/src/` — Vue editor and public-page JS entries.
|
||||
- `main.js` — Vue editor app entry.
|
||||
- `analytics-main.js` — analytics page entry (mounts `AnalyticsView` at `/_a`).
|
||||
- `langselect-main.js` + `LangSelector.vue` — public language selector, imported on demand by pagerite.js on pages with more than one hreflang alternate (the editors' `LangSelect` flag dropdown).
|
||||
- `store.js` — the shared Pinia store (`useStore`, id `pagerite`) for cross-bundle UI state.
|
||||
- `pagerite.js` — public page entry.
|
||||
- `editorLang.js` + `LangSelect.vue` — the editor shell's shared language selection and its selector component (page + structure tabs; drives the page preview while the panel is open, via `swapdoc.setLangOverride`).
|
||||
- `reconnect.js` — shared WebSocket pacing for all sockets (staggered connect slots, stuck-CONNECTING watchdog, exponential backoff): bursts and rapid retries trip the browser's WebSocket throttling.
|
||||
- `assets/` — base CSS, Pygments styles, fonts.
|
||||
- `scripts/devserver.py` — dev server with auto reload (the user mostly uses this; avoid running the server yourself, ask the user to test).
|
||||
- `scripts/translator.py` — Seed-X translator service client for the `/_translate/{key}` socket (reference client, runs in its own uv env via PEP 723); stays connected full time, unloads the model after 60 s idle and reloads on the next job.
|
||||
- `scripts/llm_translator.py` — instruct-LLM translator service client (docs/llm-translation.md): speaks the `markdown`/`article`/`nav` job modes against an OpenAI Chat Completions endpoint or ollama's native `/api/chat` (its `/v1` ignores `think: false`); all LLM specifics (prompts, sampling, generation caps) live here, not in pagerite.
|
||||
- `scripts/import_translation.py` — import a human-made whole-article translation file into the fragment store (same `align_article` validation as article-mode results; run with the server stopped).
|
||||
|
||||
Server run by CLI entry point `uv run pagerite` (no auto reloads, build needed). Dev mode is `scripts/devserver.py` (auto reloads, no build needed).
|
||||
|
||||
## Toolchain
|
||||
|
||||
- Python >= 3.14, managed with **uv**. Dependencies: `fastapi[standard]`,
|
||||
`fastapi-vue`, `html5tagger`, `kanta`, `markdown-it-py`, `mdit-py-plugins`,
|
||||
`pygments`, `tracerite`; dev group has `httpx`. Run anything via
|
||||
`uv run ...` (the venv is `.venv`).
|
||||
- Python >= 3.14, managed with **uv**. Dependencies: `fastapi[standard]`, `fastapi-vue`, `html5tagger`, `kanta`, `markdown-it-py`, `mdit-py-plugins`, `platformdirs`, `pygments`, `tracerite`; dev group has `httpx`. Run anything via `uv run ...` (the venv is `.venv`).
|
||||
- Key libraries:
|
||||
- **html5tagger** — all HTML generation (`E`, `Document`, `Template`,
|
||||
`HTML` for trusted/raw HTML).
|
||||
- **html5tagger** — all HTML generation (`E`, `Document`, `Template`, `HTML` for trusted/raw HTML).
|
||||
- To create stand alone pages, begin with `doc = Document(...)` that gives a HTML5 page header
|
||||
- Chain with `doc.p("text").br`: every attribute access creates element to doc (returning self), calls add content to current element.
|
||||
- Closing tags are not used where optional, e.g. no `</p>` or `</li>` is ever included in output. Due to this proper "nesting" of content is NOT required and should be avoided. Where needed, () directly after tag define attributes and content INSIDE the element, then close the element. `with doc.ul:` and such may be used for larger chunks.
|
||||
- Prefer building directly on one builder with `with` blocks (recursing
|
||||
inside a with block for hierarchies) over preparing `E.` snippets into
|
||||
variables and composing them. Note `with doc.li:` alone fails (`li`
|
||||
has an optional end tag) — use `with doc.li.ul:` style chains, or
|
||||
`doc.li.a(...)` followed by a nested `with doc.ul:` block.
|
||||
- `Template(builder)` freezes a builder with **Capitalized** attribute
|
||||
placeholders (e.g. `E.Title`, `doc.main(E.Main, id="main")`); calling
|
||||
it fills the slots with escaping — pass `HTML(...)` for raw HTML.
|
||||
Passing a list to a template slot expands it; passing a list to a
|
||||
normal builder call does NOT (spread it: `E.ul(*items)`).
|
||||
- Prefer building directly on one builder with `with` blocks (recursing inside a with block for hierarchies) over preparing `E.` snippets into variables and composing them. Note `with doc.li:` alone fails (`li` has an optional end tag) — use `with doc.li.ul:` style chains, or `doc.li.a(...)` followed by a nested `with doc.ul:` block.
|
||||
- `Template(builder)` freezes a builder with **Capitalized** attribute placeholders (e.g. `E.Title`, `doc.main(E.Main, id="main")`); calling it fills the slots with escaping — pass `HTML(...)` for raw HTML. Passing a list to a template slot expands it; passing a list to a normal builder call does NOT (spread it: `E.ul(*items)`).
|
||||
- To create plain HTML snippets use `E.div(E.p("content"))` etc using the `E` empty builder.
|
||||
- **kanta** — asyncio-native embedded database: `Kanta(filename, data)`
|
||||
root object, `transaction`, `flush`, snapshot/replay-log persistence.
|
||||
- **kanta** — asyncio-native embedded database: `Kanta(filename, data)` root object, `transaction`, `flush`, snapshot/replay-log persistence.
|
||||
- `async with Kanta(Data(),...) as kanta:` (or await kanta.open/close)
|
||||
- `with kanta.transaction(...) as data:` - transactions only for writes
|
||||
- `data` may be referenced directly to read anywhere and to modify in transactions (`as data` is just a shorthand access)
|
||||
@@ -294,32 +62,13 @@ not for the public pages. See `docs/design-principles.md` for the design.
|
||||
- We prefer objects rather than lists, as this works better in change diffs. E.g. `dict[str, True]` where the keys indicate presence and always have value `True`.
|
||||
- Maintaining and owning the app's own `Data` object is preferable; Kanta never copies this, only edits in place
|
||||
- Note: besides opening it every access is immediate direct variable access: no `await`, no locks, no delays
|
||||
- **fastapi-vue** — template glue for serving/building the Vue frontend;
|
||||
keep its integration points (`Frontend`, build hook) intact.
|
||||
- **markdown-it-py** — Markdown rendering with `html=True` raw
|
||||
passthrough; mdit-py-plugins for footnote/deflist/tasklists/attrs;
|
||||
**Pygments** for server-side code highlighting (`nowrap` spans, styled
|
||||
by `frontend/src/assets/pygments.css` which maps token classes 1:1 onto
|
||||
the `--code-*` variables; light/dark palette sets live in
|
||||
`pagerite.css` and resolve via `light-dark()` from the theme's
|
||||
`color-scheme` — themes pick a set, not individual colors).
|
||||
- **fastapi-vue** — template glue for serving/building the Vue frontend; keep its integration points (`Frontend`, build hook) intact.
|
||||
- **platformdirs** — platform user/system data dirs for the theme and font search roots (`views.THEME_DIRS` / `views.FONT_DIRS`; use `site_data_dir(..., multipath=True)`, not `site_data_path`, which collapses multipath).
|
||||
- **markdown-it-py** — Markdown rendering with `html=True` raw passthrough; mdit-py-plugins for footnote/deflist/tasklists/attrs; in-body h1/h2 headings get auto slug ids + self-links when the body has 3+ of them (`python-slugify`, mirroring `slugify.js`); **Pygments** for server-side code highlighting (`nowrap` spans, styled by `frontend/src/assets/pygments.css` which maps token classes 1:1 onto the `--code-*` variables; light/dark palette sets live in `pagerite.css` and resolve via `light-dark()` from the theme's `color-scheme` — themes pick a set, not individual colors).
|
||||
|
||||
## Conventions
|
||||
|
||||
- Keep dependencies minimal; add via `uv add` and mention it.
|
||||
- The public URL space belongs to content (pretty slugs at root). Reserve
|
||||
only `/_` for the machinery (`/_api/`, `/_f/`, `/_assets/`), plus
|
||||
`/favicon.ico` from the build. Slugs are lowercase ASCII letters, digits,
|
||||
hyphens and underscores `[a-z0-9_-]` (the site editor filters input live
|
||||
via `slugify.js`, built on the `transliteration` npm package — unicode
|
||||
folds to ASCII, spaces become hyphens; an empty slug on a new page is
|
||||
derived from its title), may not begin with `_` or `.`, and such URLs are
|
||||
never looked up as content.
|
||||
- No auth in core code; the SSO/reverse proxy gates all of `/_api`
|
||||
(forward-auth) and owns `/auth/` (login/logout, session validation).
|
||||
Pages render identically for everyone; pagerite.js adds the editing UI
|
||||
only after the auth server validates the session. Never add output
|
||||
sanitization "for safety" against the author — embedded HTML/scripts in
|
||||
Markdown are passed through deliberately.
|
||||
- Update this file and `docs/design-principles.md` when architecture,
|
||||
tooling, or conventions change.
|
||||
- The public URL space belongs to content (pretty slugs at root). Reserve only `/_` for the machinery (`/_api/`, `/_f/`, `/_assets/`), plus `/favicon.ico` (backend redirect to the configured site icon). Slugs are lowercase ASCII letters, digits, hyphens and underscores `[a-z0-9_-]` (the site editor filters input live via `slugify.js`, built on the `transliteration` npm package — unicode folds to ASCII, spaces become hyphens; an empty slug on a new page is derived from its title), may not begin with `_` or `.`, and such URLs are never looked up as content.
|
||||
- No auth in core code; the SSO/reverse proxy gates all of `/_api` (forward-auth) and owns `/auth/` (login/logout, session validation). Pages render identically for everyone; pagerite.js adds the editing UI only after the auth server validates the session. The one keyed exception is `/_translate/{key}` (translator service; `Data.translate_keys`, see docs/localization.md). Admin components use the paskia npm package's `apiFetch`/`apiJson` for `/_api` calls (login dialog + retry on expired sessions); pagerite.js uses `apiJson` only for the task-checkbox toggle (an explicit edit attempt) and `fetchJson` for its auth probes — never `apiFetch` there, so anonymous visitors never get a login popup.
|
||||
- Update the relevant MarkDown files when architecture, tooling, or conventions change.
|
||||
|
||||
@@ -1,5 +1,34 @@
|
||||
|
||||
|
||||
# Pagerite
|
||||
|
||||
A single-user CMS/blog. FastAPI serves HTML rendered in Python with html5tagger,
|
||||
content is persisted in a kanta database and rendered on the fly per request.
|
||||
Vue is used only for the interactive editing tools, not for the public pages.
|
||||
A CMS for people who are done patching WordPress. There's no PHP or Node.js to exploit — the whole editing surface sits behind your own SSO proxy, so the server the internet can talk to just renders plain pages that search engines and social media can read too.
|
||||
|
||||
The articles have rich layout and don't look boxed in like with most web publishing platforms. The software is lightweight and fast enough to serve any number of visitors you have. We run our own site [vasanko.com](https://vasanko.com/) on it, in case you wish to have a quick look.
|
||||
|
||||
## Run it
|
||||
|
||||
```sh
|
||||
uvx pagerite localhost
|
||||
```
|
||||
|
||||
That serves a demo site on localhost using [uv](https://docs.astral.sh/uv/getting-started/installation/). When you take it to production, pass your domain name instead. Our [setup guide](https://git.zi.fi/LeoVasanko/pagerite/src/branch/main/docs/setup.md) walks through the whole production arrangement. **Read it before running this online.**
|
||||
|
||||
## What it's like
|
||||
|
||||
**You write, Pagerite renders.** Articles are Markdown with the extensions that matter — tables, footnotes, task lists, callouts, highlighted code, aside boxes — and raw HTML goes through untouched when Markdown runs out. Long articles reflow into a proper two-column composition on wide screens without you doing anything.
|
||||
|
||||
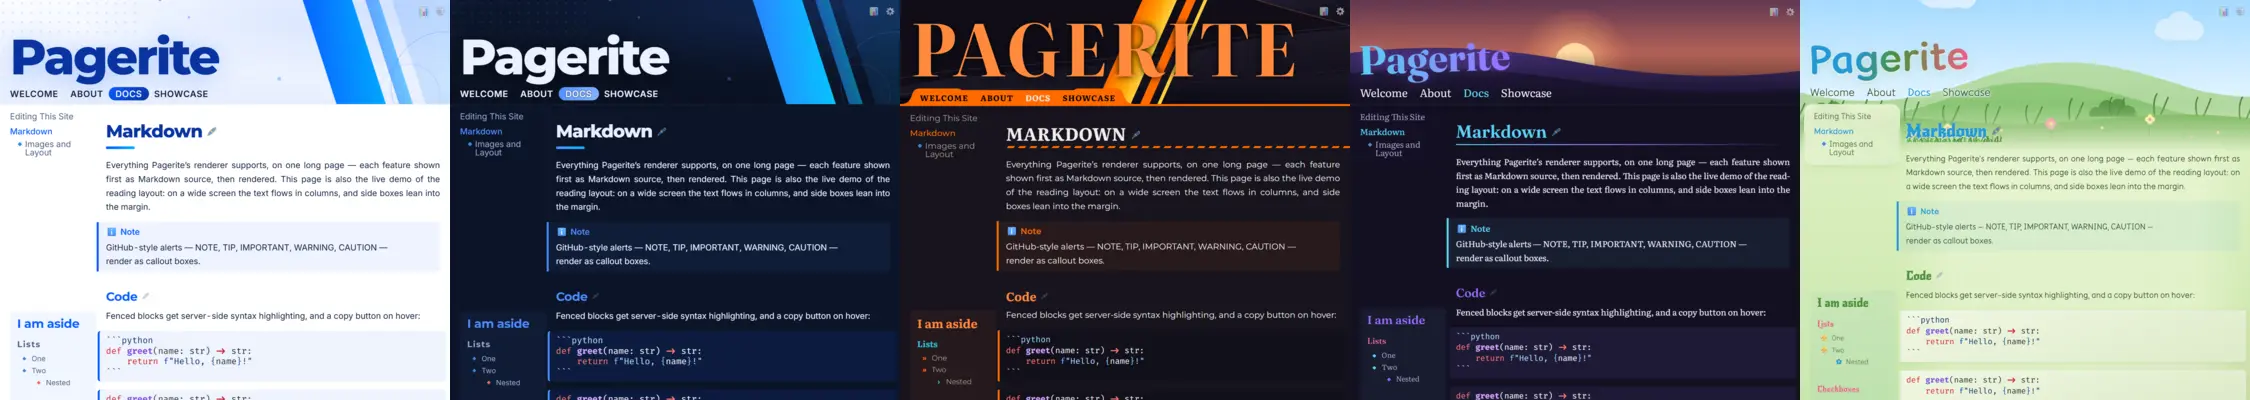
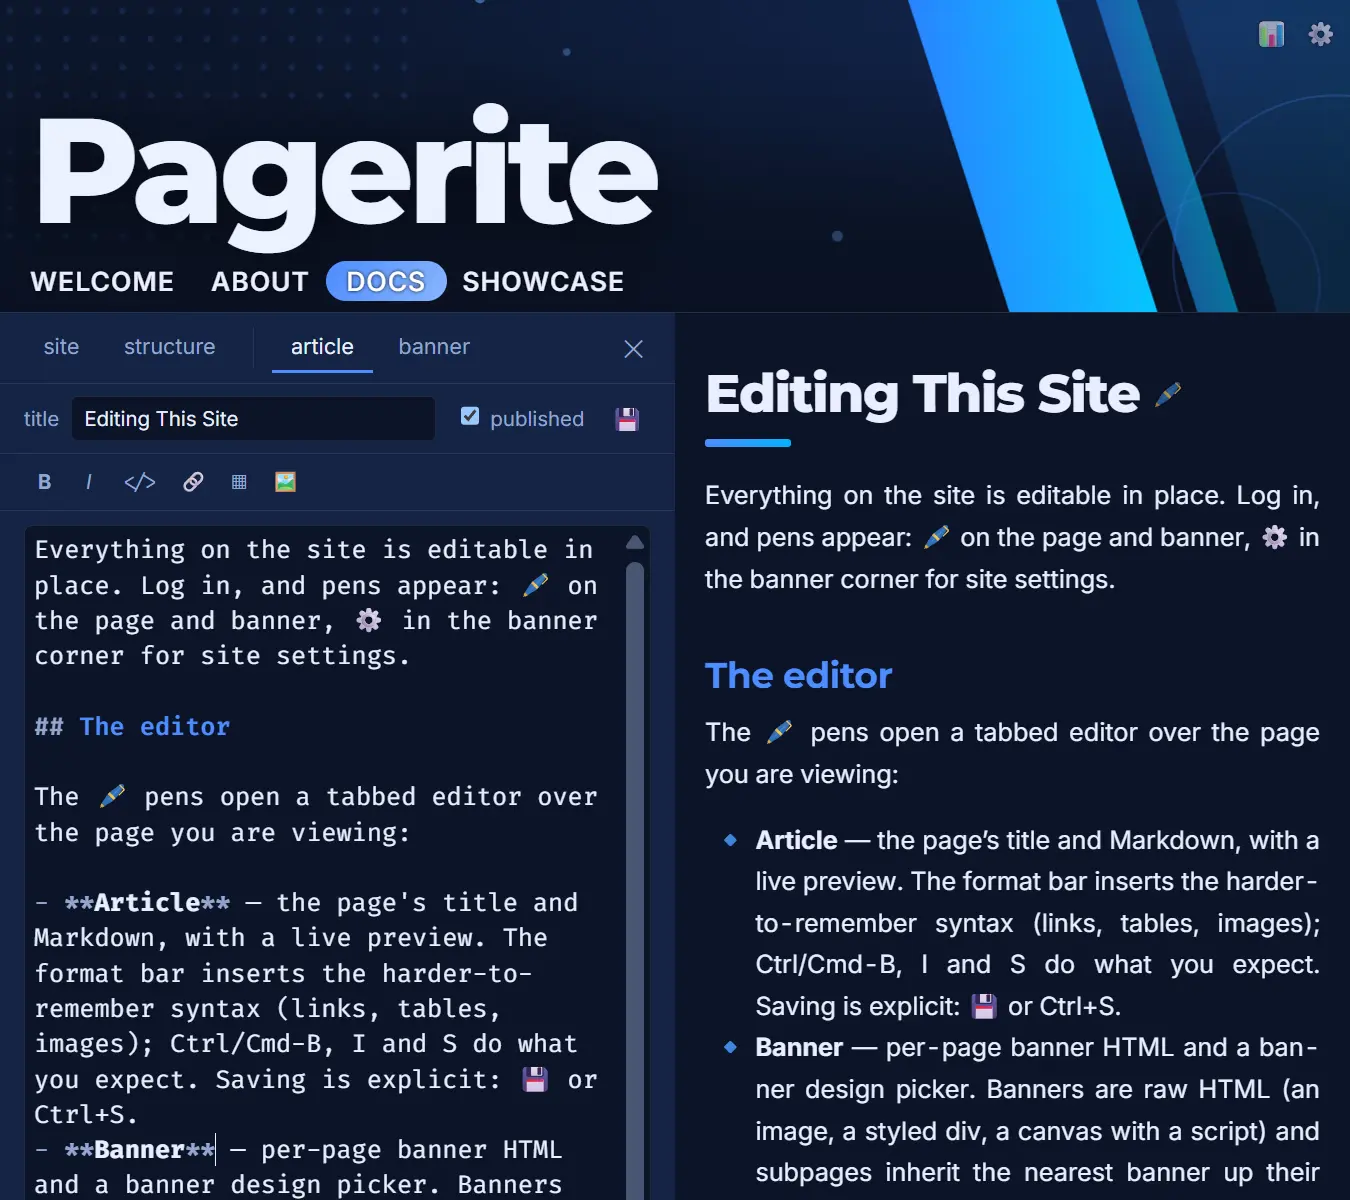
**Editing happens on the page.** Click the pen next to a heading and an editor docks beside the live article, previewing server-side as you type. Site name, theme, fonts, banner, custom CSS — changed in a panel, applied immediately. New pages grow from a ➕ in the structure tree; drag or rename rows to reorder your whole navigational hierarchy. Entirely custom or premade top banner designs per category or page are available, animations included.
|
||||
|
||||
Full scripting and styling is available for editors who wish to implement more complex functionality on their articles. This also means you should only let trusted users write on your site: this is by no means a public blog platform.
|
||||
|
||||
The worst case scenario when a hacker gains access to your admin accounts (say if you didn't read the setup guide): they can take over the entire site and run scripts on users' browsers, but the damage is limited to same domain. All your articles can be restored to the state prior to that hack or that one user's edits undone, and no data is irrecoverably lost. This is much better than other platforms that also let hackers run code on your server (WordPress).
|
||||
|
||||
|
||||
|
||||
**Theme just every part to your liking.** Themes, banner designs and page transitions are included — pick one from the site editor or copy a folder and make it yours. Several high quality fonts are included among with other assets: your site never phones a third party or us for anything. And if after all you need to customize, additional site and banner code may be provided by the admin panel.
|
||||
|
||||
**Search engines and social cards come free.** Every page gets a proper description, canonical link and Open Graph/Twitter card metadata derived from the article — including a card image picked from your own figures — without a single "SEO plugin". Category index pages, if you wish to have those, also get their sub pages shown automatically in card format.
|
||||
|
||||
|
||||
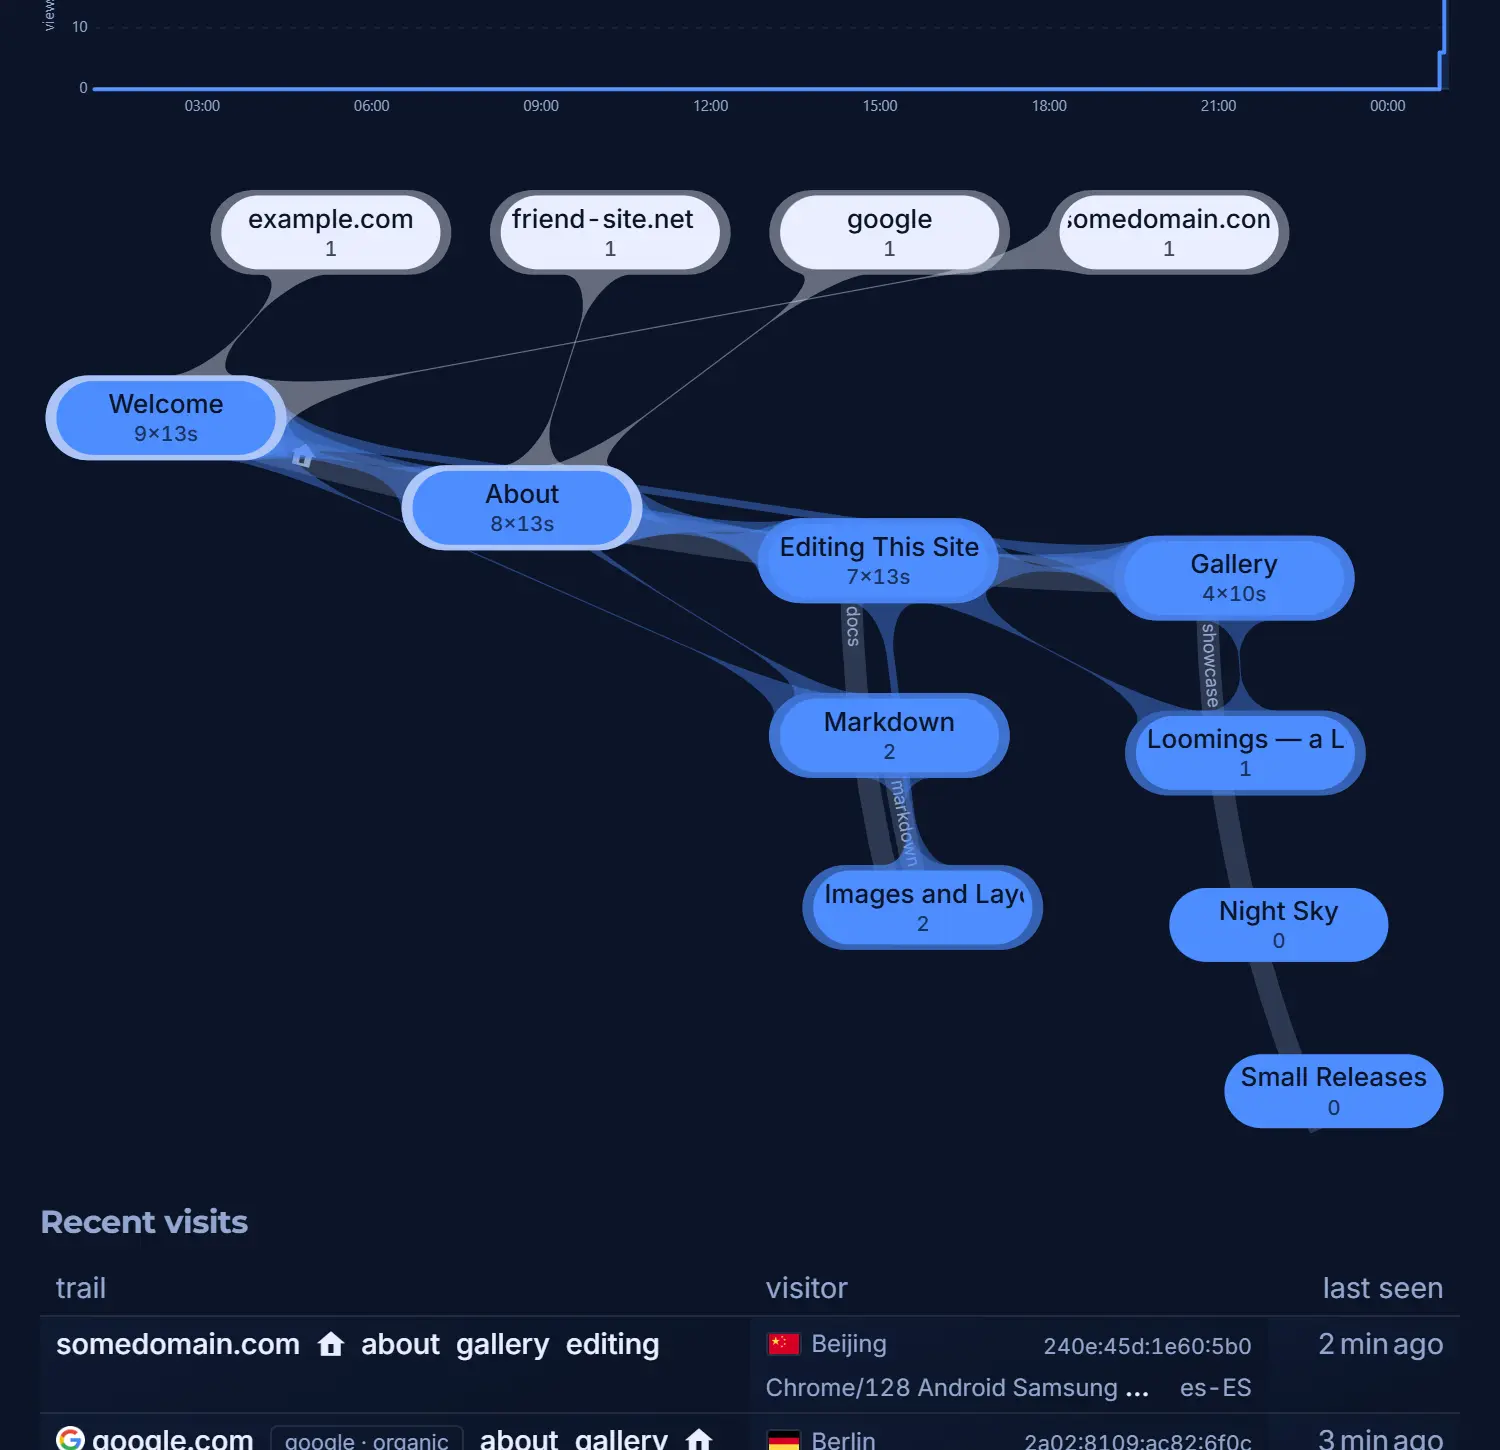
_You can see your readers. Built-in analytics need no cookies and no third-party tracker: visits, referers, reading time and a live map of how people move between your pages, plus separate ledgers for crawlers and the abusers probing for wordpress PHP files — who are, of course, wasting their time here._
|
||||
|
||||
@@ -0,0 +1,454 @@
|
||||
# Analytics
|
||||
|
||||
Server-side visit analytics built on a **raw access-log-style event store**.
|
||||
Data lives in a plain JSON file — a msgspec Struct dumped to disk — separate
|
||||
from the kanta content database, path from `PAGERITE_ANALYTICS` (default:
|
||||
`analytics.json` in the per-site data directory, e.g. `localhost/analytics.json`).
|
||||
|
||||
- `pagerite/analytics.py` — data model (`Analytics`, `Get`, `Msg`, `Client`,
|
||||
`Favicon`), the `Store` (raw log + atomic JSON persistence) and
|
||||
`Store.display()`, where **all** classification happens.
|
||||
- `pagerite/pages.py` — records every served document as one raw GET line
|
||||
(`_record_get`, in `pagerite/tracking.py`) with its true HTTP status, plus
|
||||
the `/robots.txt` and `/sitemap.xml` machinery GETs (never followed by an
|
||||
activity message, they surface as crawler hits).
|
||||
- `pagerite/tracking.py` — the `/_ws` activity WebSocket, and
|
||||
`WebSocket /_api/ws/analytics` (admin-gated like every `/_api` endpoint).
|
||||
- `frontend/src/pagerite.js` — the client activity channel and the 📊 pen.
|
||||
- `frontend/src/AnalyticsView.vue` — viewer component rendered inside the
|
||||
normal site layout on the `/_a` analytics page.
|
||||
- `frontend/src/analytics-main.js` — page entry that mounts `AnalyticsView`
|
||||
into `#analytics-app` inside `#main`.
|
||||
|
||||
## Raw records
|
||||
|
||||
The store is deliberately close to an access log: two append-only lists plus
|
||||
shared metadata. **Nothing is classified when recorded** — whether a client
|
||||
turns out to be a reader, a crawler or a scanner is decided by
|
||||
`Store.display()` from the raw events, so the stored data survives any future
|
||||
change to the classification rules.
|
||||
|
||||
Each `Get` record (one per served document):
|
||||
|
||||
- `t` — timestamp of the request,
|
||||
- `path` — full request path, query string included (e.g. `/.env?x=1`),
|
||||
- `status` — the true HTTP status of the response (200, or 404 for a category
|
||||
placeholder or a missing page),
|
||||
- `ref` — external https origin of the `Referer`, `""` for direct/internal
|
||||
(same-origin referers are dropped by the recorder),
|
||||
- `pre` — true for idle-time link preloads from pagerite.js
|
||||
(`x-pagerite-preload` header): never counted as a view, crawler hit or
|
||||
abuse — recorded only so a navigation later served from the in-memory page
|
||||
cache (which issues no GET at all) can be attributed this GET's status,
|
||||
- `lang` — rendered content language of the served document (the resolved
|
||||
language of a localized page), `""` for non-localized responses (404
|
||||
probes, reserved paths),
|
||||
- `client` — 6-byte blake3 hash referencing `Analytics.clients`.
|
||||
|
||||
304 revalidation responses return before recording and are not logged.
|
||||
|
||||
Each `Msg` record (one per pagerite.js activity message over `/_ws`):
|
||||
|
||||
- `t` — timestamp,
|
||||
- `client` — 6-byte blake3 hash referencing `Analytics.clients`,
|
||||
- `fr` — path of the page the activity happened on (`""` for the initial
|
||||
load),
|
||||
- `to` — navigation target (validated at record time: internal slug path or
|
||||
external https URL; anything else is dropped — sanitation, not
|
||||
classification),
|
||||
- `read` — active seconds spent on `fr` since the previous report,
|
||||
- `lang` — rendered language reported by the client for the page the
|
||||
activity happened on (the page's `<html lang>`; `""` from old clients).
|
||||
|
||||
Each `Client` record (shared by every event, keyed by hash):
|
||||
|
||||
- `ip` — visitor IP address (first `X-Forwarded-For` hop, or direct peer),
|
||||
- `host` — reverse-DNS host name for `ip` when resolvable, else `""`,
|
||||
- `lang` — first `Accept-Language` tag, lowercased (e.g. `"en-us"`),
|
||||
- `country` — two-letter country code. Initially derived from the
|
||||
`Accept-Language` region subtag, but overwritten by the DB-IP MMDB result
|
||||
when a database is available,
|
||||
- `city` — city name from the DB-IP MMDB lookup, when available,
|
||||
- `ua` — raw `User-Agent` string,
|
||||
- `hide` — true for admin clients (`hide` message field): everything this
|
||||
client ever did is recorded but excluded from every statistic and from the
|
||||
viewer payload. This is the one flag set at record time — it is a client
|
||||
property, not a classification.
|
||||
|
||||
The viewer payload adds one display-time field to each client, never
|
||||
persisted (stored records keep the default and old data always follows the
|
||||
current uarite version):
|
||||
|
||||
- `uarite` — the `uarite.UA` dataclass from parsing the raw UA
|
||||
(`pretty`/`engine`/`os`/`provider`/`kind`/`url`): the crawler name for
|
||||
bots,
|
||||
with a category suffix only where a provider runs crawlers of more than
|
||||
one kind (`GPTBot (AI)` vs `OAI-SearchBot (search)`, `Googlebot (search)`
|
||||
vs `Google-Extended (AI)`; single-kind providers stay plain: `Facebook`,
|
||||
`WhatsApp`), `Browser/major OS` on the desktop, the device where that is
|
||||
the relevant information (iPhone reports its iOS version, Android phones
|
||||
their model instead of the OS), otherwise the raw string; `url` is the
|
||||
crawler's info page when uarite knows one (rendered as a 🔗 link after the
|
||||
pretty UA in the viewer), `kind` drives the bot classification.
|
||||
|
||||
A reverse-DNS lookup is attempted for each new client and the result, when
|
||||
available, is stored as `host`; local/reserved/multicast addresses are
|
||||
skipped. If a DB-IP MMDB file (`dbip-*.mmdb` or `dbip-*.mmdb.gz`) is present
|
||||
in the working directory, it is loaded at startup and used to look up
|
||||
`country`/`city`. These lookups run in background tasks after the event is
|
||||
stored, so WebSocket message handling is never delayed. Only the downloaded
|
||||
`.mmdb.gz` is kept on disk (in the working directory, ignored by git); it is
|
||||
decompressed into RAM when opened. The
|
||||
CLI flag `--dbip` (`uv run pagerite --dbip`) downloads the latest
|
||||
`dbip-city-lite-YYYY-MM.mmdb.gz` from DB-IP at startup (in the app lifespan,
|
||||
before the MMDB is opened), skipping the download when the local database is
|
||||
already current and removing older versions after an update; without the flag
|
||||
only an existing file is used.
|
||||
|
||||
## What the client sends
|
||||
|
||||
The client (`pagerite.js`) keeps a WebSocket connection to `/_ws` for the
|
||||
whole browsing session and sends activity messages over it — JSON text
|
||||
frames matching the server's `Ping` msgspec struct with the fields `fr`
|
||||
(source path), `to` (navigation target), `read` (active seconds on `fr`
|
||||
since the last report), `lang` (the rendered language of the page the
|
||||
activity happened on — its `<html lang>`, except the language-switch
|
||||
navigation ping, which passes the picked tag explicitly because the view
|
||||
transition applies the new `<html lang>` only after the ping goes out) and
|
||||
`hide`; falsy fields are omitted. One channel
|
||||
follows the session, so the activity of a visit stays tied together, and
|
||||
while the user is active the accumulated reading time is flushed every few
|
||||
seconds: the times are incremental, so a disconnection simply leaves the
|
||||
last reported time in place (no close beacon). After 5 minutes without
|
||||
any activity the client closes the socket itself — a sleeping browser tab
|
||||
would lose it anyway — and the next activity reconnects; reconnects are
|
||||
attempted only on user activity, with an exponential backoff between
|
||||
attempts so a failing endpoint is never hammered. Idle-time link preloads
|
||||
stay plain `fetch()` calls so the browser may cache the responses; the
|
||||
WebSocket reports actual navigations and active time spent on a page.
|
||||
|
||||
- **Initial page load**: only `to` — the loaded path — is sent, never `fr`
|
||||
(an `fr` equal to `to` would log a bogus self-transition when a session
|
||||
already exists, e.g. a second tab). Reloads are not
|
||||
visits: the message is skipped (PerformanceNavigationTiming `reload`), so a
|
||||
refresh neither counts a second view nor logs a self-transition.
|
||||
- **Internal fetch-navigations**: `to` is the target path, sent only after
|
||||
the swap actually happened (a failed swap falls back to a full load,
|
||||
whose initial message counts the view instead — no gap, no double count).
|
||||
- **External links** (`https` only): `to` is the link's full URL. This is the
|
||||
exit-link record; the user may continue navigating afterwards (new tab,
|
||||
back), so the exit URL is not necessarily the last trail entry. Outbound
|
||||
links are stored by full URL so several links to the same domain remain
|
||||
distinct.
|
||||
- **Excluded**: back/forward (popstate) navigations, navigating *to* the
|
||||
analytics page (`/_a` — its GET is untracked, and the server cannot
|
||||
record it as a navigation target anyway), and everything while the user has
|
||||
the editor open (`body.editing`). Admin noise, not visits. Navigating
|
||||
*away* from `/_a` does report.
|
||||
- **Admins**: when SSO is in use and the session is known to be an admin,
|
||||
the client still reports but adds `hide`. The activity is recorded as
|
||||
usual (navigations and all), but the `hide` flag is set on the **client
|
||||
record** — so it covers everything that client ever did, including the
|
||||
time before the login. Hidden clients never appear in the viewer payload:
|
||||
`Store.display()` drops their events and metadata, and computes every
|
||||
aggregate (site visits, page views, transitions) from the visible visits
|
||||
only, so nothing needs to be reversed or redacted. With no auth proxy
|
||||
(dev/test) "admin" is everyone's state, so `hide` stays 0 and everything
|
||||
is recorded.
|
||||
- **External-site favicons**: for every external https origin seen as a GET
|
||||
referer or an exit link, the server fetches `{origin}/favicon.ico` in a
|
||||
background task (httpx, 8 s timeout, ≤ 64 KB, image content-types only —
|
||||
SVG is sniffed from the body when served without an image type) and stores
|
||||
the icon content-hashed on disk in the FileStore (served at `/_f/{name}`,
|
||||
extension matching the actual MIME). The origin → file name mapping is
|
||||
recorded in `Analytics.favicons` (`Favicon.file`/`fetched`); misses are
|
||||
recorded too and retried only after 7 days. Fetches are scheduled after
|
||||
each activity message and once at startup, which backfills icons for
|
||||
already-recorded data. The viewer payload carries `favicons` (origin →
|
||||
`/_f/...` path), and the viewer shows the icon wherever an external site
|
||||
is mentioned: referer/exit trail links in the visit table and the
|
||||
source/exit pills of the transition map (UTM-attributed source nodes
|
||||
without an https origin stay text-only).
|
||||
|
||||
## Display-time classification
|
||||
|
||||
`Store.display(in_menu)` derives the viewer payload from the raw events on
|
||||
every (debounced) broadcast — O(n log n) over the log, cheap enough for a
|
||||
small CMS. `in_menu(path)` resolves a path against the current menu (passed
|
||||
in from `tracking.py`, which owns the content database import) so 404
|
||||
responses for real menu nodes — category placeholders — are not mistaken
|
||||
for misses.
|
||||
|
||||
- **Visits and sessions**: a client's messages are grouped into visits
|
||||
chronologically; a new visit starts after 30 minutes of inactivity
|
||||
(`_SESSION_GAP`). A fresh page load with an already-open visit (second
|
||||
tab) extends it, logging a `(direct)` transition. The visit's trail holds
|
||||
first-seen targets in order; `read` updates accumulate active seconds on
|
||||
the trail item matching `fr` (preferring the item whose language matches
|
||||
the report, so seconds after a language switch land on the new-language
|
||||
step). Each trail item's HTTP status comes from
|
||||
the client's latest GET for that path — preloads included, which is what
|
||||
allows 404 pages to render red in the viewer even when the navigation
|
||||
itself was served from the page cache. Each trail item also carries the
|
||||
rendered language: the client's report, for the entry page falling back
|
||||
to its GET's rendered language (old clients don't send one); a page
|
||||
re-visited in a different language becomes a distinct trail step instead
|
||||
of merging into the existing item. The entry page's referer and
|
||||
`utm_*` tags come from the GET that loaded it (within 10 s before the
|
||||
first message).
|
||||
- **Crawler hits**: a document GET no activity message matched within
|
||||
`_CRAWLER_TIMEOUT` (10 s) is a crawler hit — plain bots that only fetch
|
||||
documents never register as visits. JS-running crawlers (Googlebot,
|
||||
GoogleOther, Applebot, ...) do connect and send messages, but their UA
|
||||
gives them away (`_is_bot_ua`, backed by `uarite.uaparse` — which
|
||||
also knows the disguised ones: facebookexternalhit, Google-Extended,
|
||||
WhatsApp, ...): their messages are ignored at display
|
||||
time, so their GETs never match and land in the crawler list too. Real-
|
||||
browser bots whose UA does not match are caught by engagement: a visit
|
||||
whose total reported reading time is under 5 seconds (`_MIN_VISIT_READ`;
|
||||
durations are client-provided and trusted — such bots report 0–2 s) is
|
||||
reclassified as crawler hits, one per internal trail page, and counts in
|
||||
no visit aggregate. No source-IP verification is done: a spoofed bot UA
|
||||
merely lands in the crawler stats, and scanners that probe telltale paths
|
||||
are caught by the abuse rules regardless. In the viewer, crawler hits are
|
||||
grouped by client hash and shown as a trail of pages, preceded by the
|
||||
referer when there is one (rendered with its favicon like visit
|
||||
referers). Non-article machinery GETs (`/robots.txt`, `/sitemap.xml`,
|
||||
`/llms.txt`, the feeds) appear as
|
||||
emoji-marked steps (🤖 / 🗺️ / 🧠 / 📡) so they stand out from article steps.
|
||||
The crawler table lists the most recent crawler first, with
|
||||
the most active as a tie-breaker.
|
||||
- **Abuse (scanner) hits**: a 404 on a telltale path — an empty URL segment
|
||||
(`//foo` — no real client generates those), any segment starting with a
|
||||
dot (`/.env`, `/.git/config`) or ending in `.php` — classifies the source
|
||||
IP as abuse, and ten plain 404s within one hour (`_ABUSE_404_WINDOW`) on
|
||||
paths that don't resolve to a menu node do too. Two exemptions keep
|
||||
legitimate traffic out: RFC 8615 well-known URIs (`/.well-known/…` —
|
||||
browsers and services probe them, e.g. Chrome's devtools fetch of
|
||||
`appspecific/com.chrome.devtools.json`) are never telltale and never
|
||||
count toward the threshold, and category placeholders return 404 but are
|
||||
real menu nodes, so they never count either. The window keeps a
|
||||
long-time reader's slowly accumulating misses from ever crossing the
|
||||
threshold — scanners spray in bursts. Hidden (admin) clients never
|
||||
trigger classification: editing means visiting not-found pages, since
|
||||
that is where the create pen lives. Once an IP is classified, **all** its document GETs are shown in the abuse list —
|
||||
including any that arrived before classification, since the raw log keeps
|
||||
everything — and its activity messages are ignored. In the viewer, abuse
|
||||
hits are grouped by IP (never by client/UA — scanners randomize theirs)
|
||||
in a separate "Abuse" table, split by the recorded status: the 404 probes
|
||||
("paths abused" — flagged paths that triggered classification first, then
|
||||
other 404s, shown verbatim with query strings) versus the real articles
|
||||
the abuser actually read ("articles read" — the 200 document GETs,
|
||||
rendered as trail links like the visitor and crawler tables, query string
|
||||
stripped). Raw User-Agent strings are shown one per line with their
|
||||
occurrence counts, and the full lists are click-to-copy.
|
||||
|
||||
In the visitor and crawler tables, internal paths that returned a 404 status
|
||||
are shown in red and the link title includes the status code, so it is easy
|
||||
to tell misses from real pages at a glance.
|
||||
|
||||
## Derived shapes (the viewer payload)
|
||||
|
||||
The `Display` payload contains the derived `visits`, `crawlers` and `abuse`
|
||||
rows (structs `Visit`/`Nav`/`TrailItem`, `CrawlerHit`, `AbuseHit` — display
|
||||
DTOs only, never persisted), the visible `clients`, the fetched `favicons`,
|
||||
the site language context (`multilingual` — translation languages are
|
||||
configured, so the viewer can suppress language UI on single-language
|
||||
sites — and `primary_lang` — the front page's primary language, so the
|
||||
viewer can skip the primary-language default case),
|
||||
and the aggregates below.
|
||||
|
||||
Each derived `Visit`:
|
||||
|
||||
- `start` — timestamp of the first activity,
|
||||
- `entry` — first page (path) seen,
|
||||
- `referer` — external https origin of the entry GET, `""` for direct,
|
||||
- `client` — 6-byte blake3 hash referencing `Analytics.clients`,
|
||||
- `trail` — the entry page and everything seen afterwards, keyed by the
|
||||
timestamp of first sight (insertion order = first-seen order). Each item
|
||||
holds `to` (page path or external exit URL), the accumulated active
|
||||
reading time in seconds (`read`), the most recent HTTP status seen
|
||||
for the target (`status`) and the rendered language (`lang`; a page
|
||||
seen in two languages within one visit gets one item per language),
|
||||
- `navs` — every navigation (`fr`, `to`), keyed by its timestamp, repeats
|
||||
included. The aggregates are computed from this log,
|
||||
- `utm` — `utm_*` query parameters from the landing URL, as a dict.
|
||||
|
||||
Each derived `CrawlerHit`:
|
||||
|
||||
- `start` — timestamp of the document GET,
|
||||
- `entry` — page path requested,
|
||||
- `client` — 6-byte blake3 hash referencing `Analytics.clients`,
|
||||
- `referer` — external https origin of the request, `""` for direct/none,
|
||||
- `query` — raw query string of the request,
|
||||
- `status` — HTTP status of the served response (200 for a real page, 404
|
||||
for a category placeholder or missing page),
|
||||
- `lang` — rendered content language of the served document (from the GET).
|
||||
|
||||
Each derived `AbuseHit`:
|
||||
|
||||
- `start` — timestamp of the request,
|
||||
- `path` — full request path including the query string,
|
||||
- `client` — 6-byte blake3 hash referencing `Analytics.clients`,
|
||||
- `flag` — true for the paths that triggered abuse classification (telltale
|
||||
paths, or the 404 that crossed the threshold),
|
||||
- `is_404` — true for 404 responses, false for real (200) document GETs.
|
||||
|
||||
Crawler hits are grouped by client hash in the analytics viewer; abuse hits
|
||||
are grouped by IP alone (resolved from the referenced `Client`). In the
|
||||
Abuse table identical requests (same path and status class) are collapsed
|
||||
with their counts — a path's 404 probes and its later 200 reads never
|
||||
merge. Within each list paths are sorted by count descending, then by their
|
||||
earliest hit.
|
||||
|
||||
## Aggregates
|
||||
|
||||
Aggregates are **not stored**; they are computed at display time by
|
||||
`Store.display()` from the derived visits (entry + `navs` log), skipping
|
||||
hidden clients and short visits reclassified as crawler hits. This is
|
||||
what allows a client to become hidden after navigations were already
|
||||
logged: no counts need reversing. The computed shapes, part of the
|
||||
WebSocket payload (`Display` struct alongside `visits`, `crawlers`, `abuse`
|
||||
and `clients`):
|
||||
|
||||
- `transitions`: time series of page transitions, sparse nested dict
|
||||
`from -> to -> bucket -> count` with 5-minute bucketing. `from` is the
|
||||
referer origin or `"(direct)"` for initial loads, a page path for
|
||||
navigations.
|
||||
- `views`: time series of page loads, `path -> bucket -> count`, sparse: only
|
||||
non-zero 5-minute buckets exist (bucket key is its floored ISO timestamp).
|
||||
Every load counts, including repeats within a visit; external exit origins
|
||||
are not page views and are not counted here.
|
||||
- `site_visits`: `bucket -> count` of new visits started, same sparse
|
||||
5-minute bucketing.
|
||||
|
||||
Sparseness keeps quiet sites small; dropping old data is a matter of deleting
|
||||
list entries (`gets`/`msgs` are plain append-only lists).
|
||||
|
||||
## Persistence
|
||||
|
||||
The whole `Analytics` struct is JSON-encoded and written atomically
|
||||
(temp file + rename) on every recorded event. Traffic on a small CMS makes
|
||||
this cheap enough; batching can be added later without changing the format.
|
||||
A file written by the pre-redesign schema (stored `visits`/`crawlers`/`abuse`
|
||||
lists) is not convertible; it is renamed to `analytics.json.bak-legacy` and
|
||||
recording starts fresh.
|
||||
|
||||
## Viewing
|
||||
|
||||
The 📊 pen in the banner corner (admins only, injected by pagerite.js next to
|
||||
the edit pens) links to `/_a`, the analytics page. It is a normal site page:
|
||||
the standard banner, navigation and footer stay in place, and the analytics
|
||||
content is rendered inside `#main`. The page itself is public, but the data
|
||||
stream comes from `WebSocket /_api/ws/analytics`, which remains admin-gated
|
||||
like the rest of the management API; visitors without access see the viewer
|
||||
with a "could not be loaded" message.
|
||||
|
||||
Because it is a real page, fetch-navigation handles it like any other internal
|
||||
link: clicking the 📊 pen (or any link to `/_a`) fetches the server-rendered
|
||||
HTML, swaps the dynamic regions and mounts the Vue analytics app in place. The
|
||||
range selector updates the URL hash (`#week` etc.) so links to a specific
|
||||
range can be shared. When the URL has no hash, the client derives the
|
||||
default from the first analytics snapshot: `day` if the recorded history
|
||||
spans less than 24 hours, otherwise `week`.
|
||||
|
||||
`AnalyticsView.vue` is no longer a full-screen overlay; the `body.analytics-open`
|
||||
page-chrome hiding and `#/analytics/<range>` hash routing have been removed.
|
||||
|
||||
Charts are SVG curves (Catmull-Rom over an edge-aware Gaussian — a
|
||||
change-point detector splits the series at traffic-level shifts, then each
|
||||
segment is smoothed independently with a fixed sigma chosen so N events in
|
||||
a single bucket peak at N events per unit. The raw series is drawn faint
|
||||
underneath). Values are
|
||||
**per-unit rates** — per hour on the week view (5-minute bucket counts × 12,
|
||||
plotted at native 5-minute resolution), per day on the month+ ranges — and
|
||||
the smoothing time scale follows the unit: the month+ sigmas are 24× the
|
||||
hourly ones. The y max is derived from the smoothed curves so single-bucket
|
||||
spikes don't blow up the scale, and raw spikes are clamped into the plot.
|
||||
Axes always start at 0 and end at a multiple of a 1-2-5 major step (max 5
|
||||
labeled intervals, minor lines at fifths when integral; the minimum y-axis
|
||||
range is 10 so tiny values such as a single visit are not stretched to a
|
||||
fractional scale).
|
||||
The week range is aligned to Monday 00:00 UTC (the current week keeps the
|
||||
accent color and is truncated at the current bucket, never drawing fake
|
||||
zeroes for the future). Since the window is fixed Monday-to-Monday, **last
|
||||
week's curve** continues the graph from the current bucket to the end of
|
||||
the week in the secondary accent (`--accent2`, translucent fill like the
|
||||
current week), so the chart shows useful data
|
||||
on Monday too and last week is gradually replaced by the current week;
|
||||
the tail is only drawn when the recorded data reaches into last week.
|
||||
Both the week and day views overlay a **"typical"
|
||||
history estimate** as a muted fill with no stroke, translucent to the same
|
||||
degree as the current data — shown only once the history spans twice the
|
||||
view's full time (from the third day on the day view, the third week on
|
||||
the week view; `analytics/seasonal.js`, a port of
|
||||
`seasonal.py`): the whole recorded history is densified to 5-minute bins,
|
||||
smoothed with the same Gaussian as the week view, then folded onto a weekly
|
||||
grid with exponential decay over age — a 7-day half-life for the average
|
||||
time-of-day pattern and a 42-day half-life for per-weekday deviations from
|
||||
it, the deviation shrunk by the effective number of weeks behind each bin
|
||||
(`n_eff / (n_eff + 3)`) so the estimate falls back to the common daily
|
||||
pattern when history is short. History is capped at the most recent 180
|
||||
days, beyond which even the slow kernel's weight is negligible (~5%). The
|
||||
week view draws the full Monday-first
|
||||
estimate as "Typical week" (future included); the day view cuts the rolling
|
||||
24-hour window's bins from the same estimate and labels them by the weekday
|
||||
("Typical Saturday"). A compact legend inside the top right of the visits
|
||||
chart marks the current data in accent (ISO week label, or a bar specimen
|
||||
for "Last 24 hours"), the previous week's tail on a secondary-accent line
|
||||
specimen (week view only), and the typical estimate on a muted fill
|
||||
specimen. The week
|
||||
view's x labels are weekday names centered at midday UTC, without
|
||||
vertical grid
|
||||
lines (day boundaries would be misleading in the viewer's timezone). The
|
||||
month view labels days the same lineless way — day numbers at noon UTC,
|
||||
with the month name substituted for the 1st. Month, year and all are
|
||||
rolling windows ending at now, aligned to UTC day boundaries at the start
|
||||
so the labels span the whole range; the bucket size follows the window —
|
||||
6 hours up to 31 days, daily beyond — with boundary lines at months/years
|
||||
on the longer ranges. All uses the full data reach, but keeps
|
||||
at least the past 30 days (identical to the month view when the site is
|
||||
younger than that, bucket size included) so the chart never collapses to a
|
||||
tiny sliver when the site is young. Below the charts: a **transition map** (all pages from
|
||||
`/_api/pages` — top-level menu items on a large-radius circular arc whose
|
||||
bottom point is the last item (each earlier item a bit higher), connected
|
||||
by a top lane labeled 🏠︎ beside the home pill (50% thicker than
|
||||
the branch lanes, its label font and guide offset scaled along), each item's
|
||||
subtree fanning out below it in menu order along a large-radius circular
|
||||
arc that leaves heading
|
||||
straight down and gradually bends right, index pages without views omitted
|
||||
and their children promoted in their place. The submenu structure is drawn
|
||||
as wide branch lanes: one per path prefix with at least two visible
|
||||
nodes, running behind the branch's node pills as circle arcs concentric
|
||||
with the fan (parent levels one radius step outward, so all lanes of a
|
||||
group share exactly one form), each labeled with its branch slug
|
||||
left-aligned just past the first pill and allowed to run along the lane to
|
||||
its end, disappearing under later pills when long — so the lanes reflect
|
||||
the path
|
||||
structure even where index pages are omitted — opposite transition
|
||||
directions joined into organic
|
||||
tapered connections whose middle width grows logarithmically (base 2)
|
||||
with the daily hit rate (uncapped), connections
|
||||
carrying less than 1% of the total traffic
|
||||
pruned, as are those whose thin middle would render below ~0.8 px —
|
||||
fainter strands are invisible and only their wide end flares would show; beads are simulated one by one in JS (requestAnimationFrame) and
|
||||
flow along each edge, persisting across data reloads (emitters are keyed
|
||||
per edge direction and beads tracked by progress, so an unrelated count
|
||||
change never reshuffles them), emitted at a rate linearly proportional
|
||||
to the directional count with no in-flight limit, opposing directions
|
||||
offset onto parallel lanes. External sources and exits whose connectors are
|
||||
all culled by the width threshold are dropped from their rows themselves
|
||||
(the site's own page nodes always stay, connected or not). External sources show as a node row above the
|
||||
map: each visit is attributed to `utm_campaign`, then `utm_source`, then the
|
||||
referer origin, then any other `utm_*` tag, so UTM-tagged visits are grouped
|
||||
under their campaign/source value rather than the referer domain. A UTM
|
||||
source node only links to its referer when every visit carrying that tag
|
||||
came from the same origin. Within the source and exit rows the pills are
|
||||
not sorted by count; each slides sideways toward the pages it connects to,
|
||||
minimizing the weighted horizontal connection distance while keeping a
|
||||
minimum pill spacing. External exits are full-size nodes in a matching
|
||||
row below the map, so the site itself stays in the middle), per-page view
|
||||
counts, the top transitions and the 50 most recent visit trails. Data is
|
||||
streamed live over `WebSocket /_api/ws/analytics`, which pushes the latest
|
||||
JSON snapshot on connect and again whenever the analytics file is updated
|
||||
(with a small server-side debounce to avoid flooding under high traffic).
|
||||
@@ -0,0 +1,46 @@
|
||||
# Backend
|
||||
|
||||
The Python backend lives in `pagerite/`.
|
||||
|
||||
## `app.py`
|
||||
|
||||
Thin FastAPI assembly: lifespan (open the kanta database, load the file store, the frontend build and GeoIP), the `FastAPI(...)` instance with built-in API docs disabled (`docs_url`/`redoc_url`/`openapi_url=None`) because `/docs` belongs to our content, the `server` header middleware, and router includes. The routes themselves live in specialized modules:
|
||||
|
||||
- `state.py` — shared core, no routes: the environment-derived site constants (`HOSTNAME`, `SITE_URL`, `DB_PATH`, `FILES_DIR`, image/favicon tunables), the `data` root and its `kanta` handle (`Kanta(..., migrations="pagerite.migrations")`), the `analytics_store`, the fastapi-vue `frontend`, the page render cache and `_html_response`, the translator `dispatcher`, the slug charset helpers, and the `@kanta.bootstrap` hooks (demo seed, translator defaults).
|
||||
- `files.py` — the `FileStore` and image derivative helpers, and the file routes: `/_api/files`, `/_f/`, `/_themes/`, `/_fonts/`, the favicon settings endpoints.
|
||||
- `api.py` — the editor REST API and WebSockets: `/_api/pages`, `/_api/structure`, `/_api/settings`, `/_api/toggle-task`, `/_api/translations`, `/_api/ws/editor`, and the translator channel `/_translate/{clientkey}`.
|
||||
- `tracking.py` — visit analytics: GeoIP, client enrichment, favicon fetching, debounced broadcasts, the `/_ws` activity socket, the admin stream `/_api/ws/analytics`, and the `/_a` viewer page.
|
||||
- `feeds.py` — machine-readable site exports: `/llms.txt` (Markdown site map for LLM agents), `/feed.json` (JSON Feed 1.1) and `/feed.xml` (RSS 2.0 + atom:link), all carrying every published article with full content (relative URLs absolutized), linked from every page's `<head>` and from the sitemap, and recorded in analytics like page GETs. Bodies are RAM-cached (keyed by base URL, cleared by `_invalidate_pages` like the page render cache) and served with a content-hash ETag (304 revalidation).
|
||||
- `pages.py` — the public content pages: `/`, `/sitemap.xml`, `/robots.txt` and the `/{path:path}` catch-all.
|
||||
|
||||
Route ordering is load-bearing and lives in `app.py`: the api/tracking/files routers are included BEFORE `frontend.route(app, "/")` is called — fastapi-vue inserts its file routes at the position where `route()` was called (during `load()` in the lifespan), so anything registered earlier wins. The content catch-all `/{path:path}` is included AFTER `frontend.route()` so that built frontend assets still take priority over content slugs. The `Frontend` is constructed with `spa=False` explicitly: it only serves the built files without a catch-all.
|
||||
|
||||
The build mirrors the URL space — hashed immutable assets under `/_assets/`, `favicon.ico` at the site root — and an `index.html` in the build would become a `/` route, so leave it out of the build to keep `/` ours.
|
||||
|
||||
Generated HTML pages (content pages, category/404 placeholders, `/_a`) go through `state.py`'s `_html_response`: zstd-compressed per request at level 9 when the client sends `accept-encoding: zstd` (no gzip fallback; static assets are pre-compressed by the `Frontend`), with `vary: accept-encoding` set and the ETag kept identical across encodings so `if-none-match` revalidation still works. In production the rendered bodies are cached in an LRU keyed by everything the output depends on — page kind, path, the site origin (social meta), encoding — and cleared wholesale by `_invalidate_pages()` on every content/settings change, which also bumps the in-memory render generation. The cache is bypassed in dev, where theme/design CSS is re-read from disk per request. Content pages carry an ETag built from the node's modified timestamp and the render generation; `/_a` instead gets a blake3 hash of the rendered body (it has no Node), with matching `if-none-match` revalidations answered by a 304.
|
||||
|
||||
Uploaded files, seed assets and fetched external-site favicons live in the `FileStore` (in `files.py`): content-addressed files on disk under `<hostname>/files/` (`PAGERITE_FILES`), fully cached in RAM at startup — both the raw body and a zstd-compressed copy (kept only when smaller). `GET /_f/{name}` serves from the RAM cache with immutable caching, answering the zstd variant when the client accepts it; the name is the ETag. Uploaded raster images (and rasterized SVGs) are stored as `<hash>.orig<ext>` (internal only, never served) plus AVIF, WebP and JPEG derivatives, and pages link the extension-less `/_f/{hash}`: the server serves a format only when the Accept header lists it explicitly (`image/avif` → AVIF, `image/webp` → WebP, otherwise — including `*/*` — JPEG), with `vary: accept`; an explicit extension pins the format. `migrate_v2` rewrites old `/_f/{hash}.avif` article links to the bare form, backfills missing derivatives on disk, and drops the obsolete `version` field. Legacy databases that still carry blobs in a `files` kanta field or a flat `pages` store are migrated by `pagerite/migrations.py::migrate_v1` (kanta's `migrate_vN` mechanism, wired via `Kanta(..., migrations="pagerite.migrations")`), which rewrites the raw state before struct decoding — all schema/storage upgrades live in that module, none in the app lifespan.
|
||||
|
||||
## `data.py`
|
||||
|
||||
msgspec Structs for the kanta database. See `docs/content-model.md` for the full data model.
|
||||
|
||||
## `markdown.py`
|
||||
|
||||
markdown-it-py renderer (html passthrough + attrs, footnote, deflist, tasklists, admon, gfm_autolink, sub/superscript plugins; typographer + breaks on). In bodies with at least three top-level h1/h2 headings (nested ones, e.g. inside `::: aside`, never participate), each gets a slug id (`python-slugify`, mirroring the editor's `slugify.js` — unicode folds to ASCII, separators become single hyphens) unless the author set `{#id}`, and their text is wrapped in a self-link (`a.anchor`) so section links are copyable; anchored headings also carry `data-line` with their markdown source line (the page editor's section pens and piecewise scroll sync key off it); the first in-body h1 is the article title — when the markdown has no h1, `render(title=...)` injects it as `# {title}` so implicit and explicit titles take the same path — it gets no id and doesn't count toward the three, its self-link is `href=""` (scroll to top); shorter articles stay anchor-free, h3+ is never navigable, and duplicates get `-2`/`-3` suffixes. Custom image rule: relative srcs resolve against the page path; an image standing alone in its paragraph becomes a figure (captioned when titled), while inline-with-text images and raw `<img>` HTML stay plain. A lone `{name}` / `{name: args}` line is a block directive: a core rule turns it into a `directive` token (render instance only — the verbatim parser keeps the plain paragraph so segments/chunks see the placeholder source), and the render rule delegates to the resolvers passed as `render(directives=...)`, leaving the source literal where no resolver applies (e.g. the editor preview of a page that does not exist yet). Built in: `{dates}` expands to the article's published/updated dateline (`p.dateline`, from `Node.created`/`modified`, registered by `render()` when `created` is given); views.py resolves `{cards}` — the page's published children, one card each (on the front page: the other top-level pages) — and `{cards: path path/* path/** ...}` (space-separated: a plain path renders that page alone, `path/*` its published children, `path/**` all published descendant pages; a page-less item is represented by its first leaf page, the nav-link logic) into the same card-row markup as category pages (`.cards.wide`, a boundary block outside the column segments). A page with any `{cards}` tag drops the automatic end-of-page child cards; multiple tags each render their own row. Code fences take pandoc-style brace attributes on the info line (` ```{.python .wide #id key=val} ` — the first class is the language when no bare language word precedes the braces) as well as a trailing `{...}` line; both land on the `<pre>`, the `<code>` keeps only the language class.
|
||||
|
||||
`render()` returns a `Rendered(html, multicol)`: the article content segmented for the column layout (there is no wrapper div — segments and bare blocks are direct `<article>` children) — h1/h2 headings and `.wide` blocks stand bare, the runs between them become `<div class="colseg">` (margin-breakout boxes — `.margin`, `::: aside` — stay inside the segment at their anchor point; the CSS positions them out of flow into the side zone) (plus `.cols` on segments with enough text in at least two paragraphs or one long enough to split across columns, `::: nocols` opting out; in column segments, paragraphs past `BREAKABLE_TEXT` visible characters are marked `.breakable` so they may split across columns), and `multicol` flags bodies long enough to columnize (visible-text thresholds, code excluded). `views.py` puts the class on the article; pagerite.css takes it from there (at most two columns, the left-margin breakout, all viewport adaptation).
|
||||
|
||||
## `views.py`
|
||||
|
||||
The shared page layout as an html5tagger `Template` with placeholders (`Title`, `Brand`, `Banner`, `Nav`, `Sidebar`, `Main`), nav rendering straight from the `Data.menu` tree (siblings sorted by `Node.order`; nav links to content-less labels point at their first child via `first_leaf`, the first published descendant with content), and page/404 rendering.
|
||||
|
||||
Content pages get SEO/social meta (description, canonical link, Open Graph + twitter card) from heuristics over the rendered article: the description is the first paragraph's text; the card image is the node's own `Node.image` when set, otherwise mined from the article (preferring a `{.hero}`-classed image, then the first raster `<img>`, then the first SVG), and only when the article yields none the inherited one (nearest ancestor, front page last — see docs/content-model.md); the first `<video>` yields `og:video`; URLs are made absolute with the site origin (`SITE_URL` — `https://<hostname>` from the CLI hostname argument; on localhost the request's own base URL is the fallback); `article:published/modified_time` come from `Node.created`/`modified`. Additionally `twitter:image` pins extension-less `/_f/{hash}` card images to the `.webp` variant — X only honors WebP via twitter:image (not og:image) and its scraper cannot be trusted to negotiate via Accept. `twitter:card` is `summary_large_image` when the image's probed store dimensions suit a large card (wider than 600px, taller than 400px and clearly wider than tall — aspect > 1.05, so square and portrait images keep the compact layout; dimensions are read from the `<hash>.webp` derivative via pyvips, cached per hash) and `summary` otherwise — external or unprobeable images keep the presence-based default (large when an image exists). The node's `Node.large` setting overrides that pick per article (False = small, True = large, the default None = automatic; NOT inherited like `Node.image`). The page title is injected as `# {title}` when the markdown has no h1 of its own, so it never appears twice (it always supplies `<title>` and nav labels).
|
||||
|
||||
The navbar holds top-level items only; the current section's subitems go to a left `#sidebar` as a nested list (the section's direct children plain, deeper levels indented with article-list-style markers), rendered only from the second level down — main-level pages list their children as cards after the content instead. Below that, the sidebar renders when the section offers at least two published items, or exactly one while viewing anything other than that only page — the section index, a 404, a grandchild (so those pages can reach the child), and also on that only page itself when it has published children of its own; no aside element at all on the front page, main-level pages, leaf pages and the sole childless page of a one-page section. Also, category labels are nodes without content — None *or* empty markdown — and their nav links point at their first child page. Dynamic regions have stable ids (`#page-banner`, `#nav`, `#sidebar`, `#main`) for fetch-navigation swaps (`#sidebar` may be absent on either side of a swap).
|
||||
|
||||
Any page with published children — a category page — lists them as a card grid (`nav.cards`) after the markdown content, as does the content-less category 404. Each card links to the child page (a content-less child to its first leaf) and shows the child's card image (its own `Node.image` when set, else the same hero → first raster → first SVG heuristics as `og:image`, else the inherited image). The layout follows the same selection as `twitter:card` (_card_large — the child's per-article `Node.large` override, else the image's probed dimensions): large cards show the image as a full-card cover with the title overlaid, small cards (`.card.compact`) split horizontally at the golden ratio (two sub-grids, top φ : bottom 1): the square image fills the top part with the title beside it at its bottom, the article description (which only the small format carries) tops the bottom part — title and description carry the translucent band (the same band color as the large cards' title) as their own background; imageless cards keep the image space as a blank gradient. Each card carries the target article's language as its `lang` (the page language when the target is translated into it, else the target's primary language — matching the per-card text fallback) so the clamped title/description hyphenate correctly (`hyphens: auto`).
|
||||
|
||||
## `seed.py`
|
||||
|
||||
Demo content written only when the database is first created, via a `@kanta.bootstrap` handler in `state.py`.
|
||||
@@ -0,0 +1,43 @@
|
||||
# Content model
|
||||
|
||||
The site structure is stored in the kanta database managed by `pagerite/data.py`.
|
||||
|
||||
## Site tree
|
||||
|
||||
`Data.menu` maps top-level slugs to `Node`s, each with `children` keyed by slug — the URL path is the slug chain. The front page is whichever top-level node has slug "" (parallel to the other main level pages, not their parent); it cannot have children, and renaming its slug away leaves no front page ("/" redirects to the first nav item).
|
||||
|
||||
`Node.content` is the Markdown page, or None for a pure category label whose URL renders a 404 listing its children as cards (while nav links to it point at its first child); every label's title and slug are editable. A page with published children — a category page — lists them as cards after its markdown content; the sidebar sub-navigation renders only from the second level down, never on main-level pages.
|
||||
|
||||
Siblings order by the fractional `Node.order` key: a moved item gets a fresh key relative to its new siblings, all others keep theirs. `resolve`/`find_slot` walk the tree by path; moves are slot detach/attach carrying the whole subtree. Legacy flat `pages` (pre-tree databases) migrates into `menu` via `migrate_v1`. The app owns the `Data` object; reads are plain attribute access, writes in `kanta.transaction(...)`.
|
||||
|
||||
Every content/settings write calls `_invalidate_pages()` in state.py, which clears the rendered-body LRU and bumps an in-memory render generation embedded in page ETags, so nav-affecting changes invalidate caches. (This used to be a persisted `Data.version` counter — cache invalidation is not database state, so the field was dropped; old databases lose the key on re-serialization.)
|
||||
|
||||
## Files
|
||||
|
||||
Files are content-addressed (blake3[:12] + extension) and stored **on disk** under `<hostname>/files/` (path from `PAGERITE_FILES`), served at `/_f/{name}` with immutable caching. Uploaded raster images (except GIF) and SVGs (rasterized) get a set of derivatives: the untouched original under `<hash>.orig<ext>` (internal only — it may carry EXIF data and is never served; SVG originals stay servable as `<hash>.svg`), a mediapreview-recompressed AVIF (`<hash>.avif`, thumbnailed to `IMAGE_MAXSIZE` at `IMAGE_QUALITY`), and WebP/JPEG fallbacks re-encoded from the AVIF at lower quality (`IMAGE_WEBP_QUALITY`/`IMAGE_JPG_QUALITY`, chosen for similar-or-smaller file size). Pages link the bare `/_f/<hash>` and the server negotiates by Accept header: a format is served only when listed explicitly (`image/avif` → AVIF, `image/webp` → WebP, anything else including `image/*` and `*/*` → JPEG); an explicit extension in the URL pins the format. Responses carry `vary: accept`. Favicons uploaded in settings go through the same pipeline at `FAVICON_MAXSIZE` (192px). Existing databases are updated by `migrate_v2` (link rewrite plus on-disk derivative backfill). Deleting any name of a hash removes the whole group. The `FileStore` in files.py caches every file in RAM, both uncompressed and zstd-compressed (the compressed copy only when smaller), so `/_f` answers both encodings without disk reads. Pages reference files by absolute `/_f/` URLs so hierarchy moves never break them. Pre-refactor databases kept the blobs in a `Data.files` kanta field; the kanta migration `pagerite/migrations.py::migrate_v1` writes them to disk on open and drops the field (removed from `Data`). Fetched favicons of external analytics sites live in the same store (see `docs/analytics.md`).
|
||||
|
||||
## Banners
|
||||
|
||||
`Node.banner` is a raw trusted HTML snippet for the header banner (img, styled div, canvas+script...); empty inherits from the node's ancestors (front page last). It is rendered AFTER the banner design's artwork, so author code (e.g. a `<style>` override) always wins over the design's own styles.
|
||||
|
||||
`Node.banner_design` picks a banner design: a theme folder name whose `banner.css` styles it and whose `banner.html` (arbitrary markup: canvas + style + script) or `banner.svg` supplies the inline artwork (wrapped in `div[data-design]`); "" = explicitly no design, None = inherit (nearest ancestor, front page last, then the active theme's own design if it ships banner.css/banner.svg/banner.html). The design's banner.css lives in `<head>` (id `pagerite-banner`) between the theme and the custom CSS — a `<link>` in dev, an inline `<style>` in production.
|
||||
|
||||
## Card images
|
||||
|
||||
`Node.image` names a content-addressed store file (12-hex hash, served at `/_f/{name}`) used as the page's card image: `og:image`/`twitter:image` meta and the card cover in listings. The effective image follows the priority: the node's own `image`, then one mined from the rendered article (hero → first raster → first SVG), then the inherited image (the nearest ancestor's, the front page last). The special value `@favicon` resolves to the site icon (`Data.favicon`) at render time — it follows favicon changes rather than copying the current icon. Set in the editor's banner panel (upload → `PUT /_api/files/{name}` or paste from the pasteboard — an image uploads, an image URL is sent as the `image` setting itself and fetched/stored server-side by the save handler, since cross-origin URLs are CORS-blocked for the browser — then a `save` with `image` over the editor WebSocket; the site-icon button saves `@favicon`), stored at `IMAGE_MAXSIZE` like other uploads. `twitter:card` picks `summary_large_image` vs `summary` from the image's probed dimensions (views.py `_image_dims`).
|
||||
|
||||
`Node.large: bool | None` overrides the automatic card-mode pick per article: None = automatic, False forces a small card, True a large one. Unlike `image`, it is NOT inherited down the tree. Set from the banner panel's card previews (a `save` with `large` over the editor WebSocket).
|
||||
|
||||
## Site settings
|
||||
|
||||
`Data.brand` is the site name (header link + `<title>` suffix), editable in the site editor via `/_api/settings`; empty = no header link and no `<title>` suffix.
|
||||
|
||||
`Data.brand_html` is raw trusted HTML replacing the brand link entirely (rendered in a `#brand` div on top of the banner, next to the nav) — site-wide, not per-page like banners; edited in the site editor with image/video upload into the content-addressed file store.
|
||||
|
||||
`Data.theme` is the active theme name (empty = none/base only); themes are folders in `pagerite/themes/{name}` containing `theme.css` and/or `banner.css` (+ `banner.svg` artwork and any extra assets the CSS references, like summer's `grass.svg`), served by the backend at `/_themes/{name}/...` — read from disk per request (etag by mtime), never built, so on-disk edits show on the next page load even in prod. The theme selector and banner-design selector enumerate these folders via `GET /_api/settings`.
|
||||
|
||||
`Data.transition` is the page-transition design name (default `cube`): a theme folder shipping `transition.css`, injected as `#pagerite-transition` on every page and selected in the site editor (the selector enumerates `transition.css` folders via `GET /_api/settings`). See `docs/themes-and-assets.md`.
|
||||
|
||||
`Data.custom_css` is raw trusted CSS injected inline in every page `<head>` (id `pagerite-user`) and swapped during fetch-navigation; editable in the site editor. Font picks (heading/body/brand) in the site editor are stored as plain `:root` rows in `custom_css` (`--font-body: var(--font-source-sans);` format — parsed out and rewritten on change, the `:root` block added/removed as needed), referencing the per-family variables (`--font-source-sans` etc.) from `pagerite.css`; the base stylesheet's `--font-brand` defaults to `var(--font-heading)`.
|
||||
|
||||
`Data.favicon` names a file in the content-addressed store (on disk under `<hostname>/files/`), uploaded/cleared in the site editor via `PUT`/`DELETE /_api/settings/favicon`; when set it is linked as `<link rel="icon">` on every page, otherwise browsers fall back to the build's `/favicon.ico` by convention.
|
||||
@@ -1,253 +1,55 @@
|
||||
# Pagerite Design Principles
|
||||
|
||||
Pagerite is a single-user CMS/blog. This document records the initial
|
||||
high-level design decisions; it will be refined as the implementation
|
||||
evolves.
|
||||
Pagerite is a single-user CMS/blog. This document records the initial high-level design decisions; it will be refined as the implementation evolves.
|
||||
|
||||
## Architecture
|
||||
|
||||
- **Server-side rendered.** FastAPI serves complete HTML pages, generated in
|
||||
Python with **html5tagger**. There is no client-side templating or SPA for
|
||||
the public site.
|
||||
- **Vue only where interactivity demands it.** Small interactive islands
|
||||
(editing tools mainly) are Vue components mounted into specific elements of
|
||||
the server-rendered pages. The public reading experience has no scripting
|
||||
requirement.
|
||||
- **Persistence via kanta.** Content is stored in an asyncio-friendly kanta
|
||||
database. Rendering happens on the fly on each request — there are no
|
||||
pre-built static artifacts.
|
||||
- **Server-side rendered.** FastAPI serves complete HTML pages, generated in Python with **html5tagger**. There is no client-side templating or SPA for the public site.
|
||||
- **Vue only where interactivity demands it.** Small interactive islands (editing tools mainly) are Vue components mounted into specific elements of the server-rendered pages. The public reading experience has no scripting requirement.
|
||||
- **Persistence via kanta.** Content is stored in an asyncio-friendly kanta database. Rendering happens on the fly on each request — there are no pre-built static artifacts.
|
||||
|
||||
## Content model
|
||||
|
||||
- Pages and blog articles are fundamentally the same kind of thing: named
|
||||
pieces of content. The blog/website distinction is blurred; an article is
|
||||
just a page (possibly with metadata such as a publication date and
|
||||
listing in a feed).
|
||||
- **Pretty URLs.** Content is addressed by its name (slug), not by technical
|
||||
constructs — no `/cms/...` or `/blog/post1` prefixes. Slugs usually live
|
||||
directly at the site root; structured content may nest
|
||||
(`/docs/design-principles`-style). The URL space is the author's, so
|
||||
reserved prefixes must be kept few and deliberate: everything internal
|
||||
lives under `/_` (`/_api/`, `/_f/`, `/_assets/`). The only
|
||||
other reserved root path is `/favicon.ico`, served from the build.
|
||||
Slugs are lowercase ASCII letters, digits, hyphens and underscores
|
||||
(`[a-z0-9_-]`; input is transliterated and filtered as you type, and a
|
||||
new page's empty slug is derived from its title), may not begin with
|
||||
`_` or `.`, and such URLs are never looked up as content.
|
||||
- **Single user, trusted author.** No auth concerns in the core design.
|
||||
Everything published is public; only editing tools will later sit behind
|
||||
access control (external SSO when that time comes). The author is trusted
|
||||
to create well-meaning slugs and content — no sanitization for safety,
|
||||
only for correctness.
|
||||
- **Commenting** is not planned now but the model should not preclude it
|
||||
later.
|
||||
- Pages and blog articles are fundamentally the same kind of thing: named pieces of content. The blog/website distinction is blurred; an article is just a page (possibly with metadata such as a publication date and listing in a feed).
|
||||
- **Pretty URLs.** Content is addressed by its name (slug), not by technical constructs — no `/cms/...` or `/blog/post1` prefixes. Slugs usually live directly at the site root; structured content may nest (`/docs/design-principles`-style). The URL space is the author's, so reserved prefixes must be kept few and deliberate: everything internal lives under `/_` (`/_api/`, `/_f/`, `/_assets/`). The only other reserved root path is `/favicon.ico`, served from the build. Slugs are lowercase ASCII letters, digits, hyphens and underscores (`[a-z0-9_-]`; input is transliterated and filtered as you type, and a new page's empty slug is derived from its title), may not begin with `_` or `.`, and such URLs are never looked up as content.
|
||||
- **Single user, trusted author.** No auth concerns in the core design. Everything published is public; only editing tools will later sit behind access control (external SSO when that time comes). The author is trusted to create well-meaning slugs and content — no sanitization for safety, only for correctness.
|
||||
- **Commenting** is not planned now but the model should not preclude it later.
|
||||
|
||||
## Authoring format
|
||||
|
||||
- Content is written in **Markdown** with powerful extensions (tables,
|
||||
footnotes, code highlighting, etc.).
|
||||
- **Embedded HTML is passed through unfiltered**, including inline scripts
|
||||
and other dynamic content the author wants to post. This is safe by the
|
||||
single-trusted-author assumption above.
|
||||
- Renderer: **markdown-it-py** with mdit-py-plugins (footnotes, definition
|
||||
lists, task lists, brace-attributes; tables and strikethrough from the
|
||||
default preset), with `html=True` for raw passthrough,
|
||||
`typographer=True` for SmartyPants-style replacements in body text (curly
|
||||
quotes, `--` / `---` → en / em dashes, `...` → ellipsis, `(c)` → ©, etc.),
|
||||
and `breaks=True` so single line breaks inside paragraphs become `<br>`.
|
||||
Code spans/blocks and raw HTML are left untouched. Fenced code blocks are
|
||||
highlighted server-side with
|
||||
**Pygments** (`nowrap` spans styled by
|
||||
`/_assets/pygments-*.css`, which maps every token class onto the `--code-*`
|
||||
variables; the base stylesheet defines light and dark palette sets resolved
|
||||
via `light-dark()`, so each theme gets the set matching its `color-scheme`
|
||||
and may only retint `--code-bg` to keep the well in the page's color
|
||||
family); a JS copy button appears on hover. Should this
|
||||
prove limiting, we implement our own renderer on top of html5tagger,
|
||||
which we already use for all HTML generation.
|
||||
- **Files are content-addressed.** Uploads (`PUT /_api/files/{filename}`)
|
||||
are stored by content hash — blake3, first 6 bytes hex + original
|
||||
extension — and served immutable from `/_f/{hash}.ext`. Absolute URLs
|
||||
that survive page renames and dedupe identical content; pages no longer
|
||||
own files. An image standing alone in its paragraph becomes a block
|
||||
`<figure>` — with `<figcaption>` when it has a title; images inline
|
||||
with text and raw `<img>` HTML stay plain inline images. Positioning
|
||||
is by attribute classes:
|
||||
`{.right}` — `{.right}`, `{.left}` float at
|
||||
30% of the text column (the caption wraps within it; an explicit
|
||||
`width=300` makes the figure shrink-wrap the image instead),
|
||||
`{.wide}` goes full bleed (viewport edge to edge, or up to the docked
|
||||
editor; the sidebar stacks on top of it); plain attributes like `width=300`
|
||||
work too. Headings (h1/h2) clear floats, so images never overflow into the
|
||||
next section.
|
||||
- Content is written in **Markdown** with powerful extensions (tables, footnotes, code highlighting, etc.).
|
||||
- **Embedded HTML is passed through unfiltered**, including inline scripts and other dynamic content the author wants to post. This is safe by the single-trusted-author assumption above.
|
||||
- Renderer: **markdown-it-py** with mdit-py-plugins (footnotes, definition lists, task lists, brace-attributes, admonitions and `::: name` containers — generic `<div class="name">` wrappers (the name may be followed by brace attributes: `::: aside {.right}`), of which `::: aside` floats as a muted side box and `{.margin}` / `::: margin` marks any block a margin note — on all but phone widths they are taken out of flow into the side zone at the article's start edge (left in LTR, right in RTL — the region the nav sidebar overlays, or the sidebar's own track when the layout reserves one) and the text never moves — and `::: nocols` opts its section out of column layout; tables and strikethrough from the default preset), GitHub-style alerts (`> [!NOTE]` / TIP / IMPORTANT / WARNING / CAUTION, rendered in the admonition callout styling), with `html=True` for raw passthrough, `typographer=True` for SmartyPants-style replacements in body text (curly quotes, `--` / `---` → en / em dashes, `...` → ellipsis, `(c)` → ©, etc.), and `breaks=True` so single line breaks inside paragraphs become `<br>` — including inside blockquotes, where every newline is kept and a blank `>` line starts a new paragraph. Code spans/blocks and raw HTML are left untouched. Fenced code blocks are highlighted server-side with **Pygments** (`nowrap` spans styled by `/_assets/pygments-*.css`, which maps every token class onto the `--code-*` variables; the base stylesheet defines light and dark palette sets resolved via `light-dark()`, so each theme gets the set matching its `color-scheme` and may only retint `--code-bg` to keep the well in the page's color family); a JS copy button appears on hover. Should this prove limiting, we implement our own renderer on top of html5tagger, which we already use for all HTML generation.
|
||||
- **Files are content-addressed.** Uploads (`PUT /_api/files/{filename}`) are stored on disk (`<hostname>/files/`, RAM-cached uncompressed + zstd) by content hash — blake3, first 6 bytes hex + original extension — and served immutable from `/_f/…`. Raster images (not GIF) and SVGs (rasterized) are recompressed via mediapreview: the original is kept as `{hash}.orig{ext}` (internal only, never served — it may carry EXIF data; SVG originals stay servable as `{hash}.svg`) while pages link the extension-less `/_f/{hash}` and the server picks from the derivatives (`{hash}.avif` / `{hash}.webp` / `{hash}.jpg`) by Accept header — a format only when listed explicitly (`image/avif` → AVIF, `image/webp` → WebP, otherwise JPEG), with `vary: accept`; an explicit extension in the URL pins the format. Absolute URLs that survive page renames and dedupe identical content; pages no longer own files. An image standing alone in its paragraph becomes a block `<figure>` — with `<figcaption>` when it has a title; images inline with text and raw `<img>` HTML stay plain inline images. Positioning is by attribute classes: `{.right}` — `{.right}`, `{.left}` float at 30% of the text column, to its end/start edge following the text direction (the caption wraps within it; an explicit `width=300` makes the figure shrink-wrap the image instead), `{.margin}` makes it a margin note, placed in the side zone at the text's start edge on all but phone widths, `{.wide}` goes full bleed (viewport edge to edge, or up to the docked editor; the sidebar stacks on top of it); plain attributes like `width=300` work too. The same brace syntax on a block's last line (no blank line between) applies to the whole block: a paragraph ending with `{.wide}` becomes a full-width element that breaks out of the column layout, and space-separated at the end of a text line (`some text {.small}`) the braces likewise belong to the block — a space is what keeps them off an image or link ending the line, which keep their own directly-attached attrs; text size classes `{.small}` / `{.large}` / `{.huge}` (em-based) work on any block; written on the line after a block it applies to that preceding block — this is how headings, `::: containers` and code fences take classes (a wide code fence goes full bleed like a wide figure). Headings (h1/h2) clear floats, so images never overflow into the next section.
|
||||
|
||||
## Page structure and navigation
|
||||
|
||||
- All pages share one static layout, defined once as an **html5tagger
|
||||
Template** with capitalized placeholders (`Title`, `Banner`, `Nav`,
|
||||
`Sidebar`, `Main`) filled per request. The dynamic regions carry stable
|
||||
ids (`#page-banner`, `#nav`, `#sidebar`, `#main`).
|
||||
- The page top is a **full-width banner header** with the site name and the
|
||||
navigation bar overlaid on it — no separate chrome header. The banner
|
||||
combines two layers, stacked in `#page-banner` (a grid, so they overlay):
|
||||
first the **banner design** — a named design living in a theme folder
|
||||
(`pagerite/themes/{name}/banner.css` plus artwork as `banner.html` —
|
||||
arbitrary markup like canvas + style + script — or `banner.svg`),
|
||||
chosen per page via
|
||||
`Node.banner_design` (a design name, "" for none, None to inherit from
|
||||
the nearest ancestor, then the front page, then the active theme's own
|
||||
design). The artwork is inlined into a `div[data-design]` wrapper: SVG
|
||||
artwork can be recolored from the theme stylesheet (corporate's single
|
||||
SVG serves both light and dark mode via `var()`-driven stops). Second,
|
||||
**per-page author code**: `Node.banner` holds an arbitrary trusted HTML
|
||||
snippet (an image, a styled div, canvas + script — anything), resolved by
|
||||
walking up the node's ancestors to the front page and rendered **after**
|
||||
the design artwork, so author styles always win over the design's own.
|
||||
The base stylesheet falls back to a plain gradient. There is deliberately
|
||||
no scrim fading the banner into the page background — any such fade would
|
||||
ruin user-supplied designs; themes that want one bake it into their SVG
|
||||
(purple does).
|
||||
- **Fetch-navigation.** Links are plain `<a href>`; a small script
|
||||
(`frontend/src/pagerite.js`) intercepts same-origin clicks, fetches the
|
||||
page, and swaps the `#page-banner`, `#nav`, `#sidebar` and `#main` regions,
|
||||
the document title, and the site-wide custom CSS (`<style id="pagerite-user">`
|
||||
in `<head>`), keeping the rest of `<head>` and the layout chrome. Without JS
|
||||
everything works as normal page loads. Scripts inside fetched banner and
|
||||
content regions are re-created so they execute. Swaps run inside `document.startViewTransition` for a rotating
|
||||
cube page transition (CSS adapted from termotohtori.fi — the
|
||||
`::view-transition*` block is fragile, do not tweak; skipped under
|
||||
`prefers-reduced-motion`). Navigation within the same top-level section
|
||||
crossfades instead of rotating; browser back navigation rotates in
|
||||
reverse.
|
||||
- **The site structure is a tree of labels.** `Data.menu` holds the
|
||||
top-level items by slug, each with `children` keyed by slug — the URL
|
||||
path is the slug chain. The front page is a top-level node with slug ""
|
||||
(an item *parallel* to the other main level pages, not their parent) and
|
||||
cannot have children. The header navbar holds only the top level; a
|
||||
top-level item is highlighted when viewing any of its subpages. When the
|
||||
current page is inside a main level section with children, those direct
|
||||
children are listed in a **left sidebar** (`#sidebar`), one level deep.
|
||||
The sidebar exists only when there is something to navigate — sections
|
||||
with fewer than two published items, leaf pages and the front page render
|
||||
no aside element at all. Other sections' subitems
|
||||
are never shown without navigating into them first.
|
||||
- **Landing pages are optional.** Every label can either have content
|
||||
(`Node.content`, a Markdown page) or none — a content-less label renders
|
||||
a placeholder page (404 with a pen to create it) instead of redirecting,
|
||||
while nav links to it point straight at its first child, so categories
|
||||
need no filler content and normal navigation never sees the placeholder.
|
||||
Title and slug of every label are editable; renaming a
|
||||
slug moves the whole subtree. The sidebar never lists the section
|
||||
itself, avoiding title duplication with the navbar.
|
||||
- **Menu order is manual.** Each node has a fractional `order` key among
|
||||
its siblings; reordering/moving writes only the moved node (it takes a
|
||||
fresh value halfway between its new siblings; all other items keep
|
||||
theirs). New pages append at the end of their menu. Structure edits
|
||||
(reorder, move/rename with the whole subtree, retitle) go through
|
||||
`POST /_api/structure` and the editor's structure panel.
|
||||
- All pages share one static layout, defined once as an **html5tagger Template** with capitalized placeholders (`Title`, `Banner`, `Nav`, `Sidebar`, `Main`) filled per request. The dynamic regions carry stable ids (`#page-banner`, `#nav`, `#sidebar`, `#main`).
|
||||
- The page top is a **full-width banner header** with the site name and the navigation bar overlaid on it — no separate chrome header. The banner combines two layers, stacked in `#page-banner` (a grid, so they overlay): first the **banner design** — a named design living in a theme folder (`pagerite/themes/{name}/banner.css` plus artwork as `banner.html` — arbitrary markup like canvas + style + script — or `banner.svg`), chosen per page via `Node.banner_design` (a design name, "" for none, None to inherit from the nearest ancestor, then the front page, then the active theme's own design). The artwork is inlined into a `div[data-design]` wrapper: SVG artwork can be recolored from the theme stylesheet (corporate's single SVG serves both light and dark mode via `var()`-driven stops). Second, **per-page author code**: `Node.banner` holds an arbitrary trusted HTML snippet (an image, a styled div, canvas + script — anything), resolved by walking up the node's ancestors to the front page and rendered **after** the design artwork, so author styles always win over the design's own. The base stylesheet falls back to a plain gradient. There is deliberately no scrim fading the banner into the page background — any such fade would ruin user-supplied designs; themes that want one bake it into their SVG (purple does).
|
||||
- **Fetch-navigation.** Links are plain `<a href>`; a small script (`frontend/src/pagerite.js`) intercepts same-origin clicks, fetches the page, and swaps the `#page-banner`, `#nav`, `#sidebar` and `#main` regions, the document title, and the site-wide custom CSS (`<style id="pagerite-user">` in `<head>`), keeping the rest of `<head>` and the layout chrome. Without JS everything works as normal page loads. Scripts inside fetched banner and content regions are re-created so they execute. Swaps run inside `document.startViewTransition` for the page transition selected in the site settings (`Data.transition`; the `cube` design — CSS adapted from termotohtori.fi, fragile, do not tweak — rotates, mirrored on browser back; `crossfade` fades; both skipped under `prefers-reduced-motion`). With `cube`, navigation within the same top-level section crossfades instead of rotating.
|
||||
- **The site structure is a tree of labels.** `Data.menu` holds the top-level items by slug, each with `children` keyed by slug — the URL path is the slug chain. The front page is a top-level node with slug "" (an item *parallel* to the other main level pages, not their parent) and cannot have children. The header navbar holds only the top level; a top-level item is highlighted when viewing any of its subpages. A page with published children lists them as **cards** after its content (the child page's card image as the cover — its own `Node.image` when set, else mined like the og tags, else the inherited one — laid out by the child's card-mode selection: full-card cover with the title overlaid, or a golden-ratio split with a square image and the title in the top part, the description below it on a translucent band); a **left sidebar** (`#sidebar`) with the section's sub-navigation appears only from the second level down, when there is something to navigate — main-level pages, sections with fewer than two published items, leaf pages and the front page render no aside element at all. Other sections' subitems are never shown without navigating into them first.
|
||||
- **Landing pages are optional.** Every label can either have content (`Node.content`, a Markdown page) or none — a content-less label renders a 404 page listing its children as cards (with a pen to create the landing page) instead of redirecting, while nav links to it point straight at its first child, so categories need no filler content and normal navigation never sees the 404. Title and slug of every label are editable; renaming a slug moves the whole subtree. The sidebar never lists the section itself, avoiding title duplication with the navbar.
|
||||
- **Menu order is manual.** Each node has a fractional `order` key among its siblings; reordering/moving writes only the moved node (it takes a fresh value halfway between its new siblings; all other items keep theirs). New pages append at the end of their menu. Structure edits (reorder, move/rename with the whole subtree, retitle) go through `POST /_api/structure` and the editor's structure panel.
|
||||
- Unpublished pages are hidden from both nav and URL access (404).
|
||||
|
||||
## Reading experience
|
||||
|
||||
- The article column is sized by the **viewport, never by content**: a
|
||||
symmetric grid (`1fr minmax(0, 78rem) 1fr`) with flexible gutters keeps
|
||||
the layout stable across navigation. The sidebar occupies the left
|
||||
gutter, the right gutter balances it; wide screens get columns inside
|
||||
long articles without changing the article's width.
|
||||
- A gentle **scroll-reveal** of headings, figures and block-level elements
|
||||
(IntersectionObserver). It is layout-level: articles need no support
|
||||
for it, and `prefers-reduced-motion` disables all motion.
|
||||
- The article column is sized by the **viewport, never by content**: a symmetric grid (`1fr minmax(0, 78rem) 1fr`) with flexible gutters keeps the layout stable across navigation. The sidebar occupies the left gutter, the right gutter balances it. Long articles (flagged `.multicol` by the backend render) lift the cap and become a bounded **composition**, centered in the available space with the surplus left vacant: a fluid text lane (up to 42rem) plus a 16rem **side zone at the article's left** — the region the nav sidebar overlays — which hosts margin boxes (`.margin`, `::: aside`, margin figures) at all but phone widths, without the text ever moving. On pages with a sidebar, the sidebar gets its own track at every width — flexible, 12rem when space is tight and growing up to 150% (18rem) once the viewport has room beyond the article, the sidebar keeping its left side on the viewport's edge — and the track is the left lane instead: no in-article zone, the text lane runs fluid up to 86rem leaning on the viewport's right edge (surplus extends the left lane), and the boxes hang into the lane off the article's left border (growing leftward with it, up to 18rem), sliding under the translucent sticky nav. Once two lanes fit beside the zone (≥96rem available in `main`), the text flows in two fluid lanes (36rem minimum, capped at 102rem total — technical content wants the wider lanes, and wider windows just add vacant space). The stages step by the space actually available in `main` (container queries + `cqw` units, so the docked editor's inset is automatic). `.wide` figures on multicol pages bleed to the viewport edges measured from `main` (`cqw`), sliding under the sidebar. The backend splits the body into `.colseg` segments at h1/h2 headings and `.wide` elements (full-width separators, never inside columns); margin boxes stay inside the segment at their anchor point and the CSS takes them out of flow — absolutely positioned off the article's left border into the zone, the columns flowing through unaffected — tagging segments that hold enough text in at least two paragraphs (or one long enough to split) with `.cols` — code blocks are excluded from that measure, a `::: nocols` container opts its whole section out, and column-filling paragraphs are marked `.breakable` so they may split across the column gap (shorter paragraphs stay whole). On wide single-column pages (≥104rem), margin boxes lean into the vacant left gutter as well, growing with it up to 18rem.
|
||||
- A gentle **scroll-reveal** of headings, figures and block-level elements (IntersectionObserver). It is layout-level: articles need no support for it, and `prefers-reduced-motion` disables all motion.
|
||||
|
||||
## Styling
|
||||
|
||||
- The base stylesheet `frontend/src/assets/pagerite.css` provides the layout,
|
||||
typography and interaction rules with conservative CSS variables. A theme layer
|
||||
(`pagerite/themes/{name}/theme.css` — currently `purple`, `corporate`
|
||||
and `nitro`, served by the backend at `/_themes/{name}/theme.css` straight
|
||||
from disk, never built) overrides those variables and
|
||||
adds the visual styling; `Data.theme` selects the active theme (empty = none/base
|
||||
only) and the site editor can switch it, choosing from the theme folders
|
||||
found on disk. Vue may add per-component styles on top
|
||||
where needed. The corporate and nitro themes switch palettes automatically via
|
||||
`prefers-color-scheme` (corporate is light-first with a matching dark palette;
|
||||
nitro a warm light-grey page or, in dark mode, a deep violet one — its dark
|
||||
banner and orange accents carry over unchanged); purple (dusk) uses one
|
||||
fixed palette for everyone. Themes may restyle structural details the base
|
||||
leaves plain — heading colors and underlines, list markers, nav treatment,
|
||||
brand sizing. A theme folder may also ship a **banner design**
|
||||
(`banner.css` + `banner.svg`), selectable per page independently of the
|
||||
active theme. The banner artwork has scroll parallax: pagerite.js sets the
|
||||
`--pry` scroll parameter on `<html>` (event-driven, so it is still when the
|
||||
page is idle), the banner contents drift within their window (with scale
|
||||
overscan so no edge shows), and designs may key their own effects off the
|
||||
same parameter — purple's sun rises as you scroll.
|
||||
- Fonts, the shared stylesheet and pygments styles
|
||||
live under `frontend/src/assets/` and are emitted as hashed assets under
|
||||
`/_assets/`
|
||||
(Source Serif 4 for headings, Source Sans 3 for body, Fira Code for code
|
||||
by default; Fraunces, Literata, Cormorant, Playfair Display, Inter,
|
||||
Montserrat, Cause, Exo 2 and New Rocker kept as woff2 options with
|
||||
local `@font-face`, variable-weight where available). No third-party
|
||||
requests.
|
||||
- The base stylesheet `frontend/src/assets/pagerite.css` provides the layout, typography and interaction rules with conservative CSS variables. A theme layer (`pagerite/themes/{name}/theme.css` — currently `purple`, `corporate` and `nitro`, served by the backend at `/_themes/{name}/theme.css` straight from disk, never built) overrides those variables and adds the visual styling; `Data.theme` selects the active theme (empty = none/base only) and the site editor can switch it, choosing from the theme folders found on disk. Vue may add per-component styles on top where needed. The corporate and nitro themes switch palettes automatically via `prefers-color-scheme` (corporate is light-first with a matching dark palette; nitro a warm light-grey page or, in dark mode, a deep violet one — its dark banner and orange accents carry over unchanged); purple (dusk) uses one fixed palette for everyone. Themes may restyle structural details the base leaves plain — heading colors and underlines, list markers, nav treatment, brand sizing. A theme folder may also ship a **banner design** (`banner.css` + `banner.svg`), selectable per page independently of the active theme. The banner artwork has scroll parallax: pagerite.js sets the `--pry` scroll parameter on `<html>` (event-driven, so it is still when the page is idle), the banner contents drift within their window (with scale overscan so no edge shows), and designs may key their own effects off the same parameter — purple's sun rises as you scroll.
|
||||
- Fonts, the shared stylesheet and pygments styles live under `frontend/src/assets/` and are emitted as hashed assets under `/_assets/` (Source Serif 4 for headings, Source Sans 3 for body, Fira Code for code by default; Fraunces, Literata, Cormorant, Playfair Display, Inter, Montserrat, Cause, Exo 2 and New Rocker kept as woff2 options with local `@font-face`, variable-weight where available). No third-party requests.
|
||||
|
||||
## Editing
|
||||
|
||||
- Editing happens **in place**, in two modes opened by two pens:
|
||||
- **Page mode** — the 🖊️ next to a page's heading (including 404s, which
|
||||
is how new pages start) opens a CodeMirror Markdown editor docked to
|
||||
the left of the article: the host sits inside `#content` (below the
|
||||
banner, never over the footer), the content shifts right and the
|
||||
sidebar hides while editing. Preview renders server-side per keystroke
|
||||
(no debouncing) straight into the visible article's heading and body.
|
||||
- **Site mode** — the 🖊️ on the banner opens a panel with the site
|
||||
**brand** (applied to the header live), a **theme** selector (swapping
|
||||
the theme stylesheet in place), **font** picks (heading/body/brand —
|
||||
stored as plain `:root` rows inside the custom CSS, referencing the base
|
||||
stylesheet's per-family font variables), a **site-wide custom CSS** field (injected
|
||||
into `<style id="pagerite-user">` in the live page head and swapped during
|
||||
fetch-navigation), the page's **banner design** selector (inherit /
|
||||
none / any design found on disk, inherited by children), the page's
|
||||
**banner HTML** field (supplementing the design, previewed into the
|
||||
real banner region, so you see exactly which banner you're editing) and
|
||||
the **structure tree**. Everything saves immediately as you edit — no
|
||||
save button, no edit mode.
|
||||
- Clicking a pen again closes the editor (without saving; a dirty preview
|
||||
reloads the page). The pens are `<button>`s wired up by `pagerite.js` —
|
||||
editing is an action, not a navigation. The editor's WebSocket
|
||||
**reconnects automatically** with local text and pending saves preserved.
|
||||
(All users are trusted authors for now; access control later with
|
||||
SSO.)
|
||||
- **CodeMirror 6** for Markdown editing (no WYSIWYG), title/published
|
||||
controls.
|
||||
Images can be pasted straight into the editor or chosen via a file
|
||||
input: they upload to the content store (`PUT /_api/files/...`) and
|
||||
insert `` at the cursor.
|
||||
- The **structure panel** (vue-draggable tree of the whole site, in site
|
||||
mode) covers page management: reorder any menu level, drag across
|
||||
sections, add, delete (two clicks: the button arms, then deletes — no
|
||||
dialogs). Every node is a real label — content-less category rows offer
|
||||
a ➕ to give them a landing page.
|
||||
Deleting a category removes only its landing page (the label and its
|
||||
subpages stay). Every non-empty list ends with a ➕ row that starts a
|
||||
new page as a local-only tree row at that level; the row can be dragged
|
||||
into place before its title and slug are filled in and is persisted only
|
||||
on commit. While dragging, these ➕ rows double as "end of this list"
|
||||
drop targets; dropping ON the lower part of a row makes the page that
|
||||
row's first child (even a leaf's, creating a sublist), while a row's
|
||||
exposed top edge inserts a sibling before it. A dragged row's
|
||||
indentation previews the target list's depth. Rows are always
|
||||
editable: titles save while typing, slug edits commit on blur/Enter
|
||||
since they rename the path (moving the whole subtree). The front page
|
||||
is the root row with an empty slug — renaming it away leaves no front
|
||||
page ("/" redirects to the first nav item), and giving another
|
||||
top-level row the empty slug makes it the front page.
|
||||
- Preview and saving go over a **WebSocket** (`/_api/ws/editor`) with a
|
||||
stateless JSON protocol (`open`/`render`/`save`; on save all fields are
|
||||
optional and absent ones keep their old values, `move_from` renames),
|
||||
avoiding REST polling and races. Rendering always stays server-side.
|
||||
- A REST API also exists for scripting, all under `/_api/`:
|
||||
`GET pages` (the full tree), `PUT/DELETE pages/{path}`,
|
||||
`GET/PUT settings` (site brand, theme and custom CSS), `POST structure`
|
||||
(reorder/move/retitle), file upload/removal via `PUT/DELETE files/{name}`.
|
||||
- On startup, seed pages from `pagerite/seed.py` are added **only if
|
||||
missing** — existing user content is never overwritten.
|
||||
- **Page mode** — the 🖊️ next to a page's heading (including 404s, which is how new pages start) opens a CodeMirror Markdown editor docked to the left of the article: the panel is fixed to the viewport's left edge (its top tracks the banner's bottom until the banner scrolls away), the content shifts right and the sidebar hides while editing. Preview renders server-side per keystroke (no debouncing) and swaps the whole visible article content in one go (the edit pen and category cards survive the swap).
|
||||
- **Site mode** — the ⚙️ at the top right (after the 📊 analytics link, before login) opens a panel with the site **brand** (applied to the header live), a **theme** selector (swapping the theme stylesheet in place), a **page transition** selector (`cube`/`crossfade`, swapping `#pagerite-transition` in place), **font** picks (heading/body/brand — stored as plain `:root` rows inside the custom CSS, referencing the base stylesheet's per-family font variables), a **site-wide custom CSS** field (injected into `<style id="pagerite-user">` in the live page head and swapped during fetch-navigation), the page's **banner design** selector (inherit / none / any design found on disk, inherited by children), the page's **banner HTML** field (supplementing the design, previewed into the real banner region, so you see exactly which banner you're editing) and the **structure tree**. Everything saves immediately as you edit — no save button, no edit mode.
|
||||
- Clicking a pen again closes the editor (without saving; a dirty preview reloads the page). The pens are `<button>`s wired up by `pagerite.js` — editing is an action, not a navigation. The editor's WebSocket **reconnects automatically** with local text and pending saves preserved. (All users are trusted authors for now; access control later with SSO.)
|
||||
- **CodeMirror 6** for Markdown editing (no WYSIWYG), title/published controls. Images can be pasted straight into the editor or chosen via a file input: they upload to the content store (`PUT /_api/files/...`) and insert `` at the cursor.
|
||||
- The **structure panel** (vue-draggable tree of the whole site, in site mode) covers page management: reorder any menu level, drag across sections, add, delete (two clicks: the button arms, then deletes — no dialogs). Every node is a real label — content-less category rows offer a ➕ to give them a landing page. Deleting a category removes only its landing page (the label and its subpages stay). Every non-empty list ends with a ➕ row that starts a new page as a local-only tree row at that level; the row can be dragged into place before its title and slug are filled in and is persisted only on commit. While dragging, these ➕ rows double as "end of this list" drop targets; dropping ON the lower part of a row makes the page that row's first child (even a leaf's, creating a sublist), while a row's exposed top edge inserts a sibling before it. A dragged row's indentation previews the target list's depth. Rows are always editable: titles save while typing, slug edits commit on blur/Enter since they rename the path (moving the whole subtree). The front page is the root row with an empty slug — renaming it away leaves no front page ("/" redirects to the first nav item), and giving another top-level row the empty slug makes it the front page.
|
||||
- Preview and saving go over a **WebSocket** (`/_api/ws/editor`) with a stateless JSON protocol (`open`/`render`/`save`; on save all fields are optional and absent ones keep their old values, `move_from` renames), avoiding REST polling and races. Rendering always stays server-side.
|
||||
- A REST API also exists for scripting, all under `/_api/`: `GET pages` (the full tree), `PUT/DELETE pages/{path}`, `GET/PUT settings` (site brand, theme and custom CSS), `POST structure` (reorder/move/retitle), file upload/removal via `PUT/DELETE files/{name}`.
|
||||
- On startup, seed pages from `pagerite/seed.py` are added **only if missing** — existing user content is never overwritten.
|
||||
|
||||
@@ -0,0 +1,35 @@
|
||||
# Editing interface
|
||||
|
||||
The Vue editor is a single tabbed `EditorShell.vue` mounted in a host div created inside the static document.
|
||||
|
||||
## Tabs
|
||||
|
||||
The shell hosts five kept-alive tabs (ordered site-wide first — site, structure, localization — then, after a visual break, the per-page tabs — article, banner):
|
||||
|
||||
- `PageEditor.vue` — CodeMirror + server-rendered preview over WebSocket `/_api/ws/editor`, previewing into the visible article; editor and article scrolls are linked piecewise-linearly, keyed on the section anchors' `data-line` (markdown source line the backend stamps on top-level anchored h1/h2s): the page follows the cursor (fractional, wrap-aware, scrolling only when the cursor's page position leaves the viewport, with an edge margin), the editor follows page scroll with a progress-based viewport anchor, applied instantly (the window keeps scrolling normally while any editor is open — the panel is fixed to the viewport's left edge, its top tracking the banner's bottom edge until the banner scrolls away — and the panel scrolls internally); anchored h2s carry their own edit pens that open the editor scrolled to that section; a format bar offers Markdown helpers — bold/italic/code/link/table/image upload (always block-level on a fresh blank-separated line of its own — a cursor on a non-empty line, e.g. inside an existing image tag, inserts after that line, never into it; always with an empty `""` caption, cursor inside the quotes), toggling fences (` ``` ` code blocks and `::: aside` containers share the same machinery: clicked inside one they remove it and select the content, otherwise they wrap the selection or the cursor's line, keeping it selected), and `.left`/`.right`/`.wide`/`.margin` placement toggles plus `.small`/`.large`/`.huge` text-size toggles (brace attributes on the block at the cursor, mutually exclusive within each group; on `:::` containers a placement class replaces the container name instead — `::: aside` → `::: margin`), with Ctrl/Cmd-B/I/S bindings — for the hard-to-remember syntax. Edits content and title only, never the path.
|
||||
- `BannerEditor.vue` — per-page banner HTML + banner design selector, previewed into `#page-banner`, plus the page's card image (`Node.image`, inherited by the subtree): upload and paste (pasteboard: an image uploads, an image URL is fetched and stored server-side via the `save` socket message) buttons, a site-icon button (saves `@favicon`, which resolves to the current site icon at render time, following favicon changes) and a ✕ clearing the node's own (back to inherit) — the label states which image is in use (none / set for this article, “used in /<path>/*” when it has children / the site icon / mined from the article / inherited from …) and the card previews below show it. Below it, the site's own cards preview in both modes (small and large) with the real `.card` markup and styles from pagerite.css — theme variables included, they are the site's look — scaled down via font-size (the card internals are all em, so the layout proportions match real cards exactly); both render the effective card image (the node's own, else the image the server mines from the article, else the inherited one), and the description appears only in the small format, like the backend's `_card`. The previews double as the card-mode selector for the per-article `Node.large` override: clicking one forces that mode (thin solid outline), clicking the selected one returns to automatic; under automatic the mode auto currently resolves to gets a dashed marker (both outlines — selection never shifts the layout), approximated from image presence only (the server's dimension probe is not available in the panel).
|
||||
- `SiteEditor.vue` — site brand + optional custom brand HTML with image/video upload + theme selector + page-transition selector + font picker + favicon upload — clicking the preview tile picks a new one — + site-wide custom CSS, CSS injected into `<head id="pagerite-user">`.
|
||||
- `StructureEditor.vue` — the vue-draggable structure tree with always-editable title/slug inputs per row and a per-row flag dropdown setting the page's primary language (`Node.language`, inherited by the subtree).
|
||||
- `LocalizationEditor.vue` — the site-wide translation settings: target languages as a flag grid (toggles, grouped in geographic rows; see docs/localization.md), the refresh-all-translations button, and the translator service WebSocket URL(s) to connect `scripts/translator.py` to.
|
||||
|
||||
Media uploads everywhere use the image icon buttons (pasting into the editor works too). The article, banner and site-settings pens are shorthands that open the shell on the matching tab; once open, clicking a pen switches tabs (and retargets the editors to the current page) instead of closing/remounting. The close button in the tab bar closes the shell (deliberately NOT Escape — it fired too easily by accident); tabs have no close buttons of their own. Closing only HIDES the shell — the Vue app stays mounted, so page-editor state (unsaved text included) survives until a real page reload; the editor always follows the URL, so fetch-navigating with the shell open (or before re-opening it) retargets it to the new page — unsaved text is stashed per path for the session and restored when returning, cleared on save. Saving there is explicit (Ctrl+S) and refreshes the page regions in place. Admin panels never reload the page.
|
||||
|
||||
In-place page re-rendering shared by the banner/site/structure tabs lives in `swapdoc.js` (`runScripts`/`loadPlain`: fetch a page, swap the dynamic regions, replaceState). It also exports `dropPageCache`, which the editor tabs call after any save that can alter the rendered HTML of other pages (theme, headings, structure, banners, site brand/CSS, favicon). Dropping the cache while editing avoids re-fetching every page immediately; the public runtime re-preloads visible links once the editor panel closes.
|
||||
|
||||
The page and structure tabs share one language selector: `LangSelect.vue` (small flag + dropdown) v-modeled on the shell-wide selection in `editorLang.js` (`''` = primary). While the panel is open that selection overrides the page's normal language preferences: EditorShell calls `swapdoc.setLangOverride`, which pins every `loadPlain` fetch (`?lang=`, the primary by its own code) and pagerite.js's own fetches/prefetches (`pagerite:session-lang`), until the panel closes and the override clears.
|
||||
|
||||
All WebSockets (page/banner editors, analytics view, the pagerite.js activity channel) pace their connections through `reconnect.js`: new sockets are created a staggered slot apart (a page load opens Vite's HMR socket plus several of ours at the same moment, and such bursts — like rapid retries — trip the browser's WebSocket throttling, leaving every socket to the host "pending" for minutes), a watchdog closes sockets stuck CONNECTING so they reschedule instead of hanging forever, and retries follow an exponential backoff with jitter that only a healthy connection resets. While a socket is connecting or waiting to reconnect the panel says so (`ConnNote.vue`), and the CodeMirror editors stay locked until their document arrives (typing before the doc accept would be clobbered by it).
|
||||
|
||||
## Saving behavior
|
||||
|
||||
Everything saves immediately as you edit (brand/title/CSS debounced, slug on commit since it renames the path), theme change swaps the stylesheet in place, tree rows navigate in place without transitions when focused, and the front page is a root-only row whose empty slug is editable like any other. Saves that can affect other pages drop the prefetch cache; the cache is rebuilt when the editor panel closes so navigation stays instant.
|
||||
|
||||
Every non-empty list (and the root) ends with a non-draggable plus footer row (vuedraggable `#footer` slot): clicking it starts a new pending page at that level (its slug placeholder shows the slug derived live from the title being typed), and while dragging it is the list's "end of list" drop target. Committing a pending page PUTs it with empty markdown (creates an empty page that renders with its title — saving never deletes; deletion is the page editor's explicit choice: saving trimmed-empty text issues a REST DELETE), then switches to the page editor tab for the actual writing.
|
||||
|
||||
Dropping ON the lower part of a row moves the page under that row (the child list's container invisibly overlaps its own row's bottom via negative margin — Sortable inserts it as the first child natively), while a row's exposed top edge inserts a sibling before it. Row indentation is structural (each nested list margin-indents itself), so a dragged row previews its whole subtree at the target list's depth.
|
||||
|
||||
The shell is dynamic-imported onto the content page by pagerite.js when an edit pen is clicked (the pens are injected by pagerite.js after the session validates; they carry `data-editor-src`/`data-editor-css`/`data-editor-mode`). In dev, modules load from the Vite dev server (`PAGERITE_VITE_URL`), in prod from the hashed build assets resolved via `frontend-build/.vite/manifest.json`.
|
||||
|
||||
`vite.config.js` sets `appType: 'mpa'` (no SPA fallback) and builds with `manifest: true`, `assetsDir: '_assets'` (so the build mirrors the URL space; `frontend/public/favicon.ico` lands at the build root and is served at `/favicon.ico`). JS inputs are `src/main.js`, `src/pagerite.js` and `src/analytics-main.js`, plus `src/assets/pagerite.css` as a separate stylesheet entry; theme, banner-design and transition CSS are NOT built — they live in `pagerite/themes/{name}/` and are served by the backend. There is no `index.html` source (it would shadow `/` and turn missing dev paths into an empty Vue shell). All outputs are ES modules. The build sets `preserveEntrySignatures: 'exports-only'` because main.js is consumed via dynamic `import()` for its `openEditor`/`closeEditor` exports — Vite app builds otherwise strip unused entry exports, leaving dead edit pens. In dev the backend links theme/banner-design stylesheets like in prod (`/_themes/...`); only the base CSS is Vite-injected from JS, and pagerite.js then re-appends the `#pagerite-theme`/`#pagerite-banner`/`#pagerite-transition`/`#pagerite-user` elements to restore the canonical order (base < theme < design < transition < custom CSS). In production all page assets are inlined instead (styles as `<style id="pagerite-…">` in `<head>`, scripts at the end of the body). Theme switches in the site editor swap the `#pagerite-theme` element in place — the link href in dev, the inline style's text (fetched from `/_themes/...`) in prod.
|
||||
|
||||
`vite-plugin-fastapi.js` has an auto-upgrade marker — edit `vite.config.js`, not the plugin.
|
||||
@@ -0,0 +1,34 @@
|
||||
# Frontend runtime
|
||||
|
||||
The public page runtime lives in `frontend/src/`.
|
||||
|
||||
## `main.js`
|
||||
|
||||
Vue editor app entry, mounts the tabbed `EditorShell`. See `docs/editing.md` for the editor UI.
|
||||
|
||||
## `pagerite.js`
|
||||
|
||||
Public page entry; runs fetch-navigation (backed by an in-memory page cache: every visible internal link is fetched once at load and clicks are then served from JS with no fetch — the current page itself is not refetched, it enters the cache when navigated to — and the editors' `loadPlain` keeps the cache current via a `pagerite:page-fetched` event; articles are `cache-control: no-cache` on the wire). Editors can drop the entire cache with the `pagerite:drop-page-cache` event when site-wide or page changes (theme, headings, structure, banners, etc.) invalidate the cached HTML of other pages; `main.js` triggers a fresh `pagerite:preload-pages` pass when the editor panel closes so navigation is fast again. Navigation that starts while the editor is open bypasses the cache and fetches the target page on demand. Also runs scroll-reveal, a scroll-driven section hash (the location hash tracks the h1/h2 above the viewport middle via replaceState — removed above the first tagged heading and at the very top, never set on unscrollable pages), OverlayScrollbars on `document.body` (floating, auto-hiding scrollbars that never reserve layout space or shift the page when appearing; native scroll APIs like `window.scrollTo` keep working; themed via the `--os-*` variables in pagerite.css), brand shrink-to-fit (the themed size is the maximum; JS reduces the font-size so a long brand or narrow viewport still fits one line), nav condense-to-fit (the top nav stays on one row: link gaps shrink first, then the side padding, then the font size; `flex-wrap: wrap` remains the no-JS fallback), code copy buttons, click-to-enlarge on article figure images (a full-viewport lightbox with the caption, closed by click or Esc), and the auth check.
|
||||
|
||||
It first probes `GET /auth/api/settings` to detect whether Paskia SSO is available, then `GET /_api/settings` to learn the current session's admin status. The same reverse proxy that gates `/_api` returns 401 for anonymous users, 403 for users without the admin permission, and 200 for admins. When Paskia is detected, a login button (anonymous) or profile button (logged in) is shown in the banner corner; clicking it opens the paskia-js `profile()` dialog (an iframe overlay served by Paskia itself, which also runs the login flow), and auth is re-probed when the dialog closes. A `pageshow` handler also re-probes auth when history navigation restores a cached page. Admins also get the page/banner edit pens and a site-settings pen, plus a `modulepreload` warm-up of the editor bundle (the hashed asset is immutable, so it costs nothing). If no Paskia SSO is detected (dev/no proxy), editing is left open. Pages themselves render identically for everyone; the real gate is the auth proxy in front of all of `/_api`.
|
||||
|
||||
The editor/analytics components (everything except pagerite.js and main.js) make their `/_api` calls through paskia-js's `apiFetch`/`apiJson` instead of plain `fetch`: when a call gets a 401/403 carrying an `auth.iframe` hint (expired session), the login dialog opens in place and the request retries transparently after authentication. pagerite.js uses `apiJson` only for the task-checkbox toggle (ticking a box is an explicit edit attempt, so a login dialog is welcome there; any failure — including a cancelled login — reverts the checkbox) and `fetchJson` for its auth probes (plain fetch with JSON handling and errors on non-OK, never a dialog); page-cache and navigation fetches stay on plain `fetch`, so anonymous visitors never get a login popup uninvited.
|
||||
|
||||
Asset wiring differs by mode. In dev the backend links the Vite dev-server URLs (`pagerite:editor-src`/`-css`/`pagerite:analytics-src` meta tags, `<link>` stylesheets) and Vite injects the entry CSS from JS for hot reloads. In production there are no pagerite meta tags: all page assets are inlined into the document — stylesheets as `<style>` elements in `<head>` (fixed order: base, theme, banner design, page transition, entry sheets, custom CSS last), module scripts as inline `<script>`s at the end of the body (relative chunk imports are rewritten to absolute `/_assets/` paths) — and the on-demand bundles' URLs ride in a `<script type="application/json" id="pagerite-assets">` config. The editor bundle always stays external, imported on demand when a pen is opened. Every stylesheet element carries a stable id so fetch-navigation and the site editor can sync `<head>` positionally across swaps (the analytics sheet exists on `/_a` only and is added/removed as you navigate). The analytics entry is inlined into the `/_a` page itself; pagerite.js re-creates that script element after fetch-navigating there (inline scripts don't execute on a DOM swap) and calls the module's exposed unmount before swapping away.
|
||||
|
||||
## `assets/`
|
||||
|
||||
Shared styles and data files built by Vite and served hashed under `/_assets/`: `pagerite.css` (base layout + conservative variables), `pygments.css`, and `fonts/` (self-hosted Source Sans 3/Source Serif 4/Fraunces/Literata/Cormorant/Playfair Display/Inter/Montserrat/Fira Code/Cause/Exo 2/New Rocker variable woff2).
|
||||
|
||||
The `::view-transition*` rules live in the page-transition designs (`pagerite/themes/{cube,crossfade}/transition.css`), not in the base stylesheet. Themes, banner designs and transitions are NOT built — they live in `pagerite/themes/{name}/` and are served by the backend. See `docs/themes-and-assets.md` for details.
|
||||
|
||||
Vite builds ES-module `.js` outputs; in dev the backend links them as `<script type="module">` (module scripts defer by default), in production it inlines them at the end of the body.
|
||||
|
||||
## Data directory
|
||||
|
||||
All site data lives under `<hostname>/` in the cwd — `content.kantadb`,
|
||||
`analytics.json` and `files/` — where `<hostname>` is the CLI's first
|
||||
positional argument (default `localhost`, passed to the app as JSON in
|
||||
`PAGERITE_CONFIG`, see `pagerite/config.py`;
|
||||
`PAGERITE_DB`/`PAGERITE_ANALYTICS`/`PAGERITE_FILES` override individual
|
||||
paths). gitignored. Do not delete it without asking.
|
||||
@@ -0,0 +1,235 @@
|
||||
# Whole-article and scoped LLM translation
|
||||
|
||||
**Status: implemented** (protocol modes and validation in
|
||||
`pagerite/translate.py`, reference client `scripts/llm_translator.py`,
|
||||
human-translation import `scripts/import_translation.py`; wire-level docs
|
||||
in docs/localization.md). One deviation from the text below: ollama's
|
||||
OpenAI-compatible `/v1/chat/completions` silently ignores `think: false`
|
||||
(verified on 0.34.2), so the client's `api` config selects ollama's native
|
||||
`/api/chat` for ollama backends; the OpenAI shape serves llama.cpp and
|
||||
hosted APIs.
|
||||
|
||||
Design for augmenting the fragment-based machine translation
|
||||
(docs/localization.md) with general-purpose instruct LLMs that understand
|
||||
Markdown natively — as opposed to pure text-to-text models like Seed-X.
|
||||
|
||||
## Motivation
|
||||
|
||||
The chunk + segment pipeline (`chunks.py` → `segments.py` → Seed-X) exists
|
||||
because Seed-X mangles Markdown: links, formatting, fences and placeholders
|
||||
must be stripped before dispatch and re-inserted into the result. The
|
||||
re-insertion of link and formatting markup is the imprecise part: when
|
||||
word-alignment by form similarity finds no anchor (always for CJK targets),
|
||||
positions fall back to word-weight ratios, which land a word or so off.
|
||||
All of `segments.py` — segmentation, offset splicing, `_find_mark`,
|
||||
weight-ratio fallback, `_NEUTRAL` punctuation swaps, `<` encoding — is
|
||||
defensive scaffolding around that one limitation.
|
||||
|
||||
An instruct LLM translates Markdown natively: `[text](url)` stays intact
|
||||
and moves as a unit, fences, container markers, attrs and `{...}`
|
||||
placeholders are preserved, and link texts translate in sentence context.
|
||||
For such a translator the entire segments layer is unnecessary.
|
||||
|
||||
## Trial evidence (2026-09, RTX 4090 24 GB + 128 GB RAM, ollama 0.34)
|
||||
|
||||
Whole-article translation of two real articles (5.5 KB marketing, 18.3 KB
|
||||
technical with code fences and `{dates}`) into fi/es/zh:
|
||||
|
||||
- **qwen3.8:27b** (dense, 17 GB Q4 — fits VRAM): structure-perfect on all
|
||||
runs — URLs, placeholders, heading/block counts preserved, fenced code
|
||||
byte-identical. es/zh excellent; fi fluent with occasional lexical slips
|
||||
(covered by the human override layer). ~30 s per short article, ~2.5 min
|
||||
for 18 KB. **The reference model for article and markdown modes.**
|
||||
- **qwen3:30b-instruct**: 3× faster, good prose, but rewrote comments and
|
||||
docstrings inside code fences despite explicit instructions — fails
|
||||
anchor validation (see below).
|
||||
- **qwen3-next:80b** (MoE): best Finnish word choice on short documents,
|
||||
but degenerates on longer input in every configuration tried — runaway
|
||||
thinking loops (293k tokens), empty responses, 3× length output with
|
||||
hallucinated URLs, and ~10× blowup even in 2 KB scoped chunks. Unusable
|
||||
on current ollama builds.
|
||||
- **CPU-only** (i7-14700, 14 threads): MoE 3B-active 10.6 t/s generation
|
||||
(viable for batch), dense 27B 2.5 t/s (not viable). Hybrid GPU+CPU
|
||||
splits bottleneck prompt evaluation (~52 t/s vs 62 t/s pure CPU) —
|
||||
dense GPU-resident or MoE CPU-resident are the sane configurations;
|
||||
mixing hurts.
|
||||
|
||||
Operational requirements established by the trials (all client-side):
|
||||
|
||||
- **Always disable thinking** for hybrid models (`think: false` on
|
||||
ollama): the reasoning phase adds minutes per article and can loop
|
||||
unbounded.
|
||||
- **Always cap generation** (`num_predict` ≈ 2–3× input tokens): a
|
||||
runaway on a whole-article job burns hours, vs. seconds for a
|
||||
Seed-X segment.
|
||||
- temperature 0.2 with the strict structure prompt works well for
|
||||
qwen3.8.
|
||||
|
||||
## What carries over unchanged
|
||||
|
||||
The valuable parts of the current design are the **storage and staleness
|
||||
model**, not the segmentation — and none of them require the machine
|
||||
translation to be produced chunk by chunk. The chunk store is a
|
||||
storage/diffing format; LLM output at any granularity is *projected
|
||||
into* it:
|
||||
|
||||
- Content-addressed source chunks (`Data.chunks`, `chunk_key`) — staleness
|
||||
still falls out of source-hash keys: editing the original invalidates
|
||||
exactly the edited chunks, all other translations keep applying.
|
||||
- Per-chunk machine translations (`Data.trans[hash][lang]`) and the hybrid
|
||||
render with per-chunk fallback to the original.
|
||||
- User overrides (`Data.overrides`) — per-original-chunk edits
|
||||
(search/replace pairs, drops, anchored additions) applied structurally to
|
||||
the assembled hybrid, each independent and best-effort. Overrides are
|
||||
orthogonal to how `Data.trans` entries were produced.
|
||||
- `pending_items`: after a source edit, exactly the changed (lang, hash)
|
||||
pairs are pending — **focused retranslation of edits falls out of the
|
||||
existing bookkeeping**, no whole-article reruns.
|
||||
|
||||
## Protocol: capabilities and job modes
|
||||
|
||||
The `/_translate/{key}` WebSocket stays the single channel; Seed-X
|
||||
clients work unchanged. The client→server `Hello` gains two optional
|
||||
fields:
|
||||
|
||||
```python
|
||||
class Hello(msgspec.Struct, tag="hello"):
|
||||
langs: list[str] # as today: languages the model can produce
|
||||
model: str = "" # free-form model string (logging, debugging)
|
||||
modes: list[str] = ["segments"] # job granularities accepted
|
||||
```
|
||||
|
||||
Four job modes, in increasing granularity:
|
||||
|
||||
- **`segments`** — the current protocol, unchanged: `Job.texts` carries
|
||||
prose segments (markup never crosses the wire), `Result.texts` returns
|
||||
them, the server splices by offset (`segments.py`). For text-to-text
|
||||
models (Seed-X). Default when a client omits `modes`.
|
||||
- **`markdown`** (scoped instruct mode) — one fragment as full Markdown:
|
||||
a body chunk or a title. `Job.texts` carries a single element, the
|
||||
chunk's Markdown; `Job.contexts` carries up to two context strings
|
||||
(previous and next block of the **served hybrid** in the target
|
||||
language — current machine translation with user overrides applied),
|
||||
"" where none. The client is instructed to output ONLY the translation
|
||||
of the target block; the context is terminology/tone reference.
|
||||
Using the *overridden* hybrid as context propagates human corrections
|
||||
into fresh machine translations without the LLM ever touching override
|
||||
storage. `Result.texts` carries one element, the translated block.
|
||||
The server validates: exactly one block after re-chunking, anchor
|
||||
constructs (URLs, image destinations, code fence content, `{...}`
|
||||
placeholders) preserved where the source block has them, then stores
|
||||
to `Data.trans` as usual.
|
||||
- **`article`** — a whole page. `Job.texts` carries one element, the full
|
||||
original Markdown (the chunk sequence is recoverable server-side via
|
||||
`node.chunks`); `Result.texts` carries one element, the full translated
|
||||
Markdown. The server decomposes (below) and stores per chunk.
|
||||
- **`nav`** — the whole navigation hierarchy. `Job.texts` carries one
|
||||
element, a nested Markdown list of every node title still pending for
|
||||
the language (`- Title`, indented by depth, in menu order);
|
||||
`Result.texts` carries one element, the translated list. The server
|
||||
decomposes by list structure (`align_nav`): item count and nesting
|
||||
depth must match the source item for item, then each item is stored as
|
||||
a per-title fragment under its title's chunk hash.
|
||||
|
||||
Titles are jobs like any other in all modes (`kind="title"` keeps its
|
||||
article-opening context rule; in `markdown` mode a title crosses as
|
||||
plain text, since it carries no markup by construction) — but for
|
||||
nav-capable connections a single `nav` job names the entire menu first:
|
||||
one round trip instead of one per page, with siblings, parents and
|
||||
children translating in sight of each other. A structurally mangled list
|
||||
is rejected wholesale and the titles fall back to scoped title jobs.
|
||||
Additionally, an
|
||||
`article` job carries the page title injected as a `# {title}` line at
|
||||
the top when the render would inject it (the body has no h1 of its own):
|
||||
the title translates in document context and the opening paragraphs see
|
||||
the heading. The menu title's and parent node's existing translations
|
||||
ride along as `Job.contexts` ("" where none), so the heading can match
|
||||
the menu while the model may still adapt the in-article title to the
|
||||
content. The heading's pair in the decomposed result becomes the
|
||||
title fragment (heading text only, never stored as a body chunk).
|
||||
|
||||
### Dispatch and validation
|
||||
|
||||
- Routing is per connection as today (wanted ∩ capable, one job in
|
||||
flight, requeue on disconnect), extended by mode: the smallest
|
||||
suitable unit goes to each free connection — `article` jobs only to
|
||||
article-capable connections, and only while a page is *mostly*
|
||||
pending (a whole new article or a full refresh); steady-state edit
|
||||
follow-up is `markdown`/`segments` jobs. Mixed translator fleets (a
|
||||
Seed-X instance, a local qwen, an API-backed client) run concurrently
|
||||
and share the work by capability.
|
||||
- The validation skip-list becomes **mode-scoped** (`(lang, key, mode)`):
|
||||
a fragment a Seed-X client rejects stays offerable to instruct clients
|
||||
(and vice versa) — near-deterministic re-failure applies per model,
|
||||
not across approaches.
|
||||
- `Result` matching is unchanged (lang, key); article results match on
|
||||
the key of the article's first chunk.
|
||||
|
||||
## Article result decomposition
|
||||
|
||||
1. Re-chunk the translated article with the same `chunk_markdown`.
|
||||
2. Align translated blocks to source blocks. A well-behaved model does
|
||||
not reorder paragraphs, so positional / `SequenceMatcher` alignment
|
||||
at block granularity suffices. Blocks that must not change — code
|
||||
fences, container fence lines, `{...}` placeholders, image
|
||||
destinations, raw HTML — are matched verbatim and serve as alignment
|
||||
anchors, like diff context lines.
|
||||
3. Store each translated block in `Data.trans[source_chunk_hash][lang]`.
|
||||
|
||||
Validation happens *before* anything is stored, same spirit as the
|
||||
`pure_prose` segment checks but structural:
|
||||
|
||||
- Anchor blocks must appear verbatim and in order (this is what rejects
|
||||
qwen3:30b-instruct's translated code comments automatically).
|
||||
- Per anchor-bounded region, source and translated block counts must
|
||||
match 1:1; regions that don't align store nothing and their chunks
|
||||
stay pending (they fall back to `markdown`-mode scoped jobs).
|
||||
|
||||
## Reference client
|
||||
|
||||
A second client script next to `scripts/translator.py` speaking the
|
||||
`markdown` and `article` modes. Internally it targets the **OpenAI
|
||||
Chat Completions API shape** (`POST /v1/chat/completions`): ollama
|
||||
serves it at `:11434/v1`, llama.cpp's server likewise, and hosted APIs
|
||||
(OpenAI and compatible providers) natively — `--base-url` + `--model`
|
||||
selects local GPU, local CPU or a remote model, the API key comes from
|
||||
the standard per-provider environment variable (`KIMI_API_KEY`,
|
||||
`MOONSHOT_API_KEY`, `OPENAI_API_KEY`, each sent only to its own
|
||||
provider's host; `LLM_API_KEY` for anything else) — deliberately never
|
||||
a CLI flag or a config file — and backend quirks (ollama's
|
||||
`think: false`, `num_predict` cap, per-model sampling) live in the
|
||||
script's `DEFAULT_CONFIG`.
|
||||
How the client drives its LLM is its internal matter; the wire protocol
|
||||
above is the contract.
|
||||
|
||||
Field-proven backends: the local qwen3.8:27b of the trials above, and
|
||||
the **Kimi Code API** (`--base-url https://api.kimi.com/coding` resp.
|
||||
`api.kimi.ai`, `--model k3-256k`): the `/coding` endpoint fixes sampling
|
||||
internally (the client drops `temperature`/`top_p` for it — they 400)
|
||||
and runs `reasoning_effort: low` from the config, which produces good
|
||||
translations at a fraction of the default (high) effort's latency and
|
||||
quota; thinking output is logged verbatim but stripped from the result.
|
||||
|
||||
The client announces in `Hello`:
|
||||
|
||||
- `model`: the model string it is actually serving (e.g. `qwen3.8:27b`)
|
||||
- `langs`: from its per-model language table — for the shipped qwen3.8
|
||||
configuration the site languages as configured server-side
|
||||
(de, es, fi, pt, zh; Finnish flagged as the weakest, override-covered)
|
||||
- `modes`: `["markdown", "article", "nav"]` for a structure-proven model,
|
||||
`["markdown"]` for one that is only trusted in scoped mode
|
||||
|
||||
The Seed-X client is untouched and announces `["segments"]` (implicitly,
|
||||
by omitting `modes`).
|
||||
|
||||
## Importing human-made full translations
|
||||
|
||||
The decomposition function doubles as an import path for translations
|
||||
produced outside the pipeline — e.g. an article translated with ChatGPT
|
||||
and pasted back. Today such a paste lands in the translation editor and
|
||||
is stored as one giant set of overrides; feeding it through the same
|
||||
decomposition instead writes proper `Data.trans` fragments, so later
|
||||
source edits invalidate and re-translate per chunk rather than letting
|
||||
the monolithic override silently go stale chunk by chunk. This import path is
|
||||
also the natural testbed for the decomposition and validation logic
|
||||
before any live LLM client uses it.
|
||||
@@ -0,0 +1,649 @@
|
||||
# Localization
|
||||
|
||||
Pages are served in the visitor's language based on a `?lang=` query
|
||||
parameter or the `Accept-Language` header.
|
||||
|
||||
- **Phase 1 (implemented):** negotiation, URL scheme, caching, rendering
|
||||
plumbing. Translations are consumed through a stub interface; the database
|
||||
still holds only the original language.
|
||||
- **Phase 2 (implemented):** gettext-style fragment storage in the
|
||||
database — machine-translated chunks plus user overrides, assembled
|
||||
at render time. Storage details in `docs/migrate.md`.
|
||||
|
||||
## Phase 1: negotiation and URLs
|
||||
|
||||
### The primary language
|
||||
|
||||
Each article has a primary (original) language: `Node.language`, inherited
|
||||
down the tree like `banner` — "" = the nearest ancestor's, the front page
|
||||
last (it doubles as the site default), with `en` as the final fallback
|
||||
(`ORIGINAL_LANGUAGE`, `primary_lang()` in `pagerite/i18n.py`). It is
|
||||
configured per row in the structure editor. Everything per-article keys
|
||||
off the resolved value: language selection, `<html lang>`, canonical URLs,
|
||||
what counts as a translation, and the translation targets (a node's own
|
||||
primary is never one — so the target set may include the site default, and
|
||||
a page in another language can be translated into it).
|
||||
|
||||
### Language selection
|
||||
|
||||
Deliberately simple — **q-values are ignored**:
|
||||
|
||||
- All known `Accept-Language` implementations send the header **in order of
|
||||
preference**, so we parse it as an ordered list and never reorder.
|
||||
- Selection rule (`select_language` in `pagerite/i18n.py`):
|
||||
1. If `?lang=<tag>` is present, use it (if a translation exists; otherwise
|
||||
fall through to header logic).
|
||||
2. Otherwise walk the header list in order and use the first language that
|
||||
can be served — the original, or one with an available translation.
|
||||
3. Fall back to the original.
|
||||
|
||||
Region tags normalize to their base subtag (`fi-FI` → `fi`).
|
||||
|
||||
### URLs: pretty for users, indexable for search engines
|
||||
|
||||
- Canonical URLs stay pretty (`/some-page`). Each language version is
|
||||
addressable as `/some-page?lang=fi` so search engines can index them.
|
||||
- `<link rel="canonical">` names the **actually served language**: the plain
|
||||
URL when serving the original (for SEO the non-query URL means the
|
||||
article's own language), `?lang=xx` when serving a translation — however
|
||||
the language was arrived at (query or header).
|
||||
- `<link rel="alternate" hreflang="…">` entries follow the canonical
|
||||
directly (before the social meta tags) and list the languages the page
|
||||
is **actually available in**: `x-default` first, pointing at the plain
|
||||
autodetecting URL, then every available language — the original again by
|
||||
its plain URL, translations by `?lang=`. The public language selector
|
||||
keys off these: pagerite.js mounts the editors' flag dropdown in the
|
||||
top-right corner when the head advertises x-default plus more than one
|
||||
language, loading its bundle (Vue + the flag SVG set) on demand.
|
||||
- The override sticks for the session of clicks: a page requested with
|
||||
`?lang=` replicates the query onto the navigation links it renders (nav,
|
||||
sidebar, cards, brand — in-article links are content and stay as
|
||||
authored), so plain clicks and no-JS navigation keep the language.
|
||||
pagerite.js additionally strips the query from the address bar via
|
||||
`history.replaceState` (pretty, shareable URLs), remembers the language,
|
||||
and adds it to every internal fetch that lacks one (preloads,
|
||||
fetch-navigations, history traversals); history entries stay query-less.
|
||||
- The public selector's pick is the same override, pure JS state
|
||||
(`pagerite:set-session-lang`): the session language changes and the page
|
||||
swaps in place — no `?lang=` in the address bar, no reload. The choice is
|
||||
linked with the editor panel's language dropdown both ways; closing the
|
||||
panel keeps the chosen language instead of reverting.
|
||||
- A full page refresh or a shared link resets to automatic selection (header
|
||||
only). This gives a clean one-time override without cookies.
|
||||
|
||||
### Response correctness
|
||||
|
||||
- Content responses carry `Vary: accept-language` (added to the existing
|
||||
`accept-encoding` vary).
|
||||
- `_cached_body` and the page ETag include the **selected language** (not the
|
||||
raw header, which would blow up the cache key space) and the **replicated
|
||||
link language**: a `?lang=fi` render and a header-selected Finnish render
|
||||
of the same page differ in their navigation links, so they are cached as
|
||||
separate variants.
|
||||
- `<html lang="…">` reflects the served language, and an RTL language
|
||||
(`i18n.RTL_LANGUAGES` — ar, fa, he, ur) also sets `dir="rtl"` on `<html>`
|
||||
(the editor panel carries its own `lang="en" dir="ltr"` so it stays LTR).
|
||||
Client-side page swaps (fetch navigation in pagerite.js, editor re-renders
|
||||
in swapdoc.js) copy both attributes from the fetched document, so a hot
|
||||
switch into or out of an RTL page flips the layout without a reload.
|
||||
|
||||
### Rendering
|
||||
|
||||
- The translated Markdown goes through the same `markdown.render` pipeline.
|
||||
- Section anchors (`#hash` ids on h1/h2 headings) stay in the original
|
||||
language: render(anchors_from=...) pins the translated render's heading
|
||||
ids to the original text's slugs, matched by heading position, so links
|
||||
to sections don't break across languages.
|
||||
- Navigation/sidebar titles come from the translation's title map, with
|
||||
per-node fallback to the original title (a partially translated tree must
|
||||
still render).
|
||||
- Category placeholder pages (the 404s for content-less labels) select a
|
||||
language like content pages, but over the **subtree's** combined
|
||||
availability (`subtree_languages`) — they have no chunks of their own;
|
||||
the heading, navigation and card text localize from the title map and
|
||||
the target articles' translations. Their hreflang alternates are
|
||||
computed exactly like a content page's (a translated title counts as
|
||||
availability, so the language selector is offered there too).
|
||||
- Card descriptions and cover picks run on the target article's hybrid
|
||||
Markdown where that page is available in the served language, with
|
||||
per-card fallback to the original.
|
||||
- Fixed UI strings ("Not Found" etc.) and the editor UI stay English for now.
|
||||
- The markdown typographer (SmartyPants) is English-centric; per-language
|
||||
typographer options are a possible follow-up, not blocking.
|
||||
|
||||
## Phase 2: fragment-based translation storage (implemented)
|
||||
|
||||
Phase 1 assumed whole-page translated Markdown delivered from outside. The
|
||||
refined model is gettext-style: an article has **one primary version** (its
|
||||
`content`, in its own language) plus, per target language, **machine
|
||||
fragments** (translated chunks of Markdown) and **user overrides** (minimal
|
||||
editor edits, keyed per original chunk). Both are stored in the database and
|
||||
assembled into the served Markdown at render time.
|
||||
|
||||
### The scenario this must handle
|
||||
|
||||
1. Article written in English.
|
||||
2. Machine-translated into Spanish → fragments stored.
|
||||
3. Editor fixes one Spanish paragraph and changes a link elsewhere to point
|
||||
at a Spanish resource → user overrides stored.
|
||||
4. English article edited → the edited chunk's key changes; its Spanish
|
||||
fragment no longer matches.
|
||||
5. Page requested before the machine translation refreshes → served as a
|
||||
**hybrid**: old fragments for unchanged chunks, plain English for the
|
||||
edited chunk. User overrides key off chunk hashes, so an override whose
|
||||
chunk was the edited one is orphaned with the old hash and silently
|
||||
stops applying; overrides for untouched chunks apply as before, even
|
||||
over the hybrid.
|
||||
6. Machine translation refreshes → full Spanish again, with the surviving
|
||||
overrides applying. An override whose original paragraph was edited
|
||||
stays orphaned — the edit was about that content — and needs re-doing
|
||||
when still wanted.
|
||||
|
||||
### Chunks
|
||||
|
||||
`chunk_markdown(markdown)` splits the source into block-level chunks —
|
||||
blank-line-separated blocks: headings, paragraphs, code fences (kept whole),
|
||||
list blocks, tables, HTML blocks. Container fence lines (`::: name` openers
|
||||
and `:::` closers) are always their own chunk, blank lines or not — folded
|
||||
into a prose chunk the closer would cross to the translator as part of the
|
||||
text, where the model can drop it (the rest of the page then renders inside
|
||||
the container). A chunk's identity is its **source text**,
|
||||
gettext-msgid style:
|
||||
|
||||
```python
|
||||
chunk_key = blake3(normalize(chunk_text)).digest(9) # bytes; base64 at the JSON level
|
||||
```
|
||||
|
||||
(`normalize`: strip trailing whitespace per line, collapse surrounding blank
|
||||
lines — so whitespace-only source edits don't invalidate translations.)
|
||||
|
||||
Consequences:
|
||||
|
||||
- Editing the English source invalidates exactly the edited chunks; all
|
||||
other fragments keep applying. Stale fragments are simply never referenced
|
||||
again and can be garbage-collected lazily (or left; they are tiny).
|
||||
- No explicit "source version" bookkeeping is needed — staleness falls out
|
||||
of the keys.
|
||||
|
||||
### User overrides
|
||||
|
||||
Editors always edit **full Markdown** in the existing editor UX — never
|
||||
fragments. When editing a translated view (`?lang=es`), the editor is loaded
|
||||
with the *current hybrid Markdown*; on save, the server diffs it against
|
||||
that hybrid and records the changes as **user overrides**. Storage is keyed
|
||||
throughout — no lists, no composite keys, no stored ordering:
|
||||
|
||||
```python
|
||||
class ChunkEdit(msgspec.Struct, omit_defaults=True):
|
||||
"""One original chunk's override in one language."""
|
||||
|
||||
replace: str = "" # the user's full text for the chunk
|
||||
drop: bool = False # the chunk is deleted in this language
|
||||
before: str = "" # addition ids (LangEdits.adds) inserted
|
||||
after: str = "" # before/after this chunk
|
||||
|
||||
|
||||
class LangEdits(msgspec.Struct, omit_defaults=True):
|
||||
"""All overrides of one article in one language."""
|
||||
|
||||
chunks: dict[bytes, ChunkEdit] = {} # ORIGINAL chunk hash -> override
|
||||
adds: dict[str, str] = {} # addition id -> Markdown
|
||||
|
||||
|
||||
Data.overrides: dict[str, dict[str, LangEdits]] # path -> lang -> edits
|
||||
```
|
||||
|
||||
Everything keys off the **original chunk hashes**, which already carry the
|
||||
article's order (`Node.chunks`) — application walks that order, so nothing
|
||||
about sequence is stored. kanta's change diffs register per key, so a save
|
||||
touches only the entries for the chunks actually edited (a list would be
|
||||
rewritten whole every time).
|
||||
|
||||
The diff runs over the `chunk_markdown` block split
|
||||
(`difflib.SequenceMatcher`, autojunk off: deterministic, pages are small)
|
||||
and classifies each opcode per original chunk (`record_override` in
|
||||
`pagerite/i18n.py`):
|
||||
|
||||
- **Within-paragraph edits** — any `replace`, up to a full rewrite of the
|
||||
paragraph's text — become the chunk's **`replace`** patch: the user's
|
||||
text replaces the chunk's served text wholesale, applied by chunk hash
|
||||
alone. A retranslation of the chunk is overridden wholesale too — the
|
||||
user's edit stays in effect across AI re-runs; editing the *original*
|
||||
changes the hash and orphans the patch, so the freshly translated
|
||||
paragraph reappears (the edit was about that content). A re-edit of the
|
||||
same chunk **composes** into the patch — repeat edits never need
|
||||
ordering either. Keyed application also kills the old ambiguity problem:
|
||||
the patch applies to *its* chunk, never to an identical paragraph
|
||||
elsewhere by accident.
|
||||
- **Whole-paragraph deletions** become **`drop`** on the chunk.
|
||||
Hash-anchored, the deletion survives retranslation untouched (a
|
||||
text-anchored delete would stop matching and the paragraph would
|
||||
resurrect); when the *original* paragraph is edited its hash changes and
|
||||
the freshly translated paragraph reappears — the delete was about that
|
||||
content, not that position.
|
||||
- **Whole-paragraph insertions** become **additions** in `adds` under
|
||||
their own ids, referenced from the neighboring chunks' `before`/`after`
|
||||
— both, when both exist, and the first live referrer wins at apply time,
|
||||
so an original edit on one side leaves the other anchor. Since content
|
||||
hashes don't change under retranslation, the inserted paragraph stays in
|
||||
place across a refresh. Inserts next to existing addition text splice
|
||||
into that addition (its text is stable, user-written), as do edits and
|
||||
deletions of added paragraphs — no original hash is ever needed for
|
||||
translation-only content.
|
||||
|
||||
A save often mixes several edits. `SequenceMatcher` lumps adjacent changes
|
||||
into one `replace` opcode, so regions that *removed* blocks are refined
|
||||
(`_refine_replace`): blocks pair greedily by similarity (ratio ≥ 0.5) into
|
||||
text edits, leaving unpaired source blocks as deletions — a sentence fix
|
||||
in the paragraph above a deleted paragraph no longer drags the deletion
|
||||
into the same patch. The split-paragraph grey case (one paragraph
|
||||
becomes two) deliberately stays a single `replace` patch holding both
|
||||
paragraphs: it applies whole across retranslations, rather than
|
||||
half-applying, and telling a split apart from an edit-plus-insert is
|
||||
fuzzy anyway.
|
||||
|
||||
Every classification is best effort: a diff position whose base text no
|
||||
longer matches what the hybrid serves there (the original or the machine
|
||||
translation moved under an open editor) is skipped rather than recorded
|
||||
against the wrong chunk. Overrides for hashes the article no longer
|
||||
contains are harmless orphans (they never apply) and can be
|
||||
garbage-collected lazily, like orphaned chunks.
|
||||
|
||||
### Storage
|
||||
|
||||
Full storage design and the `migrate_v3` restructuring live in
|
||||
`docs/migrate.md`. The short version, as it concerns this document:
|
||||
|
||||
- Originals **and** translations are content-addressed text chunks in flat
|
||||
stores: `Data.chunks: dict[bytes, str]` and
|
||||
`Data.trans: dict[bytes, dict[str, str]]` (chunk hash → lang → text) —
|
||||
path-independent, so repeated paragraphs and menu titles are translated
|
||||
once and article moves touch nothing. `Node.chunks: list[bytes]` gives
|
||||
each article its order.
|
||||
- `Node` gains **`language: str = ""`**, inherited down the tree like
|
||||
`banner` (empty = nearest ancestor, front page last, site default `en`
|
||||
final). `select_language` and `<html lang>` use the resolved value instead
|
||||
of the global `ORIGINAL_LANGUAGE` constant.
|
||||
- **Known weakness:** changing a page's (or subtree's) `language` after
|
||||
translations exist mis-keys everything — translations are keyed by
|
||||
*source* chunks, so old entries silently stop matching and user
|
||||
overrides (anchored to the old chunks' hashes) are orphaned.
|
||||
That is acceptable:
|
||||
the orphaned data is harmless and translations regenerate. We do not
|
||||
migrate translations across a language change.
|
||||
- Article paths are stored and keyed **without leading slashes**
|
||||
(`"docs/setup"`, front page `""`); slashes are added only in hrefs.
|
||||
|
||||
### Render pipeline (the phase-1 `get_translation` stub, now real)
|
||||
|
||||
```python
|
||||
def get_translation(data, path, lang) -> Translation | None:
|
||||
if lang not in node.langs:
|
||||
return None
|
||||
hybrid = hybrid_markdown(data, node, path, lang) # i18n.py: walk
|
||||
# node.chunks; per chunk chunks[h] if h in node.no_trans else
|
||||
# trans.get(h, {}).get(lang, chunks[h]), with the chunk's override
|
||||
# applied structurally: its before-addition, the chunk itself (dropped,
|
||||
# or replaced wholesale by the edit's `replace`), its after-addition.
|
||||
return Translation(markdown=hybrid, titles=title_map(data, lang))
|
||||
```
|
||||
|
||||
- Availability is an article-level index: `node.langs: dict[lang, True]`,
|
||||
maintained by the translation writers (translator job, override saves) in
|
||||
the same transaction as their data writes — rendering and language selection
|
||||
never probe the `trans` store chunk by chunk. A stale key is benign (the
|
||||
"translation" just renders as the original).
|
||||
- `titles` for nav/sidebar/cards: each node's translated title is
|
||||
`trans.get(hash(node.title), {}).get(lang)` with per-node fallback — one
|
||||
dict lookup per nav item at render time.
|
||||
- Cache invalidation: writes to `chunks` / `trans` / `overrides` (translator,
|
||||
editor saves) call `_invalidate_pages()`, same as content writes.
|
||||
|
||||
### Editor flow
|
||||
|
||||
The page and structure editors share one language selector (`LangSelect.vue`:
|
||||
a small flag button opening a dropdown; the same country-flag-icons set as
|
||||
the analytics visitor cells), v-modeled on one shell-wide selection
|
||||
(`editorLang.js`, `''` = the primary language). The page editor lists the
|
||||
page's own primary language (`Node.language`, resolved through the
|
||||
hierarchy and echoed in the WS doc as `primary_lang`) plus the union of
|
||||
the page's translations (`node.langs`) and
|
||||
the site-wide `translate_langs`; it always opens in the primary language,
|
||||
even when the page itself was served in a translation. A note under the
|
||||
toolbar states the blast radius:
|
||||
edits to the primary language re-chunk the original (invalidating the
|
||||
affected translation fragments everywhere); edits to a translation stay
|
||||
local to that language.
|
||||
|
||||
While the editor panel is open, its language selection **overrides the
|
||||
normal language preferences** for the page preview: EditorShell pins every
|
||||
in-place re-render and pagerite.js fetch/prefetch to it (`?lang=` — a
|
||||
primary selection pins by the current page's own resolved primary, which
|
||||
`select_language` honors), and closing the panel restores the normal
|
||||
preferences.
|
||||
|
||||
- WS `open` with a `lang` returns the effective **hybrid** Markdown and
|
||||
title for that language (ungated by `node.langs` — a language without
|
||||
any fragments yet starts from the original text), plus the language
|
||||
metadata (`lang`, `primary_lang`, `langs`, `translate_langs`).
|
||||
- The editor keeps a **shadow copy** of the Markdown it opened. WS `save`
|
||||
with `lang` sends it as `base`; the server diffs `base` → submitted text
|
||||
(`record_override`) and stores per-chunk overrides. Diffing against the
|
||||
shadow (rather than the current hybrid) keeps the diff correct when the
|
||||
original or the machine translation moved under an open editor; positions
|
||||
that no longer match the then-current hybrid are skipped, as designed.
|
||||
- A changed **title** on a translated save becomes a fragment in
|
||||
`Data.trans` keyed by the original title's chunk hash — the same storage
|
||||
as machine title translations. An untouched title field (holding the
|
||||
served translation) is not sent, so saving never freezes a stale machine
|
||||
title into an override.
|
||||
- Saving never deletes; a translation additionally cannot be emptied (that
|
||||
would render as a blank page in that language), and a translated save on
|
||||
a page without original content is rejected outright (there is nothing
|
||||
to anchor a translation to — "the page has no content to translate").
|
||||
The converse is fine: if the original is edited empty after the fact,
|
||||
every override's anchor is gone and the translation simply renders
|
||||
empty, its overrides inert orphans.
|
||||
- The live preview renders the version being edited, whichever language
|
||||
the page itself was loaded in (the render is just the edited Markdown +
|
||||
title). A translated save keeps that preview in place — re-fetching the
|
||||
page would come back in the header-selected language.
|
||||
- Saving the primary-language version re-chunks the submitted Markdown and
|
||||
updates `Data.chunks` / `node.chunks` — only genuinely new text lands in
|
||||
the kanta change diff (see docs/migrate.md).
|
||||
|
||||
The **structure editor** selects from the same languages with the same
|
||||
`LangSelect` (the selection is shared — switching in either tab switches
|
||||
both, and the preview). It is also where a page's **primary language** is
|
||||
configured: each row carries a small flag dropdown (the resolved flag,
|
||||
dimmed while inherited) that sets `Node.language` via a structure op —
|
||||
'' = inherit, so setting it on a section covers the whole subtree. The
|
||||
tree it
|
||||
lists (`GET /_api/pages?lang=`) comes back with per-language titles where a
|
||||
translation exists (`translated` marks those rows; untranslated rows show
|
||||
the original title, dimmed). Retitling in a non-primary language posts the
|
||||
structure op with a `lang` and writes a per-language title fragment in
|
||||
`Data.trans` (keyed by the original title's chunk hash, exactly like a
|
||||
machine title translation — a user edit simply overwrites it); sending the
|
||||
original's text drops the override. The structure itself — slugs,
|
||||
hierarchy, order — is language-independent, so pending rows, slug edits,
|
||||
drag-and-drop and deletes work identically in every language.
|
||||
|
||||
### Translator service API
|
||||
|
||||
An external machine-translation service connects over WebSocket at
|
||||
`/_translate/{key}` — deliberately **not** under `/_api`: the SSO
|
||||
forward-auth does not cover that route, and the key in the path is the
|
||||
access control. Keys live in `Data.translate_keys` (key -> display name) —
|
||||
12 lowercase alphanumeric characters each; the first is generated at
|
||||
database bootstrap, further ones are managed in the editor's lang tab
|
||||
(add/rename/delete ride the `PUT /_api/settings` round-trip; the name is
|
||||
an inline display label only). The full WS URL(s) are printed in the
|
||||
startup log (`ws://localhost:{port}/_translate/{key}` locally,
|
||||
`wss://{hostname}/_translate/{key}` on a public hostname) and shown in the
|
||||
lang tab as click-to-copy links; the keys are also surfaced in
|
||||
`GET /_api/settings` as `translate_keys`. An unknown or empty key rejects
|
||||
the handshake (close-before-accept → HTTP 403). Transactions storing results record the connecting key as the kanta
|
||||
transaction `user`.
|
||||
|
||||
Frames are JSON-encoded tagged msgspec structs (`pagerite/translate.py`;
|
||||
`bytes` fields ride as base64):
|
||||
|
||||
- `{"type": "hello", "langs": [...], "model", "modes"}` — client greeting
|
||||
announcing its **capabilities**: the language codes its model can produce
|
||||
(normalized to base subtags; `en`/empty dropped). `model` is a free-form
|
||||
model string (logging only); `modes` lists the job granularities the
|
||||
client accepts (default `["segments"]`, see Job modes below).
|
||||
- `{"type": "job", "lang", "key", "texts", "path", "kind", "mode",
|
||||
"contexts"}` — server push: ONE fragment to translate (an article title
|
||||
or a chunk; the bulk `article`/`nav` modes carry a whole page resp. the
|
||||
whole navigation tree, see Job modes). In the default `segments` mode
|
||||
`texts` is a list of **prose
|
||||
segments** (see Segmentation below) and `contexts` is parallel to `texts`
|
||||
("" = none): the surround to translate the segment in — for clients that
|
||||
translate better with context (see below). Contexts are not part of the
|
||||
result. See Job modes for the other modes.
|
||||
- `{"type": "result", "lang", "key", "texts"}` — client reply: the
|
||||
segments translated, same order and count, matching its job by (lang, key).
|
||||
|
||||
Which languages get translated is **server-configured**:
|
||||
`Data.translate_langs` (presence-key dict, bootstrapped to Spanish and
|
||||
Chinese — edited in the editor shell's localization tab, whose flag grid
|
||||
lists every language including English, or set via `/_api/settings` as
|
||||
`translate_langs`). A target equal to an article's own primary language is
|
||||
skipped per article (its original already is that language), so the set
|
||||
may freely contain the site default. The dispatcher offers a
|
||||
connection jobs only in `wanted ∩ capable`; a connection without overlap
|
||||
simply stays idle.
|
||||
|
||||
`DELETE /_api/translations` (the localization tab's "refresh all
|
||||
translations" button) drops every machine translation (`Data.trans`) and
|
||||
rebuilds the availability index (`node.langs`) from the surviving user
|
||||
overrides, so the dispatcher re-translates everything from scratch; the
|
||||
run's validation skip-list is cleared with it, giving rejected fragments
|
||||
another chance.
|
||||
|
||||
Dispatch semantics (the `Dispatcher` in `pagerite/translate.py`; api.py only
|
||||
registers the route):
|
||||
|
||||
- **One job at a time per connection** — the next job is sent only after
|
||||
the current one's result. Clients wanting parallelism open multiple
|
||||
connections (e.g. several `scripts/translator.py` instances).
|
||||
- Pending work is derived from the `trans` store
|
||||
(`translate.pending_items`) minus the items in flight on any connection,
|
||||
so a **disconnect requeues** that connection's in-flight item and it is
|
||||
offered to any free capable connection.
|
||||
- Dispatch re-runs on every relevant event: Hello, result, disconnect and
|
||||
content change (`_invalidate_pages()` schedules it, so the pass runs
|
||||
after the writing transaction commits).
|
||||
- A result with no job in flight, a mismatched (lang, key), a duplicate
|
||||
hello, or any malformed frame closes the socket with a protocol error.
|
||||
|
||||
Results are stored into `trans` in one transaction and set
|
||||
`node.langs[lang]` on every article they touch (shared chunks make several
|
||||
pages gain a language from one fragment). Unknown keys are stored anyway
|
||||
and re-storing overwrites — results are idempotent.
|
||||
|
||||
#### Job modes: segments, markdown, article, nav
|
||||
|
||||
Instruct LLMs understand Markdown natively, so for them the segmentation
|
||||
round trip below is unnecessary scaffolding (docs/llm-translation.md for
|
||||
the design and the model trial evidence). `Hello.modes` announces which
|
||||
job granularities a connection accepts; routing is per connection and per
|
||||
mode, so a mixed fleet (a Seed-X instance, a local qwen, an API-backed
|
||||
client) shares the work by capability. The validation skip-list is
|
||||
mode-scoped — `(lang, key, mode)` — so a fragment one model rejects stays
|
||||
offerable to clients of another approach.
|
||||
|
||||
- **`segments`** (default when a client omits `modes`) — the protocol as
|
||||
described so far: `Job.texts` carries prose segments, `Result.texts`
|
||||
returns them, the server splices by offset.
|
||||
- **`markdown`** — one fragment as full Markdown: `Job.texts` carries a
|
||||
single element, the chunk (a title crosses as plain text, with the
|
||||
article's opening as its context as today). `Job.contexts` carries the
|
||||
previous and next block of the **served hybrid** in the target language
|
||||
(machine translation with user overrides applied, "" where none), so human
|
||||
corrections propagate into fresh translations as terminology/tone
|
||||
reference; contexts are never part of the result. The result must
|
||||
re-chunk to exactly one block with the source's anchor constructs (link
|
||||
and image destinations, `{...}` placeholders) intact (`clean_block`),
|
||||
then stores to `Data.trans` as usual.
|
||||
- **`article`** — a whole page at once, offered only to article-capable
|
||||
connections and only while a page is *mostly* pending (a new article or
|
||||
a full refresh; steady-state edit follow-up stays scoped jobs). The
|
||||
job's key is the page's first chunk; `Job.texts` carries the full
|
||||
original Markdown — with the page title injected as a `# {title}` line
|
||||
at the top when the render would inject it (the body has no h1 of its
|
||||
own), so the title translates in document context and the opening
|
||||
paragraphs see the heading. The menu title's and parent node's existing
|
||||
translations (from a nav job or earlier work) ride along as
|
||||
`Job.contexts`, so the heading can match the menu while the model may
|
||||
still adapt the in-article title to the content. The result is
|
||||
decomposed per chunk
|
||||
(`align_article`): non-translatable blocks (code fences, container
|
||||
fences, raw HTML — everything `needs_translation` rejects) must appear
|
||||
verbatim and in order and anchor the alignment; regions between anchors
|
||||
pair positionally, a region whose block count changed stores nothing
|
||||
(its chunks stay pending and fall back to scoped jobs), and a paired
|
||||
block whose destinations/placeholders did not survive likewise. An
|
||||
injected title heading's pair becomes the title fragment (heading text
|
||||
only — never a body chunk; a demoted or merged heading simply skips it
|
||||
and the title stays pending for a scoped title job).
|
||||
- **`nav`** — the whole navigation hierarchy at once, offered only to
|
||||
nav-capable connections and ahead of any per-title jobs: `Job.texts`
|
||||
carries one element, a nested Markdown list of every node title still
|
||||
pending for the language (`- Title`, indented by depth, in menu order —
|
||||
pages and category labels alike); the job's key is the hash of that
|
||||
list. One round trip names the entire menu, and sibling titles
|
||||
translate in sight of each other. The result is decomposed back into
|
||||
per-title fragments (`align_nav`): it must be the same list item for
|
||||
item — same count, same nesting depth at every position — or it is
|
||||
rejected wholesale and the titles fall back to scoped title jobs; an
|
||||
item that comes back empty, marked-up or with its destinations/
|
||||
placeholders lost is skipped individually and likewise stays pending
|
||||
for a scoped title job.
|
||||
|
||||
`scripts/llm_translator.py` is the reference markdown+article+nav client
|
||||
(instruct LLMs via an OpenAI Chat Completions endpoint or ollama's native
|
||||
API); `scripts/translator.py` (Seed-X) is untouched and announces
|
||||
`["segments"]` implicitly.
|
||||
|
||||
**Importing human-made full translations:** `align_article` doubles as an
|
||||
import path — `scripts/import_translation.py PATH LANG FILE.md` (run with
|
||||
the server stopped) decomposes a pasted whole-article translation (e.g.
|
||||
from ChatGPT) into proper `Data.trans` fragments with the same validation,
|
||||
so later source edits invalidate and re-translate per chunk rather than
|
||||
letting the translation editor's one monolithic override go stale chunk by
|
||||
chunk.
|
||||
|
||||
#### Segmentation
|
||||
|
||||
Fragments cross the wire as **prose segments** (`pagerite/segments.py`): the
|
||||
fragment is parsed with the project's own markdown-it setup
|
||||
(`markdown.make_md(verbatim=True)` — all extensions, but no typographer or
|
||||
tasklist label wrapping, so token text stays byte-identical to the source)
|
||||
and split into the runs a model may touch: paragraph/heading/table-cell text
|
||||
(merged across soft line breaks), image alt texts and captions, footnote
|
||||
bodies. A block of plain text, inline **links and paired text formatting**
|
||||
(strong/em/s) **stays whole** — link and formatted texts cross inline, in
|
||||
sentence context, with the Markdown stripped (see below). Everything else
|
||||
never leaves the server: code spans and
|
||||
fences, URLs and autolinks, link/image *destinations*, `{...}` spans
|
||||
(placeholders like `{dates}` as well as attrs), reference and footnote
|
||||
labels, container fences, GFM alert markers (`[!NOTE]`), raw HTML — and the
|
||||
remaining markup punctuation (`|`, `:::`), which is a run boundary.
|
||||
Chunks with no segments (a lone `{dates}`, container fences, pure
|
||||
code/HTML) are never dispatched at all (`needs_translation`); every
|
||||
language renders them from the original chunk. Each segment is accompanied
|
||||
by a context string (a segment carved out of a larger block carries the
|
||||
block's plain text; a whole-block segment carries "") — context is a
|
||||
prompt aid only, never spliced into the result.
|
||||
|
||||
Reassembly is offset splicing, not text the model produced: each segment's
|
||||
source span was located at dispatch (sequential search; a run that is not a
|
||||
verbatim source substring — entity-decoded text, backslash escapes — is
|
||||
skipped and stays in the original language), and the returned translations
|
||||
are swapped in by offset. Markup corruption is therefore impossible by
|
||||
construction; the failure modes that remain are a wrong segment count, an
|
||||
empty segment, markup injected INTO a segment (a `<br>` in a title
|
||||
translation would splice live HTML), or a line that would start a new
|
||||
block where the segment lands (a ``` or ::: fence line would eat the rest
|
||||
of the block it splices into, closing fence included — segments are
|
||||
inline prose, so `pure_prose` alone cannot see this) — each returned
|
||||
segment must parse as
|
||||
pure prose with no block-starting line or blank line, or the whole result
|
||||
is dropped and logged, and the (lang, key, mode)
|
||||
combination is skipped for the rest of the server run (generation is
|
||||
near-deterministic per model, so an immediate retry in the same mode would
|
||||
re-fail; the fragment stays
|
||||
pending and gets another chance on restart, in another mode, or on
|
||||
`DELETE /_api/translations`).
|
||||
`Data.trans` therefore only ever holds clean translated Markdown.
|
||||
|
||||
Link- and formatting-carrying blocks are the one place a segment is not
|
||||
spliced verbatim: a label translated apart from its sentence comes back
|
||||
grammatically incompatible with it (case government, particles, word
|
||||
order), and shown the Markdown the model mangles it (Seed-X dropped the
|
||||
`**` and the glued-on colon in `**Pagerite**: …`), so the block crosses
|
||||
whole — all Markdown stripped — and the server re-inserts the link and
|
||||
formatting syntax into the translated block. The boundaries are found by
|
||||
**text processing alone** —
|
||||
markers on the wire are hopeless (an earlier sentinel-masking design let
|
||||
the model see and mangle exactly that punctuation: Seed-X renumbered the
|
||||
tokens and turned `` or `**`. Blocks mixing in any other inline
|
||||
markup (code spans, images, raw HTML) don't qualify and still split into
|
||||
runs at those boundaries.
|
||||
|
||||
Punctuation is the translator's own job: Seed-X tends to "finish" short
|
||||
labels (titles, nav items) with a comma or period the source never had.
|
||||
Prompt wording is NOT the fix — a punctuation-instruction clause made
|
||||
Seed-X slip into its `[COT]` reasoning mode (minutes-long generations with
|
||||
reasoning text in the output, observed for Chinese). The reference client
|
||||
enforces punctuation deterministically instead (`match_punctuation` in
|
||||
scripts/translator.py): a translation of a segment without terminal
|
||||
punctuation gets any added trailing marks (and a newly opened Spanish ¡/¿)
|
||||
stripped before the result goes back.
|
||||
|
||||
The same client-side enforcement covers markup bleed as a CLASS, not per
|
||||
artifact: `<` is the prose/markup boundary on the wire and never appears in
|
||||
a segment in either direction. A literal `<` in the source text (`<1MB` is
|
||||
text, not markup — a tag needs a letter or `/!?`) crosses encoded as the
|
||||
fullwidth `<` and is decoded on return, before the result is validated and
|
||||
spliced (segments.py) — the wire itself still never carries `<`, and the
|
||||
reference client cuts the model's output at the first `<`
|
||||
(scripts/translator.py) — echoed language tags, stray `<br>`s and any
|
||||
future variant are one handled case. (The cut is post-decode, not a
|
||||
generation stop string: Seed-X opens every generation with its `<s>`
|
||||
framing token, which would trip a `<` stop immediately.)
|
||||
|
||||
Server-side, a second layer covers what the inline parser cannot: ASCII
|
||||
punctuation that is plain prose on the wire but Markdown syntax in the
|
||||
splice context — quotes (a translated `"` would close the quoted image
|
||||
title it lands in), brackets (alt texts, re-inserted link texts), `|` in
|
||||
table rows, `\` escapes. Rather than rejecting such results, `join` swaps
|
||||
them for Unicode look-alikes before splicing (`_NEUTRAL` in
|
||||
segments.py — curly quotes, fullwidth brackets; the renderer's
|
||||
typographer curls straight quotes anyway).
|
||||
|
||||
Short fragments get more than a bare prompt: each segment may carry its
|
||||
surround in `Job.contexts` — a title carries the article's opening prose
|
||||
(its own block is just the title word), a segment carved out of a larger
|
||||
block (a partial run; a link text whose block didn't qualify for the
|
||||
whole-block treatment) carries the block's plain text, and a
|
||||
whole-block segment (a plain paragraph) is self-contextualizing and carries
|
||||
"". The reference client translates segment and surround together, stops
|
||||
generation at the blank line separating them, and keeps the segment's own
|
||||
part of the output (its line resp. paragraph; a hard-break `␣␣\n` separator
|
||||
works too). If the model merged them (no separator, or an empty first
|
||||
part), it falls back to translating the segment alone. The surround fixes
|
||||
context-free readings ("About" as "approximately" — with the opening it
|
||||
becomes "Tietoa"/"Acerca de"; "here" as "就在这里" → the idiomatic
|
||||
"点击这里") and, as a side effect, most stray trailing punctuation.
|
||||
|
||||
### Explicitly out of scope for phase 2
|
||||
|
||||
- The machine translation itself: the API above moves fragments in and out;
|
||||
the translating is external. `scripts/translator.py` is the reference
|
||||
client (Seed-X-PPO-7B only — its 28 languages are the ceiling).
|
||||
- Garbage collection of orphaned chunks/translations (see docs/migrate.md).
|
||||
- sitemap.xml per-language entries; translated UI chrome; per-language
|
||||
typographer options; multi-locale date/number formatting.
|
||||
@@ -0,0 +1,183 @@
|
||||
# migrate_v3: content-addressed chunk storage
|
||||
|
||||
Status: **implemented**. `migrate_v3` restructures how article text and
|
||||
translations are stored, motivated by the localization model in
|
||||
`docs/localization.md` (phase 2). Since it is a full migration, it is free to
|
||||
break the current `Node.content: str | None` layout.
|
||||
|
||||
## Goals
|
||||
|
||||
- **Minimal change diffs.** kanta persists change diffs; editing one
|
||||
paragraph of a long article must not rewrite the whole article string, and
|
||||
a translation refresh must touch only the re-translated chunks.
|
||||
- **Fast, simple lookup.** Everything heavy lives in flat
|
||||
`dict[hash, content]` stores; ordering lives in `list[hash]`. No large
|
||||
nested structures, no deep paths.
|
||||
- **Path-independent text.** Chunks and their translations are keyed by
|
||||
content hash, not by article path — the same paragraph (or menu title)
|
||||
appearing in several articles is stored and translated once. Moving or
|
||||
renaming an article touches nothing.
|
||||
|
||||
## Design (chosen: global content-addressed stores)
|
||||
|
||||
Original articles are *also* stored as chunks; everything — originals and
|
||||
translations — lives in flat hash-keyed dicts. Costs accepted: rendering does
|
||||
one dict lookup per chunk (trivial), orphaned hashes need occasional garbage
|
||||
collection, and the editor save path re-chunks server-side (it already
|
||||
diffs). The rejected alternatives: per-article nested `LangVersion`
|
||||
structures (churn, duplication, whole-string originals) and a hybrid with
|
||||
whole originals plus global translations (keeps the worst change-diff
|
||||
property).
|
||||
|
||||
## Target layout
|
||||
|
||||
```python
|
||||
class Node(msgspec.Struct, omit_defaults=True):
|
||||
...
|
||||
#: Replaces `content: str | None`. None = pure category label;
|
||||
#: a list (possibly empty) = a page, as ordered chunk hashes.
|
||||
chunks: list[bytes] | None = None
|
||||
#: Primary language of the article (BCP-47 base tag). "" = inherit
|
||||
#: (nearest ancestor, front page last, site default "en" final).
|
||||
language: str = ""
|
||||
#: Chunk hashes the editor marked "do not translate" (always served
|
||||
#: from the original). Presence-keys, value always True.
|
||||
no_trans: dict[bytes, True] = {}
|
||||
#: Languages this article is available in (besides its primary
|
||||
#: language). Presence-keys, value always True — rendering, language
|
||||
#: selection and hreflang alternates read this set instead of probing
|
||||
#: the trans store chunk by chunk. Maintained by the writers (see
|
||||
#: "Language index maintenance" below).
|
||||
langs: dict[str, True] = {}
|
||||
|
||||
|
||||
class Data(msgspec.Struct):
|
||||
...
|
||||
#: API keys gating the translator service WebSocket (/_translate/{key}):
|
||||
#: key -> display name; the first is generated at bootstrap (state.py).
|
||||
translate_keys: dict[str, str] = {}
|
||||
#: Wanted target languages for the translator service (presence-keys);
|
||||
#: jobs are offered only in these ∩ a connection's capabilities.
|
||||
translate_langs: dict[str, True] = {}
|
||||
#: All original-language text, content-addressed: blake3(normalized)
|
||||
#: digest[:9] -> Markdown chunk. Shared by every article. Keys are
|
||||
#: bytes; kanta/msgspec base64-encode them at the JSON level.
|
||||
chunks: dict[bytes, str] = {}
|
||||
#: Machine translations: chunk hash -> lang -> translated Markdown
|
||||
#: (nested, not tuple keys: msgspec's JSON serializer rejects them).
|
||||
#: Also used for node titles (hash of the title text).
|
||||
trans: dict[bytes, dict[str, str]] = {}
|
||||
#: User override edits per article and language:
|
||||
#: path -> lang -> LangEdits (see localization.md) — keyed per original
|
||||
#: chunk hash throughout, so a save's change diff touches only the
|
||||
#: edited chunks. Replaced the old list-valued "patches" key (ignored
|
||||
#: on decode, discarding that data — no migration).
|
||||
overrides: dict[str, dict[str, LangEdits]] = {}
|
||||
```
|
||||
|
||||
Notes:
|
||||
|
||||
- **Article paths never carry a leading slash** in the DB or in lookup keys
|
||||
(`"docs/setup"`, front page `""`); the leading slash is added only when
|
||||
building hrefs. `migrate_v3` audits existing stored paths (translation
|
||||
keys, analytics references, any path-valued fields) and normalizes them.
|
||||
- **Titles are chunks too**, by hash only: the nav renderer looks up
|
||||
`trans.get(hash(node.title), {}).get(lang)`. No separate title storage;
|
||||
editing a title invalidates its translations automatically.
|
||||
- **Per-hunk options** live in two places: *inherent* options are derived at
|
||||
chunking time (code fences, HTML blocks and prose-free chunks are
|
||||
no-translate without storing anything — `needs_translation`, see
|
||||
docs/localization.md "Masking"); *editor-set* flags are `node.no_trans`
|
||||
(keyed by chunk
|
||||
hash, so a heavy edit silently drops the flag — acceptable and
|
||||
self-healing).
|
||||
- **Override payloads stay inline** in the `LangEdits` struct — overrides
|
||||
are small by construction (minimal server-computed diffs). If a
|
||||
pathological case shows up, they can be hash-stored later without schema
|
||||
pain.
|
||||
|
||||
## Language index maintenance (`node.langs`)
|
||||
|
||||
`node.langs` is a denormalized index over the `trans`/`overrides` stores so
|
||||
that article rendering, `select_language`'s availability check, and hreflang
|
||||
alternate links never enumerate chunks. It is written by whoever writes
|
||||
translation data, in the same transaction:
|
||||
|
||||
- **Translator service:** the WebSocket API at `/_translate/{key}` (see
|
||||
docs/localization.md) offers pending fragments (titles + translatable
|
||||
chunks lacking an entry for the language) as single-item jobs — one at
|
||||
a time per connection, in `Data.translate_langs` ∩ the connection's
|
||||
announced capabilities — and receives the matching result; storing it
|
||||
writes the `trans[h][lang]` entry, sets `node.langs[lang] = True` on
|
||||
every article that gained one and invalidates the page cache — all in
|
||||
one transaction.
|
||||
- **Translated-view save:** recording the first override for a `(path, lang)`
|
||||
sets `node.langs[lang] = True` (overrides alone make the version exist).
|
||||
- **Removals:** deleting overrides or GC'ing translations re-derives the key:
|
||||
keep `lang` if any `trans` entry for the article's current chunks/title or
|
||||
any override remains, otherwise drop it. Stale `langs` keys are benign (an
|
||||
advertised language that renders as the original), so removal can lag.
|
||||
|
||||
## Render / save pipeline (summary)
|
||||
|
||||
- **Render:** `text = "\n\n".join(chunks[h] for h in node.chunks)` for the
|
||||
original; for language `L` (only ever attempted when `L in node.langs`),
|
||||
per chunk `trans.get(h, {}).get(L)` unless missing or `h in node.no_trans`,
|
||||
falling back to `chunks[h]`; then apply `overrides[path][L]` structurally
|
||||
in the article's own chunk order (drops, search/replace pairs, anchored
|
||||
additions — see docs/localization.md); then
|
||||
`markdown.render` as today. All of
|
||||
this assembles the `Translation` the phase-1 plumbing already consumes.
|
||||
- **Availability:** `node.langs` is the availability index; `?lang=`
|
||||
handling uses exactly this set. (hreflang alternates are site-wide from
|
||||
`translate_langs` instead — see docs/localization.md.)
|
||||
- **Save (primary language):** server re-chunks the submitted Markdown,
|
||||
inserts new hashes into `Data.chunks`, replaces `node.chunks`. Unchanged
|
||||
chunks keep their hashes — only genuinely new text lands in the diff.
|
||||
- **Save (translated view):** diff against the served hybrid, record
|
||||
per-chunk overrides under `overrides[path][lang]`; `node.chunks` untouched.
|
||||
- **Invalidate:** any write to `chunks` / `trans` / `overrides` calls
|
||||
`_invalidate_pages()`.
|
||||
|
||||
## migrate_v3 steps
|
||||
|
||||
1. Walk `menu`; for every node with a string `content`:
|
||||
`chunks = chunk_markdown(content)`; write each into the new `chunks`
|
||||
store; replace the field with the hash list (`None` stays `None`).
|
||||
2. Initialize empty `chunks` / `trans` stores.
|
||||
3. `language`, `no_trans` and `langs` need nothing — struct defaults cover
|
||||
them (`langs` starts empty; the translator job fills it as translations
|
||||
land).
|
||||
|
||||
Chunking must be deterministic and shared with render/save, so
|
||||
`chunk_markdown` + `chunk_key` live in `pagerite/i18n.py` (or a small
|
||||
`pagerite/chunks.py`) and are imported by both `migrations.py` and
|
||||
`views.py`/`state.py`.
|
||||
|
||||
## Implementation notes (deviations from the plan above)
|
||||
|
||||
- Chunking lives in `pagerite/chunks.py`; hashing uses the `blake3` package
|
||||
(already a dependency), truncated to a 9-byte `bytes` digest (kanta's
|
||||
JSON persistence base64-encodes bytes keys to 12-char strings).
|
||||
- `trans` is keyed `hash -> lang -> text` (nested dict), not by
|
||||
`f"{hash}:{lang}"` tuples: msgspec's JSON serializer only supports
|
||||
str-like/number-like dict keys, and kanta persists as JSON lines.
|
||||
- `Translation.titles` stayed keyed by node path (phase-1 shape, views
|
||||
untouched): `get_translation` builds it by walking the menu with the same
|
||||
per-title `trans.get(chunk_key(node.title), {}).get(lang)` lookups.
|
||||
- User overrides (`record_override`) diff with `SequenceMatcher(autojunk=False)`
|
||||
so overrides are deterministic (popular lines like blank separators never
|
||||
become junk).
|
||||
- The old list-valued `patches` store was later replaced by the keyed
|
||||
`overrides` store above; the rename itself discarded the old data (msgspec
|
||||
ignores the unknown key on decode), no migration.
|
||||
|
||||
## Garbage collection (later, manual or idle-time)
|
||||
|
||||
Orphaned entries accumulate: chunks no longer referenced by any
|
||||
`node.chunks`/`node.title`, translations whose chunk hash is orphaned,
|
||||
overrides whose chunk hash is gone from the article (or whose `search`
|
||||
never matches). All are harmless (never read). A GC pass is a single
|
||||
tree walk collecting live hashes, then deleting the rest from `chunks` and
|
||||
`trans`; override entries for dead hashes get pruned. Not part of
|
||||
migrate_v3.
|
||||
@@ -0,0 +1,5 @@
|
||||
# Pagerite overview
|
||||
|
||||
Pagerite is a single-user CMS/blog. FastAPI serves HTML rendered in Python with html5tagger; content is persisted in a kanta database and rendered on the fly per request. Vue is used only for interactive bits (editing tools), not for the public pages.
|
||||
|
||||
See `docs/design-principles.md` for the high-level design and the other `docs/*.md` files for implementation details.
|
||||

|
After Width: | Height: | Size: 56 KiB |

|
After Width: | Height: | Size: 104 KiB |

|
After Width: | Height: | Size: 74 KiB |
@@ -0,0 +1,91 @@
|
||||
# Production setup
|
||||
|
||||
From a local demo to a real site: run Pagerite as a systemd service behind
|
||||
a reverse proxy that terminates HTTPS, with Paskia guarding the editing API.
|
||||
|
||||
The moving parts:
|
||||
|
||||
- **Pagerite** — serves the public site on `localhost:8100` and the editing
|
||||
API under `/_api`.
|
||||
- **Paskia** — the SSO server; owns `/auth/` and answers forward-auth
|
||||
subrequests.
|
||||
- **A reverse proxy** — Caddy below, but nginx or anything with
|
||||
forward-auth support works the same way.
|
||||
|
||||
## Pagerite as a systemd service
|
||||
|
||||
Install [uv](https://docs.astral.sh/uv/getting-started/installation/) on the
|
||||
system, create a user, and add a template unit:
|
||||
|
||||
```sh
|
||||
sudo useradd --system --home-dir /srv/pagerite --create-home pagerite
|
||||
curl -LsSf https://astral.sh/uv/install.sh | sudo env UV_INSTALL_DIR=/usr/local/bin sh
|
||||
sudo systemctl edit --force --full pagerite.service
|
||||
```
|
||||
|
||||
```ini
|
||||
[Unit]
|
||||
Description=Pagerite CMS
|
||||
|
||||
[Service]
|
||||
Type=simple
|
||||
User=pagerite
|
||||
SyslogIdentifier=pagerite
|
||||
WorkingDirectory=/srv/pagerite
|
||||
ExecStart=uvx pagerite example.com --dbip
|
||||
|
||||
[Install]
|
||||
WantedBy=multi-user.target
|
||||
```
|
||||
|
||||
Replace `example.com` with your actual domain name. `--dbip` keeps the local GeoIP database up to date: leave out if you don't want DBIP data for analytics.
|
||||
|
||||
```sh
|
||||
sudo systemctl enable --now pagerite
|
||||
sudo journalctl -ocat -fu pagerite
|
||||
```
|
||||
|
||||
## Running it on internet
|
||||
|
||||
We recommend Caddy for making your site publicly visible on the Internet. Presumably you already have some proxy, perhaps Nginx, but our setup is not much different of any other service you might already be running. ChatGPT and the likes can also help with the configuration because online documentation is limited. Note that Paskia also has extensive documentation on [running on various proxy servers](https://git.zi.fi/LeoVasanko/paskia/src/branch/main/docs/proxy/index.md)
|
||||
|
||||
Install [Caddy](https://caddyserver.com/) and follow the [Paskia setup guide](https://git.zi.fi/LeoVasanko/paskia) to get the SSO server running and its `auth` snippets copied to `/etc/caddy/auth` — that guide covers Paskia's own configuration and admin registration in detail.
|
||||
|
||||
Then the site config. Only the editing API needs gating; the site itself is public:
|
||||
|
||||
```caddyfile
|
||||
example.com {
|
||||
import auth/setup
|
||||
|
||||
reverse_proxy /auth/* localhost:4401
|
||||
|
||||
@api path /_api/*
|
||||
handle @api {
|
||||
import auth/require perm=pagerite:admin
|
||||
reverse_proxy localhost:8100
|
||||
}
|
||||
|
||||
handle {
|
||||
reverse_proxy localhost:8100
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Reload Caddy, then create a permission with scope `pagerite:admin` in the
|
||||
Paskia admin panel (`/auth/admin/`) and assign it to yourself, as the Paskia
|
||||
guide describes. Anonymous visitors now get 401 from `/_api`, logged-in
|
||||
users without the permission get 403, and admins get the editing pens.
|
||||
|
||||
## nginx or another proxy
|
||||
|
||||
The shape is identical everywhere:
|
||||
|
||||
- `/auth/` proxies to Paskia (`localhost:4401`).
|
||||
- `/_api` requires a forward-auth subrequest against Paskia — on nginx that
|
||||
is `auth_request` against Paskia's verify endpoint — before proxying to
|
||||
Pagerite (`localhost:8100`).
|
||||
- Everything else proxies straight to Pagerite.
|
||||
|
||||
Paskia ships per-proxy forward-auth guides covering
|
||||
[Caddy, nginx and others](https://git.zi.fi/LeoVasanko/paskia/src/branch/main/docs/proxy/index.md);
|
||||
adapt the matcher to `/auth/` and `/_api` as above and leave the rest public.
|
||||
@@ -0,0 +1,71 @@
|
||||
# Themes and assets
|
||||
|
||||
## Built assets
|
||||
|
||||
Files under `frontend/src/assets/` are built by Vite and served hashed under `/_assets/`:
|
||||
|
||||
- `pagerite.css` — base layout + conservative variables.
|
||||
- `pygments.css` — Pygments token styles mapped onto the `--code-*` variables.
|
||||
- `fonts/` — self-hosted variable woff2 files for Source Sans 3, Source Serif 4, Fraunces, Literata, Cormorant, Playfair Display, Inter, Montserrat, Fira Code, Cause, Exo 2 and New Rocker.
|
||||
|
||||
The `::view-transition*` rules are not in the base stylesheet: they live in the page-transition designs (`pagerite/themes/{name}/transition.css`, see below).
|
||||
|
||||
## Themes
|
||||
|
||||
Themes are folders in `pagerite/themes/{name}/` containing `theme.css` and/or `banner.css` (+ `banner.svg` artwork and any extra assets the CSS references, like summer's `grass.svg`). They are served by the backend at `/_themes/{name}/...` — read from disk per request (etag by mtime), never built, so on-disk edits show on the next page load even in prod.
|
||||
|
||||
Themes are searched across several roots, most specific first (see `views.THEME_DIRS`):
|
||||
|
||||
1. `themes/` under the current working directory
|
||||
2. `<site-dir>/themes/` (the site's own folder, e.g. `localhost/themes/`)
|
||||
3. The platform user data dir's `pagerite/themes/` (Linux: `~/.local/share/pagerite/themes/`, Windows: `%LOCALAPPDATA%\pagerite\themes\`)
|
||||
4. The platform system data dirs' `pagerite/themes/` (Linux: `/usr/local/share/pagerite/themes/`, `/usr/share/pagerite/themes/`, ...; Windows: `%PROGRAMDATA%\pagerite\themes\`) — several combine
|
||||
5. `pagerite/themes/` (built-in package dir, fallback)
|
||||
|
||||
The data dirs come from `platformdirs` (`views._data_roots`).
|
||||
|
||||
All roots combine: listings are the union of folder names, and each file resolves from the first root that has it. So users can add completely new themes in any root, shadow a built-in file with their own (`<site>/themes/corporate/theme.css`), or extend a built-in theme with extra files (any files the user folder doesn't provide still come from the built-in). Since everything is read per request, new or changed folders take effect without a server restart.
|
||||
|
||||
`Data.theme` selects the active theme (empty = none/base only) and the site editor can switch it, choosing from the theme folders found on disk. Vue may add per-component styles on top where needed.
|
||||
|
||||
The site editor shows a light/dark-mode indicator in front of each theme name, read from the theme's `color-scheme` declaration in `theme.css`: ☀️ for light-only, 🌙 for dark-only, and 🌓 for themes that support both. The base theme (`none`) is light-only.
|
||||
|
||||
Current themes:
|
||||
|
||||
- `purple` — dark dusk palette with Fraunces/Literata and a tilted oversized gradient brand.
|
||||
- `corporate` — light-first with automatic `prefers-color-scheme` dark mode, Montserrat/Inter and a huge solid brand.
|
||||
- `nitro` — racing/HUD style following `prefers-color-scheme` (warm light-grey page, deep violet in dark), Montserrat/Literata, black as an accent only, a straight orange blade under the banner, and an orange racing-tab nav clipped with a bezier `shape()`.
|
||||
- `summer` — light playful meadow, one palette sampled from its illustrated `banner.svg` (sky/grass/sun/flower pink), Fraunces/Literata, a tilted gradient brand, flower bullets, and a layered-parallax banner (sun rises, clouds drift, nearer hills move less) with idle animations (swaying flowers, floating clouds, breathing sun glow) wrapped in `prefers-reduced-motion: no-preference`.
|
||||
|
||||
## User fonts
|
||||
|
||||
Fonts are shared across themes, so user fonts live in `fonts/` folders next to the theme roots (same list minus the built-in fallback: `views.FONT_DIRS`, e.g. `localhost/fonts/` for the site; built-in fonts ship with the Vite build). A font is a folder `fonts/{name}/` with:
|
||||
|
||||
- `font.css` — `@font-face` rules with URLs relative to the folder (files served at `/_fonts/{name}/...`, per request like themes), plus a `:root { --font-{name}: "Family Name", serif; }` stack variable so themes and custom CSS reference it like the built-in `--font-*` variables.
|
||||
- the font files the CSS references (e.g. `{name}.woff2`).
|
||||
|
||||
Every font.css is linked on all pages (after the base stylesheet, before the theme). The site editor's font picker lists user fonts too, with label and serif/sans grouping parsed from the `--font-{name}` stack. Everything is read per request, so new fonts appear without a restart.
|
||||
|
||||
## Banner designs
|
||||
|
||||
A theme folder may also ship a banner design (`banner.css` + `banner.html` arbitrary markup or `banner.svg`), selectable per page independently of the active theme. Standalone banner designs (no theme.css) ship as:
|
||||
|
||||
- `eyes` — a canvas critter in the grass.
|
||||
- `stars` — a drifting starfield.
|
||||
|
||||
The banner artwork has scroll parallax: pagerite.js sets the `--pry` scroll parameter on `<html>` (event-driven, so it is still when the page is idle), the banner contents drift within their window (with scale overscan so no edge shows), and designs may key their own effects off the same parameter.
|
||||
|
||||
## Page transitions
|
||||
|
||||
A theme folder may ship a page transition (`transition.css`, `::view-transition*` rules), selected site-wide by `Data.transition` in the site settings and injected as `#pagerite-transition` (after the banner design). Standalone transition designs ship as:
|
||||
|
||||
- `cube` — rotating cube (from termotohtori.fi; the block is fragile — do not tweak), mirrored on history-back (`html.nav-back`), crossfading within a section (`html.nav-fade`).
|
||||
- `slide` — plain sideways slide, old and new pages moving together; mirrored on history-back, crossfading within a section.
|
||||
- `reveal` — clip-path wipe revealing the new page over the stationary old one; mirrored on history-back, crossfading within a section.
|
||||
- `crossfade` — plain crossfade for all navigations.
|
||||
|
||||
pagerite.js toggles the `nav-back`/`nav-fade` classes on `<html>` around `document.startViewTransition` (skipped under `prefers-reduced-motion`); a transition design keys its `::view-transition*` rules off them as needed.
|
||||
|
||||
## Stylesheet order
|
||||
|
||||
The backend emits the stylesheets in a fixed order — base (Vite build), theme, banner design, page transition, entry sheets, custom CSS last — each with a stable id so fetch-navigation and the site editor can sync them in place. In dev they are `<link>`s (the base is Vite-injected from JS instead); in production they are inlined as `<style>` elements. The base stylesheet's `--font-brand` defaults to `var(--font-heading)`. Code text (Fira Code by default) is optically matched to the body font by x-height: `font-size-adjust: ex-height var(--code-x-height)` scales whatever code font is in use, so a theme that switches its body font sets `--code-x-height` to that font's x-height ratio (base: 0.478 for Source Sans 3; themes ship values for Inter, Montserrat, Literata and Cause).
|
||||
@@ -37,3 +37,6 @@ __screenshots__/
|
||||
|
||||
# Playwright browser downloads (if ever installed locally)
|
||||
.pw-browsers/
|
||||
|
||||
# npm project config (audit/fund off: the audit endpoint stalls installs)
|
||||
!.npmrc
|
||||
|
||||
@@ -0,0 +1,2 @@
|
||||
audit=false
|
||||
fund=false
|
||||
@@ -18,8 +18,10 @@
|
||||
"@codemirror/view": "^6.43.8",
|
||||
"@lezer/highlight": "^1.2.3",
|
||||
"codemirror": "^6.0.2",
|
||||
"country-flag-icons": "^1.6.20",
|
||||
"overlayscrollbars": "^2.16.0",
|
||||
"paskia": "file:../../paskia/paskia-js",
|
||||
"paskia": "^2.1.0",
|
||||
"pinia": "^4.0.3",
|
||||
"transliteration": "^2.6.1",
|
||||
"vue": "^3.5.26",
|
||||
"vuedraggable": "^4.1.0"
|
||||
|
||||
@@ -0,0 +1,558 @@
|
||||
<script setup>
|
||||
// Analytics viewer rendered as a normal page inside #main. Receives live
|
||||
// analytics data over /_api/ws/analytics (admin-gated by the auth proxy) and
|
||||
// renders totals, smoothed visit/views curves, a transition map, and recent
|
||||
// visit/crawler tables. Read-only.
|
||||
// See docs/analytics.md for the data format.
|
||||
import { computed, onMounted, onUnmounted, ref, watch } from 'vue'
|
||||
import { apiJson } from 'paskia'
|
||||
import {
|
||||
RANGES,
|
||||
rangeWindow,
|
||||
filterRecordsByRange,
|
||||
filterTransitionsByRange,
|
||||
filterViewsByRange,
|
||||
} from './analytics/time.js'
|
||||
import {
|
||||
calcReadStats,
|
||||
calcTotalViews,
|
||||
copyIp,
|
||||
copyList,
|
||||
formatCount,
|
||||
formatAbuseRows,
|
||||
formatCrawlerRows,
|
||||
formatVisitRows,
|
||||
} from './analytics/format.js'
|
||||
import TrailLink from './TrailLink.vue'
|
||||
import RefererBadge from './RefererBadge.vue'
|
||||
import VisitorCell from './VisitorCell.vue'
|
||||
import TransitionGraph from './TransitionGraph.vue'
|
||||
import VisitorCharts from './VisitorCharts.vue'
|
||||
import { VIEW_W } from './analytics/chart.js'
|
||||
import { reconnectPolicy, socketSlot, watchConnecting } from './reconnect'
|
||||
import ConnNote from './ConnNote.vue'
|
||||
|
||||
// Same centering margin as the charts, so the totals row's left edge
|
||||
// aligns with the chart svg above the natural width.
|
||||
const CHART_MARGIN = `max(0px, calc(50% - ${VIEW_W / 2}px))`
|
||||
|
||||
const ABUSE_MAX_LINES = 5
|
||||
|
||||
const data = ref(null)
|
||||
const pageTree = ref(null)
|
||||
const error = ref('')
|
||||
const now = ref(Date.now())
|
||||
let ws = null
|
||||
let reconnectTimeout = null
|
||||
let connectWatchdog = null
|
||||
const reconnects = reconnectPolicy()
|
||||
let timeInterval = null
|
||||
|
||||
// The panel is live data over its socket: while it is connecting or waiting
|
||||
// to reconnect, say so (ConnNote) instead of showing a silent stale view.
|
||||
const conn = ref('connecting') // connecting | open | waiting
|
||||
const retryIn = ref(0)
|
||||
const connNote = computed(() =>
|
||||
conn.value === 'connecting' ? 'connecting to the server…'
|
||||
: conn.value === 'waiting' ? `connection lost — reconnecting in ~${retryIn.value} s…`
|
||||
: '',
|
||||
)
|
||||
|
||||
// The initial range comes from the URL hash (shareable links); without one,
|
||||
// it is derived from the first analytics snapshot: day when the recorded
|
||||
// history is shorter than 24 h, week otherwise.
|
||||
const hashRange = location.hash.slice(1)
|
||||
const range = ref(RANGES[hashRange] ? hashRange : 'week')
|
||||
let rangePinned = Boolean(RANGES[hashRange])
|
||||
|
||||
function connectAnalytics() {
|
||||
if (ws) return
|
||||
conn.value = 'connecting'
|
||||
const proto = location.protocol === 'https:' ? 'wss:' : 'ws:'
|
||||
ws = new WebSocket(`${proto}//${location.host}/_api/ws/analytics`)
|
||||
clearTimeout(connectWatchdog)
|
||||
connectWatchdog = watchConnecting(ws, 'analytics')
|
||||
ws.onopen = () => {
|
||||
conn.value = 'open'
|
||||
reconnects.opened()
|
||||
error.value = ''
|
||||
}
|
||||
ws.onmessage = (event) => {
|
||||
try {
|
||||
data.value = JSON.parse(event.data)
|
||||
if (!rangePinned) {
|
||||
rangePinned = true
|
||||
const starts = (data.value?.visits || [])
|
||||
.map((v) => Date.parse(v.start))
|
||||
.filter((t) => !Number.isNaN(t))
|
||||
if (starts.length && Date.now() - Math.min(...starts) < 24 * 3600 * 1000) {
|
||||
range.value = 'day'
|
||||
}
|
||||
}
|
||||
} catch {
|
||||
error.value = 'analytics data could not be loaded'
|
||||
}
|
||||
}
|
||||
ws.onerror = () => {
|
||||
error.value = 'analytics data could not be loaded'
|
||||
}
|
||||
ws.onclose = () => {
|
||||
ws = null
|
||||
// The policy paces the retry: doubling backoff with jitter, reset only
|
||||
// by a healthy connection — a fixed rapid loop trips the browser's
|
||||
// WebSocket throttling (all sockets then sit "pending" for minutes).
|
||||
const wait = reconnects.closed()
|
||||
retryIn.value = Math.max(1, Math.round(wait / 1000))
|
||||
conn.value = 'waiting'
|
||||
reconnectTimeout = setTimeout(connectAnalytics, wait)
|
||||
}
|
||||
}
|
||||
|
||||
onMounted(async () => {
|
||||
// The first connection takes a staggered slot (see ./reconnect).
|
||||
reconnectTimeout = setTimeout(connectAnalytics, socketSlot())
|
||||
now.value = Date.now()
|
||||
timeInterval = setInterval(() => { now.value = Date.now() }, 1000)
|
||||
// The site tree for the transition map (all pages in menu order). Not
|
||||
// fatal: without it the map just narrows to pages seen in transitions.
|
||||
try {
|
||||
pageTree.value = await apiJson('/_api/pages')
|
||||
} catch { /* map just narrows to pages seen in transitions */ }
|
||||
})
|
||||
|
||||
onUnmounted(() => {
|
||||
if (reconnectTimeout) clearTimeout(reconnectTimeout)
|
||||
if (connectWatchdog) clearTimeout(connectWatchdog)
|
||||
if (timeInterval) clearInterval(timeInterval)
|
||||
if (ws) {
|
||||
ws.onclose = null
|
||||
ws.close()
|
||||
ws = null
|
||||
}
|
||||
})
|
||||
|
||||
const window = computed(() => rangeWindow(range.value))
|
||||
|
||||
// All non-chart stats follow the selected range; the charts keep their own
|
||||
// range-specific x windows (week aligned to Monday, overlaid with the
|
||||
// seasonal "typical week" curve).
|
||||
const rangeData = computed(() => {
|
||||
if (!data.value) return null
|
||||
const { t0, t1 } = window.value
|
||||
return {
|
||||
...data.value,
|
||||
transitions: filterTransitionsByRange(data.value.transitions, t0, t1),
|
||||
views: filterViewsByRange(data.value.views, t0, t1),
|
||||
visits: filterRecordsByRange(data.value.visits, t0, t1),
|
||||
crawlers: filterRecordsByRange(data.value.crawlers, t0, t1),
|
||||
abuse: filterRecordsByRange(data.value.abuse, t0, t1),
|
||||
}
|
||||
})
|
||||
|
||||
const visits = computed(() => rangeData.value?.visits || [])
|
||||
const totalViews = computed(() => calcTotalViews(rangeData.value?.views))
|
||||
const readStats = computed(() => calcReadStats(visits.value))
|
||||
|
||||
// Keep the URL shareable when the range changes.
|
||||
watch(range, (r) => {
|
||||
const url = new URL(location.href)
|
||||
url.hash = r
|
||||
history.replaceState(history.state, '', url)
|
||||
})
|
||||
|
||||
const clients = computed(() => data.value?.clients || {})
|
||||
const favicons = computed(() => data.value?.favicons || {})
|
||||
// Site language context from the payload: drives the discreet rendered-
|
||||
// language markers in the visit/crawler rows (multilingual sites only).
|
||||
const site = computed(() => ({
|
||||
multilingual: !!data.value?.multilingual,
|
||||
primaryLang: data.value?.primary_lang || '',
|
||||
}))
|
||||
const visitRows = computed(() => formatVisitRows(visits.value, clients.value, pageTree.value, now.value, site.value))
|
||||
const crawlers = computed(() => rangeData.value?.crawlers || [])
|
||||
const crawlerRows = computed(() => formatCrawlerRows(crawlers.value, clients.value, pageTree.value, now.value, site.value))
|
||||
const abuseRows = computed(() => formatAbuseRows(rangeData.value?.abuse || [], clients.value, pageTree.value, now.value))
|
||||
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<!-- Untranslated admin dashboard: always LTR, like the editor panel. -->
|
||||
<div class="analytics-view" lang="en" dir="ltr">
|
||||
<div class="analytics-panel">
|
||||
<header>
|
||||
<h1>Analytics</h1>
|
||||
<nav class="ranges">
|
||||
<button v-for="(r, key) in RANGES" :key="key" type="button"
|
||||
:class="{ active: range === key }" @click="range = key">
|
||||
{{ r.label }}
|
||||
</button>
|
||||
</nav>
|
||||
<a href="/" class="close" title="home">✕</a>
|
||||
</header>
|
||||
<ConnNote :text="connNote" />
|
||||
<p v-if="error" class="error">⚠️ {{ error }}</p>
|
||||
<p v-else-if="!data" class="loading">loading…</p>
|
||||
<template v-else>
|
||||
<section class="totals" :style="{ marginLeft: CHART_MARGIN }">
|
||||
<div><strong :title="String(visits.length)">{{ formatCount(visits.length) }}</strong> visits</div>
|
||||
<div><strong :title="String(totalViews)">{{ formatCount(totalViews) }}</strong> page views</div>
|
||||
<div><strong>{{ readStats.avgMinPerVisit }}</strong> min/visit</div>
|
||||
<div><strong>{{ readStats.avgArticleMedianMin }}</strong> min/read</div>
|
||||
</section>
|
||||
|
||||
<VisitorCharts :data="data" :range="range" />
|
||||
<TransitionGraph :data="rangeData" :window="window" :page-tree="pageTree" :favicons="favicons" />
|
||||
|
||||
<section>
|
||||
<h2>Recent visits</h2>
|
||||
<div v-if="visitRows.length" class="visit-table-wrap">
|
||||
<table class="visit-table">
|
||||
<thead>
|
||||
<tr>
|
||||
<th>trail</th>
|
||||
<th>visitor</th>
|
||||
<th class="last-seen">last seen</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr v-for="(v, i) in visitRows" :key="i">
|
||||
<td class="trail">
|
||||
<RefererBadge v-if="v.refererBadge" :badge="v.refererBadge" :favicons="favicons" />
|
||||
<span v-if="v.rowFlag" class="flag" v-html="v.rowFlag" :title="v.rowFlagTitle"></span>
|
||||
<TrailLink v-for="(s, si) in v.trail" :key="si" :step="s" :favicons="favicons" :flags="s.langFlags" @close="$emit('close')" />
|
||||
</td>
|
||||
<VisitorCell
|
||||
:ip="v.ip"
|
||||
:ip-display="v.ipDisplay"
|
||||
:ua="v.ua"
|
||||
:ua-raw="v.uaRaw"
|
||||
:ua-url="v.uaUrl"
|
||||
:country="v.country"
|
||||
:city="v.city"
|
||||
:lang="v.lang"
|
||||
:lang-display="v.langDisplay"
|
||||
:is-host="v.isHost"
|
||||
/>
|
||||
<td class="last-seen muted"
|
||||
:title="v.lastSeenLocal"
|
||||
@click="copyList(v.lastSeenIso, $event)">{{ v.lastSeen }}</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
</div>
|
||||
<p v-else class="empty">no visits recorded yet</p>
|
||||
|
||||
<div v-if="crawlerRows.length" class="visit-table-wrap">
|
||||
<table class="visit-table">
|
||||
<thead>
|
||||
<tr>
|
||||
<th>pages crawled</th>
|
||||
<th>visitor</th>
|
||||
<th class="last-seen">last seen</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr v-for="(c, i) in crawlerRows" :key="i">
|
||||
<td class="trail">
|
||||
<RefererBadge v-if="c.refererBadge" :badge="c.refererBadge" :favicons="favicons" />
|
||||
<TrailLink v-for="(s, si) in c.pages" :key="si" :step="s" :count="s.count" @close="$emit('close')" />
|
||||
<span v-for="(f, fi) in c.readFlags" :key="fi" class="flag" v-html="f.flag" :title="f.name"></span>
|
||||
</td>
|
||||
<VisitorCell
|
||||
:ip="c.ip"
|
||||
:ip-display="c.ipDisplay"
|
||||
:ua="c.ua"
|
||||
:ua-raw="c.uaRaw"
|
||||
:ua-url="c.uaUrl"
|
||||
:country="c.country"
|
||||
:city="c.city"
|
||||
:lang="c.lang"
|
||||
:lang-display="c.langDisplay"
|
||||
:is-host="c.isHost"
|
||||
/>
|
||||
<td class="last-seen muted"
|
||||
:title="c.lastSeenLocal"
|
||||
@click="copyList(c.lastSeenIso, $event)">{{ c.lastSeen }}</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
<div v-if="abuseRows.length" class="visit-table-wrap">
|
||||
<table class="visit-table">
|
||||
<thead>
|
||||
<tr>
|
||||
<th>paths abused</th>
|
||||
<th>articles read</th>
|
||||
<th>visitor</th>
|
||||
<th class="last-seen">last seen</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr v-for="(a, i) in abuseRows" :key="i">
|
||||
<td class="trail abuse-list clickable-list"
|
||||
@click="copyList(a.allPaths, $event)">
|
||||
<div class="abuse-items">
|
||||
<span v-for="(p, pi) in a.paths.slice(0, ABUSE_MAX_LINES)" :key="pi"
|
||||
class="inline-item">
|
||||
<small v-if="p.count > 1" class="muted">{{ formatCount(p.count) }}×</small>{{ p.path }}
|
||||
</span>
|
||||
<small v-if="a.paths.length > ABUSE_MAX_LINES" class="muted">+{{ a.paths.length - ABUSE_MAX_LINES }} more</small>
|
||||
</div>
|
||||
</td>
|
||||
<td class="trail clickable-list"
|
||||
@click="copyList(a.allArticles, $event)">
|
||||
<TrailLink v-for="(s, si) in a.articles" :key="si" :step="s" :count="s.count" @close="$emit('close')" />
|
||||
<small v-if="!a.articles.length" class="muted">—</small>
|
||||
</td>
|
||||
<VisitorCell
|
||||
:ip="a.ip"
|
||||
:ip-display="a.ipDisplay"
|
||||
:ua="a.ua"
|
||||
:ua-raw="a.uaRaw"
|
||||
:ua-url="a.uaUrl"
|
||||
:ua-raws="a.uaRaws"
|
||||
:country="a.country"
|
||||
:city="a.city"
|
||||
:lang="a.lang"
|
||||
:lang-display="a.langDisplay"
|
||||
:is-host="a.isHost"
|
||||
:variant-count="a.clientCount"
|
||||
/>
|
||||
<td class="last-seen muted"
|
||||
:title="a.lastSeenLocal"
|
||||
@click="copyList(a.lastSeenIso, $event)">{{ a.lastSeen }}</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
</div>
|
||||
</section>
|
||||
</template>
|
||||
</div>
|
||||
</div>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
.analytics-view {
|
||||
min-height: 100vh;
|
||||
background: var(--bg, Canvas);
|
||||
color: var(--text, CanvasText);
|
||||
}
|
||||
|
||||
.analytics-panel {
|
||||
margin: 0;
|
||||
width: 100%;
|
||||
/* Same 1.25rem side spacing as main's article padding. */
|
||||
padding: 1.5rem 1.25rem 4rem;
|
||||
/* Container for cqw-based shrink-to-fit (see .totals). */
|
||||
container-type: inline-size;
|
||||
}
|
||||
|
||||
.analytics-panel header {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 1rem;
|
||||
}
|
||||
|
||||
.analytics-panel h1 {
|
||||
margin: 0;
|
||||
font-size: 1.4rem;
|
||||
}
|
||||
|
||||
.ranges {
|
||||
display: flex;
|
||||
gap: 0.25rem;
|
||||
margin-left: auto;
|
||||
}
|
||||
|
||||
.ranges button {
|
||||
padding: 0.2rem 0.7rem;
|
||||
font: inherit;
|
||||
font-size: 0.9rem;
|
||||
color: var(--muted);
|
||||
background: none;
|
||||
border: 1px solid var(--line);
|
||||
border-radius: 1rem;
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.ranges button:hover { color: var(--text); }
|
||||
|
||||
.ranges button.active {
|
||||
color: var(--text);
|
||||
border-color: var(--accent);
|
||||
}
|
||||
|
||||
.close {
|
||||
padding: 0 0.3rem;
|
||||
background: none;
|
||||
border: none;
|
||||
color: var(--muted);
|
||||
font-size: 1.2rem;
|
||||
cursor: pointer;
|
||||
}
|
||||
.close:hover { color: var(--text); }
|
||||
|
||||
.analytics-panel h2 {
|
||||
margin: 0 0 0.6rem;
|
||||
font-size: 1rem;
|
||||
color: var(--muted);
|
||||
}
|
||||
|
||||
.analytics-panel section {
|
||||
margin-top: 1.8rem;
|
||||
}
|
||||
|
||||
.analytics-view a {
|
||||
color: var(--text);
|
||||
text-decoration: none;
|
||||
}
|
||||
.analytics-view a:hover { color: var(--accent); }
|
||||
|
||||
.analytics-view :deep(.muted) { color: var(--muted); }
|
||||
.analytics-view :deep(.small) { font-size: 0.75em; }
|
||||
|
||||
/* One line at any width: the gap shrinks first, then the font (the number
|
||||
scales along in em), both following the panel's container width. */
|
||||
.totals {
|
||||
display: flex;
|
||||
gap: clamp(0.5rem, 3cqw, 2rem);
|
||||
font-size: clamp(0.6rem, 2.2cqw, 1.1rem);
|
||||
white-space: nowrap;
|
||||
}
|
||||
.totals strong { font-size: 1.36em; }
|
||||
|
||||
.visit-table-wrap {
|
||||
overflow-x: auto;
|
||||
}
|
||||
|
||||
.visit-table {
|
||||
width: 100%;
|
||||
border-collapse: collapse;
|
||||
font-size: 0.9rem;
|
||||
line-height: 1.3;
|
||||
}
|
||||
|
||||
.visit-table th,
|
||||
.visit-table td {
|
||||
padding: 0.25rem 0.5rem;
|
||||
border-bottom: 1px solid var(--line);
|
||||
text-align: left;
|
||||
vertical-align: top;
|
||||
}
|
||||
|
||||
.visit-table th {
|
||||
color: var(--muted);
|
||||
font-weight: normal;
|
||||
text-transform: lowercase;
|
||||
position: sticky;
|
||||
top: 0;
|
||||
background: var(--bg, Canvas);
|
||||
}
|
||||
|
||||
.visit-table .last-seen {
|
||||
width: 6rem;
|
||||
text-align: right;
|
||||
white-space: nowrap;
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.visit-table .trail {
|
||||
max-width: 20rem;
|
||||
overflow-wrap: break-word;
|
||||
}
|
||||
|
||||
.visit-table .trail a,
|
||||
.visit-table .trail-link {
|
||||
display: inline-block;
|
||||
max-width: 8rem;
|
||||
white-space: nowrap;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
vertical-align: bottom;
|
||||
}
|
||||
|
||||
.visit-table .trail > * + * {
|
||||
margin-left: 0.5rem;
|
||||
}
|
||||
|
||||
.analytics-view :deep(.trail-link.error),
|
||||
.analytics-view :deep(.trail-link.error:hover) {
|
||||
color: var(--error, #c00);
|
||||
}
|
||||
|
||||
/* The referer badge outgrows the 8rem trail-link cap (it carries the UTM
|
||||
summary too); keep the inline-flex layout from the component. The
|
||||
generic trail-link rule above would otherwise clip the badge (overflow:
|
||||
hidden, hiding the absolutely positioned favicon) and cap its inner
|
||||
link — the link is display: contents, so its parts lay out as badge
|
||||
flex items. */
|
||||
.visit-table .trail .referer-badge {
|
||||
display: inline-flex;
|
||||
max-width: 100%;
|
||||
overflow: visible;
|
||||
}
|
||||
|
||||
.visit-table .trail .referer-badge a.badge-link {
|
||||
display: contents;
|
||||
}
|
||||
|
||||
/* Same flag chip as the visitor cells (VisitorCell.vue); the flags here
|
||||
mark the language the page was read in. */
|
||||
.visit-table .flag {
|
||||
display: inline-flex;
|
||||
width: 18px;
|
||||
height: 12px;
|
||||
border-radius: 2px;
|
||||
overflow: hidden;
|
||||
border: 1px solid var(--line);
|
||||
box-shadow: 0 0 0 1px rgba(0, 0, 0, 0.2) inset;
|
||||
vertical-align: middle;
|
||||
}
|
||||
|
||||
.visit-table .flag :deep(svg) {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
display: block;
|
||||
}
|
||||
|
||||
.visit-table .clickable-list {
|
||||
cursor: pointer;
|
||||
max-width: 22rem;
|
||||
}
|
||||
|
||||
.visit-table .abuse-items {
|
||||
display: flex;
|
||||
flex-wrap: wrap;
|
||||
gap: 0.15rem 0.5rem;
|
||||
align-items: baseline;
|
||||
}
|
||||
|
||||
.visit-table .inline-item {
|
||||
max-width: 18rem;
|
||||
min-width: 0;
|
||||
white-space: nowrap;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
word-break: keep-all;
|
||||
hyphens: none;
|
||||
}
|
||||
|
||||
.visit-table :deep(.clickable-ip),
|
||||
.visit-table .clickable-list,
|
||||
.visit-table .last-seen {
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.crawler-top-uas {
|
||||
font-size: 0.9rem;
|
||||
margin-bottom: 0.6rem;
|
||||
}
|
||||
|
||||
.crawler-top-uas strong {
|
||||
color: var(--muted);
|
||||
}
|
||||
|
||||
.empty, .loading, .error { color: var(--muted); }
|
||||
.error { color: var(--error, #c00); }
|
||||
</style>
|
||||
@@ -1,12 +1,19 @@
|
||||
<script setup>
|
||||
// Banner editor tab: per-page banner HTML and banner design, previewed into
|
||||
// the real #page-banner region. Close and tab switching live in EditorShell.
|
||||
// the real #page-banner region, plus the page's card image (Node.image,
|
||||
// inherited by the subtree — the effective one previews, dimmed when
|
||||
// inherited). Close and tab switching live in EditorShell.
|
||||
import { computed, onActivated, onMounted, onUnmounted, ref, watch } from 'vue'
|
||||
import { EditorView, basicSetup } from 'codemirror'
|
||||
import { EditorState } from '@codemirror/state'
|
||||
import { Compartment, EditorState } from '@codemirror/state'
|
||||
import { keymap } from '@codemirror/view'
|
||||
import { indentWithTab } from '@codemirror/commands'
|
||||
import { html } from '@codemirror/lang-html'
|
||||
import { cmHighlight, cmTheme } from './cmtheme'
|
||||
import { loadPlain, runScripts } from './swapdoc'
|
||||
import ConnNote from './ConnNote.vue'
|
||||
import { reconnectPolicy, socketSlot, watchConnecting } from './reconnect'
|
||||
import { dropPageCache, loadPlain, runScripts } from './swapdoc'
|
||||
import { apiFetch, apiJson } from 'paskia'
|
||||
|
||||
const props = defineProps({
|
||||
pagePath: { type: String, default: '' },
|
||||
@@ -18,14 +25,28 @@ const path = ref('')
|
||||
const banner = ref('')
|
||||
const saveError = ref('')
|
||||
const fileInput = ref(null)
|
||||
const imageInput = ref(null)
|
||||
const bannerEl = ref(null)
|
||||
|
||||
let ws = null
|
||||
let pendingSave = null
|
||||
let reconnectTimer = null
|
||||
let reconnectDelay = 2000
|
||||
const MAX_RECONNECT_DELAY = 16000
|
||||
let connectWatchdog = null
|
||||
// Reconnection pacing lives in ./reconnect (shared with the other sockets).
|
||||
const reconnects = reconnectPolicy()
|
||||
let everConnected = false
|
||||
// Connection state drives the note at the top (ConnNote), and locks input
|
||||
// until the banner's document has arrived (typing before it would be
|
||||
// clobbered by the doc accept).
|
||||
const conn = ref('connecting') // connecting | open | waiting
|
||||
const retryIn = ref(0)
|
||||
const docReady = ref(false)
|
||||
const editable = new Compartment()
|
||||
const connNote = computed(() =>
|
||||
conn.value === 'connecting' ? 'connecting to the server…'
|
||||
: conn.value === 'waiting' ? `connection lost — reconnecting in ~${retryIn.value} s…`
|
||||
: docReady.value ? '' : 'loading the banner…',
|
||||
)
|
||||
let view = null // CodeMirror for the banner HTML
|
||||
let syncing = false // set while replacing the document programmatically
|
||||
|
||||
@@ -45,6 +66,132 @@ const bannerDesignInherited = ref('')
|
||||
// whose re-render must not race the save it triggers).
|
||||
let refreshOnSave = null
|
||||
|
||||
// --- Card image (Node.image, '' = inherit, like the banner design) ------
|
||||
// The node's own setting ('@favicon' = the site icon, resolved live
|
||||
// against the favicon ref), the effective image after inheritance ("" =
|
||||
// none, already resolved server-side) and which node supplied an
|
||||
// inherited one ("" = the front page, "" also when own/none — mirrors
|
||||
// bannerFrom).
|
||||
const image = ref('')
|
||||
const imageResolved = ref('')
|
||||
const imageSource = ref('')
|
||||
// The site icon (bare store hash, "" = none): the "@favicon" own setting
|
||||
// resolves against it, live, in the previews.
|
||||
const favicon = ref('')
|
||||
// The image the server would mine from the article itself — the card
|
||||
// previews fall back to it when the node has no image of its own, and it
|
||||
// beats an inherited one (mirrors og:image).
|
||||
const imageMined = ref('')
|
||||
// Whether the page has children (from the doc message): an own share
|
||||
// image is inherited by the whole section.
|
||||
const hasChildren = ref(false)
|
||||
// The block label states which image is currently in use.
|
||||
const imageLabel = computed(() => {
|
||||
if (image.value === '@favicon') {
|
||||
return 'card image: the site icon (follows favicon changes)'
|
||||
}
|
||||
if (image.value) {
|
||||
return hasChildren.value
|
||||
? `card image: set for this article — used in /${path.value}/*`
|
||||
: 'card image: set for this article'
|
||||
}
|
||||
if (imageMined.value) return 'card image: from the article'
|
||||
if (imageResolved.value) {
|
||||
const where = imageSource.value === '' ? 'the front page' : `/${imageSource.value}`
|
||||
return `card image: inherited from ${where}`
|
||||
}
|
||||
return 'card image: none'
|
||||
})
|
||||
// The page title and description (from the doc message) feed the mock card
|
||||
// previews; empty shows placeholder bars / text instead.
|
||||
const pageTitle = ref('')
|
||||
const pageDesc = ref('')
|
||||
// The image the Twitter cards preview with: the node's own card image
|
||||
// ("@favicon" resolves to the site icon), else the mined article image,
|
||||
// else the inherited node image (what og:image would use).
|
||||
// image/image_resolved are bare store hashes; image_mined is already a
|
||||
// src path.
|
||||
const cardImage = computed(() => {
|
||||
// "@favicon" with no site icon configured falls through like no own
|
||||
// image at all (mirrors the backend's resolution).
|
||||
const own = image.value === '@favicon' ? favicon.value : image.value
|
||||
if (own) return `/_f/${own}`
|
||||
return imageMined.value || (imageResolved.value ? `/_f/${imageResolved.value}` : '')
|
||||
})
|
||||
// Card-mode override (Node.large, per-article, NOT inherited):
|
||||
// null = automatic, false = small, true = large.
|
||||
const large = ref(null)
|
||||
// Approximation of the server's automatic pick for the "automatic"
|
||||
// marker: the real check probes image dimensions (>= 600px wide,
|
||||
// landscape-ish AR) server-side, unavailable here — presence of an
|
||||
// effective image stands in for "large".
|
||||
const autoLarge = computed(() => !!cardImage.value)
|
||||
const effectiveLarge = computed(() => large.value ?? autoLarge.value)
|
||||
|
||||
function toggleCard(forced) {
|
||||
// Clicking the already-selected card deselects back to automatic.
|
||||
const msg = {
|
||||
type: 'save',
|
||||
path: normPath(path.value),
|
||||
large: large.value === forced ? null : forced,
|
||||
}
|
||||
large.value = msg.large
|
||||
pendingSave = msg
|
||||
send(msg)
|
||||
// twitter:card is part of the page head: re-render on ack.
|
||||
refreshOnSave = rerender
|
||||
}
|
||||
function saveImage(hash) {
|
||||
const msg = { type: 'save', path: normPath(path.value), image: hash }
|
||||
pendingSave = msg
|
||||
send(msg)
|
||||
// The card image feeds the card previews, card covers and social meta:
|
||||
// on ack re-open the doc (fresh image/image_resolved/image_source — the
|
||||
// banner itself saves in real time, so nothing is lost) and re-render.
|
||||
refreshOnSave = () => {
|
||||
openPath(normPath(path.value))
|
||||
rerender()
|
||||
}
|
||||
}
|
||||
|
||||
async function uploadCardImage(ev) {
|
||||
// Card images go to the shared content store, like banner media.
|
||||
const file = ev.target.files[0]
|
||||
ev.target.value = '' // allow re-picking the same file
|
||||
if (!file || !file.type.startsWith('image/')) return
|
||||
storeCardImage(file, file.name)
|
||||
}
|
||||
|
||||
async function storeCardImage(blob, filename) {
|
||||
const name = filename.replace(/[^\w.-]/g, '-')
|
||||
const res = await apiFetch(`/_api/files/${encodeURIComponent(name)}`, { method: 'PUT', body: blob })
|
||||
if (!res.ok) return
|
||||
const { path: stored } = await res.json() // "/_f/<hash>[.ext]"
|
||||
saveImage(stored.split('/').pop().split('.')[0])
|
||||
}
|
||||
|
||||
async function pasteCardImage() {
|
||||
// The pasteboard button (unlike pasting into a text editor, where the
|
||||
// paste event carries files) must read the clipboard explicitly.
|
||||
try {
|
||||
for (const item of await navigator.clipboard.read()) {
|
||||
const type = item.types.find((t) => t.startsWith('image/'))
|
||||
if (type) {
|
||||
const blob = await item.getType(type)
|
||||
await storeCardImage(blob, `paste.${type.split('/')[1].replace('+xml', '')}`)
|
||||
return
|
||||
}
|
||||
}
|
||||
// No image on the pasteboard: a pasted URL goes as the setting
|
||||
// itself — the server fetches and stores it (cross-origin URLs are
|
||||
// CORS-blocked for the browser).
|
||||
const text = (await navigator.clipboard.readText()).trim()
|
||||
if (/^https?:\/\/\S+$/.test(text)) saveImage(text)
|
||||
} catch {
|
||||
// Clipboard read denied or empty: nothing to do.
|
||||
}
|
||||
}
|
||||
|
||||
// The inherit option names the design actually in effect and its source.
|
||||
const inheritLabel = computed(() => {
|
||||
if (bannerDesignFrom.value === null) {
|
||||
@@ -88,6 +235,9 @@ function save() {
|
||||
|
||||
function openPath(p) {
|
||||
path.value = p
|
||||
// Lock input until the doc arrives (typing would be clobbered by it).
|
||||
docReady.value = false
|
||||
view?.dispatch({ effects: editable.reconfigure(EditorView.editable.of(false)) })
|
||||
send({ type: 'open', path: p })
|
||||
}
|
||||
watch(() => props.pagePath, (p) => { openPath(normPath(p)) })
|
||||
@@ -111,7 +261,7 @@ function onEditorShown() {
|
||||
|
||||
async function loadSettings() {
|
||||
try {
|
||||
const s = await (await fetch('/_api/settings')).json()
|
||||
const s = await apiJson('/_api/settings')
|
||||
theme.value = s.theme || ''
|
||||
bannerDesigns.value = s.banner_designs || []
|
||||
} catch { /* keep default */ }
|
||||
@@ -182,7 +332,7 @@ async function uploadBannerMedia(file) {
|
||||
// Banner media goes to the shared content store, like article images.
|
||||
if (!file || !/^(image|video)\//.test(file.type)) return
|
||||
const name = file.name.replace(/[^\w.-]/g, '-')
|
||||
const res = await fetch(`/_api/files/${encodeURIComponent(name)}`, { method: 'PUT', body: file })
|
||||
const res = await apiFetch(`/_api/files/${encodeURIComponent(name)}`, { method: 'PUT', body: file })
|
||||
if (!res.ok) return
|
||||
const { path: stored } = await res.json()
|
||||
const tag = file.type.startsWith('video/')
|
||||
@@ -207,14 +357,27 @@ function onMessage(ev) {
|
||||
const msg = JSON.parse(ev.data)
|
||||
if (msg.type === 'doc' && msg.path === path.value) {
|
||||
setDocument(msg.banner ?? '')
|
||||
docReady.value = true
|
||||
view.dispatch({ effects: editable.reconfigure(EditorView.editable.of(true)) })
|
||||
bannerDesign.value = msg.banner_design ?? null
|
||||
bannerDesignFrom.value = msg.banner_design_from ?? null
|
||||
bannerDesignInherited.value = msg.banner_design_inherited ?? ''
|
||||
bannerFrom.value = msg.banner_from ?? null
|
||||
image.value = msg.image ?? ''
|
||||
imageResolved.value = msg.image_resolved ?? ''
|
||||
imageMined.value = msg.image_mined ?? ''
|
||||
imageSource.value = msg.image_source ?? ''
|
||||
favicon.value = msg.favicon ?? ''
|
||||
hasChildren.value = msg.has_children ?? false
|
||||
large.value = msg.large ?? null
|
||||
pageTitle.value = msg.title ?? ''
|
||||
pageDesc.value = msg.description ?? ''
|
||||
if (banner.value.trim()) previewBanner()
|
||||
} else if (msg.type === 'saved') {
|
||||
saveError.value = ''
|
||||
pendingSave = null
|
||||
// Banner HTML/design changes affect the rendered page; invalidate prefetches.
|
||||
dropPageCache()
|
||||
refreshOnSave?.()
|
||||
refreshOnSave = null
|
||||
} else if (msg.type === 'error') {
|
||||
@@ -230,12 +393,22 @@ function onKeydown(ev) {
|
||||
}
|
||||
|
||||
function connect() {
|
||||
clearTimeout(reconnectTimer)
|
||||
conn.value = 'connecting'
|
||||
if (ws) {
|
||||
// Replacing a stale socket: detach its handlers so its close is silent.
|
||||
ws.onopen = ws.onmessage = ws.onclose = ws.onerror = null
|
||||
if (ws.readyState !== WebSocket.CLOSED) ws.close()
|
||||
}
|
||||
ws = new WebSocket(
|
||||
`${location.protocol === 'https:' ? 'wss' : 'ws'}://${location.host}/_api/ws/editor`,
|
||||
)
|
||||
ws.onmessage = onMessage
|
||||
clearTimeout(connectWatchdog)
|
||||
connectWatchdog = watchConnecting(ws, 'banner')
|
||||
ws.onopen = () => {
|
||||
reconnectDelay = 2000
|
||||
conn.value = 'open'
|
||||
reconnects.opened()
|
||||
if (everConnected) {
|
||||
if (pendingSave) send(pendingSave)
|
||||
} else {
|
||||
@@ -244,25 +417,32 @@ function connect() {
|
||||
everConnected = true
|
||||
}
|
||||
ws.onclose = () => {
|
||||
clearTimeout(reconnectTimer)
|
||||
reconnectTimer = setTimeout(() => {
|
||||
connect()
|
||||
reconnectDelay = Math.min(reconnectDelay * 2, MAX_RECONNECT_DELAY)
|
||||
}, reconnectDelay)
|
||||
// The wait is the policy's: doubling backoff with jitter (./reconnect),
|
||||
// reset only by a healthy connection — rapid retries trip the browser's
|
||||
// WebSocket throttling (sockets stuck "pending" for minutes).
|
||||
const wait = reconnects.closed()
|
||||
retryIn.value = Math.max(1, Math.round(wait / 1000))
|
||||
conn.value = 'waiting'
|
||||
reconnectTimer = setTimeout(connect, wait)
|
||||
}
|
||||
}
|
||||
|
||||
onMounted(async () => {
|
||||
connect()
|
||||
// The first connection takes a staggered slot (see ./reconnect).
|
||||
reconnectTimer = setTimeout(connect, socketSlot())
|
||||
view = new EditorView({
|
||||
state: EditorState.create({
|
||||
doc: '',
|
||||
extensions: [
|
||||
basicSetup,
|
||||
// Tab/Shift-Tab indent and dedent instead of moving focus.
|
||||
keymap.of([indentWithTab]),
|
||||
html(),
|
||||
cmTheme,
|
||||
cmHighlight,
|
||||
EditorView.lineWrapping,
|
||||
// Locked until the banner's document arrives (docReady/ConnNote).
|
||||
editable.of(EditorView.editable.of(false)),
|
||||
EditorView.updateListener.of((u) => {
|
||||
if (u.docChanged && !syncing) {
|
||||
banner.value = view.state.doc.toString()
|
||||
@@ -280,6 +460,7 @@ onMounted(async () => {
|
||||
|
||||
onUnmounted(() => {
|
||||
clearTimeout(reconnectTimer)
|
||||
clearTimeout(connectWatchdog)
|
||||
for (const t of Object.values(timers)) clearTimeout(t)
|
||||
if (ws) {
|
||||
ws.onclose = null // intentional close, no reconnect
|
||||
@@ -294,8 +475,81 @@ onUnmounted(() => {
|
||||
<template>
|
||||
<div class="banner-editor">
|
||||
<div v-if="saveError">{{ saveError }}</div>
|
||||
<ConnNote :text="connNote" />
|
||||
|
||||
<section class="block" @paste="onBannerPaste">
|
||||
<section class="block card-image">
|
||||
<div class="block-head">
|
||||
<span class="block-label">{{ imageLabel }}</span>
|
||||
<button
|
||||
v-if="image"
|
||||
type="button"
|
||||
class="icon-btn del"
|
||||
title="clear the card image (back to inherit)"
|
||||
@click="saveImage('')"
|
||||
>❌</button>
|
||||
<button
|
||||
type="button"
|
||||
class="icon-btn"
|
||||
title="upload card image (og:image / card covers) — the subtree inherits it"
|
||||
@click="imageInput.click()"
|
||||
>🖼︎</button>
|
||||
<button
|
||||
type="button"
|
||||
class="icon-btn"
|
||||
title="paste a card image from the pasteboard (image or image URL)"
|
||||
@click="pasteCardImage"
|
||||
>📋</button>
|
||||
<button
|
||||
v-if="favicon"
|
||||
type="button"
|
||||
class="icon-btn favicon-btn"
|
||||
title="use the site icon as the card image — follows favicon changes"
|
||||
@click="saveImage('@favicon')"
|
||||
><img :src="`/_f/${favicon}`" alt="site icon" /></button>
|
||||
<input
|
||||
ref="imageInput"
|
||||
type="file"
|
||||
accept="image/*"
|
||||
hidden
|
||||
@change="uploadCardImage"
|
||||
/>
|
||||
</div>
|
||||
<!-- The site's own cards double as the card-mode selector: rendered
|
||||
with the real .card styles from pagerite.css (theme variables
|
||||
and all — they ARE the site's look). Clicking one forces that
|
||||
mode (Node.large), clicking the selected one returns to
|
||||
automatic. The description only exists in the small format,
|
||||
like the backend's _card. -->
|
||||
<div class="site-previews">
|
||||
<button
|
||||
type="button"
|
||||
class="card compact preview"
|
||||
:class="{ selected: large === false, auto: large === null && !effectiveLarge }"
|
||||
title="small card — click to force it, click again for automatic"
|
||||
@click="toggleCard(false)"
|
||||
>
|
||||
<span class="top">
|
||||
<img v-if="cardImage" class="cover" :src="cardImage" alt="" />
|
||||
<span class="title">{{ pageTitle || 'page title' }}</span>
|
||||
</span>
|
||||
<span class="bottom">
|
||||
<span v-if="pageDesc" class="desc">{{ pageDesc }}</span>
|
||||
</span>
|
||||
</button>
|
||||
<button
|
||||
type="button"
|
||||
class="card preview"
|
||||
:class="{ selected: large === true, auto: large === null && effectiveLarge }"
|
||||
title="large card — click to force it, click again for automatic"
|
||||
@click="toggleCard(true)"
|
||||
>
|
||||
<span class="cover" :style="cardImage ? `background-image: url('${cardImage}')` : null" />
|
||||
<span class="title">{{ pageTitle || 'page title' }}</span>
|
||||
</button>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section class="block banner-block" @paste="onBannerPaste">
|
||||
<div class="block-head">
|
||||
<select
|
||||
v-model="bannerDesign"
|
||||
@@ -312,7 +566,7 @@ onUnmounted(() => {
|
||||
class="icon-btn"
|
||||
title="upload banner image/video (replaces existing media) — pasting works too"
|
||||
@click="fileInput.click()"
|
||||
>🖼️</button>
|
||||
>🖼︎</button>
|
||||
<input
|
||||
ref="fileInput"
|
||||
type="file"
|
||||
@@ -341,10 +595,61 @@ onUnmounted(() => {
|
||||
gap: 0.4rem;
|
||||
padding: 0.5rem 1rem;
|
||||
background: var(--surface);
|
||||
}
|
||||
|
||||
.banner-block {
|
||||
flex: 1;
|
||||
min-height: 0;
|
||||
}
|
||||
|
||||
/* The card-image section: a real preview of the effective image (the
|
||||
node's own or the inherited one, dimmed then), with upload/clear in the
|
||||
head row like the banner media button. */
|
||||
.card-image {
|
||||
flex: 0 0 auto;
|
||||
border-bottom: 1px solid var(--line);
|
||||
}
|
||||
|
||||
.block-label {
|
||||
color: var(--muted);
|
||||
font-size: 0.8rem;
|
||||
}
|
||||
|
||||
/* The site's own card previews: real .card markup/styles from pagerite.css,
|
||||
scaled down via font-size (the card internals are all em, so the layout
|
||||
proportions match the real cards exactly). They double as the card-mode
|
||||
selector: thin outlines only (no border changes, so selecting never
|
||||
shifts the layout) — solid accent for a forced mode, dashed muted for
|
||||
the mode "automatic" currently resolves to (approximated from image
|
||||
presence). */
|
||||
.site-previews {
|
||||
display: flex;
|
||||
gap: 0.8rem;
|
||||
align-items: flex-start;
|
||||
flex-wrap: wrap;
|
||||
margin-top: 0.8rem;
|
||||
}
|
||||
|
||||
.site-previews .card.preview {
|
||||
font: inherit;
|
||||
font-size: 0.67rem;
|
||||
width: 24em;
|
||||
max-width: 100%;
|
||||
padding: 0;
|
||||
text-align: start;
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.site-previews .card.preview.selected {
|
||||
outline: 1px solid var(--accent);
|
||||
outline-offset: 2px;
|
||||
}
|
||||
|
||||
.site-previews .card.preview.auto:not(.selected) {
|
||||
outline: 1px dashed var(--muted);
|
||||
outline-offset: 2px;
|
||||
}
|
||||
|
||||
.block-head {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
@@ -357,17 +662,22 @@ onUnmounted(() => {
|
||||
}
|
||||
|
||||
.block-head .icon-btn {
|
||||
margin-left: auto;
|
||||
padding: 0 0.2rem;
|
||||
font-size: 1rem;
|
||||
background: none;
|
||||
border: none;
|
||||
cursor: pointer;
|
||||
opacity: 0.7;
|
||||
}
|
||||
|
||||
.block-head .icon-btn:hover {
|
||||
opacity: 1;
|
||||
/* The "use site icon" button shows the icon itself. */
|
||||
.favicon-btn img {
|
||||
display: block;
|
||||
width: 1rem;
|
||||
height: 1rem;
|
||||
object-fit: contain;
|
||||
}
|
||||
|
||||
/* The first icon button pushes itself (and any siblings after it, like
|
||||
the card-image clear button) to the end of the row. */
|
||||
.block-head .icon-btn:first-of-type {
|
||||
margin-left: auto;
|
||||
}
|
||||
|
||||
/* The banner design selector stays compact; the upload button is pushed
|
||||
|
||||
@@ -0,0 +1,21 @@
|
||||
<script setup>
|
||||
// Connection-state note for the WebSocket-backed panels (page/banner
|
||||
// editors, analytics view): while the socket is connecting or waiting to
|
||||
// reconnect the panel cannot load or save, and this says so. An empty
|
||||
// text hides the note.
|
||||
defineProps({ text: { type: String, default: '' } })
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<div v-if="text" class="conn-note" role="status">{{ text }}</div>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
.conn-note {
|
||||
padding: 0.2rem 1rem;
|
||||
border-bottom: 1px solid var(--line);
|
||||
background: var(--surface);
|
||||
color: var(--muted);
|
||||
font-size: 0.8rem;
|
||||
}
|
||||
</style>
|
||||
@@ -1,5 +1,5 @@
|
||||
<script setup>
|
||||
// Tabbed shell for the four admin editors. The individual pens are shorthands
|
||||
// Tabbed shell for the five admin editors. The individual pens are shorthands
|
||||
// that open the shell on a given tab; once open, tabs switch instantly without
|
||||
// closing the panel. Tabs are kept alive so switching preserves state.
|
||||
import { onMounted, onUnmounted, provide, ref, watch } from 'vue'
|
||||
@@ -7,6 +7,10 @@ import PageEditor from './PageEditor.vue'
|
||||
import BannerEditor from './BannerEditor.vue'
|
||||
import SiteEditor from './SiteEditor.vue'
|
||||
import StructureEditor from './StructureEditor.vue'
|
||||
import LocalizationEditor from './LocalizationEditor.vue'
|
||||
import { editorLang, pagePrimary } from './editorLang'
|
||||
import { loadPlain, setLangOverride } from './swapdoc'
|
||||
import { apiJson } from 'paskia'
|
||||
|
||||
const props = defineProps({
|
||||
pagePath: { type: String, default: '' },
|
||||
@@ -17,11 +21,48 @@ const emit = defineEmits(['close'])
|
||||
const currentPath = ref(props.pagePath)
|
||||
const activeMode = ref(props.initialMode)
|
||||
|
||||
// Tab order: site-wide settings first (site, structure), then — after a
|
||||
// visual break — the per-page editors (article, banner).
|
||||
// The shared language selection (./editorLang, v-modeled by the tabs'
|
||||
// LangSelects) is linked to the whole-page language: while the shell is
|
||||
// open it drives the page preview (overrides ?lang= / Accept-Language),
|
||||
// and closing keeps the pick as the session language. The primary
|
||||
// selection pins by the CURRENT PAGE's own primary language (pages may
|
||||
// differ — Node.language is inherited down the tree).
|
||||
let pinned = false
|
||||
function pinPreviewLang() {
|
||||
pinned = true
|
||||
// '' pagePrimary = not yet learned: pin 'en', the server's final fallback
|
||||
// (i18n.ORIGINAL_LANGUAGE).
|
||||
setLangOverride(editorLang.value || pagePrimary.value || 'en')
|
||||
loadPlain(currentPath.value)
|
||||
}
|
||||
// Opening the panel must not switch the page's language: adopt the
|
||||
// session's chosen language (public selector / earlier pick) once, then
|
||||
// pin. Runs only on (re)open — after that the selection is the user's.
|
||||
function openShell() {
|
||||
const session = window.__pageriteLang
|
||||
if (!editorLang.value && session && session !== (pagePrimary.value || 'en'))
|
||||
editorLang.value = session
|
||||
pinPreviewLang()
|
||||
}
|
||||
function unpinPreviewLang(ev) {
|
||||
if (!pinned) return
|
||||
pinned = false
|
||||
setLangOverride(null)
|
||||
// A close caused by navigation (to /_a) must not re-render the page the
|
||||
// editor was on: the navigation itself is swapping in the target page.
|
||||
if (!ev?.detail?.navigating) loadPlain(currentPath.value)
|
||||
}
|
||||
watch(editorLang, () => { if (pinned) pinPreviewLang() })
|
||||
// The page's primary may be (re)learned while pinned on it (doc accept,
|
||||
// tree refresh, a language change on the row) — re-pin with the new code.
|
||||
watch(pagePrimary, () => { if (pinned && !editorLang.value) pinPreviewLang() })
|
||||
|
||||
// Tab order: site-wide settings first (site, structure, localization), then
|
||||
// — after a visual break — the per-page editors (article, banner).
|
||||
const MODES = [
|
||||
{ key: 'site', label: 'site', component: SiteEditor },
|
||||
{ key: 'structure', label: 'structure', component: StructureEditor },
|
||||
{ key: 'localization', label: 'lang', component: LocalizationEditor },
|
||||
{ key: 'page', label: 'article', component: PageEditor, breakBefore: true },
|
||||
{ key: 'banner', label: 'banner', component: BannerEditor },
|
||||
]
|
||||
@@ -54,25 +95,33 @@ function onSwitchEvent(ev) {
|
||||
// Closing the shell hides it but keeps it mounted (main.js); the tabs stay
|
||||
// cached in KeepAlive the whole time, so no state is ever lost until a real
|
||||
// page reload. On re-show each active tab re-applies its window title and
|
||||
// preview via its own pagerite:editor-shown listener.
|
||||
function onKeydown(ev) {
|
||||
if (ev.key === 'Escape' && document.body.classList.contains('editing')) close()
|
||||
}
|
||||
// preview via its own pagerite:editor-shown listener. No Escape-to-close:
|
||||
// it fired too easily by accident (e.g. dismissing an editor popup).
|
||||
|
||||
onMounted(() => {
|
||||
document.body.dataset.editorMode = activeMode.value
|
||||
addEventListener('pagerite:switch-editor', onSwitchEvent)
|
||||
addEventListener('keydown', onKeydown)
|
||||
addEventListener('pagerite:editor-shown', openShell)
|
||||
addEventListener('pagerite:editor-hidden', unpinPreviewLang)
|
||||
// The shell mounts visible (openEditor), so open immediately. The site
|
||||
// default primary language comes from the settings — it only fills the
|
||||
// unknown; the page/structure tabs refine pagePrimary per page as they
|
||||
// learn it (their knowledge is strictly better).
|
||||
openShell()
|
||||
apiJson('/_api/settings').then((s) => {
|
||||
if (!pagePrimary.value) pagePrimary.value = s.primary_lang || 'en'
|
||||
}).catch(() => { /* keep the fallback */ })
|
||||
})
|
||||
|
||||
onUnmounted(() => {
|
||||
removeEventListener('pagerite:switch-editor', onSwitchEvent)
|
||||
removeEventListener('keydown', onKeydown)
|
||||
removeEventListener('pagerite:editor-shown', openShell)
|
||||
removeEventListener('pagerite:editor-hidden', unpinPreviewLang)
|
||||
})
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<div class="editor-root overlay">
|
||||
<div class="editor-root overlay" lang="en" dir="ltr">
|
||||
<header class="editor-tabs">
|
||||
<template v-for="m in MODES" :key="m.key">
|
||||
<span v-if="m.breakBefore" class="tab-break" />
|
||||
|
||||
@@ -0,0 +1,168 @@
|
||||
<script setup>
|
||||
// The editor shell's one language selector (page + structure tabs): a small
|
||||
// flag button opening a clean dropdown, v-modeled on the shared editorLang
|
||||
// ('' = the primary language). The lang tab's flag grid is a different
|
||||
// control (toggles, not a select) and stays as it is.
|
||||
import { computed, nextTick, ref } from 'vue'
|
||||
import { usePopup } from './dropdown'
|
||||
|
||||
const props = defineProps({
|
||||
modelValue: { type: String, default: '' },
|
||||
options: { type: Array, required: true }, // [{tag, code, name, flag, primary}]
|
||||
title: { type: String, default: '' }, // toggle-button tooltip override
|
||||
})
|
||||
const emit = defineEmits(['update:modelValue'])
|
||||
|
||||
const open = ref(false)
|
||||
const root = ref(null)
|
||||
const toggleBtn = ref(null)
|
||||
const pop = ref(null)
|
||||
const popStyle = ref({})
|
||||
// Closes on outside click / Escape (./dropdown), not on mouseleave.
|
||||
usePopup(open, root)
|
||||
const current = computed(
|
||||
() => props.options.find((o) => o.tag === props.modelValue) ?? props.options[0],
|
||||
)
|
||||
|
||||
function toggle() {
|
||||
open.value = !open.value
|
||||
if (open.value) {
|
||||
// Position: fixed so the popup overflows the scrolling editor panel
|
||||
// onto the page area instead of being clipped by it.
|
||||
const r = toggleBtn.value.getBoundingClientRect()
|
||||
popStyle.value = { top: `${r.bottom + 2}px`, left: `${r.left}px` }
|
||||
// A toggle mounted near the right window edge (the public page
|
||||
// selector sits top-right) opens the popup flush against that edge.
|
||||
nextTick(() => {
|
||||
const p = pop.value?.getBoundingClientRect()
|
||||
if (p && p.right > innerWidth - 4) {
|
||||
popStyle.value = {
|
||||
...popStyle.value,
|
||||
left: `${Math.max(4, innerWidth - 4 - p.width)}px`,
|
||||
}
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
function select(tag) {
|
||||
emit('update:modelValue', tag)
|
||||
open.value = false
|
||||
}
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<span v-if="options.length > 1" ref="root" class="lang-select">
|
||||
<button
|
||||
ref="toggleBtn"
|
||||
type="button"
|
||||
class="lang-current"
|
||||
:class="{ open }"
|
||||
:title="title || (current
|
||||
? `language: ${current.name}${current.primary ? ' (primary)' : ''}`
|
||||
: '')"
|
||||
@click="toggle"
|
||||
><span v-if="current?.flag" class="flag" v-html="current.flag" /></button>
|
||||
<span v-if="open" ref="pop" class="lang-pop" :style="popStyle">
|
||||
<button
|
||||
v-for="o in options"
|
||||
:key="o.code"
|
||||
type="button"
|
||||
:class="{ active: o.tag === modelValue }"
|
||||
:title="o.primary ? `${o.name} — the primary language` : `${o.name} — translation`"
|
||||
@click="select(o.tag)"
|
||||
><span v-if="o.flag" class="flag" v-html="o.flag" /> {{ o.name }}<small v-if="o.primary"> (primary)</small></button>
|
||||
</span>
|
||||
</span>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
.lang-select {
|
||||
position: relative;
|
||||
display: flex;
|
||||
}
|
||||
|
||||
/* The closed state is just the small flag — no button chrome at all, on
|
||||
hover either (it sits among borderless emoji-icon buttons); like them it
|
||||
rests dimmed and brightens on hover. */
|
||||
.lang-current {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
padding: 2px;
|
||||
background: none;
|
||||
border: none;
|
||||
border-radius: 4px;
|
||||
cursor: pointer;
|
||||
opacity: 0.7;
|
||||
}
|
||||
|
||||
.lang-current:hover,
|
||||
.lang-current.open {
|
||||
opacity: 1;
|
||||
}
|
||||
|
||||
/* The dropdown matches the page's existing popups (.picker-pop look).
|
||||
Fixed-positioned (anchored to the toggle's viewport rect on open) so it
|
||||
is not clipped by the editor panel's scrolling overflow. */
|
||||
.lang-pop {
|
||||
position: fixed;
|
||||
z-index: 20;
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
align-items: stretch;
|
||||
gap: 0.15rem;
|
||||
padding: 0.3rem;
|
||||
background: var(--bg);
|
||||
border: 1px solid var(--line);
|
||||
border-radius: 6px;
|
||||
box-shadow: 0 4px 16px #0004;
|
||||
white-space: nowrap;
|
||||
}
|
||||
|
||||
.lang-pop button {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 0.4rem;
|
||||
padding: 0.15rem 0.4rem;
|
||||
font: inherit;
|
||||
font-size: 0.9rem;
|
||||
text-align: left;
|
||||
color: var(--text);
|
||||
background: none;
|
||||
border: none;
|
||||
border-radius: 4px;
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.lang-pop button:hover {
|
||||
background: var(--surface);
|
||||
}
|
||||
|
||||
.lang-pop button.active {
|
||||
color: var(--accent);
|
||||
}
|
||||
|
||||
.lang-pop small {
|
||||
color: var(--muted);
|
||||
}
|
||||
|
||||
/* em-sized so the chip matches the surrounding text/icon size in each
|
||||
context; the hairline border delineates white-flagged countries (not
|
||||
button chrome). */
|
||||
.flag {
|
||||
display: inline-flex;
|
||||
width: 1.5em;
|
||||
height: 1em;
|
||||
flex: 0 0 auto;
|
||||
border-radius: 2px;
|
||||
overflow: hidden;
|
||||
border: 1px solid var(--line);
|
||||
box-shadow: 0 0 0 1px rgba(0, 0, 0, 0.2) inset;
|
||||
}
|
||||
|
||||
.flag :deep(svg) {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
display: block;
|
||||
}
|
||||
</style>
|
||||
@@ -0,0 +1,46 @@
|
||||
<script setup>
|
||||
// The public page's language selector: the editors' flag dropdown
|
||||
// (LangSelect) as the first item of the banner's corner container, fed
|
||||
// from the shared store (pagerite.js sets the page's hreflang alternates
|
||||
// and served language per navigation). It binds the same store.lang the
|
||||
// editor's dropdown binds, so both always show the same selection. A pick
|
||||
// also dispatches pagerite:set-session-lang — pagerite.js swaps the page
|
||||
// in place when the editor is closed (open, the editor reacts to the
|
||||
// store and re-renders it).
|
||||
import { computed } from 'vue'
|
||||
import LangSelect from './LangSelect.vue'
|
||||
import { flagFor, langName, langSort } from './langs'
|
||||
import { useStore } from './store'
|
||||
|
||||
const store = useStore()
|
||||
|
||||
// The "(primary)" marker is admin-panel information; the public selector
|
||||
// lists plain languages. Order: the primary language first, then the rest
|
||||
// in the lang tab's geographic grouping (./langs langSort) — the head's
|
||||
// hreflang order is just alphabetical.
|
||||
const primaryTag = computed(() => store.langAlternates.find((a) => a.primary)?.tag ?? '')
|
||||
const options = computed(() => {
|
||||
const rest = langSort(
|
||||
store.langAlternates.map((a) => a.tag).filter((t) => t !== primaryTag.value),
|
||||
)
|
||||
return [primaryTag.value, ...rest].filter(Boolean).map((tag) => ({
|
||||
tag,
|
||||
code: tag,
|
||||
name: langName(tag),
|
||||
flag: flagFor(tag),
|
||||
primary: false,
|
||||
}))
|
||||
})
|
||||
// The explicit pick, else the served language (header-autodetected pages
|
||||
// may have neither), else the primary.
|
||||
const model = computed(() => store.lang || store.servedLang || primaryTag.value)
|
||||
|
||||
function go(tag) {
|
||||
store.lang = tag === primaryTag.value ? '' : tag
|
||||
dispatchEvent(new CustomEvent('pagerite:set-session-lang', { detail: { lang: tag } }))
|
||||
}
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<LangSelect :model-value="model" :options="options" @update:model-value="go" />
|
||||
</template>
|
||||
@@ -0,0 +1,411 @@
|
||||
<script setup>
|
||||
// Lang tab: the site-wide translation target languages (translate_langs)
|
||||
// and the translator service keys (translate_keys) with their WebSocket
|
||||
// URLs. ALL languages are listed, English included — a page whose primary
|
||||
// language (Node.language, configured per row in the structure tab,
|
||||
// inherited down the hierarchy) differs can be translated INTO any other.
|
||||
// Flag clicks toggle and save immediately; the settings round-trip
|
||||
// re-reads the payload, so this tab only ever changes translate_langs. The
|
||||
// settings write's invalidation hook kicks the translation dispatcher. The
|
||||
// refresh button drops all machine translations (user overrides are kept),
|
||||
// making the dispatcher re-translate everything. Translator keys are
|
||||
// managed inline (➕ add, name edit, ✕ delete); new keys are generated
|
||||
// here in the server's format and everything rides the settings
|
||||
// round-trip. Clicking a key copies its full URL (following ws:// would
|
||||
// fail).
|
||||
import { computed, onActivated, onMounted, onUnmounted, ref } from 'vue'
|
||||
import { LANG_GROUPS, TRANSLATABLE, flagFor, langName } from './langs'
|
||||
import { copyList } from './analytics/format.js'
|
||||
import { dropPageCache } from './swapdoc'
|
||||
import { apiFetch, apiJson } from 'paskia'
|
||||
|
||||
defineProps({ pagePath: { type: String, default: '' } })
|
||||
// close/path-change are wired by EditorShell; this tab never emits them.
|
||||
defineEmits(['close', 'pathChange'])
|
||||
|
||||
const saveError = ref('')
|
||||
const selected = ref(new Set())
|
||||
const keyUrls = ref([])
|
||||
|
||||
// Full WebSocket URL for a key. New keys are generated right here: 12
|
||||
// lowercase alphanumerics, the server-side format (state._KEY_ALPHABET).
|
||||
const wsUrl = (key) =>
|
||||
`${location.origin.replace(/^http/, 'ws')}/_translate/${key}`
|
||||
const KEY_ALPHABET = 'abcdefghijklmnopqrstuvwxyz0123456789'
|
||||
const newKey = () =>
|
||||
[...crypto.getRandomValues(new Uint8Array(12))]
|
||||
.map((b) => KEY_ALPHABET[b % KEY_ALPHABET.length])
|
||||
.join('')
|
||||
|
||||
// The toggleable targets: every translatable language, laid out in
|
||||
// geographic/cultural groups (one row each) rather than alphabetized —
|
||||
// related languages sit together (a node's own primary is excluded per
|
||||
// article, server-side). Any code missing from LANG_GROUPS trails as an
|
||||
// extra row.
|
||||
const groups = computed(() => {
|
||||
const tile = (code) => ({ code, name: langName(code), flag: flagFor(code) })
|
||||
const rows = LANG_GROUPS.map((g) => g.filter((c) => c in TRANSLATABLE).map(tile))
|
||||
const covered = new Set(LANG_GROUPS.flat())
|
||||
const rest = Object.keys(TRANSLATABLE).filter((c) => !covered.has(c)).map(tile)
|
||||
if (rest.length) rows.push(rest)
|
||||
return rows.filter((r) => r.length)
|
||||
})
|
||||
|
||||
function updateWindowTitle() {
|
||||
document.title = 'lang 🖊️'
|
||||
}
|
||||
|
||||
onActivated(updateWindowTitle)
|
||||
|
||||
// The shell stays mounted while hidden: when it is re-shown with this tab
|
||||
// active, restore the window title.
|
||||
function onEditorShown() {
|
||||
if (document.body.dataset.editorMode === 'localization') updateWindowTitle()
|
||||
}
|
||||
|
||||
onMounted(async () => {
|
||||
addEventListener('pagerite:editor-shown', onEditorShown)
|
||||
try {
|
||||
const s = await apiJson('/_api/settings')
|
||||
selected.value = new Set(s.translate_langs || [])
|
||||
keyUrls.value = Object.entries(s.translate_keys || {})
|
||||
.map(([key, name]) => ({ key, name, url: wsUrl(key) }))
|
||||
} catch { /* keep defaults */ }
|
||||
})
|
||||
|
||||
onUnmounted(() => removeEventListener('pagerite:editor-shown', onEditorShown))
|
||||
|
||||
async function toggle(code) {
|
||||
const next = new Set(selected.value)
|
||||
if (next.has(code)) next.delete(code)
|
||||
else next.add(code)
|
||||
selected.value = next
|
||||
try {
|
||||
const s = await apiJson('/_api/settings')
|
||||
const res = await apiFetch('/_api/settings', {
|
||||
method: 'PUT',
|
||||
headers: { 'content-type': 'application/json' },
|
||||
body: JSON.stringify({ ...s, translate_langs: [...next] }),
|
||||
})
|
||||
if (res.ok) {
|
||||
saveError.value = ''
|
||||
dropPageCache()
|
||||
} else {
|
||||
saveError.value = '⚠️ changes could not be saved'
|
||||
}
|
||||
} catch {
|
||||
saveError.value = '⚠️ changes could not be saved'
|
||||
}
|
||||
}
|
||||
|
||||
// Delete all machine translations server-side; the dispatcher re-fills
|
||||
// them (a connected translator starts getting jobs right away). User
|
||||
// overrides survive — they are edits, not machine output.
|
||||
const refreshing = ref(false)
|
||||
async function refresh() {
|
||||
if (refreshing.value) return
|
||||
refreshing.value = true
|
||||
try {
|
||||
const res = await apiFetch('/_api/translations', { method: 'DELETE' })
|
||||
saveError.value = res.ok ? '' : '⚠️ translations could not be refreshed'
|
||||
if (res.ok) dropPageCache()
|
||||
} catch {
|
||||
saveError.value = '⚠️ translations could not be refreshed'
|
||||
} finally {
|
||||
refreshing.value = false
|
||||
}
|
||||
}
|
||||
|
||||
// Key management rides the settings round-trip, like toggle() above:
|
||||
// mutate keyUrls, then PUT the whole settings payload with the new
|
||||
// translate_keys. ➕ adds a fresh unnamed key, names save on every
|
||||
// keystroke (@input — spamming the server is fine), ✕ deletes without
|
||||
// confirmation.
|
||||
async function saveKeys() {
|
||||
try {
|
||||
const s = await apiJson('/_api/settings')
|
||||
const res = await apiFetch('/_api/settings', {
|
||||
method: 'PUT',
|
||||
headers: { 'content-type': 'application/json' },
|
||||
body: JSON.stringify({
|
||||
...s,
|
||||
translate_keys: Object.fromEntries(keyUrls.value.map((k) => [k.key, k.name])),
|
||||
}),
|
||||
})
|
||||
saveError.value = res.ok ? '' : '⚠️ changes could not be saved'
|
||||
} catch {
|
||||
saveError.value = '⚠️ changes could not be saved'
|
||||
}
|
||||
}
|
||||
|
||||
function addKey() {
|
||||
const key = newKey()
|
||||
keyUrls.value.push({ key, name: '', url: wsUrl(key) })
|
||||
saveKeys()
|
||||
}
|
||||
|
||||
function removeKey(k) {
|
||||
keyUrls.value = keyUrls.value.filter((x) => x.key !== k.key)
|
||||
saveKeys()
|
||||
}
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<div class="localization-editor">
|
||||
<div v-if="saveError">{{ saveError }}</div>
|
||||
|
||||
<section class="block">
|
||||
<div class="block-head">
|
||||
<span class="field-label">languages</span>
|
||||
</div>
|
||||
<div class="flags">
|
||||
<div v-for="(row, ri) in groups" :key="ri" class="flag-row">
|
||||
<button
|
||||
v-for="o in row"
|
||||
:key="o.code"
|
||||
type="button"
|
||||
class="flag-tile"
|
||||
:class="{ selected: selected.has(o.code) }"
|
||||
:title="`${o.name} (${o.code})`"
|
||||
@click="toggle(o.code)"
|
||||
>
|
||||
<span class="flag" v-html="o.flag" />
|
||||
</button>
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section class="block">
|
||||
<div class="block-head">
|
||||
<span class="field-label">Translator API</span>
|
||||
</div>
|
||||
<div v-for="k in keyUrls" :key="k.key" class="key-row">
|
||||
<a
|
||||
:href="k.url"
|
||||
class="key-link"
|
||||
title="click to copy the URL"
|
||||
@click.prevent="copyList(k.url, $event)"
|
||||
>{{ k.key }}</a>
|
||||
<input
|
||||
v-model="k.name"
|
||||
type="text"
|
||||
class="edit key-name"
|
||||
title="display name"
|
||||
@input="saveKeys()"
|
||||
>
|
||||
<button type="button" class="act del" title="delete key" @click="removeKey(k)">✕</button>
|
||||
</div>
|
||||
<div class="add-row">
|
||||
<button type="button" class="add" title="new translator key" @click="addKey()">➕ API key</button>
|
||||
</div>
|
||||
<p><small class="muted">AI translator agents can connect with the API keys to do machine translations to your selected languages. Click the button below to delete all translations and start over. User edits are kept.</small></p>
|
||||
<div class="refresh-row">
|
||||
<button
|
||||
type="button"
|
||||
class="refresh-btn"
|
||||
:disabled="refreshing"
|
||||
@click="refresh"
|
||||
>
|
||||
{{ refreshing ? 'Reseting…' : 'Reset' }}
|
||||
</button>
|
||||
</div>
|
||||
</section>
|
||||
</div>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
.localization-editor {
|
||||
overflow-y: auto;
|
||||
background: var(--surface);
|
||||
}
|
||||
|
||||
.block {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: 0.4rem;
|
||||
padding: 0.5rem 1rem;
|
||||
border-bottom: 1px solid var(--line);
|
||||
background: var(--surface);
|
||||
}
|
||||
|
||||
.block-head {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 0.6rem;
|
||||
}
|
||||
|
||||
.field-label {
|
||||
color: var(--muted);
|
||||
font-size: 0.85rem;
|
||||
}
|
||||
|
||||
.muted {
|
||||
color: var(--muted);
|
||||
}
|
||||
|
||||
/* Flag grid: one geographic group per row. Deselected flags sit dimmed and
|
||||
grayed; a click brings one to full color (selected = a translation
|
||||
target) — the shading alone carries the state, no outline. */
|
||||
.flags {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: 0.4rem;
|
||||
padding: 0.2rem 0;
|
||||
}
|
||||
|
||||
.flag-row {
|
||||
display: flex;
|
||||
flex-wrap: wrap;
|
||||
gap: 0.5rem;
|
||||
}
|
||||
|
||||
.flag-tile {
|
||||
padding: 3px;
|
||||
background: none;
|
||||
border: 2px solid transparent;
|
||||
border-radius: 5px;
|
||||
cursor: pointer;
|
||||
opacity: 0.4;
|
||||
filter: grayscale(0.8);
|
||||
transition: opacity 0.15s, filter 0.15s, border-color 0.15s;
|
||||
}
|
||||
|
||||
.flag-tile:hover {
|
||||
opacity: 0.8;
|
||||
filter: none;
|
||||
}
|
||||
|
||||
.flag-tile.selected {
|
||||
opacity: 1;
|
||||
filter: none;
|
||||
}
|
||||
|
||||
/* Same flag chips as the PageEditor language picker / analytics cells. */
|
||||
.flag {
|
||||
display: inline-flex;
|
||||
width: 18px;
|
||||
height: 12px;
|
||||
flex: 0 0 auto;
|
||||
border-radius: 2px;
|
||||
overflow: hidden;
|
||||
border: 1px solid var(--line);
|
||||
box-shadow: 0 0 0 1px rgba(0, 0, 0, 0.2) inset;
|
||||
}
|
||||
|
||||
.flag-tile .flag {
|
||||
width: 36px;
|
||||
height: 24px;
|
||||
}
|
||||
|
||||
.flag :deep(svg) {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
display: block;
|
||||
}
|
||||
|
||||
.key-row {
|
||||
display: flex;
|
||||
align-items: baseline;
|
||||
gap: 0.6rem;
|
||||
}
|
||||
|
||||
/* Real links (handy for right-click/drag) showing just the key, but the
|
||||
click copies the full URL instead of following — ws:// would fail to
|
||||
navigate. Normal text color, not link-styled; position: relative
|
||||
anchors the "Copied!" popup (analytics/format.js). */
|
||||
.key-link {
|
||||
position: relative;
|
||||
color: var(--text);
|
||||
font-family: var(--font-code);
|
||||
user-select: all;
|
||||
}
|
||||
|
||||
.refresh-row {
|
||||
display: flex;
|
||||
align-items: baseline;
|
||||
gap: 0.6rem;
|
||||
}
|
||||
|
||||
/* Name input / ✕ / ➕ follow the structure tab's conventions: inputs stay
|
||||
borderless until interacted with, glyph buttons redden / solidify on
|
||||
hover. */
|
||||
.key-name {
|
||||
flex: 0 0 9rem;
|
||||
}
|
||||
|
||||
.edit {
|
||||
font: inherit;
|
||||
font-size: 0.85rem;
|
||||
padding: 0.1rem 0.4rem;
|
||||
background: transparent;
|
||||
color: var(--text);
|
||||
border: 1px solid transparent;
|
||||
border-radius: 4px;
|
||||
min-width: 0;
|
||||
}
|
||||
|
||||
.edit:hover {
|
||||
border-color: var(--line);
|
||||
}
|
||||
|
||||
.edit:focus {
|
||||
background: var(--bg);
|
||||
border-color: var(--accent);
|
||||
outline: none;
|
||||
}
|
||||
|
||||
.act {
|
||||
padding: 0 0.25rem;
|
||||
background: none;
|
||||
border: none;
|
||||
color: var(--muted);
|
||||
font-size: 0.8rem;
|
||||
cursor: pointer;
|
||||
white-space: nowrap;
|
||||
}
|
||||
|
||||
.del:hover {
|
||||
color: #e06c75;
|
||||
}
|
||||
|
||||
.add-row {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
}
|
||||
|
||||
.add {
|
||||
padding: 0 0.3rem;
|
||||
background: none;
|
||||
border: none;
|
||||
font-size: 0.9rem;
|
||||
cursor: pointer;
|
||||
opacity: 0.5;
|
||||
}
|
||||
|
||||
.add:hover {
|
||||
opacity: 1;
|
||||
}
|
||||
|
||||
.refresh-btn {
|
||||
align-self: flex-start;
|
||||
margin-bottom: 0.2rem;
|
||||
padding: 0.3rem 0.8rem;
|
||||
font: inherit;
|
||||
font-size: 0.85rem;
|
||||
color: var(--muted);
|
||||
background: none;
|
||||
border: 1px solid var(--line);
|
||||
border-radius: 5px;
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.refresh-btn:hover:not(:disabled) {
|
||||
color: var(--text);
|
||||
border-color: var(--muted);
|
||||
}
|
||||
|
||||
.refresh-btn:disabled {
|
||||
opacity: 0.5;
|
||||
cursor: default;
|
||||
}
|
||||
</style>
|
||||
@@ -0,0 +1,113 @@
|
||||
<script setup>
|
||||
// Referer + UTM as one badge in the analytics visit/crawler tables: the
|
||||
// referer's favicon flush on the left, its host as the link text, then the
|
||||
// UTM summary smaller/muted inside the same badge. Only the favicon and
|
||||
// host are the link (external, new tab) — everything else, padding and
|
||||
// UTM text included, copies the full utm tag list to the clipboard. The
|
||||
// link is display: contents so its parts lay out as badge flex items.
|
||||
// The badge carries a single one-fact-per-line tooltip (badge.title:
|
||||
// origin, then each utm pair) — no titles on the inner elements.
|
||||
// Referers are external, so there is no close event.
|
||||
import { computed } from 'vue'
|
||||
import { copyList } from './analytics/format.js'
|
||||
|
||||
const props = defineProps({
|
||||
badge: { type: Object, required: true },
|
||||
favicons: { type: Object, default: null },
|
||||
})
|
||||
|
||||
const favicon = computed(() => (props.badge.origin ? props.favicons?.[props.badge.origin] : null))
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<span class="referer-badge"
|
||||
:class="{ 'with-icon': favicon, copyable: badge.utm }"
|
||||
:title="badge.title"
|
||||
@click="badge.utm && copyList(badge.utmCopy, $event)">
|
||||
<a v-if="badge.href" class="badge-link" :href="badge.href"
|
||||
target="_blank" rel="noopener" @click.stop>
|
||||
<img v-if="favicon" class="badge-favicon" :src="favicon" alt="" />
|
||||
<span v-if="badge.label">{{ badge.label }}</span>
|
||||
</a>
|
||||
<template v-else>
|
||||
<img v-if="favicon" class="badge-favicon" :src="favicon" alt="" />
|
||||
<span v-if="badge.label">{{ badge.label }}</span>
|
||||
</template>
|
||||
<small v-if="badge.utm" class="small">{{ badge.utm }}</small>
|
||||
</span>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
/* Browser-chrome chip on a translucent neutral wash (--badge-* in
|
||||
pagerite.css, deliberately unthemed): black-on-transparent and
|
||||
white-on-transparent favicons both stay legible on it. Colors go on the
|
||||
inner elements, so the theme's link color rules cannot cascade in. The
|
||||
padding is matched by negative margins so the chip's content stays
|
||||
exactly where the bare text would sit without the badge — except on the
|
||||
right, which keeps a small positive margin so the next trail item does
|
||||
not abut the chip. */
|
||||
.referer-badge {
|
||||
position: relative;
|
||||
display: inline-flex;
|
||||
align-items: center;
|
||||
gap: 0.35em;
|
||||
/* Fixed line-height: the bar height is then exactly 1.2em + padding =
|
||||
1.6em, so the icon below can be sized to match precisely (an
|
||||
absolutely positioned replaced element cannot derive its height from
|
||||
top/bottom offsets — its aspect ratio wins and bottom is dropped). */
|
||||
line-height: 1.2;
|
||||
padding: 0.2em 0.5em;
|
||||
margin: -0.2em 0.25em -0.2em -0.2em;
|
||||
/* Fully rounded: the bar is exactly 1.6em tall, so a 0.8em radius makes
|
||||
both ends semicircles — a pill, with a full circle around the favicon
|
||||
on the left. */
|
||||
border-radius: 0.8em;
|
||||
background: var(--badge-bg);
|
||||
color: var(--badge-text);
|
||||
white-space: nowrap;
|
||||
}
|
||||
|
||||
/* Room for the absolutely positioned icon (its 1.6em width plus the gap). */
|
||||
.referer-badge.with-icon {
|
||||
padding-left: 1.95em;
|
||||
}
|
||||
|
||||
/* Exactly the bar's height (1.6em, see line-height above), flush to the
|
||||
top/left/bottom borders. The badge does not clip it (no overflow:
|
||||
hidden): the icon may stick out past the bar's rounded corners.
|
||||
Absolute on purpose: an in-flow image is the flex
|
||||
container's first item and would supply the badge's baseline (an image's
|
||||
baseline is its bottom edge), pushing the badge text above the baseline
|
||||
of the trail items that follow. Out of flow, the badge's baseline comes
|
||||
from its text, so baselines match. */
|
||||
.badge-favicon {
|
||||
position: absolute;
|
||||
top: 0;
|
||||
left: 0;
|
||||
width: 1.6em;
|
||||
height: 1.6em;
|
||||
object-fit: cover;
|
||||
}
|
||||
|
||||
/* The link is display: contents: the favicon and label lay out as flex
|
||||
items of the badge itself, and only their actual boxes are clickable. */
|
||||
.badge-link {
|
||||
display: contents;
|
||||
}
|
||||
|
||||
/* Click-to-copy affordance on everything outside the link (the UTM text
|
||||
and the surrounding padding). */
|
||||
.referer-badge.copyable {
|
||||
cursor: pointer;
|
||||
}
|
||||
|
||||
.referer-badge span,
|
||||
.referer-badge small {
|
||||
min-width: 0;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
}
|
||||
|
||||
.referer-badge span { color: var(--badge-text); }
|
||||
.referer-badge small { color: var(--badge-muted); }
|
||||
</style>
|
||||
@@ -5,10 +5,13 @@
|
||||
import { computed, onActivated, onMounted, onUnmounted, ref, watch } from 'vue'
|
||||
import { EditorView, basicSetup } from 'codemirror'
|
||||
import { EditorState } from '@codemirror/state'
|
||||
import { keymap } from '@codemirror/view'
|
||||
import { indentWithTab } from '@codemirror/commands'
|
||||
import { css } from '@codemirror/lang-css'
|
||||
import { html } from '@codemirror/lang-html'
|
||||
import { cmHighlight, cmTheme } from './cmtheme'
|
||||
import { loadPlain, runScripts } from './swapdoc'
|
||||
import { dropPageCache, loadPlain, runScripts } from './swapdoc'
|
||||
import { apiFetch, apiJson } from 'paskia'
|
||||
|
||||
const props = defineProps({
|
||||
pagePath: { type: String, default: '' },
|
||||
@@ -56,11 +59,22 @@ const brand = ref('')
|
||||
const theme = ref('')
|
||||
// Theme options come from the backend (theme folders on disk, see GET
|
||||
// /_api/settings), so added themes need no frontend changes.
|
||||
const themeOptions = ref([{ value: '', label: 'none' }])
|
||||
const themeOptions = ref([{ value: '', label: '☀️ none' }])
|
||||
// Page transition (cube, crossfade, ...): a design folder with
|
||||
// transition.css under pagerite/themes/, injected as #pagerite-transition.
|
||||
const transition = ref('cube')
|
||||
const transitionOptions = ref([])
|
||||
|
||||
// Mode icons match the ones used in the Paskia auth frontend.
|
||||
const MODE_ICONS = { light: '☀️', dark: '🌙', both: '🌓' }
|
||||
|
||||
function themeLabel(t) {
|
||||
return `${MODE_ICONS[t.mode] || MODE_ICONS.light} ${t.name}`
|
||||
}
|
||||
|
||||
async function loadSettings() {
|
||||
try {
|
||||
const s = await (await fetch('/_api/settings')).json()
|
||||
const s = await apiJson('/_api/settings')
|
||||
brand.value = s.brand
|
||||
brandHtml.value = s.brand_html || ''
|
||||
setBrandDocument(brandHtml.value)
|
||||
@@ -69,8 +83,18 @@ async function loadSettings() {
|
||||
customCss.value = s.custom_css || ''
|
||||
favicon.value = s.favicon || ''
|
||||
themeOptions.value = [
|
||||
{ value: '', label: 'none' },
|
||||
...(s.themes || []).map((t) => ({ value: t, label: t })),
|
||||
{ value: '', label: `${MODE_ICONS.light} none` },
|
||||
...(s.themes || []).map((t) => ({ value: t.name, label: themeLabel(t) })),
|
||||
]
|
||||
transition.value = s.transition || 'cube'
|
||||
transitionOptions.value = s.transitions || []
|
||||
fontOptions.value = [
|
||||
...BASE_FONT_OPTIONS,
|
||||
...(s.fonts || []).map((f) => ({
|
||||
value: `var(--font-${f.name})`,
|
||||
label: f.label,
|
||||
serif: f.serif,
|
||||
})),
|
||||
]
|
||||
} catch { /* keep default */ }
|
||||
}
|
||||
@@ -100,7 +124,7 @@ function applyFavicon(url) {
|
||||
|
||||
async function uploadFavicon(file) {
|
||||
if (!file || !file.type.startsWith('image/')) return
|
||||
const res = await fetch('/_api/settings/favicon', {
|
||||
const res = await apiFetch('/_api/settings/favicon', {
|
||||
method: 'PUT',
|
||||
headers: { 'x-filename': file.name.replace(/[^\w.-]/g, '-') },
|
||||
body: file,
|
||||
@@ -110,6 +134,7 @@ async function uploadFavicon(file) {
|
||||
const { path: url } = await res.json()
|
||||
favicon.value = url
|
||||
applyFavicon(url)
|
||||
dropPageCache()
|
||||
} else {
|
||||
saveError.value = `⚠️ ${await errorDetail(res)}`
|
||||
}
|
||||
@@ -174,7 +199,7 @@ function onBrandHtmlInput() {
|
||||
async function uploadBrandMedia(file) {
|
||||
if (!file || !/^(image|video)\//.test(file.type)) return
|
||||
const name = file.name.replace(/[^\w.-]/g, '-')
|
||||
const res = await fetch(`/_api/files/${encodeURIComponent(name)}`, { method: 'PUT', body: file })
|
||||
const res = await apiFetch(`/_api/files/${encodeURIComponent(name)}`, { method: 'PUT', body: file })
|
||||
if (!res.ok) return
|
||||
const { path: stored } = await res.json()
|
||||
const tag = file.type.startsWith('video/')
|
||||
@@ -221,7 +246,7 @@ function onEditorShown() {
|
||||
}
|
||||
|
||||
async function saveSettings(opts = {}) {
|
||||
const res = await fetch('/_api/settings', {
|
||||
const res = await apiFetch('/_api/settings', {
|
||||
method: 'PUT',
|
||||
headers: { 'content-type': 'application/json' },
|
||||
body: JSON.stringify({
|
||||
@@ -229,11 +254,13 @@ async function saveSettings(opts = {}) {
|
||||
theme: theme.value,
|
||||
custom_css: customCss.value,
|
||||
brand_html: brandHtml.value,
|
||||
transition: transition.value,
|
||||
...opts,
|
||||
}),
|
||||
})
|
||||
if (res.ok) {
|
||||
saveError.value = ''
|
||||
dropPageCache()
|
||||
} else {
|
||||
saveError.value = '⚠️ changes could not be saved'
|
||||
}
|
||||
@@ -242,34 +269,78 @@ async function saveSettings(opts = {}) {
|
||||
async function onThemeChange() {
|
||||
await saveSettings()
|
||||
// Theme CSS is backend-served at /_themes/{theme}/theme.css in both dev
|
||||
// and prod: swap the link in place, then re-render (the theme's default
|
||||
// banner design and the page's stylesheet links may change with it).
|
||||
let link = document.getElementById('pagerite-theme')
|
||||
// and prod, but rendered differently: a <link> in dev, an inline <style>
|
||||
// in prod. Swap it in place, then re-render (the theme's default banner
|
||||
// design and the page's stylesheets may change with it).
|
||||
let el = document.getElementById('pagerite-theme')
|
||||
const url = `/_themes/${theme.value}/theme.css`
|
||||
if (theme.value) {
|
||||
const href = `/_themes/${theme.value}/theme.css`
|
||||
if (link) {
|
||||
link.href = href
|
||||
} else {
|
||||
if (el?.tagName === 'STYLE') {
|
||||
el.textContent = await (await apiFetch(url)).text()
|
||||
} else if (el) {
|
||||
el.href = url
|
||||
} else if (import.meta.env.DEV) {
|
||||
// Re-create after "none": keep base < theme < design < custom CSS.
|
||||
// In dev there is no #pagerite-base link (the base is a
|
||||
// In dev there is no #pagerite-base element (the base is a
|
||||
// Vite-injected <style>), so anchor to the next sheet instead of
|
||||
// prepending before the base styles.
|
||||
link = document.createElement('link')
|
||||
link.rel = 'stylesheet'
|
||||
link.id = 'pagerite-theme'
|
||||
link.href = href
|
||||
el = document.createElement('link')
|
||||
el.rel = 'stylesheet'
|
||||
el.id = 'pagerite-theme'
|
||||
el.href = url
|
||||
const before = document.getElementById('pagerite-base')?.nextSibling
|
||||
?? document.getElementById('pagerite-banner')
|
||||
?? document.getElementById('pagerite-user')
|
||||
if (before) before.before(link)
|
||||
else document.head.append(link)
|
||||
if (before) before.before(el)
|
||||
else document.head.append(el)
|
||||
} else {
|
||||
// Prod: inline <style>, fetched from the backend-served URL.
|
||||
el = document.createElement('style')
|
||||
el.id = 'pagerite-theme'
|
||||
el.textContent = await (await apiFetch(url)).text()
|
||||
const before = document.getElementById('pagerite-base')?.nextSibling
|
||||
?? document.getElementById('pagerite-banner')
|
||||
?? document.getElementById('pagerite-user')
|
||||
if (before) before.before(el)
|
||||
else document.head.append(el)
|
||||
}
|
||||
} else if (link) {
|
||||
link.remove()
|
||||
} else if (el) {
|
||||
el.remove()
|
||||
}
|
||||
loadPlain(path.value)
|
||||
}
|
||||
|
||||
async function onTransitionChange() {
|
||||
await saveSettings()
|
||||
// Transition CSS is backend-served at /_themes/{name}/transition.css in
|
||||
// both dev and prod (<link> in dev, inline <style> in prod), like the
|
||||
// theme. Swap #pagerite-transition in place — it only styles view
|
||||
// transitions, so no re-render of the page regions is needed.
|
||||
let el = document.getElementById('pagerite-transition')
|
||||
const url = `/_themes/${transition.value}/transition.css`
|
||||
if (el?.tagName === 'STYLE') {
|
||||
el.textContent = await (await apiFetch(url)).text()
|
||||
} else if (el) {
|
||||
el.href = url
|
||||
} else {
|
||||
// Missing (created before this feature, or "none" saved directly):
|
||||
// re-create, keeping base < theme < design < transition < custom CSS.
|
||||
if (import.meta.env.DEV) {
|
||||
el = document.createElement('link')
|
||||
el.rel = 'stylesheet'
|
||||
el.href = url
|
||||
} else {
|
||||
el = document.createElement('style')
|
||||
el.textContent = await (await apiFetch(url)).text()
|
||||
}
|
||||
el.id = 'pagerite-transition'
|
||||
const before = document.getElementById('pagerite-banner')?.nextSibling
|
||||
?? document.getElementById('pagerite-user')
|
||||
if (before) before.before(el)
|
||||
else document.head.append(el)
|
||||
}
|
||||
}
|
||||
|
||||
// --- Site-wide custom CSS --------------------------------------------------
|
||||
// Edits apply to the live page immediately and save while typing.
|
||||
function applyCustomCss(css) {
|
||||
@@ -314,7 +385,7 @@ function setCssDocument(text) {
|
||||
// inline with other content, and those must be stripped/parsed too or
|
||||
// re-picking a font would insert a duplicate row.
|
||||
const FONT_DECL = /--font-(?:body|heading|brand)\s*:\s*var\(--font-[a-z0-9-]+\)\s*;/g
|
||||
const FONT_OPTIONS = [
|
||||
const BASE_FONT_OPTIONS = [
|
||||
{ value: 'var(--font-source-serif)', label: 'Source Serif 4', serif: true },
|
||||
{ value: 'var(--font-fraunces)', label: 'Fraunces', serif: true },
|
||||
{ value: 'var(--font-literata)', label: 'Literata', serif: true },
|
||||
@@ -328,6 +399,10 @@ const FONT_OPTIONS = [
|
||||
{ value: 'var(--font-exo2)', label: 'Exo 2', serif: false },
|
||||
{ value: 'var(--font-fira-code)', label: 'Fira Code', serif: false },
|
||||
]
|
||||
// Built-in options plus user fonts reported by the backend (fonts/
|
||||
// folders on disk, see GET /_api/settings), so added fonts need no
|
||||
// frontend changes.
|
||||
const fontOptions = ref(BASE_FONT_OPTIONS)
|
||||
const fontHeading = ref('')
|
||||
const fontBody = ref('')
|
||||
const fontBrand = ref('')
|
||||
@@ -337,8 +412,8 @@ const fontBrand = ref('')
|
||||
// the candidate font at the size and weight of the element being styled.
|
||||
const fontPicker = ref(null) // open tab: 'heading' | 'body' | 'brand' | null
|
||||
let fontTabLast = 'body'
|
||||
const serifFonts = computed(() => FONT_OPTIONS.filter((o) => o.serif))
|
||||
const sansFonts = computed(() => FONT_OPTIONS.filter((o) => !o.serif))
|
||||
const serifFonts = computed(() => fontOptions.value.filter((o) => o.serif))
|
||||
const sansFonts = computed(() => fontOptions.value.filter((o) => !o.serif))
|
||||
|
||||
function toggleFontPanel() {
|
||||
if (fontPicker.value) {
|
||||
@@ -415,6 +490,8 @@ onMounted(async () => {
|
||||
doc: '',
|
||||
extensions: [
|
||||
basicSetup,
|
||||
// Tab/Shift-Tab indent and dedent instead of moving focus.
|
||||
keymap.of([indentWithTab]),
|
||||
css(),
|
||||
cmTheme,
|
||||
cmHighlight,
|
||||
@@ -434,6 +511,8 @@ onMounted(async () => {
|
||||
doc: '',
|
||||
extensions: [
|
||||
basicSetup,
|
||||
// Tab/Shift-Tab indent and dedent instead of moving focus.
|
||||
keymap.of([indentWithTab]),
|
||||
html(),
|
||||
cmTheme,
|
||||
cmHighlight,
|
||||
@@ -468,6 +547,7 @@ onUnmounted(() => {
|
||||
<div v-if="saveError">{{ saveError }}</div>
|
||||
|
||||
<section class="block">
|
||||
<div class="field-grid">
|
||||
<label class="field">
|
||||
<span class="field-label">site name</span>
|
||||
<input
|
||||
@@ -477,6 +557,25 @@ onUnmounted(() => {
|
||||
@input="onBrandInput"
|
||||
/>
|
||||
</label>
|
||||
<div class="field">
|
||||
<span class="field-label">favicon</span>
|
||||
<button
|
||||
type="button"
|
||||
class="favicon-tile"
|
||||
title="upload favicon (ico, png, svg...)"
|
||||
@click="faviconInput.click()"
|
||||
>
|
||||
<img v-if="favicon" :src="favicon" alt="current favicon" />
|
||||
<span v-else>?</span>
|
||||
</button>
|
||||
<input
|
||||
ref="faviconInput"
|
||||
type="file"
|
||||
accept="image/*"
|
||||
hidden
|
||||
@change="(ev) => { uploadFavicon(ev.target.files[0]); ev.target.value = '' }"
|
||||
/>
|
||||
</div>
|
||||
<div class="field">
|
||||
<span class="field-label">theme</span>
|
||||
<select
|
||||
@@ -499,6 +598,20 @@ onUnmounted(() => {
|
||||
A
|
||||
</button>
|
||||
</div>
|
||||
<label class="field">
|
||||
<span class="field-label">transition</span>
|
||||
<select
|
||||
v-model="transition"
|
||||
class="text-input theme-select"
|
||||
title="Page transition"
|
||||
@change="onTransitionChange"
|
||||
>
|
||||
<option v-for="t in transitionOptions" :key="t" :value="t">
|
||||
{{ t }}
|
||||
</option>
|
||||
</select>
|
||||
</label>
|
||||
</div>
|
||||
<div v-if="fontPicker" class="font-picker">
|
||||
<div class="font-tabs">
|
||||
<button
|
||||
@@ -540,28 +653,9 @@ onUnmounted(() => {
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
<div class="field">
|
||||
<span class="field-label">favicon</span>
|
||||
<button
|
||||
type="button"
|
||||
class="favicon-tile"
|
||||
title="upload favicon (ico, png, svg...)"
|
||||
@click="faviconInput.click()"
|
||||
>
|
||||
<img v-if="favicon" :src="favicon" alt="current favicon" />
|
||||
<span v-else>?</span>
|
||||
</button>
|
||||
<input
|
||||
ref="faviconInput"
|
||||
type="file"
|
||||
accept="image/*"
|
||||
hidden
|
||||
@change="(ev) => { uploadFavicon(ev.target.files[0]); ev.target.value = '' }"
|
||||
/>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section class="block" @paste="onBrandPaste">
|
||||
<section class="block grow" @paste="onBrandPaste">
|
||||
<div class="block-head">
|
||||
<span class="field-label">brand code (replaces the brand link)</span>
|
||||
<button
|
||||
@@ -581,7 +675,7 @@ onUnmounted(() => {
|
||||
<div ref="brandEl" class="brand-cm" />
|
||||
</section>
|
||||
|
||||
<section class="block">
|
||||
<section class="block grow">
|
||||
<div class="block-head">
|
||||
<span class="field-label">custom CSS (applies to every page, on top of the theme)</span>
|
||||
</div>
|
||||
@@ -595,6 +689,7 @@ onUnmounted(() => {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
overflow-y: auto;
|
||||
background: var(--surface);
|
||||
}
|
||||
|
||||
.block {
|
||||
@@ -606,6 +701,13 @@ onUnmounted(() => {
|
||||
background: var(--surface);
|
||||
}
|
||||
|
||||
/* Editor blocks (brand HTML, custom CSS) share the leftover panel height
|
||||
equally; their CodeMirror windows fill the block and scroll internally. */
|
||||
.block.grow {
|
||||
flex: 1;
|
||||
min-height: 7rem;
|
||||
}
|
||||
|
||||
.block-head {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
@@ -618,6 +720,26 @@ onUnmounted(() => {
|
||||
gap: 0.5rem;
|
||||
}
|
||||
|
||||
/* Two-column grid (site name + favicon, theme + transition) so the rows
|
||||
and labels align with each other. */
|
||||
.field-grid {
|
||||
display: grid;
|
||||
grid-template-columns: 1fr auto;
|
||||
align-items: center;
|
||||
gap: 0.4rem 1.5rem;
|
||||
}
|
||||
|
||||
/* Labels share one narrow track per field, sized to the longest label
|
||||
("transition"), so they line up across rows without excess space. */
|
||||
.field-grid > .field {
|
||||
display: grid;
|
||||
grid-template-columns: 4.3rem 1fr auto;
|
||||
}
|
||||
|
||||
.field-grid .field-label {
|
||||
min-width: 0;
|
||||
}
|
||||
|
||||
/* Fixed-width labels keep the settings rows aligned. */
|
||||
.field > .field-label {
|
||||
min-width: 5rem;
|
||||
@@ -661,14 +783,6 @@ onUnmounted(() => {
|
||||
margin-left: auto;
|
||||
padding: 0 0.2rem;
|
||||
font-size: 1rem;
|
||||
background: none;
|
||||
border: none;
|
||||
cursor: pointer;
|
||||
opacity: 0.7;
|
||||
}
|
||||
|
||||
.block-head .icon-btn:hover {
|
||||
opacity: 1;
|
||||
}
|
||||
|
||||
.text-input {
|
||||
@@ -775,42 +889,29 @@ onUnmounted(() => {
|
||||
border-color: var(--accent);
|
||||
}
|
||||
|
||||
/* Small CodeMirror window for the custom brand HTML; scrolls internally. */
|
||||
.brand-cm {
|
||||
border: 1px solid var(--line);
|
||||
border-radius: 4px;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
.brand-cm :deep(.cm-editor) {
|
||||
max-height: 7rem;
|
||||
font-size: 0.85rem;
|
||||
}
|
||||
|
||||
.brand-cm :deep(.cm-scroller) {
|
||||
overflow: auto;
|
||||
}
|
||||
|
||||
.brand-cm :deep(.cm-gutters) {
|
||||
display: none;
|
||||
}
|
||||
|
||||
/* CodeMirror window for site-wide custom CSS. */
|
||||
/* CodeMirror windows for the brand HTML and custom CSS: fill the growing
|
||||
block, scroll internally. */
|
||||
.brand-cm,
|
||||
.css-cm {
|
||||
flex: 1;
|
||||
min-height: 0;
|
||||
border: 1px solid var(--line);
|
||||
border-radius: 4px;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
.brand-cm :deep(.cm-editor),
|
||||
.css-cm :deep(.cm-editor) {
|
||||
max-height: 12rem;
|
||||
height: 100%;
|
||||
font-size: 0.85rem;
|
||||
}
|
||||
|
||||
.brand-cm :deep(.cm-scroller),
|
||||
.css-cm :deep(.cm-scroller) {
|
||||
overflow: auto;
|
||||
}
|
||||
|
||||
.brand-cm :deep(.cm-gutters),
|
||||
.css-cm :deep(.cm-gutters) {
|
||||
display: none;
|
||||
}
|
||||
|
||||
@@ -7,10 +7,22 @@
|
||||
// real — a label with a title and slug, with content (landing page) or
|
||||
// without (category whose URL renders a placeholder page). The front page
|
||||
// is a top-level row with an empty slug, not the parent of the others.
|
||||
import { inject, onActivated, onMounted, onUnmounted, provide, ref, watch } from 'vue'
|
||||
//
|
||||
// Languages: the LangSelect switches which language the TITLES are shown
|
||||
// and edited in (rows without a translation show the original, dimmed) —
|
||||
// the selection is shared shell-wide (./editorLang) with the page editor
|
||||
// and the page preview. Translated title edits write a per-language
|
||||
// fragment (POST /_api/structure with lang); the structure itself —
|
||||
// slugs, order, hierarchy — is language-independent and always edits the
|
||||
// same tree.
|
||||
import { computed, inject, onActivated, onMounted, onUnmounted, provide, ref, watch } from 'vue'
|
||||
import StructureTree from './StructureTree.vue'
|
||||
import LangSelect from './LangSelect.vue'
|
||||
import { slugify } from './slugify'
|
||||
import { loadPlain } from './swapdoc'
|
||||
import { flagFor, langName, langSort } from './langs'
|
||||
import { editorLang, pagePrimary } from './editorLang'
|
||||
import { dropPageCache, loadPlain } from './swapdoc'
|
||||
import { apiFetch, apiJson } from 'paskia'
|
||||
|
||||
const props = defineProps({
|
||||
pagePath: { type: String, default: '' },
|
||||
@@ -23,6 +35,51 @@ const path = ref('')
|
||||
const saveError = ref('')
|
||||
const tree = ref([])
|
||||
|
||||
// The language the tree's titles are shown and edited in: "" = primary.
|
||||
const lang = editorLang
|
||||
const primaryLang = ref('en')
|
||||
const siteLangs = ref([])
|
||||
|
||||
// The strip's options: the primary language first, then the configured
|
||||
// translation targets (the lang tab manages that set) in the lang tab's
|
||||
// geographic grouping (./langs langSort).
|
||||
const langOptions = computed(() =>
|
||||
[primaryLang.value, ...langSort(siteLangs.value.filter((l) => l !== primaryLang.value))]
|
||||
.map((code) => ({
|
||||
tag: code === primaryLang.value ? '' : code,
|
||||
code,
|
||||
name: langName(code),
|
||||
flag: flagFor(code),
|
||||
primary: code === primaryLang.value,
|
||||
})),
|
||||
)
|
||||
const currentLang = computed(
|
||||
() => langOptions.value.find((o) => o.tag === lang.value) ?? langOptions.value[0],
|
||||
)
|
||||
|
||||
// The selection is shared (./editorLang): a change re-fetches the tree's
|
||||
// titles in it (and EditorShell swaps the page preview into it).
|
||||
watch(lang, () => refreshPages())
|
||||
|
||||
// Per-row primary language (Node.language, '' = inherit): the row's
|
||||
// dropdown lists "inherit" first (naming what it resolves to), then every
|
||||
// site language. Setting it on a section covers its whole subtree.
|
||||
const rowLangChoices = computed(() =>
|
||||
[primaryLang.value, ...langSort(siteLangs.value.filter((l) => l !== primaryLang.value))]
|
||||
.map((code) => ({ tag: code, code, name: langName(code), flag: flagFor(code), primary: false })),
|
||||
)
|
||||
function rowLangOptions(el) {
|
||||
const resolved = el.primary || primaryLang.value
|
||||
return [
|
||||
{ tag: '', code: '_inherit', name: `inherit (${langName(resolved)})`, flag: flagFor(resolved), primary: false },
|
||||
...rowLangChoices.value,
|
||||
]
|
||||
}
|
||||
|
||||
async function setLanguage(node, tag) {
|
||||
await postStructure({ path: node.path, language: tag })
|
||||
}
|
||||
|
||||
function normPath(p) {
|
||||
return p.trim().replace(/^\/+|\/+$/g, '')
|
||||
}
|
||||
@@ -106,7 +163,8 @@ function discardPending() {
|
||||
async function commitPending() {
|
||||
const node = pending.value
|
||||
if (!node) return
|
||||
// Empty slug: derive one from the title (transliterated to ASCII).
|
||||
// The typed slug is slugified at commit; empty derives one from the
|
||||
// title (transliterated to ASCII).
|
||||
const slug = slugify(node.slug.trim()) || slugify(node.title)
|
||||
if (!slug) {
|
||||
return
|
||||
@@ -114,7 +172,7 @@ async function commitPending() {
|
||||
const loc = locatePending(tree.value, '')
|
||||
const parentPath = loc?.parentPath ?? ''
|
||||
const newPath = parentPath ? `${parentPath}/${slug}` : slug
|
||||
const res = await fetch(`/_api/pages/${newPath}`, {
|
||||
const res = await apiFetch(`/_api/pages/${newPath}`, {
|
||||
method: 'PUT',
|
||||
headers: { 'content-type': 'application/json' },
|
||||
body: JSON.stringify({
|
||||
@@ -144,15 +202,29 @@ async function commitPending() {
|
||||
}
|
||||
pending.value = null
|
||||
await refreshPages()
|
||||
dropPageCache()
|
||||
await navigate(newPath)
|
||||
// Hand over to the page editor tab for the actual writing.
|
||||
shell?.switchMode('page')
|
||||
}
|
||||
|
||||
// --- Site structure tree (drag-and-drop ordering/moving) ----------------
|
||||
function findNode(nodes, p) {
|
||||
for (const n of nodes) {
|
||||
if (n.path === p) return n
|
||||
const found = findNode(n.children, p)
|
||||
if (found) return found
|
||||
}
|
||||
return null
|
||||
}
|
||||
|
||||
async function refreshPages() {
|
||||
try {
|
||||
tree.value = await (await fetch('/_api/pages')).json()
|
||||
const q = lang.value ? `?lang=${lang.value}` : ''
|
||||
tree.value = await apiJson(`/_api/pages${q}`)
|
||||
// The tree carries each node's resolved primary language: publish the
|
||||
// current page's (the shell pins the preview by it on '' selection).
|
||||
pagePrimary.value = findNode(tree.value, path.value)?.primary || 'en'
|
||||
} catch { /* list stays stale; not fatal */ }
|
||||
}
|
||||
|
||||
@@ -164,13 +236,15 @@ async function errorDetail(res) {
|
||||
}
|
||||
|
||||
async function postStructure(op) {
|
||||
const res = await fetch('/_api/structure', {
|
||||
const res = await apiFetch('/_api/structure', {
|
||||
method: 'POST',
|
||||
headers: { 'content-type': 'application/json' },
|
||||
body: JSON.stringify(op),
|
||||
})
|
||||
if (res.ok) {
|
||||
saveError.value = ''
|
||||
// Structure changes alter navigation on every page; drop prefetches.
|
||||
dropPageCache()
|
||||
loadPlain(path.value) // refresh menus and content from the server
|
||||
} else {
|
||||
saveError.value = `⚠️ ${await errorDetail(res)}`
|
||||
@@ -203,20 +277,25 @@ async function onReorder(parentPath, list, evt) {
|
||||
}
|
||||
|
||||
// Inline title/slug editing: rows are always editable. Title saves while
|
||||
// typing (debounced); the slug commits on blur/Enter, since it renames
|
||||
// the path (moving the whole subtree with it).
|
||||
// typing (debounced) — in the selected language (a translation writes a
|
||||
// title fragment, the primary language the original); the slug commits on
|
||||
// blur/Enter, since it renames the path (moving the whole subtree with it).
|
||||
// Slugs are language-independent.
|
||||
function onTitleInput(node, ev) {
|
||||
const title = ev.target.value.trim()
|
||||
if (!title || title === node.title) return
|
||||
debounce(`title:${node.path}`, async () => {
|
||||
await postStructure({ path: node.path, title })
|
||||
await postStructure({ path: node.path, title, lang: lang.value })
|
||||
})
|
||||
}
|
||||
|
||||
// The slug inputs are filtered as you type (StructureTree onSlugInput,
|
||||
// see slugify.js); the server re-validates and its reason is shown.
|
||||
// Slug inputs are typed freely (spaces become hyphens live, see
|
||||
// StructureTree onSlugInput); the value is slugified here at commit
|
||||
// (blur/Enter) before talking to the server, which re-validates (e.g.
|
||||
// reserved names) and its reason is shown.
|
||||
async function commitSlug(node, ev) {
|
||||
const slug = ev.target.value.trim()
|
||||
const slug = slugify(ev.target.value.trim())
|
||||
ev.target.value = slug
|
||||
if (slug === node.slug) return
|
||||
const parent = node.path.split('/').slice(0, -1).join('/')
|
||||
// Empty slug at top level = the front page (path "").
|
||||
@@ -228,28 +307,13 @@ async function commitSlug(node, ev) {
|
||||
}
|
||||
}
|
||||
|
||||
// Two-step delete (no dialogs): the first click arms the row's button for
|
||||
// a few seconds, the second actually deletes.
|
||||
const arming = ref(null)
|
||||
let armTimer = null
|
||||
|
||||
function armRemove(node) {
|
||||
if (arming.value === node.path) {
|
||||
clearTimeout(armTimer)
|
||||
arming.value = null
|
||||
removePage(node)
|
||||
} else {
|
||||
arming.value = node.path
|
||||
clearTimeout(armTimer)
|
||||
armTimer = setTimeout(() => { arming.value = null }, 3000)
|
||||
}
|
||||
}
|
||||
|
||||
// Deletion is immediate, no confirmation.
|
||||
async function removePage(node) {
|
||||
const res = await fetch(`/_api/pages/${node.path}`, { method: 'DELETE' })
|
||||
const res = await apiFetch(`/_api/pages/${node.path}`, { method: 'DELETE' })
|
||||
if (res.ok) {
|
||||
saveError.value = ''
|
||||
refreshPages()
|
||||
dropPageCache()
|
||||
const p = node.path
|
||||
if (p === path.value || (p && path.value.startsWith(`${p}/`))) {
|
||||
// The current page was deleted — or reduced to a category, which now
|
||||
@@ -267,24 +331,29 @@ async function removePage(node) {
|
||||
provide('structureHandlers', {
|
||||
current: () => path.value,
|
||||
open: navigate,
|
||||
arming: () => arming.value,
|
||||
armRemove,
|
||||
removePage,
|
||||
reorder: onReorder,
|
||||
titleInput: onTitleInput,
|
||||
commitSlug,
|
||||
commitPending,
|
||||
discardPending,
|
||||
newPage,
|
||||
langOptions: rowLangOptions,
|
||||
setLanguage,
|
||||
})
|
||||
|
||||
onMounted(() => {
|
||||
path.value = normPath(props.pagePath)
|
||||
refreshPages()
|
||||
addEventListener('pagerite:editor-shown', onEditorShown)
|
||||
// The language strip: site primary + configured targets.
|
||||
apiJson('/_api/settings').then((s) => {
|
||||
primaryLang.value = s.primary_lang || 'en'
|
||||
siteLangs.value = s.translate_langs || []
|
||||
}).catch(() => { /* no strip */ })
|
||||
})
|
||||
|
||||
onUnmounted(() => {
|
||||
clearTimeout(armTimer)
|
||||
for (const t of Object.values(timers)) clearTimeout(t)
|
||||
removeEventListener('pagerite:editor-shown', onEditorShown)
|
||||
})
|
||||
@@ -293,8 +362,15 @@ onUnmounted(() => {
|
||||
<template>
|
||||
<div class="structure-editor">
|
||||
<div v-if="saveError">{{ saveError }}</div>
|
||||
<div v-if="langOptions.length > 1" class="block lang-block">
|
||||
<div><LangSelect v-model="lang" :options="langOptions" /></div>
|
||||
<small v-if="lang" class="muted">
|
||||
viewing {{ currentLang.name }} titles — dimmed rows are untranslated
|
||||
(shown in the primary language); slugs never translate
|
||||
</small>
|
||||
</div>
|
||||
<section class="block structure">
|
||||
<StructureTree :nodes="tree" />
|
||||
<StructureTree :nodes="tree" :lang="lang" />
|
||||
</section>
|
||||
</div>
|
||||
</template>
|
||||
@@ -319,4 +395,10 @@ onUnmounted(() => {
|
||||
overflow-y: auto;
|
||||
min-height: 0;
|
||||
}
|
||||
|
||||
/* The language selector is LangSelect.vue — its styles live there. */
|
||||
|
||||
.muted {
|
||||
color: var(--muted);
|
||||
}
|
||||
</style>
|
||||
|
||||
@@ -1,7 +1,13 @@
|
||||
<script setup>
|
||||
// Recursive site-structure tree with drag-and-drop ordering (vue-draggable).
|
||||
// Nodes come from the server (GET /_api/pages via StructureEditor.vue) as
|
||||
// {slug, path, title, order, published, has_content, children}.
|
||||
// {slug, path, title, translated, order, published, has_content, language,
|
||||
// primary, children}. The row's flag
|
||||
// (LangSelect) sets the node's primary language (language; '' = inherit —
|
||||
// dimmed, showing the resolved flag); the setting covers the whole subtree.
|
||||
// With a `lang` prop (StructureEditor's language strip) the titles shown
|
||||
// are that language's; `translated` marks rows with an actual translation
|
||||
// (untranslated rows show the original title, dimmed).
|
||||
// Every node is real: a label whose title and slug are always editable
|
||||
// inline — the title saves while typing (and focusing it opens the page),
|
||||
// the slug commits on blur/Enter since it renames the path, moving the
|
||||
@@ -24,26 +30,32 @@
|
||||
import { inject } from 'vue'
|
||||
import draggable from 'vuedraggable'
|
||||
import { slugify } from './slugify'
|
||||
import LangSelect from './LangSelect.vue'
|
||||
|
||||
defineOptions({ name: 'StructureTree' })
|
||||
const props = defineProps({
|
||||
nodes: { type: Array, required: true },
|
||||
parentPath: { type: String, default: '' },
|
||||
depth: { type: Number, default: 0 },
|
||||
// StructureEditor's selected language ('' = original). Only used for the
|
||||
// untranslated-title styling here; the fetch and title edits live in the
|
||||
// parent (handlers.titleInput posts the lang with the op).
|
||||
lang: { type: String, default: '' },
|
||||
})
|
||||
|
||||
const handlers = inject('structureHandlers')
|
||||
|
||||
// Live-filter the slug inputs as they are typed (oninput): invalid
|
||||
// characters are simply not accepted, spaces become hyphens and unicode
|
||||
// folds to ASCII (see slugify.js). Existing rows commit on change, the
|
||||
// pending row is v-modeled.
|
||||
function onSlugInput(ev) {
|
||||
ev.target.value = slugify(ev.target.value)
|
||||
}
|
||||
|
||||
function onPendingSlugInput(element, ev) {
|
||||
element.slug = slugify(ev.target.value)
|
||||
// Slug inputs accept free typing; the only live rewrites are turning
|
||||
// spaces into hyphens and lowercasing (both keep the length for ASCII,
|
||||
// so the cursor stays put). Anything else (unicode folding, stripping,
|
||||
// collapsing) is left for commit time, where the value is run through
|
||||
// slugify before talking to the server (StructureEditor). `element` is
|
||||
// the pending row (v-modeled), null for existing rows (plain :value
|
||||
// binding, read back on commit).
|
||||
function onSlugInput(element, ev) {
|
||||
const v = ev.target.value.replace(/\s/g, '-').toLowerCase()
|
||||
ev.target.value = v
|
||||
if (element) element.slug = v
|
||||
}
|
||||
|
||||
// Focus the title input of a fresh pending row.
|
||||
@@ -113,7 +125,7 @@ function onEnd() {
|
||||
class="edit slug-edit"
|
||||
:placeholder="slugify(element.title)"
|
||||
title="Slug (last path segment) — empty: derived from the title"
|
||||
@input="onPendingSlugInput(element, $event)"
|
||||
@input="onSlugInput(element, $event)"
|
||||
@keyup.enter="handlers.commitPending()"
|
||||
@keyup.esc="handlers.discardPending()"
|
||||
/>
|
||||
@@ -125,8 +137,11 @@ function onEnd() {
|
||||
<template v-else>
|
||||
<input
|
||||
class="edit title-edit"
|
||||
:class="{ untranslated: lang && !element.translated }"
|
||||
:value="element.title"
|
||||
title="Label in the navigation — saves while typing; click opens the page"
|
||||
:title="lang && !element.translated
|
||||
? 'No translation yet — showing the original; typing creates the translated title'
|
||||
: 'Label in the navigation — saves while typing; click opens the page'"
|
||||
@input="handlers.titleInput(element, $event)"
|
||||
@focus="handlers.open(element.path)"
|
||||
/>
|
||||
@@ -135,21 +150,31 @@ function onEnd() {
|
||||
:value="element.slug"
|
||||
placeholder="front page"
|
||||
title="Slug (last path segment) — renames move the whole subtree. Empty at top level = front page"
|
||||
@input="onSlugInput"
|
||||
@input="onSlugInput(null, $event)"
|
||||
@change="handlers.commitSlug(element, $event)"
|
||||
/>
|
||||
<span class="acts">
|
||||
<span
|
||||
class="row-lang"
|
||||
:class="{ inherited: !element.language }"
|
||||
><LangSelect
|
||||
:model-value="element.language"
|
||||
:options="handlers.langOptions(element)"
|
||||
:title="element.language
|
||||
? `primary language: set on this page (subtree inherits)`
|
||||
: `primary language: inherited — set it here (subtree inherits)`"
|
||||
@update:model-value="handlers.setLanguage(element, $event)"
|
||||
/></span>
|
||||
<span v-if="!element.published" class="draft">draft</span>
|
||||
<button
|
||||
v-if="element.has_content || !element.children.length"
|
||||
type="button"
|
||||
class="act del"
|
||||
:class="{ armed: handlers.arming() === element.path }"
|
||||
:title="element.children.length
|
||||
? 'delete the landing page (the category keeps its subpages)'
|
||||
: 'delete page'"
|
||||
@click="handlers.armRemove(element)"
|
||||
>{{ handlers.arming() === element.path ? 'delete?' : '✕' }}</button>
|
||||
@click="handlers.removePage(element)"
|
||||
>✕</button>
|
||||
</span>
|
||||
</template>
|
||||
</div>
|
||||
@@ -158,6 +183,7 @@ function onEnd() {
|
||||
:nodes="element.children"
|
||||
:parent-path="element.path"
|
||||
:depth="depth + 1"
|
||||
:lang="lang"
|
||||
/>
|
||||
</div>
|
||||
</template>
|
||||
@@ -223,7 +249,7 @@ body.tree-dragging .treelist {
|
||||
level, not across levels). */
|
||||
.row {
|
||||
display: grid;
|
||||
grid-template-columns: 1.2em minmax(3rem, 1fr) 7rem 5rem;
|
||||
grid-template-columns: 1.2em minmax(3rem, 1fr) 7rem auto;
|
||||
align-items: baseline;
|
||||
gap: 0.35rem;
|
||||
/* Vertical spacing widens the drop zones: the exposed top strip is the
|
||||
@@ -274,6 +300,13 @@ body.tree-dragging .treelist {
|
||||
cursor: text;
|
||||
}
|
||||
|
||||
/* With a language selected (StructureEditor's strip), rows without an
|
||||
actual translation show the original title dimmed and italic. */
|
||||
.title-edit.untranslated {
|
||||
color: var(--muted);
|
||||
font-style: italic;
|
||||
}
|
||||
|
||||
.slug-edit {
|
||||
font-family: var(--font-code);
|
||||
}
|
||||
@@ -285,6 +318,20 @@ body.tree-dragging .treelist {
|
||||
justify-content: end;
|
||||
}
|
||||
|
||||
/* Row language selector (LangSelect): the effective primary language's
|
||||
flag; dimmed while the setting is inherited rather than set on the row. */
|
||||
.row-lang {
|
||||
display: inline-flex;
|
||||
}
|
||||
|
||||
.row-lang.inherited :deep(.lang-current) {
|
||||
opacity: 0.45;
|
||||
}
|
||||
|
||||
.row-lang.inherited:hover :deep(.lang-current) {
|
||||
opacity: 0.85;
|
||||
}
|
||||
|
||||
.draft {
|
||||
color: var(--muted);
|
||||
font-size: 0.75rem;
|
||||
@@ -300,12 +347,6 @@ body.tree-dragging .treelist {
|
||||
white-space: nowrap;
|
||||
}
|
||||
|
||||
/* Two-step delete: the first click arms the button, the second deletes. */
|
||||
.act.armed {
|
||||
color: #e06c75;
|
||||
font-weight: 600;
|
||||
}
|
||||
|
||||
.del:hover {
|
||||
color: #e06c75;
|
||||
}
|
||||
|
||||
@@ -0,0 +1,72 @@
|
||||
<script setup>
|
||||
import { computed } from 'vue'
|
||||
import { formatCount, formatReadTime } from './analytics/format.js'
|
||||
|
||||
const props = defineProps({
|
||||
step: { type: Object, required: true },
|
||||
count: { type: Number, default: 0 },
|
||||
favicons: { type: Object, default: null },
|
||||
flags: { type: Array, default: () => [] },
|
||||
})
|
||||
|
||||
defineEmits(['close'])
|
||||
|
||||
const hasError = computed(() => props.step.status >= 400)
|
||||
const favicon = computed(() =>
|
||||
props.step.external && props.step.origin ? props.favicons?.[props.step.origin] : null,
|
||||
)
|
||||
|
||||
const title = computed(() => {
|
||||
const parts = [props.step.title]
|
||||
if (props.step.readSeconds > 0) {
|
||||
parts.push(formatReadTime(props.step.readSeconds))
|
||||
}
|
||||
if (hasError.value) {
|
||||
parts.push(`${props.step.status}`)
|
||||
}
|
||||
return parts.filter(Boolean).join(' — ')
|
||||
})
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<a class="trail-link"
|
||||
:class="{ error: hasError }"
|
||||
:href="step.path"
|
||||
:title="title"
|
||||
:target="step.external ? '_blank' : undefined"
|
||||
:rel="step.external ? 'noopener' : undefined"
|
||||
@click="(e) => { if (!step.external) $emit('close') }">
|
||||
<small v-if="count > 1" class="muted">{{ formatCount(count) }}×</small>
|
||||
<img v-if="favicon" class="favicon" :src="favicon" alt="" />
|
||||
<span>{{ step.slug }}</span>
|
||||
<span v-for="(f, fi) in flags" :key="fi" class="flag" v-html="f"></span>
|
||||
</a>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
.favicon {
|
||||
width: 1em;
|
||||
height: 1em;
|
||||
margin-right: 0.25em;
|
||||
vertical-align: -0.1em;
|
||||
}
|
||||
|
||||
/* Same flag chip as the visitor cells (VisitorCell.vue). */
|
||||
.flag {
|
||||
display: inline-flex;
|
||||
width: 18px;
|
||||
height: 12px;
|
||||
margin-left: 0.25em;
|
||||
border-radius: 2px;
|
||||
overflow: hidden;
|
||||
border: 1px solid var(--line);
|
||||
box-shadow: 0 0 0 1px rgba(0, 0, 0, 0.2) inset;
|
||||
vertical-align: middle;
|
||||
}
|
||||
|
||||
.flag :deep(svg) {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
display: block;
|
||||
}
|
||||
</style>
|
||||
@@ -0,0 +1,313 @@
|
||||
<script setup>
|
||||
/**
|
||||
* Radial transition map for a pre-filtered time range.
|
||||
*
|
||||
* The parent filters transitions, views and visits to the selected range
|
||||
* before passing them in; `window` carries the absolute [t0, t1) window
|
||||
* so the visual scale can normalize against a one-week reference.
|
||||
*/
|
||||
import { computed, onBeforeUnmount, onMounted, shallowRef, watch } from 'vue'
|
||||
import { DAY } from './analytics/time.js'
|
||||
import { formatCount, formatReadTime } from './analytics/format.js'
|
||||
import {
|
||||
TNODE_W,
|
||||
TNODE_H,
|
||||
BEAD_R,
|
||||
buildTransitionGraph,
|
||||
} from './analytics/transitions.js'
|
||||
|
||||
const props = defineProps({
|
||||
data: { type: Object, default: null },
|
||||
window: { type: Object, required: true },
|
||||
pageTree: { type: Array, default: null },
|
||||
favicons: { type: Object, default: null },
|
||||
})
|
||||
|
||||
// origin -> /_f/... icon URL, keyed by the node's origin (source/exit
|
||||
// pills only; UTM-tagged source nodes without an https origin stay
|
||||
// text-only).
|
||||
const extFavicon = (x) => {
|
||||
if (!x.path?.startsWith('https://')) return null
|
||||
try {
|
||||
return props.favicons?.[new URL(x.path).origin] || null
|
||||
} catch {
|
||||
return null
|
||||
}
|
||||
}
|
||||
|
||||
const dayScale = computed(() => {
|
||||
const { t0, t1 } = props.window
|
||||
// Convert raw counts to a daily hit rate (hits/day).
|
||||
if (t0 != null && t1 != null) return DAY / (t1 - t0)
|
||||
// 'all': scale by the actual data span, but never less than the 30-day
|
||||
// minimum the plot enforces, so sparse young data is not over-amplified.
|
||||
const times = new Set()
|
||||
for (const buckets of Object.values(props.data?.views || {})) {
|
||||
for (const k of Object.keys(buckets)) times.add(Date.parse(k))
|
||||
}
|
||||
const arr = [...times]
|
||||
if (arr.length < 2) return 1
|
||||
const span = Math.max(...arr) - Math.min(...arr)
|
||||
return DAY / Math.max(span, 30 * DAY)
|
||||
})
|
||||
|
||||
const graph = computed(() =>
|
||||
props.data
|
||||
? buildTransitionGraph(props.data, props.pageTree, props.data.visits || [], dayScale.value)
|
||||
: null,
|
||||
)
|
||||
|
||||
// Bead animation: every bead is simulated independently in JS. Each flow
|
||||
// (one per edge direction) emits a bead every `interval` seconds; beads
|
||||
// cross their segment in a constant TRAVERSAL_S seconds (speed relative
|
||||
// to span length) and are dropped at the end.
|
||||
// There is deliberately no cap on beads in flight.
|
||||
// Emitters persist across data reloads, keyed by flow.key: an unchanged
|
||||
// link keeps its emission phase and in-flight beads (tracked by progress,
|
||||
// not absolute time), so a count change elsewhere never reshuffles them.
|
||||
const beads = shallowRef([])
|
||||
let rafId = 0
|
||||
const emitters = new Map() // flow.key -> { flow, interval, next, alive }
|
||||
const live = [] // { e, p } — beads in flight, p = progress 0..1
|
||||
let lastTick = 0
|
||||
|
||||
const MAX_BEAD_RATE = 120 // upper bound on total beads per second
|
||||
const TRAVERSAL_S = 0.4 // seconds to cross any segment, end to end
|
||||
|
||||
const syncBeads = (flows) => {
|
||||
const reduced = matchMedia('(prefers-reduced-motion: reduce)').matches
|
||||
if (!flows?.length || reduced) {
|
||||
emitters.clear()
|
||||
live.length = 0
|
||||
beads.value = []
|
||||
return
|
||||
}
|
||||
// Cap the total bead emission rate so a busy range cannot spawn enough
|
||||
// beads to kill the page. Existing per-range time scaling is preserved;
|
||||
// this is only a proportional emergency throttle when the limit is hit.
|
||||
const totalRate = flows.reduce((s, f) => s + 1 / f.interval, 0)
|
||||
const scale = totalRate > MAX_BEAD_RATE ? MAX_BEAD_RATE / totalRate : 1
|
||||
|
||||
const now = performance.now()
|
||||
const seen = new Set()
|
||||
for (const flow of flows) {
|
||||
seen.add(flow.key)
|
||||
const interval = (flow.interval / scale) * 1000
|
||||
const e = emitters.get(flow.key)
|
||||
if (e) {
|
||||
e.flow = flow // pick up new geometry/rate, keep the phase
|
||||
e.interval = interval
|
||||
continue
|
||||
}
|
||||
// New emitter: pre-fill the traversal with evenly spaced beads (random
|
||||
// phase), so the flow appears already running instead of empty.
|
||||
const phase = Math.random() * interval
|
||||
const dp = interval / 1000 / TRAVERSAL_S
|
||||
const ne = { flow, interval, next: now + phase, alive: true }
|
||||
for (let p = 1 - phase / 1000 / TRAVERSAL_S; p > 0; p -= dp) {
|
||||
live.push({ e: ne, p })
|
||||
}
|
||||
emitters.set(flow.key, ne)
|
||||
}
|
||||
for (const [key, e] of emitters) {
|
||||
if (!seen.has(key)) {
|
||||
e.alive = false
|
||||
emitters.delete(key)
|
||||
}
|
||||
}
|
||||
for (let i = live.length - 1; i >= 0; i--) {
|
||||
if (!live[i].e.alive) live.splice(i, 1)
|
||||
}
|
||||
}
|
||||
|
||||
const tick = (t) => {
|
||||
const dt = lastTick ? (t - lastTick) / 1000 : 0
|
||||
lastTick = t
|
||||
for (const e of emitters.values()) {
|
||||
while (e.next <= t) {
|
||||
live.push({ e, p: 0 })
|
||||
e.next += e.interval
|
||||
}
|
||||
}
|
||||
const out = []
|
||||
for (let i = live.length - 1; i >= 0; i--) {
|
||||
const b = live[i]
|
||||
b.p += dt / TRAVERSAL_S
|
||||
if (b.p >= 1) {
|
||||
live.splice(i, 1)
|
||||
continue
|
||||
}
|
||||
const f = b.e.flow
|
||||
out.push({ x: f.x1 + (f.x2 - f.x1) * b.p, y: f.y1 + (f.y2 - f.y1) * b.p })
|
||||
}
|
||||
beads.value = out
|
||||
rafId = requestAnimationFrame(tick)
|
||||
}
|
||||
|
||||
watch(() => graph.value?.flows, syncBeads, { immediate: true })
|
||||
onMounted(() => {
|
||||
if (!matchMedia('(prefers-reduced-motion: reduce)').matches) {
|
||||
rafId = requestAnimationFrame(tick)
|
||||
}
|
||||
})
|
||||
onBeforeUnmount(() => cancelAnimationFrame(rafId))
|
||||
|
||||
// The svg never renders larger than its natural size (1 viewBox unit = 1
|
||||
// px, max-width below): the layout geometry is designed in pixel-like
|
||||
// units, and upscaling would blow up the pills around their text. Narrow
|
||||
// panels scale the graph down to fit (width: 100%), text along with it.
|
||||
|
||||
// Pill text is not truncated: text is clipped at the pill's rounded border
|
||||
// (clipPath per node, inset a few units for padding). Captions center when
|
||||
// they fit; overlong ones anchor left so their beginning (not their
|
||||
// middle) survives the clip. Width estimate: ~0.52 em per glyph.
|
||||
const fitsPill = (label, fontPx = 19) => label.length * 0.52 * fontPx <= TNODE_W - 16
|
||||
|
||||
// With a favicon the label leaves room for the icon at the pill's left
|
||||
// and is always left-anchored past it.
|
||||
const labelX = (x) =>
|
||||
extFavicon(x) ? x.x - TNODE_W / 2 + 36 : fitsPill(x.label) ? x.x : x.x - TNODE_W / 2 + 8
|
||||
const labelAnchor = (x) => (!extFavicon(x) && fitsPill(x.label) ? 'middle' : 'start')
|
||||
|
||||
const countLabel = (n) =>
|
||||
n.readSec ? `${formatCount(n.views)}×${formatReadTime(n.readSec)}` : formatCount(n.views)
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<section v-if="graph">
|
||||
<svg class="tmap" :style="{ maxWidth: `${graph.bounds.x1 - graph.bounds.x0}px` }" :viewBox="`${graph.bounds.x0} ${graph.bounds.y0} ${graph.bounds.x1 - graph.bounds.x0} ${graph.bounds.y1 - graph.bounds.y0}`"
|
||||
role="img" aria-label="map of transitions between pages">
|
||||
<path v-for="(a, i) in graph.arcs" :key="'a' + i"
|
||||
:id="`tarc${i}`" :d="a.d" :class="['tarc', a.top && 'tarc-top']" />
|
||||
<template v-for="(a, i) in graph.arcs" :key="'t' + i">
|
||||
<path v-if="a.ld" :id="`tarcl${i}`" :d="a.ld" fill="none" stroke="none" />
|
||||
<text v-if="a.ld" class="tarclabel" :class="{ 'tarclabel-top': a.top }"><textPath :href="`#tarcl${i}`" startOffset="0">{{ a.label }}</textPath></text>
|
||||
</template>
|
||||
<path v-for="(e, i) in graph.edges" :key="'e' + i"
|
||||
:d="e.d" :class="['tconn', e.external && 'tconn-exit']">
|
||||
<title>{{ e.title }}</title>
|
||||
</path>
|
||||
<circle v-for="(b, i) in beads" :key="'b' + i"
|
||||
:cx="b.x" :cy="b.y" :r="BEAD_R" class="tbead" />
|
||||
<g v-for="(x, i) in graph.extNodes" :key="'x' + i">
|
||||
<clipPath :id="`xclip${i}`">
|
||||
<rect :x="x.x - TNODE_W/2 + 6" :y="x.y - TNODE_H/2" :width="TNODE_W - 12"
|
||||
:height="TNODE_H" :rx="TNODE_H/2 - 4" />
|
||||
</clipPath>
|
||||
<a v-if="x.href" :href="x.href" target="_blank" rel="noopener">
|
||||
<title>{{ x.path }}</title>
|
||||
<rect :x="x.x - TNODE_W/2" :y="x.y - TNODE_H/2" :width="TNODE_W" :height="TNODE_H" :rx="TNODE_H/2"
|
||||
:class="['txnode', x.kind === 'source' ? 'txnode-source' : 'txnode-exit']" />
|
||||
<g :clip-path="`url(#xclip${i})`">
|
||||
<image v-if="extFavicon(x)" :href="extFavicon(x)" :x="x.x - TNODE_W/2 + 12" :y="x.y - TNODE_H*0.16 - 11" width="22" height="22" />
|
||||
<text :x="labelX(x)" :y="x.y - TNODE_H*0.16" class="tnodeslug" dominant-baseline="middle" :style="{ textAnchor: labelAnchor(x) }">{{ x.label }}</text>
|
||||
<text :x="x.x" :y="x.y + TNODE_H*0.24" class="tnodecount" dominant-baseline="middle">{{ formatCount(x.count) }}</text>
|
||||
</g>
|
||||
</a>
|
||||
<g v-else>
|
||||
<title>{{ x.path }}</title>
|
||||
<rect :x="x.x - TNODE_W/2" :y="x.y - TNODE_H/2" :width="TNODE_W" :height="TNODE_H" :rx="TNODE_H/2"
|
||||
:class="['txnode', x.kind === 'source' ? 'txnode-source' : 'txnode-exit']" />
|
||||
<g :clip-path="`url(#xclip${i})`">
|
||||
<image v-if="extFavicon(x)" :href="extFavicon(x)" :x="x.x - TNODE_W/2 + 12" :y="x.y - TNODE_H*0.16 - 11" width="22" height="22" />
|
||||
<text :x="labelX(x)" :y="x.y - TNODE_H*0.16" class="tnodeslug" dominant-baseline="middle" :style="{ textAnchor: labelAnchor(x) }">{{ x.label }}</text>
|
||||
<text :x="x.x" :y="x.y + TNODE_H*0.24" class="tnodecount" dominant-baseline="middle">{{ formatCount(x.count) }}</text>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
<g v-for="(n, i) in graph.nodes" :key="n.path">
|
||||
<clipPath :id="`nclip${i}`">
|
||||
<rect :x="n.x - TNODE_W/2 + 6" :y="n.y - TNODE_H/2" :width="TNODE_W - 12"
|
||||
:height="TNODE_H" :rx="TNODE_H/2 - 4" />
|
||||
</clipPath>
|
||||
<a :href="n.path">
|
||||
<title>{{ n.title }}</title>
|
||||
<rect :x="n.x - TNODE_W/2" :y="n.y - TNODE_H/2" :width="TNODE_W" :height="TNODE_H" :rx="TNODE_H/2" class="tnode" />
|
||||
<g :clip-path="`url(#nclip${i})`">
|
||||
<text :x="fitsPill(n.label) ? n.x : n.x - TNODE_W/2 + 8" :y="n.y - TNODE_H*0.16" class="tnodeslug" dominant-baseline="middle" :style="{ textAnchor: fitsPill(n.label) ? 'middle' : 'start' }">{{ n.label }}</text>
|
||||
<text :x="n.x" :y="n.y + TNODE_H*0.24" class="tnodecount" dominant-baseline="middle">
|
||||
{{ countLabel(n) }}
|
||||
</text>
|
||||
</g>
|
||||
</a>
|
||||
</g>
|
||||
</svg>
|
||||
</section>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
/* Transition map: radial graph of internal page-to-page transitions. */
|
||||
.tmap {
|
||||
display: block;
|
||||
width: 100%;
|
||||
/* max-width is set inline to the natural content width (px = viewBox
|
||||
units), so wide panels never upscale the graph beyond 1:1. */
|
||||
margin: 0 auto;
|
||||
}
|
||||
.tmap .tconn {
|
||||
fill: var(--accent);
|
||||
opacity: 0.4; /* uniform, not strength-encoded: width carries that */
|
||||
}
|
||||
.tmap .tconn-exit {
|
||||
fill: var(--text);
|
||||
}
|
||||
.tmap .tbead {
|
||||
fill: var(--accent);
|
||||
opacity: 0.85;
|
||||
filter: drop-shadow(0 0 2.5px var(--accent));
|
||||
}
|
||||
.tmap .txnode {
|
||||
/* External source/exit pills: plain white on every theme, with a hairline
|
||||
so the pill stays visible on a white page. */
|
||||
fill: #fff;
|
||||
stroke: var(--line, rgba(128, 128, 128, 0.4));
|
||||
stroke-width: 1;
|
||||
}
|
||||
.tmap .txnode-source { fill: #fff; }
|
||||
.tmap .txnode-exit { fill: #fff; }
|
||||
/* Branch lanes: one wide concentric arc per path prefix, running behind
|
||||
the node pills around the fan's circle center; parent levels sit one
|
||||
indent (radius step) outward. Each lane's label follows a short guide
|
||||
arc across the first inter-node gap (the part pills never cover). */
|
||||
.tmap .tarc {
|
||||
fill: none;
|
||||
stroke: var(--muted);
|
||||
stroke-width: 16;
|
||||
opacity: 0.25;
|
||||
}
|
||||
.tmap .tarc-top { stroke-width: 24; }
|
||||
/* Lane labels are left-aligned: each guide arc starts just past the source
|
||||
pill's edge, the earliest point where the text is visible. */
|
||||
.tmap .tarclabel {
|
||||
fill: var(--muted);
|
||||
font-size: 13px;
|
||||
text-anchor: start;
|
||||
}
|
||||
/* The top lane is 50% thicker; its 🏠︎ label scales along. */
|
||||
.tmap .tarclabel-top {
|
||||
font-size: 19.5px;
|
||||
}
|
||||
.tmap .tnode {
|
||||
fill: var(--accent);
|
||||
stroke: none;
|
||||
}
|
||||
/* Text sizes are viewBox units: they shrink along with the graph on
|
||||
narrow panels. Overlong labels are clipped at the pill border. The text
|
||||
is always black, on accent (internal pills) and white (external pills)
|
||||
alike — black stands out from any accent color, so the coloring stays
|
||||
stable across themes and light/dark modes. */
|
||||
.tmap .tnodeslug {
|
||||
fill: #000;
|
||||
font-size: 19px;
|
||||
text-anchor: start;
|
||||
}
|
||||
.tmap a { cursor: pointer; }
|
||||
.tmap .tnodecount {
|
||||
fill: #000;
|
||||
opacity: 0.75;
|
||||
font-size: 15px;
|
||||
text-anchor: middle;
|
||||
}
|
||||
|
||||
section { margin-top: 1.8rem; }
|
||||
</style>
|
||||
@@ -0,0 +1,175 @@
|
||||
<script setup>
|
||||
// Visitor metadata cell shared by the recent-visits, crawlers, and abuse tables.
|
||||
// Displays IP/network/host, country flag/city, UA, and language when available.
|
||||
// Clicking the IP copies the full address to the clipboard.
|
||||
// ``variantCount`` overrides the UA line to warn when multiple client
|
||||
// fingerprints share the same IP (e.g. a scanner rotating UAs).
|
||||
// Clicking the UA line copies the raw UA(s) to the clipboard, one per line
|
||||
// (``uaRaws`` carries every variation for multi-client IPs).
|
||||
import { computed } from 'vue'
|
||||
import * as flagSvgs from 'country-flag-icons/string/3x2'
|
||||
import { copyIp, copyList, formatLang } from './analytics/format.js'
|
||||
import { langName } from './langs.js'
|
||||
|
||||
const props = defineProps({
|
||||
ip: { type: String, default: '' },
|
||||
ipDisplay: { type: String, default: '—' },
|
||||
ua: { type: String, default: '' },
|
||||
uaRaw: { type: String, default: '' },
|
||||
uaRaws: { type: String, default: '' },
|
||||
uaUrl: { type: String, default: '' },
|
||||
country: { type: String, default: '' },
|
||||
city: { type: String, default: '' },
|
||||
lang: { type: String, default: '' },
|
||||
langDisplay: { type: String, default: '' },
|
||||
isHost: { type: Boolean, default: false },
|
||||
variantCount: { type: Number, default: 1 },
|
||||
})
|
||||
|
||||
const hasCountry = computed(() => !!(props.country && props.country !== '—'))
|
||||
const hasCity = computed(() => !!(props.city && props.city !== '—'))
|
||||
const hasLocale = computed(() => hasCountry.value || hasCity.value)
|
||||
const langValue = computed(() => props.langDisplay || formatLang(props.lang))
|
||||
const showLang = computed(() => langValue.value && langValue.value !== '—')
|
||||
const uaCopy = computed(() => props.uaRaws || props.uaRaw)
|
||||
|
||||
function flagSvg(code) {
|
||||
return flagSvgs[code?.toUpperCase()] || ''
|
||||
}
|
||||
|
||||
function countryName(code) {
|
||||
if (!code) return ''
|
||||
try {
|
||||
return new Intl.DisplayNames(['en'], { type: 'region' }).of(code.toUpperCase())
|
||||
} catch {
|
||||
return ''
|
||||
}
|
||||
}
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<td class="visitor-cell" :class="{ 'host-cell': isHost }">
|
||||
<div class="visitor-rows">
|
||||
<div class="visitor-row">
|
||||
<div class="locale-line">
|
||||
<span v-if="flagSvg(country)" class="flag" v-html="flagSvg(country)" :title="countryName(country) || country"></span>
|
||||
<template v-if="hasCity"><small class="city-name muted">{{ city }}</small></template>
|
||||
<template v-else-if="!hasLocale">—</template>
|
||||
</div>
|
||||
<div class="ip-line">
|
||||
<span class="clickable-ip small muted"
|
||||
:title="ip"
|
||||
@click="copyIp(ip, $event)">{{ ipDisplay }}</span>
|
||||
</div>
|
||||
</div>
|
||||
<div class="visitor-row">
|
||||
<div class="ua-line">
|
||||
<small v-if="variantCount > 1" class="muted variant-hint clickable-ip"
|
||||
:title="uaCopy"
|
||||
@click="copyList(uaCopy, $event)">{{ variantCount }} client variations</small>
|
||||
<small v-else class="muted clickable-ip" :title="uaRaw"
|
||||
@click="copyList(uaCopy, $event)">{{ ua || '—' }}</small><a v-if="uaUrl && variantCount <= 1"
|
||||
class="ua-link icon-btn" :href="uaUrl"
|
||||
target="_blank" rel="noopener noreferrer"
|
||||
@click.stop>🔗</a>
|
||||
</div>
|
||||
<div v-if="showLang && variantCount <= 1" class="locale-lang"><small class="muted" :title="langName(lang)">{{ langValue }}</small></div>
|
||||
</div>
|
||||
</div>
|
||||
</td>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
.visitor-cell {
|
||||
width: 18em;
|
||||
max-width: 18em;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
vertical-align: top;
|
||||
}
|
||||
|
||||
.visitor-cell.host-cell {
|
||||
text-align: right;
|
||||
}
|
||||
|
||||
.visitor-rows {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: 0.15rem;
|
||||
}
|
||||
|
||||
.visitor-row {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: space-between;
|
||||
gap: 0.5rem;
|
||||
}
|
||||
|
||||
.visitor-row > * {
|
||||
min-width: 0;
|
||||
}
|
||||
|
||||
.locale-line,
|
||||
.ip-line,
|
||||
.ua-line {
|
||||
flex: 1 1 auto;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
white-space: nowrap;
|
||||
}
|
||||
|
||||
.locale-line {
|
||||
text-align: left;
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: 0.3rem;
|
||||
}
|
||||
|
||||
.ip-line {
|
||||
text-align: right;
|
||||
}
|
||||
|
||||
.ua-line {
|
||||
text-align: left;
|
||||
}
|
||||
|
||||
.ua-link {
|
||||
text-decoration: none;
|
||||
font-size: 0.75em;
|
||||
margin-left: 0.2em;
|
||||
vertical-align: middle;
|
||||
}
|
||||
|
||||
.locale-lang {
|
||||
flex: 0 0 auto;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
white-space: nowrap;
|
||||
text-align: right;
|
||||
}
|
||||
|
||||
.city-name {
|
||||
display: inline-block;
|
||||
overflow: hidden;
|
||||
text-overflow: ellipsis;
|
||||
white-space: nowrap;
|
||||
vertical-align: middle;
|
||||
}
|
||||
|
||||
.flag {
|
||||
display: inline-flex;
|
||||
width: 18px;
|
||||
height: 12px;
|
||||
border-radius: 2px;
|
||||
overflow: hidden;
|
||||
border: 1px solid var(--line);
|
||||
box-shadow: 0 0 0 1px rgba(0, 0, 0, 0.2) inset;
|
||||
vertical-align: middle;
|
||||
}
|
||||
|
||||
.flag :deep(svg) {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
display: block;
|
||||
}
|
||||
</style>
|
||||
@@ -0,0 +1,252 @@
|
||||
<script setup>
|
||||
/**
|
||||
* Visitor and page-view smoothed curves for a single shared time range.
|
||||
*/
|
||||
import { computed, onMounted, onUnmounted, ref } from 'vue'
|
||||
import { DAY, WEEK, makeSeries } from './analytics/time.js'
|
||||
import { typicalWeek, weekBinIndex } from './analytics/seasonal.js'
|
||||
import {
|
||||
CHART_H,
|
||||
CHART_W,
|
||||
MARGIN_B,
|
||||
MARGIN_L,
|
||||
VIEW_H,
|
||||
VIEW_W,
|
||||
buildChart,
|
||||
} from './analytics/chart.js'
|
||||
|
||||
const DAY_REFRESH_MS = 15000
|
||||
|
||||
// Keep the whole svg within page bounds: full width below the natural
|
||||
// size, centered with equal side margins above it (max() clamps the
|
||||
// centering margin to 0 at the breakpoint, so the rule is continuous).
|
||||
const CHART_MARGIN = `max(0px, calc(50% - ${VIEW_W / 2}px))`
|
||||
|
||||
const props = defineProps({
|
||||
data: { type: Object, default: null },
|
||||
range: { type: String, required: true },
|
||||
})
|
||||
|
||||
// Views across all pages combined into one raw bucket map.
|
||||
const allViews = computed(() => {
|
||||
const all = {}
|
||||
for (const buckets of Object.values(props.data?.views || {})) {
|
||||
for (const [k, c] of Object.entries(buckets)) all[k] = (all[k] || 0) + c
|
||||
}
|
||||
return all
|
||||
})
|
||||
|
||||
function freqLabel(unit) {
|
||||
return unit === '5min' ? '5 min' : unit === 'hour' ? 'hourly' : 'daily'
|
||||
}
|
||||
|
||||
/** Vertical axis caption: "visits / 5 min" on the day view, else "hourly visits" style. */
|
||||
function axisLabel(unit, ylabel) {
|
||||
return unit === '5min' ? `${ylabel} / 5 min` : `${freqLabel(unit)} ${ylabel}`
|
||||
}
|
||||
|
||||
const now = ref(Date.now())
|
||||
let refreshInterval = null
|
||||
onMounted(() => {
|
||||
refreshInterval = setInterval(() => { now.value = Date.now() }, DAY_REFRESH_MS)
|
||||
})
|
||||
onUnmounted(() => {
|
||||
if (refreshInterval) clearInterval(refreshInterval)
|
||||
})
|
||||
|
||||
/**
|
||||
* Series for the current range plus, on the day and week views, the
|
||||
* seasonal "typical week" history estimate (all history up to now, already
|
||||
* smoothed). Week view: the full Monday-first week. Day view: the rolling
|
||||
* window's bins looked up from the same estimate, labeled by the weekday.
|
||||
* The estimate only appears once the recorded history spans twice the
|
||||
* view's full time — from the third day / third week on.
|
||||
*/
|
||||
function withTypical(buckets) {
|
||||
const input = makeSeries(buckets, props.range)
|
||||
if (props.range !== 'day' && props.range !== 'week') return input
|
||||
const minHistory = props.range === 'week' ? 2 * WEEK : 2 * DAY
|
||||
const estimate = typicalWeek(buckets, now.value, { minHistory })
|
||||
if (!estimate) return input
|
||||
if (props.range === 'week') {
|
||||
return { ...input, typical: { values: [...estimate], label: 'Typical week' } }
|
||||
}
|
||||
const values = input.series[0].points.map((p) => estimate[weekBinIndex(p.t)])
|
||||
const weekday = new Date(now.value).toLocaleDateString(undefined, {
|
||||
weekday: 'long', timeZone: 'UTC',
|
||||
})
|
||||
return { ...input, typical: { values, label: `Typical ${weekday}` } }
|
||||
}
|
||||
|
||||
const visitChart = computed(() => buildChart(withTypical(props.data?.site_visits), now.value))
|
||||
const viewChart = computed(() => buildChart(withTypical(allViews.value), now.value))
|
||||
|
||||
/** The previous week's tail series on the week view, if present. */
|
||||
function pastSeries(chart) {
|
||||
return chart.series.find((s) => s.past)
|
||||
}
|
||||
</script>
|
||||
|
||||
<template>
|
||||
<section v-for="c in [
|
||||
{ ylabel: 'visits', chart: visitChart, legend: true },
|
||||
{ ylabel: 'views', chart: viewChart, legend: false },
|
||||
]" :key="c.ylabel">
|
||||
<template v-if="c.chart">
|
||||
<svg class="chart" :viewBox="`${-MARGIN_L} 0 ${VIEW_W} ${VIEW_H}`"
|
||||
:style="{ maxWidth: `${VIEW_W}px`, marginLeft: CHART_MARGIN }"
|
||||
role="img" :aria-label="axisLabel(c.chart.unit, c.ylabel)">
|
||||
<!-- Clip the plot curves to the chart area; the svg itself is
|
||||
overflow: visible for the axis labels. -->
|
||||
<clipPath :id="`plot-${c.ylabel}`">
|
||||
<rect x="0" y="0" :width="CHART_W" :height="CHART_H" />
|
||||
</clipPath>
|
||||
<line v-for="g in c.chart.majors.slice(1)" :key="'j' + g.value"
|
||||
:x1="0" :x2="CHART_W" :y1="g.y" :y2="g.y" class="major" />
|
||||
<template v-for="t in c.chart.xticks" :key="'t' + t.x">
|
||||
<line v-if="t.line" :x1="t.x" :x2="t.x" :y1="0" :y2="CHART_H"
|
||||
class="minor vertical" />
|
||||
</template>
|
||||
<g :clip-path="`url(#plot-${c.ylabel})`">
|
||||
<!-- The translucent "typical" history fill under the current data. -->
|
||||
<path v-if="c.chart.typical" :d="c.chart.typical.area" class="typical" />
|
||||
<template v-if="c.chart.bars">
|
||||
<rect v-for="(b, i) in c.chart.bars" :key="'b' + i"
|
||||
:x="b.x" :y="b.y" :width="b.width" :height="b.height" class="bar" />
|
||||
<path :d="c.chart.skyline" class="line" />
|
||||
</template>
|
||||
<template v-else>
|
||||
<template v-for="(s, i) in c.chart.series" :key="i">
|
||||
<path v-if="s.area" :d="s.area" class="area" :class="{ past: s.past }" />
|
||||
<path :d="s.line" class="line" :class="{ past: s.past }" />
|
||||
</template>
|
||||
</template>
|
||||
</g>
|
||||
<line :x1="0" :x2="CHART_W" :y1="CHART_H - 0.5" :y2="CHART_H - 0.5"
|
||||
class="axis" />
|
||||
<text v-for="g in c.chart.majors" :key="'y' + g.value" x="-5" :y="g.y"
|
||||
text-anchor="end" dominant-baseline="middle" class="ylab">{{ g.label }}</text>
|
||||
<text :x="-(MARGIN_L - 10)" :y="CHART_H / 2" text-anchor="middle"
|
||||
:transform="`rotate(-90 ${-(MARGIN_L - 10)} ${CHART_H / 2})`"
|
||||
class="yaxis-label">{{ axisLabel(c.chart.unit, c.ylabel) }}</text>
|
||||
<text v-for="t in c.chart.xticks" :key="'x' + t.x" :x="t.x" :y="CHART_H + MARGIN_B - 8"
|
||||
text-anchor="middle" class="xlab">{{ t.label }}</text>
|
||||
<!-- Legend, top right inside the plot: current data in accent
|
||||
(week label, or "Last 24 hours" on the day view), the previous
|
||||
week's tail in the secondary accent (week view only), then the
|
||||
typical history fill as a muted specimen. -->
|
||||
<g v-if="c.legend && (c.chart.typical || pastSeries(c.chart))">
|
||||
<line :x1="CHART_W - 118" :x2="CHART_W - 98" y1="10" y2="10" class="line" />
|
||||
<text :x="CHART_W - 92" y="10" dominant-baseline="middle"
|
||||
class="leglab">{{ c.chart.bars ? 'Last 24 hours' : c.chart.series[0].label }}</text>
|
||||
<template v-if="pastSeries(c.chart)">
|
||||
<line :x1="CHART_W - 118" :x2="CHART_W - 98" y1="25" y2="25"
|
||||
class="line past" />
|
||||
<text :x="CHART_W - 92" y="25" dominant-baseline="middle"
|
||||
class="leglab">{{ pastSeries(c.chart).label }}</text>
|
||||
</template>
|
||||
<template v-if="c.chart.typical">
|
||||
<rect :x="CHART_W - 118" :y="pastSeries(c.chart) ? 34 : 19"
|
||||
width="20" height="12" class="typical" />
|
||||
<text :x="CHART_W - 92" :y="pastSeries(c.chart) ? 40 : 25"
|
||||
dominant-baseline="middle"
|
||||
class="leglab">{{ c.chart.typical.label }}</text>
|
||||
</template>
|
||||
</g>
|
||||
</svg>
|
||||
</template>
|
||||
</section>
|
||||
</template>
|
||||
|
||||
<style scoped>
|
||||
/* Each chart is a self-contained SVG: the viewBox includes the axis label
|
||||
margins, so nothing is positioned with HTML overlays. Never upscale past
|
||||
the natural size (1 viewBox unit = 1 px, max-width set inline) — that
|
||||
would blow up the constant-size text; smaller panels still scale the
|
||||
chart down to fit. The margin-left (set inline) centers the chart above
|
||||
its natural width; the svg always stays within page bounds.
|
||||
overflow: visible lets wider fonts extend past the viewBox instead of
|
||||
clipping. */
|
||||
.chart {
|
||||
display: block;
|
||||
width: 100%;
|
||||
height: auto;
|
||||
overflow: visible;
|
||||
}
|
||||
|
||||
.chart .ylab,
|
||||
.chart .xlab,
|
||||
.chart .yaxis-label,
|
||||
.chart .leglab {
|
||||
font-family: system-ui, sans-serif; /* theme fonts can be overly styled */
|
||||
font-size: 11px;
|
||||
fill: var(--muted);
|
||||
}
|
||||
|
||||
.chart .ylab {
|
||||
font-variant-numeric: tabular-nums;
|
||||
}
|
||||
|
||||
.chart .minor {
|
||||
stroke: var(--line);
|
||||
stroke-width: 1;
|
||||
vector-effect: non-scaling-stroke;
|
||||
opacity: 0.35;
|
||||
}
|
||||
|
||||
.chart .minor.vertical {
|
||||
opacity: 0.25;
|
||||
}
|
||||
|
||||
.chart .major {
|
||||
stroke: var(--line);
|
||||
stroke-width: 1;
|
||||
vector-effect: non-scaling-stroke;
|
||||
stroke-dasharray: 3 4;
|
||||
opacity: 0.8;
|
||||
}
|
||||
|
||||
.chart .axis {
|
||||
stroke: var(--line);
|
||||
stroke-width: 1;
|
||||
vector-effect: non-scaling-stroke;
|
||||
}
|
||||
|
||||
.chart .area {
|
||||
fill: var(--accent);
|
||||
opacity: 0.6;
|
||||
}
|
||||
|
||||
.chart .bar {
|
||||
fill: var(--accent);
|
||||
opacity: 0.6;
|
||||
}
|
||||
|
||||
.chart .line {
|
||||
fill: none;
|
||||
stroke: var(--accent);
|
||||
stroke-width: 2;
|
||||
vector-effect: non-scaling-stroke;
|
||||
stroke-linejoin: round;
|
||||
stroke-linecap: round;
|
||||
}
|
||||
|
||||
/* The seasonal "typical" estimate is a muted fill under the current data,
|
||||
translucent to the same degree, no stroke. */
|
||||
.chart .typical {
|
||||
fill: var(--muted);
|
||||
opacity: 0.6;
|
||||
}
|
||||
|
||||
/* The previous week's tail on the week view uses the secondary accent so
|
||||
only the typical fill is grey. */
|
||||
.chart .line.past {
|
||||
stroke: var(--accent2);
|
||||
}
|
||||
|
||||
.chart .area.past {
|
||||
fill: var(--accent2);
|
||||
}
|
||||
|
||||
.empty { color: var(--muted); }
|
||||
</style>
|
||||
@@ -0,0 +1,30 @@
|
||||
// Analytics page entry: mounts AnalyticsView inside the normal page layout.
|
||||
// In production the backend inlines this module into the /_a page (and
|
||||
// pagerite.js re-creates the script element after fetch-navigations there);
|
||||
// in dev pagerite.js imports it from the Vite dev server on demand. Either
|
||||
// way it auto-mounts on #analytics-app when it evaluates, and unmounts when
|
||||
// pagerite.js announces a swap away from /_a.
|
||||
import { createApp } from 'vue'
|
||||
import AnalyticsView from './AnalyticsView.vue'
|
||||
|
||||
let app = null
|
||||
|
||||
export function mount(container) {
|
||||
if (app) return
|
||||
app = createApp(AnalyticsView)
|
||||
app.mount(container)
|
||||
}
|
||||
|
||||
export function unmount() {
|
||||
app?.unmount()
|
||||
app = null
|
||||
}
|
||||
|
||||
// pagerite.js calls this before swapping away from /_a; each evaluation
|
||||
// (the inlined production module evaluates fresh on every visit) replaces
|
||||
// the handle.
|
||||
window.__pageriteAnalyticsUnmount = unmount
|
||||
|
||||
// Auto-mount when the page holding #analytics-app is present.
|
||||
const container = document.getElementById('analytics-app')
|
||||
if (container) mount(container)
|
||||
@@ -0,0 +1,420 @@
|
||||
/**
|
||||
* Chart geometry, smoothing, and SVG path generation for analytics charts.
|
||||
*
|
||||
* Fixed 720x180 plot area inside a larger viewBox that also holds the axis
|
||||
* labels, so each chart SVG is self-contained; values are per-unit rates
|
||||
* (hour on the week view, day on month+).
|
||||
*/
|
||||
|
||||
import { DAY, HOUR, MIN5, WEEK, mondayUTC } from './time.js'
|
||||
import { formatCount } from './format.js'
|
||||
|
||||
export const CHART_W = 1000
|
||||
export const CHART_H = 150
|
||||
export const PAD_TOP = 14 // room above the highest point
|
||||
export const MARGIN_L = 40 // y tick labels + vertical axis label
|
||||
export const MARGIN_B = 24 // x tick labels
|
||||
export const VIEW_W = MARGIN_L + CHART_W + 8
|
||||
export const VIEW_H = CHART_H + MARGIN_B
|
||||
|
||||
/**
|
||||
* Y always starts at 0; the max is a multiple of a 1-2-5 major step with at
|
||||
* most 5 intervals, so labeled ticks are always round and evenly divided.
|
||||
* A minimum range of 10 keeps tiny near-zero values (e.g. a single visit)
|
||||
* from being enlarged to a fractional scale; minor lines subdivide each
|
||||
* major step in five when that yields integers.
|
||||
*/
|
||||
export function yScale(maxValue) {
|
||||
let step = 1
|
||||
outer: for (let exp = -3; exp < 8; exp++) {
|
||||
for (const base of [1, 2, 5]) {
|
||||
step = base * 10 ** exp
|
||||
if (Math.ceil(maxValue / step) <= 5) break outer
|
||||
}
|
||||
}
|
||||
let max = Math.ceil(maxValue / step) * step
|
||||
if (max < 10) {
|
||||
max = 10
|
||||
step = 2
|
||||
}
|
||||
const minor = step >= 5 && step % 5 === 0 ? step / 5 : null
|
||||
return { max, step, minor }
|
||||
}
|
||||
|
||||
/**
|
||||
* Edge-aware Gaussian smoothing with a fixed bandwidth. A change-point
|
||||
* detector first finds traffic-level shifts (two-unit totals compared on
|
||||
* both sides of each bucket; strong ratio + significance marks a candidate,
|
||||
* and each run of candidates keeps only its best-scoring bucket as an
|
||||
* edge). Each edge-delimited segment is then smoothed independently: every
|
||||
* bucket spreads its count with a fixed Gaussian sigma chosen so N events
|
||||
* in a single bucket peak at N events per unit. Mass past a detected change
|
||||
* point is dropped (kernel renormalized); mass past a true series edge is
|
||||
* mirrored back, so the curve doesn't fall where data simply ends. Either
|
||||
* way total visitor count is preserved exactly. The unit is
|
||||
* one hour on the week view and one day on the month+ views, so the
|
||||
* smoothing time scale follows the range. The raw series is drawn faintly
|
||||
* behind the curve for reference. Operates on raw counts.
|
||||
*/
|
||||
export function smooth(counts, binMinutes, unitMinutes, {
|
||||
detectorWindowMinutes = 2 * unitMinutes,
|
||||
// Count thresholds are defined per hour and scale with the unit, so
|
||||
// "low traffic" means the same thing on hourly and daily views
|
||||
// (5-20 events/hour = 120-480/day on the month+ ranges).
|
||||
highTrafficEvents = 10 * unitMinutes / 60,
|
||||
minRatio = 2.5,
|
||||
minSignificance = 4,
|
||||
} = {}) {
|
||||
const n = counts.length
|
||||
if (!n) return counts
|
||||
const detectorWindowBins = Math.max(1, Math.round(detectorWindowMinutes / binMinutes))
|
||||
|
||||
const cumsum = new Float64Array(n + 1)
|
||||
for (let i = 0; i < n; i++) cumsum[i + 1] = cumsum[i] + counts[i]
|
||||
|
||||
// Detect abrupt regime changes from aggregated traffic on both sides.
|
||||
// Individual bins are deliberately ignored because even high traffic
|
||||
// produces many 0-1 count bins at five-minute resolution.
|
||||
const score = new Float64Array(n)
|
||||
const candidate = new Uint8Array(n)
|
||||
for (let i = detectorWindowBins; i < n - detectorWindowBins; i++) {
|
||||
const left = cumsum[i] - cumsum[i - detectorWindowBins]
|
||||
const right = cumsum[i + detectorWindowBins] - cumsum[i]
|
||||
const high = Math.max(left, right)
|
||||
const low = Math.min(left, right)
|
||||
if (high < highTrafficEvents) continue
|
||||
const ratio = (high + 1) / (low + 1)
|
||||
const significance = (high - low) / Math.sqrt(high + low + 1)
|
||||
if (ratio >= minRatio && significance >= minSignificance) {
|
||||
candidate[i] = 1
|
||||
score[i] = significance * Math.log(ratio)
|
||||
}
|
||||
}
|
||||
|
||||
// Collapse each continuous detector region to its strongest boundary.
|
||||
const edges = []
|
||||
for (let i = 0; i < n;) {
|
||||
if (!candidate[i]) { i++; continue }
|
||||
let j = i + 1
|
||||
while (j < n && candidate[j]) j++
|
||||
let best = i
|
||||
for (let k = i + 1; k < j; k++) {
|
||||
if (score[k] > score[best]) best = k
|
||||
}
|
||||
edges.push(best)
|
||||
i = j
|
||||
}
|
||||
|
||||
// Fixed sigma: N events in one bucket peak at N events per unit.
|
||||
// sigma_bins * sqrt(2*pi) = rate = unitMinutes / binMinutes.
|
||||
const sigmaBins = unitMinutes / (binMinutes * Math.sqrt(2 * Math.PI))
|
||||
const radius = Math.ceil(4 * sigmaBins)
|
||||
|
||||
// Process each discontinuity-delimited regime independently so the
|
||||
// Gaussian cannot see through a detected boundary. Each input bin spreads
|
||||
// its count with the fixed sigma. Mass that would fall past a detected
|
||||
// change point is dropped and the kernel renormalized; mass that would
|
||||
// fall past a true series edge (first/last bin) is mirrored back into the
|
||||
// segment, as if the data continued as its own reflection, so constant or
|
||||
// rising data doesn't produce a spurious falling edge. Total visitor count
|
||||
// is preserved apart from floating-point error.
|
||||
const bounds = [0, ...edges, n]
|
||||
const smoothed = new Float64Array(n)
|
||||
for (let b = 0; b < bounds.length - 1; b++) {
|
||||
const lo = bounds[b]
|
||||
const length = bounds[b + 1] - lo
|
||||
const mirrorLeft = lo === 0
|
||||
const mirrorRight = lo + length === n
|
||||
const segment = counts.slice(lo, lo + length)
|
||||
for (let j = 0; j < length; j++) {
|
||||
const count = segment[j]
|
||||
if (!count) continue
|
||||
// Collect (target bin, weight) pairs over the full kernel, folding
|
||||
// mirrored mass at series edges and dropping mass past change points.
|
||||
const spread = new Map()
|
||||
let weightSum = 0
|
||||
for (let i = j - radius; i <= j + radius; i++) {
|
||||
let k = i
|
||||
// Fold repeatedly for segments shorter than the kernel radius.
|
||||
while (k < 0 || k >= length) {
|
||||
if (k < 0 && mirrorLeft) k = -k - 1
|
||||
else if (k >= length && mirrorRight) k = 2 * length - 1 - k
|
||||
else { k = null; break }
|
||||
}
|
||||
if (k === null) continue
|
||||
const w = Math.exp(-0.5 * ((i - j) / sigmaBins) ** 2)
|
||||
spread.set(k, (spread.get(k) || 0) + w)
|
||||
weightSum += w
|
||||
}
|
||||
for (const [k, w] of spread) {
|
||||
smoothed[lo + k] += count * w / weightSum
|
||||
}
|
||||
}
|
||||
}
|
||||
return [...smoothed]
|
||||
}
|
||||
|
||||
/**
|
||||
* Catmull-Rom spline through the (smoothed) points, control points clamped
|
||||
* to the plot area so the curve can never dip below zero or above the max.
|
||||
*/
|
||||
export function spline(pts) {
|
||||
if (pts.length < 3) {
|
||||
return `M${pts.map((p) => `${p.x},${p.y}`).join('L')}`
|
||||
}
|
||||
const clampY = (y) => Math.min(CHART_H, Math.max(PAD_TOP, y))
|
||||
let d = `M${pts[0].x},${pts[0].y}`
|
||||
for (let i = 0; i < pts.length - 1; i++) {
|
||||
const p0 = pts[i - 1] || pts[i]
|
||||
const p1 = pts[i]
|
||||
const p2 = pts[i + 1]
|
||||
const p3 = pts[i + 2] || p2
|
||||
const c1y = clampY(p1.y + (p2.y - p0.y) / 6)
|
||||
const c2y = clampY(p2.y - (p3.y - p1.y) / 6)
|
||||
d += `C${p1.x + (p2.x - p0.x) / 6},${c1y} `
|
||||
+ `${p2.x - (p3.x - p1.x) / 6},${c2y} ${p2.x},${p2.y}`
|
||||
}
|
||||
return d
|
||||
}
|
||||
|
||||
/** Build a full chart model from a series descriptor produced by time.js. */
|
||||
export function buildChart(input, now = Date.now()) {
|
||||
if (!input || !input.series.length) return null
|
||||
if (input.unit === '5min') return buildDayChart(input, now)
|
||||
const { series, t0, t1, rate, binMinutes, unitMinutes, unit, typical } = input
|
||||
// Values are per-unit rates (hour on the week view, day on month+); the
|
||||
// y max is derived from the *smoothed* curves so random single-bucket
|
||||
// spikes don't blow up the scale. Smoothing works on raw counts (its edge
|
||||
// detector thresholds are count-based), the result is scaled back to rates.
|
||||
const smoothed = series.map((s) =>
|
||||
smooth(s.points.map((p) => p.count), binMinutes, unitMinutes).map((v) => v * rate))
|
||||
// The "typical week" seasonal estimate is already smooth: one value per
|
||||
// bin spanning the full week (future included), drawn as a translucent
|
||||
// muted fill under the current data.
|
||||
const typicalRates = typical
|
||||
? [...typical.values].map((v) => v * rate)
|
||||
: null
|
||||
// Scale from the current series plus the typical curve; both are smooth,
|
||||
// and neither should be clipped in normal traffic.
|
||||
const highest = Math.max(0, ...smoothed.flat(), ...(typicalRates || []))
|
||||
const { max, step, minor } = yScale(highest)
|
||||
const x = (t) => ((t - t0) / (t1 - t0)) * CHART_W
|
||||
const y = (v) => PAD_TOP + (1 - Math.max(0, v) / max) * (CHART_H - PAD_TOP)
|
||||
const drawn = series.map((s, si) => {
|
||||
const pts = s.points.map((p, i) => ({ x: x(p.t), y: y(smoothed[si][i]) }))
|
||||
const line = spline(pts)
|
||||
const first = pts[0]
|
||||
const last = pts.at(-1)
|
||||
return {
|
||||
...s,
|
||||
line,
|
||||
area: s.area ? `${line}L${last.x},${CHART_H}L${first.x},${CHART_H}Z` : null,
|
||||
}
|
||||
})
|
||||
let typicalFill = null
|
||||
if (typicalRates) {
|
||||
const binMs = (t1 - t0) / typicalRates.length
|
||||
const pts = typicalRates.map((v, i) => ({ x: x(t0 + i * binMs), y: y(v) }))
|
||||
const line = spline(pts)
|
||||
typicalFill = {
|
||||
area: `${line}L${pts.at(-1).x},${CHART_H}L${pts[0].x},${CHART_H}Z`,
|
||||
label: typical.label,
|
||||
}
|
||||
}
|
||||
// Major (labeled) and minor (hairline) y grid ticks.
|
||||
const majors = []
|
||||
const minors = []
|
||||
const nMajor = Math.round(max / step)
|
||||
for (let k = 0; k <= nMajor; k++) {
|
||||
const v = k * step
|
||||
majors.push({ value: v, y: y(v), label: fmtY(v) })
|
||||
}
|
||||
if (minor) {
|
||||
for (let v = minor; v < max; v += minor) {
|
||||
if (v % step !== 0) minors.push({ y: y(v) })
|
||||
}
|
||||
}
|
||||
// X ticks. Week view: weekday labels centered at midday UTC, no vertical
|
||||
// lines (day boundaries would be misleading in the viewer's timezone).
|
||||
// Month view: likewise lineless, day numbers at noon UTC with the month
|
||||
// name substituted for the 1st (marking the month change). Longer
|
||||
// ranges: boundary lines at Mondays / months / years.
|
||||
const isWeek = t1 - t0 === WEEK
|
||||
const isMonth = !isWeek && t1 - t0 <= 31 * DAY
|
||||
let xticks
|
||||
if (isWeek) {
|
||||
xticks = Array.from({ length: 7 }, (_, d) => {
|
||||
const t = t0 + d * DAY + 12 * HOUR
|
||||
return {
|
||||
x: x(t),
|
||||
label: new Date(t).toLocaleDateString(undefined, {
|
||||
weekday: 'short', timeZone: 'UTC',
|
||||
}),
|
||||
line: false,
|
||||
}
|
||||
})
|
||||
} else if (isMonth) {
|
||||
// t0 is day-aligned; label every day whose noon falls inside the range.
|
||||
xticks = []
|
||||
for (let day = t0; day + 12 * HOUR < t1; day += DAY) {
|
||||
const date = new Date(day)
|
||||
const t = day + 12 * HOUR
|
||||
xticks.push({
|
||||
x: x(t),
|
||||
label: date.getUTCDate() === 1
|
||||
? date.toLocaleDateString(undefined, { month: 'short', timeZone: 'UTC' })
|
||||
: String(date.getUTCDate()),
|
||||
line: false,
|
||||
})
|
||||
}
|
||||
} else {
|
||||
xticks = xticksFor(t0, t1).map((t) => ({
|
||||
x: x(t), label: fmtTick(t, t1 - t0), line: true,
|
||||
}))
|
||||
}
|
||||
return { max, majors, minors, series: drawn, typical: typicalFill, xticks, unit }
|
||||
}
|
||||
|
||||
/**
|
||||
* Day view: 5-minute bars for the last 24 hours. Bars are drawn at raw
|
||||
* counts; the skyline uses a projected full-bucket value for the still-open
|
||||
* final bucket. The y scale is derived from the projected skyline maximum.
|
||||
* The optional "typical day" curve (per-bin counts aligned to the window's
|
||||
* bins, cut from the typical-week estimate) underlays the bars as a
|
||||
* translucent muted fill and also feeds the y scale.
|
||||
*/
|
||||
export function buildDayChart(input, now = Date.now()) {
|
||||
const { series, t0, t1, typical } = input
|
||||
const points = series[0]?.points || []
|
||||
const n = points.length
|
||||
if (!n) return null
|
||||
const bucketMs = (t1 - t0) / n
|
||||
const bucketWidth = CHART_W / n
|
||||
const gap = 0.2
|
||||
const barWidth = Math.max(0.2, bucketWidth - gap)
|
||||
|
||||
const x = (i) => i * bucketWidth + gap / 2
|
||||
const prevRaw = n > 1 ? points[n - 2].count : 0
|
||||
const projected = points.map((p, i) => {
|
||||
if (i !== n - 1) return p.count
|
||||
const bucketStart = t0 + i * bucketMs
|
||||
const elapsed = Math.max(1, Math.min(bucketMs, now - bucketStart))
|
||||
// Blend the observed partial bucket with the previous full bucket:
|
||||
// the longer the current bucket has run, the less we borrow from it.
|
||||
const share = elapsed / bucketMs
|
||||
return p.count + prevRaw * (1 - share)
|
||||
})
|
||||
const highest = Math.max(0, ...projected, ...(typical ? typical.values : []))
|
||||
const { max, step, minor } = yScale(highest)
|
||||
const y = (v) => PAD_TOP + (1 - Math.max(0, v) / max) * (CHART_H - PAD_TOP)
|
||||
|
||||
const bars = points.map((p, i) => {
|
||||
const bx = x(i)
|
||||
const by = y(p.count)
|
||||
return {
|
||||
x: bx,
|
||||
y: by,
|
||||
width: barWidth,
|
||||
height: CHART_H - by,
|
||||
raw: p.count,
|
||||
projected: projected[i],
|
||||
}
|
||||
})
|
||||
|
||||
let skyline = ''
|
||||
for (let i = 0; i < bars.length; i++) {
|
||||
const b = bars[i]
|
||||
const top = y(b.projected)
|
||||
if (i === 0) {
|
||||
skyline += `M${b.x},${top} H${b.x + b.width}`
|
||||
} else {
|
||||
skyline += ` V${top} H${b.x + b.width}`
|
||||
}
|
||||
}
|
||||
|
||||
let typicalFill = null
|
||||
if (typical) {
|
||||
const pts = points.map((p, i) => ({
|
||||
x: (i + 0.5) * bucketWidth,
|
||||
y: y(typical.values[i] || 0),
|
||||
}))
|
||||
const line = spline(pts)
|
||||
typicalFill = {
|
||||
area: `${line}L${pts.at(-1).x},${CHART_H}L${pts[0].x},${CHART_H}Z`,
|
||||
label: typical.label,
|
||||
}
|
||||
}
|
||||
|
||||
const majors = []
|
||||
const minors = []
|
||||
const nMajor = Math.round(max / step)
|
||||
for (let k = 0; k <= nMajor; k++) {
|
||||
const v = k * step
|
||||
majors.push({ value: v, y: y(v), label: fmtY(v) })
|
||||
}
|
||||
if (minor) {
|
||||
for (let v = minor; v < max; v += minor) {
|
||||
if (v % step !== 0) minors.push({ y: y(v) })
|
||||
}
|
||||
}
|
||||
|
||||
const xticks = []
|
||||
const tickStep = 3 * HOUR
|
||||
const firstTick = Math.ceil(t0 / tickStep) * tickStep
|
||||
for (let t = firstTick; t < t1; t += tickStep) {
|
||||
if (t < t0) continue
|
||||
const d = new Date(t)
|
||||
xticks.push({
|
||||
x: ((t - t0) / (t1 - t0)) * CHART_W,
|
||||
label: `${String(d.getUTCHours()).padStart(2, '0')}:00`,
|
||||
line: false,
|
||||
})
|
||||
}
|
||||
return { bars, skyline: skyline.trim(), typical: typicalFill, max, majors, minors, xticks, unit: '5min', series: [] }
|
||||
}
|
||||
|
||||
/** X ticks for year/all: Monday boundaries up to a quarter, UTC month
|
||||
* boundaries up to a few years, then years. */
|
||||
export function xticksFor(t0, t1) {
|
||||
const span = t1 - t0
|
||||
const ticks = []
|
||||
if (span <= 100 * DAY) {
|
||||
for (let t = mondayUTC(t0); t <= t1; t += WEEK) {
|
||||
if (t >= t0) ticks.push(t)
|
||||
}
|
||||
return ticks
|
||||
}
|
||||
if (span <= 4 * 365 * DAY) {
|
||||
const d = new Date(t0)
|
||||
let t = Date.UTC(d.getUTCFullYear(), d.getUTCMonth() + 1, 1)
|
||||
for (; t <= t1;) {
|
||||
ticks.push(t)
|
||||
const m = new Date(t)
|
||||
t = Date.UTC(m.getUTCFullYear(), m.getUTCMonth() + 1, 1)
|
||||
}
|
||||
return ticks
|
||||
}
|
||||
const d = new Date(t0)
|
||||
for (let yr = d.getUTCFullYear() + 1; Date.UTC(yr, 0, 1) <= t1; yr++) {
|
||||
ticks.push(Date.UTC(yr, 0, 1))
|
||||
}
|
||||
return ticks
|
||||
}
|
||||
|
||||
export function fmtTick(t, span) {
|
||||
const d = new Date(t)
|
||||
if (span <= 100 * DAY) {
|
||||
return d.toLocaleDateString(undefined, { month: 'short', day: 'numeric', timeZone: 'UTC' })
|
||||
}
|
||||
if (span <= 4 * 365 * DAY) {
|
||||
return d.getUTCMonth() === 0
|
||||
? d.toLocaleDateString(undefined, { year: 'numeric', timeZone: 'UTC' })
|
||||
: d.toLocaleDateString(undefined, { month: 'short', timeZone: 'UTC' })
|
||||
}
|
||||
return d.toLocaleDateString(undefined, { year: 'numeric', timeZone: 'UTC' })
|
||||
}
|
||||
|
||||
/** Y labels use the same compact formatter as text labels. */
|
||||
export function fmtY(v) {
|
||||
return formatCount(v)
|
||||
}
|
||||
@@ -0,0 +1,719 @@
|
||||
/**
|
||||
* Formatters and aggregators for summary sections: totals and the recent
|
||||
* visit trail.
|
||||
*/
|
||||
import { flagFor, langName } from '../langs.js'
|
||||
|
||||
/**
|
||||
* IPv4 unchanged, IPv6 returns the /64 network prefix in compact form.
|
||||
* Falls back to the original value when parsing fails.
|
||||
*/
|
||||
export const hostIP = (ip) => {
|
||||
try {
|
||||
if (!ip || !ip.includes(':')) return ip
|
||||
const strip = (s) => s.replace(/^\[|\]$/g, '')
|
||||
const norm = strip(new URL(`http://[${ip}]/`).hostname)
|
||||
const [l, r] = norm.split('::').map((s) => (s ? s.split(':') : []))
|
||||
const full = r
|
||||
? [...l, ...Array(8 - l.length - r.length).fill('0'), ...r]
|
||||
: l
|
||||
return strip(
|
||||
new URL(`http://[${full.slice(0, 4).join(':')}::]/`).hostname,
|
||||
).replace(/::$/, '')
|
||||
} catch (e) {
|
||||
console.error('hostIP processing failed for:', ip, e)
|
||||
return ip
|
||||
}
|
||||
}
|
||||
|
||||
function showCopiedFeedback(el, event) {
|
||||
if (typeof document === 'undefined') return
|
||||
const popup = document.createElement('span')
|
||||
popup.textContent = 'Copied!'
|
||||
popup.className = 'copy-popup'
|
||||
// Fixed to the viewport at the click point: table cells clip absolute
|
||||
// popups with their overflow: hidden ellipsis styling.
|
||||
const x = event?.clientX ?? 0
|
||||
const y = event?.clientY ?? 0
|
||||
popup.style.cssText =
|
||||
`position:fixed;left:${x}px;top:${y}px;` +
|
||||
'transform:translate(-50%, calc(-100% - 0.5rem));padding:0.15rem 0.4rem;' +
|
||||
'background:var(--text, CanvasText);color:var(--bg, Canvas);' +
|
||||
'border-radius:0.25rem;font-size:0.75rem;white-space:nowrap;' +
|
||||
'pointer-events:none;z-index:100;'
|
||||
document.body.appendChild(popup)
|
||||
setTimeout(() => popup.remove(), 1200)
|
||||
}
|
||||
|
||||
/** Copy the full IP to the clipboard and show a brief "Copied!" popup. */
|
||||
export async function copyIp(ip, event) {
|
||||
if (!ip) return
|
||||
try {
|
||||
await navigator.clipboard.writeText(ip)
|
||||
showCopiedFeedback(event?.currentTarget, event)
|
||||
} catch {
|
||||
/* ignore */
|
||||
}
|
||||
}
|
||||
|
||||
/** Copy arbitrary text to the clipboard and show a brief "Copied!" popup. */
|
||||
export async function copyList(text, event) {
|
||||
if (!text) return
|
||||
try {
|
||||
await navigator.clipboard.writeText(text)
|
||||
showCopiedFeedback(event?.currentTarget, event)
|
||||
} catch {
|
||||
/* ignore */
|
||||
}
|
||||
}
|
||||
|
||||
/** Total page views across every page and every bucket. */
|
||||
export function calcTotalViews(views) {
|
||||
let n = 0
|
||||
for (const buckets of Object.values(views || {})) {
|
||||
for (const c of Object.values(buckets)) n += c
|
||||
}
|
||||
return n
|
||||
}
|
||||
|
||||
// Very short reads are navigation/skims, not real reading time.
|
||||
export const MIN_READ_SECONDS = 10
|
||||
|
||||
/** path -> accumulated read seconds for a visit, derived from its trail. */
|
||||
export function readMapOf(v) {
|
||||
const map = {}
|
||||
for (const item of Object.values(v.trail || {})) {
|
||||
if (item.read) map[item.to] = (map[item.to] || 0) + item.read
|
||||
}
|
||||
return map
|
||||
}
|
||||
|
||||
/** Average minutes per visit and average of per-article median read minutes. */
|
||||
export function calcReadStats(visits) {
|
||||
const perArticle = {}
|
||||
let totalVisitSeconds = 0
|
||||
let visitCount = 0
|
||||
for (const v of visits || []) {
|
||||
const read = readMapOf(v)
|
||||
const secs = Object.values(read).filter((s) => s >= MIN_READ_SECONDS)
|
||||
if (!secs.length) continue
|
||||
visitCount++
|
||||
totalVisitSeconds += secs.reduce((a, b) => a + b, 0)
|
||||
for (const [path, s] of Object.entries(read)) {
|
||||
if (s >= MIN_READ_SECONDS) {
|
||||
; (perArticle[path] || (perArticle[path] = [])).push(s)
|
||||
}
|
||||
}
|
||||
}
|
||||
const avgMinPerVisit = visitCount
|
||||
? Math.max(1, Math.round(totalVisitSeconds / visitCount / 60))
|
||||
: 0
|
||||
|
||||
let articleMedianSum = 0
|
||||
const articleCount = Object.keys(perArticle).length
|
||||
for (const arr of Object.values(perArticle)) {
|
||||
arr.sort((a, b) => a - b)
|
||||
const mid = Math.floor(arr.length / 2)
|
||||
const median = arr.length % 2 ? arr[mid] : (arr[mid - 1] + arr[mid]) / 2
|
||||
articleMedianSum += Math.max(MIN_READ_SECONDS, median)
|
||||
}
|
||||
const avgArticleMedianMin = articleCount
|
||||
? Math.max(1, Math.round(articleMedianSum / articleCount / 60))
|
||||
: 0
|
||||
|
||||
return { avgMinPerVisit, avgArticleMedianMin }
|
||||
}
|
||||
|
||||
/** Build a path -> page title lookup from the site tree. */
|
||||
function buildTitleMap(pageTree) {
|
||||
const titles = new Map()
|
||||
const walk = (items) => {
|
||||
for (const item of items || []) {
|
||||
titles.set(`/${item.path}`, item.title)
|
||||
walk(item.children)
|
||||
}
|
||||
}
|
||||
walk(pageTree)
|
||||
return titles
|
||||
}
|
||||
|
||||
/** Last path segment for display; front page becomes a house icon. */
|
||||
function slugOf(path) {
|
||||
return path === '/' ? '🏠︎' : path.split('/').pop()
|
||||
}
|
||||
|
||||
/** Host name of an external https origin, with scheme and www. stripped. */
|
||||
function externalSlug(origin) {
|
||||
try {
|
||||
return new URL(origin).host.replace(/^www\./, '')
|
||||
} catch {
|
||||
return origin.replace(/^https?:\/\//, '').replace(/^www\./, '')
|
||||
}
|
||||
}
|
||||
|
||||
/** Origin (scheme://host) of an external https URL, for favicon lookup. */
|
||||
function externalOrigin(url) {
|
||||
try {
|
||||
return new URL(url).origin
|
||||
} catch {
|
||||
return ''
|
||||
}
|
||||
}
|
||||
|
||||
// Non-article machinery paths shown in trails with an emoji marker:
|
||||
// recorded like page GETs but fetched by crawlers/feed readers, so they
|
||||
// surface in the crawler rows. Feed paths are pre-registered for the
|
||||
// future RSS/Atom routes.
|
||||
const MACHINE_STEPS = {
|
||||
'/robots.txt': ['🤖', 'robots.txt'],
|
||||
'/sitemap.xml': ['🗺️', 'sitemap.xml'],
|
||||
'/llms.txt': ['🧠', 'llms.txt'],
|
||||
'/feed.json': ['📡', 'feed.json'],
|
||||
'/feed.xml': ['📡', 'feed.xml'],
|
||||
'/rss.xml': ['📡', 'rss.xml'],
|
||||
'/atom.xml': ['📡', 'atom.xml'],
|
||||
'/feed': ['📡', 'feed'],
|
||||
}
|
||||
|
||||
/** Format one trail step: an internal page or an external https origin. */
|
||||
function stepOf(path, titles) {
|
||||
if (path?.startsWith('/')) {
|
||||
// Known non-article machinery GETs (fetched by crawlers and feed
|
||||
// readers, recorded like page GETs): emoji-marked so they stand out
|
||||
// from article steps in the trails.
|
||||
const machine = MACHINE_STEPS[path]
|
||||
if (machine) {
|
||||
const [emoji, name] = machine
|
||||
return { path, slug: `${emoji} ${name}`, title: name, external: false, machine: true }
|
||||
}
|
||||
return { path, slug: slugOf(path), title: titles.get(path) || '', external: false, home: path === '/' }
|
||||
}
|
||||
if (path?.startsWith('https://')) {
|
||||
return {
|
||||
path,
|
||||
slug: externalSlug(path),
|
||||
title: 'External site',
|
||||
external: true,
|
||||
origin: externalOrigin(path),
|
||||
}
|
||||
}
|
||||
return null
|
||||
}
|
||||
|
||||
/**
|
||||
* Badge data combining a visit's/crawler's external referer origin with the
|
||||
* visit's UTM tags: the origin as the badge link/label (the favicon is
|
||||
* looked up by origin in the component), a compact UTM summary (the few
|
||||
* most informative values) as ``utm`` with the full ``utm_*=value`` list
|
||||
* as ``utmCopy`` for click-to-copy, and a one-fact-per-line tooltip — the
|
||||
* full origin URL on the first line, then every ``utm_*=value`` pair.
|
||||
* Null when there is no external referer and no UTM tag (a plain direct
|
||||
* visit).
|
||||
*/
|
||||
function refererBadgeOf(referer, titles, utmTags = {}) {
|
||||
const step = stepOf(referer, titles)
|
||||
const external = step?.external ? step : null
|
||||
// Compact UTM summary, in display order source, campaign, content, term:
|
||||
// source only when no referer is known (it just repeats where the visitor
|
||||
// came from), content only as a stand-in when there is no term. The
|
||||
// remaining tags (medium and any nonstandard utm_*) fill in only when
|
||||
// fewer than three of these more useful items exist — and never when a
|
||||
// term is present (the term alone says enough). The tooltip keeps
|
||||
// every tag, one pair per line.
|
||||
const useful = []
|
||||
if (utmTags.utm_source && !referer) useful.push(utmTags.utm_source)
|
||||
if (utmTags.utm_campaign) useful.push(utmTags.utm_campaign)
|
||||
if (utmTags.utm_content && !utmTags.utm_term) useful.push(utmTags.utm_content)
|
||||
if (utmTags.utm_term) useful.push(utmTags.utm_term)
|
||||
const rest = useful.length < 3 && !utmTags.utm_term
|
||||
? Object.keys(utmTags)
|
||||
.filter((k) => !['utm_source', 'utm_campaign', 'utm_content', 'utm_term'].includes(k))
|
||||
.map((k) => utmTags[k])
|
||||
.filter(Boolean)
|
||||
: []
|
||||
const utm = [...useful, ...rest].join(' · ')
|
||||
if (!external && !utm) return null
|
||||
const utmCopy = Object.entries(utmTags)
|
||||
.map(([k, value]) => `${k}=${value}`)
|
||||
.join('\n')
|
||||
return {
|
||||
href: external?.origin || '',
|
||||
label: external?.slug || '',
|
||||
origin: external?.origin || '',
|
||||
utm,
|
||||
utmCopy,
|
||||
title: [
|
||||
...(external ? [external.origin] : []),
|
||||
...Object.entries(utmTags).map(([k, value]) => `${k}=${value}`),
|
||||
].join('\n'),
|
||||
}
|
||||
}
|
||||
|
||||
/**
|
||||
* Human-readable relative timestamp. Adapted from cista-storage: uses
|
||||
* ``Intl.RelativeTimeFormat`` for short intervals and a compact date for
|
||||
* anything older than a week.
|
||||
*/
|
||||
export function formatWhen(ts, now = Date.now()) {
|
||||
const date = new Date(ts)
|
||||
const diff = date.getTime() - now
|
||||
const adiff = Math.abs(diff)
|
||||
const formatter = new Intl.RelativeTimeFormat('en', { numeric: 'auto' })
|
||||
if (adiff <= 5000) return 'now'
|
||||
if (adiff <= 60000) {
|
||||
return formatter
|
||||
.format(Math.round(diff / 1000), 'second')
|
||||
.replace(' ago', '')
|
||||
.replaceAll(' ', '\u202F')
|
||||
}
|
||||
if (adiff <= 3600000) {
|
||||
return formatter
|
||||
.format(Math.round(diff / 60000), 'minute')
|
||||
.replace('utes', '')
|
||||
.replace('ute', '')
|
||||
.replaceAll(' ', '\u202F')
|
||||
}
|
||||
if (adiff <= 86400000) {
|
||||
return formatter
|
||||
.format(Math.round(diff / 3600000), 'hour')
|
||||
.replace('hours', 'h')
|
||||
.replace('hour', 'h')
|
||||
.replaceAll(' ', '\u202F')
|
||||
}
|
||||
if (adiff <= 604800000) {
|
||||
return formatter
|
||||
.format(Math.round(diff / 86400000), 'day')
|
||||
.replaceAll(' ', '\u202F')
|
||||
}
|
||||
let d = date
|
||||
.toLocaleDateString('en-ie', {
|
||||
weekday: 'short',
|
||||
year: 'numeric',
|
||||
month: 'short',
|
||||
day: 'numeric',
|
||||
})
|
||||
.replace('Sept', 'Sep')
|
||||
if (d.length === 14) d = d.replace(' ', ' \u2007')
|
||||
d = d.replaceAll(' ', '\u202F').replace('\u202F', '\u00A0')
|
||||
d = d.slice(0, -4) + d.slice(-2)
|
||||
return d
|
||||
}
|
||||
|
||||
/** Full UTC timestamp for tooltips, e.g. "2026-08-21 00:20:48 UTC". */
|
||||
export function formatWhenTooltip(ts) {
|
||||
return new Date(ts).toISOString().replace('T', ' ').replace('Z', ' UTC')
|
||||
}
|
||||
|
||||
/** Full local timestamp for tooltips, e.g. "21 Aug 2026, 17:38:48". */
|
||||
export function formatWhenLocal(ts) {
|
||||
return new Date(ts).toLocaleString('en-ie', {
|
||||
year: 'numeric',
|
||||
month: 'short',
|
||||
day: 'numeric',
|
||||
hour: '2-digit',
|
||||
minute: '2-digit',
|
||||
second: '2-digit',
|
||||
})
|
||||
}
|
||||
|
||||
/** Preserve locale case with the region/country subtag upper-cased. */
|
||||
export function formatLang(value) {
|
||||
if (!value || value === '—') return value
|
||||
const parts = value.split('-')
|
||||
if (parts.length > 1) {
|
||||
parts[parts.length - 1] = parts[parts.length - 1].toUpperCase()
|
||||
}
|
||||
return parts.join('-')
|
||||
}
|
||||
|
||||
/** ISO 8601 UTC timestamp without subseconds, e.g. "2026-08-21T00:20:48Z". */
|
||||
export function formatWhenIso(ts) {
|
||||
return `${new Date(ts).toISOString().split('.')[0]}Z`
|
||||
}
|
||||
|
||||
/**
|
||||
* Compact read time for tooltips: "50s" under a minute, "1m23s" otherwise.
|
||||
*/
|
||||
export function formatReadTime(seconds) {
|
||||
if (seconds < 60) return `${seconds}s`
|
||||
return `${Math.floor(seconds / 60)}m${seconds % 60}s`
|
||||
}
|
||||
|
||||
/**
|
||||
* Compact visitor counts: plain below 1k, then 1.2k / 10k / 1.2M.
|
||||
* Truncated, not rounded.
|
||||
*/
|
||||
export function formatCount(n) {
|
||||
if (n < 1000) return String(n)
|
||||
if (n < 10000) return `${Math.trunc(n / 1000)}.${Math.trunc((n % 1000) / 100)}k`
|
||||
if (n < 1_000_000) return `${Math.trunc(n / 1000)}k`
|
||||
return `${Math.trunc(n / 1_000_000)}.${Math.trunc((n % 1_000_000) / 100_000)}M`
|
||||
}
|
||||
|
||||
/**
|
||||
* Format recent visits for display, newest first. Each step is a linked slug
|
||||
* pointing to its article; external referers/origins are shown as their
|
||||
* domain name with the full origin as the link href. The link title shows the
|
||||
* article heading when known, or "External site" for origins.
|
||||
*/
|
||||
export function formatRecentVisits(visits, pageTree, limit = 50) {
|
||||
const titles = buildTitleMap(pageTree)
|
||||
return [...visits]
|
||||
.reverse()
|
||||
.map((v) => ({
|
||||
when: new Date(v.start).toLocaleString(),
|
||||
steps: [v.referer, ...Object.values(v.trail || {}).map((t) => t.to)]
|
||||
.map((p) => stepOf(p, titles))
|
||||
.filter(Boolean),
|
||||
}))
|
||||
.filter((v) => v.steps.length)
|
||||
.slice(0, limit)
|
||||
}
|
||||
|
||||
/**
|
||||
* Count distinct values of a visit field, sorted most-common first.
|
||||
* Returns an array of [value, count] pairs.
|
||||
*/
|
||||
export function countByField(visits, field) {
|
||||
const counts = {}
|
||||
for (const v of visits || []) {
|
||||
const value = v[field]
|
||||
if (!value) continue
|
||||
counts[value] = (counts[value] || 0) + 1
|
||||
}
|
||||
return Object.entries(counts).sort((a, b) => b[1] - a[1])
|
||||
}
|
||||
|
||||
/**
|
||||
* Count UTM parameter occurrences across visits. Each distinct
|
||||
* ``parameter: value`` pair is counted separately. Returns [pair, count].
|
||||
*/
|
||||
export function countUtmTags(visits) {
|
||||
const counts = {}
|
||||
for (const v of visits || []) {
|
||||
for (const [key, value] of Object.entries(v.utm || {})) {
|
||||
const label = `${key}: ${value}`
|
||||
counts[label] = (counts[label] || 0) + 1
|
||||
}
|
||||
}
|
||||
return Object.entries(counts).sort((a, b) => b[1] - a[1])
|
||||
}
|
||||
|
||||
/** Format a list of [value, count] pairs for inline display. */
|
||||
export function formatCounts(entries) {
|
||||
return entries.map(([value, count]) => `${value} (${count})`).join(', ')
|
||||
}
|
||||
|
||||
/**
|
||||
* Count distinct User-Agent strings among crawler hits, most common first.
|
||||
* Returns an array of [ua, count] pairs. ``clients`` maps client hashes to
|
||||
* client records.
|
||||
*/
|
||||
export function countCrawlerUas(crawlers, clients) {
|
||||
const counts = {}
|
||||
for (const c of crawlers || []) {
|
||||
const client = (clients || {})[c.client] || {}
|
||||
const value = client.uarite?.pretty || client.ua || '(no UA)'
|
||||
counts[value] = (counts[value] || 0) + 1
|
||||
}
|
||||
return Object.entries(counts).sort((a, b) => b[1] - a[1])
|
||||
}
|
||||
|
||||
/**
|
||||
* Reduce a reverse-DNS hostname to its right-most components that fit
|
||||
* within ``limit`` characters. This keeps the meaningful main domain
|
||||
* while avoiding absurdly long subdomains like ``xxx.yyy.zzz...provider.net``.
|
||||
*/
|
||||
export function mainDomain(host, limit = 24) {
|
||||
if (!host) return host
|
||||
const labels = host.split('.').filter(Boolean)
|
||||
if (!labels.length) return host
|
||||
const parts = [labels.pop()]
|
||||
while (labels.length) {
|
||||
const next = labels[labels.length - 1]
|
||||
const candidate = `${next}.${parts.join('.')}`
|
||||
if (candidate.length > limit) break
|
||||
parts.unshift(labels.pop())
|
||||
}
|
||||
return parts.join('.')
|
||||
}
|
||||
|
||||
/**
|
||||
* Group raw crawler hits by client hash and format each group as a row showing
|
||||
* every internal page that crawler visited. Rows are sorted by most recent hit
|
||||
* first, with total hits as a tie-breaker. The group's ``refererBadge`` is
|
||||
* the latest external referer seen for the crawler — spiders often advertise
|
||||
* their own site there — rendered as a badge with its favicon like visit
|
||||
* referers.
|
||||
* ``clients`` maps client hashes to client records.
|
||||
*/
|
||||
export function formatCrawlerRows(crawlers, clients, pageTree, now = Date.now(), site = { multilingual: false, primaryLang: '' }) {
|
||||
const titles = buildTitleMap(pageTree)
|
||||
const groups = new Map()
|
||||
for (const c of crawlers || []) {
|
||||
const client = (clients || {})[c.client] || {}
|
||||
const g = groups.get(c.client) || {
|
||||
clientHash: c.client,
|
||||
client,
|
||||
lastStart: 0,
|
||||
referer: '',
|
||||
pages: new Map(),
|
||||
langs: new Set(),
|
||||
}
|
||||
const start = new Date(c.start).getTime()
|
||||
if (start > g.lastStart) g.lastStart = start
|
||||
if (c.referer) g.referer = c.referer
|
||||
if (c.lang) g.langs.add(c.lang)
|
||||
if (c.entry?.startsWith('/')) {
|
||||
const existing = g.pages.get(c.entry) || { count: 0, status: c.status || 200 }
|
||||
existing.count += 1
|
||||
if (c.status != null) existing.status = c.status
|
||||
g.pages.set(c.entry, existing)
|
||||
}
|
||||
groups.set(c.client, g)
|
||||
}
|
||||
const totalHits = (g) => {
|
||||
let n = 0
|
||||
for (const p of g.pages.values()) n += p.count
|
||||
return n
|
||||
}
|
||||
return [...groups.values()]
|
||||
.sort((a, b) => b.lastStart - a.lastStart || totalHits(b) - totalHits(a))
|
||||
.slice(0, 10)
|
||||
.map((g) => {
|
||||
const client = g.client || {}
|
||||
const host = client.host || ''
|
||||
const isHost = !!host
|
||||
// Rendered languages read, shown only when they say something the
|
||||
// primary language alone would not (multilingual sites only).
|
||||
const langs = [...g.langs].sort()
|
||||
const showLangs =
|
||||
site.multilingual && (langs.length > 1 || (langs[0] && langs[0] !== site.primaryLang))
|
||||
return {
|
||||
lastSeen: formatWhen(g.lastStart, now),
|
||||
lastSeenIso: formatWhenIso(g.lastStart),
|
||||
lastSeenLocal: formatWhenLocal(g.lastStart),
|
||||
refererBadge: refererBadgeOf(g.referer, titles),
|
||||
pages: [...g.pages.entries()]
|
||||
.sort((a, b) => b[1].count - a[1].count)
|
||||
.map(([path, info]) => ({ ...stepOf(path, titles), count: info.count, status: info.status })),
|
||||
readFlags: showLangs
|
||||
? langs.map((l) => ({ flag: flagFor(l), name: langName(l) })).filter((f) => f.flag)
|
||||
: [],
|
||||
ip: client.ip || '',
|
||||
ipDisplay: isHost ? mainDomain(host) : hostIP(client.ip) || client.ip || '—',
|
||||
isHost,
|
||||
ua: client.uarite?.pretty || client.ua || '—',
|
||||
uaRaw: client.ua || '',
|
||||
uaUrl: client.uarite?.url || '',
|
||||
lang: client.lang || '—',
|
||||
langDisplay: formatLang(client.lang),
|
||||
country: client.country || '—',
|
||||
city: client.city || '—',
|
||||
total: totalHits(g),
|
||||
}
|
||||
})
|
||||
}
|
||||
|
||||
/**
|
||||
* Group abuse hits by IP and format each group as a row with the full paths
|
||||
* probed. Identical requests (same path and status class) are collapsed
|
||||
* into one entry with their hit count; a path's 404 probes and its real
|
||||
* (200) reads never merge.
|
||||
* The paths split into two lists: ``paths`` holds the 404 probes (flagged
|
||||
* paths — the ones that triggered abuse classification — first, then other
|
||||
* 404s) shown verbatim, query string included, and ``articles`` holds the
|
||||
* real (200) document GETs as trail steps resolved against the page tree
|
||||
* (query string stripped), rendered like the visitor/crawler trails. Within
|
||||
* each list paths are sorted by count descending, then earliest first.
|
||||
* Rows are sorted by most recent hit first. Visitor metadata comes from the
|
||||
* latest client hash seen for the IP; ``clientCount`` tells the visitor cell
|
||||
* how many distinct client variations the IP produced.
|
||||
* ``clients`` maps client hashes to client records.
|
||||
*/
|
||||
export function formatAbuseRows(abuse, clients, pageTree, now = Date.now()) {
|
||||
const titles = buildTitleMap(pageTree)
|
||||
const groups = new Map()
|
||||
for (const a of abuse || []) {
|
||||
const client = (clients || {})[a.client] || {}
|
||||
const ip = client.ip || ''
|
||||
const g = groups.get(ip) || {
|
||||
ip,
|
||||
pathCounts: new Map(),
|
||||
clientHashes: new Set(),
|
||||
lastStart: 0,
|
||||
lastClient: a.client,
|
||||
}
|
||||
const start = new Date(a.start).getTime()
|
||||
if (start > g.lastStart) {
|
||||
g.lastStart = start
|
||||
g.lastClient = a.client
|
||||
}
|
||||
const path = a.path || ''
|
||||
// Collapse identical requests, but never merge a path's 404 probes with
|
||||
// its real (200) reads — a page probed while missing and later created
|
||||
// must show up in both columns, not flip to "articles read".
|
||||
const key = `${a.is_404 ? '4' : '2'}${path}`
|
||||
const existing = g.pathCounts.get(key) || {
|
||||
path,
|
||||
count: 0,
|
||||
firstStart: start,
|
||||
flag: a.flag || false,
|
||||
is_404: a.is_404 || false,
|
||||
}
|
||||
existing.count += 1
|
||||
if (start < existing.firstStart) existing.firstStart = start
|
||||
if (a.flag) existing.flag = true
|
||||
g.pathCounts.set(key, existing)
|
||||
g.clientHashes.add(a.client)
|
||||
groups.set(ip, g)
|
||||
}
|
||||
const totalHits = (g) => {
|
||||
let n = 0
|
||||
for (const p of g.pathCounts.values()) n += p.count
|
||||
return n
|
||||
}
|
||||
return [...groups.values()]
|
||||
.sort((a, b) => b.lastStart - a.lastStart)
|
||||
.slice(0, 10)
|
||||
.map((g) => {
|
||||
const all = [...g.pathCounts.values()]
|
||||
const byCount = (a, b) => b.count - a.count || a.firstStart - b.firstStart
|
||||
const paths = all
|
||||
.filter((p) => p.flag || p.is_404)
|
||||
.sort((a, b) => (a.flag ? 0 : 1) - (b.flag ? 0 : 1) || byCount(a, b))
|
||||
const articles = all.filter((p) => !p.flag && !p.is_404).sort(byCount)
|
||||
const pathList = (list) =>
|
||||
list.map((p) => (p.count > 1 ? `${p.count}× ${p.path}` : p.path)).join('\n')
|
||||
const client = (clients || {})[g.lastClient] || {}
|
||||
const host = client.host || ''
|
||||
const isHost = !!host
|
||||
const uaRaws = [
|
||||
...new Set(
|
||||
[...g.clientHashes]
|
||||
.map((h) => (clients || {})[h]?.ua)
|
||||
.filter(Boolean),
|
||||
),
|
||||
].join('\n')
|
||||
return {
|
||||
lastSeen: formatWhen(g.lastStart, now),
|
||||
lastSeenIso: formatWhenIso(g.lastStart),
|
||||
lastSeenLocal: formatWhenLocal(g.lastStart),
|
||||
paths: paths.map((p) => ({
|
||||
path: p.path,
|
||||
count: p.count,
|
||||
flag: p.flag,
|
||||
is_404: p.is_404,
|
||||
})),
|
||||
allPaths: pathList(paths),
|
||||
articles: articles
|
||||
.map((p) => {
|
||||
const step = stepOf(p.path.split('?')[0], titles)
|
||||
return step ? { ...step, count: p.count } : null
|
||||
})
|
||||
.filter(Boolean),
|
||||
allArticles: pathList(articles),
|
||||
clientCount: g.clientHashes.size,
|
||||
ip: client.ip || g.ip,
|
||||
ipDisplay: isHost ? mainDomain(host) : hostIP(client.ip || g.ip) || client.ip || g.ip || '—',
|
||||
isHost,
|
||||
ua: client.uarite?.pretty || client.ua || '—',
|
||||
uaRaw: client.ua || '',
|
||||
uaUrl: client.uarite?.url || '',
|
||||
uaRaws,
|
||||
lang: client.lang || '—',
|
||||
langDisplay: formatLang(client.lang),
|
||||
country: client.country || '—',
|
||||
city: client.city || '—',
|
||||
total: totalHits(g),
|
||||
}
|
||||
})
|
||||
}
|
||||
|
||||
/**
|
||||
* Format raw visit records as rows for a technical table. Returns objects
|
||||
* with display strings; missing values become "—". The external referer
|
||||
* (when present) and the UTM tags ride along as ``refererBadge``; ``trail``
|
||||
* holds the entry page and any further internal pages or external exit
|
||||
* origins; consecutive views of the same page (e.g. a
|
||||
* language switch re-view) merge into one step that keeps the
|
||||
* consecutive-distinct rendered languages, summed read time, and the latest
|
||||
* status. On multilingual sites the rendered languages surface as flag
|
||||
* icons: a visit read entirely in one non-primary language gets ``rowFlag``,
|
||||
* and a visit spanning languages gets per-step ``langFlags`` markers where
|
||||
* the language begins or changes. Only the 20 most recent visits are shown.
|
||||
* ``clients`` maps client hashes to client records; ``site`` carries the
|
||||
* payload's multilingual/primary-language context.
|
||||
*/
|
||||
export function formatVisitRows(visits, clients, pageTree, now = Date.now(), site = { multilingual: false, primaryLang: '' }) {
|
||||
const titles = buildTitleMap(pageTree)
|
||||
return [...(visits || [])].reverse().slice(0, 20).map((v) => {
|
||||
const client = (clients || {})[v.client] || {}
|
||||
const steps = Object.values(v.trail || {})
|
||||
.map((item) => {
|
||||
const step = stepOf(item.to, titles)
|
||||
if (step) {
|
||||
if (item.read) step.readSeconds = item.read
|
||||
if (item.status) step.status = item.status
|
||||
if (item.lang) step.lang = item.lang
|
||||
}
|
||||
return step
|
||||
})
|
||||
.filter(Boolean)
|
||||
const trail = []
|
||||
for (const step of steps) {
|
||||
const prev = trail[trail.length - 1]
|
||||
if (prev && prev.path === step.path) {
|
||||
if (step.lang && step.lang !== prev.langs[prev.langs.length - 1]) prev.langs.push(step.lang)
|
||||
if (step.readSeconds) prev.readSeconds = (prev.readSeconds || 0) + step.readSeconds
|
||||
if (step.status) prev.status = step.status
|
||||
} else {
|
||||
step.langs = step.lang ? [step.lang] : []
|
||||
trail.push(step)
|
||||
}
|
||||
}
|
||||
const distinctLangs = new Set(trail.flatMap((s) => s.langs))
|
||||
const dash = (s) => (s || '—')
|
||||
const host = client.host || ''
|
||||
const isHost = !!host
|
||||
const row = {
|
||||
lastSeen: formatWhen(v.start, now),
|
||||
lastSeenIso: formatWhenIso(v.start),
|
||||
lastSeenLocal: formatWhenLocal(v.start),
|
||||
langDisplay: formatLang(client.lang),
|
||||
trail,
|
||||
refererBadge: refererBadgeOf(v.referer, titles, v.utm),
|
||||
ip: client.ip || '',
|
||||
ipDisplay: isHost ? mainDomain(host) : hostIP(client.ip) || client.ip || '—',
|
||||
isHost,
|
||||
lang: dash(client.lang),
|
||||
country: dash(client.country),
|
||||
city: dash(client.city),
|
||||
ua: client.uarite?.pretty || client.ua || '—',
|
||||
uaRaw: client.ua || '',
|
||||
uaUrl: client.uarite?.url || '',
|
||||
}
|
||||
if (site.multilingual && distinctLangs.size) {
|
||||
if (distinctLangs.size === 1) {
|
||||
const [tag] = distinctLangs
|
||||
const flag = flagFor(tag)
|
||||
if (flag && tag !== site.primaryLang) {
|
||||
row.rowFlag = flag
|
||||
row.rowFlagTitle = langName(tag)
|
||||
}
|
||||
} else {
|
||||
// Flag the steps where the rendered language begins or changes;
|
||||
// lang-less steps keep the comparison chain going, they never flag.
|
||||
let lastLang = null
|
||||
for (const step of trail) {
|
||||
if (!step.langs.length) continue
|
||||
if (!lastLang || step.langs[step.langs.length - 1] !== lastLang) {
|
||||
step.langFlags = step.langs.map(flagFor).filter(Boolean)
|
||||
}
|
||||
lastLang = step.langs[step.langs.length - 1]
|
||||
}
|
||||
}
|
||||
}
|
||||
return row
|
||||
})
|
||||
}
|
||||
@@ -0,0 +1,111 @@
|
||||
/**
|
||||
* Seasonal "typical week" estimate from the full visit history.
|
||||
*
|
||||
* Port of the seasonal.py demo algorithm: the whole smoothed 5-minute
|
||||
* history is collapsed onto a weekly grid with exponential decay over age —
|
||||
* a fast kernel (half-life 7 days) for the average time-of-day pattern and
|
||||
* a slow one (half-life 42 days) for per-weekday deviations from it. The
|
||||
* deviation is shrunk by the effective number of weeks behind each bin
|
||||
* (n_eff / (n_eff + 3)), so with little history the estimate falls back to
|
||||
* the common daily pattern and weekday character emerges as data accrues.
|
||||
* Bins before the first recorded bucket are treated as missing.
|
||||
*/
|
||||
|
||||
import { DAY, MIN5, mondayUTC, rawTimes } from './time.js'
|
||||
import { smooth } from './chart.js'
|
||||
|
||||
export const BINS_PER_DAY = 288
|
||||
export const BINS_PER_WEEK = 7 * BINS_PER_DAY
|
||||
|
||||
// History cap: at 180 days the slow kernel's weight is 2^(-180/42) ≈ 5%
|
||||
// (and the fast kernel's utterly negligible), so older data cannot move
|
||||
// this noisy estimate — skipping it keeps the smoothing pass O(1).
|
||||
const MAX_HISTORY_DAYS = 180
|
||||
|
||||
/**
|
||||
* Estimate the typical week from a dense 5-minute count series (oldest
|
||||
* first; non-finite values count as missing). endWeekBin is the week bin
|
||||
* (Monday-first) just past the last sample. Returns BINS_PER_WEEK counts
|
||||
* per 5-minute bin, starting Monday 00:00.
|
||||
*/
|
||||
export function seasonalCurve(counts, {
|
||||
endWeekBin,
|
||||
binsPerDay = BINS_PER_DAY,
|
||||
recentHalfLife = 7,
|
||||
weekdayHalfLife = 42,
|
||||
shrinkWeeks = 3,
|
||||
} = {}) {
|
||||
const n = counts.length
|
||||
const binsPerWeek = 7 * binsPerDay
|
||||
|
||||
const recentW = new Float64Array(binsPerDay)
|
||||
const recentX = new Float64Array(binsPerDay)
|
||||
const dayW = new Float64Array(binsPerDay)
|
||||
const dayX = new Float64Array(binsPerDay)
|
||||
const weekW = new Float64Array(binsPerWeek)
|
||||
const weekX = new Float64Array(binsPerWeek)
|
||||
const weekW2 = new Float64Array(binsPerWeek)
|
||||
|
||||
for (let i = 0; i < n; i++) {
|
||||
const x = counts[i]
|
||||
if (!Number.isFinite(x)) continue
|
||||
let weekBin = (endWeekBin - n + i) % binsPerWeek
|
||||
if (weekBin < 0) weekBin += binsPerWeek
|
||||
const dayBin = weekBin % binsPerDay
|
||||
const ageDays = (n - 1 - i) / binsPerDay
|
||||
const recent = 2 ** (-ageDays / recentHalfLife)
|
||||
const slow = 2 ** (-ageDays / weekdayHalfLife)
|
||||
recentW[dayBin] += recent
|
||||
recentX[dayBin] += recent * x
|
||||
dayW[dayBin] += slow
|
||||
dayX[dayBin] += slow * x
|
||||
weekW[weekBin] += slow
|
||||
weekX[weekBin] += slow * x
|
||||
weekW2[weekBin] += slow * slow
|
||||
}
|
||||
|
||||
const estimate = new Float64Array(binsPerWeek)
|
||||
for (let wb = 0; wb < binsPerWeek; wb++) {
|
||||
const db = wb % binsPerDay
|
||||
const recentMean = recentW[db] > 0 ? recentX[db] / recentW[db] : NaN
|
||||
const dayMean = dayW[db] > 0 ? dayX[db] / dayW[db] : NaN
|
||||
const weekMean = weekW[wb] > 0 ? weekX[wb] / weekW[wb] : 0
|
||||
const nEff = weekW2[wb] > 0 ? (weekW[wb] * weekW[wb]) / weekW2[wb] : 0
|
||||
const shrink = nEff / (nEff + shrinkWeeks)
|
||||
const base = Number.isFinite(recentMean)
|
||||
? recentMean
|
||||
: Number.isFinite(dayMean) ? dayMean : 0
|
||||
const deviation = Number.isFinite(dayMean) ? weekMean - dayMean : 0
|
||||
estimate[wb] = base + shrink * deviation
|
||||
}
|
||||
return estimate
|
||||
}
|
||||
|
||||
/** Week bin (0 = Monday 00:00–00:05 UTC) containing timestamp t. */
|
||||
export function weekBinIndex(t) {
|
||||
return Math.floor((t - mondayUTC(t)) / MIN5)
|
||||
}
|
||||
|
||||
/**
|
||||
* Typical-week estimate from sparse 5-minute buckets, using history up to
|
||||
* tEnd (default now): bins are densified from the first recorded bucket
|
||||
* (capped at MAX_HISTORY_DAYS back), smoothed with the same Gaussian the
|
||||
* week view uses, then folded by seasonalCurve. Returns BINS_PER_WEEK
|
||||
* counts per 5-minute bin starting Monday, or null when there is less than
|
||||
* a day of history or the history span (first bucket to tEnd, before
|
||||
* capping) is below minHistory.
|
||||
*/
|
||||
export function typicalWeek(buckets, tEnd = Date.now(), { minHistory = 0 } = {}) {
|
||||
const raw = rawTimes(buckets)
|
||||
const times = Object.keys(raw).map(Number)
|
||||
if (!times.length) return null
|
||||
const end = Math.floor(tEnd / MIN5) * MIN5
|
||||
if (end - Math.min(...times) < minHistory) return null
|
||||
const start = Math.max(Math.min(...times), end - MAX_HISTORY_DAYS * DAY)
|
||||
const n = Math.floor((end - start) / MIN5)
|
||||
if (n < BINS_PER_DAY) return null
|
||||
const counts = new Array(n)
|
||||
for (let i = 0; i < n; i++) counts[i] = raw[start + i * MIN5] || 0
|
||||
const smoothed = smooth(counts, 5, 60)
|
||||
return seasonalCurve(smoothed, { endWeekBin: weekBinIndex(end) })
|
||||
}
|
||||
@@ -0,0 +1,249 @@
|
||||
/**
|
||||
* Time ranges, week alignment and re-bucketing for analytics charts.
|
||||
*
|
||||
* Raw data comes as sparse 5-minute buckets; the range picks the x window
|
||||
* and a coarser bucket size to keep point counts sane. The week range is
|
||||
* aligned to Monday 00:00 UTC; a "typical week" seasonal estimate
|
||||
* (seasonal.js) is overlaid as a solid fill on the week and day views by
|
||||
* the chart builder.
|
||||
*/
|
||||
|
||||
export const MIN5 = 5 * 60e3
|
||||
export const HOUR = 3600e3
|
||||
export const DAY = 86400e3
|
||||
export const WEEK = 7 * DAY
|
||||
|
||||
export const RANGES = {
|
||||
day: { label: 'day', span: DAY, bucket: MIN5 },
|
||||
week: { label: 'week' },
|
||||
month: { label: 'month', span: 30 * DAY, bucket: 6 * HOUR },
|
||||
year: { label: 'year', span: 365 * DAY, bucket: DAY },
|
||||
all: { label: 'all', span: null, bucket: DAY, minSpan: 30 * DAY },
|
||||
}
|
||||
|
||||
/** Monday 00:00 UTC of the week containing t (epoch day 0 was a Thursday). */
|
||||
export function mondayUTC(t) {
|
||||
const d = Math.floor(t / DAY)
|
||||
return (d - ((d + 3) % 7)) * DAY
|
||||
}
|
||||
|
||||
/** ISO 8601 week number of the week containing t (via its Thursday). */
|
||||
export function isoWeek(t) {
|
||||
const d = new Date(t)
|
||||
d.setUTCHours(0, 0, 0, 0)
|
||||
d.setUTCDate(d.getUTCDate() + 4 - (d.getUTCDay() || 7))
|
||||
const yearStart = Date.UTC(d.getUTCFullYear(), 0, 1)
|
||||
return Math.ceil(((d - yearStart) / DAY + 1) / 7)
|
||||
}
|
||||
|
||||
/** Parse sparse timestamp buckets into a { epochMs: count } map. */
|
||||
export function rawTimes(buckets) {
|
||||
const raw = {}
|
||||
// Key by parsed timestamp: Python writes "+00:00", JS ISO uses "Z".
|
||||
for (const [k, c] of Object.entries(buckets || {})) raw[Date.parse(k)] = c
|
||||
return raw
|
||||
}
|
||||
|
||||
/** Sum counts from raw 5-minute buckets between t0 (inclusive) and t1 (exclusive). */
|
||||
export function sumRange(raw, t0, t1) {
|
||||
let n = 0
|
||||
for (let s = t0; s < t1; s += MIN5) n += raw[s] || 0
|
||||
return n
|
||||
}
|
||||
|
||||
/**
|
||||
* The current week at native 5-minute resolution, truncated at the current
|
||||
* bucket — no fake zeroes drawn for the future. Counts are rates per hour
|
||||
* (bucket count * 12): a lone visit in a 5-minute bucket reads as "12/h".
|
||||
* The coarser ranges use per-day rates instead (unitMinutes = 24*60).
|
||||
* Since the window is fixed Monday-to-Monday, the days not yet reached
|
||||
* would otherwise be blank early in the week: last week's curve continues
|
||||
* the graph from the current bucket to the end of the week (secondary
|
||||
* accent, translucent fill like the current week), gradually replaced by
|
||||
* the current week as it accrues. The tail is only drawn when the data
|
||||
* reaches into last week at all. The
|
||||
* "typical week" seasonal estimate (seasonal.js) is the statistical
|
||||
* history reference under both.
|
||||
*/
|
||||
export function weeklySeries(buckets) {
|
||||
const raw = rawTimes(buckets)
|
||||
const now = Date.now()
|
||||
const thisMonday = mondayUTC(now)
|
||||
const points = []
|
||||
const end = Math.min(thisMonday + WEEK, Math.floor(now / MIN5) * MIN5 + MIN5)
|
||||
for (let t = thisMonday; t < end; t += MIN5) {
|
||||
points.push({ t, count: raw[t] || 0 })
|
||||
}
|
||||
const past = []
|
||||
if (Object.keys(raw).some((t) => Number(t) < thisMonday)) {
|
||||
for (let t = end; t < thisMonday + WEEK; t += MIN5) {
|
||||
past.push({ t, count: raw[t - WEEK] || 0 })
|
||||
}
|
||||
}
|
||||
return {
|
||||
series: [
|
||||
{ points, label: `Week ${isoWeek(thisMonday)}`, opacity: 1, area: true },
|
||||
...(past.length
|
||||
? [{ points: past, label: `Week ${isoWeek(thisMonday - WEEK)}`, past: true, area: true }]
|
||||
: []),
|
||||
],
|
||||
t0: thisMonday,
|
||||
t1: thisMonday + WEEK,
|
||||
rate: HOUR / MIN5,
|
||||
binMinutes: 5,
|
||||
unitMinutes: 60,
|
||||
unit: 'hour',
|
||||
}
|
||||
}
|
||||
|
||||
/**
|
||||
* Rolling window for the non-week ranges (x max = now), counts converted
|
||||
* to per-day rates (the unit the month+ charts are read in).
|
||||
* Ranges without a fixed span use the full data reach, but never less than
|
||||
* their configured minSpan so the chart keeps a readable minimum x scale.
|
||||
* t0 is aligned to the UTC day so the x labels cover the whole range;
|
||||
* t1 is now, so the scale never extends into the future. The bucket size
|
||||
* follows the resulting window (6h up to 31 days, daily beyond), so ranges
|
||||
* covering the same window — "all" at its 30-day minimum vs "month" —
|
||||
* render the identical curve.
|
||||
*/
|
||||
export function rollingSeries(buckets, rangeKey) {
|
||||
const raw = rawTimes(buckets)
|
||||
const times = Object.keys(raw).map(Number)
|
||||
const { span, bucket, minSpan = 0 } = RANGES[rangeKey]
|
||||
const t1 = Date.now()
|
||||
const t0 = Math.floor((span != null
|
||||
? t1 - span
|
||||
: Math.min(times.length ? Math.min(...times) : Infinity, t1 - minSpan)) / DAY) * DAY
|
||||
if (!times.length) {
|
||||
const bucketMs = t1 - t0 <= 31 * DAY ? Math.min(bucket, 6 * HOUR) : bucket
|
||||
const points = []
|
||||
for (let t = t0; t < t1; t += bucketMs) {
|
||||
points.push({ t, count: 0 })
|
||||
}
|
||||
return {
|
||||
series: [{ points, label: '', opacity: 1, area: true }],
|
||||
t0,
|
||||
t1,
|
||||
rate: DAY / bucketMs,
|
||||
binMinutes: bucketMs / 60e3,
|
||||
unitMinutes: 24 * 60,
|
||||
unit: 'day',
|
||||
}
|
||||
}
|
||||
// The bucket follows the actual window length, not the range key: when
|
||||
// "all" is capped to its 30-day minimum it covers the very window "month"
|
||||
// does, and daily bins would draw a different curve over the same data
|
||||
// (coarser edge detection, points a day apart plotted at bin starts, the
|
||||
// last point stuck at today's midnight instead of reaching now).
|
||||
const bucketMs = t1 - t0 <= 31 * DAY ? Math.min(bucket, 6 * HOUR) : bucket
|
||||
const points = []
|
||||
for (let t = t0; t < t1; t += bucketMs) {
|
||||
points.push({ t, count: sumRange(raw, t, t + bucketMs) })
|
||||
}
|
||||
return {
|
||||
series: [{ points, label: '', opacity: 1, area: true }],
|
||||
t0,
|
||||
t1,
|
||||
rate: DAY / bucketMs,
|
||||
binMinutes: bucketMs / 60e3,
|
||||
unitMinutes: 24 * 60,
|
||||
unit: 'day',
|
||||
}
|
||||
}
|
||||
|
||||
/**
|
||||
* Day view: raw 5-minute bucket counts for the current 24-hour window.
|
||||
* No smoothing or rate conversion is applied; counts are used as-is.
|
||||
*/
|
||||
export function daySeries(buckets) {
|
||||
const raw = rawTimes(buckets)
|
||||
const now = Date.now()
|
||||
const { span, bucket } = RANGES.day
|
||||
const t1 = Math.floor(now / bucket) * bucket + bucket
|
||||
const t0 = t1 - span
|
||||
const points = []
|
||||
for (let t = t0; t < t1; t += bucket) {
|
||||
points.push({ t, count: raw[t] || 0 })
|
||||
}
|
||||
return {
|
||||
series: [{ points, label: '', opacity: 1, area: false }],
|
||||
t0,
|
||||
t1,
|
||||
rate: 1,
|
||||
binMinutes: bucket / 60e3,
|
||||
unitMinutes: bucket / 60e3,
|
||||
unit: '5min',
|
||||
}
|
||||
}
|
||||
|
||||
/** Dispatch to daily, weekly or rolling series based on the selected range. */
|
||||
export function makeSeries(buckets, rangeKey) {
|
||||
if (rangeKey === 'day') return daySeries(buckets)
|
||||
if (rangeKey === 'week') return weeklySeries(buckets)
|
||||
return rollingSeries(buckets, rangeKey)
|
||||
}
|
||||
|
||||
/**
|
||||
* Absolute UTC time window for a given range key. Used to filter visits,
|
||||
* transitions and views for the non-chart stats on the analytics page.
|
||||
* Every bounded range is a rolling span ending at now; the charts instead
|
||||
* align week to Monday 00:00 UTC (overlaying previous weeks) and month+
|
||||
* to UTC day boundaries, so their x windows differ from the stats range
|
||||
* on purpose.
|
||||
* Returns { t0, t1 } where null means unbounded.
|
||||
*/
|
||||
export function rangeWindow(rangeKey) {
|
||||
const now = Date.now()
|
||||
if (rangeKey === 'all') {
|
||||
return { t0: null, t1: null }
|
||||
}
|
||||
const span = rangeKey === 'week' ? WEEK : RANGES[rangeKey].span
|
||||
return { t0: now - span, t1: now }
|
||||
}
|
||||
|
||||
/**
|
||||
* Sum the bucketed transition matrix (from -> to -> bucket ISO -> count)
|
||||
* into a plain from -> to -> count matrix for the window [t0, t1).
|
||||
*/
|
||||
export function filterTransitionsByRange(transitions, t0, t1) {
|
||||
const out = {}
|
||||
for (const [fr, tos] of Object.entries(transitions || {})) {
|
||||
for (const [to, buckets] of Object.entries(tos)) {
|
||||
let n = 0
|
||||
for (const [k, c] of Object.entries(buckets)) {
|
||||
const t = Date.parse(k)
|
||||
if ((t0 == null || t >= t0) && (t1 == null || t < t1)) n += c
|
||||
}
|
||||
if (n) {
|
||||
out[fr] = out[fr] || {}
|
||||
out[fr][to] = n
|
||||
}
|
||||
}
|
||||
}
|
||||
return out
|
||||
}
|
||||
|
||||
/** Keep only the 5-minute view buckets that fall inside [t0, t1). */
|
||||
export function filterViewsByRange(views, t0, t1) {
|
||||
const filtered = {}
|
||||
for (const [path, buckets] of Object.entries(views || {})) {
|
||||
const out = {}
|
||||
for (const [k, c] of Object.entries(buckets)) {
|
||||
const t = Date.parse(k)
|
||||
if ((t0 == null || t >= t0) && (t1 == null || t < t1)) out[k] = c
|
||||
}
|
||||
if (Object.keys(out).length) filtered[path] = out
|
||||
}
|
||||
return filtered
|
||||
}
|
||||
|
||||
/** Keep only records whose start time falls inside [t0, t1). */
|
||||
export function filterRecordsByRange(records, t0, t1) {
|
||||
const out = []
|
||||
for (const r of records || []) {
|
||||
const t = Date.parse(r.start)
|
||||
if ((t0 == null || t >= t0) && (t1 == null || t < t1)) out.push(r)
|
||||
}
|
||||
return out
|
||||
}
|
||||
@@ -25,12 +25,12 @@ pre code .cp { color: var(--code-comment); font-weight: bold; font-style: italic
|
||||
pre code .cpf { color: var(--code-comment); font-style: italic } /* Comment.PreprocFile */
|
||||
pre code .c1 { color: var(--code-comment); font-style: italic } /* Comment.Single */
|
||||
pre code .cs { color: var(--code-comment); font-weight: bold; font-style: italic } /* Comment.Special */
|
||||
pre code .gd { color: var(--code-error); background-color: color-mix(in oklab, var(--code-error) 25%, var(--code-bg)) } /* Generic.Deleted */
|
||||
pre code .gd { color: var(--code-error); background-color: color-mix(var(--code-error) 25%, var(--code-bg)) } /* Generic.Deleted */
|
||||
pre code .ge { color: var(--code-text); font-style: italic } /* Generic.Emph */
|
||||
pre code .ges { color: var(--code-text); font-weight: bold; font-style: italic } /* Generic.EmphStrong */
|
||||
pre code .gr { color: var(--code-error) } /* Generic.Error */
|
||||
pre code .gh { color: var(--code-builtin); font-weight: bold } /* Generic.Heading */
|
||||
pre code .gi { color: var(--code-added); background-color: color-mix(in oklab, var(--code-added) 25%, var(--code-bg)) } /* Generic.Inserted */
|
||||
pre code .gi { color: var(--code-added); background-color: color-mix(var(--code-added) 25%, var(--code-bg)) } /* Generic.Inserted */
|
||||
pre code .go { color: var(--code-muted) } /* Generic.Output */
|
||||
pre code .gp { color: var(--code-muted) } /* Generic.Prompt */
|
||||
pre code .gs { color: var(--code-text); font-weight: bold } /* Generic.Strong */
|
||||
|
||||
@@ -8,21 +8,50 @@ import { tags } from '@lezer/highlight'
|
||||
|
||||
// The base theme sets monospace on .cm-scroller, so the font must be set
|
||||
// there, not on "&".
|
||||
export const cmTheme = EditorView.theme({
|
||||
const cmEditorTheme = EditorView.theme({
|
||||
"&": {
|
||||
backgroundColor: "var(--bg)",
|
||||
color: "var(--text)",
|
||||
},
|
||||
".cm-scroller": { fontFamily: '"Fira Code", monospace' },
|
||||
".cm-content": { caretColor: "var(--text)" },
|
||||
// Fira Code in CodeMirror: set the font on .cm-content (not only the
|
||||
// scroller) and force every span inside to inherit it, so highlighting
|
||||
// spans can't drift to a different font/metrics. Ligatures are disabled
|
||||
// entirely — CodeMirror measures per character, and ligature glyphs
|
||||
// render wider than the measured sum of their parts.
|
||||
".cm-content": {
|
||||
caretColor: "var(--text)",
|
||||
fontFamily: '"Fira Code", monospace',
|
||||
fontVariantLigatures: "none",
|
||||
fontFeatureSettings: '"calt" 0',
|
||||
letterSpacing: "normal",
|
||||
},
|
||||
".cm-content *": {
|
||||
fontFamily: "inherit",
|
||||
letterSpacing: "inherit",
|
||||
},
|
||||
".cm-cursor": { borderLeftColor: "var(--text)" },
|
||||
// basicSetup's active-line highlight assumes a dark theme.
|
||||
".cm-activeLine": { backgroundColor: "transparent" },
|
||||
"&.cm-focused .cm-selectionBackground, .cm-selectionBackground":
|
||||
{ backgroundColor: "var(--line)" },
|
||||
"&.cm-focused": { outline: "none" },
|
||||
})
|
||||
|
||||
// Selection color needs a baseTheme: only base themes support the
|
||||
// &light/&dark selectors, and @codemirror/view's own selection rules use
|
||||
// them — we must match its selectors exactly (equal specificity) and rely
|
||||
// on mounting later to win. Focused: the page's --selection-bg (the base
|
||||
// accents tint; themes may override it). Unfocused: hidden, like a normal
|
||||
// input (CodeMirror greys it by default).
|
||||
const cmSelection = EditorView.baseTheme({
|
||||
"&light .cm-selectionBackground, &dark .cm-selectionBackground":
|
||||
{ backgroundColor: "transparent" },
|
||||
"&light.cm-focused > .cm-scroller > .cm-selectionLayer .cm-selectionBackground, &dark.cm-focused > .cm-scroller > .cm-selectionLayer .cm-selectionBackground":
|
||||
{ backgroundColor: "var(--selection-bg)" },
|
||||
})
|
||||
|
||||
// Exported as one extension so the editors just list `cmTheme`.
|
||||
export const cmTheme = [cmEditorTheme, cmSelection]
|
||||
|
||||
export const cmHighlight = syntaxHighlighting(HighlightStyle.define([
|
||||
{ tag: tags.heading, fontWeight: "600", color: "var(--accent)" },
|
||||
{ tag: tags.strong, fontWeight: "700" },
|
||||
|
||||
@@ -0,0 +1,24 @@
|
||||
// Shared popup open-state behavior: while `open` (a ref, truthy = open)
|
||||
// is set, a pointerdown outside `root` (a template ref covering both the
|
||||
// toggle button and the popup) or Escape resets it to null. One logic for
|
||||
// every dropdown (LangSelect, the page editor's class/table pickers), so
|
||||
// they can't drift apart.
|
||||
import { onBeforeUnmount, watch } from 'vue'
|
||||
|
||||
export function usePopup(open, root) {
|
||||
let off = null
|
||||
const stop = watch(open, (v) => {
|
||||
off?.()
|
||||
off = null
|
||||
if (!v) return
|
||||
const down = (ev) => { if (!root.value?.contains(ev.target)) open.value = null }
|
||||
const key = (ev) => { if (ev.key === 'Escape') open.value = null }
|
||||
addEventListener('pointerdown', down, true)
|
||||
addEventListener('keydown', key)
|
||||
off = () => {
|
||||
removeEventListener('pointerdown', down, true)
|
||||
removeEventListener('keydown', key)
|
||||
}
|
||||
})
|
||||
onBeforeUnmount(() => { off?.(); stop() })
|
||||
}
|
||||
@@ -0,0 +1,20 @@
|
||||
// The editor shell's shared language selection ('' = the primary language):
|
||||
// backed by the app-wide store (./store), so the editor tabs' LangSelects
|
||||
// and the public corner selector bind the same value. Linked to the
|
||||
// whole-page language: while the panel is open it drives the page preview
|
||||
// (EditorShell applies it as the fetch-time language override, swapdoc).
|
||||
import { computed, ref } from 'vue'
|
||||
import { pinia, useStore } from './store'
|
||||
|
||||
export const editorLang = computed({
|
||||
get: () => useStore(pinia).lang,
|
||||
set: (v) => { useStore(pinia).lang = v },
|
||||
})
|
||||
|
||||
// The CURRENT PAGE's primary language ('' = not yet learned): the shell's
|
||||
// settings fetch fills it with the site default; the page/structure tabs
|
||||
// then refine it per page (doc accept / tree rows — strictly better
|
||||
// sources, so they overwrite freely while the settings fetch only fills
|
||||
// the unknown). EditorShell pins the preview by it when the selection is
|
||||
// '' (the primary).
|
||||
export const pagePrimary = ref('')
|
||||
@@ -0,0 +1,71 @@
|
||||
// Language helpers shared by the editors (the PageEditor language picker,
|
||||
// the localization settings tab). Flags come from the country-flag-icons
|
||||
// set, same as the analytics visitor cells.
|
||||
import * as flagSvgs from 'country-flag-icons/string/3x2'
|
||||
|
||||
// The Seed-X reference translator's languages (scripts/translator.py) — the
|
||||
// translation-target ceiling — each mapped to the language's home country
|
||||
// flag (England for English, Portugal for Portuguese — not the most
|
||||
// populous variant). Internal tags are the bare 2-letter base subtags; the
|
||||
// translator decides the variant. A variant tag (en-US, pt-BR) is still a
|
||||
// valid explicit selection for a future translator that distinguishes them
|
||||
// — flagFor shows its own region then.
|
||||
export const TRANSLATABLE = {
|
||||
ar: 'EG', cs: 'CZ', da: 'DK', de: 'DE', el: 'GR', en: 'GB', es: 'ES',
|
||||
fa: 'IR', fi: 'FI', fr: 'FR', hu: 'HU', id: 'ID', it: 'IT', ja: 'JP',
|
||||
ko: 'KR', ms: 'MY', nl: 'NL', no: 'NO', pl: 'PL', pt: 'PT', ro: 'RO',
|
||||
ru: 'RU', sv: 'SE', th: 'TH', tr: 'TR', uk: 'UA', vi: 'VN', zh: 'CN',
|
||||
}
|
||||
|
||||
// The languages in geographic/cultural groups (the lang tab's flag grid
|
||||
// lays them out one group per row, in this order): English with the
|
||||
// Nordics, then Western/Central and Eastern Europe, Southern Europe with
|
||||
// the Middle East, and Asia.
|
||||
export const LANG_GROUPS = [
|
||||
['en', 'nl', 'da', 'no', 'sv', 'fi', 'ru'],
|
||||
['fr', 'de', 'pl', 'cs', 'hu', 'ro', 'uk'],
|
||||
['es', 'pt', 'it', 'el', 'tr', 'ar', 'fa'],
|
||||
['zh', 'ja', 'ko', 'vi', 'th', 'id', 'ms'],
|
||||
]
|
||||
|
||||
const displayNames = new Intl.DisplayNames(['en'], { type: 'language' })
|
||||
|
||||
// Consistent menu ordering for language selectors: the geographic/cultural
|
||||
// grouping above (similar languages sit together, and it does not vary with
|
||||
// the display language the way alphabetical-by-name would). Tags outside
|
||||
// the groups trail, ordered by tag. The primary language is not special
|
||||
// here — callers put it first themselves.
|
||||
const groupOrder = new Map(LANG_GROUPS.flat().map((c, i) => [c, i]))
|
||||
export function langSort(codes) {
|
||||
return [...codes].sort(
|
||||
(a, b) =>
|
||||
(groupOrder.get(a) ?? groupOrder.size) - (groupOrder.get(b) ?? groupOrder.size)
|
||||
|| a.localeCompare(b),
|
||||
)
|
||||
}
|
||||
|
||||
// English display name for a language tag ("fi" -> "Finnish").
|
||||
export function langName(tag) {
|
||||
try {
|
||||
return displayNames.of(tag) || tag
|
||||
} catch {
|
||||
return tag
|
||||
}
|
||||
}
|
||||
|
||||
// Flag SVG string for a language tag: an explicit region variant (en-US)
|
||||
// gets its own region's flag; a bare base tag maps to the language's home
|
||||
// country (en → GB, pt → PT); languages outside the list fall back to the
|
||||
// tag's most likely region.
|
||||
export function flagFor(tag) {
|
||||
tag = tag || ''
|
||||
if (!tag.includes('-')) {
|
||||
const country = TRANSLATABLE[tag.split('-')[0].toLowerCase()]
|
||||
if (country) return flagSvgs[country] || ''
|
||||
}
|
||||
try {
|
||||
return flagSvgs[new Intl.Locale(tag).maximize().region] || ''
|
||||
} catch {
|
||||
return ''
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,50 @@
|
||||
// Public language-selector entry: imported on demand by pagerite.js on
|
||||
// pages advertising more than one language in their hreflang alternates.
|
||||
// Vue, Pinia and the flag SVG set live in this chunk only — untranslated
|
||||
// pages never pay for them. The selector's state lives in the shared
|
||||
// store (./store), not the DOM: the corner container is rebuilt freely
|
||||
// and ensureMounted re-mounts from the store.
|
||||
import { createApp } from 'vue'
|
||||
import LangSelector from './LangSelector.vue'
|
||||
import { pinia, useStore } from './store'
|
||||
|
||||
let app = null
|
||||
|
||||
function store() {
|
||||
return useStore(pinia)
|
||||
}
|
||||
|
||||
// The current page's languages (called on every navigation).
|
||||
export function setLanguages(alternates, current) {
|
||||
Object.assign(store(), {
|
||||
langAlternates: alternates,
|
||||
servedLang: current,
|
||||
langSelectorActive: true,
|
||||
})
|
||||
}
|
||||
|
||||
// The current page is single-language: the selector goes away.
|
||||
export function hide() {
|
||||
store().langSelectorActive = false
|
||||
app?.unmount()
|
||||
app = null
|
||||
}
|
||||
|
||||
// Mount the selector as the container's first item; re-mount when its
|
||||
// element went away with a container rebuild (a live app updates from the
|
||||
// store reactively).
|
||||
export function ensureMounted(host) {
|
||||
if (!store().langSelectorActive || !host) {
|
||||
app?.unmount()
|
||||
app = null
|
||||
return
|
||||
}
|
||||
if (app && host.contains(app._container)) return
|
||||
app?.unmount()
|
||||
const el = document.createElement('div')
|
||||
el.id = 'lang-selector'
|
||||
host.prepend(el)
|
||||
app = createApp(LangSelector)
|
||||
app.use(pinia)
|
||||
app.mount(el)
|
||||
}
|
||||
@@ -22,6 +22,57 @@ let host = null
|
||||
let app = null
|
||||
let savedTitle = null
|
||||
let visible = false
|
||||
let slideAnimation = null
|
||||
|
||||
const SLIDE_MS = 250 // keep in sync with the panel slide in pagerite.css
|
||||
|
||||
// The layout switches instantly when .editing toggles — no margin/width
|
||||
// transitions anywhere, so viewport resizes (and the vw-based .wide bleed)
|
||||
// always stay instant. The visible slide is a compositor-only FLIP
|
||||
// transform on #content, running in sync with the panel's own slide
|
||||
// (editor-slide-in / .closing in pagerite.css): both move by --editor-w
|
||||
// over the same duration and easing, so .wide's left edge tracks the
|
||||
// panel's right edge exactly throughout.
|
||||
function setEditingClass(enable) {
|
||||
const content = document.getElementById('content')
|
||||
const before = content.getBoundingClientRect().left
|
||||
document.body.classList.toggle('editing', enable)
|
||||
const delta = before - content.getBoundingClientRect().left
|
||||
slideAnimation?.cancel()
|
||||
if (delta) {
|
||||
slideAnimation = content.animate(
|
||||
{ transform: [`translateX(${delta}px)`, 'translateX(0)'] },
|
||||
{ duration: SLIDE_MS, easing: 'ease' }
|
||||
)
|
||||
}
|
||||
}
|
||||
|
||||
// The panel is fixed to the viewport's left edge (pagerite.css) but tracks
|
||||
// the page: its top is the banner's bottom edge while the banner is visible
|
||||
// (= #content's top edge), and the viewport top once the banner has
|
||||
// scrolled away. The window keeps scrolling normally while editing.
|
||||
// Below 48rem the panel covers the entire viewport (pagerite.css), so its
|
||||
// top stays 0 regardless of the banner.
|
||||
const narrow = matchMedia('(max-width: 48rem)')
|
||||
function trackPanelTop() {
|
||||
const content = document.getElementById('content')
|
||||
if (host && content) {
|
||||
host.style.top = narrow.matches
|
||||
? '0px'
|
||||
: `${Math.max(0, content.getBoundingClientRect().top)}px`
|
||||
}
|
||||
}
|
||||
|
||||
function startTrackingPanel() {
|
||||
trackPanelTop()
|
||||
addEventListener('scroll', trackPanelTop, { passive: true })
|
||||
addEventListener('resize', trackPanelTop)
|
||||
}
|
||||
|
||||
function stopTrackingPanel() {
|
||||
removeEventListener('scroll', trackPanelTop)
|
||||
removeEventListener('resize', trackPanelTop)
|
||||
}
|
||||
|
||||
export function openEditor(path, { mode = 'page' } = {}) {
|
||||
if (app) {
|
||||
@@ -36,9 +87,13 @@ export function openEditor(path, { mode = 'page' } = {}) {
|
||||
savedTitle = document.title
|
||||
host = document.createElement('div')
|
||||
host.className = 'editor-host'
|
||||
// Docked inside #content: below the banner, next to the article only.
|
||||
document.getElementById('content').prepend(host)
|
||||
document.body.classList.add('editing')
|
||||
// Appended to <body>, not #content: the open/close slide transforms
|
||||
// #content (setEditingClass), and a transformed element becomes the
|
||||
// containing block for fixed-position descendants — the panel would be
|
||||
// dragged along with the content instead of sliding on its own.
|
||||
document.body.append(host)
|
||||
setEditingClass(true)
|
||||
startTrackingPanel()
|
||||
// Which tab is active; pagerite.js uses this to decide whether a pen click
|
||||
// closes the panel or switches tabs.
|
||||
document.body.dataset.editorMode = mode
|
||||
@@ -64,22 +119,32 @@ function showEditor() {
|
||||
savedTitle = document.title
|
||||
host.style.display = ''
|
||||
host.firstElementChild?.classList.remove('closing')
|
||||
document.body.classList.add('editing')
|
||||
setEditingClass(true)
|
||||
startTrackingPanel()
|
||||
visible = true
|
||||
dispatchEvent(new CustomEvent('pagerite:editor-shown'))
|
||||
}
|
||||
|
||||
export function closeEditor() {
|
||||
// navigating: the close is part of a fetch-navigation (to /_a) — the shell
|
||||
// must not re-swap the page it was previewing back in, and the navigation
|
||||
// itself sets the new title, so both the unpin re-render and the title
|
||||
// restore are skipped.
|
||||
export function closeEditor({ navigating = false } = {}) {
|
||||
if (!visible) return
|
||||
visible = false
|
||||
document.body.classList.remove('editing')
|
||||
stopTrackingPanel()
|
||||
setEditingClass(false)
|
||||
// dataset.editorMode is kept while hidden: the tabs use it to tell whether
|
||||
// a pagerite:editor-shown event targets them.
|
||||
// Slide the panel out in sync with the page shifting back, then hide it.
|
||||
host.firstElementChild?.classList.add('closing')
|
||||
const h = host
|
||||
setTimeout(() => { h.style.display = 'none' }, 250)
|
||||
dispatchEvent(new CustomEvent('pagerite:editor-hidden'))
|
||||
dispatchEvent(new CustomEvent('pagerite:editor-hidden', { detail: { navigating } }))
|
||||
if (navigating) return
|
||||
// The editor may have dropped the prefetch cache; warm it again for the
|
||||
// now-final page so navigation stays instant.
|
||||
dispatchEvent(new CustomEvent('pagerite:preload-pages'))
|
||||
// Restore the server-rendered title for the current URL. Re-fetching makes
|
||||
// sure a brand change in the site editor or an in-place navigation leaves
|
||||
// the correct public title behind.
|
||||
@@ -96,3 +161,5 @@ export function closeEditor() {
|
||||
if (!visible && restoreTitle != null) document.title = restoreTitle
|
||||
})
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,56 @@
|
||||
// Shared reconnect policy for the WebSockets (page/banner editors,
|
||||
// analytics view, the activity channel). Two things trip a browser's
|
||||
// WebSocket throttling, after which every socket to the host sits
|
||||
// "pending" (never opens, never closes) for minutes:
|
||||
//
|
||||
// 1. A burst of simultaneous attempts — page load opens Vite's HMR
|
||||
// socket plus several of ours at the same moment, and every refresh
|
||||
// repeats the burst. socketSlot() spaces new sockets out.
|
||||
// 2. Too-frequent retries — so failed attempts back off exponentially
|
||||
// (a few seconds, doubling to half a minute), reset only after a
|
||||
// connection stayed open long enough to count as healthy. A socket
|
||||
// that closes right after opening must NOT reset the backoff.
|
||||
export function reconnectPolicy({ min = 2000, max = 30000, healthyAfter = 30000 } = {}) {
|
||||
let delay = min
|
||||
let openedAt = 0
|
||||
return {
|
||||
// Stamp a socket that just opened.
|
||||
opened() {
|
||||
openedAt = Date.now()
|
||||
},
|
||||
// The socket closed: the wait before the next attempt (up to 50%
|
||||
// jitter; the base doubles per failure). A healthy streak resets it.
|
||||
closed() {
|
||||
if (openedAt && Date.now() - openedAt >= healthyAfter) delay = min
|
||||
openedAt = 0
|
||||
const wait = Math.round(delay * (1 + Math.random() * 0.5))
|
||||
delay = Math.min(delay * 2, max)
|
||||
return wait
|
||||
},
|
||||
}
|
||||
}
|
||||
|
||||
// Sockets created at the same moment (page load: Vite's HMR socket plus
|
||||
// ours) read as one burst to the browser's throttling. Space new sockets
|
||||
// out: each call reserves a slot a beat after the previous one.
|
||||
let nextSlot = 0
|
||||
export function socketSlot() {
|
||||
const now = Date.now()
|
||||
const wait = Math.max(0, nextSlot - now)
|
||||
nextSlot = Math.max(now, nextSlot) + 300
|
||||
return wait
|
||||
}
|
||||
|
||||
// A socket still CONNECTING after this long counts as a failed attempt:
|
||||
// browser throttling leaves sockets "pending" (no open, no close) for
|
||||
// minutes, and without a watchdog the app would wait on one forever (the
|
||||
// recurring empty editor). Closing it fires onclose, which reschedules
|
||||
// through the policy's backoff — it never reconnects aggressively itself.
|
||||
export function watchConnecting(ws, label) {
|
||||
return setTimeout(() => {
|
||||
if (ws.readyState === WebSocket.CONNECTING) {
|
||||
console.warn(`[pagerite] ${label} socket stuck connecting — closing it, retrying with backoff`)
|
||||
ws.close()
|
||||
}
|
||||
}, 10_000)
|
||||
}
|
||||
@@ -0,0 +1,26 @@
|
||||
// The app's shared Pinia store — cross-bundle UI state lives here. Every
|
||||
// entry chunk imports its own copy of this module, so the Pinia instance
|
||||
// is parked on window (Vue itself is a shared chunk, so reactivity works
|
||||
// across the copies). Pass `pinia` explicitly when calling useStore
|
||||
// outside a component (module code, no active instance).
|
||||
import { createPinia, defineStore } from 'pinia'
|
||||
|
||||
export const pinia = (window.__pageritePinia ??= createPinia())
|
||||
|
||||
export const useStore = defineStore('pagerite', {
|
||||
state: () => ({
|
||||
// The ONE language selection, v-modeled by both dropdowns (editor
|
||||
// tabs, public corner selector): '' = no explicit pick (the page's
|
||||
// primary / autodetect), else a concrete tag. A pick from either
|
||||
// dropdown is visible to everyone immediately.
|
||||
lang: '',
|
||||
// The language the current page was actually served in (set by
|
||||
// pagerite.js per navigation) — the selector's highlight fallback
|
||||
// when there is no explicit pick.
|
||||
servedLang: '',
|
||||
// The public selector's page data: hreflang alternates
|
||||
// ([{tag, href, primary}]) and whether to show at all.
|
||||
langAlternates: [],
|
||||
langSelectorActive: false,
|
||||
}),
|
||||
})
|
||||
@@ -3,6 +3,30 @@
|
||||
// Used by BannerEditor (banner design changes), SiteEditor (theme changes)
|
||||
// and StructureEditor (tree navigation).
|
||||
|
||||
import { apiFetch } from 'paskia'
|
||||
|
||||
// Drop the public page runtime's in-memory prefetch cache. Editors call this
|
||||
// whenever a site-wide or page change invalidates the cached HTML of other
|
||||
// pages (theme, headings, structure, banner, etc.). The cache is rebuilt by
|
||||
// re-preloading visible links once the editor panel closes.
|
||||
export function dropPageCache() {
|
||||
dispatchEvent(new CustomEvent('pagerite:drop-page-cache'))
|
||||
}
|
||||
|
||||
// The editor's language override (set by EditorShell): while the panel is
|
||||
// open, its language selection wins over the normal preferences — every
|
||||
// in-place re-render asks for that language explicitly, and pagerite.js
|
||||
// applies it to its own fetches and prefetches (pagerite:session-lang).
|
||||
// The primary selection pins by its code: ?lang=<primary> selects the
|
||||
// original explicitly (i18n.select_language). Panel closed, the session's
|
||||
// chosen language (window.__pageriteLang) takes over — the pick stays.
|
||||
let overrideLang = null // the ?lang= value in force, null = the session's
|
||||
|
||||
export function setLangOverride(queryLang) {
|
||||
overrideLang = queryLang || null
|
||||
dispatchEvent(new CustomEvent('pagerite:session-lang', { detail: { lang: overrideLang } }))
|
||||
}
|
||||
|
||||
export function runScripts(root) {
|
||||
// Scripts injected via innerHTML do not execute; re-create them.
|
||||
if (!root) return
|
||||
@@ -59,33 +83,45 @@ function swapRegions(doc) {
|
||||
curUserStyle.remove()
|
||||
}
|
||||
// Theme and other public stylesheets live in <head>, rendered with stable
|
||||
// ids by the backend; sync them positionally so the custom CSS (rendered
|
||||
// last) always keeps winning by order. Diff-based: unchanged sheets keep
|
||||
// their elements, so their @keyframes are never torn down (re-creating
|
||||
// keyframes would replay the editor's slide-in animation).
|
||||
const freshLinks = [...doc.head.querySelectorAll('link[rel="stylesheet"]')]
|
||||
const freshIds = new Set(freshLinks.map((l) => l.id))
|
||||
for (const link of [...document.head.querySelectorAll('link[rel="stylesheet"]')]) {
|
||||
if (!link.dataset.pagerite && !freshIds.has(link.id)) link.remove()
|
||||
// ids by the backend (links in dev, inline <style> elements in prod);
|
||||
// sync them positionally so the custom CSS (rendered last) always keeps
|
||||
// winning by order. Diff-based: unchanged sheets keep their elements, so
|
||||
// their @keyframes are never torn down (re-creating keyframes would
|
||||
// replay the editor's slide-in animation).
|
||||
const sel = 'link[rel="stylesheet"][id], style[id]'
|
||||
const freshEls = [...doc.head.querySelectorAll(sel)]
|
||||
const freshIds = new Set(freshEls.map((el) => el.id))
|
||||
for (const el of [...document.head.querySelectorAll(sel)]) {
|
||||
if (!freshIds.has(el.id)) el.remove()
|
||||
}
|
||||
// Insert missing sheets in the fresh document's order, each right after
|
||||
// its predecessor's element. The first sheet rendered is always the base
|
||||
// CSS, so its link doubles as the fallback anchor when nothing matched yet
|
||||
// (e.g. no theme was selected before and the position is otherwise lost).
|
||||
// CSS, so its element doubles as the fallback anchor when nothing matched
|
||||
// yet (e.g. no theme was selected before and the position is otherwise
|
||||
// lost).
|
||||
let anchor = null
|
||||
for (const link of freshLinks) {
|
||||
const cur = link.id && document.getElementById(link.id)
|
||||
if (cur && cur.href === link.href) {
|
||||
for (const el of freshEls) {
|
||||
const cur = el.id && document.getElementById(el.id)
|
||||
if (cur && cur.outerHTML === el.outerHTML) {
|
||||
anchor = cur
|
||||
continue
|
||||
}
|
||||
const el = document.importNode(link, true)
|
||||
// Same id, new URL (theme switch): replace in place, keeping position.
|
||||
if (cur) cur.replaceWith(el)
|
||||
else if (anchor) anchor.after(el)
|
||||
else document.getElementById('pagerite-base')?.after(el) ?? document.head.append(el)
|
||||
anchor = el
|
||||
const imported = document.importNode(el, true)
|
||||
// Same id, new content (theme switch): replace in place, keeping position.
|
||||
if (cur) cur.replaceWith(imported)
|
||||
else if (anchor) anchor.after(imported)
|
||||
else {
|
||||
const base = document.getElementById('pagerite-base')
|
||||
if (base) base.after(imported)
|
||||
else document.head.append(imported)
|
||||
}
|
||||
anchor = imported
|
||||
}
|
||||
// The served language rides on <html> (lang + dir, rtl for e.g. Arabic):
|
||||
// follow the swapped page. The editor panel carries its own lang="en"
|
||||
// dir="ltr", so it is unaffected.
|
||||
document.documentElement.lang = doc.documentElement.lang
|
||||
document.documentElement.dir = doc.documentElement.dir
|
||||
// The editor keeps its own title while open; only inherit the server title
|
||||
// when navigating outside the editor (e.g. fetch-navigation swaps).
|
||||
if (!document.body.classList.contains('editing')) {
|
||||
@@ -96,22 +132,35 @@ function swapRegions(doc) {
|
||||
// Fetch /p, swap its regions into the live page and replaceState to it.
|
||||
// Returns the final URL (after redirects), or null when the fetch did not
|
||||
// yield a page. Category and missing URLs render a placeholder 404 page —
|
||||
// fine to swap in (new pages are created by editing them).
|
||||
// fine to swap in (new pages are created by editing them). The fetch pins
|
||||
// the editor's language override, or — panel closed — the session's chosen
|
||||
// language (window.__pageriteLang).
|
||||
export async function loadPlain(p) {
|
||||
let doc
|
||||
let finalUrl = `/${p}`
|
||||
let html
|
||||
try {
|
||||
const res = await fetch(finalUrl)
|
||||
const pin = overrideLang || window.__pageriteLang
|
||||
const res = await apiFetch(pin ? `${finalUrl}?lang=${pin}` : finalUrl)
|
||||
const type = res.headers.get('content-type') || ''
|
||||
if (!type.includes('text/html')) return null
|
||||
if (res.redirected) finalUrl = res.url
|
||||
doc = new DOMParser().parseFromString(await res.text(), 'text/html')
|
||||
html = await res.text()
|
||||
doc = new DOMParser().parseFromString(html, 'text/html')
|
||||
} catch { return null }
|
||||
if (!doc.getElementById('main')) return null
|
||||
swapRegions(doc)
|
||||
history.replaceState(null, '', finalUrl)
|
||||
// The address bar keeps the pretty URL: a language query is a fetch
|
||||
// detail, never shown (pagerite.js's initial ?lang= works the same).
|
||||
const pretty = new URL(finalUrl, location.href)
|
||||
pretty.searchParams.delete('lang')
|
||||
history.replaceState(history.state, '', pretty)
|
||||
runScripts(document.getElementById('page-banner'))
|
||||
runScripts(document.getElementById('main'))
|
||||
// Keep pagerite.js's in-memory page cache in sync with the fresh copy.
|
||||
// The URL is announced as fetched: a language-pinned copy caches under
|
||||
// its own ?lang= key, where navigation with the same pin finds it.
|
||||
dispatchEvent(new CustomEvent('pagerite:page-fetched', { detail: { url: finalUrl, html } }))
|
||||
dispatchEvent(new CustomEvent('pagerite:preview')) // re-inject + re-tuck the edit pens
|
||||
return finalUrl
|
||||
}
|
||||
|
||||
@@ -5,13 +5,14 @@
|
||||
* Configures Vite for FastAPI backend integration:
|
||||
* - Proxies /api/* requests to the FastAPI backend
|
||||
* - Builds to the Python module's frontend-build directory
|
||||
* - Disables Vite's screen clearing on startup
|
||||
*
|
||||
* Options:
|
||||
* paths - Array of paths to proxy (default: ["/api"])
|
||||
* paths - Array of paths to proxy (default: ['/api'])
|
||||
*/
|
||||
|
||||
export default function fastapiVue({ paths = ["/api"] } = {}) {
|
||||
const backendUrl = process.env.PAGERITE_BACKEND_URL || "http://localhost:3200"
|
||||
export default function fastapiVue({ paths = ['/api'] } = {}) {
|
||||
const backendUrl = process.env.PAGERITE_BACKEND_URL || 'http://localhost:8210'
|
||||
|
||||
// Build proxy configuration for each path
|
||||
const proxy = {}
|
||||
@@ -24,11 +25,12 @@ export default function fastapiVue({ paths = ["/api"] } = {}) {
|
||||
}
|
||||
|
||||
return {
|
||||
name: "vite-plugin-fastapi-pagerite",
|
||||
name: 'vite-plugin-fastapi-pagerite',
|
||||
config: () => ({
|
||||
clearScreen: false,
|
||||
server: { proxy },
|
||||
build: {
|
||||
outDir: "../pagerite/frontend-build",
|
||||
outDir: '../pagerite/frontend-build',
|
||||
emptyOutDir: true,
|
||||
},
|
||||
}),
|
||||
|
||||
@@ -5,17 +5,18 @@ import { defineConfig } from 'vite'
|
||||
import vue from '@vitejs/plugin-vue'
|
||||
import vueDevTools from 'vite-plugin-vue-devtools'
|
||||
|
||||
const backendUrl = process.env.PAGERITE_BACKEND_URL || 'http://localhost:3200'
|
||||
const backendUrl = process.env.PAGERITE_BACKEND_URL || 'http://localhost:8210'
|
||||
|
||||
// Proxy content pages (/slug, /path/to/slug) to the FastAPI backend in dev.
|
||||
// Excludes Vite internals (/@..., /src, /node_modules, /__...) and the
|
||||
// backend's /_ prefix. /_api and /_f are handled by the fastapi-vue plugin.
|
||||
const CONTENT_PROXY = '^\\/(?!_|@|src|node_modules|__)(?:[^./?]+(?:\\/[^./?]+)*)?(?:\\?.*)?$'
|
||||
// Proxy everything except Vite's own dev-time paths and the backend machinery
|
||||
// to the FastAPI backend in dev. /_api, /_f, /_themes, /_fonts and /_a are
|
||||
// handled by the fastapi-vue plugin, and /@..., /src, /node_modules, /__...
|
||||
// stay with Vite.
|
||||
const CONTENT_PROXY = '^(?!/_|/@|/src|/node_modules|/__).*$'
|
||||
|
||||
// https://vite.dev/config/
|
||||
export default defineConfig({
|
||||
plugins: [
|
||||
fastapiVue({ paths: ["/_api", "/_f", "/_themes"] }),
|
||||
fastapiVue({ paths: ["/_api", "/_f", "/_themes", "/_fonts", "/_a", "/_ws", "/_translate"] }),
|
||||
vue(),
|
||||
vueDevTools(),
|
||||
],
|
||||
@@ -25,10 +26,19 @@ export default defineConfig({
|
||||
},
|
||||
},
|
||||
appType: 'mpa', // no SPA fallback; every HTML page is served by FastAPI
|
||||
resolve: {
|
||||
alias: {
|
||||
// All components are precompiled SFCs — drop the runtime template
|
||||
// compiler (~60 kB min) from the bundle.
|
||||
vue: 'vue/dist/vue.runtime.esm-bundler.js',
|
||||
},
|
||||
},
|
||||
build: {
|
||||
// The main editor bundle (CodeMirror + Vue) is intentionally one chunk.
|
||||
chunkSizeWarningLimit: 1200,
|
||||
// Mirror the URL space in the build output: hashed files land under
|
||||
// frontend-build/_assets/ and the Frontend serves the build directory
|
||||
// at the site root (frontend/public/favicon.ico -> /favicon.ico).
|
||||
// at the site root.
|
||||
manifest: true,
|
||||
assetsDir: '_assets',
|
||||
rollupOptions: {
|
||||
@@ -39,6 +49,8 @@ export default defineConfig({
|
||||
input: {
|
||||
main: fileURLToPath(new URL('./src/main.js', import.meta.url)),
|
||||
pagerite: fileURLToPath(new URL('./src/pagerite.js', import.meta.url)),
|
||||
analytics: fileURLToPath(new URL('./src/analytics-main.js', import.meta.url)),
|
||||
langselect: fileURLToPath(new URL('./src/langselect-main.js', import.meta.url)),
|
||||
// Only the base CSS is built; theme/banner-design stylesheets live
|
||||
// in pagerite/themes/{name}/ and are served by the backend as-is.
|
||||
pagerite_base: fileURLToPath(new URL('./src/assets/pagerite.css', import.meta.url)),
|
||||
|
||||
@@ -1,31 +1,71 @@
|
||||
# auto-upgrade@fastapi-vue-setup - remove this if you modify this file
|
||||
"""Command-line entry point for running the backend server."""
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
from fastapi_vue import server
|
||||
import msgspec
|
||||
from fastapi_vue import env, server
|
||||
|
||||
DEFAULT_PORT = 3100
|
||||
DEVMODE = os.getenv("PAGERITE_DEV") == "1"
|
||||
from pagerite.config import Config
|
||||
|
||||
DEFAULT_PORT = 8100
|
||||
os.environ["FASTAPI_VUE"] = "PAGERITE"
|
||||
|
||||
|
||||
def main() -> None:
|
||||
"""Run the backend server with optional arguments."""
|
||||
parser = argparse.ArgumentParser(description="Run the pagerite server.")
|
||||
parser.add_argument(
|
||||
"hostname",
|
||||
nargs="?",
|
||||
default="localhost",
|
||||
help=(
|
||||
"Public hostname of the site; names the data directory "
|
||||
"<hostname>/{content.kantadb, analytics.json, files} under the "
|
||||
"cwd (default: localhost)."
|
||||
),
|
||||
)
|
||||
parser.add_argument(
|
||||
"-l",
|
||||
"--listen",
|
||||
action="append",
|
||||
help=(f"Endpoint (default: localhost:{DEFAULT_PORT})."),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--dbip",
|
||||
action="store_true",
|
||||
help="Download/update the DB-IP city lite database before starting.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
dev = {"reload": True, "reload_dirs": ["pagerite"]} if DEVMODE else {}
|
||||
# Hand configuration to the app as JSON in PAGERITE_CONFIG; it must be
|
||||
# set before pagerite.app is imported, as state.py reads it at import
|
||||
# time (data directory, public origin).
|
||||
os.environ["PAGERITE_CONFIG"] = msgspec.json.encode(
|
||||
Config(hostname=args.hostname, dbip=args.dbip)
|
||||
).decode()
|
||||
run_args: dict = {}
|
||||
if args.hostname != "localhost":
|
||||
# A public site sits behind TLS on its hostname; show that URL in the
|
||||
# startup box instead of the local listen address.
|
||||
run_args["startup_box"] = f"{{Name}} {{version}}\nhttps://{args.hostname}"
|
||||
server.run(
|
||||
"pagerite.app:app",
|
||||
listen=args.listen,
|
||||
default_port=DEFAULT_PORT,
|
||||
**dev,
|
||||
server_header=False,
|
||||
reload=Path(__file__).parent if env.dev else False,
|
||||
# Partial log config, merged over uvicorn's default by fastapi-vue:
|
||||
# root prints at WARNING in production / INFO in dev. Keep our own
|
||||
# loggers audible in production, and silence httpx's per-request INFO
|
||||
# (tracking._schedule_favicon_fetch logs its own one-line summary).
|
||||
log_config={
|
||||
"loggers": {
|
||||
"pagerite": {"level": "INFO"},
|
||||
"httpx": {"level": "WARNING"},
|
||||
}
|
||||
},
|
||||
**run_args,
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,781 @@
|
||||
"""Editor REST API and WebSocket sessions.
|
||||
|
||||
The management endpoints behind the SSO forward-auth gate: the site tree
|
||||
(``/_api/pages``), structure operations (``/_api/structure``), site-wide
|
||||
settings (``/_api/settings``), task-list toggles (``/_api/toggle-task``),
|
||||
the translations refresh (``/_api/translations``), the editor session
|
||||
socket (``/_api/ws/editor``), and the translator service channel
|
||||
(``/_translate/{clientkey}`` — deliberately NOT under ``/_api``: the
|
||||
server-generated key in the path is the access control).
|
||||
"""
|
||||
|
||||
import logging
|
||||
import re
|
||||
from datetime import UTC, datetime
|
||||
|
||||
from fastapi import (
|
||||
APIRouter,
|
||||
HTTPException,
|
||||
Request,
|
||||
WebSocket,
|
||||
WebSocketDisconnect,
|
||||
)
|
||||
from html5tagger import E
|
||||
from pydantic import BaseModel
|
||||
|
||||
from pagerite import i18n, views
|
||||
from pagerite.chunks import store_chunks
|
||||
from pagerite.data import (
|
||||
Node,
|
||||
append_order,
|
||||
find_slot,
|
||||
node_markdown,
|
||||
resolve,
|
||||
sorted_nodes,
|
||||
)
|
||||
from pagerite.markdown import render, toggle_task
|
||||
from pagerite.state import (
|
||||
_check_reserved,
|
||||
_ensure,
|
||||
_invalidate_pages,
|
||||
_remove_page,
|
||||
data,
|
||||
dispatcher,
|
||||
kanta,
|
||||
)
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
class PageIn(BaseModel):
|
||||
"""Payload for creating or replacing a page."""
|
||||
|
||||
title: str
|
||||
markdown: str
|
||||
published: bool = True
|
||||
banner: str | None = None # None keeps the existing banner
|
||||
|
||||
|
||||
@router.get("/_api/pages")
|
||||
async def list_pages(lang: str | None = None) -> list[dict]:
|
||||
"""The site tree for the structure editor (all nodes, drafts included).
|
||||
|
||||
Nested by slug; each node carries its full path, menu order, flags and
|
||||
language settings (``language`` is the node's own primary-language
|
||||
setting, "" = inherit; ``primary`` is the resolved effective one).
|
||||
With a ``?lang=`` translation, titles come out in that language where a
|
||||
translation exists (``translated`` flags it — true trivially for rows
|
||||
whose primary language IS the selected one; other rows fall back to
|
||||
the original title, dimmed) — the structure itself (slugs, order,
|
||||
hierarchy) is language-independent.
|
||||
"""
|
||||
tag = i18n.base_tag(lang or "")
|
||||
titles = i18n.title_map(data, tag) if tag else {}
|
||||
|
||||
def dump(nodes: dict[str, Node], prefix: str, inherited: str) -> list[dict]:
|
||||
out = []
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
primary = node.language or inherited
|
||||
out.append(
|
||||
{
|
||||
"slug": slug,
|
||||
"path": path,
|
||||
"title": titles.get(path) or node.title,
|
||||
"translated": path in titles or (bool(tag) and primary == tag),
|
||||
"order": node.order,
|
||||
"published": node.published,
|
||||
"has_content": node.chunks is not None,
|
||||
"language": node.language,
|
||||
"primary": primary,
|
||||
"children": dump(node.children, path, primary),
|
||||
}
|
||||
)
|
||||
return out
|
||||
|
||||
return dump(data.menu, "", i18n.ORIGINAL_LANGUAGE)
|
||||
|
||||
|
||||
@router.put("/_api/pages/{path:path}", status_code=204)
|
||||
async def save_page(
|
||||
path: str, page: PageIn, request: Request, lang: str | None = None
|
||||
) -> None:
|
||||
"""Create or replace the page at a slug path ("" or "/" = front page).
|
||||
|
||||
Missing ancestors are created as content-less category labels. Giving
|
||||
a category markdown turns it into a landing page. Empty markdown (after
|
||||
stripping) creates an empty page that renders with just its title —
|
||||
saving never deletes; use DELETE to remove a page (the page editor
|
||||
issues DELETE when you save empty text).
|
||||
|
||||
With a ``?lang=`` query (a translation, not the primary language) the
|
||||
save is a translated-view edit (docs/localization.md): the markdown is
|
||||
diffed against the currently served hybrid and recorded as user
|
||||
overrides under ``overrides[path][lang]`` — node.chunks and the
|
||||
original-language fields (title, published, banner) stay untouched.
|
||||
"""
|
||||
path = path.strip("/")
|
||||
_check_reserved(path)
|
||||
lang = i18n.base_tag(lang or "")
|
||||
if lang and lang != i18n.primary_lang(data.menu, path):
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is None or node.chunks is None:
|
||||
raise HTTPException(404, "no such page")
|
||||
if not node.chunks:
|
||||
raise HTTPException(400, "the page has no content to translate")
|
||||
with kanta.transaction(
|
||||
f"page:{lang}", user=request.headers.get("remote-user"), extra=path
|
||||
):
|
||||
# Overrides alone make the translated version exist.
|
||||
if i18n.record_override(data, node, path, lang, page.markdown):
|
||||
_invalidate_pages()
|
||||
return
|
||||
with kanta.transaction("page", user=request.headers.get("remote-user"), extra=path):
|
||||
node = _ensure(data.menu, path)
|
||||
node.title = page.title
|
||||
node.chunks = store_chunks(data.chunks, page.markdown)
|
||||
node.published = page.published
|
||||
if page.banner is not None:
|
||||
node.banner = page.banner
|
||||
node.modified = datetime.now(UTC)
|
||||
_invalidate_pages()
|
||||
|
||||
|
||||
@router.delete("/_api/pages/{path:path}", status_code=204)
|
||||
async def delete_page(path: str, request: Request) -> None:
|
||||
"""Delete a node by slug path.
|
||||
|
||||
A category (node with children) loses only its landing page and stays
|
||||
as a content-less label; a childless node is removed entirely.
|
||||
"""
|
||||
path = path.strip("/")
|
||||
_check_reserved(path)
|
||||
with kanta.transaction(
|
||||
"page:delete", user=request.headers.get("remote-user"), extra=path
|
||||
):
|
||||
if not _remove_page(data.menu, path):
|
||||
raise HTTPException(404, "no such page")
|
||||
_invalidate_pages()
|
||||
|
||||
|
||||
class StructureOp(BaseModel):
|
||||
"""Rearrange the site tree: reorder, move/rename or retitle a node.
|
||||
|
||||
`order` is a fresh fractional key computed client-side from the node's
|
||||
new siblings (a value halfway between them); all other items keep
|
||||
theirs. `move_to` is the full target path — the parent must exist and
|
||||
the new slug be free. Moves carry the whole subtree. The front page is
|
||||
just the top-level node with slug "": renaming it away leaves no front
|
||||
page ("/" then redirects to the first nav item), and any childless
|
||||
top-level node can take the empty slug to become the front page.
|
||||
|
||||
With `lang` (a translation, not the node's primary language) a `title`
|
||||
edit writes a per-language title fragment instead of the original — the
|
||||
same storage as machine title translations (docs/localization.md);
|
||||
sending the original's text removes the override. Structural fields are
|
||||
not combinable with a translated title edit.
|
||||
|
||||
`language` sets the node's primary language (a BCP-47 base tag; "" =
|
||||
inherit from the nearest ancestor, the front page last, site default
|
||||
"en" final — Node.language), inherited by the whole subtree.
|
||||
"""
|
||||
|
||||
path: str
|
||||
order: float | None = None
|
||||
move_to: str | None = None
|
||||
title: str | None = None
|
||||
lang: str | None = None
|
||||
language: str | None = None
|
||||
|
||||
|
||||
@router.post("/_api/structure", status_code=204)
|
||||
async def update_structure(op: StructureOp, request: Request) -> None:
|
||||
"""Apply one structure operation (see StructureOp)."""
|
||||
path = op.path.strip("/")
|
||||
chain = resolve(data.menu, path)
|
||||
if chain is None:
|
||||
raise HTTPException(404, "no such page")
|
||||
node = chain[-1]
|
||||
lang = i18n.base_tag(op.lang or "")
|
||||
if op.language is not None:
|
||||
# Primary-language setting (inherited by the subtree): reselects
|
||||
# what "the original" means for the node — its language is part of
|
||||
# every render, so a change invalidates everywhere.
|
||||
language = i18n.base_tag(op.language)
|
||||
with kanta.transaction(
|
||||
"page:language", user=request.headers.get("remote-user"), extra=path
|
||||
):
|
||||
if language != node.language:
|
||||
node.language = language
|
||||
_invalidate_pages()
|
||||
return
|
||||
if op.title is not None and lang and lang != i18n.primary_lang(data.menu, path):
|
||||
# Translated title (i18n.set_title_translation): original title,
|
||||
# slugs and hierarchy stay untouched.
|
||||
with kanta.transaction(
|
||||
f"page:{lang}:title", user=request.headers.get("remote-user"), extra=path
|
||||
):
|
||||
if i18n.set_title_translation(data, node, lang, op.title):
|
||||
_invalidate_pages()
|
||||
return
|
||||
target = op.move_to.strip("/") if op.move_to is not None else None
|
||||
if target is not None and target != path:
|
||||
_check_reserved(target)
|
||||
if path and target.startswith(f"{path}/"):
|
||||
raise HTTPException(400, "cannot move a page under itself")
|
||||
slot = find_slot(data.menu, target)
|
||||
if slot is None:
|
||||
raise HTTPException(404, "target parent does not exist")
|
||||
tnodes, tslug = slot
|
||||
if tslug in tnodes:
|
||||
raise HTTPException(400, "target path exists")
|
||||
if not tslug and node.children:
|
||||
raise HTTPException(400, "the front page cannot have children")
|
||||
# One structure call can combine a title set, a move/rename and a
|
||||
# reorder; the action names the most significant of them.
|
||||
action = (
|
||||
"page:slug"
|
||||
if target is not None and target != path
|
||||
else "page:title"
|
||||
if op.title is not None
|
||||
else "structure:reorder"
|
||||
)
|
||||
with kanta.transaction(action, user=request.headers.get("remote-user"), extra=path):
|
||||
if op.title is not None:
|
||||
node.title = op.title
|
||||
if target is not None and target != path:
|
||||
snodes, sslug = find_slot(data.menu, path)
|
||||
del snodes[sslug]
|
||||
# A pure rename (same parent) keeps its position; only a move
|
||||
# to another level appends at the end (unless an order came
|
||||
# with the drop).
|
||||
same_level = path.rpartition("/")[0] == target.rpartition("/")[0]
|
||||
node.order = (
|
||||
op.order
|
||||
if op.order is not None
|
||||
else node.order
|
||||
if same_level
|
||||
else append_order(tnodes)
|
||||
)
|
||||
tnodes[tslug] = node
|
||||
elif op.order is not None:
|
||||
node.order = op.order
|
||||
node.modified = datetime.now(UTC)
|
||||
_invalidate_pages()
|
||||
|
||||
|
||||
@router.get("/_api/settings")
|
||||
async def get_settings() -> dict:
|
||||
"""Site-wide settings (brand, theme, custom CSS and favicon URL), plus
|
||||
the themes, banner designs and user fonts available on disk for the
|
||||
selectors, the translator service keys and the wanted translation
|
||||
languages (for the /_translate socket)."""
|
||||
return {
|
||||
"brand": data.brand,
|
||||
"brand_html": data.brand_html,
|
||||
"theme": data.theme,
|
||||
"custom_css": data.custom_css,
|
||||
"favicon": f"/_f/{data.favicon}" if data.favicon else "",
|
||||
"themes": views._theme_info(),
|
||||
"banner_designs": views._banner_design_names(),
|
||||
"fonts": views._user_fonts(),
|
||||
"transition": data.transition,
|
||||
"transitions": views._transition_names(),
|
||||
"translate_keys": data.translate_keys,
|
||||
# The site default primary language: the front page's resolved
|
||||
# setting (every page may override it, inherited down the tree).
|
||||
"primary_lang": i18n.primary_lang(data.menu, ""),
|
||||
"translate_langs": sorted(data.translate_langs),
|
||||
}
|
||||
|
||||
|
||||
class SettingsIn(BaseModel):
|
||||
"""Payload for updating site-wide settings."""
|
||||
|
||||
brand: str
|
||||
theme: str
|
||||
custom_css: str
|
||||
brand_html: str = ""
|
||||
transition: str = "cube"
|
||||
translate_langs: list[str] | None = None # None keeps the current set
|
||||
translate_keys: dict[str, str] | None = None # None keeps the current keys
|
||||
|
||||
|
||||
@router.put("/_api/settings", status_code=204)
|
||||
async def put_settings(settings: SettingsIn, request: Request) -> None:
|
||||
"""Update site-wide settings; invalidates cached pages and ETags."""
|
||||
with kanta.transaction("settings", user=request.headers.get("remote-user")):
|
||||
data.brand = settings.brand
|
||||
data.brand_html = settings.brand_html
|
||||
data.theme = settings.theme
|
||||
data.custom_css = settings.custom_css
|
||||
data.transition = settings.transition
|
||||
if settings.translate_langs is not None:
|
||||
# Any language may be a target — including the site default
|
||||
# (an article in another language can be translated INTO it);
|
||||
# a node's own primary is excluded per article, not here.
|
||||
data.translate_langs = {
|
||||
tag: True
|
||||
for lang in settings.translate_langs
|
||||
if (tag := i18n.base_tag(lang))
|
||||
}
|
||||
if settings.translate_keys is not None:
|
||||
data.translate_keys = settings.translate_keys
|
||||
_invalidate_pages()
|
||||
|
||||
|
||||
@router.delete("/_api/translations", status_code=204)
|
||||
async def delete_translations(request: Request) -> None:
|
||||
"""Drop all machine translations (Data.trans) so the dispatcher
|
||||
re-translates everything from scratch (a translate:reset action:
|
||||
the invalidation hook re-offers every fragment to connected
|
||||
translators). User overrides are kept; the availability index
|
||||
(node.langs) is rebuilt from them — overrides alone still make a
|
||||
language exist on a page."""
|
||||
with kanta.transaction("translate:reset", user=request.headers.get("remote-user")):
|
||||
i18n.clear_translations(data)
|
||||
_invalidate_pages()
|
||||
# Fragments rejected this run (segment validation) stay skipped no
|
||||
# longer: a refresh is precisely the "another chance" for them.
|
||||
dispatcher.reset_validation_failures()
|
||||
|
||||
|
||||
class ToggleTaskIn(BaseModel):
|
||||
"""Payload for toggling one task-list checkbox."""
|
||||
|
||||
path: str
|
||||
index: int
|
||||
markdown: str | None = None
|
||||
|
||||
|
||||
@router.post("/_api/toggle-task")
|
||||
async def toggle_task_endpoint(body: ToggleTaskIn, request: Request) -> dict[str, str]:
|
||||
"""Toggle the Nth task-list checkbox in a page's Markdown source.
|
||||
|
||||
If ``markdown`` is provided the source is left untouched and the toggled
|
||||
Markdown is returned (used while the page editor is open, so the live
|
||||
CodeMirror document can be updated). Otherwise the stored page at
|
||||
``path`` is read, toggled, and saved.
|
||||
"""
|
||||
path = body.path.strip("/")
|
||||
_check_reserved(path)
|
||||
if body.markdown is not None:
|
||||
new_markdown = toggle_task(body.markdown, body.index)
|
||||
if new_markdown is None:
|
||||
raise HTTPException(400, "invalid task index")
|
||||
return {"markdown": new_markdown}
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is None or node.chunks is None:
|
||||
raise HTTPException(404, "no such page")
|
||||
new_markdown = toggle_task(node_markdown(data, node) or "", body.index)
|
||||
if new_markdown is None:
|
||||
raise HTTPException(400, "invalid task index")
|
||||
with kanta.transaction("page", user=request.headers.get("remote-user"), extra=path):
|
||||
# Re-chunk like any save: only the chunk containing the toggled
|
||||
# checkbox gets a new hash, the rest keep theirs.
|
||||
node.chunks = store_chunks(data.chunks, new_markdown)
|
||||
node.modified = datetime.now(UTC)
|
||||
_invalidate_pages()
|
||||
return {"markdown": new_markdown}
|
||||
|
||||
|
||||
# WebSocket API for external translation services (not under /_api: it is keyed
|
||||
# with Data.translate_keys instead of the SSO forward-auth). The dispatcher —
|
||||
# protocol, connected clients and the job pipeline — lives in translate.py.
|
||||
@router.websocket("/_translate/{clientkey}")
|
||||
async def translate_ws(ws: WebSocket, clientkey: str) -> None:
|
||||
"""Translator service channel (docs/localization.md).
|
||||
|
||||
Deliberately NOT under /_api/: the external forward-auth is skipped;
|
||||
the server-generated client key in the path is the access control
|
||||
(``Data.translate_keys``: key -> display name; the first is generated
|
||||
at bootstrap, all are shown in the admin's /_api/settings).
|
||||
"""
|
||||
await dispatcher.handle_ws(ws, clientkey)
|
||||
|
||||
|
||||
@router.websocket("/_api/ws/editor")
|
||||
async def editor_ws(ws: WebSocket) -> None:
|
||||
"""Editor session: open pages, render previews, save — over one socket.
|
||||
|
||||
Stateless protocol (each message carries the path):
|
||||
<- {"type": "open", "path", "lang"?}
|
||||
-> {"type": "doc", "path", "exists", "title", "markdown", "published",
|
||||
"banner", "banner_design", "banner_from", "banner_design_from",
|
||||
"banner_design_inherited", "description", "image", "image_resolved",
|
||||
"image_mined", "image_source", "favicon", "has_children", "large",
|
||||
"lang", "primary_lang", "langs",
|
||||
"translate_langs"}
|
||||
<- {"type": "render", "path", "markdown"}
|
||||
-> {"type": "html", "path", "html"}
|
||||
<- {"type": "save", "path", "title"?, "markdown"?, "published"?,
|
||||
"banner"?, "banner_design"?, "image"?, "large"?, "move_from"?,
|
||||
"lang"?, "base"?}
|
||||
(absent fields keep their old values; move_from: rename/move a
|
||||
page, subtree included; image: a store hash, "@favicon", "" to
|
||||
inherit, or an http(s) URL the server fetches and stores)
|
||||
-> {"type": "saved", "path"} | {"type": "error", "detail"}
|
||||
|
||||
With "lang" (a translation, not the primary language), open returns the
|
||||
effective hybrid Markdown and title for that language plus the language
|
||||
metadata the picker's UI needs; save diffs the submitted Markdown
|
||||
against "base" (the editor's shadow copy of the hybrid it started from
|
||||
— absent: the current hybrid) and records it as user overrides, and a
|
||||
changed title becomes a fragment in Data.trans — node.chunks and the
|
||||
other fields stay untouched (docs/localization.md).
|
||||
"""
|
||||
await ws.accept()
|
||||
try:
|
||||
while True:
|
||||
msg = await ws.receive_json()
|
||||
path = msg.get("path", "").strip("/")
|
||||
try:
|
||||
_check_reserved(path)
|
||||
except HTTPException:
|
||||
await ws.send_json({"type": "error", "detail": "reserved path"})
|
||||
continue
|
||||
match msg.get("type"):
|
||||
case "open":
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
# The article's primary language: its own setting,
|
||||
# inherited down the tree ("en" final fallback).
|
||||
node_lang = i18n.primary_lang(data.menu, path)
|
||||
lang = i18n.base_tag(str(msg.get("lang") or ""))
|
||||
if lang == node_lang:
|
||||
lang = ""
|
||||
markdown = ""
|
||||
title = node.title if node else ""
|
||||
if node is not None:
|
||||
markdown = node_markdown(data, node) or ""
|
||||
if lang and node.chunks is not None:
|
||||
# Translation view: the effective (hybrid)
|
||||
# Markdown and title for that language —
|
||||
# machine fragments + user overrides over the
|
||||
# original (docs/localization.md editor flow).
|
||||
markdown = i18n.hybrid_markdown(data, node, path, lang)
|
||||
title = i18n.title_map(data, lang).get(path) or title
|
||||
# The node's card image: its own setting ("" = inherit,
|
||||
# "@favicon" = the site icon), the effective one after
|
||||
# inheritance ("" = none, resolved to a store name) and
|
||||
# which node supplied an inherited one ("" = front page;
|
||||
# "" also when own/none — mirrors banner_from).
|
||||
img, img_source = views.card_image(data.menu, path)
|
||||
img = views._resolve_image_name(data, img)
|
||||
# The card preview's description and mined image,
|
||||
# from the same rendered-article heuristics as the
|
||||
# og:/twitter: meta (_description, _media).
|
||||
html = render(markdown, path).html if markdown else ""
|
||||
img_mined = views._media(html)[0] if html else ""
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "doc",
|
||||
"path": path,
|
||||
"exists": node is not None,
|
||||
"title": title,
|
||||
"markdown": markdown,
|
||||
"published": node.published if node else True,
|
||||
"banner": node.banner if node else "",
|
||||
# Own banner design setting: null = inherit,
|
||||
# "" = none, otherwise a design name.
|
||||
"banner_design": node.banner_design if node else None,
|
||||
# Which node's banner applies here ("" = front page,
|
||||
# null = default artwork); the site editor shows it
|
||||
# as the banner field's placeholder.
|
||||
"banner_from": views.banner_source(data.menu, path),
|
||||
# Which node's banner-design setting would apply on
|
||||
# inherit ("" = front page, null = the active
|
||||
# theme's default) and what design that resolves to.
|
||||
"banner_design_from": (
|
||||
src := views.banner_design_source(
|
||||
data.menu, path, data.theme
|
||||
)
|
||||
),
|
||||
"banner_design_inherited": (
|
||||
views.banner_design(data.menu, src, data.theme)
|
||||
if src is not None
|
||||
else views.theme_banner_design(data.theme)
|
||||
),
|
||||
"description": views._description(html) if html else "",
|
||||
"image": node.image if node else "",
|
||||
# For the banner panel's image label ("…used in
|
||||
# /<path>/*"): the subtree inherits it.
|
||||
"has_children": bool(node.children) if node else False,
|
||||
"image_resolved": img,
|
||||
# The site icon ("" = none): the "@favicon" own
|
||||
# setting previews/resolves against it.
|
||||
"favicon": data.favicon,
|
||||
# The image the og:/twitter: heuristics would mine
|
||||
# from the article itself ("" = none): the previews
|
||||
# show it when the node has no image of its own
|
||||
# (it beats an inherited one).
|
||||
"image_mined": img_mined,
|
||||
"image_source": (
|
||||
"" if node is None or node.image else img_source
|
||||
),
|
||||
# Card-mode override (per-article, not
|
||||
# inherited): null = automatic, otherwise
|
||||
# false = small, true = large.
|
||||
"large": node.large if node else None,
|
||||
# Language context for the editor's picker: the
|
||||
# language this Markdown represents ("" = primary),
|
||||
# the page's own primary language, the translations
|
||||
# this page already has, and the site-wide
|
||||
# configured target languages.
|
||||
"lang": lang,
|
||||
"primary_lang": node_lang,
|
||||
"langs": sorted(node.langs) if node else [],
|
||||
"translate_langs": sorted(data.translate_langs),
|
||||
}
|
||||
)
|
||||
case "render":
|
||||
markdown = msg.get("markdown", "")
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
# Expand {cards} like page_content does, so the preview
|
||||
# shows real cards, not the literal tag. No translation
|
||||
# context: the preview has no lang of its own, so cards
|
||||
# render in their originals.
|
||||
has_cards_tag = views._CARDS_TAG_RE.search(markdown) is not None
|
||||
rendered = render(
|
||||
markdown,
|
||||
path,
|
||||
node.created if node else None,
|
||||
node.modified if node else None,
|
||||
# The title is injected as h1 when the markdown has
|
||||
# none; the editor's title field edits live-preview.
|
||||
title=msg.get("title") or (node.title if node else ""),
|
||||
# Pin section anchors to the original language so the
|
||||
# preview of a translation matches the served page
|
||||
# (no-op when the previewed markdown is the original).
|
||||
anchors_from=(
|
||||
(node_markdown(data, node) or "", node.title)
|
||||
if node
|
||||
else None
|
||||
),
|
||||
directives=(
|
||||
{
|
||||
"cards": lambda args, _env, node=node, path=path: (
|
||||
views._cards_tag(data.menu, data, node, path, args)
|
||||
)
|
||||
}
|
||||
if node is not None and has_cards_tag
|
||||
else None
|
||||
),
|
||||
)
|
||||
html = rendered.html
|
||||
if node is not None and not has_cards_tag:
|
||||
# Without a {cards} tag page_content appends the
|
||||
# children's cards after the content — the preview
|
||||
# replaces the whole article, so include them here.
|
||||
doc = E.div
|
||||
with doc:
|
||||
views._cards(doc, data.menu, data, node, path)
|
||||
html += str(doc)
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "html",
|
||||
"path": path,
|
||||
"html": html,
|
||||
# Column-layout flag: the preview toggles the
|
||||
# article's .multicol class and swaps in the
|
||||
# segmented (.colseg/.cols) article html.
|
||||
"multicol": rendered.multicol,
|
||||
}
|
||||
)
|
||||
case "save":
|
||||
move_from = (msg.get("move_from") or path).strip("/")
|
||||
lang = i18n.base_tag(str(msg.get("lang") or ""))
|
||||
translated = bool(
|
||||
lang and lang != i18n.primary_lang(data.menu, move_from)
|
||||
)
|
||||
try:
|
||||
_check_reserved(move_from)
|
||||
except HTTPException:
|
||||
await ws.send_json({"type": "error", "detail": "reserved path"})
|
||||
continue
|
||||
old_chain = resolve(data.menu, move_from)
|
||||
old = old_chain[-1] if old_chain else None
|
||||
if old is None and move_from != path:
|
||||
move_from = path # nothing to carry over; plain save
|
||||
if move_from != path:
|
||||
# Rename/move: detach the node (subtree included)
|
||||
# and attach it at the new path. The target slug
|
||||
# must be free and the front page childless.
|
||||
if move_from and path.startswith(f"{move_from}/"):
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "cannot move a page under itself",
|
||||
}
|
||||
)
|
||||
continue
|
||||
tslug = path.rpartition("/")[2]
|
||||
if not tslug and old.children:
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "the front page cannot have children",
|
||||
}
|
||||
)
|
||||
continue
|
||||
tchain = resolve(data.menu, path)
|
||||
if tchain is not None:
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "target path exists",
|
||||
}
|
||||
)
|
||||
continue
|
||||
if translated and (
|
||||
move_from != path or old is None or old.chunks is None
|
||||
):
|
||||
# A translated-view save patches an existing
|
||||
# original; it cannot create or move pages.
|
||||
await ws.send_json({"type": "error", "detail": "no such page"})
|
||||
continue
|
||||
if translated and not old.chunks:
|
||||
# Nothing to anchor a translation to: the original
|
||||
# page has no content.
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "the page has no content to translate",
|
||||
}
|
||||
)
|
||||
continue
|
||||
if translated and "markdown" in msg and not msg["markdown"].strip():
|
||||
# Saving never deletes; an emptied translation would
|
||||
# render as a blank page in that language.
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "a translation cannot be emptied",
|
||||
}
|
||||
)
|
||||
continue
|
||||
image = msg.get("image")
|
||||
if image is not None:
|
||||
# Card-image setting (inherited by the subtree): a
|
||||
# 12-hex content-addressed store name, "@favicon" =
|
||||
# the site icon, "" = inherit, or an http(s) URL —
|
||||
# pasted image links are fetched and stored
|
||||
# server-side (cross-origin is CORS-blocked for the
|
||||
# browser), the stored name becomes the setting.
|
||||
image = str(image).strip()
|
||||
if image.startswith(("http://", "https://")):
|
||||
from pagerite.files import fetch_image
|
||||
|
||||
try:
|
||||
# Bare hash name, like an upload's setting.
|
||||
image = (await fetch_image(image)).split(".")[0]
|
||||
except HTTPException as e:
|
||||
await ws.send_json(
|
||||
{"type": "error", "detail": str(e.detail)}
|
||||
)
|
||||
continue
|
||||
if (
|
||||
image
|
||||
and image != "@favicon"
|
||||
and not re.fullmatch(r"[0-9a-f]{12}", image)
|
||||
):
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "image must be a store file name",
|
||||
}
|
||||
)
|
||||
continue
|
||||
large = msg.get("large")
|
||||
if "large" in msg and not (
|
||||
large is None or isinstance(large, bool)
|
||||
):
|
||||
# Card-mode override: null = automatic, true =
|
||||
# large, false = small.
|
||||
await ws.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"detail": "large must be null or a boolean",
|
||||
}
|
||||
)
|
||||
continue
|
||||
with kanta.transaction(
|
||||
f"page:{lang}" if translated else "page",
|
||||
user=ws.headers.get("remote-user"),
|
||||
extra=path,
|
||||
):
|
||||
if move_from != path:
|
||||
same_menu = (
|
||||
move_from.rpartition("/")[0] == path.rpartition("/")[0]
|
||||
)
|
||||
snodes, sslug = find_slot(data.menu, move_from)
|
||||
node = snodes.pop(sslug)
|
||||
parent = path.rpartition("/")[0]
|
||||
if parent:
|
||||
_ensure(data.menu, parent)
|
||||
tnodes, tslug = find_slot(data.menu, path)
|
||||
node.order = (
|
||||
node.order if same_menu else append_order(tnodes)
|
||||
)
|
||||
tnodes[tslug] = node
|
||||
else:
|
||||
node = old if old is not None else _ensure(data.menu, path)
|
||||
if translated:
|
||||
# node.chunks and the original-language fields
|
||||
# stay untouched: the markdown diff (against the
|
||||
# editor's shadow "base" — the hybrid it started
|
||||
# from; absent: the current hybrid) is recorded
|
||||
# as user overrides, a changed title becomes a
|
||||
# per-language title override (i18n).
|
||||
changed = False
|
||||
if "markdown" in msg:
|
||||
base = msg.get("base")
|
||||
changed = i18n.record_override(
|
||||
data,
|
||||
node,
|
||||
path,
|
||||
lang,
|
||||
msg["markdown"],
|
||||
base=base if isinstance(base, str) else None,
|
||||
)
|
||||
if "title" in msg and node.title:
|
||||
changed = (
|
||||
i18n.set_title_translation(
|
||||
data, node, lang, msg["title"]
|
||||
)
|
||||
or changed
|
||||
)
|
||||
if changed:
|
||||
_invalidate_pages()
|
||||
else:
|
||||
if "markdown" in msg:
|
||||
# Saving never deletes; empty markdown is an
|
||||
# empty page. Deletion is an explicit choice
|
||||
# by the page editor (REST DELETE).
|
||||
node.chunks = store_chunks(data.chunks, msg["markdown"])
|
||||
if "title" in msg:
|
||||
node.title = msg["title"]
|
||||
if "published" in msg:
|
||||
node.published = bool(msg["published"])
|
||||
if "banner" in msg:
|
||||
node.banner = msg["banner"]
|
||||
if "banner_design" in msg:
|
||||
node.banner_design = msg["banner_design"]
|
||||
if image is not None:
|
||||
# Part of every render's social meta and card
|
||||
# covers: a change invalidates everywhere.
|
||||
node.image = image
|
||||
if "large" in msg:
|
||||
# Per-article card-mode override (not
|
||||
# inherited); None = automatic.
|
||||
node.large = large
|
||||
node.modified = datetime.now(UTC)
|
||||
_invalidate_pages()
|
||||
await ws.send_json({"type": "saved", "path": path})
|
||||
except WebSocketDisconnect:
|
||||
pass
|
||||
@@ -1,160 +1,114 @@
|
||||
"""FastAPI application: server-rendered content pages plus Vue assets.
|
||||
"""FastAPI application assembly: server-rendered content pages plus Vue assets.
|
||||
|
||||
Route ordering matters: our routes are defined before
|
||||
``frontend.route(app, "/")`` is called, so they take priority over
|
||||
the asset routes that fastapi-vue inserts at that position during ``load()``.
|
||||
The content catch-all (``/{path:path}``) is defined last, so built
|
||||
frontend assets still win over content slugs; anything unmatched falls
|
||||
through to content (and 404 if no page exists there).
|
||||
The routes live in specialized modules, included below as APIRouters:
|
||||
|
||||
- ``pagerite.state`` — shared core, no routes: site constants, the kanta
|
||||
database, the analytics store, the fastapi-vue frontend, the render
|
||||
cache, the translator dispatcher, and the database bootstrap hooks.
|
||||
- ``pagerite.files`` — the content-addressed file store and its routes
|
||||
(``/_api/files``, ``/_f/``, ``/_themes/``, ``/_fonts/``, favicon).
|
||||
- ``pagerite.api`` — the editor REST API and WebSocket sessions
|
||||
(``/_api/*``, ``/_translate/{clientkey}``).
|
||||
- ``pagerite.tracking`` — visit analytics (``/_ws``, ``/_api/ws/analytics``,
|
||||
the ``/_a`` viewer page).
|
||||
- ``pagerite.feeds`` — machine-readable site exports: ``/llms.txt``,
|
||||
``/feed.json`` (JSON Feed) and ``/feed.xml`` (RSS).
|
||||
- ``pagerite.pages`` — the public content pages: ``/``, ``/sitemap.xml``,
|
||||
``/robots.txt`` and the ``/{path:path}`` catch-all.
|
||||
|
||||
Route ordering matters: our own routers are included before
|
||||
``frontend.route(app, "/")`` is called. That call only records the current
|
||||
route-table length; the actual asset routes are spliced in at that position
|
||||
later, when ``frontend.load()`` runs inside the lifespan — so they take
|
||||
priority over anything registered after this point but never shadow our
|
||||
own routes. The content catch-all (``/{path:path}``) is included last, so
|
||||
built frontend assets still win over content slugs; anything unmatched
|
||||
falls through to content (and 404 if no page exists there).
|
||||
|
||||
The site structure is a tree of Nodes (see data.py); URL paths resolve by
|
||||
walking the tree (``resolve``), moves are slot detach/attach
|
||||
(``find_slot``) with a fresh order key from the new siblings.
|
||||
"""
|
||||
|
||||
import mimetypes
|
||||
import os
|
||||
import re
|
||||
from collections.abc import AsyncIterator
|
||||
import asyncio
|
||||
import logging
|
||||
from collections.abc import AsyncGenerator
|
||||
from contextlib import asynccontextmanager
|
||||
from datetime import UTC, datetime
|
||||
from email.utils import format_datetime
|
||||
from pathlib import Path
|
||||
|
||||
import blake3
|
||||
from fastapi import FastAPI, HTTPException, Request, WebSocket, WebSocketDisconnect
|
||||
from fastapi.responses import HTMLResponse, RedirectResponse, Response
|
||||
from fastapi_vue import Frontend
|
||||
from kanta import Kanta
|
||||
from pydantic import BaseModel
|
||||
from fastapi import FastAPI, Request
|
||||
from fastapi.responses import Response
|
||||
from fastapi_vue import Frontend, env
|
||||
from starlette.types import ASGIApp, Receive, Scope, Send
|
||||
|
||||
from pagerite import seed, views
|
||||
from pagerite.__main__ import DEVMODE
|
||||
from pagerite.data import (
|
||||
Data,
|
||||
Node,
|
||||
append_order,
|
||||
find_slot,
|
||||
prettify,
|
||||
resolve,
|
||||
sorted_nodes,
|
||||
)
|
||||
from pagerite.markdown import has_h1, render, toggle_task
|
||||
from pagerite import api, feeds, files, pages, tracking
|
||||
from pagerite.files import file_store
|
||||
from pagerite.state import analytics_store, config, kanta
|
||||
|
||||
DB_PATH = os.getenv("PAGERITE_DB", "pagerite.kantadb")
|
||||
|
||||
# Our own data root; kanta edits it in place, reads are plain attribute access.
|
||||
data = Data()
|
||||
kanta = Kanta(DB_PATH, data)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# Vue build served at the site root, no SPA catch-all (assets only). The
|
||||
# build mirrors the URL space: hashed, immutable files live under
|
||||
# /_assets/ (assetsDir: '_/assets'), the favicon at /favicon.ico.
|
||||
BUILD_DIR = Path(__file__).with_name("frontend-build")
|
||||
frontend = Frontend(BUILD_DIR, spa=False, cached="/_assets/")
|
||||
# /_assets/ (assetsDir: '_/assets').
|
||||
frontend = Frontend(
|
||||
Path(__file__).with_name("frontend-build"), spa=False, cached="/_assets/"
|
||||
)
|
||||
|
||||
|
||||
def _hash_name(body: bytes, orig: str) -> str:
|
||||
"""Content-addressed file name: blake3 hash prefix + original extension."""
|
||||
ext = "".join(c for c in Path(orig).suffix.lower() if c.isalnum() or c == ".")
|
||||
return blake3.blake3(body).hexdigest()[:12] + ext
|
||||
class _AccessLogExtraMiddleware:
|
||||
"""Fill the ``log_extra`` slot of fastapi_vue's access log.
|
||||
|
||||
|
||||
def _store_seed_file(markdown: str, banner: str, orig: str, body: bytes) -> tuple[str, str]:
|
||||
"""Store a seed file content-addressed and point references at /_f/."""
|
||||
name = _hash_name(body, orig)
|
||||
data.files.setdefault(name, body)
|
||||
markdown = markdown.replace(f"]({orig}", f"](/_f/{name}")
|
||||
banner = banner.replace(f'src="/{orig}"', f'src="/_f/{name}"')
|
||||
banner = banner.replace(f'src="{orig}"', f'src="/_f/{name}"')
|
||||
return markdown, banner
|
||||
|
||||
|
||||
def _ensure(menu: dict[str, Node], path: str) -> Node:
|
||||
"""Return the node at ``path``, creating it and any missing ancestors
|
||||
(content-less category labels) appended at the end of their level."""
|
||||
nodes = menu
|
||||
node = None
|
||||
for seg in path.split("/"):
|
||||
node = nodes.get(seg)
|
||||
if node is None:
|
||||
node = Node(title=prettify(seg), order=append_order(nodes))
|
||||
nodes[seg] = node
|
||||
nodes = node.children
|
||||
return node
|
||||
|
||||
|
||||
def _remove_page_content(menu: dict[str, Node], path: str) -> None:
|
||||
"""Delete a page's markdown content.
|
||||
|
||||
A node with children becomes a content-less category label; a childless
|
||||
node is removed entirely. Does nothing if the path does not exist.
|
||||
Everything under ``/_api`` is gated by the SSO forward-auth, which names
|
||||
the authenticated user in the ``remote-user`` header; put that user on
|
||||
the access-log line, for plain requests and WebSocket open/close alike.
|
||||
The scope dict is shared with the outer AccessLogMiddleware, which reads
|
||||
the slot back at response/accept/close time.
|
||||
"""
|
||||
slot = find_slot(menu, path)
|
||||
if slot is None:
|
||||
return
|
||||
node = slot[0].get(slot[1])
|
||||
if node is None:
|
||||
return
|
||||
if node.children:
|
||||
node.content = None
|
||||
node.modified = datetime.now(UTC)
|
||||
else:
|
||||
del slot[0][slot[1]]
|
||||
|
||||
def __init__(self, app: ASGIApp) -> None:
|
||||
self.app = app
|
||||
|
||||
def _migrate_legacy() -> None:
|
||||
"""Rebuild the legacy flat page store as a tree (one-time migration)."""
|
||||
if not data.pages:
|
||||
return
|
||||
with kanta.transaction("migrate pages to tree"):
|
||||
for path, page in data.pages.items():
|
||||
node = _ensure(data.menu, path)
|
||||
node.title = page.title
|
||||
node.content = page.markdown
|
||||
node.banner = page.banner
|
||||
node.published = page.published
|
||||
node.order = page.order
|
||||
node.created = page.created
|
||||
node.modified = page.modified
|
||||
data.pages.clear()
|
||||
data.version += 1
|
||||
async def __call__(self, scope: Scope, receive: Receive, send: Send) -> None:
|
||||
if scope["type"] in ("http", "websocket") and scope["path"].startswith("/_api"):
|
||||
headers = dict(scope["headers"])
|
||||
user = headers.get(b"remote-user", b"").decode("latin-1")
|
||||
if user:
|
||||
scope.setdefault("state", {})["log_extra"] = user
|
||||
await self.app(scope, receive, send)
|
||||
|
||||
|
||||
@asynccontextmanager
|
||||
async def lifespan(_app: FastAPI) -> AsyncIterator[None]:
|
||||
"""Open the database, migrate/seed content, load assets."""
|
||||
await kanta.open()
|
||||
_migrate_legacy()
|
||||
missing = [p for p in seed.PAGES if resolve(data.menu, p) is None]
|
||||
if missing:
|
||||
with kanta.transaction("seed missing pages"):
|
||||
for path in missing:
|
||||
title, markdown, files, banner, order, design = seed.PAGES[path]
|
||||
for orig, body in files.items():
|
||||
markdown, banner = _store_seed_file(markdown, banner, orig, body)
|
||||
node = _ensure(data.menu, path)
|
||||
node.title = title
|
||||
node.content = markdown
|
||||
node.banner = banner
|
||||
node.banner_design = design
|
||||
node.order = order
|
||||
async def lifespan(_app: FastAPI) -> AsyncGenerator:
|
||||
"""Open the database (migrations run inside kanta.open), load assets, load GeoIP."""
|
||||
async with kanta:
|
||||
await asyncio.to_thread(file_store.load)
|
||||
await frontend.load()
|
||||
# --dbip: update the DB-IP database first, then decompress/open the
|
||||
# MMDB once. Lookups are then read-only and safe to run in
|
||||
# background ``to_thread`` workers.
|
||||
if config.dbip:
|
||||
await asyncio.to_thread(tracking._download_dbip)
|
||||
await asyncio.to_thread(tracking._geoip._load)
|
||||
analytics_store.subscribe(tracking._schedule_analytics_broadcast)
|
||||
# Backfill favicons for external sites already in the recorded data.
|
||||
tracking._schedule_favicon_fetch()
|
||||
yield
|
||||
await kanta.close()
|
||||
analytics_store.unsubscribe(tracking._schedule_analytics_broadcast)
|
||||
|
||||
|
||||
# docs_url/openapi_url disabled: /docs belongs to our content, and the API
|
||||
# is not meant to be browsable by the public anyway.
|
||||
app = FastAPI(
|
||||
title="Pagerite",
|
||||
debug=DEVMODE,
|
||||
debug=env.dev,
|
||||
lifespan=lifespan,
|
||||
docs_url=None,
|
||||
redoc_url=None,
|
||||
openapi_url=None,
|
||||
)
|
||||
|
||||
app.add_middleware(_AccessLogExtraMiddleware)
|
||||
|
||||
|
||||
@app.middleware("http")
|
||||
async def _headers(request: Request, call_next) -> Response:
|
||||
@@ -164,557 +118,17 @@ async def _headers(request: Request, call_next) -> Response:
|
||||
return response
|
||||
|
||||
|
||||
class PageIn(BaseModel):
|
||||
"""Payload for creating or replacing a page."""
|
||||
|
||||
title: str
|
||||
markdown: str
|
||||
published: bool = True
|
||||
banner: str | None = None # None keeps the existing banner
|
||||
|
||||
|
||||
@app.get("/_api/pages")
|
||||
async def list_pages() -> list[dict]:
|
||||
"""The site tree for the structure editor (all nodes, drafts included).
|
||||
|
||||
Nested by slug; each node carries its full path, menu order and flags.
|
||||
"""
|
||||
|
||||
def dump(nodes: dict[str, Node], prefix: str) -> list[dict]:
|
||||
out = []
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
out.append({
|
||||
"slug": slug,
|
||||
"path": path,
|
||||
"title": node.title,
|
||||
"order": node.order,
|
||||
"published": node.published,
|
||||
"has_content": node.content is not None,
|
||||
"children": dump(node.children, path),
|
||||
})
|
||||
return out
|
||||
|
||||
return dump(data.menu, "")
|
||||
|
||||
|
||||
@app.put("/_api/pages/{path:path}", status_code=204)
|
||||
async def save_page(path: str, page: PageIn) -> None:
|
||||
"""Create or replace the page at a slug path ("" or "/" = front page).
|
||||
|
||||
Missing ancestors are created as content-less category labels. Giving
|
||||
a category markdown turns it into a landing page. Empty markdown (after
|
||||
stripping) creates an empty page that renders with just its title —
|
||||
saving never deletes; use DELETE to remove a page (the page editor
|
||||
issues DELETE when you save empty text).
|
||||
"""
|
||||
path = path.strip("/")
|
||||
_check_reserved(path)
|
||||
with kanta.transaction("save page", extra=path):
|
||||
node = _ensure(data.menu, path)
|
||||
node.title = page.title
|
||||
node.content = page.markdown
|
||||
node.published = page.published
|
||||
if page.banner is not None:
|
||||
node.banner = page.banner
|
||||
node.modified = datetime.now(UTC)
|
||||
data.version += 1
|
||||
|
||||
|
||||
class StructureOp(BaseModel):
|
||||
"""Rearrange the site tree: reorder, move/rename or retitle a node.
|
||||
|
||||
`order` is a fresh fractional key computed client-side from the node's
|
||||
new siblings (a value halfway between them); all other items keep
|
||||
theirs. `move_to` is the full target path — the parent must exist and
|
||||
the new slug be free. Moves carry the whole subtree. The front page is
|
||||
just the top-level node with slug "": renaming it away leaves no front
|
||||
page ("/" then redirects to the first nav item), and any childless
|
||||
top-level node can take the empty slug to become the front page.
|
||||
"""
|
||||
|
||||
path: str
|
||||
order: float | None = None
|
||||
move_to: str | None = None
|
||||
title: str | None = None
|
||||
|
||||
|
||||
@app.post("/_api/structure", status_code=204)
|
||||
async def update_structure(op: StructureOp) -> None:
|
||||
"""Apply one structure operation (see StructureOp)."""
|
||||
path = op.path.strip("/")
|
||||
chain = resolve(data.menu, path)
|
||||
if chain is None:
|
||||
raise HTTPException(404, "no such page")
|
||||
node = chain[-1]
|
||||
target = op.move_to.strip("/") if op.move_to is not None else None
|
||||
if target is not None and target != path:
|
||||
_check_reserved(target)
|
||||
if path and target.startswith(f"{path}/"):
|
||||
raise HTTPException(400, "cannot move a page under itself")
|
||||
slot = find_slot(data.menu, target)
|
||||
if slot is None:
|
||||
raise HTTPException(404, "target parent does not exist")
|
||||
tnodes, tslug = slot
|
||||
if tslug in tnodes:
|
||||
raise HTTPException(400, "target path exists")
|
||||
if not tslug and node.children:
|
||||
raise HTTPException(400, "the front page cannot have children")
|
||||
with kanta.transaction("update structure", extra=path):
|
||||
if op.title is not None:
|
||||
node.title = op.title
|
||||
if target is not None and target != path:
|
||||
snodes, sslug = find_slot(data.menu, path)
|
||||
del snodes[sslug]
|
||||
# A pure rename (same parent) keeps its position; only a move
|
||||
# to another level appends at the end (unless an order came
|
||||
# with the drop).
|
||||
same_level = path.rpartition("/")[0] == target.rpartition("/")[0]
|
||||
node.order = (
|
||||
op.order
|
||||
if op.order is not None
|
||||
else node.order if same_level else append_order(tnodes)
|
||||
)
|
||||
tnodes[tslug] = node
|
||||
elif op.order is not None:
|
||||
node.order = op.order
|
||||
node.modified = datetime.now(UTC)
|
||||
data.version += 1
|
||||
|
||||
|
||||
@app.get("/_api/settings")
|
||||
async def get_settings() -> dict:
|
||||
"""Site-wide settings (brand, theme, custom CSS and favicon URL), plus
|
||||
the themes and banner designs available on disk for the selectors."""
|
||||
return {
|
||||
"brand": data.brand,
|
||||
"brand_html": data.brand_html,
|
||||
"theme": data.theme,
|
||||
"custom_css": data.custom_css,
|
||||
"favicon": f"/_f/{data.favicon}" if data.favicon else "",
|
||||
"themes": views._theme_names(),
|
||||
"banner_designs": views._banner_design_names(),
|
||||
}
|
||||
|
||||
|
||||
class SettingsIn(BaseModel):
|
||||
"""Payload for updating site-wide settings."""
|
||||
|
||||
brand: str
|
||||
theme: str
|
||||
custom_css: str
|
||||
brand_html: str = ""
|
||||
|
||||
|
||||
@app.put("/_api/settings", status_code=204)
|
||||
async def put_settings(settings: SettingsIn) -> None:
|
||||
"""Update site-wide settings; bumps the version so ETags invalidate."""
|
||||
with kanta.transaction("update settings"):
|
||||
data.brand = settings.brand
|
||||
data.brand_html = settings.brand_html
|
||||
data.theme = settings.theme
|
||||
data.custom_css = settings.custom_css
|
||||
data.version += 1
|
||||
|
||||
|
||||
@app.put("/_api/settings/favicon")
|
||||
async def put_favicon(request: Request) -> dict[str, str]:
|
||||
"""Upload a favicon into the content-addressed store and activate it.
|
||||
|
||||
Raw image body (ico/png/svg...); the stored name is a blake3 hash
|
||||
prefix + extension, and pages link it as <link rel="icon">. Returns
|
||||
{"path": "/_f/..."}.
|
||||
"""
|
||||
body = await request.body()
|
||||
if not body:
|
||||
raise HTTPException(400, "empty file")
|
||||
stored = _hash_name(body, request.headers.get("x-filename", "favicon.ico"))
|
||||
with kanta.transaction("upload favicon"):
|
||||
data.files[stored] = body
|
||||
data.favicon = stored
|
||||
data.version += 1
|
||||
return {"path": f"/_f/{stored}"}
|
||||
|
||||
|
||||
@app.delete("/_api/settings/favicon", status_code=204)
|
||||
async def delete_favicon() -> None:
|
||||
"""Clear the custom favicon (back to the build's /favicon.ico).
|
||||
|
||||
The blob stays in the content-addressed store; only the reference goes.
|
||||
"""
|
||||
with kanta.transaction("clear favicon"):
|
||||
data.favicon = ""
|
||||
data.version += 1
|
||||
|
||||
|
||||
class ToggleTaskIn(BaseModel):
|
||||
"""Payload for toggling one task-list checkbox."""
|
||||
|
||||
path: str
|
||||
index: int
|
||||
markdown: str | None = None
|
||||
|
||||
|
||||
@app.post("/_api/toggle-task")
|
||||
async def toggle_task_endpoint(body: ToggleTaskIn) -> dict[str, str]:
|
||||
"""Toggle the Nth task-list checkbox in a page's Markdown source.
|
||||
|
||||
If ``markdown`` is provided the source is left untouched and the toggled
|
||||
Markdown is returned (used while the page editor is open, so the live
|
||||
CodeMirror document can be updated). Otherwise the stored page at
|
||||
``path`` is read, toggled, and saved.
|
||||
"""
|
||||
path = body.path.strip("/")
|
||||
_check_reserved(path)
|
||||
if body.markdown is not None:
|
||||
new_markdown = toggle_task(body.markdown, body.index)
|
||||
if new_markdown is None:
|
||||
raise HTTPException(400, "invalid task index")
|
||||
return {"markdown": new_markdown}
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is None or node.content is None:
|
||||
raise HTTPException(404, "no such page")
|
||||
new_markdown = toggle_task(node.content, body.index)
|
||||
if new_markdown is None:
|
||||
raise HTTPException(400, "invalid task index")
|
||||
with kanta.transaction("toggle task", extra=path):
|
||||
node.content = new_markdown
|
||||
node.modified = datetime.now(UTC)
|
||||
data.version += 1
|
||||
return {"markdown": new_markdown}
|
||||
|
||||
|
||||
@app.put("/_api/files/{name}")
|
||||
async def upload_file(name: str, request: Request) -> dict[str, str]:
|
||||
"""Store an upload (image, video...) in the content-addressed store.
|
||||
|
||||
The stored name is a blake3 hash prefix + the original extension,
|
||||
served immutable at "/_f/{name}"; returns {"path": "/_f/..."}.
|
||||
"""
|
||||
if "/" in name or name in {".", ".."}:
|
||||
raise HTTPException(400, "bad file name")
|
||||
body = await request.body()
|
||||
stored = _hash_name(body, name)
|
||||
with kanta.transaction("upload file", extra=name):
|
||||
data.files[stored] = body
|
||||
data.version += 1
|
||||
return {"path": f"/_f/{stored}"}
|
||||
|
||||
|
||||
@app.delete("/_api/files/{name}", status_code=204)
|
||||
async def delete_file(name: str) -> None:
|
||||
"""Remove a file from the content-addressed store (no refcounting:
|
||||
other pages referencing the same content will 404)."""
|
||||
if name not in data.files:
|
||||
raise HTTPException(404, "no such file")
|
||||
with kanta.transaction("delete file", extra=name):
|
||||
del data.files[name]
|
||||
data.version += 1
|
||||
|
||||
|
||||
@app.get("/_themes/{name}/{filename}")
|
||||
async def theme_file(name: str, filename: str, request: Request) -> Response:
|
||||
"""Serve a theme/banner-design file from pagerite/themes/{name}/.
|
||||
|
||||
Stylesheets plus any extra assets the CSS references (like summer's
|
||||
grass.svg). Read from disk on every request (etag by mtime+size):
|
||||
theme files are never built or content-hashed, so edits on disk show
|
||||
on the next page load, in prod as well as dev.
|
||||
"""
|
||||
if (
|
||||
"/" in filename
|
||||
or filename.startswith(".")
|
||||
or "/" in name
|
||||
or name.startswith(".")
|
||||
):
|
||||
raise HTTPException(404)
|
||||
path = views.THEMES / name / filename
|
||||
try:
|
||||
stat = path.stat()
|
||||
except FileNotFoundError:
|
||||
raise HTTPException(404) from None
|
||||
if not path.is_file():
|
||||
raise HTTPException(404)
|
||||
etag = f'"{stat.st_mtime_ns:x}-{stat.st_size:x}"'
|
||||
if request.headers.get("if-none-match") == etag:
|
||||
return Response(status_code=304)
|
||||
mime = mimetypes.guess_type(filename)[0] or "application/octet-stream"
|
||||
return Response(
|
||||
path.read_bytes(),
|
||||
media_type=mime,
|
||||
headers={"etag": etag, "cache-control": "no-cache"},
|
||||
)
|
||||
|
||||
|
||||
@app.get("/_f/{name}")
|
||||
async def stored_file(name: str, request: Request) -> Response:
|
||||
"""Serve a file from the content-addressed store (immutable: the name
|
||||
is its own hash, so cache forever)."""
|
||||
body = data.files.get(name)
|
||||
if body is None:
|
||||
raise HTTPException(404)
|
||||
if request.headers.get("if-none-match") == name:
|
||||
return Response(status_code=304)
|
||||
mime = mimetypes.guess_type(name)[0] or "application/octet-stream"
|
||||
return Response(
|
||||
body,
|
||||
media_type=mime,
|
||||
headers={"etag": name, "cache-control": "public, max-age=31536000, immutable"},
|
||||
)
|
||||
|
||||
|
||||
@app.delete("/_api/pages/{path:path}", status_code=204)
|
||||
async def delete_page(path: str) -> None:
|
||||
"""Delete a node by slug path.
|
||||
|
||||
A category (node with children) loses only its landing page and stays
|
||||
as a content-less label; a childless node is removed entirely.
|
||||
"""
|
||||
path = path.strip("/")
|
||||
_check_reserved(path)
|
||||
slot = find_slot(data.menu, path)
|
||||
node = slot[0].get(slot[1]) if slot else None
|
||||
if node is None:
|
||||
raise HTTPException(404, "no such page")
|
||||
with kanta.transaction("delete page", extra=path):
|
||||
if node.children:
|
||||
node.content = None
|
||||
node.modified = datetime.now(UTC)
|
||||
else:
|
||||
del slot[0][slot[1]]
|
||||
data.version += 1
|
||||
|
||||
|
||||
_SLUG_RE = re.compile(r"^[a-z0-9][a-z0-9_-]*$")
|
||||
|
||||
|
||||
def _http_date(dt: datetime) -> str:
|
||||
"""RFC 7231 date for the Last-Modified header."""
|
||||
return format_datetime(dt.astimezone(UTC), usegmt=True)
|
||||
|
||||
|
||||
def _is_reserved(path: str) -> bool:
|
||||
"""Slug shape that content may never use: each segment must be lower-case
|
||||
ASCII letters, digits, hyphens and underscores (underscores may not be
|
||||
the first character), and dots are never allowed.
|
||||
"""
|
||||
if path == "":
|
||||
return False
|
||||
return any(not _SLUG_RE.match(seg) for seg in path.split("/"))
|
||||
|
||||
|
||||
def _check_reserved(path: str) -> None:
|
||||
"""Reject paths that do not follow the slug charset."""
|
||||
if _is_reserved(path):
|
||||
raise HTTPException(
|
||||
400,
|
||||
'slugs may only use a-z, 0-9, "-" and "_" (not as the first character), and no dots',
|
||||
)
|
||||
|
||||
|
||||
@app.websocket("/_api/ws/editor")
|
||||
async def editor_ws(ws: WebSocket) -> None:
|
||||
"""Editor session: open pages, render previews, save — over one socket.
|
||||
|
||||
Stateless protocol (each message carries the path):
|
||||
<- {"type": "open", "path"}
|
||||
-> {"type": "doc", "path", "exists", "title", "markdown", "published",
|
||||
"banner", "banner_design"}
|
||||
<- {"type": "render", "path", "markdown"}
|
||||
-> {"type": "html", "path", "html"}
|
||||
<- {"type": "save", "path", "title"?, "markdown"?, "published"?,
|
||||
"banner"?, "banner_design"?, "move_from"?} (absent fields keep
|
||||
their old values; move_from: rename/move a page, subtree included)
|
||||
-> {"type": "saved", "path"} | {"type": "error", "detail"}
|
||||
"""
|
||||
await ws.accept()
|
||||
try:
|
||||
while True:
|
||||
msg = await ws.receive_json()
|
||||
path = msg.get("path", "").strip("/")
|
||||
try:
|
||||
_check_reserved(path)
|
||||
except HTTPException:
|
||||
await ws.send_json({"type": "error", "detail": "reserved path"})
|
||||
continue
|
||||
match msg.get("type"):
|
||||
case "open":
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
await ws.send_json({
|
||||
"type": "doc",
|
||||
"path": path,
|
||||
"exists": node is not None,
|
||||
"title": node.title if node else "",
|
||||
"markdown": node.content if node and node.content is not None else "",
|
||||
"published": node.published if node else True,
|
||||
"banner": node.banner if node else "",
|
||||
# Own banner design setting: null = inherit,
|
||||
# "" = none, otherwise a design name.
|
||||
"banner_design": node.banner_design if node else None,
|
||||
# Which node's banner applies here ("" = front page,
|
||||
# null = default artwork); the site editor shows it
|
||||
# as the banner field's placeholder.
|
||||
"banner_from": views.banner_source(data.menu, path),
|
||||
# Which node's banner-design setting would apply on
|
||||
# inherit ("" = front page, null = the active
|
||||
# theme's default) and what design that resolves to.
|
||||
"banner_design_from": (
|
||||
src := views.banner_design_source(
|
||||
data.menu, path, data.theme
|
||||
)
|
||||
),
|
||||
"banner_design_inherited": (
|
||||
views.banner_design(data.menu, src, data.theme)
|
||||
if src is not None
|
||||
else views.theme_banner_design(data.theme)
|
||||
),
|
||||
})
|
||||
case "render":
|
||||
markdown = msg.get("markdown", "")
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
await ws.send_json({
|
||||
"type": "html",
|
||||
"path": path,
|
||||
"html": render(
|
||||
markdown,
|
||||
path,
|
||||
node.created if node else None,
|
||||
node.modified if node else None,
|
||||
),
|
||||
"has_h1": has_h1(markdown),
|
||||
})
|
||||
case "save":
|
||||
move_from = (msg.get("move_from") or path).strip("/")
|
||||
try:
|
||||
_check_reserved(move_from)
|
||||
except HTTPException:
|
||||
await ws.send_json({"type": "error", "detail": "reserved path"})
|
||||
continue
|
||||
old_chain = resolve(data.menu, move_from)
|
||||
old = old_chain[-1] if old_chain else None
|
||||
if old is None and move_from != path:
|
||||
move_from = path # nothing to carry over; plain save
|
||||
if move_from != path:
|
||||
# Rename/move: detach the node (subtree included)
|
||||
# and attach it at the new path. The target slug
|
||||
# must be free and the front page childless.
|
||||
if move_from and path.startswith(f"{move_from}/"):
|
||||
await ws.send_json({
|
||||
"type": "error",
|
||||
"detail": "cannot move a page under itself",
|
||||
})
|
||||
continue
|
||||
tslug = path.rpartition("/")[2]
|
||||
if not tslug and old.children:
|
||||
await ws.send_json({
|
||||
"type": "error",
|
||||
"detail": "the front page cannot have children",
|
||||
})
|
||||
continue
|
||||
tchain = resolve(data.menu, path)
|
||||
if tchain is not None:
|
||||
await ws.send_json({
|
||||
"type": "error",
|
||||
"detail": "target path exists",
|
||||
})
|
||||
continue
|
||||
with kanta.transaction("editor save", extra=path):
|
||||
if move_from != path:
|
||||
same_menu = (
|
||||
move_from.rpartition("/")[0] == path.rpartition("/")[0]
|
||||
)
|
||||
snodes, sslug = find_slot(data.menu, move_from)
|
||||
node = snodes.pop(sslug)
|
||||
parent = path.rpartition("/")[0]
|
||||
if parent:
|
||||
_ensure(data.menu, parent)
|
||||
tnodes, tslug = find_slot(data.menu, path)
|
||||
node.order = (
|
||||
node.order if same_menu else append_order(tnodes)
|
||||
)
|
||||
tnodes[tslug] = node
|
||||
else:
|
||||
node = old if old is not None else _ensure(data.menu, path)
|
||||
if "markdown" in msg:
|
||||
# Saving never deletes; empty markdown is an
|
||||
# empty page. Deletion is an explicit choice by
|
||||
# the page editor (REST DELETE).
|
||||
node.content = msg["markdown"]
|
||||
if "title" in msg:
|
||||
node.title = msg["title"]
|
||||
if "published" in msg:
|
||||
node.published = bool(msg["published"])
|
||||
if "banner" in msg:
|
||||
node.banner = msg["banner"]
|
||||
if "banner_design" in msg:
|
||||
node.banner_design = msg["banner_design"]
|
||||
node.modified = datetime.now(UTC)
|
||||
data.version += 1
|
||||
await ws.send_json({"type": "saved", "path": path})
|
||||
except WebSocketDisconnect:
|
||||
pass
|
||||
|
||||
|
||||
@app.get("/")
|
||||
async def front_page(request: Request) -> Response:
|
||||
"""Render the front page (slug path "")."""
|
||||
return await show_page(request, "")
|
||||
|
||||
# Our own routes first: the editor API and translator socket, the analytics
|
||||
# machinery, and the file store/user assets.
|
||||
app.include_router(api.router)
|
||||
app.include_router(tracking.router)
|
||||
app.include_router(files.router)
|
||||
|
||||
# Vue build asset routes are inserted at this position during load(): the
|
||||
# build mirrors the URL space (/_assets/*, /favicon.ico at the root).
|
||||
# build mirrors the URL space (/_assets/*).
|
||||
frontend.route(app, "/")
|
||||
|
||||
|
||||
@app.get("/{path:path}", response_model=None)
|
||||
async def show_page(request: Request, path: str) -> HTMLResponse | Response:
|
||||
"""Render the content page at a slug path, or 404.
|
||||
|
||||
A node without content is a category label: its URL renders a
|
||||
placeholder page (nav links point straight at its first child).
|
||||
"""
|
||||
path = path.strip("/")
|
||||
if path and _is_reserved(path):
|
||||
# Invalid slug shape: not a content URL, let FastAPI return its
|
||||
# built-in 404 instead of rendering an editable article page.
|
||||
raise HTTPException(404)
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is not None and node.published and node.content is not None:
|
||||
# ETag on content + render version; clients revalidate cheaply,
|
||||
# which keeps prefetched pages warm and current. no-cache forces
|
||||
# that revalidation: with Last-Modified but no Cache-Control,
|
||||
# browsers would otherwise cache heuristically and serve stale
|
||||
# pages (e.g. after a theme change) without asking us at all.
|
||||
etag = f'"{path}@{node.modified.timestamp()}v{data.version}"'
|
||||
if request.headers.get("if-none-match") == etag:
|
||||
return Response(status_code=304)
|
||||
return HTMLResponse(
|
||||
views.render_page(data.menu, path, data.brand, data.custom_css, data.theme, data.favicon, data.brand_html),
|
||||
headers={
|
||||
"etag": etag,
|
||||
"last-modified": _http_date(node.modified),
|
||||
"cache-control": "no-cache",
|
||||
},
|
||||
)
|
||||
if node is not None and node.published and node.content is None:
|
||||
# Category label without a landing page: placeholder with the pen
|
||||
# to create it (404 — no page here, but the node is real).
|
||||
return HTMLResponse(
|
||||
views.render_category(data.menu, path, data.brand, data.custom_css, data.theme, data.favicon, data.brand_html),
|
||||
404,
|
||||
headers={
|
||||
"last-modified": _http_date(node.modified),
|
||||
"cache-control": "no-cache",
|
||||
},
|
||||
)
|
||||
if node is None and not path:
|
||||
# No front page (no top-level node with slug ""): "/" opens the
|
||||
# first item of the navigation instead.
|
||||
for slug, item in sorted_nodes(data.menu):
|
||||
if item.published:
|
||||
return RedirectResponse(f"/{slug}")
|
||||
return HTMLResponse(views.render_not_found(data.menu, path, data.brand, data.custom_css, data.theme, data.favicon, data.brand_html), 404)
|
||||
# The content catch-all goes last: built assets win over content slugs,
|
||||
# anything unmatched falls through to content (and 404).
|
||||
app.include_router(feeds.router)
|
||||
app.include_router(pages.router)
|
||||
|
||||
@@ -0,0 +1,180 @@
|
||||
"""Block-level Markdown chunking for content-addressed storage.
|
||||
|
||||
A page's Markdown is split into deterministic block-level chunks, each
|
||||
stored once under its content hash in ``Data.chunks`` (docs/migrate.md).
|
||||
Shared by the render/save pipeline (app.py, views.py, i18n.py) and the
|
||||
schema migration (migrations.py), so a chunk's key is stable no matter
|
||||
where the split happens.
|
||||
"""
|
||||
|
||||
import re
|
||||
|
||||
import blake3
|
||||
|
||||
from pagerite.segments import has_prose
|
||||
|
||||
#: Fenced code block opener/closer: up to 3 spaces indent, then 3+
|
||||
#: backticks or tildes (CommonMark).
|
||||
_FENCE_OPEN = re.compile(r"^ {0,3}(`{3,}|~{3,})")
|
||||
|
||||
#: A container fence line (mdit-py-plugins container): the "::: aside"
|
||||
#: opener and the ":::" closer alike. Always its own block, even with no
|
||||
#: blank line around it: folded into a prose paragraph it would cross to
|
||||
#: the translator as part of the text run, where the model can drop it —
|
||||
#: the rest of the page then renders inside the container.
|
||||
_CONTAINER = re.compile(r"^ {0,3}:{3,}(?:[ \t]|$)")
|
||||
|
||||
#: HTML block openers that may span blank lines (CommonMark types 1-5:
|
||||
#: script/pre/style/textarea, comments, processing instructions,
|
||||
#: declarations, CDATA) with their closing condition. Other HTML blocks
|
||||
#: end at the first blank line, which the generic blank-line split
|
||||
#: already does.
|
||||
_HTML_ATOMIC = (
|
||||
(
|
||||
re.compile(r"^ {0,3}<(?:script|pre|style|textarea)(?:\s|>|$)", re.IGNORECASE),
|
||||
re.compile(r"</(?:script|pre|style|textarea)\s*>", re.IGNORECASE),
|
||||
),
|
||||
(re.compile(r"^ {0,3}<!--"), re.compile(r"-->")),
|
||||
(re.compile(r"^ {0,3}<\?"), re.compile(r"\?>")),
|
||||
(re.compile(r"^ {0,3}<!\[CDATA\["), re.compile(r"\]\]>")),
|
||||
(re.compile(r"^ {0,3}<![A-Za-z]"), re.compile(r">")),
|
||||
)
|
||||
|
||||
#: First line of a generic HTML block (a block-level tag).
|
||||
_HTML_TAG = re.compile(r"^ {0,3}</?[A-Za-z][^>]*>")
|
||||
|
||||
|
||||
def _fence_close(line: str, opener: str) -> bool:
|
||||
"""True when ``line`` closes a code fence opened by ``opener``: the
|
||||
same marker char, at least as many, and nothing else on the line."""
|
||||
stripped = line.strip()
|
||||
return (
|
||||
len(stripped) >= len(opener)
|
||||
and stripped[0] == opener[0]
|
||||
and set(stripped) == {opener[0]}
|
||||
)
|
||||
|
||||
|
||||
def chunk_markdown(markdown: str) -> list[str]:
|
||||
"""Split Markdown into block-level chunks, deterministically.
|
||||
|
||||
Blocks are separated by blank lines; fenced code blocks and the
|
||||
multi-line HTML blocks (comments, script/pre/style, CDATA...) are
|
||||
kept atomic, even across blank lines, and end at their closing
|
||||
condition. Container fence lines (:::, open and close alike) are
|
||||
always their own block, blank lines or not (see _CONTAINER). Chunks
|
||||
carry no surrounding blank lines and no trailing newline; rejoining
|
||||
with ``join_chunks`` reproduces the source modulo blank-line
|
||||
normalization.
|
||||
"""
|
||||
chunks: list[str] = []
|
||||
buf: list[str] = []
|
||||
fence = "" # opener marker of the code fence we are in ("" = outside)
|
||||
html_end: re.Pattern | None = None # closes the atomic HTML block we are in
|
||||
|
||||
def flush() -> None:
|
||||
text = "\n".join(buf).strip("\n")
|
||||
if text.strip():
|
||||
chunks.append(text)
|
||||
buf.clear()
|
||||
|
||||
for line in markdown.split("\n"):
|
||||
if fence:
|
||||
buf.append(line)
|
||||
if _fence_close(line, fence):
|
||||
fence = ""
|
||||
flush()
|
||||
continue
|
||||
if html_end is not None:
|
||||
buf.append(line)
|
||||
if html_end.search(line):
|
||||
html_end = None
|
||||
flush()
|
||||
continue
|
||||
if not line.strip():
|
||||
flush()
|
||||
continue
|
||||
if m := _FENCE_OPEN.match(line):
|
||||
# Fences interrupt paragraphs (CommonMark): start a new block.
|
||||
flush()
|
||||
fence = m.group(1)
|
||||
buf.append(line)
|
||||
continue
|
||||
if _CONTAINER.match(line):
|
||||
# Container fence lines (open and close alike) are their own
|
||||
# block — never part of a prose chunk (see _CONTAINER).
|
||||
flush()
|
||||
buf.append(line)
|
||||
flush()
|
||||
continue
|
||||
if not buf:
|
||||
for open_re, close_re in _HTML_ATOMIC:
|
||||
if open_re.match(line):
|
||||
buf.append(line)
|
||||
if close_re.search(line): # opens and closes on one line
|
||||
flush()
|
||||
else:
|
||||
html_end = close_re
|
||||
break
|
||||
else:
|
||||
buf.append(line)
|
||||
continue
|
||||
buf.append(line)
|
||||
flush() # an unterminated fence/HTML block runs to EOF, kept as code/HTML
|
||||
return chunks
|
||||
|
||||
|
||||
def _normalize(text: str) -> str:
|
||||
"""Whitespace-insensitive chunk identity: strip trailing whitespace
|
||||
per line and collapse surrounding blank lines, so whitespace-only
|
||||
source edits don't invalidate translations."""
|
||||
return "\n".join(line.rstrip() for line in text.split("\n")).strip("\n")
|
||||
|
||||
|
||||
def chunk_key(text: str) -> bytes:
|
||||
"""Content key of a chunk: the first 9 bytes of the blake3 digest of
|
||||
the normalized text (72 bits — a site's chunk count stays far below
|
||||
the birthday bound), using the same hasher as app.py's file store.
|
||||
|
||||
Keys are bytes: kanta/msgspec base64-encode them at the JSON
|
||||
persistence level, so the raw database dicts carry 12-char strings.
|
||||
"""
|
||||
return blake3.blake3(_normalize(text).encode()).digest(9)
|
||||
|
||||
|
||||
def needs_translation(chunk: str) -> bool:
|
||||
"""False for chunks without prose: pure code fences, HTML blocks, and
|
||||
anything that yields no translatable segments (pagerite/segments.py) —
|
||||
container fences, lone {placeholders}, reference definitions.
|
||||
|
||||
These are inherently no-translate (docs/migrate.md): derived from the
|
||||
chunk text itself, nothing is stored. Every language renders them from
|
||||
the original chunk via the hybrid fallback.
|
||||
"""
|
||||
if _FENCE_OPEN.match(chunk):
|
||||
return False
|
||||
first = chunk.split("\n", 1)[0]
|
||||
if any(open_re.match(first) for open_re, _ in _HTML_ATOMIC):
|
||||
return False
|
||||
if _HTML_TAG.match(first):
|
||||
return False
|
||||
return has_prose(chunk)
|
||||
|
||||
|
||||
def join_chunks(chunks: list[str]) -> str:
|
||||
"""The stored page form of chunks: blocks joined by a blank line,
|
||||
with a trailing newline ("" for no chunks)."""
|
||||
return "\n\n".join(chunks) + "\n" if chunks else ""
|
||||
|
||||
|
||||
def store_chunks(store: dict[bytes, str], markdown: str) -> list[bytes]:
|
||||
"""Chunk ``markdown`` into ``store`` (hash -> text); return the ordered
|
||||
hashes. Unchanged chunks keep their hashes, so only genuinely new text
|
||||
lands in the kanta change diff. First writer wins: variants sharing a
|
||||
key differ only in insignificant whitespace (see chunk_key)."""
|
||||
hashes = []
|
||||
for chunk in chunk_markdown(markdown):
|
||||
key = chunk_key(chunk)
|
||||
store.setdefault(key, chunk)
|
||||
hashes.append(key)
|
||||
return hashes
|
||||
@@ -0,0 +1,28 @@
|
||||
"""CLI → app configuration, passed as JSON in the ``PAGERITE_CONFIG`` env var.
|
||||
|
||||
Kept dependency-free (msgspec only) so ``__main__`` can build and serialize
|
||||
the config before any app module is imported, and the app side parses the
|
||||
same struct back. Import-time safe: nothing here reads the environment
|
||||
until ``load()`` is called.
|
||||
"""
|
||||
|
||||
import os
|
||||
|
||||
import msgspec
|
||||
|
||||
|
||||
class Config(msgspec.Struct):
|
||||
"""Configuration passed from the CLI entry point to the app."""
|
||||
|
||||
#: Public hostname of the site; names the per-site data directory
|
||||
#: ``<hostname>/{content.kantadb, analytics.json, files}`` under the cwd.
|
||||
hostname: str = "localhost"
|
||||
#: Download/update the DB-IP city lite database at startup (--dbip).
|
||||
dbip: bool = False
|
||||
|
||||
|
||||
def load() -> Config:
|
||||
"""Parse ``PAGERITE_CONFIG``, or the defaults when unset."""
|
||||
if raw := os.getenv("PAGERITE_CONFIG"):
|
||||
return msgspec.json.decode(raw.encode(), type=Config)
|
||||
return Config()
|
||||
@@ -2,8 +2,9 @@
|
||||
|
||||
The site structure is a tree of Nodes. Every node is a menu label with a
|
||||
configurable title and slug (its key in the parent's ``children``); the
|
||||
URL path is the chain of slugs from the top level. ``content`` is the
|
||||
node's Markdown page, or None for a pure category label, whose URL renders
|
||||
URL path is the chain of slugs from the top level. ``chunks`` is the
|
||||
node's Markdown page as ordered content-hash keys into ``Data.chunks``
|
||||
(docs/migrate.md), or None for a pure category label, whose URL renders
|
||||
a placeholder page while nav links point at its first child.
|
||||
"""
|
||||
|
||||
@@ -11,6 +12,43 @@ from datetime import UTC, datetime
|
||||
|
||||
import msgspec
|
||||
|
||||
from pagerite.chunks import join_chunks
|
||||
|
||||
|
||||
class ChunkEdit(msgspec.Struct, omit_defaults=True):
|
||||
"""One original chunk's user override in one language
|
||||
(docs/localization.md). Fields are independent and applied by chunk
|
||||
hash alone; an entry for a hash the article no longer contains simply
|
||||
never applies."""
|
||||
|
||||
#: Full-chunk replacement text, applied whenever the article still
|
||||
#: contains the chunk — a retranslation of the chunk is overridden
|
||||
#: wholesale (editing the original changes the hash, orphaning the
|
||||
#: patch). May contain blank lines (a paragraph split). A re-edit of
|
||||
#: the chunk composes into this text.
|
||||
replace: str = ""
|
||||
#: The chunk is deleted in this language. Hash-anchored, so the
|
||||
#: deletion survives retranslation; when the original paragraph itself
|
||||
#: is edited its hash changes and the fresh translation reappears.
|
||||
drop: bool = False
|
||||
#: Addition ids (LangEdits.adds) inserted before/after this chunk.
|
||||
before: str = ""
|
||||
after: str = ""
|
||||
|
||||
|
||||
class LangEdits(msgspec.Struct, omit_defaults=True):
|
||||
"""All user overrides of one article in one language. Keyed throughout
|
||||
(no lists), so a save's database diff touches only the edited chunks;
|
||||
application order comes from the article's own chunk order."""
|
||||
|
||||
#: Original chunk hash -> override.
|
||||
chunks: dict[bytes, ChunkEdit] = {}
|
||||
#: Translation-only additions: id -> Markdown, one per insertion gap,
|
||||
#: referenced from the neighboring chunks' ``before``/``after`` (both
|
||||
#: point at the same id; the first live referrer wins at apply time, so
|
||||
#: an original edit on one side leaves the other anchor).
|
||||
adds: dict[str, str] = {}
|
||||
|
||||
|
||||
class Node(msgspec.Struct, omit_defaults=True):
|
||||
"""One item of the site hierarchy.
|
||||
@@ -28,9 +66,21 @@ class Node(msgspec.Struct, omit_defaults=True):
|
||||
|
||||
title: str = ""
|
||||
order: float = 0
|
||||
#: Markdown source of the node's page; None = pure category label
|
||||
#: (its URL renders a placeholder page).
|
||||
content: str | None = None
|
||||
#: Ordered chunk hashes (9-byte keys into ``Data.chunks``); None =
|
||||
#: pure category label (its URL renders a placeholder page), a list
|
||||
#: (possibly empty) = a page.
|
||||
chunks: list[bytes] | None = None
|
||||
#: Primary language of the article (BCP-47 base tag). "" = inherit
|
||||
#: (nearest ancestor, front page last, site default "en" final).
|
||||
language: str = ""
|
||||
#: Chunk hashes the editor marked "do not translate" (always served
|
||||
#: from the original). Presence-keys, value always True.
|
||||
no_trans: dict[bytes, bool] = {}
|
||||
#: Languages this article is available in (besides its primary
|
||||
#: language). Presence-keys, value always True — the availability
|
||||
#: index for rendering and language selection; maintained by whoever
|
||||
#: writes translation data (docs/migrate.md).
|
||||
langs: dict[str, bool] = {}
|
||||
#: Raw HTML for the header banner (img, styled div, canvas+script...),
|
||||
#: rendered after the banner design's artwork so author code always
|
||||
#: wins over the design's own styles.
|
||||
@@ -40,28 +90,22 @@ class Node(msgspec.Struct, omit_defaults=True):
|
||||
#: "" = explicitly no design, None = inherit (nearest ancestor, front
|
||||
#: page last, then the active theme's own design).
|
||||
banner_design: str | None = None
|
||||
#: Content-addressed card image name (served at "/_f/{name}") for
|
||||
#: og:image/twitter:image and card covers. "" inherits the nearest
|
||||
#: ancestor's image, the front page last; unset everywhere falls back
|
||||
#: to mining the rendered article (which beats an inherited image).
|
||||
#: "@favicon" resolves to the site icon (Data.favicon) at render time,
|
||||
#: following favicon changes.
|
||||
image: str = ""
|
||||
#: Card-mode override (site cards + twitter:card): None = pick
|
||||
#: automatically from the card image's dimensions, False forces a
|
||||
#: small card, True a large one. Per-article only — NOT inherited
|
||||
#: down the tree (unlike image).
|
||||
large: bool | None = None
|
||||
published: bool = True
|
||||
children: dict[str, "Node"] = {}
|
||||
created: datetime = msgspec.field(
|
||||
default_factory=lambda: datetime.now(UTC),
|
||||
)
|
||||
modified: datetime = msgspec.field(
|
||||
default_factory=lambda: datetime.now(UTC),
|
||||
)
|
||||
|
||||
|
||||
class Page(msgspec.Struct, omit_defaults=True):
|
||||
"""Legacy flat page record, from before the tree model.
|
||||
|
||||
Kept only so old databases still decode; app.py migrates any entries
|
||||
into ``Data.menu`` on startup and clears this.
|
||||
"""
|
||||
|
||||
title: str
|
||||
markdown: str
|
||||
published: bool = True
|
||||
order: float = 0
|
||||
banner: str = ""
|
||||
# Quoted: msgspec 0.21 evaluates the bare self-reference eagerly at
|
||||
# class creation (Python 3.14 lazy annotations) and NameErrors.
|
||||
children: dict[str, "Node"] = {} # noqa: UP037
|
||||
created: datetime = msgspec.field(
|
||||
default_factory=lambda: datetime.now(UTC),
|
||||
)
|
||||
@@ -75,13 +119,6 @@ class Data(msgspec.Struct):
|
||||
|
||||
#: Top-level menu items by slug; "" is the front page.
|
||||
menu: dict[str, Node] = {}
|
||||
#: Content-addressed file store: name (blake3 hash prefix + extension)
|
||||
#: -> bytes, served immutable at "/_f/{name}". Absolute URLs that stay
|
||||
#: valid when pages move.
|
||||
files: dict[str, bytes] = {}
|
||||
#: Bumped on every structure/content write, so page ETags (which embed
|
||||
#: it) invalidate cached copies when navigation-affecting changes happen.
|
||||
version: int = 0
|
||||
#: Site name shown in the header and <title> suffix; editable in the
|
||||
#: site editor. Empty = no brand link in the header, no title suffix.
|
||||
brand: str = "Pagerite"
|
||||
@@ -91,18 +128,58 @@ class Data(msgspec.Struct):
|
||||
#: banner artwork, next to the nav. Empty = the plain brand link.
|
||||
brand_html: str = ""
|
||||
#: Active theme name (empty = none/base only). Themes live in
|
||||
#: frontend/src/assets/themes/{theme}/theme.css, with their banner
|
||||
#: artwork at pagerite/themes/{theme}/banner.svg (inlined server-side).
|
||||
theme: str = "purple"
|
||||
#: pagerite/themes/{theme}/ (theme.css and/or banner.css/banner.svg/
|
||||
#: banner.html), served by the backend from disk.
|
||||
theme: str = "corporate"
|
||||
#: Page transition design name (cube, crossfade, ...). Designs live in
|
||||
#: pagerite/themes/{name}/transition.css and are injected as
|
||||
#: #pagerite-transition on every page.
|
||||
transition: str = "cube"
|
||||
#: Raw site-wide custom CSS, injected inline in every page <head>.
|
||||
#: Trusted author content; not sanitized.
|
||||
custom_css: str = ""
|
||||
#: Favicon: name of a file in `files` (content-addressed), linked as
|
||||
#: <link rel="icon"> on every page. Empty = the build's /favicon.ico.
|
||||
#: Favicon: content-addressed file name (served at "/_f/{name}"),
|
||||
#: linked as <link rel="icon"> on every page; /favicon.ico redirects
|
||||
#: to it. Empty = no icon (and /favicon.ico 404s).
|
||||
favicon: str = ""
|
||||
#: Legacy flat page store (pre-tree databases); migrated into `menu`
|
||||
#: on startup, then cleared. Never written otherwise.
|
||||
pages: dict[str, Page] = {}
|
||||
#: API keys gating the translator service WebSocket (/_translate/{key};
|
||||
#: the external forward-auth does not cover that route): key -> display
|
||||
#: name. Keys are 12 lowercase alphanumeric characters; the first is
|
||||
#: generated at database bootstrap, more are managed in the editor
|
||||
#: shell's lang tab (via /_api/settings).
|
||||
translate_keys: dict[str, str] = {}
|
||||
#: Wanted target languages for the translator service (presence-keys,
|
||||
#: value always True). The dispatcher offers jobs only in the
|
||||
#: intersection of these and a connection's announced capabilities.
|
||||
#: Bootstrapped to es+zh; edited in the editor shell's localization
|
||||
#: tab (or via /_api/settings).
|
||||
translate_langs: dict[str, bool] = {}
|
||||
#: All original-language page text, content-addressed:
|
||||
#: chunk_key (9 bytes; base64 at the JSON level) -> Markdown chunk.
|
||||
#: Shared by every article.
|
||||
chunks: dict[bytes, str] = {}
|
||||
#: Machine translations: chunk hash -> lang -> translated Markdown
|
||||
#: (a nested dict rather than tuple keys, which msgspec's JSON
|
||||
#: serializer does not support). Also used for node titles (hash of
|
||||
#: the title text).
|
||||
trans: dict[bytes, dict[str, str]] = {}
|
||||
#: User override edits per article and language:
|
||||
#: path -> lang -> LangEdits (paths without leading slash). Replaces
|
||||
#: the old "patches" key (ignored on decode, discarding that data).
|
||||
overrides: dict[str, dict[str, LangEdits]] = {}
|
||||
|
||||
|
||||
def node_markdown(data: Data, node: Node) -> str | None:
|
||||
"""The node's original Markdown assembled from the chunk store.
|
||||
|
||||
None for category labels (chunks is None); an empty page gives "".
|
||||
Hashes missing from the store (shouldn't happen) are skipped.
|
||||
"""
|
||||
if node.chunks is None:
|
||||
return None
|
||||
return join_chunks(
|
||||
[t for h in node.chunks if (t := data.chunks.get(h)) is not None]
|
||||
)
|
||||
|
||||
|
||||
def prettify(slug: str) -> str:
|
||||
|
||||
@@ -0,0 +1,182 @@
|
||||
"""Machine-readable site exports: /llms.txt, /feed.json and /feed.xml.
|
||||
|
||||
- ``/llms.txt`` (llmstxt.org convention): a Markdown map of the site for
|
||||
LLM agents — the brand as title, then every published article as a link
|
||||
with a short excerpt.
|
||||
- ``/feed.json``: JSON Feed 1.1 of all published articles, full content.
|
||||
- ``/feed.xml``: the same as RSS 2.0 (with an atom:link self reference)
|
||||
for older feed readers.
|
||||
|
||||
All three are linked from every page's <head> (see views._layout) and from
|
||||
the sitemap, recorded in analytics like page GETs (they surface as crawler
|
||||
hits — no activity message ever follows them), and rendered in the site's
|
||||
primary language only (feeds have no per-language negotiation here).
|
||||
|
||||
Rendering every article is expensive, so bodies are cached in RAM keyed by
|
||||
the public base URL and cleared by ``state._invalidate_pages`` on any
|
||||
content/settings write — the same hook that drops the page render cache.
|
||||
Each response also carries a content-hash ETag and answers 304, so polling
|
||||
feed readers revalidate cheaply.
|
||||
"""
|
||||
|
||||
import blake3
|
||||
import json
|
||||
from datetime import UTC
|
||||
from email.utils import format_datetime
|
||||
from functools import lru_cache
|
||||
from xml.sax.saxutils import escape as xml_escape
|
||||
|
||||
from fastapi import APIRouter, Request
|
||||
from fastapi.responses import Response
|
||||
|
||||
from pagerite.data import Node, node_markdown, sorted_nodes
|
||||
from pagerite.markdown import make_md
|
||||
from pagerite.state import SITE_URL, data
|
||||
from pagerite.tracking import _record_get
|
||||
from pagerite.views import _description
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
_md = make_md()
|
||||
|
||||
|
||||
def _articles() -> list[tuple[str, Node]]:
|
||||
"""All published content pages in menu order: (path, node)."""
|
||||
out: list[tuple[str, Node]] = []
|
||||
|
||||
def walk(nodes: dict[str, Node], prefix: str) -> None:
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
if node.published and node.chunks is not None:
|
||||
out.append((path, node))
|
||||
if node.children:
|
||||
walk(node.children, path)
|
||||
|
||||
walk(data.menu, "")
|
||||
return out
|
||||
|
||||
|
||||
def _body_html(node: Node, base: str) -> str:
|
||||
"""Full article HTML for feed content, with relative URLs absolutized.
|
||||
|
||||
Rendered without the layout segmentation of page rendering (colseg
|
||||
wrappers are meaningless in a feed reader); the item title carries the
|
||||
page title, so no implicit h1 is injected either.
|
||||
"""
|
||||
html = _md.render(node_markdown(data, node) or "")
|
||||
return html.replace('src="/', f'src="{base}/').replace('href="/', f'href="{base}/')
|
||||
|
||||
|
||||
def _rfc822(node: Node) -> str:
|
||||
return format_datetime(node.modified.astimezone(UTC), usegmt=True)
|
||||
|
||||
|
||||
def _iso(node: Node) -> str:
|
||||
return node.modified.astimezone(UTC).replace(microsecond=0).isoformat()
|
||||
|
||||
|
||||
def _render_llms(base: str) -> str:
|
||||
lines = [f"# {data.brand}", "", "## Pages", ""]
|
||||
for path, node in _articles():
|
||||
url = f"{base}/{path}" if path else base
|
||||
excerpt = _description(_body_html(node, base), 120)
|
||||
suffix = f": {excerpt}" if excerpt else ""
|
||||
lines.append(f"- [{node.title or path}]({url}){suffix}")
|
||||
return "\n".join(lines) + "\n"
|
||||
|
||||
|
||||
def _render_feed_json(base: str) -> str:
|
||||
items = [
|
||||
{
|
||||
"id": (url := f"{base}/{path}" if path else base),
|
||||
"url": url,
|
||||
"title": node.title or path,
|
||||
"content_html": _body_html(node, base),
|
||||
"date_published": node.created.astimezone(UTC)
|
||||
.replace(microsecond=0)
|
||||
.isoformat(),
|
||||
"date_modified": _iso(node),
|
||||
}
|
||||
for path, node in _articles()
|
||||
]
|
||||
feed = {
|
||||
"version": "https://jsonfeed.org/version/1.1",
|
||||
"title": data.brand,
|
||||
"home_page_url": base,
|
||||
"feed_url": f"{base}/feed.json",
|
||||
"items": items,
|
||||
}
|
||||
return json.dumps(feed, ensure_ascii=False, indent=1)
|
||||
|
||||
|
||||
def _render_feed_xml(base: str) -> str:
|
||||
items = []
|
||||
for path, node in _articles():
|
||||
url = f"{base}/{path}" if path else base
|
||||
items.append(
|
||||
f"<item><title>{xml_escape(node.title or path)}</title>"
|
||||
f"<link>{xml_escape(url)}</link>"
|
||||
f'<guid isPermaLink="true">{xml_escape(url)}</guid>'
|
||||
f"<pubDate>{_rfc822(node)}</pubDate>"
|
||||
f"<description><![CDATA[{_body_html(node, base)}]]></description>"
|
||||
f"</item>"
|
||||
)
|
||||
return (
|
||||
'<?xml version="1.0" encoding="UTF-8"?>'
|
||||
'<rss version="2.0" xmlns:atom="http://www.w3.org/2005/Atom">'
|
||||
f"<channel><title>{xml_escape(data.brand)}</title>"
|
||||
f"<link>{xml_escape(base)}</link>"
|
||||
f"<description>{xml_escape(data.brand)}</description>"
|
||||
f'<atom:link href="{xml_escape(base)}/feed.xml" rel="self" type="application/rss+xml" />'
|
||||
+ "".join(items)
|
||||
+ "</channel></rss>"
|
||||
)
|
||||
|
||||
|
||||
#: Export body builders by route path.
|
||||
_RENDERERS = {
|
||||
"/llms.txt": (_render_llms, "text/plain"),
|
||||
"/feed.json": (_render_feed_json, "application/feed+json"),
|
||||
"/feed.xml": (_render_feed_xml, "application/rss+xml"),
|
||||
}
|
||||
|
||||
|
||||
@lru_cache(maxsize=12)
|
||||
def _cached_feed(path: str, base_url: str) -> str:
|
||||
"""Rendered export body; cleared by ``state._invalidate_pages`` on any
|
||||
content/settings write. base_url is part of the key because the bodies
|
||||
bake absolute URLs into every link, image and guid."""
|
||||
return _RENDERERS[path][0](base_url)
|
||||
|
||||
|
||||
def _feed_response(request: Request, path: str) -> Response:
|
||||
"""Cached export response with a content-hash ETag (304 on match), so
|
||||
polling feed readers revalidate without a rerender or a download."""
|
||||
base = SITE_URL or str(request.base_url).rstrip("/")
|
||||
body = _cached_feed(path, base)
|
||||
headers = {"cache-control": "no-cache"}
|
||||
tag = f'"{blake3.blake3(body.encode()).hexdigest()[:32]}"'
|
||||
headers["etag"] = tag
|
||||
if request.headers.get("if-none-match") == tag:
|
||||
return Response(status_code=304, headers=headers)
|
||||
_record_get(request)
|
||||
return Response(body, media_type=_RENDERERS[path][1], headers=headers)
|
||||
|
||||
|
||||
@router.get("/llms.txt")
|
||||
async def llms_txt(request: Request) -> Response:
|
||||
"""Markdown map of the site for LLM agents (llmstxt.org)."""
|
||||
return _feed_response(request, "/llms.txt")
|
||||
|
||||
|
||||
@router.get("/feed.json")
|
||||
async def feed_json(request: Request) -> Response:
|
||||
"""JSON Feed 1.1 of all published articles, full content."""
|
||||
return _feed_response(request, "/feed.json")
|
||||
|
||||
|
||||
@router.get("/feed.xml")
|
||||
async def feed_xml(request: Request) -> Response:
|
||||
"""RSS 2.0 of all published articles (full content in CDATA), with an
|
||||
atom:link self reference."""
|
||||
return _feed_response(request, "/feed.xml")
|
||||
@@ -0,0 +1,416 @@
|
||||
"""Content-addressed file store, image derivatives, and file routes.
|
||||
|
||||
``FileStore`` keeps uploads, seed assets and fetched favicons on disk under
|
||||
hash-prefixed names, fully cached in RAM (uncompressed plus a zstd copy
|
||||
when compression shrinks the body), served immutable at ``/_f/``. Raster
|
||||
images and SVGs are recompressed into AVIF/WebP/JPEG derivatives
|
||||
(``store_image`` and helpers); the untouched original is kept alongside as
|
||||
``<hash>.orig<ext>`` (never served). Routes: upload/delete under
|
||||
``/_api/files``, the favicon settings endpoints, the /favicon.ico
|
||||
redirect to the configured icon, the ``/_f/`` server with
|
||||
Accept-negotiated formats, and the user assets (``/_themes/``, ``/_fonts/``).
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import logging
|
||||
import mimetypes
|
||||
import tempfile
|
||||
from contextlib import suppress
|
||||
from pathlib import Path
|
||||
from urllib.parse import urlsplit
|
||||
|
||||
import blake3
|
||||
import httpx
|
||||
from fastapi import APIRouter, HTTPException, Request
|
||||
from fastapi.responses import RedirectResponse, Response
|
||||
from mediapreview import dispatch
|
||||
|
||||
from pagerite import views
|
||||
from pagerite.state import (
|
||||
FAVICON_MAXSIZE,
|
||||
FILES_DIR,
|
||||
IMAGE_JPG_QUALITY,
|
||||
IMAGE_MAXSIZE,
|
||||
IMAGE_QUALITY,
|
||||
IMAGE_WEBP_QUALITY,
|
||||
_invalidate_pages,
|
||||
_zstd,
|
||||
data,
|
||||
kanta,
|
||||
)
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
class FileStore:
|
||||
"""Content-addressed files on disk, fully cached in RAM.
|
||||
|
||||
Every file is kept in RAM uncompressed and zstd-compressed (the
|
||||
compressed copy only when it actually shrinks the body), so ``/_f``
|
||||
serves both encodings without touching disk or re-compressing.
|
||||
"""
|
||||
|
||||
def __init__(self, path: Path) -> None:
|
||||
self.path = path
|
||||
#: name -> (uncompressed body, zstd body or None)
|
||||
self._cache: dict[str, tuple[bytes, bytes | None]] = {}
|
||||
|
||||
@staticmethod
|
||||
def _entry(body: bytes) -> tuple[bytes, bytes | None]:
|
||||
compressed = _zstd.compress(body)
|
||||
return body, compressed if len(compressed) < len(body) else None
|
||||
|
||||
def load(self) -> None:
|
||||
"""Read every stored file into the RAM cache (startup)."""
|
||||
try:
|
||||
entries = sorted(self.path.iterdir())
|
||||
except FileNotFoundError:
|
||||
return
|
||||
for f in entries:
|
||||
if f.is_file() and not f.name.startswith("."):
|
||||
self._cache.setdefault(f.name, self._entry(f.read_bytes()))
|
||||
|
||||
def get(self, name: str) -> tuple[bytes, bytes | None] | None:
|
||||
return self._cache.get(name)
|
||||
|
||||
def put(self, name: str, body: bytes) -> None:
|
||||
"""Store ``body`` under ``name`` on disk and in the RAM cache."""
|
||||
if name in self._cache:
|
||||
return
|
||||
self.path.mkdir(parents=True, exist_ok=True)
|
||||
(self.path / name).write_bytes(body)
|
||||
self._cache[name] = self._entry(body)
|
||||
|
||||
def delete(self, name: str) -> None:
|
||||
"""Delete a file plus its derivatives/original counterparts, if any.
|
||||
|
||||
An image upload is stored as a group sharing the hash prefix
|
||||
(``<hash>.orig.<ext>`` + ``<hash>.avif/.webp/.jpg``); deleting any
|
||||
of the names removes them all.
|
||||
"""
|
||||
stem = name.partition(".")[0]
|
||||
for key in [k for k in self._cache if k.partition(".")[0] == stem]:
|
||||
self._cache.pop(key, None)
|
||||
with suppress(FileNotFoundError):
|
||||
(self.path / key).unlink()
|
||||
|
||||
def __contains__(self, name: str) -> bool:
|
||||
return name in self._cache
|
||||
|
||||
|
||||
file_store = FileStore(FILES_DIR)
|
||||
|
||||
|
||||
def _ext(orig: str) -> str:
|
||||
"""Sanitized lowercase extension (with dot) of an original file name."""
|
||||
return "".join(c for c in Path(orig).suffix.lower() if c.isalnum() or c == ".")
|
||||
|
||||
|
||||
def _hash_name(body: bytes, orig: str) -> str:
|
||||
"""Content-addressed file name: blake3 hash prefix + original extension."""
|
||||
return blake3.blake3(body).hexdigest()[:12] + _ext(orig)
|
||||
|
||||
|
||||
def _to_avif(body: bytes, ext: str, maxsize: int = IMAGE_MAXSIZE) -> bytes | None:
|
||||
"""Recompress an image body to a thumbnailed AVIF via mediapreview's
|
||||
dispatch (pyvips for common formats, ffmpeg for HEIC/HEIF/AVIF), or
|
||||
None if the body is not a decodable image (stored as-is by the caller).
|
||||
Dispatch needs a real file for format routing, so the body goes
|
||||
through a temp file.
|
||||
"""
|
||||
with tempfile.NamedTemporaryFile(suffix=ext) as tmp:
|
||||
tmp.write(body)
|
||||
tmp.flush()
|
||||
with suppress(Exception):
|
||||
# Not a decodable image: stored as-is by the caller.
|
||||
avif, _resp = dispatch(
|
||||
Path(tmp.name),
|
||||
quality=IMAGE_QUALITY,
|
||||
maxsize=maxsize,
|
||||
maxzoom=1,
|
||||
)
|
||||
return avif
|
||||
return None
|
||||
|
||||
|
||||
def _svg_to_png(body: bytes, maxsize: int) -> bytes | None:
|
||||
"""Rasterize an SVG to PNG via pyvips, scaled so the long side is
|
||||
``maxsize`` — SVGs often carry no meaningful intrinsic resolution, so
|
||||
we rasterize at full image size rather than the tiny nominal one."""
|
||||
import pyvips
|
||||
|
||||
try:
|
||||
img = pyvips.Image.new_from_buffer(body, "")
|
||||
scale = (
|
||||
maxsize / max(img.width, img.height)
|
||||
if img.width and img.height
|
||||
else maxsize
|
||||
)
|
||||
if scale != 1:
|
||||
img = pyvips.Image.new_from_buffer(body, "", scale=scale)
|
||||
return img.write_to_buffer(".png")
|
||||
except pyvips.Error:
|
||||
return None
|
||||
|
||||
|
||||
def _avif_to_format(avif: bytes, suffix: str, quality: int) -> bytes:
|
||||
"""Re-encode the AVIF derivative into a fallback format (WebP/JPEG)
|
||||
via pyvips. JPEG has no alpha, so it is flattened onto white."""
|
||||
import pyvips
|
||||
|
||||
img = pyvips.Image.new_from_buffer(avif, "")
|
||||
if suffix == ".jpg" and img.hasalpha():
|
||||
img = img.flatten(background=[255, 255, 255])
|
||||
return img.write_to_buffer(suffix, Q=quality, keep="none")
|
||||
|
||||
|
||||
def _image_derivatives(
|
||||
body: bytes, ext: str, maxsize: int = IMAGE_MAXSIZE
|
||||
) -> dict[str, bytes] | None:
|
||||
"""The served variants of an uploaded image: ``avif`` (primary,
|
||||
thumbnailed to ``maxsize``) plus ``webp`` and ``jpg`` fallbacks
|
||||
re-encoded from it. SVGs are rasterized first (they are vector, so
|
||||
the raster replaces nothing — the .svg itself stays servable).
|
||||
Returns None for non-decodable content (stored as-is by the caller).
|
||||
"""
|
||||
if ext == ".svg":
|
||||
png = _svg_to_png(body, maxsize)
|
||||
if png is None:
|
||||
return None
|
||||
body, ext = png, ".png"
|
||||
avif = _to_avif(body, ext, maxsize)
|
||||
if avif is None:
|
||||
return None
|
||||
return {
|
||||
"avif": avif,
|
||||
"webp": _avif_to_format(avif, ".webp", IMAGE_WEBP_QUALITY),
|
||||
"jpg": _avif_to_format(avif, ".jpg", IMAGE_JPG_QUALITY),
|
||||
}
|
||||
|
||||
|
||||
def store_image(
|
||||
body: bytes, ext: str, maxsize: int = IMAGE_MAXSIZE, *, derive: bool = True
|
||||
) -> str:
|
||||
"""Store an image body content-addressed and return its file name.
|
||||
|
||||
Decodable images get AVIF/WebP/JPEG derivatives thumbnailed to
|
||||
``maxsize``; the original is kept as ``<hash>.orig<ext>`` (SVG
|
||||
originals as ``<hash>.svg``, still servable) and the bare ``<hash>``
|
||||
name is returned (the server negotiates the format by Accept header).
|
||||
Anything else — undecodable content, or ``derive=False`` (GIFs, whose
|
||||
animation recompression would lose) — is stored as-is and returned with
|
||||
its extension. Blocking (pyvips/ffmpeg); call via ``asyncio.to_thread``
|
||||
from async code.
|
||||
"""
|
||||
digest = blake3.blake3(body).hexdigest()[:12]
|
||||
derivatives = _image_derivatives(body, ext, maxsize) if derive else None
|
||||
if derivatives is None: # store the body as-is
|
||||
file_store.put(digest + ext, body)
|
||||
return digest + ext
|
||||
file_store.put(f"{digest}.svg" if ext == ".svg" else f"{digest}.orig{ext}", body)
|
||||
for fmt, variant in derivatives.items():
|
||||
file_store.put(f"{digest}.{fmt}", variant)
|
||||
return digest
|
||||
|
||||
|
||||
#: Pasted-URL image fetches (fetch_image) refuse bodies over this size.
|
||||
FETCH_MAXSIZE = 20 * 1024 * 1024
|
||||
|
||||
|
||||
async def fetch_image(url: str) -> str:
|
||||
"""Fetch an image URL and store it like an upload (store_image's
|
||||
derivative pipeline), returning the stored file name.
|
||||
|
||||
Server-side because arbitrary cross-origin URLs are CORS-blocked for
|
||||
the browser; used by the editor socket when a card-image setting
|
||||
arrives as a URL (paste). 415 for non-images, 413 over FETCH_MAXSIZE,
|
||||
502 when the fetch itself fails.
|
||||
"""
|
||||
try:
|
||||
async with httpx.AsyncClient(follow_redirects=True, timeout=15) as client:
|
||||
r = await client.get(url)
|
||||
r.raise_for_status()
|
||||
except httpx.HTTPError as e:
|
||||
raise HTTPException(502, f"image fetch failed: {e}") from e
|
||||
ctype = r.headers.get("content-type", "").split(";")[0].strip().lower()
|
||||
if not ctype.startswith("image/"):
|
||||
raise HTTPException(415, "the URL is not an image")
|
||||
if len(r.content) > FETCH_MAXSIZE:
|
||||
raise HTTPException(413, "image too large")
|
||||
ext = _ext(Path(urlsplit(url).path).name) or mimetypes.guess_extension(ctype) or ""
|
||||
return await asyncio.to_thread(store_image, r.content, ext, derive=ext != ".gif")
|
||||
|
||||
|
||||
@router.put("/_api/files/{name}")
|
||||
async def upload_file(name: str, request: Request) -> dict[str, str]:
|
||||
"""Store an upload (image, video...) in the content-addressed store.
|
||||
|
||||
The stored name is a blake3 hash prefix + the original extension,
|
||||
served immutable at "/_f/{name}"; returns {"path": "/_f/..."}.
|
||||
|
||||
Raster images and SVGs are recompressed (SVGs rasterized) into AVIF
|
||||
(primary) plus WebP and JPEG fallbacks: the original goes to
|
||||
``<hash>.orig<ext>`` (kept for reprocessing, never served — it may
|
||||
carry EXIF data; SVG originals stay servable as ``<hash>.svg`` since
|
||||
vector carries no EXIF) and pages link the bare ``/_f/<hash>``, the
|
||||
server picking the format from the request's Accept header. GIFs are
|
||||
stored as-is (animation would be lost), as is other non-decodable
|
||||
content.
|
||||
"""
|
||||
if "/" in name or name in {".", ".."}:
|
||||
raise HTTPException(400, "bad file name")
|
||||
body = await request.body()
|
||||
if not body:
|
||||
raise HTTPException(400, "empty file")
|
||||
ext = _ext(name)
|
||||
stored = await asyncio.to_thread(store_image, body, ext, derive=ext != ".gif")
|
||||
return {"path": f"/_f/{stored}"}
|
||||
|
||||
|
||||
@router.delete("/_api/files/{name}", status_code=204)
|
||||
async def delete_file(name: str) -> None:
|
||||
"""Remove a file from the content-addressed store (no refcounting:
|
||||
other pages referencing the same content will 404)."""
|
||||
if name not in file_store:
|
||||
raise HTTPException(404, "no such file")
|
||||
file_store.delete(name)
|
||||
|
||||
|
||||
@router.get("/favicon.ico", include_in_schema=False)
|
||||
async def favicon_ico() -> Response:
|
||||
"""The conventional /favicon.ico: redirect to the configured site icon.
|
||||
|
||||
Browsers request this path on their own (tabs, bookmarks, feeds and
|
||||
other non-HTML contexts) regardless of the <link rel="icon"> pages
|
||||
carry. Redirect to the icon's store URL, which negotiates the format
|
||||
and caches immutably; 404 when no custom icon is configured.
|
||||
"""
|
||||
if not data.favicon:
|
||||
raise HTTPException(404)
|
||||
return RedirectResponse(f"/_f/{data.favicon}")
|
||||
|
||||
|
||||
@router.put("/_api/settings/favicon")
|
||||
async def put_favicon(request: Request) -> dict[str, str]:
|
||||
"""Upload a favicon into the content-addressed store and activate it.
|
||||
|
||||
Raw image body (ico/png/svg...). Decodable images are thumbnailed to
|
||||
FAVICON_MAXSIZE (192px — browsers scale down from there themselves)
|
||||
and stored as AVIF/WebP/JPEG derivatives linked extension-less; SVG
|
||||
originals also stay servable under their ``.svg`` name. Undecodable
|
||||
bodies are stored as-is. Pages link it as <link rel="icon">. Returns
|
||||
{"path": "/_f/..."}.
|
||||
"""
|
||||
body = await request.body()
|
||||
if not body:
|
||||
raise HTTPException(400, "empty file")
|
||||
ext = _ext(request.headers.get("x-filename", "favicon.ico"))
|
||||
stored = await asyncio.to_thread(store_image, body, ext, FAVICON_MAXSIZE)
|
||||
with kanta.transaction("settings", user=request.headers.get("remote-user")):
|
||||
data.favicon = stored
|
||||
_invalidate_pages()
|
||||
return {"path": f"/_f/{stored}"}
|
||||
|
||||
|
||||
@router.delete("/_api/settings/favicon", status_code=204)
|
||||
async def delete_favicon(request: Request) -> None:
|
||||
"""Clear the custom favicon (/favicon.ico goes back to 404, pages drop
|
||||
the <link rel="icon">).
|
||||
|
||||
The blob stays in the content-addressed store; only the reference goes.
|
||||
"""
|
||||
with kanta.transaction("settings", user=request.headers.get("remote-user")):
|
||||
data.favicon = ""
|
||||
_invalidate_pages()
|
||||
|
||||
|
||||
async def _serve_user_file(path: Path | None, request: Request) -> Response:
|
||||
"""Serve a user-asset file resolved on disk, with mtime etag.
|
||||
|
||||
Read from disk on every request (etag by mtime+size): user assets are
|
||||
never built or content-hashed, so edits on disk show on the next page
|
||||
load, in prod as well as dev.
|
||||
"""
|
||||
if path is None:
|
||||
raise HTTPException(404)
|
||||
stat = path.stat()
|
||||
etag = f'"{stat.st_mtime_ns:x}-{stat.st_size:x}"'
|
||||
if request.headers.get("if-none-match") == etag:
|
||||
return Response(status_code=304)
|
||||
mime = mimetypes.guess_type(path.name)[0] or "application/octet-stream"
|
||||
return Response(
|
||||
path.read_bytes(),
|
||||
media_type=mime,
|
||||
headers={"etag": etag, "cache-control": "no-cache"},
|
||||
)
|
||||
|
||||
|
||||
@router.get("/_themes/{name}/{filename}")
|
||||
async def theme_file(name: str, filename: str, request: Request) -> Response:
|
||||
"""Serve a theme/banner-design file, resolved across views.THEME_DIRS.
|
||||
|
||||
Stylesheets plus any extra assets the CSS references (like summer's
|
||||
grass.svg).
|
||||
"""
|
||||
return await _serve_user_file(views.theme_file(name, filename), request)
|
||||
|
||||
|
||||
@router.get("/_fonts/{name}/{filename}")
|
||||
async def user_font_file(name: str, filename: str, request: Request) -> Response:
|
||||
"""Serve a user font file, resolved across views.FONT_DIRS.
|
||||
|
||||
The folder's font.css (@font-face rules + --font-{name} stack variable)
|
||||
is linked on every page; the woff2 files it references come from here.
|
||||
"""
|
||||
return await _serve_user_file(views.font_file(name, filename), request)
|
||||
|
||||
|
||||
@router.get("/_f/{name}")
|
||||
async def stored_file(name: str, request: Request) -> Response:
|
||||
"""Serve a file from the content-addressed store (immutable: the name
|
||||
is its own hash, so cache forever). Bodies are served from the RAM
|
||||
cache, zstd-compressed when the client accepts it and compression
|
||||
actually shrank the file.
|
||||
|
||||
A bare ``/_f/{hash}`` (no extension, how pages link uploaded images)
|
||||
content-negotiates between the stored derivatives: a format is served
|
||||
only when the Accept header lists it explicitly — ``image/avif`` →
|
||||
AVIF, ``image/webp`` → WebP, anything else (including ``image/*`` and
|
||||
``*/*``) → JPEG. An explicit extension pins the format. ``.orig.``
|
||||
originals are internal (they may carry EXIF data) and never served."""
|
||||
if ".orig." in name:
|
||||
raise HTTPException(404)
|
||||
etag = name
|
||||
vary = ""
|
||||
entry = file_store.get(name)
|
||||
if entry is None and "." not in name:
|
||||
# Extension-less image link: negotiate avif/webp/jpg by Accept.
|
||||
vary = "accept"
|
||||
accept = request.headers.get("accept", "")
|
||||
if "image/avif" in accept:
|
||||
order = ("avif", "webp", "jpg")
|
||||
elif "image/webp" in accept:
|
||||
order = ("webp", "jpg", "avif")
|
||||
else:
|
||||
order = ("jpg", "webp", "avif")
|
||||
for ext in order:
|
||||
etag = f"{name}.{ext}"
|
||||
entry = file_store.get(etag)
|
||||
if entry is not None:
|
||||
break
|
||||
if entry is None:
|
||||
raise HTTPException(404)
|
||||
if request.headers.get("if-none-match") == etag:
|
||||
return Response(status_code=304)
|
||||
body, compressed = entry
|
||||
headers = {"etag": etag, "cache-control": "public, max-age=31536000, immutable"}
|
||||
if compressed is not None and "zstd" in request.headers.get("accept-encoding", ""):
|
||||
headers["content-encoding"] = "zstd"
|
||||
vary = f"{vary}, accept-encoding".lstrip(", ")
|
||||
body = compressed
|
||||
if vary:
|
||||
headers["vary"] = vary
|
||||
mime = mimetypes.guess_type(etag)[0] or "application/octet-stream"
|
||||
return Response(body, media_type=mime, headers=headers)
|
||||
@@ -0,0 +1,476 @@
|
||||
"""Localization: language selection, translation storage and assembly.
|
||||
|
||||
See docs/localization.md and docs/migrate.md. Each article's primary
|
||||
language is ``Node.language``, inherited down the hierarchy (front page =
|
||||
site default, ORIGINAL_LANGUAGE as the final fallback). The database holds
|
||||
the original language as content-addressed chunks (``Data.chunks``); per
|
||||
target language there are machine-translated fragments (``Data.trans``)
|
||||
and user overrides (``Data.overrides``), assembled into the served
|
||||
Markdown at render time, with per-node fallback to the original titles.
|
||||
"""
|
||||
|
||||
import secrets
|
||||
from collections.abc import Callable
|
||||
from difflib import SequenceMatcher
|
||||
|
||||
import msgspec
|
||||
|
||||
from pagerite.chunks import chunk_key, chunk_markdown, join_chunks
|
||||
from pagerite.data import ChunkEdit, Data, LangEdits, Node, resolve
|
||||
|
||||
#: Final fallback for a page's primary language when neither it nor any
|
||||
#: ancestor (up to the front page) sets one (Node.language, "" = inherit).
|
||||
ORIGINAL_LANGUAGE = "en"
|
||||
|
||||
#: Languages written right-to-left; pages served in one get dir="rtl" on
|
||||
#: <html> (views._layout).
|
||||
RTL_LANGUAGES = frozenset({"ar", "fa", "he", "ur"})
|
||||
|
||||
|
||||
def primary_lang(menu: dict[str, Node], path: str) -> str:
|
||||
"""The primary language of the article at ``path``: its own
|
||||
``language`` setting, else the nearest ancestor's (the front page
|
||||
last — it doubles as the site default), falling back to
|
||||
ORIGINAL_LANGUAGE. Missing tail segments (a page being created)
|
||||
resolve to the nearest existing ancestor."""
|
||||
p = path.strip("/")
|
||||
while True:
|
||||
chain = resolve(menu, p)
|
||||
if chain:
|
||||
for node in reversed(chain):
|
||||
if node.language:
|
||||
return node.language
|
||||
if not p:
|
||||
return ORIGINAL_LANGUAGE
|
||||
p = p.rpartition("/")[0]
|
||||
|
||||
|
||||
class Translation(msgspec.Struct, omit_defaults=True):
|
||||
"""Translated content for one page and language.
|
||||
|
||||
``markdown`` is the translated page source in the same format as the
|
||||
original (None = keep the original Markdown); ``titles`` maps node paths
|
||||
(top-level slug, then slash-joined) to translated navigation titles, so a
|
||||
partially translated tree still renders with per-node English fallback.
|
||||
"""
|
||||
|
||||
markdown: str | None = None
|
||||
titles: dict[str, str] = {}
|
||||
|
||||
|
||||
def base_tag(tag: str) -> str:
|
||||
"""The lowercase base subtag of a language tag (fi-FI -> fi)."""
|
||||
return tag.strip().lower().partition("-")[0]
|
||||
|
||||
|
||||
def parse_accept_language(header: str) -> list[str]:
|
||||
"""Accept-Language header as an ordered, deduped list of base subtags.
|
||||
|
||||
q-values are deliberately ignored: all known implementations send the
|
||||
header in order of preference. Region tags normalize to their base
|
||||
subtag (fi-FI -> fi); "*" and empties are dropped.
|
||||
"""
|
||||
langs = []
|
||||
for part in header.split(","):
|
||||
tag = base_tag(part.split(";", 1)[0])
|
||||
if tag and tag != "*" and tag not in langs:
|
||||
langs.append(tag)
|
||||
return langs
|
||||
|
||||
|
||||
def select_language(
|
||||
query_lang: str | None,
|
||||
accept_language: str | None,
|
||||
is_available: Callable[[str], bool],
|
||||
original: str = ORIGINAL_LANGUAGE,
|
||||
) -> str:
|
||||
"""The language to serve (see docs/localization.md).
|
||||
|
||||
1. ``?lang=`` wins when a translation exists for it (otherwise falls
|
||||
through to the header logic).
|
||||
2. Otherwise the first header language that can be served — the
|
||||
original, or one with an available translation.
|
||||
3. Fall back to the original.
|
||||
"""
|
||||
if query_lang:
|
||||
tag = base_tag(query_lang)
|
||||
if tag == original or (tag and is_available(tag)):
|
||||
return tag
|
||||
for lang in parse_accept_language(accept_language or ""):
|
||||
if lang == original or is_available(lang):
|
||||
return lang
|
||||
return original
|
||||
|
||||
|
||||
def hybrid_items(
|
||||
data: Data, node: Node, path: str, lang: str
|
||||
) -> list[tuple[bytes | None, str]]:
|
||||
"""The served hybrid as (anchor, block text) pairs: the anchor is the
|
||||
ORIGINAL chunk hash behind the block (None for translation-only
|
||||
addition blocks), in article order.
|
||||
|
||||
User overrides (``Data.overrides``) are structural: walking the
|
||||
article's own chunk order, each original chunk contributes its
|
||||
before-addition, the chunk itself (dropped, or its text replaced
|
||||
wholesale by the edit's ``replace``), and its after-addition. An
|
||||
override for a hash the article no longer contains never applies; an
|
||||
addition id referenced from two neighbors is emitted once, at the
|
||||
first live referrer.
|
||||
"""
|
||||
le = (data.overrides.get(path) or {}).get(lang)
|
||||
items: list[tuple[bytes | None, str]] = []
|
||||
emitted: set[str] = set()
|
||||
|
||||
def emit_add(add_id: str) -> None:
|
||||
if le and add_id not in emitted and (md := le.adds.get(add_id)):
|
||||
emitted.add(add_id)
|
||||
items.extend((None, block) for block in chunk_markdown(md))
|
||||
|
||||
for h in node.chunks or []:
|
||||
edit = le.chunks.get(h) if le else None
|
||||
if edit is not None:
|
||||
emit_add(edit.before)
|
||||
if edit is None or not edit.drop:
|
||||
text = (
|
||||
data.chunks.get(h, "")
|
||||
if h in node.no_trans
|
||||
else data.trans.get(h, {}).get(lang) or data.chunks.get(h, "")
|
||||
)
|
||||
if edit is not None and edit.replace:
|
||||
text = edit.replace
|
||||
items.extend((h, block) for block in chunk_markdown(text))
|
||||
if edit is not None:
|
||||
emit_add(edit.after)
|
||||
return items
|
||||
|
||||
|
||||
def hybrid_markdown(data: Data, node: Node, path: str, lang: str) -> str:
|
||||
"""The served Markdown for ``lang``: per chunk the translation from
|
||||
``Data.trans``, unless missing or marked no-translate (fallback to the
|
||||
original chunk), with the language's user overrides applied
|
||||
structurally (hybrid_items).
|
||||
|
||||
Not gated on ``node.langs`` (get_translation is the gated view): the
|
||||
editor save path diffs against this even for a language's first edit.
|
||||
"""
|
||||
return join_chunks([text for _, text in hybrid_items(data, node, path, lang)])
|
||||
|
||||
|
||||
#: Minimum block similarity for two blocks in a shrunk replace region to
|
||||
#: pair as a text edit (a per-chunk replace patch) rather than a
|
||||
#: drop + insertion (_refine_replace).
|
||||
_PAIR_MIN = 0.5
|
||||
|
||||
|
||||
def _refine_replace(
|
||||
a: list[str], i1: int, i2: int, b: list[str], j1: int, j2: int
|
||||
) -> list[tuple[str, int, int, int, int]]:
|
||||
"""Split a ``replace`` opcode that removed blocks (more source than
|
||||
edited blocks) into single-block sub-opcodes: greedily pair the most
|
||||
similar source/edited blocks as text edits — a sentence fixed in the
|
||||
paragraph above a deleted paragraph must not drag the deletion into
|
||||
the same replace pair — leaving unpaired source blocks as deletions
|
||||
and any unpaired edited blocks as insertions.
|
||||
|
||||
Only shrunk regions are refined: 1:1 replacements (up to a full
|
||||
paragraph rewrite) and paragraph splits stay single replace pairs by
|
||||
design. Regions are a handful of blocks, so the O(n*m) pairing with a
|
||||
character-level ratio per candidate is cheap, and pages are small, so
|
||||
the greedy best-first order is deterministic enough.
|
||||
"""
|
||||
paired: list[tuple[int, int]] = []
|
||||
left_a = list(range(i1, i2))
|
||||
left_b = list(range(j1, j2))
|
||||
while left_a and left_b:
|
||||
ratio, ai, bj = max(
|
||||
(SequenceMatcher(None, a[x], b[y], autojunk=False).ratio(), x, y)
|
||||
for x in left_a
|
||||
for y in left_b
|
||||
)
|
||||
if ratio < _PAIR_MIN:
|
||||
break
|
||||
paired.append((ai, bj))
|
||||
left_a.remove(ai)
|
||||
left_b.remove(bj)
|
||||
ops = []
|
||||
for ai, bj in paired:
|
||||
ops.append((ai, bj, ("replace", ai, ai + 1, bj, bj + 1)))
|
||||
for ai in left_a:
|
||||
ops.append((ai, j1, ("delete", ai, ai + 1, j1, j1)))
|
||||
for bj in left_b:
|
||||
# Anchor an unpaired insertion just after the nearest preceding
|
||||
# paired source block (the region start when none).
|
||||
pos = max((ai + 1 for ai, prev in paired if prev < bj), default=i1)
|
||||
ops.append((pos, bj, ("insert", pos, pos, bj, bj + 1)))
|
||||
return [op for _, _, op in sorted(ops, key=lambda e: (e[0], e[1]))]
|
||||
|
||||
|
||||
def record_override(
|
||||
data: Data, node: Node, path: str, lang: str, edited: str, base: str | None = None
|
||||
) -> bool:
|
||||
"""Record a translated-view edit as user overrides (``Data.overrides``):
|
||||
the block-level diff of ``edited`` against ``base`` (default: the
|
||||
currently served hybrid), classified per original chunk (docs/
|
||||
localization.md):
|
||||
|
||||
- a changed block becomes its chunk's full-text ``replace`` patch — a
|
||||
re-edit composes into the patch;
|
||||
- a removed block becomes its chunk's ``drop``;
|
||||
- new blocks become an addition in ``adds``, anchored from the
|
||||
neighboring chunks' ``before``/``after`` (inserts next to existing
|
||||
addition text splice into that addition instead).
|
||||
|
||||
Each save touches only the keys of the chunks actually edited. Every
|
||||
classification is best effort: a diff position whose base text no
|
||||
longer matches what the hybrid serves there (the original or the
|
||||
machine translation moved under an open editor) is skipped rather than
|
||||
recorded against the wrong chunk. Overrides alone make the translated
|
||||
version exist, so ``node.langs`` is set. Returns True when anything
|
||||
was recorded. Pure data ops — the caller wraps in a transaction and
|
||||
invalidates.
|
||||
|
||||
The callers reject pages without original chunks (there is nothing to
|
||||
anchor a translation to); should one slip through, the diff finds no
|
||||
anchors and nothing is recorded.
|
||||
"""
|
||||
le = (data.overrides.get(path) or {}).get(lang)
|
||||
items = hybrid_items(data, node, path, lang)
|
||||
a = chunk_markdown(base) if base is not None else [text for _, text in items]
|
||||
b = chunk_markdown(edited)
|
||||
aligned = len(a) == len(items)
|
||||
changed = False
|
||||
|
||||
def edits() -> LangEdits:
|
||||
nonlocal le
|
||||
if le is None:
|
||||
le = data.overrides.setdefault(path, {}).setdefault(lang, LangEdits())
|
||||
return le
|
||||
|
||||
def anchor_at(i: int) -> bytes | None:
|
||||
return items[i][0] if aligned else None
|
||||
|
||||
def verified(i: int) -> bool:
|
||||
"""The diff position still holds the text the hybrid serves there
|
||||
(False when the original or the translation moved under an open
|
||||
editor — structural ops against a shifted position are skipped)."""
|
||||
return aligned and a[i] == items[i][1]
|
||||
|
||||
def served(h: bytes) -> str:
|
||||
return (
|
||||
data.chunks.get(h, "")
|
||||
if h in node.no_trans
|
||||
else data.trans.get(h, {}).get(lang) or data.chunks.get(h, "")
|
||||
)
|
||||
|
||||
def find_add(block: str) -> tuple[str, list[str]] | None:
|
||||
"""(id, blocks) of the addition containing ``block`` (exact block
|
||||
match — addition text is stable, user-written)."""
|
||||
if le:
|
||||
for add_id, md in le.adds.items():
|
||||
blocks = chunk_markdown(md)
|
||||
if block in blocks:
|
||||
return add_id, blocks
|
||||
return None
|
||||
|
||||
def do_delete(i: int) -> None:
|
||||
nonlocal changed
|
||||
h = anchor_at(i)
|
||||
if h is not None:
|
||||
if not verified(i):
|
||||
return
|
||||
ce = edits().chunks.setdefault(h, ChunkEdit())
|
||||
ce.drop = True
|
||||
ce.replace = ""
|
||||
elif found := find_add(a[i]):
|
||||
add_id, blocks = found
|
||||
blocks.remove(a[i])
|
||||
if blocks:
|
||||
edits().adds[add_id] = "\n\n".join(blocks)
|
||||
else:
|
||||
del edits().adds[add_id]
|
||||
else:
|
||||
return
|
||||
changed = True
|
||||
|
||||
def do_insert(i1: int, new_blocks: list[str]) -> None:
|
||||
nonlocal changed
|
||||
left, right = i1 > 0, i1 < len(a)
|
||||
# Next to existing addition text: splice into that addition.
|
||||
if left and anchor_at(i1 - 1) is None and (found := find_add(a[i1 - 1])):
|
||||
add_id, blocks = found
|
||||
idx = blocks.index(a[i1 - 1]) + 1
|
||||
blocks[idx:idx] = new_blocks
|
||||
edits().adds[add_id] = "\n\n".join(blocks)
|
||||
elif right and anchor_at(i1) is None and (found := find_add(a[i1])):
|
||||
add_id, blocks = found
|
||||
idx = blocks.index(a[i1])
|
||||
blocks[idx:idx] = new_blocks
|
||||
edits().adds[add_id] = "\n\n".join(blocks)
|
||||
else:
|
||||
# An inter-chunk gap: anchor on the neighboring original
|
||||
# chunks (both, when both verify — the first live referrer
|
||||
# wins at apply time).
|
||||
after_h = anchor_at(i1) if right and verified(i1) else None
|
||||
before_h = anchor_at(i1 - 1) if left and verified(i1 - 1) else None
|
||||
if after_h is None and before_h is None:
|
||||
return # no live anchor (drifted base): skip
|
||||
add_id = ""
|
||||
for h, field in ((after_h, "before"), (before_h, "after")):
|
||||
if h is not None and (ce := le.chunks.get(h) if le else None):
|
||||
add_id = add_id or getattr(ce, field)
|
||||
if add_id and add_id in edits().adds:
|
||||
edits().adds[add_id] += "\n\n" + "\n\n".join(new_blocks)
|
||||
else:
|
||||
add_id = secrets.token_hex(6)
|
||||
edits().adds[add_id] = "\n\n".join(new_blocks)
|
||||
if after_h is not None:
|
||||
edits().chunks.setdefault(after_h, ChunkEdit()).before = add_id
|
||||
if before_h is not None:
|
||||
edits().chunks.setdefault(before_h, ChunkEdit()).after = add_id
|
||||
changed = True
|
||||
|
||||
def do_replace(i: int, new_blocks: list[str]) -> None:
|
||||
nonlocal changed
|
||||
h = anchor_at(i)
|
||||
if h is None:
|
||||
if not (found := find_add(a[i])):
|
||||
return
|
||||
add_id, blocks = found
|
||||
blocks[blocks.index(a[i]) : blocks.index(a[i]) + 1] = new_blocks
|
||||
edits().adds[add_id] = "\n\n".join(blocks)
|
||||
else:
|
||||
if not verified(i):
|
||||
return
|
||||
ce = le.chunks.get(h) if le else None
|
||||
# The base shows the live patch when one exists, else the
|
||||
# served text: splice the edit into its blocks, so the patch
|
||||
# always covers the chunk's whole text (a patch may hold
|
||||
# several blocks — a paragraph split). a[i] not in the blocks
|
||||
# = the base doesn't reflect this chunk (drifted): skip.
|
||||
base_text = ce.replace if ce is not None and ce.replace else served(h)
|
||||
blocks = chunk_markdown(base_text)
|
||||
if a[i] not in blocks:
|
||||
return
|
||||
blocks[blocks.index(a[i]) : blocks.index(a[i]) + 1] = new_blocks
|
||||
if ce is None:
|
||||
ce = edits().chunks.setdefault(h, ChunkEdit())
|
||||
ce.replace = "\n\n".join(blocks)
|
||||
ce.drop = False
|
||||
changed = True
|
||||
|
||||
def emit(tag: str, i1: int, i2: int, j1: int, j2: int) -> None:
|
||||
if tag == "delete":
|
||||
for i in range(i1, i2):
|
||||
do_delete(i)
|
||||
elif tag == "insert":
|
||||
do_insert(i1, list(b[j1:j2]))
|
||||
elif i2 - i1 == 1: # replace of one block, possibly into several
|
||||
do_replace(i1, list(b[j1:j2]))
|
||||
else: # a grown region: pair positionally, insert the surplus
|
||||
for k in range(i2 - i1):
|
||||
do_replace(i1 + k, [b[j1 + k]])
|
||||
do_insert(i2, list(b[j1 + i2 - i1 : j2]))
|
||||
|
||||
for tag, i1, i2, j1, j2 in SequenceMatcher(
|
||||
None, a, b, autojunk=False
|
||||
).get_opcodes():
|
||||
if tag == "equal":
|
||||
continue
|
||||
if tag == "replace" and i2 - i1 > j2 - j1:
|
||||
for sub in _refine_replace(a, i1, i2, b, j1, j2):
|
||||
emit(*sub)
|
||||
else:
|
||||
emit(tag, i1, i2, j1, j2)
|
||||
if not changed:
|
||||
return False
|
||||
node.langs[lang] = True
|
||||
return True
|
||||
|
||||
|
||||
def set_title_translation(data: Data, node: Node, lang: str, title: str) -> bool:
|
||||
"""Record (or drop) a per-language title override: a fragment in
|
||||
``Data.trans`` keyed by the ORIGINAL title's chunk hash — the same
|
||||
storage machine title translations use, overriding them. Sending the
|
||||
original's text drops the override. Returns True when anything changed.
|
||||
Pure data ops — the caller wraps in a transaction and invalidates."""
|
||||
key = chunk_key(node.title)
|
||||
current = data.trans.get(key, {}).get(lang)
|
||||
if title == node.title:
|
||||
if current is None:
|
||||
return False
|
||||
del data.trans[key][lang]
|
||||
return True
|
||||
if current == title:
|
||||
return False
|
||||
data.trans.setdefault(key, {})[lang] = title
|
||||
node.langs[lang] = True
|
||||
return True
|
||||
|
||||
|
||||
def clear_translations(data: Data) -> None:
|
||||
"""Drop all machine translations (``Data.trans``) and rebuild the
|
||||
availability index (``node.langs``) from the surviving user overrides —
|
||||
overrides alone make a language exist on a page. Pure data ops — the
|
||||
caller wraps in a transaction and invalidates."""
|
||||
data.trans.clear()
|
||||
|
||||
def walk(nodes: dict[str, Node], prefix: str) -> None:
|
||||
for slug, node in nodes.items():
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
node.langs = {lang: True for lang in data.overrides.get(path, ())}
|
||||
walk(node.children, path)
|
||||
|
||||
walk(data.menu, "")
|
||||
|
||||
|
||||
def title_map(data: Data, lang: str) -> dict[str, str]:
|
||||
"""path -> translated title for every node that has one.
|
||||
|
||||
Titles are chunks too (docs/migrate.md): keyed by the hash of the
|
||||
title text, so editing a title invalidates its translations. Nodes
|
||||
without an entry fall back to their original title in views — as do
|
||||
nodes whose primary language IS ``lang`` (their original title already
|
||||
is in that language).
|
||||
"""
|
||||
titles = {}
|
||||
|
||||
def walk(nodes: dict[str, Node], prefix: str, inherited: str) -> None:
|
||||
for slug, node in nodes.items():
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
node_lang = node.language or inherited
|
||||
if node.title and node_lang != lang:
|
||||
t = data.trans.get(chunk_key(node.title), {}).get(lang)
|
||||
if t:
|
||||
titles[path] = t
|
||||
walk(node.children, path, node_lang)
|
||||
|
||||
walk(data.menu, "", ORIGINAL_LANGUAGE)
|
||||
return titles
|
||||
|
||||
|
||||
def subtree_languages(node: Node) -> set[str]:
|
||||
"""Languages available anywhere in the node's subtree (the union of the
|
||||
``langs`` indexes). Category placeholder pages select their language
|
||||
from this: they have no chunks of their own, but their title,
|
||||
navigation and card text localize wherever a translation exists."""
|
||||
langs = set(node.langs)
|
||||
for child in node.children.values():
|
||||
langs |= subtree_languages(child)
|
||||
return langs
|
||||
|
||||
|
||||
def get_translation(data: Data, path: str, lang: str) -> Translation | None:
|
||||
"""The translation of the page at ``path`` for ``lang``, or None.
|
||||
|
||||
None when the page does not exist or is not available in ``lang``:
|
||||
``node.langs`` is the availability index (a stale key is benign — the
|
||||
"translation" then just renders as the original).
|
||||
"""
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is None or node.chunks is None or lang not in node.langs:
|
||||
return None
|
||||
return Translation(
|
||||
markdown=hybrid_markdown(data, node, path, lang),
|
||||
titles=title_map(data, lang),
|
||||
)
|
||||
@@ -4,12 +4,45 @@ Raw HTML (including inline scripts) is passed through unfiltered: the
|
||||
single author is trusted. Extensions: tables and strikethrough (from the
|
||||
"default" preset), footnotes, definition lists, task lists,
|
||||
brace-attributes (`{.class width=300}` on any element, images in
|
||||
particular) and admonitions (``!!! note Title`` with an indented body —
|
||||
note/tip/warning/etc., the title optional). Bare URLs autolink (GFM), with
|
||||
particular), admonitions (``!!! note Title`` with an indented body —
|
||||
note/tip/warning/etc., the title optional) and GitHub-style alerts
|
||||
(``> [!NOTE]`` / TIP / IMPORTANT / WARNING / CAUTION, rendered in the
|
||||
same callout styling). ``::: name`` opens a generic container rendered
|
||||
as ``<div class="name">`` and closed by a matching ``:::`` (nest by
|
||||
giving the outer container more colons, e.g. `::::`); the name may be
|
||||
followed by brace attributes (``::: aside {.right}``), or omitted for a
|
||||
pandoc-style nameless div (``::: {.aside}``). ``::: aside``
|
||||
floats as a muted side box, floating in the side zone at the article's
|
||||
left on all but phone widths — the same margin float ``{.margin}`` (or
|
||||
``::: margin``) gives any block — and ``::: nocols`` opts its section out
|
||||
of the column layout. A brace-attribute
|
||||
line as a block's last line (no blank line between) applies to the whole
|
||||
block, e.g. a paragraph ending with ``{.wide}`` breaks out of the column
|
||||
layout as a full-width element; written after a block (code fence,
|
||||
heading, container, ...) it applies to that preceding block. Bare URLs autolink (GFM), with
|
||||
the ``https://`` scheme hidden in the link text (``http://`` and other
|
||||
schemes stay visible; manually labelled links are untouched), and
|
||||
``H~2~O`` / ``x^2^`` give sub/superscripts.
|
||||
|
||||
render() also builds the layout structure: the top-level blocks are
|
||||
segmented for the column layout — h1/h2 headings and ``.wide`` blocks
|
||||
stand on their own, the runs between them are wrapped in
|
||||
``<div class="colseg">`` (tagged
|
||||
``.cols`` when the segment holds enough text — COLS_TEXT — in at least
|
||||
COLS_PARAS paragraphs or one paragraph long enough to turn .breakable,
|
||||
unless a ``::: nocols`` container opts it out;
|
||||
in column segments, paragraphs past BREAKABLE_TEXT are marked
|
||||
``.breakable`` so they may split across columns). Margin-breakout boxes
|
||||
(``.margin``, ``::: aside``) stay inside the segment at their anchor
|
||||
point; pagerite.css takes them out of flow (absolute, off the article's
|
||||
left border, into the side zone), so the columns flow through as if the
|
||||
box wasn't there. The result carries
|
||||
``multicol`` when the whole body justifies columns (views.py puts the
|
||||
class on the article); how many columns (never more than two), whether
|
||||
the margin breakout applies and every other viewport adaptation is then
|
||||
pagerite.css's call. The thresholds measure visible text, code blocks
|
||||
excluded.
|
||||
|
||||
markdown-it's typographer is enabled, so body text gets SmartyPants-style
|
||||
replacements: straight quotes become curly, ``--`` / ``---`` become en / em
|
||||
dashes, ``...`` becomes an ellipsis, ``(c)`` becomes ©, and so on. Single
|
||||
@@ -23,16 +56,27 @@ becomes a block `<figure>` — with `<figcaption>` when it has a title.
|
||||
Images inline with other content stay plain inline `<img>`, as does raw
|
||||
`<img>` HTML written by the author. Positioning is done with attribute
|
||||
classes, e.g. `{.right}`.
|
||||
|
||||
A lone `{name}` or `{name: args}` line is a block directive, expanded by
|
||||
the caller through render(directives=...) — `{dates}` (built in) expands
|
||||
to the article's dateline, `{cards}` / `{cards: path ...}` to card rows
|
||||
of other pages (views.py). Unresolved tags render as the literal source.
|
||||
"""
|
||||
|
||||
import re
|
||||
from collections.abc import Callable
|
||||
from datetime import datetime, timedelta
|
||||
from typing import NamedTuple
|
||||
|
||||
from markdown_it import MarkdownIt
|
||||
from markdown_it.common.utils import escapeHtml
|
||||
from markdown_it.renderer import RendererHTML
|
||||
from markdown_it.token import Token
|
||||
from mdit_py_plugins.admon import admon_plugin
|
||||
from mdit_py_plugins.attrs import attrs_plugin
|
||||
from mdit_py_plugins.attrs.parse import ParseError
|
||||
from mdit_py_plugins.attrs.parse import parse as parse_attrs
|
||||
from mdit_py_plugins.container import container_plugin
|
||||
from mdit_py_plugins.deflist import deflist_plugin
|
||||
from mdit_py_plugins.footnote import footnote_plugin
|
||||
from mdit_py_plugins.gfm_autolink import gfm_autolink_plugin
|
||||
@@ -43,6 +87,7 @@ from pygments import highlight
|
||||
from pygments.formatters import HtmlFormatter
|
||||
from pygments.lexers import get_lexer_by_name
|
||||
from pygments.util import ClassNotFound
|
||||
from slugify import slugify
|
||||
|
||||
# Styles in /_assets/pygments-*.css match this formatter (regenerate:
|
||||
# HtmlFormatter(style="github-dark").get_style_defs("pre code"))
|
||||
@@ -65,6 +110,45 @@ def _highlight(text: str, lang: str, _attrs: str) -> str:
|
||||
return highlight(text, lexer, _formatter)
|
||||
|
||||
|
||||
def _fence_rule(
|
||||
self: RendererHTML,
|
||||
tokens,
|
||||
idx: int,
|
||||
options,
|
||||
env: dict,
|
||||
) -> str:
|
||||
"""Render a fenced code block.
|
||||
|
||||
Like the default fence rule, but block attributes go on the <pre> —
|
||||
the block element — instead of the <code>, which keeps only the
|
||||
language class. Attributes are accepted both pandoc-style on the
|
||||
info line (```{.python .wide #id key=val} — the first class is the
|
||||
language when no bare language word precedes the braces) and as a
|
||||
trailing `{...}` line applied by _block_attrs. This is what makes
|
||||
e.g. `{.wide}` or `{style="..."}` style the block itself.
|
||||
"""
|
||||
token = tokens[idx]
|
||||
info = token.info.strip() if token.info else ""
|
||||
lang, _, brace = info.partition("{")
|
||||
lang = lang.split(maxsplit=1)[0] if lang.strip() else ""
|
||||
if brace:
|
||||
try:
|
||||
_, attrs = parse_attrs("{" + brace)
|
||||
except ParseError:
|
||||
attrs = {}
|
||||
classes = attrs.pop("class", "").split()
|
||||
if not lang and classes:
|
||||
lang = classes.pop(0)
|
||||
if classes:
|
||||
_apply_attrs(token, {"class": " ".join(classes)})
|
||||
_apply_attrs(token, attrs)
|
||||
highlighted = _highlight(token.content, lang, "") or escapeHtml(token.content)
|
||||
code_class = f' class="{options.langPrefix}{lang}"' if lang else ""
|
||||
return (
|
||||
f"<pre{self.renderAttrs(token)}><code{code_class}>{highlighted}</code></pre>\n"
|
||||
)
|
||||
|
||||
|
||||
def _image_rule(
|
||||
self: RendererHTML,
|
||||
tokens,
|
||||
@@ -79,14 +163,27 @@ def _image_rule(
|
||||
page = env.get("page_path", "")
|
||||
token.attrs["src"] = f"/{page}/{src}" if page else f"/{src}"
|
||||
token.attrs["alt"] = self.renderInlineAsText(token.children, options, env)
|
||||
img = self.renderToken(tokens, idx, options, env)
|
||||
if len(tokens) == 1:
|
||||
# The only inline content of its paragraph: render as a block
|
||||
# figure, captioned when titled. (The <p> wrapper is dropped by
|
||||
# _unwrap_lone_figures below.)
|
||||
# _unwrap_lone_figures below.) {.margin} positions the whole
|
||||
# figure, so it moves from the img onto the figure wrapper — left
|
||||
# on the img, the margin-breakout CSS would pull the image out of
|
||||
# the figure (and mostly off-screen), leaving the caption behind.
|
||||
classes = (token.attrs.get("class") or "").split()
|
||||
figure_class = ""
|
||||
if "margin" in classes:
|
||||
classes.remove("margin")
|
||||
if classes:
|
||||
token.attrs["class"] = " ".join(classes)
|
||||
else:
|
||||
del token.attrs["class"]
|
||||
figure_class = ' class="margin"'
|
||||
img = self.renderToken(tokens, idx, options, env)
|
||||
title = token.attrs.get("title")
|
||||
caption = f"<figcaption>{escapeHtml(title)}</figcaption>" if title else ""
|
||||
return f"<figure>{img}{caption}</figure>"
|
||||
return f"<figure{figure_class}>{img}{caption}</figure>"
|
||||
img = self.renderToken(tokens, idx, options, env)
|
||||
# Inline with other content: a plain inline image.
|
||||
return img
|
||||
|
||||
@@ -103,10 +200,23 @@ def _unwrap_lone_figures(state) -> None:
|
||||
for i, token in enumerate(tokens):
|
||||
if token.type != "inline" or not token.children:
|
||||
continue
|
||||
[child] = token.children if len(token.children) == 1 else [None]
|
||||
if child and child.type == "image":
|
||||
if (tokens[i - 1].type == "paragraph_open"
|
||||
and tokens[i + 1].type == "paragraph_close"):
|
||||
# Attrs consumed out of the text (e.g. {style=...} space-separated
|
||||
# on the image's own line) leave empty text tokens behind — strip
|
||||
# them so the lone-image check is not thrown off by user styling.
|
||||
children = [c for c in token.children if c.type != "text" or c.content]
|
||||
if children:
|
||||
token.children = children
|
||||
[child] = children if len(children) == 1 else [None]
|
||||
if (
|
||||
child
|
||||
and child.type == "image"
|
||||
and tokens[i - 1].type == "paragraph_open"
|
||||
and tokens[i + 1].type == "paragraph_close"
|
||||
):
|
||||
# A lone image becomes a <figure> (see _image_rule); block
|
||||
# attrs on the paragraph (e.g. a trailing {.wide} line) move
|
||||
# onto the image so they survive the unwrap.
|
||||
_apply_attrs(child, tokens[i - 1].attrs or {})
|
||||
tokens[i - 1].hidden = True
|
||||
tokens[i + 1].hidden = True
|
||||
|
||||
@@ -149,29 +259,471 @@ def _shorten_autolinks(state) -> None:
|
||||
text.content = text.content.removeprefix("https://")
|
||||
|
||||
|
||||
md = (
|
||||
_CONTAINER_NAME_RE = re.compile(r"[a-zA-Z][\w-]*")
|
||||
|
||||
|
||||
def _apply_attrs(token, attrs: dict) -> None:
|
||||
"""Join/set parsed brace attributes (`{.class key=value}`) on a token."""
|
||||
for key, value in attrs.items():
|
||||
if key == "class":
|
||||
token.attrJoin("class", value)
|
||||
else:
|
||||
token.attrSet(key, value)
|
||||
|
||||
|
||||
def _container_validate(params: str, _markup: str) -> bool:
|
||||
"""`::: name`, optionally followed by brace attrs (`::: aside {.right}`).
|
||||
|
||||
Pandoc-style nameless divs (`::: {.aside}`) are accepted too — the
|
||||
attrs alone give the container its classes.
|
||||
"""
|
||||
name, _, rest = params.strip().partition(" ")
|
||||
if name.startswith("{"):
|
||||
name, rest = "", params.strip()
|
||||
elif not _CONTAINER_NAME_RE.fullmatch(name):
|
||||
return False
|
||||
rest = rest.strip()
|
||||
if not rest:
|
||||
return bool(name) # a nameless container needs the attrs
|
||||
try:
|
||||
pos, _ = parse_attrs(rest)
|
||||
except ParseError:
|
||||
return False
|
||||
# parse() stops at (returns the index of) the closing brace.
|
||||
return pos == len(rest) - 1
|
||||
|
||||
|
||||
def _container_attrs(state) -> None:
|
||||
"""Apply `::: name {attrs}` classes to container tokens at parse time.
|
||||
|
||||
The container plugin's default render is a plain renderToken, so the
|
||||
name and brace attributes must live on the token itself — and being a
|
||||
core rule (rather than a render rule) lets the segmentation in
|
||||
render() see the classes (the ::: nocols opt-out, {.wide}
|
||||
containers).
|
||||
"""
|
||||
for token in state.tokens:
|
||||
if token.type != "container_block_open":
|
||||
continue
|
||||
info = token.info.strip()
|
||||
name, _, rest = info.partition(" ")
|
||||
if name.startswith("{"):
|
||||
name, rest = "", info
|
||||
if name:
|
||||
token.attrJoin("class", name)
|
||||
if rest.strip():
|
||||
_, attrs = parse_attrs(rest.strip())
|
||||
_apply_attrs(token, attrs)
|
||||
|
||||
|
||||
def _block_attrs(state) -> None:
|
||||
"""Apply `{.class key=value}` on a block's last line to the block.
|
||||
|
||||
The inline attrs plugin only covers attributes right after an image,
|
||||
code span or link; this extends the same brace syntax to whole blocks.
|
||||
A paragraph takes them at the end of its last line, either directly
|
||||
(a trailing `{.wide}` line, no blank line between) or space-separated
|
||||
at the end of the text (`some text {.small}`) — a space means the
|
||||
braces belong to the block, not to an image or link before them.
|
||||
A lone `{...}` paragraph applies to the previous block instead (this
|
||||
is how headings take attributes, since a heading's next line always
|
||||
starts a new paragraph). Runs before the typographer so quotes inside
|
||||
attributes stay straight.
|
||||
"""
|
||||
tokens = state.tokens
|
||||
for i, token in enumerate(tokens):
|
||||
if token.type != "inline" or not token.children:
|
||||
continue
|
||||
text = token.children[-1]
|
||||
if text.type != "text":
|
||||
continue
|
||||
m = re.search(r"(\{[^{}]*\})\s*$", text.content)
|
||||
if not m:
|
||||
continue
|
||||
start = m.start(1)
|
||||
if start and not text.content[start - 1].isspace():
|
||||
continue # glued to the text — literal, or inline attrs
|
||||
try:
|
||||
_, attrs = parse_attrs(m.group(1))
|
||||
except ParseError:
|
||||
continue
|
||||
standalone = len(token.children) == 1
|
||||
if not standalone and start == 0 and token.children[-2].type != "softbreak":
|
||||
continue
|
||||
# The target: the enclosing block for a trailing attrs line, or the
|
||||
# previous same-level block for a standalone attrs paragraph —
|
||||
# including self-contained blocks like code fences and <hr>. Never
|
||||
# a hidden token (tight-list paragraphs render no tag to hold the
|
||||
# attributes) — in that case leave the text untouched instead of
|
||||
# silently swallowing it.
|
||||
own = i - 1 # standalone: the attrs paragraph's own opening token
|
||||
j = i - 1
|
||||
while j >= 0:
|
||||
target = tokens[j]
|
||||
if target.hidden:
|
||||
pass
|
||||
elif standalone:
|
||||
if (
|
||||
j != own
|
||||
and target.level == tokens[own].level
|
||||
and (
|
||||
target.nesting == 1
|
||||
or target.type in ("fence", "code_block", "hr")
|
||||
)
|
||||
):
|
||||
break
|
||||
elif target.nesting == 1:
|
||||
break
|
||||
j -= 1
|
||||
if j < 0:
|
||||
continue
|
||||
_apply_attrs(tokens[j], attrs)
|
||||
if standalone:
|
||||
tokens[own].hidden = True
|
||||
token.children = []
|
||||
tokens[i + 1].hidden = True
|
||||
elif start == 0:
|
||||
del token.children[-2:]
|
||||
else:
|
||||
# Braces space-separated at the end of a text line: strip them
|
||||
# (a whitespace-only remainder means they were on a line of
|
||||
# their own after all — drop the softbreak too).
|
||||
text.content = text.content[:start].rstrip()
|
||||
if not text.content and token.children[-2].type == "softbreak":
|
||||
del token.children[-2:]
|
||||
|
||||
|
||||
#: Minimum number of in-body h1/h2 headings for section anchors to be
|
||||
#: useful — shorter articles get no ids/self-links at all.
|
||||
ANCHOR_MIN_HEADINGS = 3
|
||||
|
||||
|
||||
def _heading_ids(state) -> None:
|
||||
"""Anchor the in-body h1/h2 headings of long-enough articles.
|
||||
|
||||
The markdown body's own h1 and h2 headings get a slug id and their
|
||||
text is wrapped in a self-link (``<a class="anchor" href="#id">``) so
|
||||
section links are copyable by click or right-click — but only when the
|
||||
body has at least ANCHOR_MIN_HEADINGS of them; shorter articles stay
|
||||
anchor-free. The FIRST h1 is the article title: like the implicit
|
||||
page-title h1 it gets no id, does not count toward the threshold, and
|
||||
its self-link is ``href=""`` (back to the top of the page). An
|
||||
author-set `{#id}` always wins; auto ids slugify the heading text
|
||||
(python-slugify, mirroring the editor's slugify.js) and dedupe with
|
||||
-2/-3 suffixes per render — unless env["anchor_ids"] presets them, as
|
||||
render(anchors_from=...) does for translated pages so section URLs
|
||||
stay in the original language. Headings that already contain a link are
|
||||
``data-line`` records the heading's markdown source line (0-based, after
|
||||
undoing the render(title=...) injection offset via ``env``) — the page
|
||||
editor uses it for section pens and piecewise-linear scroll sync.
|
||||
"""
|
||||
tokens = state.tokens
|
||||
line_offset = state.env.get("line_offset", 0)
|
||||
|
||||
def wrap(i: int, token, href: str) -> None:
|
||||
inline = tokens[i + 1]
|
||||
if not inline.children or any(c.type == "link_open" for c in inline.children):
|
||||
return
|
||||
anchor = Token("link_open", "a", 1)
|
||||
anchor.attrs = {"href": href, "class": "anchor"}
|
||||
inline.children = [anchor, *inline.children, Token("link_close", "a", -1)]
|
||||
|
||||
# The first in-body h1 is the title: href="" self-link, never an id.
|
||||
# Only TOP-LEVEL headings participate — h1/h2 nested in ::: containers
|
||||
# or asides (level > 0) get no anchors, data-lines or pens.
|
||||
first_h1 = next(
|
||||
(
|
||||
i
|
||||
for i, t in enumerate(tokens)
|
||||
if t.type == "heading_open" and t.tag == "h1" and t.level == 0
|
||||
),
|
||||
None,
|
||||
)
|
||||
if first_h1 is not None:
|
||||
wrap(first_h1, tokens[first_h1], "")
|
||||
|
||||
heads = [
|
||||
(i, token)
|
||||
for i, token in enumerate(tokens)
|
||||
if token.type == "heading_open"
|
||||
and token.tag in ("h1", "h2")
|
||||
and token.level == 0
|
||||
and i != first_h1
|
||||
]
|
||||
if len(heads) < ANCHOR_MIN_HEADINGS:
|
||||
return
|
||||
seen: set[str] = set()
|
||||
preset = state.env.get("anchor_ids")
|
||||
for k, (i, token) in enumerate(heads):
|
||||
inline = tokens[i + 1]
|
||||
hid = token.attrGet("id")
|
||||
if not isinstance(hid, str) or not hid:
|
||||
if preset is not None and k < len(preset):
|
||||
# Translated render: the original language's slug, matched
|
||||
# by heading position (a translation never adds, removes or
|
||||
# reorders headings; a patched one that does falls back to
|
||||
# slugging its own text past the end of the list).
|
||||
base = preset[k]
|
||||
else:
|
||||
# Slug the visible text, not the raw markdown (`## [a](url)`).
|
||||
text = "".join(
|
||||
c.content
|
||||
for c in inline.children
|
||||
if c.type in ("text", "code_inline")
|
||||
)
|
||||
base = slugify(text) or "section"
|
||||
hid, n = base, 2
|
||||
while hid in seen:
|
||||
hid = f"{base}-{n}"
|
||||
n += 1
|
||||
token.attrSet("id", hid)
|
||||
seen.add(hid)
|
||||
if token.map:
|
||||
token.attrSet("data-line", str(max(0, token.map[0] - line_offset)))
|
||||
wrap(i, token, f"#{hid}")
|
||||
|
||||
|
||||
def anchor_ids(text: str, title: str | None = None) -> list[str]:
|
||||
"""The section anchor ids of text, in heading order.
|
||||
|
||||
render(anchors_from=...) feeds these to _heading_ids via
|
||||
env["anchor_ids"], pinning a translated render's anchors to the
|
||||
original language's slugs. The selection mirrors _heading_ids exactly
|
||||
(the same md instance assigns the ids during this parse, author-set
|
||||
{#id} included as-is); the in-body title h1 is excluded.
|
||||
"""
|
||||
if title and not has_h1(text):
|
||||
text = f"# {title}\n\n{text}"
|
||||
tokens = md.parse(text, {"page_path": ""})
|
||||
first_h1 = next(
|
||||
(
|
||||
i
|
||||
for i, t in enumerate(tokens)
|
||||
if t.type == "heading_open" and t.tag == "h1" and t.level == 0
|
||||
),
|
||||
None,
|
||||
)
|
||||
return [
|
||||
t.attrGet("id")
|
||||
for i, t in enumerate(tokens)
|
||||
if t.type == "heading_open"
|
||||
and t.tag in ("h1", "h2")
|
||||
and t.level == 0
|
||||
and i != first_h1
|
||||
]
|
||||
|
||||
|
||||
#: A lone {...} paragraph: a block directive like {dates} or
|
||||
#: {cards: docs/* news} — name, then optional ":"-separated argument text.
|
||||
_DIRECTIVE_RE = re.compile(r"\{([a-z][a-z0-9_-]*)(?::([^{}\n]*))?\}")
|
||||
|
||||
|
||||
def _directives(state) -> None:
|
||||
"""Turn lone ``{name}`` / ``{name: args}`` paragraphs into directive tokens.
|
||||
|
||||
The expansion is not markdown.py's business: _directive_rule delegates
|
||||
to the resolvers render() put in env["directives"], falling back to the
|
||||
literal source when the tag is unknown in the context (e.g. the editor
|
||||
preview of a page that does not exist yet). The ``cards`` directive gets .wide so it
|
||||
stands alone as a full-width block outside the column segments (the
|
||||
card markup never flows in columns). Runs on the render instance only —
|
||||
the verbatim parser keeps the plain paragraph so segments/chunks see
|
||||
the placeholder source.
|
||||
"""
|
||||
tokens = state.tokens
|
||||
out = []
|
||||
i = 0
|
||||
while i < len(tokens):
|
||||
if (
|
||||
i + 2 < len(tokens)
|
||||
and tokens[i].type == "paragraph_open"
|
||||
and tokens[i + 1].type == "inline"
|
||||
and tokens[i + 2].type == "paragraph_close"
|
||||
):
|
||||
inline = tokens[i + 1]
|
||||
children = inline.children or []
|
||||
if len(children) == 1 and children[0].type == "text":
|
||||
m = _DIRECTIVE_RE.fullmatch(children[0].content.strip())
|
||||
if m:
|
||||
token = Token("directive", "", 0)
|
||||
token.level = tokens[i].level
|
||||
token.map = tokens[i].map
|
||||
token.content = m.group(0)
|
||||
token.meta = {
|
||||
"name": m.group(1),
|
||||
"args": (m.group(2) or "").strip(),
|
||||
}
|
||||
if m.group(1) == "cards":
|
||||
token.attrSet("class", "wide")
|
||||
out.append(token)
|
||||
i += 3
|
||||
continue
|
||||
out.append(tokens[i])
|
||||
i += 1
|
||||
state.tokens = out
|
||||
|
||||
|
||||
def _directive_rule(self: RendererHTML, tokens, idx: int, options, env: dict) -> str:
|
||||
"""Render a directive token via env["directives"][name](args, env);
|
||||
unresolved tags render as the literal source paragraph."""
|
||||
token = tokens[idx]
|
||||
resolver = (env.get("directives") or {}).get(token.meta["name"])
|
||||
html = resolver(token.meta["args"], env) if resolver else None
|
||||
if html is None:
|
||||
return f"<p>{escapeHtml(token.content)}</p>\n"
|
||||
return html + "\n"
|
||||
|
||||
|
||||
def make_md(*, verbatim: bool = False) -> MarkdownIt:
|
||||
"""A fully configured parser. The module-level ``md`` (below) is the
|
||||
render instance; ``verbatim=True`` builds the segmentation instance for
|
||||
segments.py, where token text must stay byte-identical to the source so
|
||||
prose spans can be spliced back by offset: no typographer (quotes and
|
||||
dashes stay straight), no tasklist label wrapping (the item text stays
|
||||
a plain text token), and soft line breaks (wrapped prose merges into
|
||||
one segment instead of splitting at hardbreaks)."""
|
||||
parser = (
|
||||
MarkdownIt(
|
||||
"default",
|
||||
{
|
||||
"html": True,
|
||||
"highlight": _highlight,
|
||||
"typographer": True,
|
||||
"breaks": True,
|
||||
"typographer": not verbatim,
|
||||
"breaks": not verbatim,
|
||||
},
|
||||
)
|
||||
.use(attrs_plugin)
|
||||
.use(admon_plugin)
|
||||
.use(container_plugin, "block", validate=_container_validate)
|
||||
.use(footnote_plugin)
|
||||
.use(deflist_plugin)
|
||||
.use(tasklists_plugin, enabled=True)
|
||||
# label wrapping (render) puts the item text inside the checkbox
|
||||
# <label> html_inline; without it the text stays a plain token.
|
||||
.use(
|
||||
tasklists_plugin, enabled=True, label=not verbatim, label_after=not verbatim
|
||||
)
|
||||
.use(gfm_autolink_plugin)
|
||||
.use(sub_plugin)
|
||||
.use(superscript_plugin)
|
||||
)
|
||||
md.add_render_rule("image", _image_rule)
|
||||
md.core.ruler.push("unwrap_lone_figures", _unwrap_lone_figures)
|
||||
md.core.ruler.push("tag_task_checkboxes", _tag_task_checkboxes)
|
||||
md.core.ruler.push("shorten_autolinks", _shorten_autolinks)
|
||||
)
|
||||
parser.add_render_rule("image", _image_rule)
|
||||
parser.add_render_rule("fence", _fence_rule)
|
||||
parser.add_render_rule("directive", _directive_rule)
|
||||
# GFM alerts (`> [!NOTE]` etc.), built into markdown-it-py's blockquote rule.
|
||||
parser.options["alerts"] = True
|
||||
# Block attrs must be stripped before the typographer curlifies their quotes.
|
||||
parser.core.ruler.before("replacements", "block_attrs", _block_attrs)
|
||||
parser.core.ruler.push("container_attrs", _container_attrs)
|
||||
parser.core.ruler.push("unwrap_lone_figures", _unwrap_lone_figures)
|
||||
parser.core.ruler.push("tag_task_checkboxes", _tag_task_checkboxes)
|
||||
parser.core.ruler.push("shorten_autolinks", _shorten_autolinks)
|
||||
parser.core.ruler.push("heading_ids", _heading_ids)
|
||||
if not verbatim:
|
||||
parser.core.ruler.push("directives", _directives)
|
||||
return parser
|
||||
|
||||
|
||||
md = make_md()
|
||||
|
||||
|
||||
# Text-length thresholds (visible characters, code blocks excluded) for the
|
||||
# column layout: the article goes .multicol past MULTICOL_TEXT, and a column
|
||||
# segment gets .cols past COLS_TEXT — provided it also has at least
|
||||
# COLS_PARAS paragraphs or a paragraph long enough to turn .breakable: a
|
||||
# lone unbreakable paragraph would fill a column on its own and strand the
|
||||
# rest (e.g. a floated figure) in the other, leaving a mostly empty column.
|
||||
MULTICOL_TEXT = 1800
|
||||
COLS_TEXT = 600
|
||||
COLS_PARAS = 2
|
||||
|
||||
#: Paragraphs past this visible length are marked .breakable, letting them
|
||||
#: split across columns (shorter ones stay unbreakable so a paragraph never
|
||||
#: straddles the column gap).
|
||||
BREAKABLE_TEXT = 800
|
||||
|
||||
_PRE_BLOCK_RE = re.compile(r"<pre\b.*?</pre>", re.DOTALL)
|
||||
_TAG_RE = re.compile(r"<[^>]+>")
|
||||
_PARA_OPEN_RE = re.compile(r"<p[\s>]")
|
||||
_PARA_RE = re.compile(r"<p((?:\s[^>]*)?)>(.*?)</p>", re.DOTALL)
|
||||
|
||||
# Classes that take their block out of the column flow: .wide is a
|
||||
# full-width separator that splits the column segments. Margin-breakout
|
||||
# boxes (.margin/.aside) are NOT boundaries: they stay inside the segment
|
||||
# at their anchor point, and CSS positions them absolutely out of the
|
||||
# article's left border (the zone rules anchor off the article), so the
|
||||
# column flow is unaffected.
|
||||
_WIDE = "wide"
|
||||
|
||||
|
||||
class Rendered(NamedTuple):
|
||||
"""render() result: the segmented body HTML, and whether the article
|
||||
should carry .multicol (enough visible text to justify columns)."""
|
||||
|
||||
html: str
|
||||
multicol: bool
|
||||
|
||||
|
||||
def _classes(token) -> set[str]:
|
||||
return set((token.attrGet("class") or "").split())
|
||||
|
||||
|
||||
def _text_len(html: str) -> int:
|
||||
"""Visible-text length of rendered HTML, code blocks excluded."""
|
||||
return len(_TAG_RE.sub("", _PRE_BLOCK_RE.sub("", html)).strip())
|
||||
|
||||
|
||||
def _breakable_paras(html: str) -> str:
|
||||
"""Mark column-filling paragraphs .breakable so they may split.
|
||||
|
||||
Columns keep paragraphs whole (break-inside: avoid-column), but a
|
||||
paragraph long enough to fill a column would strand everything after
|
||||
it in a column of its own — these get .breakable, and pagerite.css
|
||||
lets them split across the column gap. Only applied to .cols segments.
|
||||
"""
|
||||
|
||||
def repl(m: re.Match[str]) -> str:
|
||||
attrs, body = m.group(1), m.group(2)
|
||||
if _text_len(body) <= BREAKABLE_TEXT:
|
||||
return m.group(0)
|
||||
if 'class="' in attrs:
|
||||
attrs = attrs.replace('class="', 'class="breakable ', 1)
|
||||
else:
|
||||
attrs = f'{attrs} class="breakable"'
|
||||
return f"<p{attrs}>{body}</p>"
|
||||
|
||||
return _PARA_RE.sub(repl, html)
|
||||
|
||||
|
||||
def _top_level_blocks(tokens: list) -> list[list]:
|
||||
"""Split the token stream into its top-level blocks.
|
||||
|
||||
A new block starts at each level-0 opening/self-contained token;
|
||||
closing and nested tokens (inline children, sub-containers) belong to
|
||||
the current block, so every slice is balanced and renders on its own.
|
||||
"""
|
||||
blocks = []
|
||||
for token in tokens:
|
||||
if token.level == 0 and token.nesting >= 0:
|
||||
blocks.append([token])
|
||||
elif blocks:
|
||||
blocks[-1].append(token)
|
||||
return blocks
|
||||
|
||||
|
||||
def _is_boundary(block: list) -> bool:
|
||||
"""True for blocks that never go inside a column segment (see the
|
||||
_WIDE comment above): h1/h2 headings and anything carrying .wide."""
|
||||
first = block[0]
|
||||
if first.type == "heading_open" and first.tag in ("h1", "h2"):
|
||||
return True
|
||||
for token in block:
|
||||
if _WIDE in _classes(token):
|
||||
return True
|
||||
if token.type == "inline":
|
||||
children = token.children or []
|
||||
if any(_WIDE in _classes(c) for c in children):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def render(
|
||||
@@ -179,26 +731,97 @@ def render(
|
||||
page_path: str = "",
|
||||
created: datetime | None = None,
|
||||
modified: datetime | None = None,
|
||||
) -> str:
|
||||
"""Render Markdown text to an HTML string.
|
||||
title: str | None = None,
|
||||
anchors_from: tuple[str, str] | None = None,
|
||||
directives: dict[str, Callable[[str, dict], str | None]] | None = None,
|
||||
) -> Rendered:
|
||||
"""Render Markdown text to the article body's HTML and layout flags.
|
||||
|
||||
``title`` injects a ``# {title}`` line at the top when the markdown has
|
||||
no h1 of its own, so the implicit page title goes through the exact
|
||||
same pipeline as an explicit one (first-h1 anchor treatment included).
|
||||
``anchors_from`` is the (markdown, title) of the ORIGINAL language when
|
||||
rendering a translation: section anchors are pinned to its slugs so
|
||||
localized pages keep the original #hash URLs.
|
||||
|
||||
The top-level blocks are grouped into column segments: boundary blocks
|
||||
(h1/h2 headings, .wide — see _is_boundary) are rendered bare, the runs
|
||||
between them wrapped in <div class="colseg">.
|
||||
A segment is tagged .cols when it holds enough text (COLS_TEXT) in at
|
||||
least two paragraphs (COLS_PARAS) or one breakable-length paragraph,
|
||||
and no ::: nocols container; its long paragraphs are marked .breakable;
|
||||
the article is .multicol when the whole body exceeds MULTICOL_TEXT.
|
||||
pagerite.css keys all column and margin-breakout layout off these
|
||||
classes.
|
||||
|
||||
A ``{dates}`` line expands to the article's published/updated dateline
|
||||
(needs ``created``/``modified``; left as-is in contexts without them,
|
||||
e.g. the editor preview). Position is the author's choice — typically
|
||||
(needs ``created``/``modified``). Block directives in general — a lone
|
||||
``{name}`` or ``{name: args}`` line — are expanded by the resolvers
|
||||
passed as ``directives`` (name → (args, env) → HTML or None), with
|
||||
``dates`` built in when ``created`` is given; unresolved tags render as
|
||||
the literal source (e.g. in the editor preview of a not-yet-created
|
||||
page).
|
||||
Position is the author's choice — the dateline typically goes
|
||||
right after the article's h1.
|
||||
"""
|
||||
html = md.render(text, {"page_path": page_path})
|
||||
if created is not None and "<p>{dates}</p>" in html:
|
||||
html = html.replace("<p>{dates}</p>", _dateline(created, modified))
|
||||
return html
|
||||
directives = dict(directives or {})
|
||||
if created is not None:
|
||||
directives.setdefault("dates", lambda _args, _env: _dateline(created, modified))
|
||||
env = {"page_path": page_path, "line_offset": 0, "directives": directives}
|
||||
if anchors_from is not None:
|
||||
env["anchor_ids"] = anchor_ids(*anchors_from)
|
||||
if title and not has_h1(text):
|
||||
text = f"# {title}\n\n{text}"
|
||||
# The injected title shifts source lines by two; _heading_ids
|
||||
# subtracts this from its data-line attributes.
|
||||
env["line_offset"] = 2
|
||||
blocks = _top_level_blocks(md.parse(text, env))
|
||||
# Group consecutive non-boundary blocks into segments (is_segment,
|
||||
# flat tokens); boundary blocks stand on their own between them.
|
||||
groups: list[tuple[bool, list]] = []
|
||||
for block in blocks:
|
||||
if _is_boundary(block):
|
||||
groups.append((False, block))
|
||||
elif groups and groups[-1][0]:
|
||||
groups[-1][1].extend(block)
|
||||
else:
|
||||
groups.append((True, list(block)))
|
||||
|
||||
parts = []
|
||||
total = 0
|
||||
for is_segment, group in groups:
|
||||
html = md.renderer.render(group, md.options, env)
|
||||
if not html.strip():
|
||||
continue # e.g. a consumed standalone-attrs paragraph
|
||||
text_len = _text_len(html)
|
||||
total += text_len
|
||||
if not is_segment:
|
||||
parts.append(html)
|
||||
continue
|
||||
nocols = any(
|
||||
"nocols" in _classes(t) for t in group if t.type == "container_block_open"
|
||||
)
|
||||
marked = _breakable_paras(html)
|
||||
cols = (
|
||||
" cols"
|
||||
if text_len > COLS_TEXT
|
||||
and not nocols
|
||||
and (len(_PARA_OPEN_RE.findall(html)) >= COLS_PARAS or marked != html)
|
||||
else ""
|
||||
)
|
||||
if cols:
|
||||
html = marked
|
||||
parts.append(f'<div class="colseg{cols}">{html}</div>')
|
||||
html = "".join(parts)
|
||||
return Rendered(html, total > MULTICOL_TEXT)
|
||||
|
||||
|
||||
def _dateline(created: datetime, modified: datetime | None) -> str:
|
||||
"""Dateline for the ``{dates}`` tag: "1 Jan 2026", plus
|
||||
" – edited 3 Jan 2026" when the last edit came >= 24h after
|
||||
" – edited 3 Jan 2026" when the last edit came >= 48h after
|
||||
publishing (quick fixes right after posting stay unmentioned)."""
|
||||
out = f'<time datetime="{created.isoformat()}">{created.day} {created:%b %Y}</time>'
|
||||
if modified is not None and modified - created >= timedelta(hours=24):
|
||||
if modified is not None and modified - created >= timedelta(hours=48):
|
||||
out += f' – edited <time datetime="{modified.isoformat()}">{modified.day} {modified:%b %Y}</time>'
|
||||
return f'<p class="dateline">{out}</p>'
|
||||
|
||||
@@ -206,9 +829,9 @@ def _dateline(created: datetime, modified: datetime | None) -> str:
|
||||
def has_h1(text: str) -> bool:
|
||||
"""True if the Markdown source itself contains an h1 heading.
|
||||
|
||||
When it does, the article owns its heading and the page title is not
|
||||
rendered as an additional h1 (the title is still used for the document
|
||||
<title> and navigation labels).
|
||||
When it does, the article owns its heading and render(title=...) does
|
||||
not inject the page title as an h1 (the title is still used for the
|
||||
document <title> and navigation labels).
|
||||
"""
|
||||
return any(t.type == "heading_open" and t.tag == "h1" for t in md.parse(text))
|
||||
|
||||
|
||||
@@ -0,0 +1,172 @@
|
||||
"""Kanta schema migrations, discovered by name (``migrate_vN``).
|
||||
|
||||
Each function receives the raw state dict (JSON-level: bytes are base64
|
||||
strings, datetimes RFC 3339 strings, struct fields with default values
|
||||
omitted) before it is decoded into ``Data`` structs, and runs exactly once
|
||||
per database based on its recorded version.
|
||||
|
||||
All storage/schema upgrades live here — including on-disk file work, which
|
||||
runs through files.py's file store (imported lazily: files.py owns the store
|
||||
and state.py passes this module to Kanta; at migration time, during lifespan
|
||||
``kanta.open()``, both modules are fully loaded).
|
||||
"""
|
||||
|
||||
import base64
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
from pagerite.chunks import chunk_key, chunk_markdown
|
||||
from pagerite.data import prettify
|
||||
|
||||
|
||||
def _append_order(nodes: dict) -> float:
|
||||
"""Raw-dict equivalent of data.append_order (order keys may be absent)."""
|
||||
return max((n.get("order", 0) for n in nodes.values()), default=0) + 1
|
||||
|
||||
|
||||
def _ensure(menu: dict, path: str) -> dict:
|
||||
"""Raw-dict equivalent of state._ensure: the node dict at ``path``,
|
||||
creating it and any missing ancestors (content-less category labels)
|
||||
appended at the end of their level."""
|
||||
nodes = menu
|
||||
node = None
|
||||
for seg in path.split("/"):
|
||||
node = nodes.get(seg)
|
||||
if node is None:
|
||||
node = {"title": prettify(seg), "order": _append_order(nodes)}
|
||||
nodes[seg] = node
|
||||
nodes = node.setdefault("children", {})
|
||||
return node
|
||||
|
||||
|
||||
def migrate_v1(d: dict) -> None:
|
||||
"""Move in-database file blobs to the on-disk content-addressed store,
|
||||
and rebuild the legacy flat page store (``pages``) as the menu tree."""
|
||||
files = d.pop("files", None)
|
||||
if files:
|
||||
from pagerite.files import file_store
|
||||
|
||||
for name, body in files.items():
|
||||
if isinstance(body, str): # JSON-level bytes are base64 strings
|
||||
body = base64.b64decode(body)
|
||||
file_store.put(name, body)
|
||||
pages = d.pop("pages", None)
|
||||
if not pages:
|
||||
return
|
||||
menu = d.setdefault("menu", {})
|
||||
for path, page in pages.items():
|
||||
node = _ensure(menu, path)
|
||||
node["title"] = page["title"]
|
||||
node["content"] = page["markdown"]
|
||||
for key in ("banner", "published", "order", "created", "modified"):
|
||||
if key in page:
|
||||
node[key] = page[key]
|
||||
|
||||
|
||||
#: Extension-less file links: uploaded images are linked as /_f/<hash>
|
||||
#: and the server negotiates avif/webp/jpg from the Accept header.
|
||||
_DERIVATIVE_LINK = re.compile(r"(/_f/[0-9a-f]{12})\.(?:avif|webp)\b")
|
||||
|
||||
|
||||
def _backfill_derivatives() -> None:
|
||||
"""Create missing AVIF/WebP/JPEG derivatives for files stored before
|
||||
they were introduced (older uploads may have only the original plus
|
||||
AVIF, and SVGs no raster variants at all). WebP/JPEG are re-encoded
|
||||
from an existing AVIF when available, everything else from the
|
||||
original (SVGs rasterized first)."""
|
||||
from pagerite.files import (
|
||||
IMAGE_JPG_QUALITY,
|
||||
IMAGE_MAXSIZE,
|
||||
IMAGE_WEBP_QUALITY,
|
||||
_avif_to_format,
|
||||
_svg_to_png,
|
||||
_to_avif,
|
||||
file_store,
|
||||
)
|
||||
|
||||
try:
|
||||
paths = [f for f in file_store.path.iterdir() if f.is_file()]
|
||||
except FileNotFoundError:
|
||||
return
|
||||
groups: dict[str, list[Path]] = {}
|
||||
for p in paths:
|
||||
groups.setdefault(p.name.partition(".")[0], []).append(p)
|
||||
for digest, files in groups.items():
|
||||
names = {p.name for p in files}
|
||||
source = next(
|
||||
(p for p in files if ".orig." in p.name or p.suffix == ".svg"), None
|
||||
)
|
||||
if source is None:
|
||||
continue # plain as-is file, no derivatives to make
|
||||
avif = file_store.get(f"{digest}.avif")
|
||||
if avif is None:
|
||||
ext = source.suffix
|
||||
body = source.read_bytes()
|
||||
if ext == ".svg":
|
||||
png = _svg_to_png(body, IMAGE_MAXSIZE)
|
||||
if png is None:
|
||||
continue
|
||||
body, ext = png, ".png"
|
||||
converted = _to_avif(body, ext)
|
||||
if converted is None:
|
||||
continue
|
||||
file_store.put(f"{digest}.avif", converted)
|
||||
avif = file_store.get(f"{digest}.avif")
|
||||
for fmt, quality in (
|
||||
("webp", IMAGE_WEBP_QUALITY),
|
||||
("jpg", IMAGE_JPG_QUALITY),
|
||||
):
|
||||
if f"{digest}.{fmt}" not in names:
|
||||
file_store.put(
|
||||
f"{digest}.{fmt}", _avif_to_format(avif[0], f".{fmt}", quality)
|
||||
)
|
||||
|
||||
|
||||
def migrate_v2(d: dict) -> None:
|
||||
"""Extension-less image links: strip .avif/.webp extensions from /_f/
|
||||
links in page content and banners (the server now negotiates the format
|
||||
by Accept header), backfill missing AVIF/WebP/JPEG derivatives on disk,
|
||||
and drop the obsolete render-counter field ``version`` (invalidation is
|
||||
an in-memory concern now, not database state)."""
|
||||
|
||||
def walk(nodes: dict) -> None:
|
||||
for node in nodes.values():
|
||||
for field in ("content", "banner"):
|
||||
if isinstance(node.get(field), str):
|
||||
node[field] = _DERIVATIVE_LINK.sub(r"\1", node[field])
|
||||
walk(node.get("children") or {})
|
||||
|
||||
walk(d.get("menu") or {})
|
||||
d.pop("version", None)
|
||||
_backfill_derivatives()
|
||||
|
||||
|
||||
def migrate_v3(d: dict) -> None:
|
||||
"""Content-addressed chunk storage (docs/migrate.md): split every
|
||||
node's string ``content`` into block chunks stored once per content
|
||||
hash in the new ``chunks`` store; the node keeps the ordered hash
|
||||
list as ``chunks`` (an absent content stays absent, i.e. None = a
|
||||
pure category label; "" chunks to an empty list = an empty page).
|
||||
|
||||
Chunk keys are 9-byte blake3 digests; at this raw JSON level they are
|
||||
base64 strings (decoding into the structs restores ``bytes`` keys).
|
||||
``trans`` starts empty; the translator job fills it and maintains the
|
||||
``langs`` index as translations land. ``language``, ``no_trans`` and
|
||||
``langs`` need nothing — struct defaults cover them.
|
||||
"""
|
||||
store = d.setdefault("chunks", {})
|
||||
d.setdefault("trans", {})
|
||||
|
||||
def walk(nodes: dict) -> None:
|
||||
for node in nodes.values():
|
||||
content = node.pop("content", None)
|
||||
if isinstance(content, str):
|
||||
hashes = []
|
||||
for chunk in chunk_markdown(content):
|
||||
key = base64.b64encode(chunk_key(chunk)).decode()
|
||||
store.setdefault(key, chunk)
|
||||
hashes.append(key)
|
||||
node["chunks"] = hashes
|
||||
walk(node.get("children") or {})
|
||||
|
||||
walk(d.get("menu") or {})
|
||||
@@ -0,0 +1,254 @@
|
||||
"""Public content pages: front page, sitemap, robots, and the catch-all.
|
||||
|
||||
``GET /{path:path}`` resolves a slug path against the menu tree and renders
|
||||
the page (or a category placeholder, or 404); it must be registered AFTER
|
||||
the fastapi-vue asset routes so built frontend files win over content slugs
|
||||
(see app.py). Every served document is recorded raw in analytics (one
|
||||
access-log line with its true HTTP status; classification happens at
|
||||
display time — see pagerite/analytics.py), as are robots.txt and sitemap.xml
|
||||
fetches (they surface as crawler hits, since no activity message ever
|
||||
follows them).
|
||||
"""
|
||||
|
||||
import logging
|
||||
from datetime import UTC, datetime
|
||||
from email.utils import format_datetime
|
||||
from xml.sax.saxutils import escape as xml_escape
|
||||
|
||||
from fastapi import APIRouter, HTTPException, Request
|
||||
from fastapi.responses import RedirectResponse, Response
|
||||
|
||||
from pagerite import i18n, state
|
||||
from pagerite.data import Node, resolve, sorted_nodes
|
||||
from pagerite.state import (
|
||||
SITE_URL,
|
||||
_html_response,
|
||||
_is_reserved,
|
||||
data,
|
||||
)
|
||||
from pagerite.tracking import _record_get
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
def _http_date(dt: datetime) -> str:
|
||||
"""RFC 7231 date for the Last-Modified header."""
|
||||
return format_datetime(dt.astimezone(UTC), usegmt=True)
|
||||
|
||||
|
||||
def _is_trackable_path(path: str) -> bool:
|
||||
"""Content URLs only: skip auth endpoints and reserved/machinery paths."""
|
||||
if not path:
|
||||
return True
|
||||
if path == "auth" or path.startswith("auth/"):
|
||||
return False
|
||||
return not _is_reserved(path)
|
||||
|
||||
|
||||
@router.get("/")
|
||||
async def front_page(request: Request) -> Response:
|
||||
"""Render the front page (slug path "")."""
|
||||
return await show_page(request, "")
|
||||
|
||||
|
||||
@router.get("/sitemap.xml")
|
||||
async def sitemap(request: Request) -> Response:
|
||||
"""Dynamically generate a sitemap of all published article pages, plus
|
||||
the machine-readable exports (feeds, llms.txt)."""
|
||||
base = SITE_URL or str(request.base_url).rstrip("/")
|
||||
entries: list[tuple[str, datetime, int]] = []
|
||||
|
||||
def walk(
|
||||
nodes: dict[str, Node], prefix: str, parent_has_content: bool = True
|
||||
) -> None:
|
||||
first_content_slug = next(
|
||||
(
|
||||
slug
|
||||
for slug, node in sorted_nodes(nodes)
|
||||
if node.published and node.chunks is not None
|
||||
),
|
||||
None,
|
||||
)
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
depth = path.count("/") if path else 0
|
||||
if (
|
||||
not parent_has_content
|
||||
and slug == first_content_slug
|
||||
and node.published
|
||||
and node.chunks is not None
|
||||
and depth > 0
|
||||
):
|
||||
depth -= 1
|
||||
if node.published and node.chunks is not None:
|
||||
entries.append((path, node.modified, depth))
|
||||
if node.children:
|
||||
walk(node.children, path, node.chunks is not None)
|
||||
|
||||
walk(data.menu, "")
|
||||
|
||||
def priority(depth: int) -> float:
|
||||
return max(0.1, 1.0 - depth * 0.2)
|
||||
|
||||
lines = [
|
||||
'<?xml version="1.0" encoding="UTF-8"?>',
|
||||
'<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">',
|
||||
]
|
||||
for path, modified, depth in entries:
|
||||
loc = xml_escape(f"{base}/{path}" if path else base)
|
||||
lastmod = (
|
||||
modified.astimezone(UTC)
|
||||
.replace(microsecond=0)
|
||||
.isoformat()
|
||||
.replace("+00:00", "Z")
|
||||
)
|
||||
lines.append(
|
||||
f" <url>"
|
||||
f"<loc>{loc}</loc>"
|
||||
f"<lastmod>{lastmod}</lastmod>"
|
||||
f"<priority>{priority(depth):.1f}</priority>"
|
||||
f"</url>"
|
||||
)
|
||||
lines.append("</urlset>")
|
||||
|
||||
# The machine-readable exports (feeds, llms.txt) are linked too, with
|
||||
# the latest article's modification time as their lastmod.
|
||||
if entries:
|
||||
latest = max(m for _, m, _ in entries)
|
||||
lastmod = (
|
||||
latest.astimezone(UTC)
|
||||
.replace(microsecond=0)
|
||||
.isoformat()
|
||||
.replace("+00:00", "Z")
|
||||
)
|
||||
for special in ("llms.txt", "feed.json", "feed.xml"):
|
||||
lines.insert(
|
||||
-1,
|
||||
f" <url><loc>{xml_escape(f'{base}/{special}')}</loc>"
|
||||
f"<lastmod>{lastmod}</lastmod></url>",
|
||||
)
|
||||
|
||||
# Recorded like a page GET: never followed by an activity message, so
|
||||
# it lands in the crawler list at display time (docs/analytics.md).
|
||||
_record_get(request)
|
||||
return Response(
|
||||
"\n".join(lines),
|
||||
media_type="application/xml",
|
||||
headers={"cache-control": "no-cache"},
|
||||
)
|
||||
|
||||
|
||||
@router.get("/robots.txt")
|
||||
async def robots_txt(request: Request) -> Response:
|
||||
"""Allow content crawling, keep the SSO login (/auth/) and the
|
||||
admin-gated API (/_api) out of search results, and point crawlers at
|
||||
the sitemap."""
|
||||
base = SITE_URL or str(request.base_url).rstrip("/")
|
||||
body = f"User-agent: *\nAllow: /\nDisallow: /auth/\nDisallow: /_api\nSitemap: {base}/sitemap.xml\n"
|
||||
_record_get(request)
|
||||
return Response(
|
||||
body,
|
||||
media_type="text/plain",
|
||||
headers={"cache-control": "no-cache"},
|
||||
)
|
||||
|
||||
|
||||
@router.get("/{path:path}", response_model=None)
|
||||
async def show_page(request: Request, path: str) -> Response:
|
||||
"""Render the content page at a slug path, or 404.
|
||||
|
||||
A node without content is a category label: its URL renders a
|
||||
placeholder page (nav links point straight at its first child).
|
||||
"""
|
||||
path = path.strip("/")
|
||||
accept_language = request.headers.get("accept-language", "")
|
||||
if path and _is_reserved(path):
|
||||
# Invalid slug shape: not a content URL, let FastAPI return its
|
||||
# built-in 404 instead of rendering an editable article page.
|
||||
# Recorded like any other GET: telltale scanner paths (dotpaths
|
||||
# like /.env, *.php) classify the IP as abuse at display time.
|
||||
_record_get(request, status=404)
|
||||
raise HTTPException(404)
|
||||
chain = resolve(data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is not None and node.published and node.chunks is not None:
|
||||
# Language selection (docs/localization.md): ?lang= wins when a
|
||||
# translation exists, else header logic. Analytics keep the raw
|
||||
# Accept-Language header regardless of the selection, and record
|
||||
# the resolved language as the GET's rendered language.
|
||||
query_lang = request.query_params.get("lang")
|
||||
lang = i18n.select_language(
|
||||
query_lang,
|
||||
accept_language,
|
||||
lambda tag: tag in node.langs,
|
||||
original=i18n.primary_lang(data.menu, path),
|
||||
)
|
||||
# A ?lang= override is replicated onto the page's navigation links
|
||||
# (link_lang), so clicks and prefetches stay in the chosen language.
|
||||
# Query and header-selected renders of the same language differ in
|
||||
# their links, so link_lang is part of the ETag and body cache key.
|
||||
link_lang = i18n.base_tag(query_lang or "")
|
||||
# no-cache forbids serving a stored page without revalidation
|
||||
# (browsers would otherwise cache heuristically and serve stale
|
||||
# pages, e.g. after a theme change). In-session speed instead comes
|
||||
# from pagerite.js's in-memory page cache (preload everything, never
|
||||
# fetch on navigation); the ETag just makes those one-time preload
|
||||
# fetches and any revalidation cheap.
|
||||
etag = f'"{path}@{node.modified.timestamp()}g{state._render_gen}l{lang}q{link_lang}"'
|
||||
if request.headers.get("if-none-match") == etag:
|
||||
return Response(status_code=304)
|
||||
if _is_trackable_path(path):
|
||||
_record_get(request, lang=lang)
|
||||
return _html_response(
|
||||
request,
|
||||
"page",
|
||||
path,
|
||||
headers={
|
||||
"etag": etag,
|
||||
"last-modified": _http_date(node.modified),
|
||||
"cache-control": "no-cache",
|
||||
},
|
||||
lang=lang,
|
||||
link_lang=link_lang,
|
||||
)
|
||||
if node is not None and node.published and node.chunks is None:
|
||||
# Category label without a landing page: placeholder with the pen
|
||||
# to create it (404 — no page here, but the node is real).
|
||||
# Language selection as on content pages, but over the whole
|
||||
# subtree's availability: the category has no chunks of its own —
|
||||
# its heading, the navigation and the cards' text localize from
|
||||
# the title map and the target articles' translations.
|
||||
query_lang = request.query_params.get("lang")
|
||||
subtree_langs = i18n.subtree_languages(node)
|
||||
lang = i18n.select_language(
|
||||
query_lang,
|
||||
accept_language,
|
||||
lambda tag: tag in subtree_langs,
|
||||
original=i18n.primary_lang(data.menu, path),
|
||||
)
|
||||
link_lang = i18n.base_tag(query_lang or "")
|
||||
if _is_trackable_path(path):
|
||||
_record_get(request, status=404, lang=lang)
|
||||
return _html_response(
|
||||
request,
|
||||
"category",
|
||||
path,
|
||||
404,
|
||||
headers={
|
||||
"last-modified": _http_date(node.modified),
|
||||
"cache-control": "no-cache",
|
||||
},
|
||||
lang=lang,
|
||||
link_lang=link_lang,
|
||||
)
|
||||
if node is None and not path:
|
||||
# No front page (no top-level node with slug ""): "/" opens the
|
||||
# first item of the navigation instead.
|
||||
for slug, item in sorted_nodes(data.menu):
|
||||
if item.published:
|
||||
return RedirectResponse(f"/{slug}")
|
||||
if _is_trackable_path(path):
|
||||
_record_get(request, status=404)
|
||||
return _html_response(request, "not-found", path, 404)
|
||||

|
After Width: | Height: | Size: 410 KiB |

|
After Width: | Height: | Size: 59 KiB |
@@ -1,147 +1,411 @@
|
||||
"""Seed content written to the database on first run (when it is empty).
|
||||
"""Seed content written to the database on first creation only
|
||||
(``@kanta.bootstrap`` in ``app.py``).
|
||||
|
||||
Demonstrates the formatting options: images attached to pages and served
|
||||
from the page path, figures with captions, attribute classes for
|
||||
positioning, footnotes, definition lists, task lists, tables and raw HTML.
|
||||
A "welcome to your new site" starter: a structured docs section (three
|
||||
menu levels deep) covering editing and one long article that walks the
|
||||
full Markdown feature set — each feature shown as its Markdown source in
|
||||
a code block followed by the rendered result — and a showcase section
|
||||
with image positioning, long-form layout and banner designs.
|
||||
|
||||
Binary seed images live in ``seed-assets/`` (public domain, from
|
||||
Wikimedia Commons: the two whale engravings are Augustus Burnham
|
||||
Shute's illustrations for an 1892 edition of Moby-Dick; the wave is
|
||||
Hokusai's "The Great Wave off Kanagawa").
|
||||
"""
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
ASSETS = Path(__file__).with_name("seed-assets")
|
||||
|
||||
|
||||
def _asset(name: str) -> bytes:
|
||||
return (ASSETS / name).read_bytes()
|
||||
|
||||
|
||||
WELCOME = """\
|
||||
Welcome to your new **Pagerite** site. Pages are written in Markdown — including raw HTML — and served from pretty URLs.
|
||||
Welcome to your new **Pagerite** site. Everything you see is a page written in Markdown, served from a pretty URL, and editable right here in the browser.
|
||||
|
||||
Have a look around:
|
||||
Where to go next:
|
||||
|
||||
- The [docs](/docs) section explains [how to write content](/docs/editing), including images and positioning.
|
||||
- [The Long Read](/blog/the-long-read) demonstrates a longer article with scroll effects.
|
||||
- The [about](/about) page shows off assorted formatting.
|
||||
- The [docs](/docs/editing) section explains how to edit this site and walks through every supported Markdown feature, source and result side by side.
|
||||
- The [showcase](/showcase/gallery) section shows what finished pages can look like: image positioning, banners, a long read.
|
||||
- Click the 🖊️ pen on any page to open the editor, and the ⚙️ pen for site settings and the structure tree.
|
||||
|
||||

|
||||
{width=420}
|
||||
|
||||
*Delete or rewrite any of these pages — they are only here to get you started.*
|
||||
"""
|
||||
|
||||
ABOUT = """\
|
||||
This site runs on **Pagerite**: FastAPI + html5tagger + kanta, with content written in Markdown.
|
||||
EDITING = """\
|
||||
Everything on the site is editable in place. Log in, and pens appear: 🖊️ on the page and banner, ⚙️ in the banner corner for site settings.
|
||||
|
||||
Some formatting samples:
|
||||
## The editor
|
||||
|
||||
- [x] Write content in Markdown
|
||||
- [x] Attach images to pages
|
||||
- [ ] Add editing UI
|
||||
The 🖊️ pens open a tabbed editor over the page you are viewing:
|
||||
|
||||
Term
|
||||
: A definition list entry, rendered by the deflist plugin.
|
||||
- **Article** — the page's title and Markdown, with a live preview. The format bar inserts the harder-to-remember syntax (links, tables, images); Ctrl/Cmd-B, I and S do what you expect. Saving is explicit: 💾 or Ctrl+S.
|
||||
- **Banner** — per-page banner HTML and a banner design picker. Banners are raw HTML (an image, a styled div, a canvas with a script) and subpages inherit the nearest banner up their path.
|
||||
- **Site** — brand, theme, fonts, favicon and custom CSS, all applied immediately.
|
||||
- **Structure** — the page tree. Drag rows to reorder or nest, rename titles and slugs inline, ➕ adds a page, ✕ deletes one.
|
||||
|
||||
And a table:
|
||||
## URLs and structure
|
||||
|
||||
The URL is the structure: a page at `docs/markdown` lives under `docs`, and the menus are derived from that. Slugs are lowercase ASCII (`a-z 0-9 - _`). A node without content is a category label — it renders a placeholder and its menu link points at its first child page. This site's own `docs` label demonstrates that, and the sidebar on this page shows the two submenu levels below it.
|
||||
|
||||
Images and files uploaded anywhere land in a content-addressed store served from `/_f/{hash}`, so links survive page moves. The server picks AVIF, WebP or JPEG from your browser's Accept header. The article editor's format bar and copy-paste both upload images for you.
|
||||
|
||||
{dates}
|
||||
"""
|
||||
|
||||
# The full feature walkthrough: every supported extension in one long
|
||||
# article, each shown as Markdown source followed by the rendered result.
|
||||
MD_ARTICLE = """\
|
||||
# Markdown
|
||||
|
||||
Everything Pagerite's renderer supports, on one long page — each feature shown first as Markdown source, then rendered. This page is also the live demo of the reading layout: on a wide screen the text flows in columns, and side boxes lean into the margin.
|
||||
|
||||
## Text and headings
|
||||
|
||||
```markdown
|
||||
*Emphasis*, **strong**, ~~strikethrough~~, `inline code`, and a
|
||||
[link to the front page](/). A hard line break
|
||||
is just a newline.
|
||||
|
||||
Straight quotes become "curly", dashes -- and --- come out
|
||||
properly, and ... becomes an ellipsis, all automatically.
|
||||
```
|
||||
|
||||
*Emphasis*, **strong**, ~~strikethrough~~, `inline code`, and a [link to the front page](/). A hard line break
|
||||
is just a newline.
|
||||
|
||||
Straight quotes become "curly", dashes -- and --- come out properly, and ... becomes an ellipsis, all automatically.
|
||||
|
||||
Headings from `##` down organize the article. On pages with at least three of them, each h1/h2 gets an anchor id and a self-link, so sections are linkable (try hovering a heading here) — and the editor's section pens and scroll sync key off the same anchors.
|
||||
|
||||
## Lists
|
||||
|
||||
```markdown
|
||||
- One
|
||||
- Two
|
||||
- Nested
|
||||
|
||||
1. First
|
||||
2. Second
|
||||
|
||||
- [x] Task lists with real checkboxes
|
||||
- [x] Clickable on the rendered page
|
||||
- [ ] Like this one
|
||||
```
|
||||
|
||||
- One
|
||||
- Two
|
||||
- Nested
|
||||
|
||||
1. First
|
||||
2. Second
|
||||
|
||||
- [x] Task lists with real checkboxes
|
||||
- [x] Clickable on the rendered page
|
||||
- [ ] Like this one
|
||||
|
||||
## Quotes and alerts
|
||||
|
||||
```markdown
|
||||
> A blockquote. Newlines inside it are kept,
|
||||
> and a blank `>` line starts a new paragraph.
|
||||
|
||||
> [!NOTE]
|
||||
> GitHub-style alerts — `NOTE`, `TIP`, `IMPORTANT`, `WARNING`, `CAUTION` —
|
||||
> render as callout boxes.
|
||||
```
|
||||
|
||||
> A blockquote. Newlines inside it are kept,
|
||||
> and a blank `>` line starts a new paragraph.
|
||||
|
||||
> [!NOTE]
|
||||
> GitHub-style alerts — `NOTE`, `TIP`, `IMPORTANT`, `WARNING`, `CAUTION` —
|
||||
> render as callout boxes.
|
||||
|
||||
## Code
|
||||
|
||||
Fenced blocks get server-side syntax highlighting, and a copy button on hover:
|
||||
|
||||
````markdown
|
||||
```python
|
||||
def greet(name: str) -> str:
|
||||
return f"Hello, {name}!"
|
||||
```
|
||||
````
|
||||
|
||||
```python
|
||||
def greet(name: str) -> str:
|
||||
return f"Hello, {name}!"
|
||||
```
|
||||
|
||||
## Tables
|
||||
|
||||
```markdown
|
||||
| Feature | Status |
|
||||
|---------|--------|
|
||||
| Pages | done |
|
||||
| Images | done |
|
||||
```
|
||||
|
||||
| Feature | Status |
|
||||
|---------|--------|
|
||||
| Pages | done |
|
||||
| Images | done |
|
||||
| Comments| later |
|
||||
|
||||
Footnotes work too.[^1]
|
||||
## Footnotes
|
||||
|
||||
```markdown
|
||||
Footnotes work inline.[^1]
|
||||
|
||||
[^1]: Rendered at the bottom of the page, with a back-reference.
|
||||
"""
|
||||
|
||||
EDITING = """\
|
||||
Pages are written in Markdown with extensions. Everything below is plain Markdown source — no special support from the article is needed for the site's layout or scroll effects.
|
||||
|
||||
## Images
|
||||
|
||||
Upload a file (`PUT /_api/files/{filename}`) and it lands in the content-addressed store, served immutable from `/_f/{hash}.ext` — an absolute URL that survives page moves:
|
||||
|
||||
```
|
||||
{.right width=280}
|
||||
```
|
||||
|
||||
{.right width=280}
|
||||
Footnotes work inline.[^1]
|
||||
|
||||
The title becomes a `<figcaption>`, and brace attributes (the attrs plugin) control positioning: `{.right}`, `{.left}`, `{.wide}`, plus plain attributes like `width=280`. Absolute and external URLs pass through unchanged.
|
||||
[^1]: Rendered at the bottom of the page, with a back-reference.
|
||||
|
||||
## Text
|
||||
## Definition lists
|
||||
|
||||
*Emphasis*, **strong**, ~~strikethrough~~, `inline code`, and [links](/about) as usual. Blockquotes:
|
||||
```markdown
|
||||
Term
|
||||
: A definition list entry.
|
||||
|
||||
> The URL space is the author's. Pretty slugs at the root, nesting only
|
||||
> where the content is genuinely structured.
|
||||
|
||||
## Code
|
||||
|
||||
```python
|
||||
def render(text: str, page_path: str) -> str:
|
||||
return md.render(text, {"page_path": page_path})
|
||||
Another term
|
||||
: With its definition.
|
||||
```
|
||||
"""
|
||||
|
||||
LONG_READ = """\
|
||||
*An essay long enough to scroll, to demonstrate the gentle reveal of headings, figures and code blocks as they enter the viewport.*
|
||||
Term
|
||||
: A definition list entry.
|
||||
|
||||
Another term
|
||||
: With its definition.
|
||||
|
||||
## Sub- and superscript
|
||||
|
||||
```markdown
|
||||
H~2~O and x^2^ + y^2^ = z^2^.
|
||||
```
|
||||
|
||||
H~2~O and x^2^ + y^2^ = z^2^.
|
||||
|
||||
## Admonitions
|
||||
|
||||
```markdown
|
||||
!!! note
|
||||
An admonition block for notes, warnings, tips...
|
||||
|
||||
!!! warning "Mind the whale"
|
||||
With an optional custom title.
|
||||
```
|
||||
|
||||
!!! note
|
||||
An admonition block for notes, warnings, tips...
|
||||
|
||||
!!! warning "Mind the whale"
|
||||
With an optional custom title.
|
||||
|
||||
## Containers and margin notes
|
||||
|
||||
`::: name` wraps its contents in a `<div class="name">` — brace attributes allowed. Three names are built in: `aside` floats a muted side box, `margin` marks a block as a margin note, and `nocols` opts its section out of the column layout. The `{.margin}` attribute does the same for a single block, written on its last line:
|
||||
|
||||
````markdown
|
||||
::: aside
|
||||
A side box. On all but phone widths it floats in the side zone at
|
||||
the article's left, and the text never moves.
|
||||
:::
|
||||
|
||||
This paragraph is a margin note.
|
||||
{.margin}
|
||||
|
||||
::: nocols
|
||||
This section never flows into columns, however long the article.
|
||||
:::
|
||||
````
|
||||
|
||||
::: aside
|
||||
A side box. On all but phone widths it floats in the side zone at the article's left, and the text never moves.
|
||||
:::
|
||||
|
||||
This paragraph is a margin note.
|
||||
{.margin}
|
||||
|
||||
::: nocols
|
||||
This section never flows into columns, however long the article.
|
||||
:::
|
||||
|
||||
## Raw HTML
|
||||
|
||||
HTML passes through untouched — useful for `<kbd>` keys, `<details>` sections, embedded media:
|
||||
|
||||
```html
|
||||
<details><summary>Click to expand</summary>Hidden content.</details>
|
||||
```
|
||||
|
||||
<details><summary>Click to expand</summary>Hidden content.</details>
|
||||
|
||||
## Datelines
|
||||
|
||||
A `{dates}` line on its own expands to the article's published/updated dateline:
|
||||
|
||||
```markdown
|
||||
{dates}
|
||||
```
|
||||
|
||||
{dates}
|
||||
|
||||
{.wide}
|
||||
## Images and layout
|
||||
|
||||
## Chapter one
|
||||
An image standing alone in its paragraph becomes a `<figure>`; its title becomes the caption; brace attributes control placement — `{.right}`, `{.left}`, `{.margin}`, `{.wide}`, or plain ones like `width=280`. That deserves its own page: [Images and Layout](/docs/markdown/images-and-layout).
|
||||
|
||||
The distinction between a blog and a website is largely an accident of history. Early content management systems filed everything under "posts", stamped them with a date, and arranged them in reverse chronological order under a `/blog/` prefix. Anything else was a "page", which lived somewhere else entirely, often in a separate editing interface with separate rules.
|
||||
## The page title
|
||||
|
||||
But readers do not think in these terms. A reader follows a link, reads what is there, and follows another link. The URL is a promise about where something lives, not about which database table it came from. Pagerite therefore treats every piece of content as a page: named, addressable, and rendered on the fly.
|
||||
|
||||
## Chapter two
|
||||
|
||||
Consider what happens to URLs when the tooling leads the design. You get addresses like `/cms/frontpage` or `/blog/post1` — the name of the machine leaking into the name of the thing. The slug should be chosen by the author, the way a book's title is chosen, and it should sit at the root of the site like the title sits on the cover.
|
||||
|
||||
Nesting still has its place. Structured content — documentation, a series, a portfolio — benefits from paths that mirror the structure. The navigation on this very site is derived from the paths: open a section, and you see what it contains. No menu editor, no duplication of structure in two places.
|
||||
|
||||
Lorem ipsum dolor sit amet, consectetur adipiscing elit, sed do eiusmod tempor incididunt ut labore et dolore magna aliqua. Ut enim ad minim veniam, quis nostrud exercitation ullamco laboris nisi ut aliquip ex ea commodo consequat. Duis aute irure dolor in reprehenderit in voluptate velit esse cillum dolore eu fugiat nulla pariatur. Excepteur sint occaecat cupidatat non proident, sunt in culpa qui officia deserunt mollit anim id est laborum.
|
||||
|
||||
Sed ut perspiciatis unde omnis iste natus error sit voluptatem accusantium doloremque laudantium, totam rem aperiam, eaque ipsa quae ab illo inventore veritatis et quasi architecto beatae vitae dicta sunt explicabo. Nemo enim ipsam voluptatem quia voluptas sit aspernatur aut odit aut fugit, sed quia consequuntur magni dolores eos qui ratione voluptatem sequi nesciunt.
|
||||
|
||||
## Chapter three
|
||||
|
||||
On the reading experience itself: motion on the web is usually either absent or obnoxious. The interesting middle ground is motion that acknowledges the reader's own movement — the scroll. Elements that fade in as they enter the viewport give the page a sense of depth, as if the content were arriving just in time.
|
||||
|
||||
Crucially, none of this may depend on the article. The author writes Markdown; the effects come from the layout. And when the reader prefers reduced motion, everything must hold still.
|
||||
|
||||
Neque porro quisquam est, qui dolorem ipsum quia dolor sit amet, consectetur, adipisci velit, sed quia non numquam eius modi tempora incidunt ut labore et dolore magnam aliquam quaerat voluptatem. Ut enim ad minima veniam, quis nostrum exercitationem ullam corporis suscipit laboriosam, nisi ut aliquid ex ea commodi consequatur?
|
||||
|
||||
```text
|
||||
Quis autem vel eum iure reprehenderit
|
||||
qui in ea voluptate velit esse quam nihil
|
||||
molestiae consequatur, vel illum qui
|
||||
dolorem eum fugiat quo voluptas nulla pariatur?
|
||||
```
|
||||
|
||||
At vero eos et accusamus et iusto odio dignissimos ducimus qui blanditiis praesentium voluptatum deleniti atque corrupti quos dolores et quas molestias excepturi sint occaecati cupiditate non provident, similique sunt in culpa qui officia deserunt mollitia animi, id est laborum et dolorum fuga. Et harum quidem rerum facilis est et expedita distinctio.
|
||||
|
||||
## Chapter four
|
||||
|
||||
Nam libero tempore, cum soluta nobis est eligendi optio cumque nihil impedit quo minus id quod maxime placeat facere possimus, omnis voluptas assumenda est, omnis dolor repellendus. Temporibus autem quibusdam et aut officiis debitis aut rerum necessitatibus saepe eveniet ut et voluptates repudiandae sint et molestiae non recusandae.
|
||||
|
||||
Itaque earum rerum hic tenetur a sapiente delectus, ut aut reiciendis voluptatibus maiores alias consequatur aut perferendis doloribus asperiores repellat. And so we arrive back where we started: the blog and the website were one thing all along. [Return to the front page](/).
|
||||
If your Markdown contains its own `# heading`, the page title is not repeated as a second h1 — it still supplies the `<title>` and the menu labels. This page is an example: its `# Markdown` heading *is* the title.
|
||||
"""
|
||||
|
||||
NOTES_ON_URLS = """\
|
||||
A URL is part of the content. A few rules of thumb I keep coming back to:
|
||||
MD_LAYOUT = """\
|
||||
## Images and figures
|
||||
|
||||
- Pick slugs like book titles, not like database keys.
|
||||
- Nest only when the structure is real.
|
||||
- Once published, a URL is a promise. Redirect if you must break it.
|
||||
An image standing alone in its paragraph becomes a `<figure>`; its title becomes the caption. Inline images within text stay plain.
|
||||
|
||||
> Cool URIs don't change; uncool ones at least apologise.
|
||||
|
||||
That's all. Short posts are posts too.
|
||||
"""
|
||||
|
||||
CANVAS_NIGHTS = """\
|
||||
This post's banner is not an image at all — it's a `<canvas>` animated by a few lines of JavaScript embedded in the page's banner HTML.
|
||||
|
||||
Banners on this site are arbitrary markup: an image, a gradient div, or a small animated scene like the one above. Subpages inherit the nearest banner up their path, so a whole section can share one look.
|
||||
|
||||
```js
|
||||
// the essence of the banner above
|
||||
stars.forEach(s => { s.x = (s.x + s.speed * dt) % 1 })
|
||||
```markdown
|
||||

|
||||
```
|
||||
|
||||
No build step, no framework — the snippet is stored with the page and dropped into the header as-is.
|
||||

|
||||
|
||||
## Positioning with attributes
|
||||
|
||||
Brace attributes (the attrs plugin) control placement: `{.right}` and `{.left}` float, `{.margin}` moves a figure into the side zone, `{.wide}` breaks out of the text column, and plain attributes like `width=280` pass through.
|
||||
|
||||
```markdown
|
||||
{.right width=280}
|
||||
```
|
||||
|
||||
{.right width=280}
|
||||
|
||||
Floated images let the text wrap around them, like this paragraph does. Relative image paths resolve against the page's own path, so attached files travel with the page. Uploaded files get content-addressed `/_f/` URLs that never break, no matter where the page moves.
|
||||
|
||||
```markdown
|
||||
{.margin}
|
||||
```
|
||||
|
||||
{.margin}
|
||||
|
||||
The same figure as a margin note: it leans into the side zone left of the text on all but phone widths, alongside the text it belongs to.
|
||||
|
||||
{.wide} artwork spans the full content width:
|
||||
|
||||
```markdown
|
||||
{.wide}
|
||||
```
|
||||
|
||||
{.wide}
|
||||
"""
|
||||
|
||||
GALLERY = """\
|
||||
This page's banner is the **eyes** design — a critter in the grass in — picked from banner menu (⚙️ in the top right corner). The selection applies to current page and all its children, allowing differently themed sections be created. [Night Sky](night-sky) picked its own. You should also find the theme settings, which allow choosing overall site theme, fonts and transitions. You may wish to try the more playful **summer** theme which the eyes theme builds on.
|
||||
|
||||
## Break out of the box!
|
||||
|
||||
{.wide}
|
||||
|
||||
::: aside
|
||||

|
||||
|
||||
## Aside boxes
|
||||
|
||||
When you have to sideline a bit with something important to say, use `::: aside` and end with `:::`, markdown between.
|
||||
|
||||
On larger screens they break outside the normal page bounds. `{.margin}` can be used to a similar effect without a box.
|
||||
:::
|
||||
|
||||
Images and text boxes can also be positioned for a more lively layout.
|
||||
|
||||
{.right}
|
||||
|
||||
This text wraps around a left or right floated figure. The caption comes from the image title, with additional styling like `{.left width=240}` — brace attributes on the image itself.
|
||||
|
||||
Note how the layout may take different forms from a phone in portrait to widest of desktop browsers, not leaving large empty areas nor being constrained to a classic container box model.
|
||||
|
||||
Lifting off elements here and there makes a great difference to how your site is received!
|
||||
|
||||
### Design matters
|
||||
|
||||
Good graphical design gives a website a clear visual structure and makes information easy to understand at a glance. Layout, spacing, typography, color, and imagery should work together to establish hierarchy and guide attention naturally through the page. Consistency between sections also helps users quickly learn how the interface is organized.
|
||||
|
||||
A strong website layout balances visual character with usability. Content should have enough space to remain readable, while navigation and important actions should be easy to find without dominating the design. Responsive layouts should preserve these relationships across different screen sizes rather than simply shrinking the desktop arrangement.
|
||||
"""
|
||||
|
||||
NIGHT_SKY = """\
|
||||
This page's banner is not an image or a code snippet — it's the **stars** banner design, picked from a dropdown in the banner editor (🖊️ in the banner corner). Nothing is stored in the page beyond that choice.
|
||||
|
||||
Banner designs are folders in `pagerite/themes/{name}/` — a `banner.css` plus a `banner.html` or `banner.svg` — so a design can be anything from a static gradient to an animated canvas like the starfield above. This site ships `stars` and `eyes` (a critter in the grass, seen on the [gallery](/showcase/gallery)), and themes can bring their own.
|
||||
|
||||
Subpages inherit the nearest banner and design up their path, so a whole section can share one look — set one on a category and every page under it gets it, until a page overrides with its own. This page is a leaf: the design chosen here affects nothing else.
|
||||
|
||||
A page can also carry its own banner HTML — an `<img>`, a styled div, a canvas with a script — which renders *on top of* the design's artwork, so author code always wins. But most of the time, picking a design is all you need.
|
||||
"""
|
||||
|
||||
# Moby-Dick; or, The Whale (1851), Herman Melville — public domain.
|
||||
# Chapter 1, abridged and headed. A real long-read: flowing sections,
|
||||
# figures, a list, side notes — not a feature showcase. (Engravings:
|
||||
# Augustus Burnham Shute's illustrations for the 1892 edition, public
|
||||
# domain; the wave is Hokusai, public domain.)
|
||||
LOOMINGS = """\
|
||||
*The opening of Herman Melville's Moby-Dick (1851), abridged — here to show what a longer article feels like: the multi-column layout on wide screens, images breaking up the text, and the gentle reveal as sections scroll into view.*
|
||||
|
||||
{dates}
|
||||
|
||||
{.wide}
|
||||
|
||||
## The watery part of the world
|
||||
|
||||
Call me Ishmael. Some years ago — never mind how long precisely — having little or no money in my purse, and nothing particular to interest me on shore, I thought I would sail about a little and see the watery part of the world. It is a way I have of driving off the spleen and regulating the circulation. Whenever I find myself growing grim about the mouth; whenever it is a damp, drizzly November in my soul; whenever I find myself involuntarily pausing before coffin warehouses, and bringing up the rear of every funeral I meet; and especially whenever my hypos get such an upper hand of me, that it requires a strong moral principle to prevent me from deliberately stepping into the street, and methodically knocking people's hats off — then, I account it high time to get to sea as soon as I can. This is my substitute for pistol and ball. With a philosophical flourish Cato throws himself upon his sword; I quietly take to the ship. There is nothing surprising in this. If they but knew it, almost all men in their degree, some time or other, cherish very nearly the same feelings towards the ocean with me.
|
||||
|
||||
::: aside
|
||||
Melville interrupts his story often — whole chapters on cetology, rope and chowder. Abridgments drop most of them, but notes like this one are where they would have gone.
|
||||
:::
|
||||
|
||||
There now is your insular city of the Manhattoes, belted round by wharves as Indian isles by coral reefs — commerce surrounds it with her surf. Right and left, the streets take you waterward. Its extreme downtown is the battery, where that noble mole is washed by waves, and cooled by breezes, which a few hours previous were out of sight of land. Look at the crowds of water-gazers there.
|
||||
|
||||
Circumambulate the city of a dreamy Sabbath afternoon. Go from Corlears Hook to Coenties Slip, and from thence, by Whitehall, northward. What do you see? — Posted like silent sentinels all around the town, stand thousands upon thousands of mortal men fixed in ocean reveries. Some leaning against the spiles; some seated upon the pier-heads; some looking over the bulwarks of ships from China; some high aloft in the rigging, as if striving to get a still better seaward peep. But these are all landsmen; of week days pent up in lath and plaster — tied to counters, nailed to benches, clinched to desks. How then is this? Are the green fields gone? What do they here?
|
||||
|
||||
But look! here come more crowds, pacing straight for the water, and seemingly bound for a dive. Strange! Nothing will content them but the extremest limit of the land; loitering under the shady lee of yonder warehouses will not suffice. No. They must get just as nigh the water as they possibly can without falling in. And there they stand — miles of them — leagues. Inlanders all, they come from lanes and alleys, streets and avenues — north, east, south, and west. Yet here they all unite. Tell me, does the magnetic virtue of the needles of the compasses of all those ships attract them thither?
|
||||
|
||||
## Meditation and water
|
||||
|
||||
Once more. Say you are in the country; in some high land of lakes. Take almost any path you please, and ten to one it carries you down in a dale, and leaves you there by a pool in the stream. There is magic in it. Let the most absent-minded of men be plunged in his deepest reveries — stand that man on his legs, set his feet a-going, and he will infallibly lead you to water, if water there be in all that region. Should you ever be athirst in the great American desert, try this experiment, if your caravan happen to be supplied with a metaphysical professor. Yes, as every one knows, meditation and water are wedded for ever.
|
||||
|
||||
Ishmael sails from New Bedford, the whaling port south of Boston — Nantucket was the older, prouder whaling town, and he briefly considers it first.
|
||||
{.margin}
|
||||
|
||||
### The artist's problem
|
||||
|
||||
But here is an artist. He desires to paint you the dreamiest, shadiest, quietest, most enchanting bit of romantic landscape in all the valley of the Saco. What is the chief element he employs? There stand his trees, each with a hollow trunk, as if a hermit and a crucifix were within; and here sleeps his meadow, and there sleep his cattle; and up from yonder cottage goes a sleepy smoke. Deep into distant woodlands winds a mazy way, reaching to overlapping spurs of mountains bathed in their hill-side blue. But though the picture lies thus tranced, and though this pine-tree shakes down its sighs like leaves upon this shepherd's head, yet all were vain, unless the shepherd's eye were fixed upon the magic stream before him.
|
||||
|
||||
Why did the poor poet of Tennessee, upon suddenly receiving two handfuls of silver, deliberate whether to buy him a coat, which he sadly needed, or invest his money in a pedestrian trip to Rockaway Beach? Why is almost every robust healthy boy with a robust healthy soul in him, at some time or other crazy to go to sea? Why upon your first voyage as a passenger, did you yourself feel such a mystical vibration, when you were first told that you and your ship were now out of sight of land? Why did the old Persians hold the sea holy? Why did the Greeks give it a separate deity, and own brother of Jove? Surely all this is not without meaning. And still deeper the meaning of that story of Narcissus, who because he could not grasp the tormenting, mild image he saw in the fountain, plunged into it and was drowned. But that same image, we ourselves see in all rivers and oceans. It is the image of the ungraspable phantom of life; and this is the key to it all.
|
||||
|
||||
## A simple sailor, right before the mast
|
||||
|
||||
Now, when I say that I am in the habit of going to sea whenever I begin to grow hazy about the eyes, and begin to be over conscious of my lungs, I do not mean to have it inferred that I ever go to sea as a passenger. For to go as a passenger you must needs have a purse, and a purse is but a rag unless you have something in it. Besides, passengers get sea-sick — grow quarrelsome — don't sleep of nights — do not enjoy themselves much, as a general thing; — no, I never go as a passenger; nor, though I am something of a salt, do I ever go to sea as a Commodore, or a Captain, or a Cook. I abandon the glory and distinction of such offices to those who like them. For my part, I abominate all honorable respectable toils, trials, and tribulations of every kind whatsoever. It is quite as much as I can do to take care of myself, without taking care of ships, barques, brigs, schooners, and what not.
|
||||
|
||||
{.right width=400}
|
||||
|
||||
No, when I go to sea, I go as a simple sailor, right before the mast, plumb down into the forecastle, aloft there to the royal mast-head. True, they rather order me about some, and make me jump from spar to spar, like a grasshopper in a May meadow. And at first, this sort of thing is unpleasant enough. It touches one's sense of honor, particularly if you come of an old established family in the land, the Van Rensselaers, or Randolphs, or Hardicanutes. And more than all, if just previous to putting your hand into the tar-pot, you have been lording it as a country schoolmaster, making the tallest boys stand in awe of you. The transition is a keen one, I assure you, from a schoolmaster to a sailor, and requires a strong decoction of Seneca and the Stoics to enable you to grin and bear it. But even this wears off in time.
|
||||
|
||||
What of it, if some old hunks of a sea-captain orders me to get a broom and sweep down the decks? What does that indignity amount to, weighed, I mean, in the scales of the New Testament? Do you think the archangel Gabriel thinks anything the less of me, because I promptly and respectfully obey that old hunks in that particular instance? Who ain't a slave? Tell me that. Well, then, however the old sea-captains may order me about — however they may thump and punch me about, I have the satisfaction of knowing that it is all right; that everybody else is one way or other served in much the same way — either in a physical or metaphysical point of view, that is; and so the universal thump is passed round, and all hands should rub each other's shoulder-blades, and be content.
|
||||
|
||||
And finally, what shall I say of the reasons for going a-whaling? Chief among them:
|
||||
|
||||
- The overwhelming idea of the great whale himself — such a portentous and mysterious monster roused all my curiosity.
|
||||
- The undeliverable, nameless perils of the whale, and the attendants of the wondrous world of waters.
|
||||
- The tormenting, mild image of the ungraspable phantom of life, seen in all rivers and oceans.
|
||||
|
||||
These were the things that finally drew me to the sea — and if they but knew it, almost all men cherish very nearly the same feelings towards the ocean with me.
|
||||
"""
|
||||
|
||||
SMALL_RELEASES = """\
|
||||
@@ -151,42 +415,22 @@ Software wants to be shipped. The longer a change sits unmerged, the more it rot
|
||||
2. Ship it behind whatever door you like.
|
||||
3. Let real use argue with your assumptions.
|
||||
|
||||
A release is a conversation with reality. Small releases keep the conversation lively.
|
||||
A release is a conversation with reality. Small releases keep the conversation lively — and small *pieces* keep the whole thing standing, as [the comic on the About page](/about) illustrates all too well.
|
||||
"""
|
||||
|
||||
CANVAS_BANNER = """\
|
||||
<canvas id="stars"></canvas>
|
||||
<script>
|
||||
(() => {
|
||||
const c = document.getElementById("stars");
|
||||
const ctx = c.getContext("2d");
|
||||
const fit = () => { c.width = c.clientWidth; c.height = c.clientHeight; };
|
||||
fit();
|
||||
addEventListener("resize", fit);
|
||||
const stars = Array.from({ length: 110 }, () => ({
|
||||
x: Math.random(), y: Math.random(),
|
||||
r: Math.random() * 1.4 + 0.3, v: Math.random() * 0.05 + 0.01,
|
||||
}));
|
||||
let prev = performance.now();
|
||||
(function frame(now) {
|
||||
if (!c.isConnected) return;
|
||||
const dt = Math.min(now - prev, 100); prev = now;
|
||||
ctx.fillStyle = "#0b0e1d";
|
||||
ctx.fillRect(0, 0, c.width, c.height);
|
||||
ctx.fillStyle = "#cdd6ff";
|
||||
for (const s of stars) {
|
||||
s.x = (s.x + s.v * dt / 1000) % 1;
|
||||
ctx.beginPath();
|
||||
ctx.arc(s.x * c.width, s.y * c.height, s.r, 0, 7);
|
||||
ctx.fill();
|
||||
}
|
||||
requestAnimationFrame(frame);
|
||||
})(prev);
|
||||
})();
|
||||
</script>
|
||||
"""
|
||||
ABOUT = """\
|
||||
This site runs on **Pagerite**: FastAPI + html5tagger + kanta, with content written in Markdown and rendered on the fly.
|
||||
|
||||
BLOG_BANNER = '<div style="background: linear-gradient(100deg, #14243d, #3d2b6b 45%, #7c5cff 75%, #ff5c8a)"></div>'
|
||||
- [How to edit this site](/docs/editing)
|
||||
- [Everything Markdown can do](/docs/markdown)
|
||||
- [The showcase](/showcase/gallery)
|
||||
|
||||
Pagerite keeps its dependency list short and knows every entry on it. Modern software in general builds on taller towers of other people's work:
|
||||
|
||||
[{width=280}](https://xkcd.com/2347/)
|
||||
|
||||
*Replace this page with whatever your site is about.*
|
||||
"""
|
||||
|
||||
WAVES_SVG = """\
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 800 400">
|
||||
@@ -231,33 +475,55 @@ DUNES_SVG = """\
|
||||
"""
|
||||
|
||||
#: path -> (title, markdown, {filename: bytes}, banner HTML, menu order,
|
||||
#: banner design). Banners are deliberately set only on select sub pages
|
||||
#: (not the front page), so the theme's default design shows elsewhere.
|
||||
#: Note there are deliberately no "docs" or "blog" landing pages: those
|
||||
#: labels are created without content, so they render a placeholder page
|
||||
#: and their nav links point at the first child (see views.first_leaf).
|
||||
#: banner design). Designs demonstrate per-page choice: the gallery
|
||||
#: picks "eyes" (its page alone), night-sky picks "stars"; everything
|
||||
#: else inherits the active theme's own design.
|
||||
#: Note there are deliberately no "docs" or "showcase" landing pages:
|
||||
#: those labels are created without content, so they render a placeholder
|
||||
#: page and their nav links point at the first child (see
|
||||
#: views.first_leaf). "showcase" is seeded explicitly (empty markdown,
|
||||
#: which the seeder leaves as content=None) purely to fix its menu order.
|
||||
PAGES: dict[str, tuple[str, str, dict[str, bytes], str, float, str | None]] = {
|
||||
"": ("Welcome", WELCOME, {"waves.svg": WAVES_SVG.encode()}, "", 1, None),
|
||||
"about": ("About", ABOUT, {}, "", 2, None),
|
||||
"docs/editing": (
|
||||
"Writing Content",
|
||||
EDITING,
|
||||
{"shapes.svg": SHAPES_SVG.encode()},
|
||||
"about": ("About", ABOUT, {}, "", 3, None),
|
||||
"docs/editing": ("Editing This Site", EDITING, {}, "", 1, None),
|
||||
"docs/markdown": ("Markdown", MD_ARTICLE, {}, "", 2, None),
|
||||
"docs/markdown/images-and-layout": (
|
||||
"Images and Layout",
|
||||
MD_LAYOUT,
|
||||
{
|
||||
"shapes.svg": SHAPES_SVG.encode(),
|
||||
"waves.svg": WAVES_SVG.encode(),
|
||||
"dunes.svg": DUNES_SVG.encode(),
|
||||
},
|
||||
"",
|
||||
1,
|
||||
None,
|
||||
),
|
||||
"blog/the-long-read": (
|
||||
"The Long Read",
|
||||
LONG_READ,
|
||||
{"dunes.svg": DUNES_SVG.encode()},
|
||||
BLOG_BANNER,
|
||||
"showcase": ("Showcase", "", {}, "", 4, None),
|
||||
"showcase/gallery": (
|
||||
"Gallery",
|
||||
GALLERY,
|
||||
{
|
||||
"dunes.svg": DUNES_SVG.encode(),
|
||||
"shapes.svg": SHAPES_SVG.encode(),
|
||||
"waves.svg": WAVES_SVG.encode(),
|
||||
},
|
||||
"",
|
||||
1,
|
||||
"eyes",
|
||||
),
|
||||
"showcase/loomings": (
|
||||
"Loomings — a Long Read",
|
||||
LOOMINGS,
|
||||
{
|
||||
"great-wave.jpg": _asset("great-wave.jpg"),
|
||||
"md-whale.jpg": _asset("md-whale.jpg"),
|
||||
},
|
||||
"",
|
||||
2,
|
||||
None,
|
||||
),
|
||||
# The eyes critter is a named banner design (pagerite/themes/eyes/),
|
||||
# not code embedded in the page.
|
||||
"blog/notes-on-urls": ("Notes on URLs", NOTES_ON_URLS, {}, "", 2, "eyes"),
|
||||
"blog/canvas-nights": ("Canvas Nights", CANVAS_NIGHTS, {}, CANVAS_BANNER, 3, None),
|
||||
"blog/small-releases": ("Small Releases", SMALL_RELEASES, {}, "", 4, None),
|
||||
"showcase/night-sky": ("Night Sky", NIGHT_SKY, {}, "", 3, "stars"),
|
||||
"showcase/small-releases": ("Small Releases", SMALL_RELEASES, {}, "", 4, None),
|
||||
}
|
||||
|
||||
@@ -0,0 +1,701 @@
|
||||
"""Segmented translation round trip: prose out, translations back in.
|
||||
|
||||
A translator model mangles anything that is not plain prose — sentinels get
|
||||
renumbered, ``", "](dest \"title\")", "][ref]",
|
||||
#: "[]" or a bare "]" (shortcut reference); the destination may nest one
|
||||
#: level of parens. Best effort — a mis-scan fails the span-reconstruction
|
||||
#: check in _linked_block and the block falls back to per-run segments.
|
||||
_LINK_TAIL = re.compile(r"\](?:\((?:\\.|[^()\\]|\([^()]*\))*\)|\[(?:\\.|[^\]])*\])?")
|
||||
|
||||
#: Weight units for mapping link boundaries from source to translation:
|
||||
#: a word counts 1 and so does every single CJK ideograph (kana runs count
|
||||
#: as one) — CJK has no spaces to count words by. Punctuation and
|
||||
#: whitespace count nothing, so mapped boundaries always land on unit
|
||||
#: starts.
|
||||
_UNIT = re.compile(
|
||||
r"[\u3400-\u4dbf\u4e00-\u9fff\uf900-\ufaff]" # CJK ideographs: one unit each
|
||||
r"|[\u3040-\u309f\u30a0-\u30ff]+" # kana runs: one unit each
|
||||
r"|\w+" # anything else word-like (Latin, Cyrillic, Hangul, digits)
|
||||
)
|
||||
|
||||
|
||||
class Mark(NamedTuple):
|
||||
"""One inline link or paired formatting (strong/em/s) inside a
|
||||
whole-block segment: the source weight (unit count, see _UNIT) at the
|
||||
inner text's start and end (fallback for mapping the boundaries into
|
||||
the translation when fuzzy word alignment finds nothing, _find_mark),
|
||||
the exact source syntax around the text ("[" / "](url)", "**" / "**",
|
||||
...) and the source text itself — the words fuzzy alignment looks for,
|
||||
and the fallback when the mapped slice comes out empty (better an
|
||||
untranslated label than a broken "[](url)")."""
|
||||
|
||||
w_start: int
|
||||
w_end: int
|
||||
pre: str
|
||||
post: str
|
||||
inner: str
|
||||
|
||||
|
||||
class Span(NamedTuple):
|
||||
"""A segment's source span in the fragment: offsets for splicing the
|
||||
translation back, the segment's source weight and the links to
|
||||
re-insert into its translation (empty = a plain prose segment)."""
|
||||
|
||||
start: int
|
||||
end: int
|
||||
weight: int
|
||||
marks: list[Mark]
|
||||
|
||||
|
||||
def _weight(text: str) -> int:
|
||||
"""The text's weight in translation-mapping units (see _UNIT)."""
|
||||
return len(_UNIT.findall(text))
|
||||
|
||||
|
||||
def _runs(children: list) -> list[str]:
|
||||
"""Prose runs of an inline token's children, in order.
|
||||
|
||||
Text tokens merge across soft breaks into one run; every markup token
|
||||
(emphasis, links, code, images, HTML, footnote refs, hard breaks) is a
|
||||
run boundary. Link and image *text* is prose; autolink text (the URL
|
||||
itself) is not. Image tokens contribute their alt-text children and
|
||||
their title attribute.
|
||||
"""
|
||||
runs: list[str] = []
|
||||
cur: list[str] = []
|
||||
|
||||
def flush() -> None:
|
||||
if cur:
|
||||
s = "".join(cur)
|
||||
cur.clear()
|
||||
if _LETTER.search(s):
|
||||
runs.append(s)
|
||||
|
||||
skip = 0 # inside an autolink (its text is the URL — not prose)
|
||||
for t in children:
|
||||
if skip:
|
||||
if t.type == "link_close":
|
||||
skip -= 1
|
||||
continue
|
||||
if t.type == "text":
|
||||
cur.append(t.content)
|
||||
elif t.type == "softbreak":
|
||||
cur.append("\n")
|
||||
elif t.type == "link_open" and t.markup == "autolink":
|
||||
flush()
|
||||
skip = 1
|
||||
elif t.type == "image":
|
||||
flush()
|
||||
if t.children:
|
||||
runs.extend(_runs(t.children))
|
||||
title = t.attrGet("title")
|
||||
if title and _LETTER.search(title):
|
||||
runs.append(title)
|
||||
else:
|
||||
flush()
|
||||
if t.children:
|
||||
runs.extend(_runs(t.children))
|
||||
flush()
|
||||
return runs
|
||||
|
||||
|
||||
def _block_text(children: list) -> str:
|
||||
"""The block's text as a reader sees it: text runs and link texts
|
||||
merged (softbreaks as newlines); image alts, autolink URLs, code and
|
||||
other markup content excluded. Used as the translation CONTEXT for
|
||||
segments carved out of the block (link texts, partial runs): a lone
|
||||
word translates differently than the same word inside its sentence."""
|
||||
parts: list[str] = []
|
||||
skip = 0 # inside an autolink (its text is the URL)
|
||||
for t in children:
|
||||
if skip:
|
||||
if t.type == "link_close":
|
||||
skip -= 1
|
||||
continue
|
||||
if t.type == "text":
|
||||
parts.append(t.content)
|
||||
elif t.type == "softbreak":
|
||||
parts.append("\n")
|
||||
elif t.type == "link_open" and t.markup == "autolink":
|
||||
skip = 1
|
||||
elif t.type == "image":
|
||||
continue
|
||||
elif t.children:
|
||||
parts.append(_block_text(t.children))
|
||||
return "".join(parts)
|
||||
|
||||
|
||||
def _locate(source: str, needle: str, cursor: int) -> int:
|
||||
"""The needle's offset in source at/after cursor, -1 when absent.
|
||||
|
||||
An occurrence preceded by a backslash is an escaped character, not the
|
||||
token's source: keep looking (failing that, the run is skipped — it
|
||||
stays in the original language).
|
||||
"""
|
||||
pos = source.find(needle, cursor)
|
||||
while pos > 0 and source[pos - 1] == "\\":
|
||||
pos = source.find(needle, pos + 1)
|
||||
return pos
|
||||
|
||||
|
||||
def _linked_block(
|
||||
source: str, kids: list, cursor: int, strip_alert: bool
|
||||
) -> tuple[Span, str] | None:
|
||||
"""A whole-block segment for an inline of plain text, prose links and
|
||||
paired text formatting (strong/em/s): (Span, wire text) with the links
|
||||
and formatting as marks, or None when the block has any other shape —
|
||||
the caller then falls back to per-run segments.
|
||||
|
||||
The block crosses the wire as one prose piece, link texts and formatted
|
||||
text inline (the model is never shown any Markdown — it mangles it),
|
||||
so a translation that inflects or reorders around them stays coherent;
|
||||
join re-inserts the link/formatting syntax at weight-mapped positions.
|
||||
The source span is located piece by piece and verified by
|
||||
reconstruction; anything not byte-exact (entities, escapes, an odd
|
||||
link tail) bails to the fallback.
|
||||
"""
|
||||
pieces: list[
|
||||
tuple[str, str]
|
||||
] = [] # (text, mark): "" plain, "link", else the delimiter
|
||||
buf: list[str] = [] # current plain piece
|
||||
link: list[str] | None = None # current mark's text parts
|
||||
mark_kind = "" # the current mark's opener ("link" or the delimiter)
|
||||
for tok in kids:
|
||||
if tok.type in ("link_open", "strong_open", "em_open", "s_open"):
|
||||
if link is not None or tok.markup == "autolink":
|
||||
return None
|
||||
if buf:
|
||||
pieces.append(("".join(buf), ""))
|
||||
buf = []
|
||||
link = []
|
||||
mark_kind = "link" if tok.type == "link_open" else tok.markup
|
||||
elif tok.type in ("link_close", "strong_close", "em_close", "s_close"):
|
||||
if (
|
||||
link is None
|
||||
or ("link" if tok.type == "link_close" else tok.markup) != mark_kind
|
||||
):
|
||||
return None
|
||||
inner = "".join(link)
|
||||
if not _LETTER.search(inner):
|
||||
return None
|
||||
pieces.append((inner, mark_kind))
|
||||
link = None
|
||||
elif tok.type in ("text", "softbreak"):
|
||||
(link if link is not None else buf).append(
|
||||
"\n" if tok.type == "softbreak" else tok.content
|
||||
)
|
||||
else: # code, images, HTML, footnote refs: run boundaries
|
||||
return None
|
||||
if link is not None:
|
||||
return None # unbalanced (the parser should not do this)
|
||||
if buf:
|
||||
pieces.append(("".join(buf), ""))
|
||||
if not any(mark for _, mark in pieces):
|
||||
return None
|
||||
if strip_alert and pieces and not pieces[0][1]:
|
||||
# A GFM alert marker leading the blockquote's first paragraph is
|
||||
# syntax; strip it from the wire text (it stays out of the span).
|
||||
first = _ALERT.sub("", pieces[0][0], count=1)
|
||||
if first.strip():
|
||||
pieces[0] = (first, "")
|
||||
else:
|
||||
pieces.pop(0)
|
||||
if not pieces:
|
||||
return None
|
||||
raw = "".join(text for text, _ in pieces)
|
||||
lead = len(raw) - len(raw.lstrip())
|
||||
wire = raw.strip()
|
||||
if not _LETTER.search(wire) or _BRACES.search(wire):
|
||||
return None
|
||||
# Locate each piece verbatim, in order; the source slices between the
|
||||
# located pieces are then the link syntax, exact by construction.
|
||||
located: list[tuple[int, int]] = []
|
||||
pos = cursor
|
||||
for text_, _ in pieces:
|
||||
at = _locate(source, text_, pos)
|
||||
if at == -1:
|
||||
return None
|
||||
located.append((at, at + len(text_)))
|
||||
pos = at + len(text_)
|
||||
span_start, span_end = located[0][0], located[-1][1]
|
||||
marks: list[Mark] = []
|
||||
offset = 0 # raw (pre-strip) plain-text offset of the current piece
|
||||
for i, ((text_, kind), (s, e)) in enumerate(zip(pieces, located)):
|
||||
if not kind:
|
||||
offset += len(text_)
|
||||
continue
|
||||
# The syntax around the text: the gap between pieces goes to the
|
||||
# mark on its left as post (so between two marks the whole "](u)["
|
||||
# or "**" is the first's post); a block-leading mark takes its
|
||||
# opener in front of its text ("[" or the delimiter), a
|
||||
# block-trailing one the scanned link tail or the close delimiter.
|
||||
if i == 0:
|
||||
opener = "[" if kind == "link" else kind
|
||||
if s < len(opener) or source[s - len(opener) : s] != opener:
|
||||
return None
|
||||
pre, span_start = opener, s - len(opener)
|
||||
elif pieces[i - 1][1]:
|
||||
pre = "" # the previous mark's post covers the whole gap
|
||||
else:
|
||||
pre = source[located[i - 1][1] : s]
|
||||
if i + 1 < len(pieces):
|
||||
post = source[e : located[i + 1][0]]
|
||||
elif kind == "link":
|
||||
m = _LINK_TAIL.match(source, e)
|
||||
if m is None:
|
||||
return None
|
||||
post, span_end = m.group(), m.end()
|
||||
else:
|
||||
if source[e : e + len(kind)] != kind:
|
||||
return None
|
||||
post, span_end = kind, e + len(kind)
|
||||
ps = min(max(offset - lead, 0), len(wire))
|
||||
pe = min(max(offset + len(text_) - lead, 0), len(wire))
|
||||
if pe <= ps:
|
||||
return None
|
||||
marks.append(
|
||||
Mark(_weight(wire[:ps]), _weight(wire[:pe]), pre, post, wire[ps:pe])
|
||||
)
|
||||
offset += len(text_)
|
||||
# Verify: the marks must reconstruct the source span exactly (the only
|
||||
# real risk is the guessed tail of a trailing link).
|
||||
rec: list[str] = []
|
||||
mi = 0
|
||||
for text_, kind in pieces:
|
||||
if kind:
|
||||
mark = marks[mi]
|
||||
mi += 1
|
||||
rec += [mark.pre, text_, mark.post]
|
||||
else:
|
||||
rec.append(text_)
|
||||
if source[span_start:span_end] != "".join(rec):
|
||||
return None
|
||||
return Span(span_start, span_end, _weight(wire), marks), _encode(wire)
|
||||
|
||||
|
||||
def split(text: str) -> tuple[list[Span], list[str], list[str]]:
|
||||
"""Split a fragment into (spans, segments, contexts): prose segments to
|
||||
translate, their source spans in ``text`` for splicing the translations
|
||||
back, and per-segment translation context.
|
||||
|
||||
A block of plain text, prose links and paired formatting (strong/em/s)
|
||||
becomes ONE segment (link/formatted text inline, in context, Markdown
|
||||
stripped), the links and formatting recorded as marks on its Span for
|
||||
weight-mapped re-insertion in join. Other blocks split into text runs
|
||||
at markup boundaries; runs containing {...} spans are carved further —
|
||||
the braces stay out of the wire text. A run that cannot be located
|
||||
verbatim in the source contributes no segment. A segment's context is
|
||||
its block's plain text when the segment was carved OUT of a larger
|
||||
block (a partial run); a segment that IS the whole block (a plain
|
||||
paragraph, a heading, a linked block) is self-contextualizing and gets
|
||||
"".
|
||||
"""
|
||||
spans: list[Span] = []
|
||||
segments: list[str] = []
|
||||
contexts: list[str] = []
|
||||
cursor = 0
|
||||
blockquote_fresh = 0 # blockquote depth whose first inline is upcoming
|
||||
|
||||
def emit(run: str, at: int, ctx: str) -> None:
|
||||
"""Carve {...} spans out of the located run; emit the prose pieces,
|
||||
stripped — padding whitespace stays in the template, off the wire.
|
||||
A literal "<" crosses encoded (``_encode``): it is text, not
|
||||
markup, but the wire keeps "<" as the prose/markup boundary."""
|
||||
pieces = []
|
||||
pos = 0
|
||||
for m in _BRACES.finditer(run):
|
||||
pieces.append((pos, m.start()))
|
||||
pos = m.end()
|
||||
pieces.append((pos, len(run)))
|
||||
for p0, p1 in pieces:
|
||||
raw = run[p0:p1]
|
||||
piece = raw.strip()
|
||||
if _LETTER.search(piece):
|
||||
start = at + p0 + (len(raw) - len(raw.lstrip()))
|
||||
spans.append(Span(start, start + len(piece), 0, []))
|
||||
segments.append(_encode(piece))
|
||||
contexts.append(ctx)
|
||||
|
||||
tokens = _MD.parse(text)
|
||||
for t in tokens:
|
||||
if t.type == "blockquote_open":
|
||||
blockquote_fresh += 1
|
||||
elif t.type == "blockquote_close":
|
||||
blockquote_fresh -= 1
|
||||
elif t.type == "inline":
|
||||
kids = t.children or []
|
||||
# An alert marker ([!NOTE]) leading a blockquote's first
|
||||
# paragraph is syntax; both paths strip it. (Only the first
|
||||
# inline of the blockquote can carry it — the flag clears on
|
||||
# the first inline seen.)
|
||||
alert = bool(blockquote_fresh)
|
||||
blockquote_fresh = 0
|
||||
linked = _linked_block(text, kids, cursor, strip_alert=alert)
|
||||
if linked is not None:
|
||||
span, wire = linked
|
||||
spans.append(span)
|
||||
segments.append(wire)
|
||||
contexts.append("")
|
||||
cursor = span.end
|
||||
continue
|
||||
runs = _runs(kids)
|
||||
block = _encode(_block_text(kids).strip())
|
||||
if alert and runs:
|
||||
run = _ALERT.sub("", runs[0], count=1)
|
||||
if _LETTER.search(run):
|
||||
runs[0] = run
|
||||
else:
|
||||
runs.pop(0)
|
||||
for run in runs:
|
||||
ctx = block if block and _encode(run.strip()) != block else ""
|
||||
pos = _locate(text, run, cursor)
|
||||
if pos != -1:
|
||||
emit(run, pos, ctx)
|
||||
cursor = pos + len(run)
|
||||
elif "\n" in run:
|
||||
# Indented continuation lines etc. break the verbatim
|
||||
# match: locate each line separately instead.
|
||||
for part in run.split("\n"):
|
||||
if not _LETTER.search(part):
|
||||
continue
|
||||
pos = _locate(text, part, cursor)
|
||||
if pos != -1:
|
||||
emit(part, pos, ctx)
|
||||
cursor = pos + len(part)
|
||||
return spans, segments, contexts
|
||||
|
||||
|
||||
#: Block-level Markdown a translation must not introduce: a segment is
|
||||
#: spliced INSIDE a block of the fragment, so a line starting a heading,
|
||||
#: quote, list, code/container fence or a setext/thematic-break underline
|
||||
#: would break the fragment's block structure — a ``` or ::: line eats the
|
||||
#: rest of the fence it lands in, closing fence included. pure_prose only
|
||||
#: parses inline and lets such lines through as softbreak prose, so join
|
||||
#: rejects them here. Blank lines split the host block and are rejected
|
||||
#: too (a faithful translation of a single block has none).
|
||||
_BLOCK = re.compile(
|
||||
r"^[ \t]*(?:#{1,6}(?:[ \t]|$)|>[ \t]?|(?:[-+*]|\d{1,9}[.)])[ \t]|`{3,}|~{3,}|:{3,}(?:[ \t]|$)"
|
||||
r"|-(?:[ \t]*-){2,}[ \t]*$|=[ =]*$|_(?:[ \t]*_){2,}[ \t]*$)",
|
||||
re.MULTILINE,
|
||||
)
|
||||
_BLANK = re.compile(r"\n[ \t]*\n")
|
||||
|
||||
|
||||
def pure_prose(text: str) -> bool:
|
||||
"""True when the text parses as nothing but prose (text and softbreak
|
||||
tokens) — the acceptance test for a translated segment: the model may
|
||||
not return markup of its own (a `<br>` here would splice live HTML into
|
||||
the fragment)."""
|
||||
children = _MD.parseInline(text)[0].children or []
|
||||
return all(t.type in ("text", "softbreak") for t in children)
|
||||
|
||||
|
||||
def _word_sim(a: str, b: str) -> float:
|
||||
"""How likely two words are the same term across a translation, 0..1.
|
||||
|
||||
A case-folded exact match is 1; otherwise the better of the sequence
|
||||
ratio and the shared-prefix ratio — inflection and derivational change
|
||||
mostly move the ending ("banana" -> "banaanilla") or drop an article or
|
||||
preposition around it. Case-folded so capitalization differences across
|
||||
languages don't hide a term, with a small bonus when BOTH sides are
|
||||
capitalized: a mid-sentence capital on both sides is likely the same
|
||||
name (capitalization conventions differ per language, so its absence
|
||||
proves nothing).
|
||||
"""
|
||||
bonus = 0.1 if a[:1].isupper() and b[:1].isupper() else 0.0
|
||||
a, b = a.casefold(), b.casefold()
|
||||
if a == b:
|
||||
return 1.0
|
||||
prefix = 0
|
||||
for ca, cb in zip(a, b):
|
||||
if ca != cb:
|
||||
break
|
||||
prefix += 1
|
||||
sim = max(
|
||||
difflib.SequenceMatcher(None, a, b).ratio(),
|
||||
prefix / max(len(a), len(b)),
|
||||
)
|
||||
return min(1.0, sim + bonus)
|
||||
|
||||
|
||||
#: Alignment costs for _find_mark: skipping a translation word (an article
|
||||
#: or preposition the target language added) is cheap, skipping a source
|
||||
#: word (one the translation dropped) costs more — a mark whose words
|
||||
#: mostly vanished is no match at all. Every matched pair pays _MATCH, so
|
||||
#: aligning a word to a lookalike-nothing (similarity below _MATCH) is
|
||||
#: worse than skipping it.
|
||||
_GAP_T = 0.25
|
||||
_GAP_S = 0.6
|
||||
_MATCH = 0.3
|
||||
|
||||
|
||||
def _find_mark(
|
||||
src: list[str], units: list[re.Match], start: int
|
||||
) -> tuple[int, int] | None:
|
||||
"""Locate a mark's source words in the translation's units (from unit
|
||||
index ``start`` on), as the (start, end) unit-index span of the best
|
||||
fuzzy alignment; None when no alignment is convincing (the caller falls
|
||||
back to the weight ratio).
|
||||
|
||||
Word-for-word alignment with skips (_word_sim per pair, _GAP_T/_GAP_S
|
||||
per skipped word): reordering is handled by the search itself, an added
|
||||
or dropped article/preposition by the skip penalties. Accepted only
|
||||
with an anchor — one pair of similarity >= 0.7 — and a decent average,
|
||||
so a fully reworded label doesn't snap onto chance lookalikes.
|
||||
"""
|
||||
tgt = [u.group() for u in units[start:]]
|
||||
n, m = len(src), len(tgt)
|
||||
if not n or not m:
|
||||
return None
|
||||
# dp[i][j]: best score aligning src[:i] to tgt[:j]; a free tail (the
|
||||
# answer is the best dp[n][j] over j) keeps trailing words costless.
|
||||
dp = [[0.0] * (m + 1) for _ in range(n + 1)]
|
||||
back: list[list[tuple[int, int]]] = [[(0, 0)] * (m + 1) for _ in range(n + 1)]
|
||||
for i in range(1, n + 1):
|
||||
dp[i][0] = dp[i - 1][0] - _GAP_S
|
||||
back[i][0] = (i - 1, 0)
|
||||
for j in range(1, m + 1):
|
||||
options = [
|
||||
(
|
||||
dp[i - 1][j - 1] + _word_sim(src[i - 1], tgt[j - 1]) - _MATCH,
|
||||
(i - 1, j - 1),
|
||||
),
|
||||
(dp[i][j - 1] - _GAP_T, (i, j - 1)),
|
||||
(dp[i - 1][j] - _GAP_S, (i - 1, j)),
|
||||
]
|
||||
dp[i][j], back[i][j] = max(options, key=lambda o: o[0])
|
||||
j_end = max(range(m + 1), key=lambda j: dp[n][j])
|
||||
pairs: list[tuple[int, int]] = [] # matched (source, target) indices
|
||||
i, j = n, j_end
|
||||
while i > 0:
|
||||
pi, pj = back[i][j]
|
||||
if (pi, pj) == (i - 1, j - 1):
|
||||
pairs.append((i - 1, j - 1))
|
||||
i, j = pi, pj
|
||||
if not pairs:
|
||||
return None
|
||||
pairs.reverse() # backtracking collected them last-first
|
||||
sims = [_word_sim(src[a], tgt[t]) for a, t in pairs]
|
||||
# Weak pairs at the span's ends are not part of the label (a declined
|
||||
# neighbor the DP matched for a pittance) — trim them off.
|
||||
while len(sims) > 1 and sims[0] < 0.5:
|
||||
pairs.pop(0)
|
||||
sims.pop(0)
|
||||
while len(sims) > 1 and sims[-1] < 0.5:
|
||||
pairs.pop()
|
||||
sims.pop()
|
||||
if max(sims) < 0.7 or sum(sims) / len(sims) < 0.45:
|
||||
return None
|
||||
return start + pairs[0][1], start + pairs[-1][1] + 1
|
||||
|
||||
|
||||
def _place_marks(translation: str, weight: int, marks: list[Mark]) -> str | None:
|
||||
"""Re-insert a whole-block segment's links into its translation.
|
||||
|
||||
Each mark's boundaries are found by fuzzy word-form alignment
|
||||
(_find_mark): the mark's source words are matched against the
|
||||
translation's units by form similarity — no markers on the wire
|
||||
(sentinels never survived the model), no assumption that word order or
|
||||
count survived either. Slicing exactly at unit boundaries keeps the
|
||||
whitespace between the mark and its neighbors in the plain text, where
|
||||
it belongs. A mark with no convincing alignment falls back to its
|
||||
source weight ratio (units before the boundary / total applied to the
|
||||
translation's units) — the pre-fuzz heuristic, still the CJK path,
|
||||
where form similarity across scripts is nil. A boundary landing empty
|
||||
degrades to the source link text: better an untranslated label than a
|
||||
broken "[](url)". None when the translation has no units to map onto
|
||||
(the caller rejects the result).
|
||||
"""
|
||||
units = list(_UNIT.finditer(translation))
|
||||
total = len(units)
|
||||
if not total or not weight:
|
||||
return None
|
||||
starts = [u.start() for u in units]
|
||||
bounds = starts + [len(translation)]
|
||||
out: list[str] = []
|
||||
cur = 0 # char cursor: never before the previous mark's end
|
||||
ucur = 0 # unit cursor, the same monotonicity in unit indices
|
||||
for mark in marks:
|
||||
found = _find_mark(_UNIT.findall(mark.inner), units, ucur)
|
||||
if found is not None:
|
||||
u1, u2 = found
|
||||
x1, x2 = units[u1].start(), units[u2 - 1].end()
|
||||
else:
|
||||
x1 = bounds[min(round(mark.w_start / weight * total), total)]
|
||||
x2 = bounds[min(round(mark.w_end / weight * total), total)]
|
||||
x1 = max(x1, cur)
|
||||
x2 = max(x2, x1)
|
||||
# The slice ends at the next unit's start, so the whitespace
|
||||
# and punctuation before that unit is inside it — but it
|
||||
# belongs BETWEEN the mark and the following word, not in the
|
||||
# inner text: end the inner text at its last unit and leave
|
||||
# the rest for the following slice.
|
||||
raw = translation[x1:x2]
|
||||
inner_units = list(_UNIT.finditer(raw))
|
||||
x2 = x1 + inner_units[-1].end() if inner_units else x1
|
||||
inner = translation[x1:x2].strip() or mark.inner
|
||||
out += [translation[cur:x1], mark.pre, inner, mark.post]
|
||||
cur = x2
|
||||
ucur = bisect.bisect_left(starts, x2)
|
||||
out.append(translation[cur:])
|
||||
return "".join(out)
|
||||
|
||||
|
||||
def join(original: str, spans: list[Span], texts: list[str]) -> str | None:
|
||||
"""Splice translated segments back into the original fragment; None on
|
||||
any validation failure (count mismatch, empty, non-prose or
|
||||
block-structure segment) — the caller drops the result and the fragment
|
||||
stays pending. Segments with marks (a block that crossed as one piece)
|
||||
get their links re-inserted at weight-mapped positions after the prose
|
||||
check.
|
||||
|
||||
Markdown-significant ASCII punctuation that pure_prose cannot see
|
||||
(plain text inline, syntax in the splice context — quoted titles, alt
|
||||
and link texts, table rows) is neutralized to Unicode look-alikes
|
||||
(``_NEUTRAL``) before splicing and mark placement (the swap is
|
||||
char-for-char, so unit alignment is unaffected); lines that would
|
||||
start a new block (a heading, a ``` or ::: fence — they would eat the
|
||||
rest of the block/fence they land in) reject the result outright
|
||||
(``_BLOCK``, ``_BLANK``)."""
|
||||
if len(texts) != len(spans):
|
||||
return None
|
||||
out: list[str] = []
|
||||
cursor = 0
|
||||
for span, translation in zip(spans, texts):
|
||||
# Decode the wire form ("<" back to "<") first: pure_prose then
|
||||
# validates exactly what gets spliced — a "<" the model formed
|
||||
# into anything tag-like is markup and rejects the result.
|
||||
translation = translation.replace("<", "<")
|
||||
if (
|
||||
not translation.strip()
|
||||
or not pure_prose(translation)
|
||||
or _BLOCK.search(translation)
|
||||
or _BLANK.search(translation.strip())
|
||||
):
|
||||
return None
|
||||
translation = translation.translate(_NEUTRAL)
|
||||
if span.marks:
|
||||
translation = _place_marks(translation, span.weight, span.marks)
|
||||
if translation is None:
|
||||
return None
|
||||
out.append(original[cursor : span.start])
|
||||
out.append(translation)
|
||||
cursor = span.end
|
||||
out.append(original[cursor:])
|
||||
return "".join(out)
|
||||
|
||||
|
||||
def has_prose(text: str) -> bool:
|
||||
"""True when the fragment yields at least one translatable segment.
|
||||
Chunks that are all markup, code, placeholders or reference definitions
|
||||
have no business reaching the model: every language renders them from
|
||||
the original chunk."""
|
||||
return bool(split(text)[1])
|
||||
@@ -0,0 +1,372 @@
|
||||
"""Shared core: site constants, the kanta database, and the render cache.
|
||||
|
||||
Everything the route modules (files, api, tracking, pages) need that is not
|
||||
a route itself: environment-derived paths and tunables, the ``Data`` root
|
||||
with its ``Kanta`` handle (migrations in pagerite.migrations), the analytics
|
||||
store, the page render cache
|
||||
(``_render_html``/``_cached_body``/``_html_response`` plus the
|
||||
``_render_gen`` ETag generation, bumped by ``_invalidate_pages`` on every
|
||||
content/settings write), the translator ``dispatcher``, the slug charset
|
||||
helpers, and the database bootstrap hooks (demo seed, translator defaults).
|
||||
Importable by every other pagerite module without cycles.
|
||||
"""
|
||||
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
import secrets
|
||||
from datetime import UTC, datetime
|
||||
from functools import lru_cache
|
||||
from pathlib import Path
|
||||
|
||||
import blake3
|
||||
from fastapi import HTTPException, Request
|
||||
from fastapi.responses import Response
|
||||
from fastapi_vue import env
|
||||
from kanta import Kanta
|
||||
from zstandard import ZstdCompressor
|
||||
|
||||
from pagerite import analytics, i18n, seed, translate, views
|
||||
from pagerite.chunks import store_chunks
|
||||
from pagerite.config import load
|
||||
from pagerite.data import (
|
||||
Data,
|
||||
Node,
|
||||
append_order,
|
||||
find_slot,
|
||||
prettify,
|
||||
)
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
#: The CLI-passed configuration (PAGERITE_CONFIG) for this process.
|
||||
config = load()
|
||||
|
||||
# Site identity: the hostname comes from the CLI (first positional argument,
|
||||
# passed in PAGERITE_CONFIG) and names the per-site data directory
|
||||
# ``<hostname>/{content.kantadb, analytics.json, files}`` under the cwd.
|
||||
HOSTNAME = config.hostname
|
||||
SITE_DIR = Path(HOSTNAME)
|
||||
#: Public origin of the site, used for absolute social/canonical/sitemap
|
||||
#: URLs. Localhost serves varying ports, so it falls back to the request's
|
||||
#: own base URL instead.
|
||||
SITE_URL = f"https://{HOSTNAME}" if HOSTNAME != "localhost" else ""
|
||||
|
||||
DB_PATH = os.getenv("PAGERITE_DB", str(SITE_DIR / "content.kantadb"))
|
||||
|
||||
# Visit analytics go to their own JSON file, not the kanta database.
|
||||
ANALYTICS_PATH = Path(os.getenv("PAGERITE_ANALYTICS", str(SITE_DIR / "analytics.json")))
|
||||
# The per-hostname data directory may not exist yet on first run; kanta
|
||||
# creates the database file but not its parent directory.
|
||||
Path(DB_PATH).parent.mkdir(parents=True, exist_ok=True)
|
||||
ANALYTICS_PATH.parent.mkdir(parents=True, exist_ok=True)
|
||||
analytics_store = analytics.Store(ANALYTICS_PATH)
|
||||
|
||||
# Content-addressed file store (uploads, seed assets, fetched favicons):
|
||||
# files on disk under hash-prefixed names, cached in RAM, served at /_f/.
|
||||
FILES_DIR = Path(os.getenv("PAGERITE_FILES", str(SITE_DIR / "files")))
|
||||
|
||||
# Uploaded images are thumbnailed to this size and recompressed to AVIF
|
||||
# (primary), with WebP and JPEG fallbacks re-encoded from the AVIF at
|
||||
# somewhat lower quality (similar or smaller file size); the untouched
|
||||
# original is kept alongside as ``<hash>.orig<ext>`` (never served).
|
||||
IMAGE_MAXSIZE = 1920
|
||||
IMAGE_QUALITY = 60
|
||||
IMAGE_WEBP_QUALITY = 50
|
||||
IMAGE_JPG_QUALITY = 55
|
||||
|
||||
# Favicons get the same derivatives but thumbnailed much smaller — 192px
|
||||
# is plenty (browsers scale down for the 16x16 tab icon themselves).
|
||||
FAVICON_MAXSIZE = 192
|
||||
|
||||
# Our own data root; kanta edits it in place, reads are plain attribute access.
|
||||
data = Data()
|
||||
kanta = Kanta(DB_PATH, data, migrations="pagerite.migrations")
|
||||
|
||||
# Dynamic HTML is compressed per request at level 9 (static assets are
|
||||
# already pre-compressed by fastapi-vue's Frontend).
|
||||
_zstd = ZstdCompressor(9)
|
||||
|
||||
|
||||
def _render_html(
|
||||
kind: str,
|
||||
path: str,
|
||||
base_url: str,
|
||||
lang: str = i18n.ORIGINAL_LANGUAGE,
|
||||
link_lang: str = "",
|
||||
) -> str:
|
||||
"""Render one of the generated pages (see _html_response)."""
|
||||
if kind == "page":
|
||||
# A selected language without an actual translation renders the
|
||||
# original (translation is None; see docs/localization.md).
|
||||
original = i18n.primary_lang(data.menu, path)
|
||||
translation = (
|
||||
i18n.get_translation(data, path, lang) if lang != original else None
|
||||
)
|
||||
return views.render_page(
|
||||
data.menu,
|
||||
data,
|
||||
path,
|
||||
data.brand,
|
||||
data.custom_css,
|
||||
data.theme,
|
||||
data.favicon,
|
||||
data.brand_html,
|
||||
base_url,
|
||||
transition=data.transition,
|
||||
lang=lang,
|
||||
translation=translation,
|
||||
link_lang=link_lang,
|
||||
)
|
||||
if kind == "category":
|
||||
# A category has no Markdown of its own; only the title map
|
||||
# localizes (heading, navigation, card text).
|
||||
original = i18n.primary_lang(data.menu, path)
|
||||
translation = (
|
||||
i18n.Translation(titles=i18n.title_map(data, lang))
|
||||
if lang != original
|
||||
else None
|
||||
)
|
||||
return views.render_category(
|
||||
data.menu,
|
||||
data,
|
||||
path,
|
||||
data.brand,
|
||||
data.custom_css,
|
||||
data.theme,
|
||||
data.favicon,
|
||||
data.brand_html,
|
||||
base_url,
|
||||
transition=data.transition,
|
||||
lang=lang,
|
||||
translation=translation,
|
||||
link_lang=link_lang,
|
||||
)
|
||||
if kind == "not-found":
|
||||
return views.render_not_found(
|
||||
data.menu,
|
||||
path,
|
||||
data.brand,
|
||||
data.custom_css,
|
||||
data.theme,
|
||||
data.favicon,
|
||||
data.brand_html,
|
||||
transition=data.transition,
|
||||
)
|
||||
return views.render_analytics(
|
||||
data.menu,
|
||||
data.brand,
|
||||
data.custom_css,
|
||||
data.theme,
|
||||
data.favicon,
|
||||
data.brand_html,
|
||||
transition=data.transition,
|
||||
)
|
||||
|
||||
|
||||
# Render generation: bumped (and the body cache cleared) by every
|
||||
# content/settings write, so page ETags and cached copies invalidate when
|
||||
# navigation-affecting changes happen. In-memory only — not database state.
|
||||
_render_gen = 0
|
||||
|
||||
|
||||
def _invalidate_pages() -> None:
|
||||
"""Drop cached page bodies (and the feed/llms.txt export bodies) and
|
||||
bump the render generation (ETags); any content change also re-runs
|
||||
translation dispatch."""
|
||||
global _render_gen
|
||||
_render_gen += 1
|
||||
_cached_body.cache_clear()
|
||||
# Local import: pagerite.feeds imports this module.
|
||||
from pagerite import feeds
|
||||
|
||||
feeds._cached_feed.cache_clear()
|
||||
dispatcher.schedule()
|
||||
|
||||
|
||||
@lru_cache(maxsize=128)
|
||||
def _cached_body(
|
||||
kind: str,
|
||||
path: str,
|
||||
base_url: str,
|
||||
zstd: bool,
|
||||
lang: str = i18n.ORIGINAL_LANGUAGE,
|
||||
link_lang: str = "",
|
||||
) -> bytes:
|
||||
"""Rendered page body; cleared by _invalidate_pages on any
|
||||
content/settings change. base_url feeds the social meta URLs, zstd
|
||||
selects the stored encoding (both variants are cached rather than
|
||||
re-compressed) and lang the selected language (not the raw
|
||||
Accept-Language header, which would blow up the cache key space).
|
||||
link_lang is the ?lang= override replicated onto the navigation links:
|
||||
a query render and a header-selected render of the same language differ
|
||||
in their links, so they are cached separately.
|
||||
"""
|
||||
body = _render_html(kind, path, base_url, lang, link_lang).encode()
|
||||
return _zstd.compress(body) if zstd else body
|
||||
|
||||
|
||||
def _html_response(
|
||||
request: Request,
|
||||
kind: str,
|
||||
path: str,
|
||||
status_code: int = 200,
|
||||
headers: dict | None = None,
|
||||
etag: bool = False,
|
||||
lang: str = i18n.ORIGINAL_LANGUAGE,
|
||||
link_lang: str = "",
|
||||
) -> Response:
|
||||
"""Response for a generated page, zstd-compressed when the client
|
||||
accepts it (no gzip fallback).
|
||||
|
||||
Done per handler rather than in middleware so that Frontend's
|
||||
already-compressed asset responses are never touched. The ETag stays
|
||||
identical across encodings (revalidation compares it before
|
||||
compression); ``vary: accept-encoding`` keeps caches from mixing the
|
||||
representations. In dev the cache is bypassed so theme/design edits on
|
||||
disk apply immediately.
|
||||
|
||||
``etag=True`` derives the validator from a blake3 hash of the
|
||||
(uncompressed) body — for pages like /_a that have no Node whose
|
||||
modified timestamp could serve as one — and answers matching
|
||||
if-none-match revalidations with a 304.
|
||||
"""
|
||||
zstd = "zstd" in request.headers.get("accept-encoding", "")
|
||||
# Absolute social/canonical URLs use the site's public origin; on
|
||||
# localhost (varying ports) fall back to the request's own base URL.
|
||||
base_url = SITE_URL or str(request.base_url).rstrip("/")
|
||||
if env.dev:
|
||||
identity = _render_html(kind, path, base_url, lang, link_lang).encode()
|
||||
body = _zstd.compress(identity) if zstd else identity
|
||||
else:
|
||||
identity = _cached_body(kind, path, base_url, False, lang, link_lang)
|
||||
body = (
|
||||
_cached_body(kind, path, base_url, True, lang, link_lang)
|
||||
if zstd
|
||||
else identity
|
||||
)
|
||||
h = dict(headers or {})
|
||||
# Content varies by language (Accept-Language selects a translation)
|
||||
# and by encoding; keep caches from mixing either representation.
|
||||
h["vary"] = "accept-language" + (", accept-encoding" if zstd else "")
|
||||
if etag:
|
||||
tag = f'"{blake3.blake3(identity).hexdigest()[:32]}"'
|
||||
h["etag"] = tag
|
||||
if request.headers.get("if-none-match") == tag:
|
||||
return Response(status_code=304, headers=h)
|
||||
if zstd:
|
||||
h["content-encoding"] = "zstd"
|
||||
return Response(body, status_code, h, media_type="text/html")
|
||||
|
||||
|
||||
_SLUG_RE = re.compile(r"^[a-z0-9][a-z0-9_-]*$")
|
||||
|
||||
|
||||
def _is_reserved(path: str) -> bool:
|
||||
"""Slug shape that content may never use: each segment must be lower-case
|
||||
ASCII letters, digits, hyphens and underscores (underscores may not be
|
||||
the first character), and dots are never allowed.
|
||||
"""
|
||||
if path == "":
|
||||
return False
|
||||
return any(not _SLUG_RE.match(seg) for seg in path.split("/"))
|
||||
|
||||
|
||||
def _check_reserved(path: str) -> None:
|
||||
"""Reject paths that do not follow the slug charset."""
|
||||
if _is_reserved(path):
|
||||
raise HTTPException(
|
||||
400,
|
||||
'slugs may only use a-z, 0-9, "-" and "_" (not as the first character), and no dots',
|
||||
)
|
||||
|
||||
|
||||
def _ensure(menu: dict[str, Node], path: str) -> Node:
|
||||
"""Return the node at ``path``, creating it and any missing ancestors
|
||||
(content-less category labels) appended at the end of their level."""
|
||||
nodes = menu
|
||||
node = None
|
||||
for seg in path.split("/"):
|
||||
node = nodes.get(seg)
|
||||
if node is None:
|
||||
node = Node(title=prettify(seg), order=append_order(nodes))
|
||||
nodes[seg] = node
|
||||
nodes = node.children
|
||||
return node
|
||||
|
||||
|
||||
def _remove_page(menu: dict[str, Node], path: str) -> bool:
|
||||
"""Delete the node at ``path`` (inside a transaction).
|
||||
|
||||
A node with children becomes a content-less category label; a childless
|
||||
node is removed entirely. Returns False if the path does not exist.
|
||||
"""
|
||||
slot = find_slot(menu, path)
|
||||
node = slot[0].get(slot[1]) if slot else None
|
||||
if node is None:
|
||||
return False
|
||||
if node.children:
|
||||
node.chunks = None
|
||||
node.modified = datetime.now(UTC)
|
||||
else:
|
||||
del slot[0][slot[1]]
|
||||
return True
|
||||
|
||||
|
||||
def _store_seed_file(
|
||||
markdown: str, banner: str, orig: str, body: bytes
|
||||
) -> tuple[str, str]:
|
||||
"""Store a seed file content-addressed and point references at /_f/.
|
||||
|
||||
Images get the same AVIF/WebP/JPEG derivatives as uploads and are
|
||||
linked extension-less; other content is stored as-is with its
|
||||
extension."""
|
||||
from pagerite.files import _ext, store_image # lazy: files imports state
|
||||
|
||||
ext = _ext(orig)
|
||||
name = store_image(body, ext, derive=ext != ".gif")
|
||||
markdown = markdown.replace(f"]({orig}", f"](/_f/{name}")
|
||||
banner = banner.replace(f'src="/{orig}"', f'src="/_f/{name}"')
|
||||
banner = banner.replace(f'src="{orig}"', f'src="/_f/{name}"')
|
||||
return markdown, banner
|
||||
|
||||
|
||||
@kanta.bootstrap
|
||||
def _seed(data: Data) -> None:
|
||||
"""Write the demo pages on database creation (never on existing dbs)."""
|
||||
for path in seed.PAGES:
|
||||
title, markdown, files, banner, order, design = seed.PAGES[path]
|
||||
for orig, body in files.items():
|
||||
markdown, banner = _store_seed_file(markdown, banner, orig, body)
|
||||
node = _ensure(data.menu, path)
|
||||
node.title = title
|
||||
# Empty markdown means a pure category label (e.g. "showcase",
|
||||
# seeded only to carry a banner design): leave chunks as None so
|
||||
# the node renders the placeholder and nav points at its children.
|
||||
if markdown:
|
||||
node.chunks = store_chunks(data.chunks, markdown)
|
||||
node.banner = banner
|
||||
node.banner_design = design
|
||||
node.order = order
|
||||
|
||||
|
||||
#: Translator key format: 12 lowercase alphanumeric characters — not
|
||||
#: brute-forceable over a WebSocket handshake, still human-manageable.
|
||||
#: The editor's lang tab generates further keys in the same format.
|
||||
_KEY_ALPHABET = "abcdefghijklmnopqrstuvwxyz0123456789"
|
||||
|
||||
|
||||
@kanta.bootstrap
|
||||
def _translator_defaults(data: Data) -> None:
|
||||
"""Translator defaults on database creation: the first service key and
|
||||
the wanted target languages (Spanish and Chinese — English is the
|
||||
original language, never a translation target). Further keys are
|
||||
managed in the editor shell's lang tab."""
|
||||
key = "".join(secrets.choice(_KEY_ALPHABET) for _ in range(12))
|
||||
data.translate_keys[key] = "default"
|
||||
data.translate_langs = {"es": True, "zh": True}
|
||||
|
||||
|
||||
# The translator dispatcher — protocol, connected clients and the job
|
||||
# pipeline live in translate.py; its WebSocket route is in api.py.
|
||||
dispatcher = translate.Dispatcher(data, kanta, _invalidate_pages)
|
||||
@@ -3,11 +3,6 @@
|
||||
SVG from the active palette (var(--accent)), so one SVG serves light
|
||||
and dark — and other themes too. */
|
||||
|
||||
#banner {
|
||||
min-height: 15rem;
|
||||
border-bottom: none;
|
||||
}
|
||||
|
||||
/* Artwork colors, light mode */
|
||||
.cb-bg0 {
|
||||
stop-color: #ffffff;
|
||||
|
||||

@@ -1,4 +1,4 @@
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1600 360" preserveAspectRatio="xMidYMid slice">
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1600 360" preserveAspectRatio="xMidYMax slice">
|
||||
<defs>
|
||||
<linearGradient id="cbg" x1="0" y1="0" x2="0" y2="1">
|
||||
<stop offset="0" class="cb-bg0"/>
|
||||
|
||||
|
Before Width: | Height: | Size: 2.0 KiB After Width: | Height: | Size: 2.0 KiB |
@@ -16,6 +16,7 @@
|
||||
--line: #12203f14;
|
||||
--font-body: var(--font-inter);
|
||||
--font-heading: var(--font-montserrat);
|
||||
--code-x-height: 0.546; /* Inter's x-height ratio */
|
||||
}
|
||||
|
||||
@media (prefers-color-scheme: dark) {
|
||||
@@ -32,18 +33,13 @@
|
||||
}
|
||||
}
|
||||
|
||||
::selection {
|
||||
background: var(--accent);
|
||||
color: #fff;
|
||||
}
|
||||
|
||||
/* Genuinely large solid brand with a soft blue shadow overlapping the
|
||||
artwork — conservative, but unmissable. */
|
||||
#brand {
|
||||
font-size: clamp(4rem, 11vw, 8.5rem);
|
||||
font-weight: 800;
|
||||
letter-spacing: -0.04em;
|
||||
line-height: 1;
|
||||
line-height: 1.1;
|
||||
white-space: nowrap;
|
||||
color: var(--accent2);
|
||||
filter: drop-shadow(0 0.4rem 1.4rem rgb(10 92 255 / 0.3));
|
||||
@@ -110,19 +106,18 @@ article h2 {
|
||||
|
||||
article h3 {
|
||||
font-weight: 700;
|
||||
font-size: 0.95rem;
|
||||
letter-spacing: 0.08em;
|
||||
text-transform: uppercase;
|
||||
color: var(--muted);
|
||||
}
|
||||
|
||||
blockquote {
|
||||
border-left-color: var(--accent);
|
||||
background: color-mix(in oklab, var(--accent) 6%, transparent);
|
||||
border-inline-start-color: var(--accent);
|
||||
background: color-mix(var(--accent) 6%, transparent);
|
||||
padding: 0.4rem 0.9rem;
|
||||
/* Keep the quoted text on the paragraph edge: the tinted box extends
|
||||
past it by its own border/padding, like code blocks. */
|
||||
margin: 0 -0.9rem 1rem calc(-0.25rem - 0.9rem);
|
||||
margin: 0 0 1rem;
|
||||
margin-inline: calc(-0.25rem - 0.9rem) -0.9rem;
|
||||
border-radius: 6px;
|
||||
}
|
||||
|
||||
@@ -131,16 +126,12 @@ blockquote {
|
||||
bar stays in both. */
|
||||
pre {
|
||||
border: 1px solid transparent;
|
||||
border-left: 0.25rem solid var(--accent);
|
||||
border-inline-start: 0.25rem solid var(--accent);
|
||||
/* Text on the paragraph edge: the box extends by padding + border. */
|
||||
margin-left: calc(-0.8rem - 0.25rem);
|
||||
margin-inline-start: calc(-0.8rem - 0.25rem);
|
||||
border-radius: 6px;
|
||||
}
|
||||
|
||||
img {
|
||||
border-radius: 4px;
|
||||
}
|
||||
|
||||
::view-transition {
|
||||
background: var(--bg);
|
||||
}
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
/* Crossfade page transition. Injected by the backend as #pagerite-transition
|
||||
when the "crossfade" transition is selected in the site settings. The old
|
||||
snapshot stays fully opaque underneath while the new one fades in on top —
|
||||
never a dip to black. Direction-neutral, so html.nav-back needs no
|
||||
mirroring (and same-section html.nav-fade changes nothing). */
|
||||
@keyframes nav-fade-in {
|
||||
from {
|
||||
opacity: 0;
|
||||
}
|
||||
}
|
||||
|
||||
::view-transition-old(root),
|
||||
::view-transition-new(root) {
|
||||
mix-blend-mode: normal;
|
||||
animation: none;
|
||||
}
|
||||
|
||||
::view-transition-new(root) {
|
||||
animation: 200ms ease-in-out nav-fade-in;
|
||||
}
|
||||
@@ -0,0 +1,98 @@
|
||||
/* Rotating-cube page transition (from termotohtori.fi). FRAGILE — do not
|
||||
tweak. Injected by the backend as #pagerite-transition when the "cube"
|
||||
transition is selected in the site settings. pagerite.js toggles
|
||||
html.nav-back for history-back navigation and html.nav-fade for
|
||||
same-section navigation. */
|
||||
::view-transition {
|
||||
perspective: 1000px;
|
||||
inset: 0;
|
||||
background: color-mix(var(--bg) 50%, black 50%);
|
||||
}
|
||||
|
||||
::view-transition-group(root),
|
||||
::view-transition-image-pair(root) {
|
||||
transform-style: preserve-3d;
|
||||
isolation: auto;
|
||||
}
|
||||
|
||||
::view-transition-old(root),
|
||||
::view-transition-new(root) {
|
||||
mix-blend-mode: normal;
|
||||
backface-visibility: hidden;
|
||||
animation: none;
|
||||
}
|
||||
|
||||
@keyframes group-rotate {
|
||||
to {
|
||||
transform: rotateY(-90deg);
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes fade-out-a-bit {
|
||||
to {
|
||||
opacity: 0.5;
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes fade-in-a-bit {
|
||||
from {
|
||||
opacity: 0.5;
|
||||
}
|
||||
}
|
||||
|
||||
::view-transition-group(root) {
|
||||
transform-origin: 50% 50% -50vw;
|
||||
animation: 300ms ease-in-out forwards group-rotate;
|
||||
}
|
||||
|
||||
::view-transition-old(root) {
|
||||
animation: 300ms ease-in-out forwards fade-out-a-bit;
|
||||
}
|
||||
|
||||
::view-transition-new(root) {
|
||||
transform-origin: 0 0;
|
||||
transform: rotateY(90deg);
|
||||
inset: 0 auto 0 100%;
|
||||
animation: 300ms ease-in-out forwards fade-in-a-bit;
|
||||
}
|
||||
|
||||
/* Reverse direction for browser back navigation (same geometry, mirrored). */
|
||||
@keyframes group-rotate-back {
|
||||
to {
|
||||
transform: rotateY(90deg);
|
||||
}
|
||||
}
|
||||
|
||||
html.nav-back::view-transition-group(root) {
|
||||
animation-name: group-rotate-back;
|
||||
}
|
||||
|
||||
html.nav-back::view-transition-new(root) {
|
||||
transform-origin: 100% 0;
|
||||
transform: rotateY(-90deg);
|
||||
inset: 0 100% 0 auto;
|
||||
}
|
||||
|
||||
/* Same-section navigation: a plain crossfade instead of the cube. These
|
||||
rules only override animation/geometry, leaving the block above's
|
||||
perspective and layering untouched. The old snapshot stays fully opaque
|
||||
underneath while the new one fades in on top — never a dip to black. */
|
||||
@keyframes nav-fade-in {
|
||||
from {
|
||||
opacity: 0;
|
||||
}
|
||||
}
|
||||
|
||||
html.nav-fade::view-transition-group(root) {
|
||||
animation: none;
|
||||
}
|
||||
|
||||
html.nav-fade::view-transition-old(root) {
|
||||
animation: none;
|
||||
}
|
||||
|
||||
html.nav-fade::view-transition-new(root) {
|
||||
transform: none;
|
||||
inset: 0;
|
||||
animation: 200ms ease-in-out nav-fade-in;
|
||||
}
|
||||
@@ -1,7 +1,13 @@
|
||||
/* Eyes banner design: a canvas critter watching the cursor from the
|
||||
grass (banner.html — markup + styles + script inlined by the backend
|
||||
into #page-banner). Fixed-height stage matching the canvas. */
|
||||
into #page-banner). The canvas fills the banner; the scene composes
|
||||
against the 13rem layout box and extends flat grass into any overflow
|
||||
a theme adds below (summer's cross-fade strip). */
|
||||
|
||||
#banner {
|
||||
height: 240px;
|
||||
/* Opt out of the base parallax (scale overscan + --pry drift): it lands on
|
||||
the design wrapper the backend puts around banner.html, and scaling from
|
||||
the bottom edge would crop the top of the composed scene — pushing the
|
||||
critter out of view — while this canvas animates on its own. */
|
||||
#page-banner>[data-design="eyes"] {
|
||||
transform: none;
|
||||
}
|
||||
|
||||
@@ -2,7 +2,13 @@
|
||||
<style>
|
||||
#eyes {
|
||||
width: 100%;
|
||||
height: 240px;
|
||||
/* 13rem — the banner's layout height, correct from the first frame,
|
||||
before any external stylesheet has sized #page-banner. Themes that
|
||||
extend the banner past the layout box (summer's overflow fade) raise
|
||||
--eyes-h to 100% so the canvas follows the taller stage; the script
|
||||
still composes the scene against the 13rem box and only extends the
|
||||
meadow, so the scene itself never shifts. */
|
||||
height: var(--eyes-h, 13rem);
|
||||
display: block;
|
||||
}
|
||||
</style>
|
||||
@@ -10,32 +16,51 @@
|
||||
(() => {
|
||||
const c = document.getElementById('eyes')
|
||||
const ctx = c.getContext('2d')
|
||||
const DPR = devicePixelRatio || 1
|
||||
|
||||
const fit = () => {
|
||||
const w = Math.max(1, c.clientWidth)
|
||||
const h = Math.max(1, c.clientHeight)
|
||||
c.width = Math.round(w * DPR)
|
||||
c.height = Math.round(h * DPR)
|
||||
// Sync the backing store to the canvas' laid-out size. Checked every
|
||||
// frame: this inline script runs before the stylesheets that size
|
||||
// #page-banner, so observers/load events can still miss the transition.
|
||||
// Assigning width/height also clears the canvas. DPR is read here, not
|
||||
// captured: it changes with browser zoom.
|
||||
const syncSize = () => {
|
||||
const DPR = devicePixelRatio || 1
|
||||
const w = Math.round(Math.max(1, c.clientWidth) * DPR)
|
||||
const h = Math.round(Math.max(1, c.clientHeight) * DPR)
|
||||
if (c.width !== w || c.height !== h) {
|
||||
c.width = w
|
||||
c.height = h
|
||||
}
|
||||
ctx.setTransform(DPR, 0, 0, DPR, 0, 0)
|
||||
}
|
||||
|
||||
fit()
|
||||
addEventListener('resize', fit)
|
||||
|
||||
let mx = 0
|
||||
let my = 0
|
||||
let lastMove = 0
|
||||
|
||||
addEventListener('mousemove', e => {
|
||||
// Mouse and touch tracked with separate listeners (pointer events arrive
|
||||
// too late on some mobile browsers). Passive listeners: a drag on the
|
||||
// banner still scrolls the page — on browsers that stop delivering
|
||||
// touchmove once scrolling takes over, the gaze just follows until then.
|
||||
const track = (x, y) => {
|
||||
const r = c.getBoundingClientRect()
|
||||
|
||||
// Convert viewport coordinates into the canvas' CSS-pixel coordinate
|
||||
// system. This remains correct with browser zoom, CSS transforms, etc.
|
||||
mx = (e.clientX - r.left) * c.clientWidth / r.width
|
||||
my = (e.clientY - r.top) * c.clientHeight / r.height
|
||||
mx = (x - r.left) * c.clientWidth / r.width
|
||||
my = (y - r.top) * c.clientHeight / r.height
|
||||
lastMove = performance.now()
|
||||
})
|
||||
}
|
||||
|
||||
addEventListener('mousemove', e => track(e.clientX, e.clientY))
|
||||
|
||||
const trackTouch = e => {
|
||||
const t = e.touches[0]
|
||||
|
||||
if (t) track(t.clientX, t.clientY)
|
||||
}
|
||||
|
||||
addEventListener('touchstart', trackTouch, { passive: true })
|
||||
addEventListener('touchmove', trackTouch, { passive: true })
|
||||
|
||||
let gx = 0.5
|
||||
let gy = 0.5
|
||||
@@ -54,7 +79,7 @@
|
||||
]
|
||||
|
||||
const ridgeY = (x, w, h) =>
|
||||
h * 0.72 +
|
||||
h * 0.83 +
|
||||
Math.sin(x * 0.012) * 10 +
|
||||
Math.sin(x * 0.003 + 1.4) * 16 +
|
||||
Math.sin(x * 0.02 + 0.7) * 3
|
||||
@@ -114,7 +139,7 @@
|
||||
|
||||
for (let i = 0; i < 5; i++) {
|
||||
const x = (i + 0.5) * w / 5
|
||||
const y = h * 0.58 + Math.sin(i * 1.7) * 8
|
||||
const y = h * 0.69 + Math.sin(i * 1.7) * 8
|
||||
|
||||
ctx.fillStyle = '#5f8d4e'
|
||||
ctx.beginPath()
|
||||
@@ -307,7 +332,10 @@
|
||||
ctx.moveTo(0, h)
|
||||
ctx.lineTo(0, ridgeY(0, w, h))
|
||||
|
||||
for (let x = 0; x <= w; x += 8)
|
||||
// Sample one step PAST the right edge (x <= w + 8): stopping at w would
|
||||
// leave the path closing with a visible vertical drop at the edge
|
||||
// whenever the width isn't a multiple of the 8px step.
|
||||
for (let x = 0; x <= w + 8; x += 8)
|
||||
ctx.lineTo(x, ridgeY(x, w, h))
|
||||
|
||||
ctx.lineTo(w, h)
|
||||
@@ -319,7 +347,7 @@
|
||||
ctx.moveTo(0, h)
|
||||
ctx.lineTo(0, ridgeY(0, w, h) + 10)
|
||||
|
||||
for (let x = 0; x <= w; x += 8)
|
||||
for (let x = 0; x <= w + 8; x += 8)
|
||||
ctx.lineTo(x, ridgeY(x, w, h) + 10)
|
||||
|
||||
ctx.lineTo(w, h)
|
||||
@@ -362,8 +390,17 @@
|
||||
const dt = Math.min(now - prev, 100) / 16.7
|
||||
prev = now
|
||||
|
||||
syncSize()
|
||||
|
||||
const w = c.clientWidth
|
||||
const h = c.clientHeight
|
||||
// Compose the scene against the banner's layout box, not the canvas:
|
||||
// a theme may extend #page-banner past #banner (e.g. summer overflows
|
||||
// the artwork into the page for a masked cross-fade), and the critter
|
||||
// must stay in the visible part. The overflow strip is filled with the
|
||||
// flat meadow color below — a hard canvas edge would show through the
|
||||
// fade, a grass extension just blends.
|
||||
const h = Math.min(c.clientHeight,
|
||||
c.closest('#banner')?.clientHeight || c.clientHeight)
|
||||
const R = Math.min(h * 0.11, 38)
|
||||
|
||||
if (now > nextMove && !hidePhase) {
|
||||
@@ -399,6 +436,16 @@
|
||||
vy *= Math.pow(0.85, dt)
|
||||
yoff += vy * dt
|
||||
|
||||
// Clip the scene to the composed area: the ducking critter travels
|
||||
// below it, and the overflow strip is only flat meadow painted after —
|
||||
// without the clip the critter would leave trails there as it sinks.
|
||||
// Clipping against grass-on-grass is invisible, so the duck still
|
||||
// reads as sinking into the meadow.
|
||||
ctx.save()
|
||||
ctx.beginPath()
|
||||
ctx.rect(0, 0, w, h)
|
||||
ctx.clip()
|
||||
|
||||
drawBackground(w, h)
|
||||
|
||||
const cx0 = gx * w
|
||||
@@ -415,6 +462,18 @@
|
||||
drawCritter(cx0, eyeY, R, now, dt)
|
||||
drawForeground(w, h)
|
||||
|
||||
ctx.restore()
|
||||
|
||||
// Extend the meadow into any overflow below the composed scene, with
|
||||
// the same two layers drawForeground leaves at the bottom (base grass
|
||||
// plus the dark under-band) so the joint is invisible.
|
||||
if (c.clientHeight > h) {
|
||||
ctx.fillStyle = '#69ae4b'
|
||||
ctx.fillRect(0, h, w, c.clientHeight - h)
|
||||
ctx.fillStyle = 'rgba(48,102,34,0.18)'
|
||||
ctx.fillRect(0, h, w, c.clientHeight - h)
|
||||
}
|
||||
|
||||
requestAnimationFrame(frame)
|
||||
}
|
||||
|
||||
|
||||
@@ -2,13 +2,6 @@
|
||||
(inlined by the backend into #page-banner), in neutral dark greys that
|
||||
follow the page's color scheme. */
|
||||
|
||||
/* Bezier-swept banner with wide orange stripes (inlined SVG), separated
|
||||
from the page by a straight orange blade. */
|
||||
#banner {
|
||||
height: 13rem;
|
||||
border-bottom: 4px solid var(--accent);
|
||||
}
|
||||
|
||||
/* Banner artwork dark tones: neutral greys in light mode (retinted to the
|
||||
page's violet family by the dark-scheme block below). */
|
||||
.nb-base {
|
||||
@@ -44,6 +37,7 @@
|
||||
}
|
||||
|
||||
@media (prefers-color-scheme: dark) {
|
||||
|
||||
/* Banner dark tones tinted to the same violet family as the page. */
|
||||
.nb-base {
|
||||
fill: #100d18;
|
||||
|
||||

@@ -1,4 +1,4 @@
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1600 360" preserveAspectRatio="xMidYMid slice">
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1600 360" preserveAspectRatio="xMidYMax slice">
|
||||
<defs>
|
||||
<linearGradient id="flare" x1="0" y1="0" x2="1" y2="0">
|
||||
<stop offset="0" stop-color="#ff6a00"/>
|
||||
|
||||
|
Before Width: | Height: | Size: 2.5 KiB After Width: | Height: | Size: 2.5 KiB |
@@ -41,6 +41,10 @@
|
||||
|
||||
--font-body: var(--font-montserrat);
|
||||
--font-heading: var(--font-literata);
|
||||
--code-x-height: 0.517; /* Montserrat's x-height ratio */
|
||||
/* Neutral grey selection instead of the accent tint: accent-colored
|
||||
text (h2, links, markers) stays readable on it in both schemes. */
|
||||
--selection-bg: #6664;
|
||||
}
|
||||
|
||||
/* Dark scheme: same identity, but the page goes deep violet (never muddy
|
||||
@@ -61,15 +65,17 @@
|
||||
}
|
||||
}
|
||||
|
||||
::selection {
|
||||
background: var(--accent);
|
||||
color: var(--ink);
|
||||
/* Any banner used is separated from page by a thick orange line */
|
||||
#banner {
|
||||
border-bottom: 4px solid var(--accent);
|
||||
}
|
||||
|
||||
/* Oversized outlined brand, spilling off the banner edge: orange stroke,
|
||||
solid black fill. */
|
||||
#brand {
|
||||
font-size: 10rem;
|
||||
/* Scales down proportionally below ~1000px: 10rem at a 62.5rem viewport,
|
||||
shrinking with vmin (smaller of viewport width/height) below that. */
|
||||
font-size: clamp(2.5rem, 16vmin, 10rem);
|
||||
line-height: 1.2;
|
||||
font-weight: 700;
|
||||
letter-spacing: 0.04em;
|
||||
@@ -131,21 +137,16 @@
|
||||
|
||||
/* Console-style headings: uppercase monospace. h1 in the page text color
|
||||
with a hazard-stripe underline, h2 deep orange, h3 cyan. */
|
||||
article h1,
|
||||
article h2,
|
||||
article h3 {
|
||||
article h1 {
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 0.02em;
|
||||
}
|
||||
|
||||
article h1 {
|
||||
color: var(--text);
|
||||
font-weight: 700;
|
||||
padding-bottom: 0.5rem;
|
||||
/* The hazard-stripe underline breaks out of the page box: the negative
|
||||
right margin extends the h1's box (and thus its background) all the
|
||||
way to the viewport's right edge. */
|
||||
margin-right: calc((100% - 100vw) / 2);
|
||||
end margin extends the h1's box (and thus its background) all the
|
||||
way to the viewport's edge on that side. */
|
||||
margin-inline-end: calc((100% - 100vw) / 2);
|
||||
background:
|
||||
linear-gradient(-55deg,
|
||||
transparent 0 0.2rem,
|
||||
@@ -181,32 +182,28 @@ article ul ul li::before {
|
||||
}
|
||||
|
||||
article ul ul ul li::before {
|
||||
content: "»";
|
||||
color: var(--accent);
|
||||
color: var(--muted);
|
||||
}
|
||||
|
||||
blockquote {
|
||||
border-left-color: var(--accent2);
|
||||
background: color-mix(in oklab, var(--accent2) 6%, transparent);
|
||||
border-inline-start-color: var(--accent2);
|
||||
background: color-mix(var(--accent2) 6%, transparent);
|
||||
padding: 0.25rem 0.75rem;
|
||||
/* Keep the quoted text on the paragraph edge: the tinted box extends
|
||||
past it by its own border/padding, like code blocks. */
|
||||
margin: 0 -0.75rem 1rem -1rem;
|
||||
margin: 0 0 1rem;
|
||||
margin-inline: -1rem -0.75rem;
|
||||
}
|
||||
|
||||
/* Code follows the color scheme; the dark-scheme well joins the violet
|
||||
family (--code-bg above). The orange side bar stays in both. */
|
||||
pre {
|
||||
border-left: 0.25rem solid var(--accent);
|
||||
border-inline-start: 0.25rem solid var(--accent);
|
||||
/* Text on the paragraph edge: the box extends by padding + border. */
|
||||
margin-left: calc(-0.8rem - 0.25rem);
|
||||
margin-inline-start: calc(-0.8rem - 0.25rem);
|
||||
border-radius: 3px;
|
||||
}
|
||||
|
||||
img {
|
||||
border-radius: 3px;
|
||||
}
|
||||
|
||||
::view-transition {
|
||||
background: var(--bg);
|
||||
}
|
||||
|
||||
@@ -15,7 +15,3 @@
|
||||
.banner-fade {
|
||||
stop-color: var(--bg);
|
||||
}
|
||||
|
||||
#banner {
|
||||
min-height: 13rem;
|
||||
}
|
||||
|
||||

@@ -1,4 +1,4 @@
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1200 300" preserveAspectRatio="xMidYMid slice">
|
||||
<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 1200 300" preserveAspectRatio="xMidYMax slice">
|
||||
<defs>
|
||||
<linearGradient id="sky" x1="0" y1="0" x2="0" y2="1">
|
||||
<stop offset="0" stop-color="#2b1b4d"/>
|
||||
|
||||
|
Before Width: | Height: | Size: 1.9 KiB After Width: | Height: | Size: 1.9 KiB |
@@ -17,11 +17,7 @@
|
||||
--line: #ffffff1c;
|
||||
--font-body: var(--font-literata);
|
||||
--font-heading: var(--font-fraunces);
|
||||
}
|
||||
|
||||
::selection {
|
||||
background: var(--accent2);
|
||||
color: #fff;
|
||||
--code-x-height: 0.507; /* Literata's x-height ratio */
|
||||
}
|
||||
|
||||
/* Oversized tilted brand in the sky→violet gradient. */
|
||||
@@ -64,12 +60,14 @@ article h3 {
|
||||
}
|
||||
|
||||
/* Theme-colored diamond markers instead of the base emoji (blue/orange
|
||||
clashes with this palette). */
|
||||
clashes with this palette). The text-style ◆ runs heavy at full size,
|
||||
so it's shrunk with font-size, the box is widened to compensate. */
|
||||
article ul li::before {
|
||||
content: "◆";
|
||||
color: var(--accent);
|
||||
font-size: 0.7em;
|
||||
vertical-align: 0.15em;
|
||||
font-size: 0.8em;
|
||||
margin-inline-start: calc(-1 * var(--list-indent) / 0.8);
|
||||
width: calc(var(--list-indent) / 0.8);
|
||||
}
|
||||
|
||||
article ul ul li::before {
|
||||
@@ -78,12 +76,11 @@ article ul ul li::before {
|
||||
}
|
||||
|
||||
article ul ul ul li::before {
|
||||
content: "◆";
|
||||
color: var(--accent3);
|
||||
}
|
||||
|
||||
blockquote {
|
||||
border-left-color: var(--accent2);
|
||||
border-inline-start-color: var(--accent2);
|
||||
}
|
||||
|
||||
/* Code panels sit slightly lighter than the page; the token colors come
|
||||
@@ -91,7 +88,3 @@ blockquote {
|
||||
pre {
|
||||
--code-bg: var(--surface);
|
||||
}
|
||||
|
||||
::view-transition {
|
||||
background: #000;
|
||||
}
|
||||
|
||||
@@ -0,0 +1,52 @@
|
||||
/* Wipe-reveal page transition: the old page stays put while the new one is
|
||||
revealed on top of it by a clip-path wipe sweeping left to right.
|
||||
Injected by the backend as #pagerite-transition when the "reveal"
|
||||
transition is selected in the site settings. Mirrored on history-back
|
||||
(html.nav-back: the wipe sweeps right to left); same-section navigation
|
||||
crossfades (html.nav-fade). */
|
||||
::view-transition-old(root),
|
||||
::view-transition-new(root) {
|
||||
mix-blend-mode: normal;
|
||||
animation: none;
|
||||
}
|
||||
|
||||
@keyframes reveal-right {
|
||||
from {
|
||||
clip-path: inset(0 100% 0 0);
|
||||
}
|
||||
to {
|
||||
clip-path: inset(0);
|
||||
}
|
||||
}
|
||||
|
||||
::view-transition-new(root) {
|
||||
clip-path: inset(0);
|
||||
animation: 350ms ease-in-out reveal-right;
|
||||
}
|
||||
|
||||
/* Reverse direction for browser back navigation. */
|
||||
@keyframes reveal-left {
|
||||
from {
|
||||
clip-path: inset(0 0 0 100%);
|
||||
}
|
||||
to {
|
||||
clip-path: inset(0);
|
||||
}
|
||||
}
|
||||
|
||||
html.nav-back::view-transition-new(root) {
|
||||
animation-name: reveal-left;
|
||||
}
|
||||
|
||||
/* Same-section navigation: a plain crossfade instead of the wipe. The old
|
||||
snapshot stays fully opaque underneath while the new one fades in on
|
||||
top — never a dip to black. */
|
||||
@keyframes nav-fade-in {
|
||||
from {
|
||||
opacity: 0;
|
||||
}
|
||||
}
|
||||
|
||||
html.nav-fade::view-transition-new(root) {
|
||||
animation: 200ms ease-in-out nav-fade-in;
|
||||
}
|
||||
@@ -0,0 +1,74 @@
|
||||
/* Horizontal slide page transition: the old page slides left while the new
|
||||
one follows from the right, both moving together like pages side by side.
|
||||
Injected by the backend as #pagerite-transition when the "slide"
|
||||
transition is selected in the site settings. Mirrored on history-back
|
||||
(html.nav-back); same-section navigation crossfades (html.nav-fade). Both
|
||||
snapshots cover the viewport throughout, so no background shows between
|
||||
them. */
|
||||
::view-transition {
|
||||
background: var(--bg);
|
||||
}
|
||||
|
||||
::view-transition-old(root),
|
||||
::view-transition-new(root) {
|
||||
mix-blend-mode: normal;
|
||||
animation: none;
|
||||
}
|
||||
|
||||
@keyframes slide-out-left {
|
||||
to {
|
||||
transform: translateX(-100%);
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes slide-in-right {
|
||||
from {
|
||||
transform: translateX(100%);
|
||||
}
|
||||
}
|
||||
|
||||
::view-transition-old(root) {
|
||||
animation: 300ms ease-in-out forwards slide-out-left;
|
||||
}
|
||||
|
||||
::view-transition-new(root) {
|
||||
animation: 300ms ease-in-out slide-in-right;
|
||||
}
|
||||
|
||||
/* Reverse direction for browser back navigation. */
|
||||
@keyframes slide-out-right {
|
||||
to {
|
||||
transform: translateX(100%);
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes slide-in-left {
|
||||
from {
|
||||
transform: translateX(-100%);
|
||||
}
|
||||
}
|
||||
|
||||
html.nav-back::view-transition-old(root) {
|
||||
animation-name: slide-out-right;
|
||||
}
|
||||
|
||||
html.nav-back::view-transition-new(root) {
|
||||
animation-name: slide-in-left;
|
||||
}
|
||||
|
||||
/* Same-section navigation: a plain crossfade instead of the slide. The old
|
||||
snapshot stays fully opaque underneath while the new one fades in on
|
||||
top — never a dip to black. */
|
||||
@keyframes nav-fade-in {
|
||||
from {
|
||||
opacity: 0;
|
||||
}
|
||||
}
|
||||
|
||||
html.nav-fade::view-transition-old(root) {
|
||||
animation: none;
|
||||
}
|
||||
|
||||
html.nav-fade::view-transition-new(root) {
|
||||
animation: 200ms ease-in-out nav-fade-in;
|
||||
}
|
||||
@@ -0,0 +1,7 @@
|
||||
/* Stars banner design: a drifting starfield (banner.html — canvas + script
|
||||
inlined by the backend into #page-banner). The canvas takes the banner's
|
||||
13rem layout height directly so it never renders unclipped before the
|
||||
main stylesheet loads; the starfield scales to any height. The design's
|
||||
opt-out of theme banner overflow/fade effects also lives in banner.html's
|
||||
inline <style>, so it applies atomically with the markup (this file would
|
||||
load a beat later and let the overflow flash through mid-transition). */
|
||||
@@ -0,0 +1,73 @@
|
||||
<canvas id="stars"></canvas>
|
||||
<style>
|
||||
#stars {
|
||||
width: 100%;
|
||||
/* 13rem — the banner's layout height, not 100%: a percentage only
|
||||
resolves after the main stylesheet sizes #page-banner, and until
|
||||
then the canvas would render at its intrinsic height, unclipped,
|
||||
over the page. (This design always opts out of theme overflows —
|
||||
below — so the layout height is always the right one.) */
|
||||
height: 13rem;
|
||||
display: block;
|
||||
}
|
||||
|
||||
/* The night sky stays a windowed stage: undo the summer theme's banner
|
||||
overflow/cross-fade — a starfield must not bleed into a daylit page.
|
||||
Kept in this inlined <style> (not banner.css) so the opt-out applies
|
||||
atomically with the markup; a separate stylesheet can arrive a beat
|
||||
later and let the overflow flash through mid-transition. Later in
|
||||
document order than theme.css, so same-specificity rules win. */
|
||||
#page-banner {
|
||||
inset: 0;
|
||||
mask-image: none;
|
||||
}
|
||||
</style>
|
||||
<script><!--
|
||||
(() => {
|
||||
const c = document.getElementById('stars')
|
||||
const ctx = c.getContext('2d')
|
||||
|
||||
// Sync the backing store to the canvas' laid-out size. Checked every
|
||||
// frame: this inline script runs before the stylesheets that size
|
||||
// #page-banner, so observers/load events can still miss the transition.
|
||||
// Assigning width/height also clears the canvas. DPR is read here, not
|
||||
// captured: it changes with browser zoom.
|
||||
const syncSize = () => {
|
||||
const DPR = devicePixelRatio || 1
|
||||
const w = Math.round(Math.max(1, c.clientWidth) * DPR)
|
||||
const h = Math.round(Math.max(1, c.clientHeight) * DPR)
|
||||
if (c.width !== w || c.height !== h) {
|
||||
c.width = w
|
||||
c.height = h
|
||||
}
|
||||
ctx.setTransform(DPR, 0, 0, DPR, 0, 0)
|
||||
}
|
||||
|
||||
const stars = Array.from({ length: 110 }, () => ({
|
||||
x: Math.random(),
|
||||
y: Math.random(),
|
||||
r: Math.random() * 1.4 + 0.3,
|
||||
v: Math.random() * 0.05 + 0.01
|
||||
}))
|
||||
|
||||
let prev = performance.now()
|
||||
;(function frame(now) {
|
||||
if (!c.isConnected) return
|
||||
syncSize()
|
||||
const w = c.clientWidth
|
||||
const h = c.clientHeight
|
||||
const dt = Math.min(now - prev, 100)
|
||||
prev = now
|
||||
ctx.fillStyle = '#0b0e1d'
|
||||
ctx.fillRect(0, 0, w, h)
|
||||
ctx.fillStyle = '#cdd6ff'
|
||||
for (const s of stars) {
|
||||
s.x = (s.x + (s.v * dt) / 1000) % 1
|
||||
ctx.beginPath()
|
||||
ctx.arc(s.x * w, s.y * h, s.r, 0, 7)
|
||||
ctx.fill()
|
||||
}
|
||||
requestAnimationFrame(frame)
|
||||
})(prev)
|
||||
})()
|
||||
</script>
|
||||
@@ -2,10 +2,6 @@
|
||||
backend into #page-banner) — rolling hills, leafy bushes, swaying
|
||||
flowers, drifting clouds and a sun that rises as you scroll. */
|
||||
|
||||
#banner {
|
||||
min-height: 15rem;
|
||||
}
|
||||
|
||||
/* The artwork fades into the page background at its bottom edge. */
|
||||
.summer-fade {
|
||||
stop-color: var(--bg);
|
||||
@@ -44,9 +40,17 @@
|
||||
animation: summer-sun 9s ease-in-out infinite alternate;
|
||||
}
|
||||
|
||||
#page-banner .cloud-a { animation: summer-drift 56s ease-in-out infinite alternate; }
|
||||
#page-banner .cloud-b { animation: summer-drift 73s ease-in-out infinite alternate-reverse; }
|
||||
#page-banner .cloud-c { animation: summer-drift 64s ease-in-out infinite alternate; }
|
||||
#page-banner .cloud-a {
|
||||
animation: summer-drift 56s ease-in-out infinite alternate;
|
||||
}
|
||||
|
||||
#page-banner .cloud-b {
|
||||
animation: summer-drift 73s ease-in-out infinite alternate-reverse;
|
||||
}
|
||||
|
||||
#page-banner .cloud-c {
|
||||
animation: summer-drift 64s ease-in-out infinite alternate;
|
||||
}
|
||||
|
||||
#page-banner .flower {
|
||||
transform-box: fill-box;
|
||||
@@ -55,21 +59,42 @@
|
||||
}
|
||||
|
||||
/* Stagger the sway so the meadow doesn't move in lockstep. */
|
||||
#page-banner .flower:nth-child(3n) { animation-delay: -1.7s; }
|
||||
#page-banner .flower:nth-child(3n + 1) { animation-delay: -3.1s; animation-duration: 6s; }
|
||||
#page-banner .flower:nth-child(3n) {
|
||||
animation-delay: -1.7s;
|
||||
}
|
||||
|
||||
#page-banner .flower:nth-child(3n + 1) {
|
||||
animation-delay: -3.1s;
|
||||
animation-duration: 6s;
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes summer-sun {
|
||||
from { opacity: 0.22; }
|
||||
to { opacity: 0.38; }
|
||||
from {
|
||||
opacity: 0.22;
|
||||
}
|
||||
|
||||
to {
|
||||
opacity: 0.38;
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes summer-drift {
|
||||
from { transform: translateX(-1.6%); }
|
||||
to { transform: translateX(1.6%); }
|
||||
from {
|
||||
transform: translateX(-1.6%);
|
||||
}
|
||||
|
||||
to {
|
||||
transform: translateX(1.6%);
|
||||
}
|
||||
}
|
||||
|
||||
@keyframes summer-sway {
|
||||
from { transform: rotate(-2.6deg); }
|
||||
to { transform: rotate(2.6deg); }
|
||||
from {
|
||||
transform: rotate(-2.6deg);
|
||||
}
|
||||
|
||||
to {
|
||||
transform: rotate(2.6deg);
|
||||
}
|
||||
}
|
||||
|
||||

@@ -1,6 +1,6 @@
|
||||
<svg xmlns="http://www.w3.org/2000/svg"
|
||||
viewBox="0 0 1600 320"
|
||||
preserveAspectRatio="xMidYMid slice">
|
||||
preserveAspectRatio="xMidYMax slice">
|
||||
|
||||
<defs>
|
||||
<linearGradient id="sky" x1="0" y1="0" x2="0" y2="1">
|
||||
|
||||
|
Before Width: | Height: | Size: 11 KiB After Width: | Height: | Size: 11 KiB |
@@ -8,6 +8,7 @@
|
||||
|
||||
/* Every color is sampled (or text-darkened) from banner.svg. */
|
||||
--bg: #e6f4cf;
|
||||
--sky: #d9f1ff;
|
||||
/* pale meadow — the banner fades into this */
|
||||
--surface: #f8fbf0;
|
||||
--text: #2c4a2f;
|
||||
@@ -23,11 +24,12 @@
|
||||
--sun: #ffe071;
|
||||
--line: #4f913b29;
|
||||
|
||||
--link: color-mix(in oklab, var(--text) 38%, var(--accent));
|
||||
--link: color-mix(var(--text) 38%, var(--accent));
|
||||
|
||||
--font-body: var(--font-cause);
|
||||
--font-heading: var(--font-new-rocker);
|
||||
--font-brand: var(--font-cause);
|
||||
--code-x-height: 0.5; /* Cause's x-height ratio */
|
||||
}
|
||||
|
||||
/* The page is the same landscape the banner paints: hazy sky light up top
|
||||
@@ -56,15 +58,33 @@ body {
|
||||
color: var(--text);
|
||||
}
|
||||
|
||||
::selection {
|
||||
background: var(--sun);
|
||||
color: #3d5223;
|
||||
/* No separation between banner and page: the frame loses its background,
|
||||
border and shadow, and the artwork overflows into the document below,
|
||||
masked by a transparency gradient so it cross-fades into the body's fixed
|
||||
meadow gradient. A plain color match is impossible — both sides are
|
||||
gradients, and the parallax drift keeps the banner side moving. */
|
||||
#banner {
|
||||
background: none;
|
||||
border-bottom: 0;
|
||||
box-shadow: none;
|
||||
}
|
||||
|
||||
/* The banner frame ties into the meadow beneath it. */
|
||||
#banner {
|
||||
border-bottom-color: #4f913b30;
|
||||
box-shadow: 0 0.3rem 1rem #4f913b22;
|
||||
#page-banner {
|
||||
inset: 0 0 -6rem;
|
||||
/* Paints over the page background in the overlap, but never swallows its
|
||||
clicks. */
|
||||
pointer-events: none;
|
||||
mask-image: linear-gradient(180deg, #000 calc(100% - 6rem), transparent);
|
||||
/* Canvas banner designs (eyes) default to the 13rem layout height; here
|
||||
they must fill the taller overflow stage so their meadow extension
|
||||
reaches through the fade strip. */
|
||||
--eyes-h: 100%;
|
||||
}
|
||||
|
||||
/* The mask above replaced the SVG's flat-color bottom fade (meadowFade) —
|
||||
fading to a single --bg would reintroduce a seam against the gradient. */
|
||||
#page-banner .summer-fade {
|
||||
stop-opacity: 0;
|
||||
}
|
||||
|
||||
/* Cheerful oversized tilted brand in a sky→grass→flower gradient. */
|
||||
@@ -114,23 +134,37 @@ body {
|
||||
}
|
||||
|
||||
/* Content sits in a soft wash of sunlit meadow rather than on a white
|
||||
card. */
|
||||
card. The wash lives on a pseudo-element so it can carry a vertical
|
||||
mask: it fades in from transparent over the strip where the banner
|
||||
artwork overflows into the page, so the two never fight — no matter
|
||||
which side paints on top. */
|
||||
main {
|
||||
position: relative;
|
||||
}
|
||||
|
||||
main::before {
|
||||
content: "";
|
||||
position: absolute;
|
||||
inset: 0;
|
||||
z-index: -1;
|
||||
background: linear-gradient(90deg,
|
||||
transparent,
|
||||
#f0f8dc80 15%,
|
||||
#f0f8dc8c 50%,
|
||||
#f0f8dc80 85%,
|
||||
transparent);
|
||||
mask-image: linear-gradient(180deg, transparent, #000 6rem);
|
||||
}
|
||||
|
||||
/* The sidebar is a piece of the same meadow: glassy green with a light
|
||||
top edge and a grassy shadow. */
|
||||
#sidebar {
|
||||
background: linear-gradient(160deg, #f4faddd9, #d9eec5cf);
|
||||
border-right: 1px solid #ffffff80;
|
||||
border-inline-end: 1px solid #ffffff80;
|
||||
border-bottom: 1px solid var(--line);
|
||||
box-shadow: 0 0.3rem 1rem #4f913b1f;
|
||||
border-radius: 1rem;
|
||||
margin-inline: 0.5rem;
|
||||
}
|
||||
|
||||
#sidebar a {
|
||||
@@ -171,12 +205,11 @@ article a:hover {
|
||||
color: var(--accent);
|
||||
}
|
||||
|
||||
/* Flower bullets, one accent per nesting level. */
|
||||
/* Fleur-de-lis on the first level, flowers below — one accent per level.
|
||||
(⚜️ renders emoji-style, so it needs no shrinking like the flowers.) */
|
||||
article ul li::before {
|
||||
content: "❀";
|
||||
content: "⚜️";
|
||||
color: var(--accent3);
|
||||
font-size: 0.8em;
|
||||
vertical-align: 0.1em;
|
||||
}
|
||||
|
||||
article ul ul li::before {
|
||||
@@ -192,7 +225,7 @@ article ul ul ul li::before {
|
||||
/* Quotes get a grassy edge and a wash of sunlight. */
|
||||
blockquote {
|
||||
color: #4d6849;
|
||||
border-left-color: var(--accent2);
|
||||
border-inline-start-color: var(--accent2);
|
||||
background: linear-gradient(90deg, #fff0a238, transparent 70%);
|
||||
padding-top: 0.25rem;
|
||||
padding-bottom: 0.25rem;
|
||||
@@ -260,8 +293,7 @@ figcaption,
|
||||
background: linear-gradient(160deg, #eef7dd, #d9eec5);
|
||||
}
|
||||
|
||||
/* The page transition exposes summer color around the rotating
|
||||
snapshots. */
|
||||
::view-transition {
|
||||
background: var(--bg);
|
||||
/* Override to mid sky shade instead of the darker --bg we otherwise get */
|
||||
background: var(--sky);
|
||||
}
|
||||
|
||||
@@ -0,0 +1,502 @@
|
||||
"""Visit analytics: collection sockets, geoip enrichment, favicon fetch.
|
||||
|
||||
The visitor-activity WebSocket (``/_ws``, public) and the admin analytics
|
||||
stream (``/_api/ws/analytics``) plus the ``/_a`` viewer page. Client IPs are
|
||||
enriched in background tasks with reverse DNS (cached PTR lookups) and the
|
||||
DB-IP city MMDB (``GeoIP``, decompressed into RAM and opened once at
|
||||
startup);
|
||||
external referrers get their favicon fetched and stored content-hashed.
|
||||
Snapshot broadcasts to connected admin sockets are debounced.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import gzip
|
||||
import io
|
||||
import ipaddress
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
import socket
|
||||
from contextlib import suppress
|
||||
from datetime import UTC, date, datetime
|
||||
from functools import lru_cache
|
||||
from pathlib import Path
|
||||
from urllib.parse import urlparse
|
||||
|
||||
import httpx
|
||||
import msgspec
|
||||
from fastapi import APIRouter, Request, WebSocket, WebSocketDisconnect
|
||||
from fastapi.responses import Response
|
||||
from uarite import uaparse
|
||||
|
||||
from pagerite import analytics, i18n
|
||||
from pagerite.data import resolve
|
||||
from pagerite.files import _hash_name, file_store
|
||||
from pagerite.state import SITE_URL, _html_response, analytics_store, data
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
# Live WebSocket clients for the analytics stream.
|
||||
_analytics_ws_clients: set[WebSocket] = set()
|
||||
_analytics_broadcast_task: asyncio.Task | None = None
|
||||
|
||||
|
||||
# DB-IP databases persist in the working directory (one download serves all
|
||||
# sites run from it). Not the package directory: reinstalls/upgrades wipe it.
|
||||
_DBIP_DIR = Path.cwd()
|
||||
|
||||
DBIP_URL = "https://download.db-ip.com/free/dbip-city-lite-{month}.mmdb.gz"
|
||||
|
||||
|
||||
def _download_dbip() -> None:
|
||||
"""Download the latest dbip-city-lite MMDB if ours is missing or older."""
|
||||
today = datetime.now(UTC).date()
|
||||
months = [f"{today:%Y-%m}"]
|
||||
# The current month's file may not be published yet; fall back to last month.
|
||||
prev = (today.replace(day=1) - date.resolution).replace(day=1)
|
||||
months.append(f"{prev:%Y-%m}")
|
||||
|
||||
existing = sorted(
|
||||
p.stem.removeprefix("dbip-city-lite-").removesuffix(".mmdb")
|
||||
for p in _DBIP_DIR.glob("dbip-city-lite-*.mmdb*")
|
||||
)
|
||||
if existing and existing[-1] >= months[0]:
|
||||
logger.info("DB-IP database is current (%s), skipping download", existing[-1])
|
||||
return
|
||||
|
||||
for month in months:
|
||||
url = DBIP_URL.format(month=month)
|
||||
target = _DBIP_DIR / f"dbip-city-lite-{month}.mmdb.gz"
|
||||
tmp = target.with_suffix(".mmdb.gz.tmp")
|
||||
logger.info("Downloading %s", url)
|
||||
try:
|
||||
with httpx.stream("GET", url, follow_redirects=True, timeout=120) as r:
|
||||
if r.status_code == 404:
|
||||
continue
|
||||
r.raise_for_status()
|
||||
with open(tmp, "wb") as f:
|
||||
f.writelines(r.iter_bytes())
|
||||
except httpx.HTTPError as e:
|
||||
logger.warning("DB-IP download failed: %s", e)
|
||||
tmp.unlink(missing_ok=True)
|
||||
continue
|
||||
# Verify it is actually gzip data before installing it.
|
||||
try:
|
||||
with gzip.open(tmp, "rb") as f:
|
||||
f.read(1)
|
||||
except OSError:
|
||||
logger.warning("DB-IP download for %s was not valid gzip", month)
|
||||
tmp.unlink(missing_ok=True)
|
||||
continue
|
||||
os.replace(tmp, target)
|
||||
# Drop older databases so the app never picks up a stale one.
|
||||
for old in _DBIP_DIR.glob("dbip-city-lite-*.mmdb*"):
|
||||
if old.name != target.name:
|
||||
old.unlink()
|
||||
logger.info("DB-IP database updated to %s", target.name)
|
||||
return
|
||||
logger.warning("Could not download a DB-IP database")
|
||||
|
||||
|
||||
def _geoip_db_path() -> Path | None:
|
||||
"""Find a DB-IP MMDB in the working directory: the ``.mmdb.gz`` download
|
||||
is canonical (decompressed into RAM at open); a plain ``.mmdb`` left over
|
||||
from older versions is still usable, and removed once the matching ``.gz``
|
||||
is present so it does not linger on disk. Returns None if none is present.
|
||||
"""
|
||||
gz = sorted(_DBIP_DIR.glob("dbip-*.mmdb.gz"))
|
||||
if gz:
|
||||
for stale in _DBIP_DIR.glob("dbip-*.mmdb"):
|
||||
stale.unlink()
|
||||
return gz[0]
|
||||
mmdb = sorted(_DBIP_DIR.glob("dbip-*.mmdb"))
|
||||
if mmdb:
|
||||
return mmdb[0]
|
||||
return None
|
||||
|
||||
|
||||
class GeoIP:
|
||||
"""Lazy DB-IP MMDB reader. Call ``_load()`` once at startup before
|
||||
concurrent requests arrive; ``country()`` is read-only and safe to call
|
||||
from ``asyncio.to_thread`` workers afterwards.
|
||||
"""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._reader: object | None = None
|
||||
|
||||
def _load(self) -> None:
|
||||
if self._reader is not None:
|
||||
return
|
||||
source = _geoip_db_path()
|
||||
if source is None:
|
||||
return
|
||||
try:
|
||||
import maxminddb
|
||||
|
||||
if source.suffix == ".gz":
|
||||
# Only the .gz is kept on disk; the database is decompressed
|
||||
# into RAM (MODE_FD makes the pure-Python Reader .read() the
|
||||
# buffer — never mmap — and bypasses the C extension).
|
||||
buf = io.BytesIO(gzip.decompress(source.read_bytes()))
|
||||
self._reader = maxminddb.open_database(buf, maxminddb.MODE_FD)
|
||||
else:
|
||||
self._reader = maxminddb.open_database(str(source))
|
||||
except Exception:
|
||||
logger.exception("Failed to open DB-IP database %s", source)
|
||||
|
||||
def country(self, ip: str) -> str:
|
||||
"""Two-letter ISO country code for ``ip``, or "" when unavailable."""
|
||||
if not ip or self._reader is None:
|
||||
return ""
|
||||
with suppress(Exception):
|
||||
rec = self._reader.get(ip)
|
||||
if rec:
|
||||
return (rec.get("country") or {}).get("iso_code", "")
|
||||
return ""
|
||||
|
||||
def city(self, ip: str) -> str:
|
||||
"""City name for ``ip``, or "" when unavailable.
|
||||
|
||||
GeoIP sometimes appends district names in parentheses (e.g.
|
||||
"Berlin (Bezirk Tempelhof-Schöneberg)"); those are stripped before
|
||||
the value is stored.
|
||||
"""
|
||||
if not ip or self._reader is None:
|
||||
return ""
|
||||
with suppress(Exception):
|
||||
rec = self._reader.get(ip)
|
||||
if rec:
|
||||
city = (rec.get("city") or {}).get("names", {}).get("en", "")
|
||||
if city:
|
||||
city = re.sub(r"\s*\([^)]*\)", "", city).strip()
|
||||
return city
|
||||
return ""
|
||||
|
||||
|
||||
_geoip = GeoIP()
|
||||
|
||||
|
||||
def _client_ip(request: Request | WebSocket) -> str:
|
||||
"""Client IP: first X-Forwarded-For hop (we sit behind a proxy), else
|
||||
the direct peer."""
|
||||
forwarded = request.headers.get("x-forwarded-for", "").split(",")[0].strip()
|
||||
return forwarded or (request.client.host if request.client else "")
|
||||
|
||||
|
||||
def _query_suffix(request: Request) -> str:
|
||||
"""The request's query string as a "?..." suffix, or "" when absent."""
|
||||
query = str(request.url.query)
|
||||
return f"?{query}" if query else ""
|
||||
|
||||
|
||||
@lru_cache(maxsize=4096)
|
||||
def _cached_ptr(ip: str) -> str:
|
||||
"""Reverse-DNS lookup with in-RAM LRU cache. Returns the host name or ""."""
|
||||
if not ip:
|
||||
return ""
|
||||
try:
|
||||
addr = ipaddress.ip_address(ip)
|
||||
except ValueError:
|
||||
return ""
|
||||
if (
|
||||
addr.is_private
|
||||
or addr.is_loopback
|
||||
or addr.is_reserved
|
||||
or addr.is_multicast
|
||||
or addr.is_link_local
|
||||
):
|
||||
return ""
|
||||
try:
|
||||
host, _, _ = socket.gethostbyaddr(ip)
|
||||
except socket.herror:
|
||||
return ""
|
||||
return host
|
||||
|
||||
|
||||
async def _lookup_host(ip: str) -> str:
|
||||
"""Async wrapper around ``_cached_ptr``; runs the blocking lookup in a thread."""
|
||||
return await asyncio.to_thread(_cached_ptr, ip)
|
||||
|
||||
|
||||
async def _geoip_country(ip: str) -> str:
|
||||
"""Async wrapper around the DB-IP MMDB lookup."""
|
||||
return await asyncio.to_thread(_geoip.country, ip)
|
||||
|
||||
|
||||
async def _geoip_city(ip: str) -> str:
|
||||
"""Async wrapper around the DB-IP MMDB city lookup."""
|
||||
return await asyncio.to_thread(_geoip.city, ip)
|
||||
|
||||
|
||||
async def _enrich_client(client_hash: bytes) -> None:
|
||||
"""Run non-blocking reverse-DNS and geoip enrichment for a client."""
|
||||
client = analytics_store.data.clients.get(client_hash)
|
||||
if not client or not client.ip:
|
||||
return
|
||||
host = await _lookup_host(client.ip)
|
||||
country = await _geoip_country(client.ip)
|
||||
city = await _geoip_city(client.ip)
|
||||
analytics_store.enrich_client(client_hash, host=host, country=country, city=city)
|
||||
|
||||
|
||||
def _schedule_client_enrichment(client_hashes: list[bytes]) -> None:
|
||||
"""Start background host/geoip enrichment for the given client hashes."""
|
||||
for client_hash in client_hashes:
|
||||
asyncio.create_task(_enrich_client(client_hash))
|
||||
|
||||
|
||||
#: Icon MIME -> file extension for the stored favicon name. The extension
|
||||
#: reflects the actual content, not the /favicon.ico request path.
|
||||
_FAVICON_EXT = {
|
||||
"image/x-icon": ".ico",
|
||||
"image/vnd.microsoft.icon": ".ico",
|
||||
"image/png": ".png",
|
||||
"image/gif": ".gif",
|
||||
"image/jpeg": ".jpg",
|
||||
"image/webp": ".webp",
|
||||
"image/avif": ".avif",
|
||||
"image/svg+xml": ".svg",
|
||||
}
|
||||
|
||||
_FAVICON_MAX_BYTES = 65536
|
||||
|
||||
#: Origins with a fetch task currently in flight.
|
||||
_favicon_in_flight: set[str] = set()
|
||||
|
||||
|
||||
async def _fetch_favicon(origin: str) -> None:
|
||||
"""Fetch ``{origin}/favicon.ico`` and store it content-hashed on disk.
|
||||
|
||||
The result (icon file name, or "" for a miss) is recorded in the
|
||||
analytics store; misses are retried after analytics._FAVICON_RETRY.
|
||||
Never raises: analytics must not break page serving.
|
||||
"""
|
||||
try:
|
||||
async with httpx.AsyncClient(follow_redirects=True, timeout=8) as client:
|
||||
r = await client.get(f"{origin}/favicon.ico")
|
||||
body = r.content
|
||||
if (
|
||||
not (200 <= r.status_code < 300)
|
||||
or not body
|
||||
or len(body) > _FAVICON_MAX_BYTES
|
||||
):
|
||||
analytics_store.record_favicon(origin)
|
||||
return
|
||||
mime = r.headers.get("content-type", "").split(";")[0].strip().lower()
|
||||
if not mime.startswith("image/"):
|
||||
# Served without an image type: sniff SVG, else assume ICO.
|
||||
if b"<svg" in body[:1024]:
|
||||
mime = "image/svg+xml"
|
||||
elif mime in ("", "application/octet-stream", "text/plain"):
|
||||
mime = "image/x-icon"
|
||||
else:
|
||||
analytics_store.record_favicon(origin)
|
||||
return
|
||||
ext = _FAVICON_EXT.get(mime, ".ico")
|
||||
name = _hash_name(body, f"favicon{ext}")
|
||||
file_store.put(name, body)
|
||||
analytics_store.record_favicon(origin, name)
|
||||
except httpx.HTTPError, OSError:
|
||||
analytics_store.record_favicon(origin)
|
||||
finally:
|
||||
_favicon_in_flight.discard(origin)
|
||||
|
||||
|
||||
def _schedule_favicon_fetch() -> None:
|
||||
"""Start background favicon fetches for origins that need one."""
|
||||
origins = [
|
||||
origin
|
||||
for origin in analytics_store.favicon_origins_needed()
|
||||
if origin not in _favicon_in_flight
|
||||
]
|
||||
if not origins:
|
||||
return
|
||||
logger.info(
|
||||
"Fetching favicons: %s",
|
||||
", ".join(o.removeprefix("https://") for o in origins),
|
||||
)
|
||||
for origin in origins:
|
||||
_favicon_in_flight.add(origin)
|
||||
asyncio.create_task(_fetch_favicon(origin))
|
||||
|
||||
|
||||
async def _broadcast_analytics() -> None:
|
||||
"""Send the current analytics snapshot to every connected WS client."""
|
||||
if not _analytics_ws_clients:
|
||||
return
|
||||
payload = _display_json()
|
||||
closed = set()
|
||||
for ws in _analytics_ws_clients:
|
||||
try:
|
||||
await ws.send_text(payload)
|
||||
except Exception:
|
||||
logger.exception("Analytics broadcast failed; dropping client")
|
||||
closed.add(ws)
|
||||
for ws in closed:
|
||||
_analytics_ws_clients.discard(ws)
|
||||
|
||||
|
||||
async def _debounced_analytics_broadcast() -> None:
|
||||
"""Wait briefly, then broadcast the latest snapshot once."""
|
||||
await asyncio.sleep(0.2)
|
||||
await _broadcast_analytics()
|
||||
|
||||
|
||||
def _schedule_analytics_broadcast() -> None:
|
||||
"""Schedule a single debounced broadcast, ignoring duplicate triggers."""
|
||||
global _analytics_broadcast_task
|
||||
if _analytics_broadcast_task is not None and not _analytics_broadcast_task.done():
|
||||
return
|
||||
_analytics_broadcast_task = asyncio.get_running_loop().create_task(
|
||||
_debounced_analytics_broadcast()
|
||||
)
|
||||
|
||||
|
||||
def _in_menu(path: str) -> bool:
|
||||
"""True when ``path`` ("/a/b" or "/") resolves to a real menu node.
|
||||
|
||||
Category placeholders return 404 but are real nodes: their GETs must not
|
||||
count as misses in the display-time abuse classification.
|
||||
"""
|
||||
return resolve(data.menu, path.strip("/")) is not None
|
||||
|
||||
|
||||
def _display_json() -> str:
|
||||
"""The current analytics snapshot as JSON for the admin stream.
|
||||
|
||||
Adds the site's language context: ``multilingual`` (translation
|
||||
languages configured) lets the viewer suppress language UI on
|
||||
single-language sites, ``primary_lang`` (the front page's) lets it skip
|
||||
the primary-language default case.
|
||||
"""
|
||||
return analytics_store.display_json(
|
||||
_in_menu,
|
||||
multilingual=bool(data.translate_langs),
|
||||
primary_lang=i18n.primary_lang(data.menu, ""),
|
||||
)
|
||||
|
||||
|
||||
def _record_get(request: Request, *, status: int = 200, lang: str = "") -> None:
|
||||
"""Record the document GET as one raw access-log line in analytics.
|
||||
|
||||
Nothing is classified here — the true HTTP status, the full request path
|
||||
(query included), an external referer origin, the preload flag and the
|
||||
rendered content language (``lang``, "" for non-localized responses such
|
||||
as 404 probes and reserved paths) are stored, and
|
||||
visitor/crawler/abuse classification happens at display time
|
||||
(see analytics.Store.display). Idle-time preloads from pagerite.js
|
||||
(``x-pagerite-preload`` header) are recorded with ``pre=True``: never
|
||||
counted, but a navigation later served from the in-memory page cache is
|
||||
attributed this GET's status.
|
||||
|
||||
The devserver's health probe (``GET /?from=devserver.py`` from
|
||||
``127.0.0.1``) is ignored: it is not real traffic. The root-path and
|
||||
localhost checks prevent remote visitors from forging the same query.
|
||||
"""
|
||||
if (
|
||||
request.url.path == "/"
|
||||
and str(request.url.query) == "from=devserver.py"
|
||||
and _client_ip(request) == "127.0.0.1"
|
||||
):
|
||||
return
|
||||
own_origin = SITE_URL or f"https://{urlparse(str(request.base_url)).netloc}"
|
||||
referer = request.headers.get("referer", "")
|
||||
if analytics._origin(referer) in (None, own_origin):
|
||||
referer = ""
|
||||
client_hash = analytics_store.record_get(
|
||||
_client_ip(request),
|
||||
request.headers.get("user-agent", ""),
|
||||
f"{request.url.path}{_query_suffix(request)}",
|
||||
status=status,
|
||||
referer=referer,
|
||||
accept_language=request.headers.get("accept-language", ""),
|
||||
pre=bool(request.headers.get("x-pagerite-preload")),
|
||||
lang=lang,
|
||||
)
|
||||
if client_hash is not None:
|
||||
_schedule_client_enrichment([client_hash])
|
||||
|
||||
|
||||
@router.get("/_a", response_model=None)
|
||||
async def analytics_page(request: Request) -> Response:
|
||||
"""Render the analytics viewer as a normal site page at /_a.
|
||||
|
||||
The page itself is public, but the data stream (/_api/ws/analytics) stays
|
||||
admin-gated like the rest of /_api, so only authorized users see the
|
||||
statistics; others get the viewer with a "could not be loaded" message.
|
||||
"""
|
||||
return _html_response(
|
||||
request,
|
||||
"analytics",
|
||||
"",
|
||||
headers={"cache-control": "no-cache"},
|
||||
etag=True,
|
||||
)
|
||||
|
||||
|
||||
@router.websocket("/_ws")
|
||||
async def activity_ws(ws: WebSocket) -> None:
|
||||
"""Collect visitor activity: navigations and reading-time updates.
|
||||
|
||||
Public, like the pages themselves (only /_api is gated); one connection
|
||||
follows a browsing session. Messages are ``analytics.Ping`` structs as
|
||||
JSON text frames; ``to`` set is a navigation, ``read`` alone a
|
||||
reading-time update. Everything is recorded raw — known bot UAs and
|
||||
abusive IPs are filtered at display time, not here. The reverse-DNS and
|
||||
DB-IP geoip lookups happen in background tasks so message handling is
|
||||
never delayed by slow DNS or the first MMDB decompress.
|
||||
"""
|
||||
ip = _client_ip(ws)
|
||||
ua = ws.headers.get("user-agent", "")
|
||||
accept_language = ws.headers.get("accept-language", "")
|
||||
# Identify the visitor on the access-log open/close lines (the IP is
|
||||
# already printed there): compact UA plus the browser's language tag.
|
||||
lang, _country = analytics._parse_accept_language(accept_language)
|
||||
ws.scope.setdefault("state", {})["log_extra"] = " ".join(
|
||||
part for part in (uaparse(ua).pretty, lang) if part
|
||||
)
|
||||
await ws.accept()
|
||||
try:
|
||||
while True:
|
||||
text = await ws.receive_text()
|
||||
try:
|
||||
msg = msgspec.json.decode(text.encode(), type=analytics.Ping)
|
||||
except msgspec.DecodeError:
|
||||
continue
|
||||
new_client = analytics_store.record_msg(
|
||||
msg.fr,
|
||||
msg.to or None,
|
||||
ip,
|
||||
ua,
|
||||
accept_language,
|
||||
hide=msg.hide,
|
||||
read=msg.read,
|
||||
lang=msg.lang,
|
||||
)
|
||||
if new_client is not None:
|
||||
_schedule_client_enrichment([new_client])
|
||||
_schedule_favicon_fetch()
|
||||
except WebSocketDisconnect:
|
||||
pass
|
||||
|
||||
|
||||
@router.websocket("/_api/ws/analytics")
|
||||
async def analytics_websocket(ws: WebSocket) -> None:
|
||||
"""Stream the analytics snapshot, then push updates as they happen.
|
||||
|
||||
Admin-only via the /_api forward-auth gate, like every management
|
||||
endpoint. Powers the analytics viewer rendered at /_a.
|
||||
"""
|
||||
await ws.accept()
|
||||
await ws.send_text(_display_json())
|
||||
_analytics_ws_clients.add(ws)
|
||||
try:
|
||||
# Receive until the client goes away; we only push.
|
||||
while True:
|
||||
await ws.receive_text()
|
||||
except WebSocketDisconnect:
|
||||
logger.debug("Analytics WS client disconnected")
|
||||
finally:
|
||||
_analytics_ws_clients.discard(ws)
|
||||
@@ -0,0 +1,842 @@
|
||||
"""Translator service protocol, dispatcher and its transport-independent core.
|
||||
|
||||
The external machine-translation service connects over WebSocket
|
||||
(``/_translate/<key>``, the route itself is in api.py) and exchanges JSON
|
||||
frames decoded into the tagged msgspec structs below (``bytes`` fields ride
|
||||
as base64 — no manual encoding anywhere). This module holds everything
|
||||
else: the message structs, the connected-client dispatcher (``Dispatcher``
|
||||
— one job at a time per connection, wanted ∩ capable language matching,
|
||||
requeue on disconnect), which fragments are pending for a language
|
||||
(``pending_items``) and storing results (``store_results``).
|
||||
|
||||
Four job modes (Hello.modes announces which a connection accepts;
|
||||
docs/llm-translation.md):
|
||||
|
||||
- ``segments`` (default) — fragments cross as prose segments; markup never
|
||||
leaves the server and translations are spliced back by offset
|
||||
(``pagerite/segments.py``). For text-to-text models (Seed-X).
|
||||
- ``markdown`` — one fragment as full Markdown (a body chunk or a title),
|
||||
with the surrounding blocks of the served hybrid as context. For
|
||||
Markdown-native instruct LLMs; the result must re-chunk to exactly one
|
||||
block with anchor constructs (link destinations, placeholders) intact.
|
||||
- ``article`` — a whole page's Markdown at once (only while a page is
|
||||
mostly pending); the result is decomposed back into per-chunk
|
||||
translations (``align_article``), anchor-aligned and validated.
|
||||
- ``nav`` — the whole navigation hierarchy as one nested Markdown list of
|
||||
titles; the result is decomposed back into per-title fragments by list
|
||||
structure (``align_nav``). One round trip names the entire menu, and
|
||||
sibling titles translate consistently.
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import difflib
|
||||
import itertools
|
||||
import logging
|
||||
import re
|
||||
|
||||
import msgspec
|
||||
from fastapi import WebSocket, WebSocketDisconnect
|
||||
from kanta import Kanta
|
||||
|
||||
from pagerite import i18n
|
||||
from pagerite.chunks import chunk_key, chunk_markdown, needs_translation
|
||||
from pagerite.data import Data, Node, node_markdown, resolve, sorted_nodes
|
||||
from pagerite.markdown import has_h1
|
||||
from pagerite.segments import Span, join, pure_prose, split
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
#: Job granularities a translator connection may announce (Hello.modes).
|
||||
MODES = frozenset({"segments", "markdown", "article", "nav"})
|
||||
|
||||
|
||||
class Hello(msgspec.Struct, tag="hello"):
|
||||
"""Client greeting on connect: the language codes its model CAN produce
|
||||
(capabilities). The server offers jobs only in the intersection with
|
||||
the wanted target languages (``Data.translate_langs``)."""
|
||||
|
||||
langs: list[str]
|
||||
model: str = "" #: free-form model string (logging, debugging)
|
||||
#: Job granularities accepted (default: segments only).
|
||||
modes: list[str] = msgspec.field(default_factory=lambda: ["segments"])
|
||||
|
||||
|
||||
class TransItem(msgspec.Struct):
|
||||
"""One fragment to translate: original Markdown (or a node title)."""
|
||||
|
||||
key: bytes #: 9-byte chunk hash (base64 in the JSON frame)
|
||||
text: str
|
||||
path: str #: article it came from ("" = front page), no leading slash
|
||||
kind: str #: "chunk" | "title"
|
||||
#: Title jobs only: the article's opening prose, so the model sees the
|
||||
#: title as a heading in context, not a lone sentence.
|
||||
context: str = ""
|
||||
|
||||
|
||||
class Job(msgspec.Struct, tag="job"):
|
||||
"""Server push: ONE fragment to translate.
|
||||
|
||||
Exactly one job is in flight per connection — the next is sent only
|
||||
after this one's Result. Clients wanting parallelism open multiple
|
||||
connections."""
|
||||
|
||||
lang: str
|
||||
key: bytes #: 9-byte chunk hash (base64 in the JSON frame)
|
||||
#: segments mode: the fragment's prose segments (pagerite/segments.py)
|
||||
#: — plain text runs only, no markup. markdown/article/nav modes: a
|
||||
#: single element — the fragment's, the whole page's resp. the whole
|
||||
#: navigation tree's Markdown.
|
||||
texts: list[str]
|
||||
path: str #: article it came from ("" = front page), no leading slash
|
||||
kind: str #: "chunk" | "title" | "article" | "nav"
|
||||
#: The job granularity (the connection's mode this job was built for).
|
||||
mode: str = "segments"
|
||||
#: segments mode: per segment (parallel to texts; "" = none) the
|
||||
#: surround to translate it in. markdown mode: for chunks the previous
|
||||
#: and next block of the served hybrid (target language, patches
|
||||
#: applied; "" where none), for titles the article's opening. article
|
||||
#: mode with an injected title: the menu title's and the parent node's
|
||||
#: existing translations ("" where none). Contexts are reference only,
|
||||
#: never part of the result.
|
||||
contexts: list[str] = msgspec.field(default_factory=list)
|
||||
|
||||
|
||||
class TransResult(msgspec.Struct):
|
||||
"""One translated fragment (storage level, see store_results)."""
|
||||
|
||||
key: bytes
|
||||
text: str
|
||||
|
||||
|
||||
class Result(msgspec.Struct, tag="result"):
|
||||
"""Client reply: the translation of the connection's current Job
|
||||
(must match its lang and key exactly)."""
|
||||
|
||||
lang: str
|
||||
key: bytes
|
||||
#: The job's texts, translated: same order and count for segments jobs
|
||||
#: (each pure prose, or the result is rejected); a single element —
|
||||
#: the translated block, the whole translated article resp. the whole
|
||||
#: translated navigation list — for markdown/article/nav jobs.
|
||||
texts: list[str]
|
||||
|
||||
|
||||
#: Union of the client -> server frames (the "type" tag selects).
|
||||
ClientMsg = Hello | Result
|
||||
|
||||
#: A dispatchable offer: the job, its segment spans (segments mode), the
|
||||
#: full source text, the (lang, key) pairs it covers, and the page title's
|
||||
#: chunk key when an article job carries an injected title heading.
|
||||
_Offer = tuple["Job", list[Span], str, set[tuple[str, bytes]], "bytes | None"]
|
||||
|
||||
#: Constructs a translation must preserve verbatim inside a prose block:
|
||||
#: link/image destinations and {...} placeholders (sorted multisets are
|
||||
#: compared, so additions and drops both fail validation).
|
||||
_DEST = re.compile(r"\]\(([^)\s]+)")
|
||||
_BRACES = re.compile(r"\{[^{}\n]*\}")
|
||||
|
||||
#: Cap for a markdown-mode context block (previous/next hybrid block).
|
||||
_CONTEXT_CHARS = 1500
|
||||
|
||||
|
||||
def _marks(text: str) -> list[str]:
|
||||
return sorted(_DEST.findall(text) + _BRACES.findall(text))
|
||||
|
||||
|
||||
def clean_block(source: str, translated: str, kind: str) -> str | None:
|
||||
"""The translated block of a markdown-mode result, or None when it
|
||||
fails validation: the result must re-chunk to exactly one block with
|
||||
the source's anchor constructs (destinations, placeholders) intact;
|
||||
titles must stay a single prose line."""
|
||||
blocks = chunk_markdown(translated)
|
||||
if len(blocks) != 1:
|
||||
return None
|
||||
block = blocks[0]
|
||||
if kind == "title" and ("\n" in block or not pure_prose(block)):
|
||||
return None
|
||||
return block if _marks(source) == _marks(block) else None
|
||||
|
||||
|
||||
def align_article(source: str, translated: str) -> list[tuple[bytes, str]] | None:
|
||||
"""Decompose a whole-article translation into (source chunk key,
|
||||
translated block) pairs (also the import path for human-made
|
||||
translations, scripts/import_translation.py).
|
||||
|
||||
Blocks that must not change (code fences, container fences, raw HTML —
|
||||
everything ``needs_translation`` rejects) anchor the alignment: they
|
||||
must appear verbatim (chunk_key equality) and in order, or the whole
|
||||
result is rejected. Between two anchors the regions pair positionally;
|
||||
a region whose block count changed stores nothing (its chunks stay
|
||||
pending and fall back to scoped jobs), as does a paired block whose
|
||||
anchor constructs did not survive.
|
||||
"""
|
||||
src, tgt = chunk_markdown(source), chunk_markdown(translated)
|
||||
tgt_keys = [chunk_key(c) for c in tgt]
|
||||
locs: list[tuple[int, int]] = [] # (source index, target index) of anchors
|
||||
pos = 0
|
||||
for i, chunk in enumerate(src):
|
||||
if needs_translation(chunk):
|
||||
continue
|
||||
want = chunk_key(chunk)
|
||||
while pos < len(tgt) and tgt_keys[pos] != want:
|
||||
pos += 1
|
||||
if pos == len(tgt):
|
||||
return None
|
||||
locs.append((i, pos))
|
||||
pos += 1
|
||||
pairs: list[tuple[bytes, str]] = []
|
||||
ends = [(-1, -1), *locs, (len(src), len(tgt))]
|
||||
for (s0, t0), (s1, t1) in itertools.pairwise(ends):
|
||||
sregion, tregion = src[s0 + 1 : s1], tgt[t0 + 1 : t1]
|
||||
if len(sregion) != len(tregion):
|
||||
continue
|
||||
pairs.extend(
|
||||
(chunk_key(s), t)
|
||||
for s, t in zip(sregion, tregion)
|
||||
if _marks(s) == _marks(t)
|
||||
)
|
||||
return pairs
|
||||
|
||||
|
||||
#: One item line of a nested Markdown navigation list (nav mode).
|
||||
_NAV_LINE = re.compile(r"^([ \t]*)-\s+(.*\S)\s*$")
|
||||
|
||||
|
||||
def _nav_lines(md: str) -> list[tuple[int, str]] | None:
|
||||
"""(depth, text) per item of a nested Markdown list, or None when a
|
||||
non-blank line is not a "- " item. Depths are the indent strings in
|
||||
order of first appearance, so any consistent indent width maps."""
|
||||
indents: list[str] = []
|
||||
items: list[tuple[int, str]] = []
|
||||
for line in md.split("\n"):
|
||||
if not line.strip():
|
||||
continue
|
||||
m = _NAV_LINE.match(line)
|
||||
if not m:
|
||||
return None
|
||||
indent, text = m.groups()
|
||||
if indent not in indents:
|
||||
indents.append(indent)
|
||||
items.append((indents.index(indent), text))
|
||||
return items
|
||||
|
||||
|
||||
def align_nav(
|
||||
source: str, translated: str
|
||||
) -> tuple[list[tuple[bytes, str]], list[bytes]] | None:
|
||||
"""Decompose a whole-navigation translation into (title chunk key,
|
||||
translated title) pairs, plus the keys of titles that failed
|
||||
item-level validation (they stay pending for scoped title jobs).
|
||||
|
||||
The result must be the same nested list item for item — same count,
|
||||
same nesting depth at every position — or the whole job is rejected
|
||||
(None) and every title falls back to scoped title jobs. A paired item
|
||||
that came back empty, marked-up or with its anchor constructs (link
|
||||
destinations, placeholders) lost is skipped individually.
|
||||
"""
|
||||
src, tgt = _nav_lines(source), _nav_lines(translated)
|
||||
if src is None or tgt is None or len(src) != len(tgt):
|
||||
return None
|
||||
pairs: list[tuple[bytes, str]] = []
|
||||
skipped: list[bytes] = []
|
||||
for (sdepth, stitle), (tdepth, ttitle) in zip(src, tgt):
|
||||
if sdepth != tdepth:
|
||||
return None
|
||||
key = chunk_key(stitle)
|
||||
if not ttitle or not pure_prose(ttitle) or _marks(stitle) != _marks(ttitle):
|
||||
skipped.append(key)
|
||||
continue
|
||||
pairs.append((key, ttitle))
|
||||
return pairs, skipped
|
||||
|
||||
|
||||
def pending_items(data: Data, lang: str) -> list[TransItem]:
|
||||
"""Fragments of the site still untranslated for ``lang``, deduped by key.
|
||||
|
||||
Every node (published or not, pages and pure category labels alike)
|
||||
contributes its title; pages also contribute each chunk
|
||||
that needs translation (``needs_translation``), is not editor-flagged
|
||||
no-translate (``node.no_trans``) and has no ``trans`` entry for ``lang``
|
||||
yet. Content-addressed text (shared paragraphs, repeated titles) appears
|
||||
once, under the first page in menu order that has it.
|
||||
"""
|
||||
items: list[TransItem] = []
|
||||
seen: set[bytes] = set()
|
||||
|
||||
def emit(key: bytes, text: str, path: str, kind: str, context: str = "") -> None:
|
||||
if key in seen or lang in data.trans.get(key, {}):
|
||||
return
|
||||
seen.add(key)
|
||||
items.append(
|
||||
TransItem(key=key, text=text, path=path, kind=kind, context=context)
|
||||
)
|
||||
|
||||
def opening(node: Node) -> str:
|
||||
"""The article's opening prose (first segment, capped): the title
|
||||
job's context — a lone word like "About" reads as a heading on top
|
||||
of an article, not as a sentence. Empty when there's no prose."""
|
||||
for h in node.chunks or ():
|
||||
text = data.chunks.get(h)
|
||||
if text and (segs := split(text)[1]):
|
||||
return segs[0][:400]
|
||||
return ""
|
||||
|
||||
def walk(nodes: dict[str, Node], prefix: str, inherited: str) -> None:
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
# An article whose primary language IS the target needs no
|
||||
# translation into it — skip its title and chunks entirely.
|
||||
# Category labels (chunks is None) contribute only their title:
|
||||
# it is their nav-menu label.
|
||||
node_lang = node.language or inherited
|
||||
if node_lang != lang:
|
||||
if node.title:
|
||||
emit(
|
||||
chunk_key(node.title),
|
||||
node.title,
|
||||
path,
|
||||
"title",
|
||||
context=opening(node),
|
||||
)
|
||||
for h in node.chunks or ():
|
||||
text = data.chunks.get(h)
|
||||
if (
|
||||
text is not None
|
||||
and h not in node.no_trans
|
||||
and needs_translation(text)
|
||||
):
|
||||
emit(h, text, path, "chunk")
|
||||
walk(node.children, path, node_lang)
|
||||
|
||||
walk(data.menu, "", i18n.ORIGINAL_LANGUAGE)
|
||||
return items
|
||||
|
||||
|
||||
def store_results(data: Data, lang: str, items: list[TransResult]) -> list[str]:
|
||||
"""Store machine translations for ``lang``; return the paths of the
|
||||
articles that gained at least one entry.
|
||||
|
||||
Pure data operations: the caller wraps this in a kanta transaction and
|
||||
invalidates pages. Unknown keys are stored anyway (unreferenced hashes
|
||||
are never read, and the content may simply have moved on since the job
|
||||
was pushed); re-storing an existing key overwrites, last wins. Every
|
||||
article that gained an entry gets ``node.langs[lang]`` set (the
|
||||
availability index, docs/migrate.md) — because chunks are
|
||||
content-addressed, that includes pages merely sharing a fragment.
|
||||
"""
|
||||
stored = {item.key for item in items}
|
||||
for item in items:
|
||||
data.trans.setdefault(item.key, {})[lang] = item.text
|
||||
pages: list[str] = []
|
||||
|
||||
def walk(nodes: dict[str, Node], prefix: str, inherited: str) -> None:
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
path = f"{prefix}/{slug}" if prefix else slug
|
||||
node_lang = node.language or inherited
|
||||
if node_lang != lang:
|
||||
keys = set(node.chunks or ())
|
||||
if node.title:
|
||||
keys.add(chunk_key(node.title))
|
||||
if keys & stored:
|
||||
node.langs[lang] = True
|
||||
pages.append(path)
|
||||
walk(node.children, path, node_lang)
|
||||
|
||||
walk(data.menu, "", i18n.ORIGINAL_LANGUAGE)
|
||||
return pages
|
||||
|
||||
|
||||
class _Connection:
|
||||
"""One connected translator socket: the language codes and job modes it
|
||||
announced (Hello), its model string, and the job currently in flight on
|
||||
it — one at a time, the next is sent only after its Result.
|
||||
|
||||
Per-connection only: in-flight lives solely here, so on disconnect the
|
||||
item simply becomes pending again and is re-offered to any free capable
|
||||
connection."""
|
||||
|
||||
def __init__(self, capable: set[str], modes: set[str], model: str) -> None:
|
||||
self.capable = capable
|
||||
self.modes = modes
|
||||
self.model = model
|
||||
self.inflight: tuple[str, bytes] | None = None
|
||||
self.mode: str = "" #: the in-flight job's mode
|
||||
#: (lang, chunk key) pairs the in-flight job covers (an article job
|
||||
#: covers its page's pending chunks).
|
||||
self.items: set[tuple[str, bytes]] = set()
|
||||
#: segments mode: source spans of the in-flight job's segments
|
||||
#: (splice offsets and link marks).
|
||||
self.spans: list[Span] = []
|
||||
self.original: str = "" # its full source text (splicing / alignment)
|
||||
self.kind: str = "" # "chunk" | "title" | "article" | "nav"
|
||||
#: Article jobs with an injected title heading: the page title's
|
||||
#: chunk key (its translation is extracted from the result's first
|
||||
#: block, never stored as a body chunk).
|
||||
self.title_key: bytes | None = None
|
||||
|
||||
def take(self) -> tuple[str, str, str, list[Span], bytes | None]:
|
||||
"""Snapshot and clear the in-flight job's working state."""
|
||||
out = (self.mode, self.kind, self.spans, self.original, self.title_key)
|
||||
self.inflight = None
|
||||
self.items = set()
|
||||
self.mode = self.kind = ""
|
||||
self.spans = []
|
||||
self.original = ""
|
||||
self.title_key = None
|
||||
return out
|
||||
|
||||
|
||||
class Dispatcher:
|
||||
"""The translator dispatcher: connected client sockets and the job
|
||||
pipeline (docs/localization.md, docs/llm-translation.md).
|
||||
|
||||
One single-item job at a time per connection, offered in the
|
||||
intersection of the wanted languages (``Data.translate_langs``), the
|
||||
connection's announced capabilities and its accepted job modes:
|
||||
``article`` jobs (a whole page) only to article-capable connections and
|
||||
only while a page is mostly pending, steady-state follow-up as scoped
|
||||
``markdown``/``segments`` jobs, and ``nav`` jobs (the whole menu tree
|
||||
as one nested list) only to nav-capable connections, ahead of any
|
||||
per-title jobs. Pending work is derived from the
|
||||
``trans`` store (``pending_items``) minus the items in flight on any
|
||||
connection, so a dropped connection's in-flight item is simply
|
||||
re-offered. Results are matched to content by chunk key alone (an
|
||||
article job's key is its page's first chunk, a nav job's the hash of
|
||||
its list Markdown). A (lang, key, mode)
|
||||
whose Result fails validation is skipped for the rest of the run —
|
||||
generation is near-deterministic per model, so an immediate retry in
|
||||
the same mode would just re-fail, while other modes stay offerable.
|
||||
"""
|
||||
|
||||
def __init__(self, data: Data, db: Kanta, invalidate) -> None:
|
||||
self.data = data
|
||||
self.db = db
|
||||
#: Sync content-change hook (state._invalidate_pages), called inside
|
||||
#: transactions; schedules the next dispatch pass.
|
||||
self.invalidate = invalidate
|
||||
#: Connected translator sockets and their per-connection state.
|
||||
self.clients: dict[WebSocket, _Connection] = {}
|
||||
#: (lang, chunk key, mode) of jobs whose result failed validation
|
||||
#: this run.
|
||||
self.validation_failures: set[tuple[str, bytes, str]] = set()
|
||||
|
||||
def reset_validation_failures(self) -> None:
|
||||
"""Clear the skip list of fragments rejected this run: a
|
||||
translations refresh is precisely the "another chance" for them."""
|
||||
self.validation_failures.clear()
|
||||
|
||||
def schedule(self) -> None:
|
||||
"""Schedule a dispatch pass, if any translator is connected.
|
||||
|
||||
The invalidate hook is sync and called inside transactions: the
|
||||
task first runs once the current coroutine awaits again, i.e. after
|
||||
the transaction has committed. No-op without a running loop (CLI
|
||||
use)."""
|
||||
if not self.clients:
|
||||
return
|
||||
try:
|
||||
asyncio.get_running_loop()
|
||||
except RuntimeError:
|
||||
return
|
||||
asyncio.create_task(self._dispatch())
|
||||
|
||||
def _scoped_job(self, item: TransItem, lang: str, mode: str) -> _Offer | None:
|
||||
"""A title/chunk job for one pending item, in segments or markdown
|
||||
mode."""
|
||||
if mode == "segments":
|
||||
spans, texts, contexts = split(item.text)
|
||||
if not texts:
|
||||
return None # prose that could not be located for splicing
|
||||
if item.kind == "title" and item.context:
|
||||
# A title's surround is the article's opening prose
|
||||
# (TransItem.context), not its own one-word block.
|
||||
contexts = [item.context] * len(texts)
|
||||
job = Job(
|
||||
lang=lang,
|
||||
key=item.key,
|
||||
texts=texts,
|
||||
path=item.path,
|
||||
kind=item.kind,
|
||||
contexts=contexts,
|
||||
)
|
||||
else: # markdown: the fragment crosses whole, as Markdown
|
||||
if item.kind == "title":
|
||||
contexts = [item.context] if item.context else []
|
||||
else:
|
||||
contexts = self._block_contexts(lang, item)
|
||||
job = Job(
|
||||
lang=lang,
|
||||
key=item.key,
|
||||
texts=[item.text],
|
||||
path=item.path,
|
||||
kind=item.kind,
|
||||
mode="markdown",
|
||||
contexts=contexts,
|
||||
)
|
||||
return (
|
||||
job,
|
||||
spans if mode == "segments" else [],
|
||||
item.text,
|
||||
{(lang, item.key)},
|
||||
None,
|
||||
)
|
||||
|
||||
def _block_contexts(self, lang: str, item: TransItem) -> list[str]:
|
||||
"""The previous and next block of the served hybrid around a pending
|
||||
chunk (current machine translation with user overrides applied, so
|
||||
human corrections propagate into fresh translations)."""
|
||||
chain = resolve(self.data.menu, item.path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is None or not node.chunks or item.key not in node.chunks:
|
||||
return []
|
||||
served = [
|
||||
self.data.trans.get(h, {}).get(lang) or self.data.chunks.get(h, "")
|
||||
for h in node.chunks
|
||||
]
|
||||
blocks = chunk_markdown(i18n.hybrid_markdown(self.data, node, item.path, lang))
|
||||
i = node.chunks.index(item.key)
|
||||
# Map the chunk's served-list position onto the patched block list
|
||||
# (patches may merge, split or drop blocks).
|
||||
j = min(i, len(blocks))
|
||||
for tag, i1, i2, j1, j2 in difflib.SequenceMatcher(
|
||||
None, served, blocks, autojunk=False
|
||||
).get_opcodes():
|
||||
if i1 <= i < i2:
|
||||
j = j1 + (i - i1) if tag == "equal" else j1
|
||||
break
|
||||
prev = blocks[j - 1] if 0 < j <= len(blocks) else ""
|
||||
next_ = blocks[j + 1] if j + 1 < len(blocks) else ""
|
||||
return [prev[-_CONTEXT_CHARS:], next_[:_CONTEXT_CHARS]]
|
||||
|
||||
def _nav_job(self, lang: str, inflight: set[tuple[str, bytes]]) -> _Offer | None:
|
||||
"""The whole navigation hierarchy as one nested-Markdown-list job
|
||||
(nav-capable connections only): every node title still pending for
|
||||
``lang``, in menu order, indented by depth — pages and pure
|
||||
category labels alike, duplicates included (repeated titles keep
|
||||
the tree shape faithful and store under one key anyway).
|
||||
|
||||
One round trip names the entire menu, and sibling titles translate
|
||||
in sight of each other. The result is decomposed back into
|
||||
per-title fragments by ``align_nav``; a structurally mangled list
|
||||
is rejected wholesale and the titles fall back to scoped title
|
||||
jobs. A lone pending title is served directly by a scoped job."""
|
||||
titles: list[tuple[int, str, bytes]] = []
|
||||
|
||||
def walk(nodes: dict[str, Node], depth: int, inherited: str) -> None:
|
||||
for slug, node in sorted_nodes(nodes):
|
||||
node_lang = node.language or inherited
|
||||
if node_lang != lang and node.title and "\n" not in node.title:
|
||||
key = chunk_key(node.title)
|
||||
if (
|
||||
lang not in self.data.trans.get(key, {})
|
||||
and (lang, key) not in inflight
|
||||
and (lang, key, "nav") not in self.validation_failures
|
||||
):
|
||||
titles.append((depth, node.title, key))
|
||||
walk(node.children, depth + 1, node_lang)
|
||||
|
||||
walk(self.data.menu, 0, i18n.ORIGINAL_LANGUAGE)
|
||||
if len(titles) < 2:
|
||||
return None
|
||||
md = "\n".join(f"{' ' * depth}- {title}" for depth, title, _ in titles)
|
||||
key = chunk_key(md)
|
||||
if (lang, key, "nav") in self.validation_failures:
|
||||
return None
|
||||
job = Job(lang=lang, key=key, texts=[md], path="", kind="nav", mode="nav")
|
||||
return job, [], md, {(lang, k) for _, _, k in titles}, None
|
||||
|
||||
def _article_job(
|
||||
self, lang: str, items: list[TransItem], inflight: set[tuple[str, bytes]]
|
||||
) -> _Offer | None:
|
||||
"""A whole-page job for the first page that is mostly pending for
|
||||
``lang`` (a whole new article or a full refresh; steady-state edits
|
||||
stay scoped jobs). The job's key is the page's first chunk.
|
||||
|
||||
When the render would inject the page title as an h1 (the body has
|
||||
none of its own), the job text carries the same ``# {title}`` line:
|
||||
the title translates in document context, and the opening
|
||||
paragraphs see the heading. The menu title's and parent node's
|
||||
existing translations (from a nav job or earlier work) ride along
|
||||
as contexts, so the heading can match the menu — or deliberately
|
||||
deviate where the content calls for it."""
|
||||
by_path: dict[str, list[TransItem]] = {}
|
||||
for item in items:
|
||||
if item.kind == "chunk":
|
||||
by_path.setdefault(item.path, []).append(item)
|
||||
for path, page_items in by_path.items():
|
||||
chain = resolve(self.data.menu, path)
|
||||
node = chain[-1] if chain else None
|
||||
if node is None or not node.chunks:
|
||||
continue
|
||||
total = {
|
||||
h
|
||||
for h in node.chunks
|
||||
if h not in node.no_trans
|
||||
and (text := self.data.chunks.get(h)) is not None
|
||||
and needs_translation(text)
|
||||
}
|
||||
pend = {item.key for item in page_items}
|
||||
if (
|
||||
not pend
|
||||
or len(pend) * 2 < len(total)
|
||||
or any((lang, key) in inflight for key in pend)
|
||||
):
|
||||
continue
|
||||
key = node.chunks[0]
|
||||
if (lang, key, "article") in self.validation_failures:
|
||||
continue
|
||||
md = node_markdown(self.data, node) or ""
|
||||
title_key = None
|
||||
contexts: list[str] = []
|
||||
if node.title and not has_h1(md):
|
||||
md = f"# {node.title}\n\n{md}"
|
||||
title_key = chunk_key(node.title)
|
||||
parent = chain[-2] if len(chain) >= 2 else None
|
||||
contexts = [
|
||||
self.data.trans.get(title_key, {}).get(lang, ""),
|
||||
self.data.trans.get(chunk_key(parent.title), {}).get(lang, "")
|
||||
if parent is not None and parent.title
|
||||
else "",
|
||||
]
|
||||
covered = {(lang, k) for k in pend}
|
||||
if title_key is not None:
|
||||
covered.add((lang, title_key))
|
||||
job = Job(
|
||||
lang=lang,
|
||||
key=key,
|
||||
texts=[md],
|
||||
path=path,
|
||||
kind="article",
|
||||
mode="article",
|
||||
contexts=contexts,
|
||||
)
|
||||
return job, [], md, covered, title_key
|
||||
return None
|
||||
|
||||
def _pick(
|
||||
self, state: _Connection, langs: list[str], inflight: set[tuple[str, bytes]]
|
||||
) -> _Offer | None:
|
||||
"""The next job for a free connection: the navigation tree before
|
||||
titles before articles before chunks — across languages too, so
|
||||
every menu is named before any article body is worked on (a page's
|
||||
name is its most visible string). pending_items emits in menu
|
||||
order, a page's title before its chunks."""
|
||||
pending = {lang: pending_items(self.data, lang) for lang in langs}
|
||||
scoped = (
|
||||
"markdown"
|
||||
if "markdown" in state.modes
|
||||
else "segments"
|
||||
if "segments" in state.modes
|
||||
else ""
|
||||
)
|
||||
for kind in ("nav", "title", "article", "chunk"):
|
||||
for lang in langs:
|
||||
if kind == "nav":
|
||||
if "nav" in state.modes and (
|
||||
offer := self._nav_job(lang, inflight)
|
||||
):
|
||||
return offer
|
||||
continue
|
||||
if kind == "article":
|
||||
if "article" in state.modes and (
|
||||
offer := self._article_job(lang, pending[lang], inflight)
|
||||
):
|
||||
return offer
|
||||
continue
|
||||
if not scoped:
|
||||
continue
|
||||
for item in pending[lang]:
|
||||
if (
|
||||
item.kind != kind
|
||||
or (lang, item.key) in inflight
|
||||
or (lang, item.key, scoped) in self.validation_failures
|
||||
):
|
||||
continue
|
||||
if offer := self._scoped_job(item, lang, scoped):
|
||||
return offer
|
||||
return None
|
||||
|
||||
async def _dispatch(self) -> None:
|
||||
"""Offer one pending item to every free capable connection."""
|
||||
wanted = {
|
||||
tag for lang in self.data.translate_langs if (tag := i18n.base_tag(lang))
|
||||
}
|
||||
if not wanted:
|
||||
return
|
||||
for ws, state in list(self.clients.items()):
|
||||
if state.inflight is not None:
|
||||
continue
|
||||
langs = sorted(wanted & state.capable)
|
||||
if not langs:
|
||||
continue
|
||||
inflight = {item for s in self.clients.values() for item in s.items}
|
||||
offer = self._pick(state, langs, inflight)
|
||||
if offer is None:
|
||||
continue
|
||||
job, spans, original, items, title_key = offer
|
||||
state.inflight = (job.lang, job.key) # before the await: no double-assign
|
||||
state.mode = job.mode
|
||||
state.kind = job.kind
|
||||
state.spans = spans
|
||||
state.original = original
|
||||
state.items = items
|
||||
state.title_key = title_key
|
||||
try:
|
||||
await ws.send_text(msgspec.json.encode(job).decode())
|
||||
except Exception: # send failed: the receive loop cleans up
|
||||
logger.exception("Job send failed; dropping translator client")
|
||||
self.clients.pop(ws, None)
|
||||
|
||||
def _results(
|
||||
self,
|
||||
mode: str,
|
||||
kind: str,
|
||||
key: bytes,
|
||||
original: str,
|
||||
spans: list[Span],
|
||||
texts: list[str],
|
||||
title_key: bytes | None = None,
|
||||
) -> tuple[list[TransResult], list[bytes]] | None:
|
||||
"""Validate a Result against its in-flight job and turn it into
|
||||
storable fragments plus the title keys a nav result failed at item
|
||||
level (empty for other modes); None when it fails validation (the
|
||||
caller skips the (lang, key, mode) for this run and the work stays
|
||||
pending)."""
|
||||
if mode == "segments":
|
||||
text = join(original, spans, texts) if len(texts) == len(spans) else None
|
||||
return ([TransResult(key=key, text=text)], []) if text is not None else None
|
||||
if mode == "markdown":
|
||||
block = clean_block(original, texts[0], kind) if len(texts) == 1 else None
|
||||
return ([TransResult(key=key, text=block)], []) if block else None
|
||||
if mode == "nav":
|
||||
out = align_nav(original, texts[0]) if len(texts) == 1 else None
|
||||
if out is None:
|
||||
return None
|
||||
pairs, skipped = out
|
||||
return [TransResult(key=k, text=t) for k, t in pairs], skipped
|
||||
pairs = align_article(original, texts[0]) if len(texts) == 1 else None
|
||||
if not pairs:
|
||||
return None
|
||||
if title_key is not None:
|
||||
# The job carried an injected "# {title}" heading: its pair
|
||||
# becomes the title fragment (heading text only, never a body
|
||||
# chunk). A demoted/merged heading just skips the title — it
|
||||
# stays pending for a scoped title job.
|
||||
heading = chunk_key(chunk_markdown(original)[0])
|
||||
title = ""
|
||||
kept = []
|
||||
for k, t in pairs:
|
||||
if k == heading and not title:
|
||||
m = re.fullmatch(r"# (.+)", t)
|
||||
if m and pure_prose(m.group(1)):
|
||||
title = m.group(1)
|
||||
continue
|
||||
kept.append((k, t))
|
||||
pairs = ([(title_key, title)] if title else []) + kept
|
||||
return [TransResult(key=k, text=t) for k, t in pairs], []
|
||||
|
||||
async def handle_ws(self, ws: WebSocket, clientkey: str) -> None:
|
||||
"""The /_translate/<key> channel (docs/localization.md).
|
||||
|
||||
A wrong/empty key rejects the handshake (closing before accept
|
||||
makes Starlette answer HTTP 403). Protocol (JSON frames): the
|
||||
client opens with Hello(langs, model, modes) announcing its
|
||||
CAPABILITIES — the language codes its model can produce (normalized
|
||||
to translation tags; "en"/empty dropped) and the job modes it
|
||||
accepts — then answers each Job with its Result(lang, key, texts).
|
||||
A Result without an in-flight job or with a different (lang, key),
|
||||
a duplicate Hello, or any malformed frame closes the socket with a
|
||||
protocol error.
|
||||
"""
|
||||
if clientkey not in self.data.translate_keys:
|
||||
await ws.close(code=1008) # policy violation; pre-accept = HTTP 403
|
||||
return
|
||||
await ws.accept()
|
||||
state: _Connection | None = None
|
||||
try:
|
||||
while True:
|
||||
raw = await ws.receive_text()
|
||||
try:
|
||||
msg = msgspec.json.decode(raw.encode(), type=ClientMsg)
|
||||
except msgspec.DecodeError:
|
||||
await ws.close(code=1002) # protocol error
|
||||
return
|
||||
if isinstance(msg, Hello):
|
||||
if state is not None: # one Hello per connection
|
||||
await ws.close(code=1002)
|
||||
return
|
||||
state = _Connection(
|
||||
{tag for lang in msg.langs if (tag := i18n.base_tag(lang))},
|
||||
set(msg.modes) & MODES or {"segments"},
|
||||
msg.model,
|
||||
)
|
||||
self.clients[ws] = state
|
||||
logger.info(
|
||||
"translator connected: model=%r, modes=%s, langs=%s",
|
||||
state.model,
|
||||
sorted(state.modes),
|
||||
sorted(state.capable),
|
||||
)
|
||||
self.schedule()
|
||||
else: # Result
|
||||
lang = i18n.base_tag(msg.lang)
|
||||
if (
|
||||
state is None # results before Hello
|
||||
or state.inflight is None # no job in flight
|
||||
or (lang, msg.key) != state.inflight # wrong job
|
||||
):
|
||||
await ws.close(code=1002)
|
||||
return
|
||||
mode, kind, spans, original, title_key = state.take()
|
||||
out = self._results(
|
||||
mode, kind, msg.key, original, spans, msg.texts, title_key
|
||||
)
|
||||
if out is None:
|
||||
# The model broke the contract (bad segment count,
|
||||
# markup in a segment, a merged/split block, a lost
|
||||
# anchor): drop the result and skip the (lang, key,
|
||||
# mode) for this run — the work stays pending and a
|
||||
# restart, a refresh, another mode or a model change
|
||||
# gets another chance.
|
||||
self.validation_failures.add((lang, msg.key, mode))
|
||||
logger.warning(
|
||||
"[%s] %s result for %s rejected: failed validation",
|
||||
lang,
|
||||
mode,
|
||||
msg.key.hex(),
|
||||
)
|
||||
self.schedule()
|
||||
continue
|
||||
results, skipped = out
|
||||
if skipped:
|
||||
# Titles a nav result mangled individually: skip
|
||||
# them in future nav jobs, leaving them to scoped
|
||||
# title jobs (which track their own failures).
|
||||
self.validation_failures.update(
|
||||
(lang, k, "nav") for k in skipped
|
||||
)
|
||||
logger.warning(
|
||||
"[%s] nav result: %d title(s) failed validation, "
|
||||
"left for scoped title jobs",
|
||||
lang,
|
||||
len(skipped),
|
||||
)
|
||||
with self.db.transaction(
|
||||
f"translate:{lang}{':' + kind if kind != 'chunk' else ''}",
|
||||
user=clientkey,
|
||||
):
|
||||
paths = store_results(self.data, lang, results)
|
||||
self.invalidate() # schedules the next dispatch
|
||||
if paths:
|
||||
logger.info(
|
||||
"[%s] now available for %d page(s): %s",
|
||||
lang,
|
||||
len(paths),
|
||||
", ".join(sorted(paths)),
|
||||
)
|
||||
except WebSocketDisconnect:
|
||||
pass
|
||||
finally:
|
||||
if self.clients.pop(ws, None) is not None:
|
||||
# The in-flight item (if any) is pending again; offer it around.
|
||||
self.schedule()
|
||||
@@ -17,13 +17,20 @@ readme = "README.md"
|
||||
requires-python = ">=3.14"
|
||||
dependencies = [
|
||||
"blake3>=1.0.9",
|
||||
"fastapi-vue>=1.3.1",
|
||||
"fastapi-vue~=1.7.2",
|
||||
"fastapi[standard]>=0.141.1",
|
||||
"html5tagger>=2.0.0",
|
||||
"kanta>=0.8.1",
|
||||
"httpx>=0.28.1",
|
||||
"kanta>=0.9.2",
|
||||
"markdown-it-py>=4.2.0",
|
||||
"maxminddb>=3.1.1",
|
||||
"mdit-py-plugins>=0.6.1",
|
||||
"mediapreview[standard]>=0.2.6",
|
||||
"platformdirs>=4.11.5",
|
||||
"pygments>=2.20.0",
|
||||
"python-slugify>=8.0.4",
|
||||
"uarite>=0.2.2",
|
||||
"zstandard>=0.25.0",
|
||||
]
|
||||
|
||||
[project.scripts]
|
||||
@@ -31,11 +38,10 @@ pagerite = "pagerite.__main__:main"
|
||||
|
||||
[project.urls]
|
||||
Repository = "https://git.zi.fi/LeoVasanko/pagerite"
|
||||
Issues = "https://github.com/LeoVasanko/pagerite"
|
||||
|
||||
[dependency-groups]
|
||||
dev = [
|
||||
"httpx>=0.28.1",
|
||||
]
|
||||
dev = []
|
||||
|
||||
[tool.hatch.version]
|
||||
source = "vcs"
|
||||
@@ -45,9 +51,11 @@ packages = ["pagerite"]
|
||||
|
||||
[tool.hatch.build]
|
||||
# `only-packages` drops directories without an __init__.py, so the theme
|
||||
# files must be force-included as artifacts (like the frontend build).
|
||||
artifacts = ["pagerite/frontend-build", "pagerite/themes"]
|
||||
# files and seed image assets must be force-included as artifacts (like
|
||||
# the frontend build).
|
||||
artifacts = ["pagerite/frontend-build", "pagerite/themes", "pagerite/seed-assets"]
|
||||
only-packages = true
|
||||
packages = ["pagerite"]
|
||||
|
||||
[tool.hatch.build.targets.sdist.hooks.custom]
|
||||
path = "scripts/fastapi-vue/buildhook.py"
|
||||
|
||||
@@ -1,13 +1,16 @@
|
||||
#!/usr/bin/env -S uv run
|
||||
# auto-upgrade@fastapi-vue-setup - remove this if you modify this file
|
||||
"""Run Vite development server for Vue app and FastAPI backend with auto-reload."""
|
||||
|
||||
import argparse
|
||||
import asyncio
|
||||
import os
|
||||
import subprocess
|
||||
import sys
|
||||
from contextlib import suppress
|
||||
from pathlib import Path
|
||||
|
||||
import tracerite
|
||||
|
||||
# Import util.py from scripts/fastapi-vue (not a package, so we adjust sys.path)
|
||||
sys.path.insert(0, str(Path(__file__).with_name("fastapi-vue")))
|
||||
from devutil import (
|
||||
@@ -19,8 +22,8 @@ from devutil import (
|
||||
setup_vite,
|
||||
)
|
||||
|
||||
DEFAULT_VITE_PORT = 3100
|
||||
DEFAULT_DEV_PORT = 3200
|
||||
DEFAULT_VITE_PORT = 8200
|
||||
DEFAULT_DEV_PORT = 8210
|
||||
HEALTH = "/?from=devserver.py"
|
||||
|
||||
|
||||
@@ -39,21 +42,22 @@ async def run_devserver(
|
||||
viteurl, npm_install, vite = setup_vite(listen, DEFAULT_VITE_PORT)
|
||||
backurl, pagerite = setup_cli("pagerite", backend, DEFAULT_DEV_PORT)
|
||||
|
||||
# Tell the everyone by environment (vite proxy and backend devmode use these)
|
||||
# Tell everyone via environment (vite proxy and backend devmode use these)
|
||||
os.environ["PAGERITE_VITE_URL"] = viteurl
|
||||
os.environ["PAGERITE_BACKEND_URL"] = backurl
|
||||
os.environ["PAGERITE_DEV"] = "1"
|
||||
|
||||
async with ProcessGroup() as pg:
|
||||
pg.create_task(check_ports_free(viteurl, backurl))
|
||||
npm_i = await pg.spawn(*npm_install, cwd=front)
|
||||
await check_ports_free(viteurl, backurl)
|
||||
await pg.spawn(*pagerite, *(extra_args or []))
|
||||
await pg.spawn(*pagerite, *(extra_args or []), vital=True)
|
||||
await pg.wait(npm_i, ready(backurl, path=HEALTH))
|
||||
await pg.spawn(*vite, cwd=front)
|
||||
await pg.spawn(*vite, cwd=front, vital=True)
|
||||
|
||||
|
||||
def main() -> None:
|
||||
"""Parse CLI arguments and run the devserver."""
|
||||
tracerite.load()
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Run Vite and FastAPI development servers",
|
||||
formatter_class=argparse.RawDescriptionHelpFormatter,
|
||||
@@ -71,8 +75,12 @@ def main() -> None:
|
||||
help=f"FastAPI (default: localhost:{DEFAULT_DEV_PORT})",
|
||||
)
|
||||
args, extra_args = parser.parse_known_args()
|
||||
with suppress(KeyboardInterrupt):
|
||||
try:
|
||||
asyncio.run(run_devserver(args.listen, args.backend, extra_args))
|
||||
except* KeyboardInterrupt:
|
||||
pass # user stopped the devserver: normal exit
|
||||
except* subprocess.SubprocessError, RuntimeError:
|
||||
raise SystemExit(1) from None # logged in devutil already; exit 1
|
||||
|
||||
|
||||
HELP_EPILOG = """
|
||||
|
||||